# LinkSurge — Full Blog Content
> Complete Markdown content of all LinkSurge blog posts.
> For a table of contents, see [llms.txt](https://linksurge.jp/llms.txt)
---
# 日本語記事
---
## ChatGPTが日本語で引用するドメインの構造 — Reddit・PR TIMES・note・楽天市場が上位に並ぶ理由と、業界別・時系列で見た引用元の地図
> URL: https://linksurge.jp/blog/chatgpt-citation-sources-japan-2026/
> Date: 2026-09-08 | Category: AIO | Author: 緒方亜朗
> Tags: ChatGPT対策, 引用元, Ahrefs, PR TIMES, note, Reddit, 日本市場, AI検索最適化
## この記事の結論:ChatGPTの日本語引用元は「英語圏の参照ソース+日本の発信媒体」の二層構造
ChatGPT対策の相談で必ず出るのが「どこに載れば引用されるのか」という質問です。私がAhrefsの日本市場データを2025年5月から2026年6月まで3時点で並べ、業界別の分析と突き合わせて見えてきた構造は、次の5つにまとめられます。
1. **上位は英語圏の参照ソースと日本の発信媒体の混成** — 2026年6月版のChatGPT引用元TOP10は、Reddit、PR TIMES、Ameblo、英語版Wikipedia、note、楽天市場、マイナビニュース、YouTube、Yahoo!知恵袋、ITmediaです。他のAI検索が日本語版Wikipediaやnoteを安定して上位に置くのに対し、ChatGPTだけが英語圏ソースを混ぜてきます
2. **順位は3か月で入れ替わる** — 2026年4月版で1位だったAmebloは6月版で3位に下がり、8位だったRedditが1位に上がりました。YouTubeとYahoo!知恵袋は6月版で新たにTOP10入りしています。「今の1位」に最適化する発想は成り立ちません
3. **業界によって主食が違う** — Ahrefsの業界別分析(2025年9〜12月)では、IT業界のChatGPT引用元1位はReddit、食品業界は PR TIMES、自動車業界は英語版Wikipediaでした。自社カテゴリの地図を自分で描く必要があります
4. **英語版Wikipediaが日本語版より上位に来るのは、英語へのクエリ展開の可能性** — Ahrefsはこの現象について、ChatGPTが日本語の質問を内部で英語のサブクエリに展開している可能性を指摘しています。MJ Cachónのブランド系プロンプト調査でも、国際的なブランドではサブクエリの27.3%に英語語彙が混ざりました
5. **上位1,000引用URLのうち直接影響できるのは32.3%、残る約67%は影響できない領域** — Ahrefsが2025年9月の英語圏データで示した構成では、Wikipedia 29.7%、ホームページ 23.8%、アプリストア 6.6%が主な「影響できない」区分です。影響できる32.3%(教育コンテンツ・レビュー・ニュース・ブログ)に施策を集中させ、ホームページの23.8%は「自社の公式サイトを整える」施策として取りに行くのが現実的です
以下では、時系列、業界別、言語、影響可能性の順に見ていき、最後に自社カテゴリの引用元マップの作り方を示します。
---
## 1. 3時点で見るChatGPTの日本語引用元
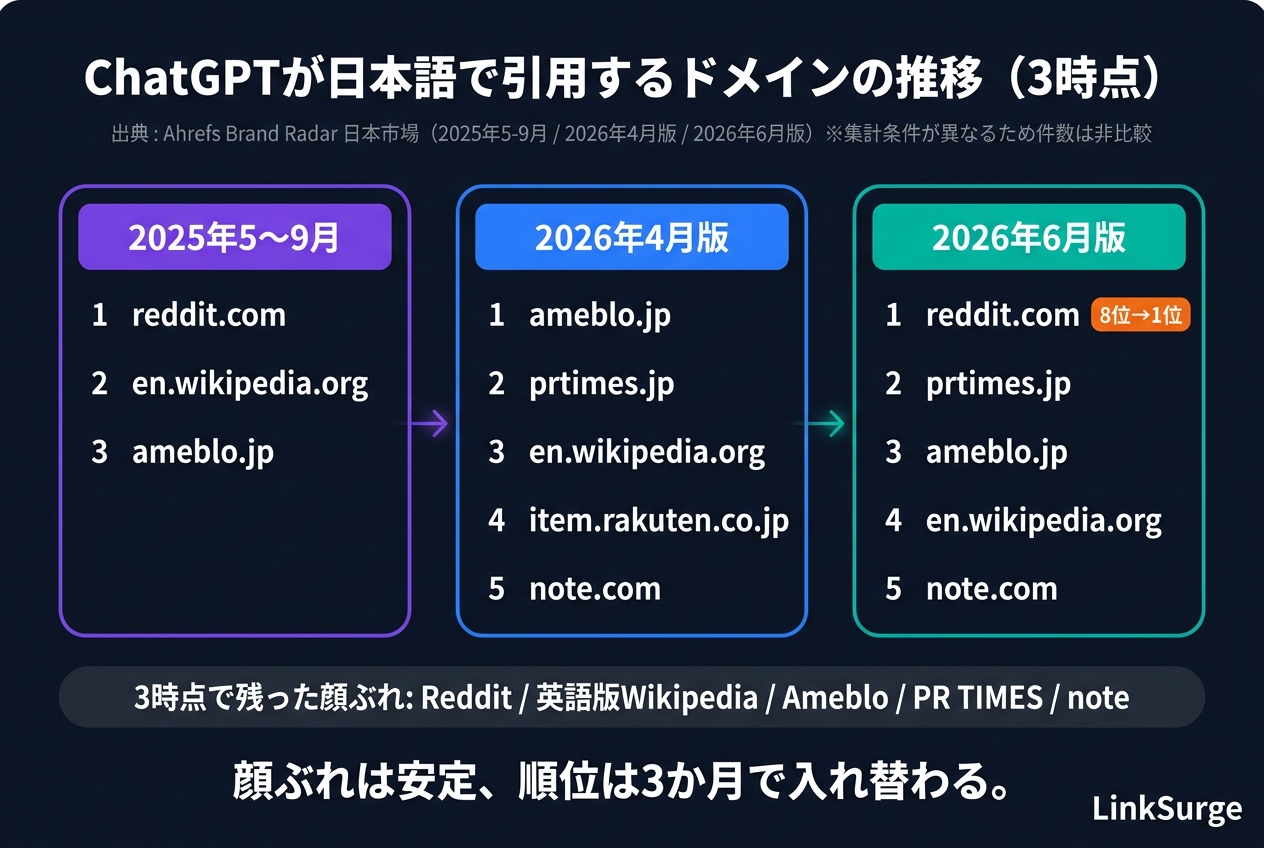
Ahrefsは自社ツールBrand Radarのデータをもとに、日本市場でAI検索が引用するドメインのランキングを継続的に公開しています。ChatGPTについて公開されている3時点を並べると、次のようになります。
| 順位 | 2025年5〜9月 | 2026年4月版 | 2026年6月版 |
|:---|:---|:---|:---|
| 1 | reddit.com(228,388) | ameblo.jp(103,459) | reddit.com |
| 2 | en.wikipedia.org(166,445) | prtimes.jp(95,655) | prtimes.jp |
| 3 | ameblo.jp(131,629) | en.wikipedia.org(71,950) | ameblo.jp |
| 4 | — | item.rakuten.co.jp(53,147) | en.wikipedia.org |
| 5 | — | note.com(52,679) | note.com |
| 6 | — | — | item.rakuten.co.jp |
| 7 | — | — | news.mynavi.jp |
| 8 | — | — | youtube.com |
| 9 | — | — | detail.chiebukuro.yahoo.co.jp |
| 10 | — | — | itmedia.co.jp |
括弧内は公開されている引用回数で、期間や集計条件が時点ごとに異なるため、回数の直接比較はできません。ここで見るべきは顔ぶれと順位の動きです。
### 顔ぶれは安定、順位は不安定
3時点を通じて残っているのはReddit、英語版Wikipedia、Ameblo、PR TIMES、noteです。一方で順位は大きく動きます。Redditは2025年に1位、4月版でTOP5圏外(8位)、6月版で再び1位。Amebloは4月版で1位に上がり、6月版で3位に戻りました。
率直に言って、私はこの変動を見て「ChatGPTの日本語引用元ランキングに最適化する」という発想を捨てました。3か月で1位が入れ替わる指標に合わせて施策を組んでも、公開する頃には前提が変わっています。顔ぶれとして安定している媒体を押さえつつ、順位ではなく「自社カテゴリで誰が引用されているか」を定点で見る方が現実的です。
引用元の変動そのものについては「[ChatGPTの引用元は4日で86%動く](/blog/chatgpt-citation-volatility-2026/)」で扱っています。
> 参考・引用:
> [Ahrefs、日本国内における AI 検索エンジンの引用元を徹底分析 - マナミナ](https://manamina.valuesccg.com/articles/4596)
> [AI 検索が引用するドメイン TOP 10【2026 年 4 月最新版】 - Ahrefs](https://ahrefs.com/blog/ja/brand-radar-top-10-cited-domains-2026-update/)
> [AI が引用する日本のドメインランキング 2026 年 6 月版 - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
---
## 2. 業界によって主食が違う
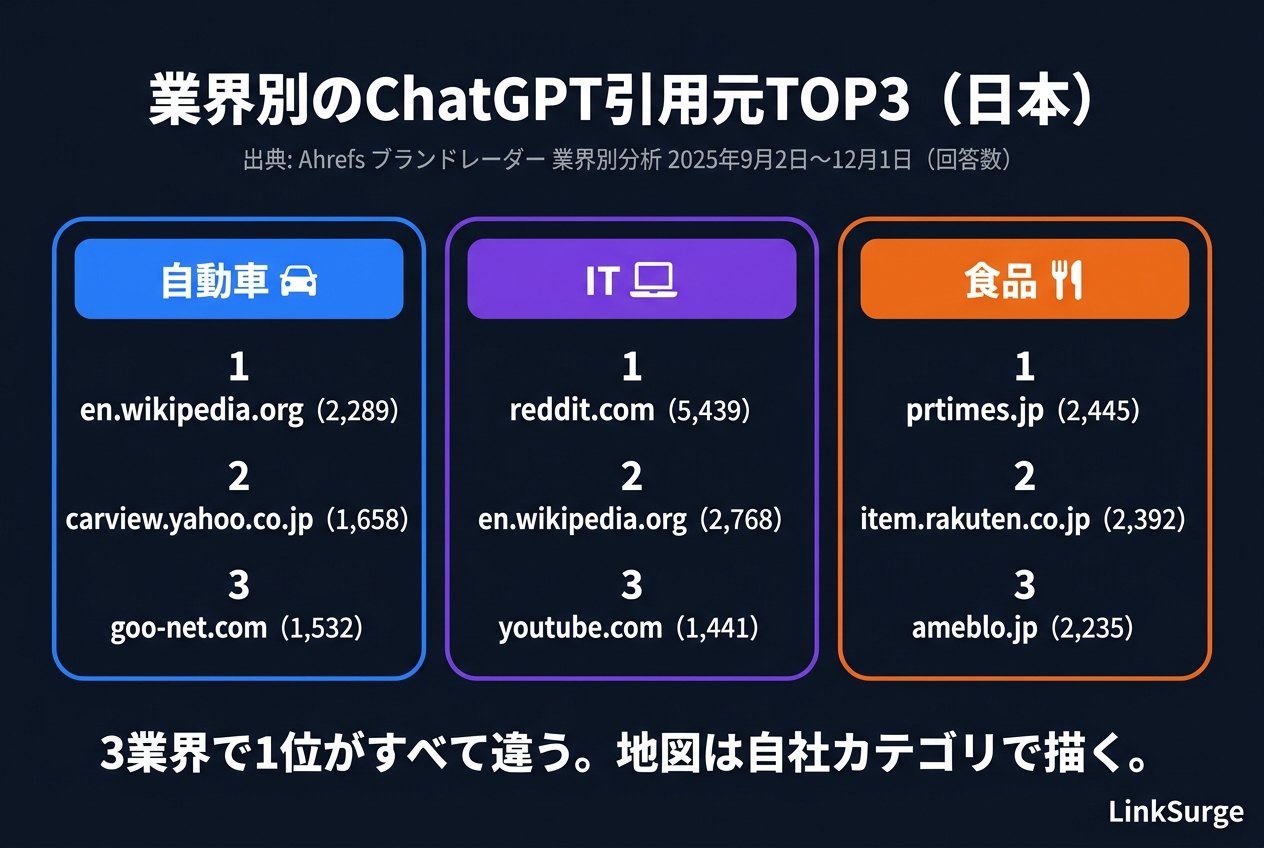
全体ランキングだけを見ていると見落とすのが、業界ごとの違いです。Ahrefsが2025年11月30日に公開した業界別分析は、2025年9月2日から12月1日の90日間、自動車・IT・食品の3業界について、AI Overviews・AIモード・ChatGPTの引用元を集計したものです。ChatGPTの結果だけを抜き出します。
| 業界 | 1位 | 2位 | 3位 |
|:---|:---|:---|:---|
| 自動車 | en.wikipedia.org(2,289) | carview.yahoo.co.jp(1,658) | goo-net.com(1,532) |
| IT | reddit.com(5,439) | en.wikipedia.org(2,768) | youtube.com(1,441) |
| 食品 | prtimes.jp(2,445) | item.rakuten.co.jp(2,392) | ameblo.jp(2,235) |
面白いのは、3業界で1位がすべて違うことです。ITではエンジニアの議論が集まるRedditが圧倒的で、食品ではプレスリリースと楽天市場の商品ページが上位に来ます。自動車では英語版Wikipediaとカービュー、グーネットという専門メディアが並びました。
つまり、「ChatGPTはRedditを引用する」も「PR TIMESを引用する」も、業界を限定しなければ正確ではありません。自社カテゴリの地図は、自社カテゴリの質問で引いた結果からしか描けないということです。
同じ分析では、AIモードは3業界すべてでYouTubeが1位、AI Overviewsも自動車以外でYouTubeが1位でした。Google系とChatGPTでは主食がまったく違います。
> 参考・引用:
> [2025年AI検索トレンド分析|Ahrefsブランドレーダーで見る業界別引用傾向 - Ahrefs](https://ahrefs.com/blog/ja/2025-ahrefs-brand-radar-ai-search-analysis/)
---
## 3. なぜ英語版Wikipediaが日本語版より上位なのか
ここが日本語のChatGPT対策で最も見過ごされている論点です。日本語で質問しているのに、引用元の上位に英語版Wikipediaが入り、日本語版Wikipediaは入らない。6月版でも4月版でも、2025年のデータでも同じ現象が出ています。
Ahrefsは6月版の解説で、ChatGPTが元のクエリを英語に展開して検索している可能性を挙げています。私が別の観測データと突き合わせても、この仮説は筋が通っています。MJ Cachónが2026年8月にOpenAIのAPI経由で723回の実行を分析したブランド系プロンプトの調査では、サブクエリ全体の8.9%、国際的なブランドでは27.3%に英語語彙が含まれていました。
ChatGPTが日本語の質問を内部で英語のサブクエリに分解しているなら、日本語だけで書かれたサイトはそのサブクエリからは見つかりません。逆に、英語の要約ページや英語版を持つサイトは、日本語の質問に対する回答の材料になる経路が1本増えます。
### 実務での対応
- 主要ページに英語の要約(見出しと結論だけでも)を用意し、hreflangで日本語版と紐づける
- 固有名詞は日本語表記と英語表記の両方を本文に書く(社名、製品名、技術用語)
- 英語版Wikipediaに自社や自社カテゴリの項目があるか確認し、なければ第三者による作成を待つのではなく、引用可能な一次情報(プレスリリース、調査)を英語でも出す
ファンアウトの仕組みと英語混在の実測は「[ChatGPTのクエリファンアウトは今どうなっているか](/blog/chatgpt-query-fanout-hidden-2026/)」で解説しています。
> 参考・引用:
> [AI が引用する日本のドメインランキング 2026 年 6 月版 - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
> [A study of query fan-out in ChatGPT using brand searches - MJ Cachón](https://www.mjcachon.com/en/blog/study-query-fan-out-chatgpt-brand/)
---
{{linksurge-card}}
## 4. 引用元の約67%は影響できない。残りの32.3%にどう集中するか
引用元の地図を描いたら、次は「そのうちどこに手が届くか」を切り分けます。Ahrefsが2025年10月28日に公開した分析は、2025年9月のChatGPTの上位1,000引用URLをページタイプ別に分類したものです(英語圏データ)。
| ページタイプ | 構成比 | 影響できるか |
|:---|---:|:---|
| Wikipedia | 29.7% | 直接は不可 |
| ホームページ・ランディングページ | 23.8% | 自社サイトなら可 |
| 教育コンテンツ | 19.4% | 可 |
| アプリストア | 6.6% | 直接は不可 |
| レビュー | 5.8% | 促進は可 |
| ニュース・メディア | 5.2% | 働きかけは可 |
| ブログ・記事 | 1.9% | 可 |
| その他 | 10.5% | — |
Ahrefsはこのうち教育コンテンツ・レビュー・ニュース・ブログの32.3%を「影響できる引用」とし、直接影響できないグループを「おおむね3分の2(約67%)」と示しています。表の各区分はAhrefsの分類をそのまま転記したもので、区分に重複があるため合計は100%を超え、約67%は表の単純な補集合ではありません。「影響できるのは3分の1」という整理として読んでください。
私はこの切り分けに一つ補足を加えたいと思います。ホームページの23.8%は、他社のホームページには影響できませんが、自社のホームページは自分で整えられます。ChatGPTのファンアウトではブランド系プロンプトの16.6%が自社ドメインを名指しした検索になっていますから、公式サイトのトップページと主要ページが「何を提供している誰なのか」を明確に示していることは、この23.8%を取りに行く施策になります。
日本市場に当てはめると、影響できる領域は次のように読み替えられます。
- **教育コンテンツ** — 自社ブログ、noteでの解説記事、ITmediaやマイナビニュースへの寄稿
- **レビュー** — 楽天市場・Amazonのレビュー、比較サイト、Yahoo!知恵袋での回答
- **ニュース** — PR TIMESのプレスリリース、業界メディアの記事
- **ホームページ** — 自社公式サイトの構造
> 参考・引用:
> [ChatGPT's most cited pages - Ahrefs](https://ahrefs.com/blog/chatgpts-most-cited-pages)
---
## 5. 他のAI検索との違い:ChatGPTだけが英語圏ソースを混ぜる
ChatGPT対策を考えるとき、Google AI OverviewsやPerplexityと同じ施策で済むと考えると外します。Ahrefsの2026年4月版で、各AI検索の日本語引用元TOP3を並べます。
| AI検索 | 1位 | 2位 | 3位 |
|:---|:---|:---|:---|
| ChatGPT | ameblo.jp | prtimes.jp | en.wikipedia.org |
| Google AIモード | youtube.com | google.com | instagram.com |
| Google AI Overviews | youtube.com | ja.wikipedia.org | note.com |
| Perplexity | youtube.com | ja.wikipedia.org | note.com |
| Copilot | ja.wikipedia.org | note.com | ameblo.jp |
Google系とPerplexityはYouTubeと日本語版Wikipediaを中心に据え、CopilotはWikipedia日本語版とnoteです。ChatGPTだけがプレスリリースと英語版Wikipediaを上位に置いています。この違いは、各社が使うインデックスと取得の仕組みの違いから来ていると考えられます。ChatGPTの三層インデックスについては「[ChatGPT検索の内部構造](/blog/chatgpt-search-architecture-2026/)」をご覧ください。
実務上の結論は、AI媒体ごとに引用元を分けて記録することです。ChatGPTで引用されていてもAI Overviewsでは引用されない、あるいはその逆は珍しくありません。[LinkSurge](https://linksurge.jp/)のGEOモニタリングでは、ChatGPT Search・Gemini・Google AI Overviews・Claude・Perplexityの5媒体それぞれで、監視クエリに対する自社の言及有無と引用URLを媒体別に記録できます。
> 参考・引用:
> [AI 検索が引用するドメイン TOP 10【2026 年 4 月最新版】 - Ahrefs](https://ahrefs.com/blog/ja/brand-radar-top-10-cited-domains-2026-update/)
---
## 6. 自社カテゴリの引用元マップを描く手順
ここまでの内容を落とし込みます。全体ランキングは参考に留め、自社カテゴリの地図を自分で描く手順です。
1. **質問を20〜30本設計する** — 「カテゴリ名 おすすめ」「A B 比較」「用途 向け 選び方」など、絞り込み系を中心に
2. **ChatGPTで各質問を3回以上実行し、引用URLを記録する** — 回答は実行ごとに変わるため、1回では偏る
3. **引用URLをドメイン別に集計し、5分類する** — 参照ソース(Wikipedia等)、プレスリリース、UGC・ブログ(note・Ameblo・知恵袋・Reddit)、EC・レビュー(楽天市場・Amazon)、業界メディア
4. **競合が引用されていて自社がいないドメインを優先順位付けする** — 影響できる領域(教育・レビュー・ニュース・自社サイト)に絞る
5. **月1回、同じ質問群で再計測する** — 順位が3か月で入れ替わる前提で、地図を更新し続ける
手順2と5を手作業で続けるのは負担が大きいので、私たちは監視クエリを登録して自動で記録する方法を採っています。媒体別の記録があれば、「ChatGPTではPR TIMESが効いたが、AI Overviewsではnoteが効いた」といった違いも見えてきます。
対策の全体像は「[ChatGPTに引用される方法 完全ガイド](/blog/chatgpt-geo-complete-guide-2026/)」を、PR TIMES・note・UGCそれぞれの使い方は「[PR TIMES・note・Yahoo!知恵袋をChatGPT引用に使う方法](/blog/chatgpt-press-release-note-ugc-2026/)」をご覧ください。
---
## よくある質問(FAQ)
### ChatGPTが日本語で最も引用するドメインはどこですか?
Ahrefsの2026年6月版データでは、1位がReddit、2位がPR TIMES、3位がAmeblo、4位が英語版Wikipedia、5位がnoteでした。ただし4月版では1位がAmeblo、Redditは8位であり、順位は数か月で入れ替わります。顔ぶれとして安定しているのはReddit、英語版Wikipedia、Ameblo、PR TIMES、noteの5つです。
### 業界によってChatGPTの引用元は変わりますか?
変わります。Ahrefsの2025年9〜12月の業界別分析では、IT業界のChatGPT引用元1位はReddit(5,439回答)、食品業界はPR TIMES(2,445回答)、自動車業界は英語版Wikipedia(2,289回答)でした。全体ランキングではなく、自社カテゴリの質問で実際に引用されるドメインを確認する必要があります。
### なぜ日本語の質問なのに英語版Wikipediaが引用されるのですか?
Ahrefsは、ChatGPTが日本語の質問を内部で英語のサブクエリに展開している可能性を指摘しています。MJ Cachónの2026年8月の調査でも、国際的なブランドではサブクエリの27.3%に英語語彙が含まれていました。日本語だけのサイトは英語のサブクエリから見つからないため、主要ページの英語要約や固有名詞の英語表記を用意することが対策になります。
### ChatGPTの引用元のうち、自社で影響できるのはどのくらいですか?
Ahrefsの2025年9月の英語圏データでは、ChatGPTの上位1,000引用URLのうち直接影響できるのは教育コンテンツ・レビュー・ニュース・ブログの32.3%で、Ahrefsは残る約67%(Wikipedia 29.7%、ホームページ 23.8%、アプリストア 6.6% が主な区分)を直接影響できない領域と整理しています。ただしホームページ(23.8%)のうち自社サイトは自分で整えられるため、公式サイトの構造改善は取りに行ける施策です。
### ChatGPTとGoogle AI Overviewsで引用元は同じですか?
異なります。Ahrefsの2026年4月版では、ChatGPTの上位はAmeblo・PR TIMES・英語版Wikipediaでしたが、Google AI OverviewsはYouTube・日本語版Wikipedia・note、AIモードはYouTube・Google・Instagramでした。AI媒体ごとに引用元を分けて記録し、媒体別に施策を組む必要があります。
---
## まとめ:全体ランキングを追わず、自社カテゴリの地図を描く
ChatGPTが日本語で引用するドメインは、英語圏の参照ソースと日本の発信媒体が混ざった二層構造で、顔ぶれは安定していても順位は3か月で入れ替わります。業界ごとに主食が違い、上位1,000引用のうち直接影響できるのは3分の1です。
だからこそ、やるべきことは全体ランキングへの最適化ではなく、自社カテゴリの質問で誰が引用されているかを記録し、影響できる領域(教育コンテンツ・レビュー・ニュース・自社サイト)と英語の受け皿に施策を集中させることです。そして地図は月1回更新してください。
LinkSurgeの[GEOモニタリング](https://linksurge.jp/geo)では、ChatGPT Searchを含む5媒体で監視クエリごとの引用URLを媒体別に記録し、競合との比較まで確認できます。引用元マップの初回作成と月次更新に、あわせてお使いください。
---
## ChatGPTの引用元は4日で86%動く — 2026年8月のReddit急落で分かった変動の実態と、変動を前提にした媒体分散の設計
> URL: https://linksurge.jp/blog/chatgpt-citation-volatility-2026/
> Date: 2026-09-08 | Category: AIO | Author: 緒方亜朗
> Tags: ChatGPT対策, 引用変動, Reddit, Promptwatch, Petra Labs, GEO, 定点観測, AI検索最適化
## この記事の結論:引用元は数日で入れ替わる。対策は「当てる」ではなく「分散して記録する」
2026年8月の半ば、私が定点で追っていたクエリ群で、ChatGPTの回答からRedditのリンクがほぼ消えました。最初は計測側の不具合を疑いましたが、複数の観測データが同じ動きを示していました。この出来事から学べる要点は次の5つです。
1. **Redditの引用シェアは4日間で86%低下した** — Promptwatchの計測では、ChatGPT SearchでのRedditの引用シェアは2026年7月18日〜8月7日に3.8%で安定していたのが、8月8日に2%台へ下がり、8月14日に1%未満、8月14〜17日の平均で0.5%になりました
2. **社会系プラットフォーム全体が同時に減った** — Petra Labsが8月9〜18日の126,500件のChatGPT回答を分析したところ、8月14日を境にYouTubeが88%、Redditが81%、TikTokが72%、LinkedInが36%、Facebookが28%減っていました
3. **引用は自社サイトとドキュメントに移った** — 同時期の観測では、ヘルプセンター・製品ドキュメントが2%から32%へ、大手企業サイトが4%から18%へ、アプリマーケットプレイスが2%から17%へ増え、小規模サイト・ブログは66%から32%に減りました
4. **推奨されるブランドは変わらなかった** — Petra Labsは、引用元が入れ替わったにもかかわらずChatGPTが推奨するブランドはほぼ同じだったと報告し、これを「非常に稀で奇妙」と表現しています。引用元と推奨は別のレイヤーで動いています
5. **原因は未確定で、変動は初めてではない** — Promptwatchは「ソース選択の変化が有力だが、データ収集側の問題も排除できない」と留保しています。Redditの引用シェアは2025年10月から2026年1月にかけても半減しており、変動はChatGPTの常態です
以下では、時系列で何が起きたかを追い、変動を前提にした設計に落とし込みます。
---
## 1. 2026年8月に何が起きたか
### Promptwatchの計測
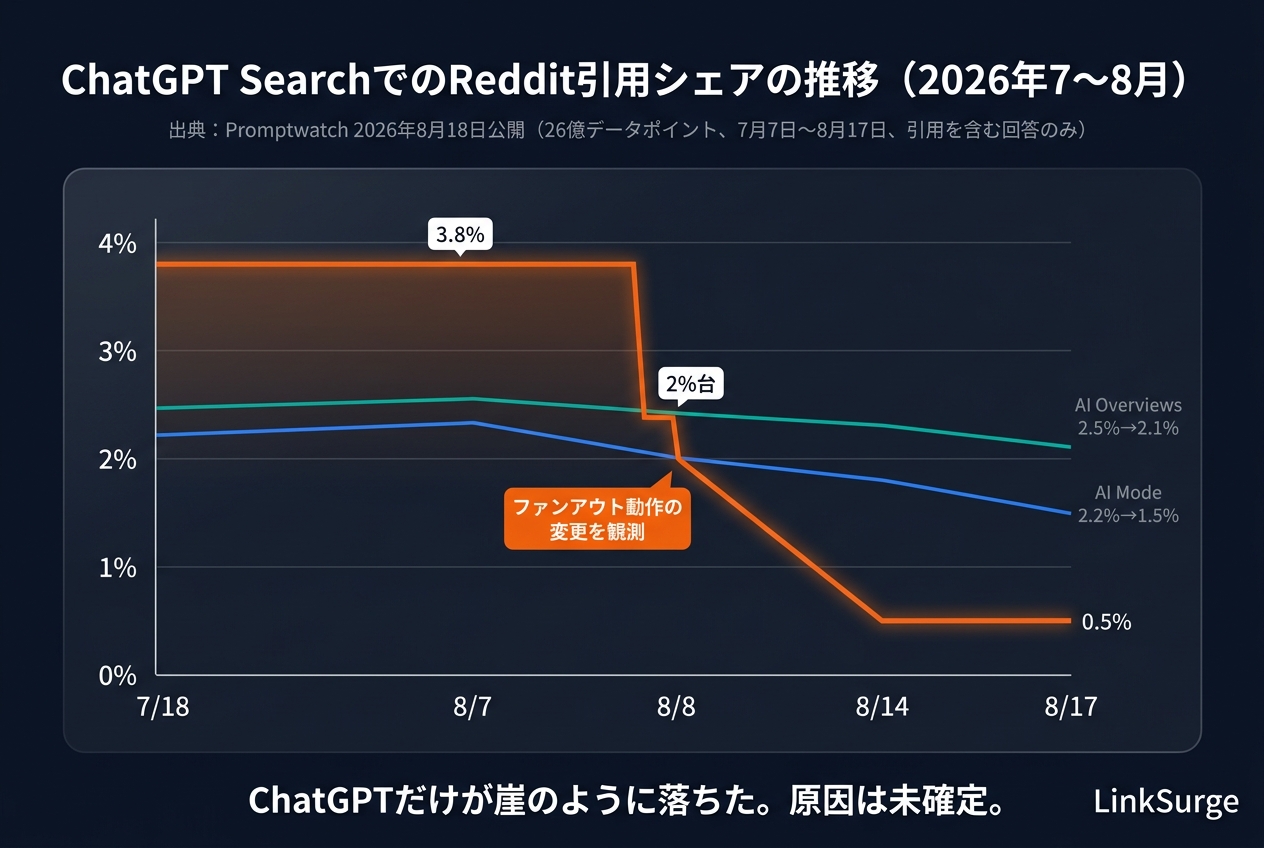
Promptwatchは2026年8月18日に、ChatGPT・Google AI Overviews・Google AI Modeの実際のUIから収集した26億以上のデータポイントをもとに、Redditの引用シェアの推移を公開しました。対象期間は2026年7月7日から8月17日、少なくとも1つの引用を含む回答が集計対象です。
| 期間 | ChatGPT SearchでのReddit引用シェア |
|:---|---:|
| 7月18日〜8月7日 | 3.8%(安定) |
| 8月8日 | 3%台から2%台中盤へ低下 |
| 8月14日 | 1%未満に急落 |
| 8月14〜17日の平均 | 0.5%(前期比86%低下) |
同じ期間のGoogle側は緩やかでした。AI Overviewsは7月初旬の2.5%から8月に2.1%へ、AI Modeは2.2%から1.5%へ下がりました(Promptwatchが丸め前の値から算出した相対低下はそれぞれ11.3%、30.5%)。ChatGPTだけが崖のように落ちています。
Promptwatchは、8月8日に「ChatGPT Searchがクエリファンアウトの動作を変更した」点にも触れています。[Lily Rayが同時期に観測した](https://lilyraynyc.substack.com/p/what-we-can-learn-from-evolving-chatgpt) `site:` 演算子の急増(0.3%から約23%)とあわせて読むと、ファンアウトの仕様変更と引用元の変化が同じタイミングで起きたことになります。ファンアウト側の変化は「[ChatGPTのクエリファンアウトは今どうなっているか](/blog/chatgpt-query-fanout-hidden-2026/)」で扱っています。
### Petra Labsの分析
Petra Labsは2026年8月9日から18日の126,500件のChatGPT回答を分析し、8月14日を境に社会系プラットフォームの引用が一斉に減ったことを報告しました。
| プラットフォーム | 8月中旬の減少率 |
|:---|---:|
| YouTube | −88% |
| Reddit | −81% |
| TikTok | −72% |
| LinkedIn | −36% |
| Facebook | −28% |
Redditだけの話ではなく、動画・SNS・専門職ネットワークを含めた「第三者の投稿」全体が引用されにくくなった、というのがこの分析の示すところです。
> 参考・引用:
> [Reddit Citations Are Dropping in ChatGPT - Promptwatch](https://promptwatch.com/data/reddit-citations-are-dropping-in-chatgpt)
> [Reddit's ChatGPT Search citations fell 86% in four days - Search Engine Land](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473)
> [ChatGPT slashes citations from Reddit, YouTube, and TikTok: Petra Labs - Adgully](https://www.adgully.com/post/19605/chatgpt-slashes-citations-from-reddit-youtube-and-tiktok-petra-labs)
---
## 2. 引用はどこへ移ったのか
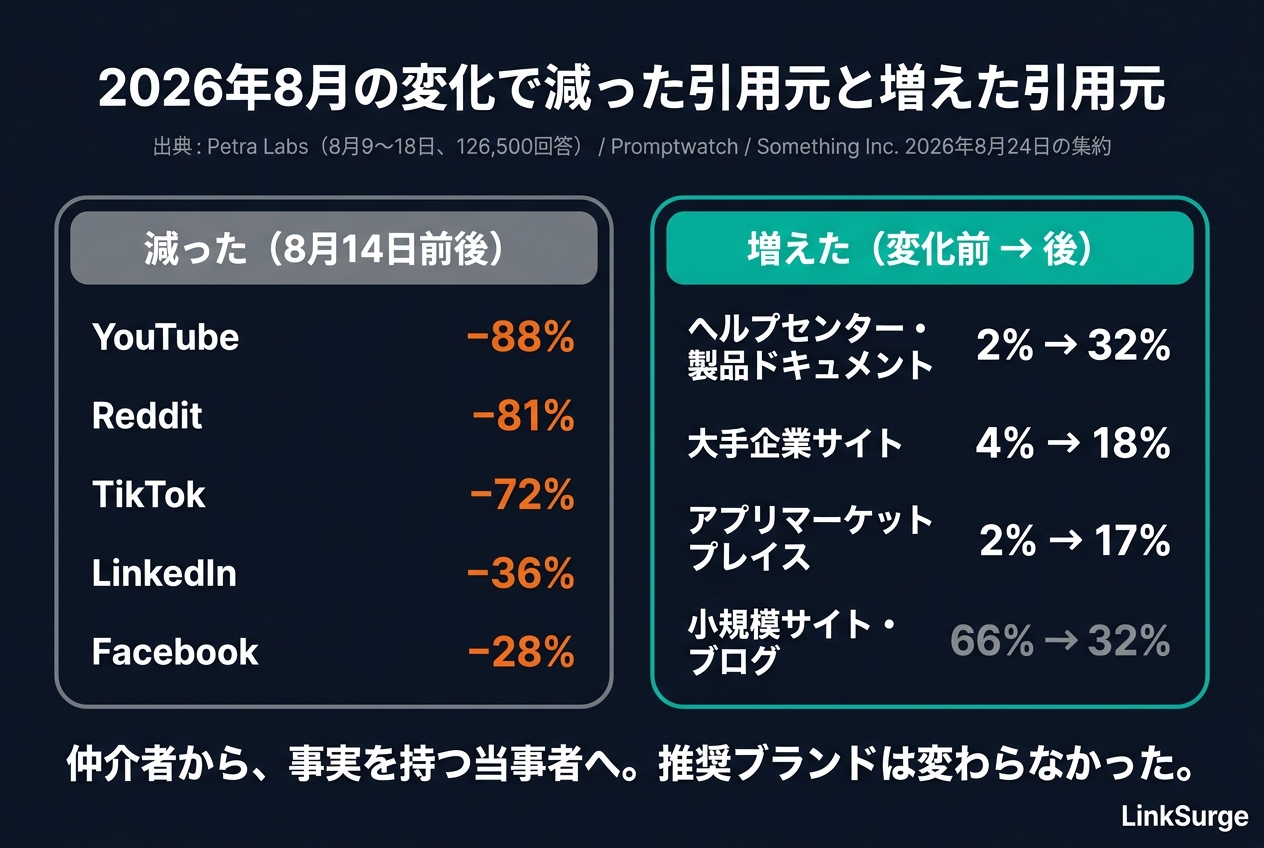
減った分はどこかへ行ったはずです。Petra LabsとPromptwatchのデータ、およびモデルバージョン間の比較分析をまとめたSomething Inc.の2026年8月24日の記事は、増減を次のように整理しています。
| 引用元の種類 | 変化前 | 変化後 |
|:---|---:|---:|
| ヘルプセンター・製品ドキュメント | 2% | 32% |
| 大手企業サイト(Salesforce など) | 4% | 18% |
| アプリマーケットプレイス | 2% | 17% |
| 小規模サイト・ブログ | 66% | 32% |
表は主要4カテゴリのみを抜粋したもので、合計は変化前74%・変化後99%です。残りは未掲載のカテゴリに分かれます。集計対象と期間は上記の出典に従います。
Petra Labs自身も、消えた引用の多くは出版社や別のSNSではなく、企業が運営する自社サイトに移ったと述べています。Inc.の報道では、レビューサイトも比率を伸ばしたとされています。
私がこの数字を見て考えたのは、「仲介者が減り、事実を持っている当事者が優先されるようになった」ということです。製品の仕様や料金について答えるなら、Redditのスレッドより公式のヘルプセンターの方が正確です。ChatGPT側がその判断に寄せたとすれば、自社サイトのドキュメント整備が引用対策として直接効く局面になったと言えます。
### 推奨ブランドは変わらなかった
もう一つ重要なのが、Petra Labsの「引用元が入れ替わったのに、推奨されるブランドはほぼ同じだった」という観測です。同社はこれを「非常に稀で奇妙」と表現しています。
この観測が示すのは、ChatGPTの回答には「どのブランドを推奨するか」と「その根拠としてどのURLを引用するか」の2つのレイヤーがあり、後者が動いても前者は動かないことがある、ということです。引用元だけを追いかけていると、ブランド推奨の実態を見誤ります。計測では言及と引用を分けて記録する必要があります。
> 参考・引用:
> [ChatGPT Citation Sources: Docs Replaced Reddit in August 2026 - Something Inc.](https://somethinginc.com/blog/chatgpt-citation-sources-docs-replaced-reddit/)
> ['Very rare and very curious': Reddit, YouTube and TikTok citations collapse, but ChatGPT still recommends the same brands - Mi3](https://www.mi-3.com.au/21-08-2026/very-rare-and-very-curious-chatgpt-guts-reddit-youtube-and-tiktok-citations-keeps)
> [ChatGPT Suddenly Cut Reddit Citations by 81 Percent - Inc.](https://www.inc.com/victoria-salves/chatgpt-suddenly-cut-reddit-citations-by-81-percent-new-report-found/91394126)
---
## 3. 変動は初めてではない
8月の急落は規模が大きかっただけで、ChatGPTの引用元が動くこと自体は珍しくありません。手元にある観測を時系列に並べます。
| 時期 | 観測 | 出典 |
|:---|:---|:---|
| 2025年5〜9月 | 日本語クエリでChatGPTの引用元1位はReddit(228,388回) | Ahrefs |
| 2025年10月→2026年1月 | Redditの引用シェアが2.02%から1.01%へ半減 | Conductor |
| 2026年1月→2月 | 5媒体35万件超の引用で、Redditの引用が77,111件から105,967件へ増加 | Wellows |
| 2026年4月版 | 日本語クエリでRedditはTOP5圏外(8位)、Amebloが1位 | Ahrefs |
| 2026年6月版 | Redditが8位から1位へ再浮上 | Ahrefs |
| 2026年8月8〜17日 | Reddit引用シェアが3.8%から0.5%へ | Promptwatch |
2025年5月から2026年8月までの約15か月で、半減、倍増、圏外、1位、急落を一巡しています。私が実務で使っている感覚は「ChatGPTの引用元は四半期ごとに別物になる」です。
日本語の引用元の顔ぶれと順位の動きは「[ChatGPTが日本語で引用するドメインの構造](/blog/chatgpt-citation-sources-japan-2026/)」で時系列にまとめています。
> 参考・引用:
> [Reddit AI Citation Decline - Conductor](https://www.conductor.com/academy/reddit-ai-citation-decline/)
> [Social Media in AI Citations (2026): Reddit & YouTube Dominate - Wellows](https://wellows.com/blog/social-media-ai-citations-report-2026/)
> [AI が引用する日本のドメインランキング 2026 年 6 月版 - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
---
{{linksurge-card}}
## 4. 原因について分かっていること、分かっていないこと
ここは慎重に書きます。8月の変化について、確定した原因は公表されていません。
**分かっていること**
- 変化は8月8日と8月14日の2段階で起きた(Promptwatch)
- 8月8日にChatGPT Searchのファンアウト動作が変わった(Promptwatch)。同時期に `site:` 演算子の使用が急増した(Lily Ray)
- Google AI OverviewsとAI Modeでは同じ規模の急落は起きていない(Promptwatch)
- 引用は自社サイト・ドキュメント・アプリストアへ移った(Petra Labs、Something Inc.)
**分かっていないこと**
- OpenAI側の意図。OpenAIはこの変化について公式に説明していません
- Redditのクローラー制限が原因かどうか。一部の解説はrobots.txtの変更を挙げていますが、私たちはこれを確認できていません
- 計測側の問題の可能性。Promptwatch自身が「データ収集の問題も排除できないため、数値は暫定的に扱うべき」と留保しています
原因が分からない以上、「Redditが戻るまで待つ」も「Redditは終わった」も根拠のない判断です。原因に依存しない設計に切り替える方が確実です。
---
## 5. 変動を前提にした設計
ここまでの内容を実務に落とし込みます。原則は「特定の媒体に当てにいかず、分散して記録する」です。
### 媒体を分散する
引用元を5分類し、それぞれに最低1つの施策を持ちます。
| 分類 | 日本語圏での例 | 施策 |
|:---|:---|:---|
| 自社サイト・ドキュメント | 公式サイト、ヘルプセンター、料金・仕様ページ | 見出し単位で完結する構造、仕様・料金・比較をテキストで明記 |
| プレスリリース・ニュース | PR TIMES、業界メディア | 調査名・サンプル数・期間・数値を本文に明記したリリース |
| 長文の一次体験 | note、Ameblo、自社ブログ | 実際に使った・試した記録を長文で |
| UGC・Q&A | Yahoo!知恵袋、Reddit、レビュー | 自作せず促進する。回答・レビューの依頼 |
| 動画 | YouTube | 説明文とチャプターにテキストで要点を書く |
8月の変化で増えたのは1行目です。減ったのは4〜5行目です。しかし6月には4行目のRedditが1位でした。どの行が次に効くかは分からないので、全行に薄く持つのが変動への備えになります。
### 自社ドキュメントを「事実の一次資料」にする
ヘルプセンターと製品ドキュメントが2%から32%に増えた事実は、当事者が持つ事実がそのまま引用候補になることを示しています。料金、仕様、対応範囲、更新履歴を、画像ではなくテキストで、見出し単位で完結させて置いてください。
### 言及と引用を分けて週次で記録する
推奨ブランドが変わらないのに引用元が入れ替わる以上、記録は2系統必要です。自社カテゴリの質問20〜30本に対して、(1)回答に自社が言及されたか、(2)引用URLはどのドメインか、を分けて週次で残します。回答は実行ごとに変わるため、複数回の記録が要ります。[LinkSurge](https://linksurge.jp/)のGEOモニタリングでは、ChatGPT Search・Gemini・Google AI Overviews・Claude・Perplexityの5媒体で、言及の有無と言及位置、引用URL、競合との比較を記録できます。8月の急落も、この定点記録があったから気付けました。
対策の全体像は「[ChatGPTに引用される方法 完全ガイド](/blog/chatgpt-geo-complete-guide-2026/)」を、UGC媒体の扱いは「[UGC × AI検索引用戦略](/blog/ugc-ai-search-brand-mentions-2026/)」をご覧ください。
---
## よくある質問(FAQ)
### 2026年8月にChatGPTのReddit引用はどのくらい減りましたか?
Promptwatchの計測では、ChatGPT SearchでのRedditの引用シェアは2026年7月18日〜8月7日の3.8%から、8月14〜17日の平均で0.5%へ、86%低下しました。Petra Labsの126,500件の回答分析でも、8月14日を境にRedditが81%、YouTubeが88%、TikTokが72%減っています。
### ChatGPTの引用はどこへ移ったのですか?
Petra LabsとPromptwatchのデータをまとめた分析では、ヘルプセンター・製品ドキュメントが2%から32%へ、大手企業サイトが4%から18%へ、アプリマーケットプレイスが2%から17%へ増え、小規模サイト・ブログは66%から32%に減りました。第三者の投稿から、事実を持つ当事者のサイトへ移った形です。
### Reddit引用が減った原因は何ですか?
確定していません。Promptwatchは「ChatGPTのソース選択の変化が有力候補だが、データ収集の問題も排除できない」と留保しています。8月8日にChatGPT Searchのファンアウト動作が変わったことは観測されていますが、OpenAIは公式に説明していません。原因に依存しない、媒体分散と定点観測の設計を推奨します。
### 引用元が変わると、ChatGPTが推奨するブランドも変わりますか?
必ずしも変わりません。Petra Labsは、2026年8月に引用元が入れ替わったにもかかわらず、ChatGPTが推奨するブランドはほぼ同じだったと報告しています。ブランドの推奨と引用URLは別のレイヤーで動くため、計測では言及の有無と引用元を分けて記録する必要があります。
### 変動が大きいなら、ChatGPT対策は無駄ではありませんか?
無駄ではありませんが、特定の媒体に賭ける対策は無駄になります。自社サイト・ドキュメント、プレスリリース、長文の一次体験、UGC、動画の5分類に薄く分散し、自社ドキュメントを事実の一次資料として整え、言及率と引用元を週次で記録する設計にすれば、次の変動が来ても対応の軸はぶれません。
---
## まとめ:次の変動は必ず来る。当てにいかず、分散して記録する
2026年8月の出来事は、ChatGPTの引用元が数日で入れ替わること、引用が第三者の投稿から当事者のサイトへ移りうること、そして引用元が動いても推奨ブランドは動かないことがあることを示しました。原因は確定していません。
だからこそ、施策は特定の媒体に当てにいくのではなく、5分類に分散し、自社ドキュメントを一次資料として整え、言及と引用を分けて週次で記録する形にしてください。次の変動が来たときに、それに最初に気付き、最初に調整できる体制が、変動の大きい環境での優位になります。
LinkSurgeの[GEOモニタリング](https://linksurge.jp/geo)では、ChatGPT Searchを含む5媒体で言及と引用元を定点で記録できます。自社ドキュメントの構造点検には[AI Ready診断](https://linksurge.jp/ai-ready)をあわせてお使いください。
---
## ChatGPTに引用される方法 完全ガイド2026 — 検索の仕組み・日本語の引用元・対策の全体像・計測まで
> URL: https://linksurge.jp/blog/chatgpt-geo-complete-guide-2026/
> Date: 2026-09-08 | Category: AIO | Author: 緒方亜朗
> Tags: ChatGPT対策, ChatGPT検索, GEO, LLMO, AI引用, OAI-SearchBot, クエリファンアウト, AI検索最適化
## この記事の結論:ChatGPTに引用されるための5つの前提
ChatGPT対策の相談を受けるたびに、私は最初に「Googleと同じ発想を一度捨ててください」とお願いしています。ChatGPTの検索は、順位表のない世界で、1つの質問を複数の内部検索に分解し、取得した数十ページの中から数本だけを引用します。この記事はChatGPT対策シリーズのハブとして、仕組みから計測までの全体像をまとめたものです。OpenAIの公式資料と、Ahrefs・Peec AI・Profound・Lily Rayらが2026年に公開した一次データに基づく要点は次の5つです。
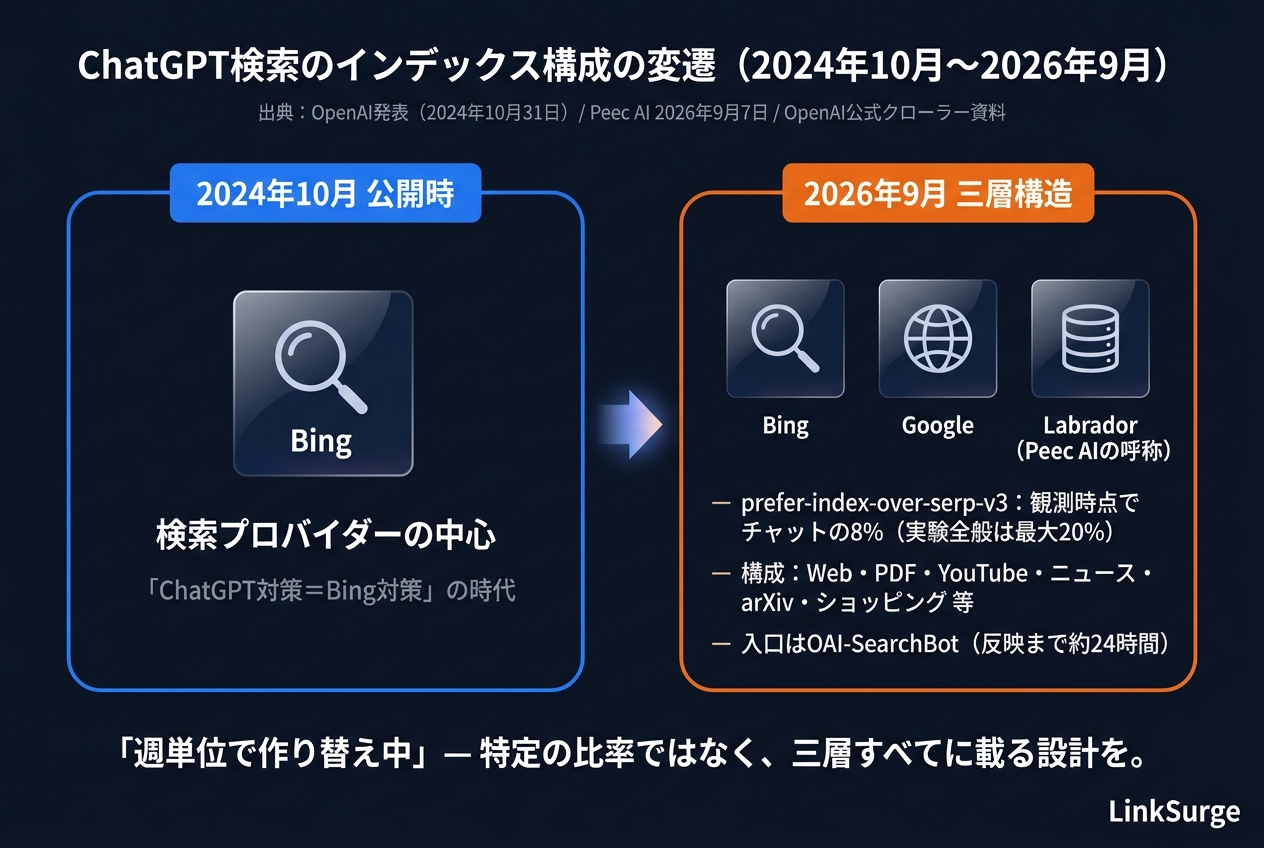
1. **ChatGPT検索は三層のインデックスで動いている** — 2024年10月の公開時はBingを主な検索基盤としていましたが、2026年9月のPeec AIの分析では、同社が「Labrador」と呼ぶOpenAI独自のインデックス(OpenAIは公式に確認していません)を外部検索より優先する実験が、観測時点でチャットの8%に適用されていました(同社によると実験全般の適用範囲は1桁台から最大20%)。Bing・Google・独自インデックスのすべてに載る状態を作るのが前提です
2. **1つの質問は平均7本以上の内部検索に分解される** — Lily Rayの2026年8月の観測では、単一クエリで処理される比率が94%から43.5%に下がり、1プロンプトあたりのファンアウトは2.17本から7.61本に増えました。しかも2026年半ばからこのサブクエリはブラウザから見えなくなっています
3. **日本語クエリの引用元は独特の構造を持つ** — Ahrefsの2026年6月版データでは、ChatGPTが日本語で引用するドメインの上位はReddit、PR TIMES、Ameblo、英語版Wikipedia、note、楽天市場でした。英語圏ソースとプレスリリース、UGCが並ぶこの構造は、他国のガイドをそのまま輸入できないことを意味します
4. **引用元は数日で入れ替わる** — 2026年8月、ChatGPT SearchでのRedditの引用シェアが4日間で86.4%低下しました。特定媒体への依存はそれ自体がリスクで、対策は「媒体分散」と「定点観測」を前提に組む必要があります
5. **対策は土台・構造・第三者言及・計測の4層** — OAI-SearchBotの許可とサーバーサイド描画、回答として抽出しやすい構造、PR TIMES・note・レビュー媒体での言及、そしてChatGPTでの言及率と引用元の週次記録。この4層を順に整えるのが、2026年9月時点で私が推奨する進め方です
以下では、各層を順に解説し、詳細は個別記事へ案内します。要点は動画でも解説しています。
{{youtube:huGy_h3GAms|ChatGPTに引用される方法 完全ガイド|三層インデックス・日本語の引用元・30日の順序}}
---
## 1. ChatGPT検索はどう動いているのか
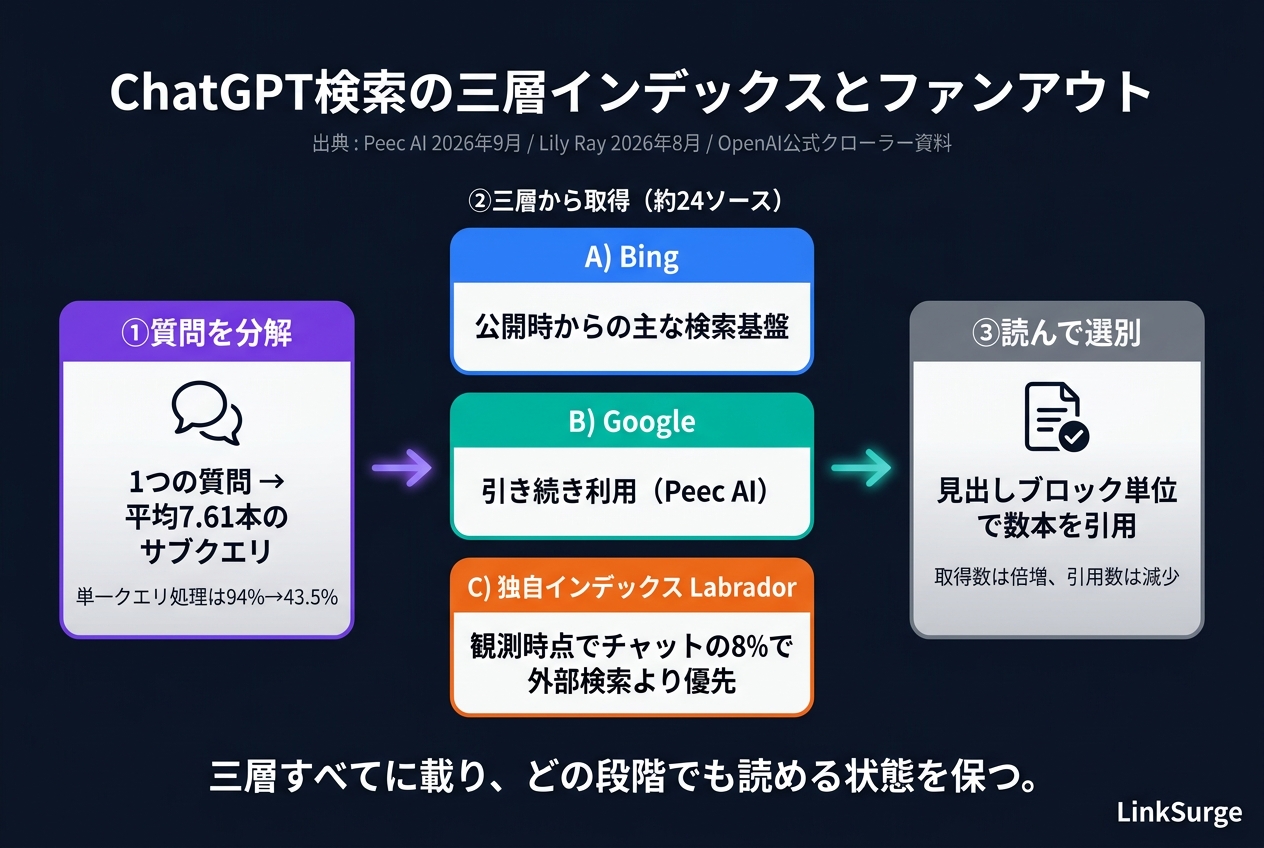
率直に言って、ChatGPT検索の内部は2026年に入ってから毎月のように変わっています。それでも、公開情報から確認できる骨格は3つに整理できます。
### 三層のインデックス
OpenAIは2024年10月31日にChatGPT searchを正式公開し、当初は検索プロバイダーとしてMicrosoft Bingを中心に使う構成でした。その後の変化を追ったPeec AIの2026年9月4日公開の分析によると、OpenAIは複数の垂直インデックスからなる独自インデックスを構築しており、Peec AIはこれを「Labrador」と呼んでいます(OpenAIが公式に確認した名称ではありません)。一般Web、PDF、YouTube、ニュース(1日以内・7日以内・それ以上で分類)、arXiv、Wikipedia、ローカル、金融、法律、医療、ショッピング、画像という構成で、`prefer-index-over-serp-v3` という実験が観測時点(2026年8月中旬)でチャットの8%に適用され、「外部検索結果より独自インデックスを優先」しているとされています。同社によると、こうした実験の適用範囲は1桁台から最大20%です。同じ分析は「GoogleとMicrosoftは依然として重要」であり、「システムは週単位で作り替えられている」とも述べています。
実務上の結論は単純です。Bingにインデックスされていること、Googleにインデックスされていること、そしてOAI-SearchBotがクロールできることの3つを同時に満たしておく必要があります。どれか1つに載っていれば十分、という状態ではありません。
### クエリファンアウト
ChatGPTはユーザーの質問をそのまま検索しません。複数の内部検索(サブクエリ)に分解し、それぞれの結果を束ねてから回答を生成します。この挙動は「クエリファンアウト」と呼ばれ、Google AI Modeでも同じ考え方が使われています。ChatGPT側の特徴は、2026年半ばのモデル更新でファンアウトの本数が大きく増えたことと、そのサブクエリがブラウザの応答から消えて見えなくなったことです。詳細は「[ChatGPTのクエリファンアウトは今どうなっているか](/blog/chatgpt-query-fanout-hidden-2026/)」で扱います。
### 取得と引用は別物
Lily Rayの観測では、モデル更新後に取得されるソース数が約12から約24に倍増した一方、実際に引用される数は逆方向に動いています。つまり、ChatGPTに「読まれる」ことと「引用される」ことの間には大きな差があります。読まれるための土台と、引用されるための構造は分けて考える必要があります。
内部構造の詳しい解説は「[ChatGPT検索の内部構造:Bing・Google・独自インデックスの三層](/blog/chatgpt-search-architecture-2026/)」をご覧ください。
> 参考・引用:
> [ChatGPT built its own search index - Peec AI](https://peec.ai/blog/chatgpt-built-its-own-search-index)
> [What We Can Learn from Evolving ChatGPT Fan-Out Queries - Lily Ray](https://lilyraynyc.substack.com/p/what-we-can-learn-from-evolving-chatgpt)
> [ChatGPT search officially launches - Search Engine Land](https://searchengineland.com/chatgpt-search-officially-launches-447919)
---
## 2. 土台:OpenAIのクローラーに読ませる
ここが整っていなければ、後の施策はすべて無駄になります。OpenAIは公式ドキュメントで4種類のボットを公開しています。
| ボット | 用途 | robots.txtでの扱い |
|:---|:---|:---|
| OAI-SearchBot | ChatGPTの検索結果にサイトを表示するためのクロール | 許可すると検索結果に表示される。拒否するとナビゲーション用リンクとして出る可能性はあるが、検索回答には出ない |
| GPTBot | 基盤モデルの学習にコンテンツを使う可能性があるクロール | 拒否すれば学習利用を避けられる。検索表示とは独立 |
| ChatGPT-User | ユーザーがChatGPTやカスタムGPTで質問したときのページ取得 | ユーザー起動のため、robots.txtの規則が適用されない場合がある |
| OAI-AdsBot | 広告のランディングページの安全性・関連性の検証 | 広告出稿時のみ関係する |
重要なのは、「学習には使わせたくないが検索には出たい」という要望が、GPTBotを拒否しOAI-SearchBotを許可することで実現できる点です。OpenAIはrobots.txtの更新が反映されるまで約24時間かかると案内しており、各ボットのIPレンジもJSONで公開しています。
### サーバーサイド描画が前提になる
OpenAIの公式資料はクローラーの用途とrobots.txt、IPレンジを説明していますが、JavaScriptを実行するかどうかは明記していません。したがって、重要な本文がクライアント側のJavaScriptでしか描画されない構成は、取得時に本文が読まれないリスクを抱えます。Next.jsやNuxtのようなフレームワークでも、サーバーサイド描画か事前描画で本文を初期HTMLに含めておくのが安全です。画像に埋め込んだ数値や表も、テキストとして書いておくことを推奨します。
Cloudflareが提唱するAIエージェント向けのMarkdown配信のような、機械可読な形式を用意する動きについては「[Cloudflare Markdown for AgentsとAI対策の新常識](/blog/cloudflare-markdown-for-agents-2026/)」で扱っています。
> 参考・引用:
> [Overview of OpenAI Crawlers - OpenAI](https://developers.openai.com/api/docs/bots)
---
## 3. 構造:回答として抽出しやすい形にする
土台ができたら、次は「取得された数十ページの中から選ばれる」ための構造です。ここは私たちが自社で一次調査を続けている領域なので、確認できていることと、まだ確認できていないことを分けて書きます。
### 確認できていること
当社がGoogle AI Overviewsの実引用277件を解析したところ、引用の69.3%はリード文以外の見出しブロックから発生していました。この調査の対象はGoogle AI Overviewsであり、ChatGPT Searchを直接測定したものではありません。ただしChatGPTも取得したページの本文を読んで引用箇所を選ぶ以上、各見出しの直下に40〜60語で完結する回答を置く構造は同じ方向に効くと私たちは考えており、ChatGPTでの検証はこのシリーズの計測記事で扱う予定です。詳細は「[AI検索は記事のどこを引用するのか](/blog/ai-citation-block-position-research-2026/)」をご覧ください。
MJ Cachónが2026年8月にOpenAIのAPI経由で723回の実行を分析したブランド系プロンプトの調査では、サブクエリの23.8%に完全一致のクォートが、19.6%に年号が含まれていました。固有名詞と年号を本文と見出しに明示しておくことは、ファンアウトの受け皿として合理的です。
### 確認できていないこと
FAQスキーマなどの構造化データがChatGPTでの引用を増やすという効果は、当社の対照実験では確認できていません。schema追加前後のChatGPTの変化(+2.2%)はノイズと区別できませんでした。構造化データは検索エンジン向けの目的が定まっている場合に実装し、AI引用の切り札として扱わないことを推奨します。経緯は「[「FAQスキーマで引用率3.2倍」は本当か](/blog/faq-schema-ai-citation-myth-2026/)」で公開しています。
見出し設計とAtomic Answersの書き方は「[LLMOとは何か?初心者向け完全ガイド](/blog/llmo-guide-beginners-2026/)」にまとめています。
> 参考・引用:
> [A study of query fan-out in ChatGPT using brand searches - MJ Cachón](https://www.mjcachon.com/en/blog/study-query-fan-out-chatgpt-brand/)
---
## 4. 第三者言及:日本語の引用元構造に合わせる
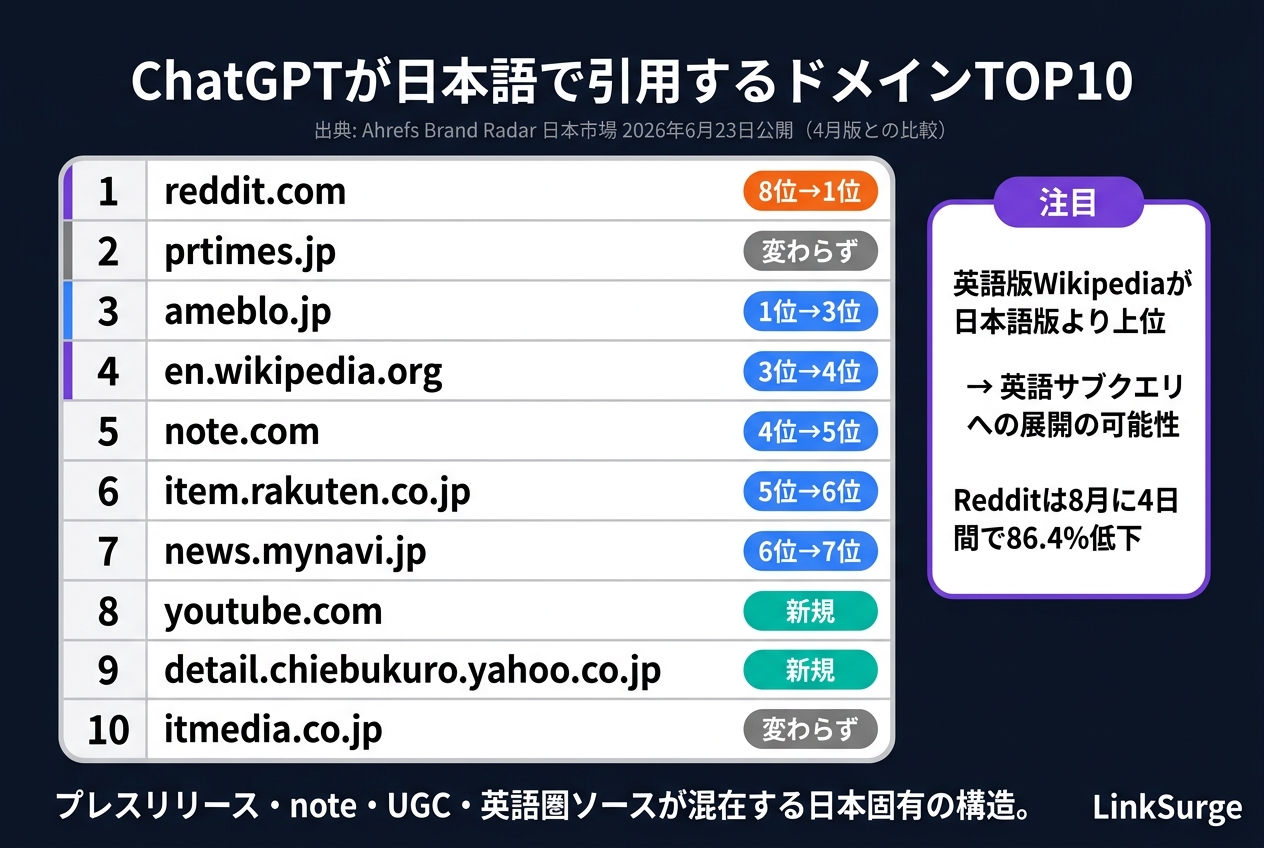
ここがChatGPT対策で最も日本固有の部分です。Ahrefsが2026年6月23日に公開した日本市場のデータでは、ChatGPTが引用するドメインの上位は次の通りでした。
| 順位 | ドメイン | 4月版からの変動 |
|:---|:---|:---|
| 1 | reddit.com | 8位から上昇 |
| 2 | prtimes.jp | 変わらず |
| 3 | ameblo.jp | 1位から下降 |
| 4 | en.wikipedia.org | 3位から下降 |
| 5 | note.com | 4位から下降 |
| 6 | item.rakuten.co.jp | 5位から下降 |
| 7 | news.mynavi.jp | 6位から下降 |
| 8 | youtube.com | 新規 |
| 9 | detail.chiebukuro.yahoo.co.jp | 新規 |
| 10 | itmedia.co.jp | 変わらず |
驚いたのは、英語版Wikipediaが日本語版より上位にあることです。Ahrefsはこの理由として、ChatGPTが日本語の質問を内部で英語のサブクエリに展開している可能性を挙げています。MJ Cachónの調査でも、国際的なブランドではサブクエリの27.3%に英語語彙が含まれていました。日本語だけで書かれたサイトは、英語のサブクエリからは見つからないことになります。
### 日本語で効く3つの媒体
- **PR TIMES** — 4月版でも6月版でも2位を維持しています。プレスリリースは日付・固有名詞・数値が揃った一次情報であり、ChatGPTの引用元として安定しています
- **note・Ameblo** — 個人や企業の一次体験が長文で書かれている媒体です。自社の知見をnoteで公開する、または自社に言及した記事を増やす施策は、日本語圏でのChatGPT対策として直接効きます
- **楽天市場・Yahoo!知恵袋** — 商品ページとQ&Aです。ECであればモール内の商品情報の正確さが、サービスであれば知恵袋での回答がそのまま引用候補になります
Redditについては、6月に1位へ急浮上した直後の8月に、Promptwatchのデータで引用シェアが4日間で86.4%低下しました(原因は未確定)。Petra Labsが2026年8月9〜18日の126,500件のChatGPT回答を分析したところ、同時期にYouTube・Reddit・TikTokの引用が7〜9割減っていました。UGC媒体は効く時は大きく効きますが、1つの媒体に寄せる設計は避けてください。8月の変化の詳細と変動を前提にした設計は「[ChatGPTの引用元は4日で86%動く](/blog/chatgpt-citation-volatility-2026/)」で、日本語の引用元の時系列・業界別の構造は「[ChatGPTが日本語で引用するドメインの構造](/blog/chatgpt-citation-sources-japan-2026/)」で、PR TIMES・note・知恵袋の具体的な使い方は「[PR TIMES・note・Yahoo!知恵袋をChatGPT引用に使う方法](/blog/chatgpt-press-release-note-ugc-2026/)」で扱っています。UGCの扱いは「[UGC × AI検索引用戦略](/blog/ugc-ai-search-brand-mentions-2026/)」で詳しく解説しています。
### ブランド名の一貫性
Lily Rayの観測では、モデル更新後にファンアウト内で `site:` 演算子が使われる比率が0.3%から約23%に跳ね上がりました。MJ Cachónの調査では、サブクエリの69.8%は通常検索ですが、`site:` 付きサブクエリ(全体の30.2%)の55.1%は自社ドメインを対象にしており、全体の16.6%が自社ドメインの名指し検索でした。ブランド系プロンプトでは、公式サイトを対象にした検索が一定割合で発生するということです。公式サイトが「どのページが公式で、何を提供しているか」を明確に示していることが、ここで効いてきます。エンティティとしての一貫性は「[エンティティ権威がAI検索可視性を決める](/blog/entity-authority-ai-search-2026/)」で扱っています。
> 参考・引用:
> [AI が引用する日本のドメインランキング 2026 年 6 月版 - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
> [AI 検索が引用するドメイン TOP 10【2026 年 4 月最新版】 - Ahrefs](https://ahrefs.com/blog/ja/brand-radar-top-10-cited-domains-2026-update/)
> [Reddit's ChatGPT Search citations fell 86% in four days - Search Engine Land](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473)
> [ChatGPT slashes citations from Reddit, YouTube, and TikTok: Petra Labs - Adgully](https://www.adgully.com/post/19605/chatgpt-slashes-citations-from-reddit-youtube-and-tiktok-petra-labs)
---
{{linksurge-card}}
## 5. ショッピングとブランド指名:商品が選ばれる条件
ECや商品を持つ企業にとって、ChatGPTのショッピング機能は別枠で考える必要があります。Profoundが2026年7月に公開した分析(2026年6月18〜25日、201,137プロンプト、812,190枚の商品カード)では、商品情報の87.3%はWebクロールから、12.7%はマーチャントが直接提供するフィードから取得されていました。1位に表示された商品カードは、4位以下と比べてレビュー数の中央値が787件対352件と2倍以上でした。
2025年9月に始まったChatGPT内での決済機能「Instant Checkout」は、米メディアの報道によると2026年3月に終了し、「発見はChatGPT、購入は各社のサイト」という形に戻っています。つまり商品ページの正確さと、レビュー数のような第三者の評価が、ChatGPTで選ばれる条件として残りました。
Z世代の54.3%が購買検討に生成AIを使い、それでも最も信頼する情報源は検索エンジンだという楽天の調査結果とあわせて読むと、「AIで絞られ、検索で確かめられる」導線の両方に出る必要があることが分かります。詳細は「[Z世代の54%が買う前にAIに聞く](/blog/gen-z-ai-shopping-search-trust-2026/)」をご覧ください。
> 参考・引用:
> [Breaking down how ChatGPT Shopping works behind the user experience - Profound](https://www.tryprofound.com/blog/chatgpt-shopping-end-to-end-breakdown)
> [OpenAI revamps shopping experience in ChatGPT after struggling with Instant Checkout offering - CNBC](https://www.cnbc.com/2026/03/24/openai-revamps-shopping-experience-in-chatgpt-after-instant-checkout.html)
> [楽天、Z世代における「生成AI利用に関する調査」結果を発表 - 楽天グループ株式会社](https://corp.rakuten.co.jp/news/press/2026/0904_01.html)
---
## 6. 計測:見えないファンアウトを、見える言及率に置き換える
ファンアウトが非表示になった今、「どのサブクエリで自社が拾われているか」を直接見ることは難しくなりました。代わりに追うべきは、自社カテゴリの質問に対するChatGPTの回答で、自社が言及・引用される比率と、誰が引用されているかです。
### 週次で記録する3つの指標
1. **言及率** — 自社カテゴリの質問20〜30本に対し、回答に自社名または自社URLが含まれた比率
2. **引用元ドメイン** — 回答に引用されたURLをドメイン別に集計し、レビュー媒体・プレスリリース・UGC・競合サイトに分類
3. **競合との比較** — 同じ質問群で競合が言及される比率との差
ChatGPTの回答は同じ質問でも実行ごとに変わるため、1回の確認ではなく複数回の記録が要ります。[LinkSurge](https://linksurge.jp/)のGEOモニタリングでは、ChatGPT Search・Gemini・Google AI Overviews・Claude・Perplexityの5媒体に監視クエリを登録し、言及の有無、言及位置、引用URL、競合ブランドとの比較を記録できます。私たちはこのシリーズの効果測定にも同じ仕組みを使っており、結果は後続の記事で公開していく予定です。
ファンアウトそのものを見たい場合は、OpenAIのResponses APIを使うと `action.queries` としてサブクエリを取得できます。手順は「[ChatGPTのクエリファンアウトは今どうなっているか](/blog/chatgpt-query-fanout-hidden-2026/)」で解説しています。
---
## 7. 30日で始めるChatGPT対策の順序
ここまでの内容を実行順に並べます。
| 週 | やること | 確認方法 |
|:---|:---|:---|
| 第1週 | robots.txtでOAI-SearchBotを許可、GPTBotの方針を決める。主要ページの本文が初期HTMLに含まれるか確認。BingとGoogleのインデックス状況を確認 | curlで取得したHTMLに本文があるか。Bing Webmaster Tools・Search Console |
| 第2週 | 自社カテゴリの質問20〜30本を設計し、ChatGPTでの言及率と引用元の初回記録を取る | GEOモニタリングまたは手動記録 |
| 第3週 | 主要ページの見出し直下に40〜60語の回答ブロックを置き、固有名詞と年号を明示する。英語の要約ページを用意するか検討する | 引用元の記録を再取得 |
| 第4週 | PR TIMES・note・レビュー媒体のうち、競合が引用されていて自社がいない媒体に働きかける | 引用元ドメインの変化を週次で追う |
シリーズの各記事は、この表の各行を深掘りする形で追加していきます。
---
## よくある質問(FAQ)
### ChatGPTに引用されるには何から始めればいいですか?
最初にrobots.txtでOAI-SearchBotを許可し、主要ページの本文がサーバーサイドで描画された初期HTMLに含まれているかを確認してください。OpenAIの公式ドキュメントでは、OAI-SearchBotを拒否したサイトは検索回答に表示されません。次に、BingとGoogleの両方にインデックスされていることを確認します。この土台が整って初めて、コンテンツ構造や第三者言及の施策が意味を持ちます。
### ChatGPTはBingとGoogleのどちらを使っていますか?
両方に加えて独自インデックスを使っています。Peec AIの2026年9月の分析では、同社が「Labrador」と呼ぶOpenAI独自のインデックス(OpenAIは公式に未確認)を外部検索結果より優先する実験 prefer-index-over-serp-v3 が観測時点でチャットの8%に適用されており、同時にGoogleとMicrosoftの検索も引き続き使われていると報告されています。どれか1つに載っていれば十分という状態ではなく、3つすべてに載る必要があります。
### 日本語のサイトがChatGPTに引用されにくいのはなぜですか?
Ahrefsの2026年6月の日本市場データでは、ChatGPTの引用元上位に英語版WikipediaやRedditが入っており、ChatGPTが日本語の質問を内部で英語のサブクエリに展開している可能性が指摘されています。日本語だけのサイトは英語のサブクエリからは見つかりません。一方で、PR TIMES、note、Ameblo、楽天市場といった日本語媒体も上位にあるため、これらでの言及を増やす施策は有効です。
### FAQスキーマや構造化データを入れればChatGPTに引用されますか?
当社の対照実験では、構造化データを追加した前後でChatGPTでの引用の変化はノイズと区別できませんでした。構造化データはリッチリザルトなど検索エンジン向けの目的がある場合に実装するものであり、ChatGPT対策の切り札としては扱わないことを推奨します。効果が確認できているのは、見出し単位で完結する回答ブロックと、固有名詞・年号の明示です。
### ChatGPTでの引用率はどうやって計測しますか?
自社カテゴリの質問を20〜30本設計し、ChatGPTの回答に自社名やURLが含まれる比率、引用されたURLのドメイン、競合の言及率を週次で記録します。回答は実行ごとに変わるため複数回の記録が必要です。LinkSurgeのGEOモニタリングのように、複数のAI媒体に監視クエリを登録して言及と引用元を自動で記録する仕組みを使うと、変動の大きさに振り回されずに済みます。
---
## まとめ:順位のない世界で、読まれて選ばれる状態をつくる
ChatGPTには順位表がありません。あるのは、三層のインデックスから取得された数十ページと、その中から選ばれた数本の引用です。選ばれるためには、まず読まれる土台を整え、次に見出し単位で完結する構造を作り、日本語の引用元構造に合わせて第三者の言及を増やし、最後に言及率と引用元を定点で記録する。この4層を順番に積むのが、2026年9月時点での最短ルートです。
引用元は数日で入れ替わり、インデックスは週単位で作り替えられています。だからこそ、一度きりの施策ではなく、記録しながら調整し続ける体制が要ります。このシリーズでは、内部構造、ファンアウト、日本語の引用元、ショッピング、計測設計を個別記事で掘り下げていきます。
LinkSurgeの[GEOモニタリング](https://linksurge.jp/geo)では、ChatGPT Searchを含む5媒体での自社ブランドの言及と引用元を定点で記録し、競合と比較できます。土台の点検には[AI Ready診断](https://linksurge.jp/ai-ready)をあわせてお使いください。
---
## PR TIMES・note・Yahoo!知恵袋をChatGPT引用に使う方法 — ChatGPTの回答の最大42.8%にプレスリリースが登場する日本固有の構造と、引用される条件
> URL: https://linksurge.jp/blog/chatgpt-press-release-note-ugc-2026/
> Date: 2026-09-08 | Category: AIO | Author: 緒方亜朗
> Tags: ChatGPT対策, PR TIMES, プレスリリース, note, Yahoo!知恵袋, UGC, GEO, AI検索最適化
## この記事の結論:日本語のChatGPT対策は、プレスリリース・長文の一次体験・Q&Aの3媒体で組む
海外のChatGPT対策ガイドをそのまま日本に持ち込むと、必ず抜け落ちるものがあります。PR TIMESです。私がAhrefsの日本市場データと、2026年に公開された2つのプレスリリース引用調査を突き合わせて確認できた要点は次の5つです。
1. **ChatGPTの回答の最大42.84%にプレスリリースが登場する** — Wallabee(Optyino.ai)が2026年4月21日〜7月8日に9種類のAIで81,895件の回答を分析したところ、GPT-5 miniの回答の42.84%、GPT-5.2の27.33%が少なくとも1件のプレスリリースを引用していました。Perplexityは21.45%、Claudeは6.00%、Copilotは2.90%です
2. **プレスリリース引用の60.5%はPR TIMES** — 同調査でプレスリリースの引用URL 9,381件の60.5%がPR TIMESドメインでした。Ahrefsの日本市場データでもPR TIMESはChatGPTの引用元で2026年4月版・6月版ともに2位、食品業界では1位です
3. **引用されるかどうかは、リリースの型ごとの「要素」で決まる** — Sighted(Tech Knowledge Base)が2026年5〜6月にOpenAIのAPIで1,056回のテストを行った結果、調査レポート型は調査名・調査主体・サンプル数・期間・数値の明記、商品型は商品名・発売日・価格・店舗情報の明記が条件でした。商品型では中堅企業の引用率78%に対し大手チェーンは30%です
4. **PR TIMESと公式サイトは、質問の言葉で使い分けられる** — 同調査では「実態調査」「ランキング」「限定」を含む質問ではPR TIMESが、「おすすめ」「導入状況」「新商品」では公式サイトが引用されやすい傾向がありました。両方を整えて初めて取りこぼしがなくなります
5. **note・Ameblo・Yahoo!知恵袋・楽天市場は、それぞれ役割が違う** — note と Ameblo は長文の一次体験、Yahoo!知恵袋はQ&A、楽天市場は商品事実の置き場です。UGCは自作せず促進するのが原則で、2026年8月の引用変動が示す通り、1つの媒体に寄せる設計は避けます
以下では、プレスリリース、公式サイトとの使い分け、note・Ameblo、Q&A・EC・レビューの順に、実務の手順まで解説します。
---
## 1. プレスリリースはChatGPTにどれだけ引用されているか
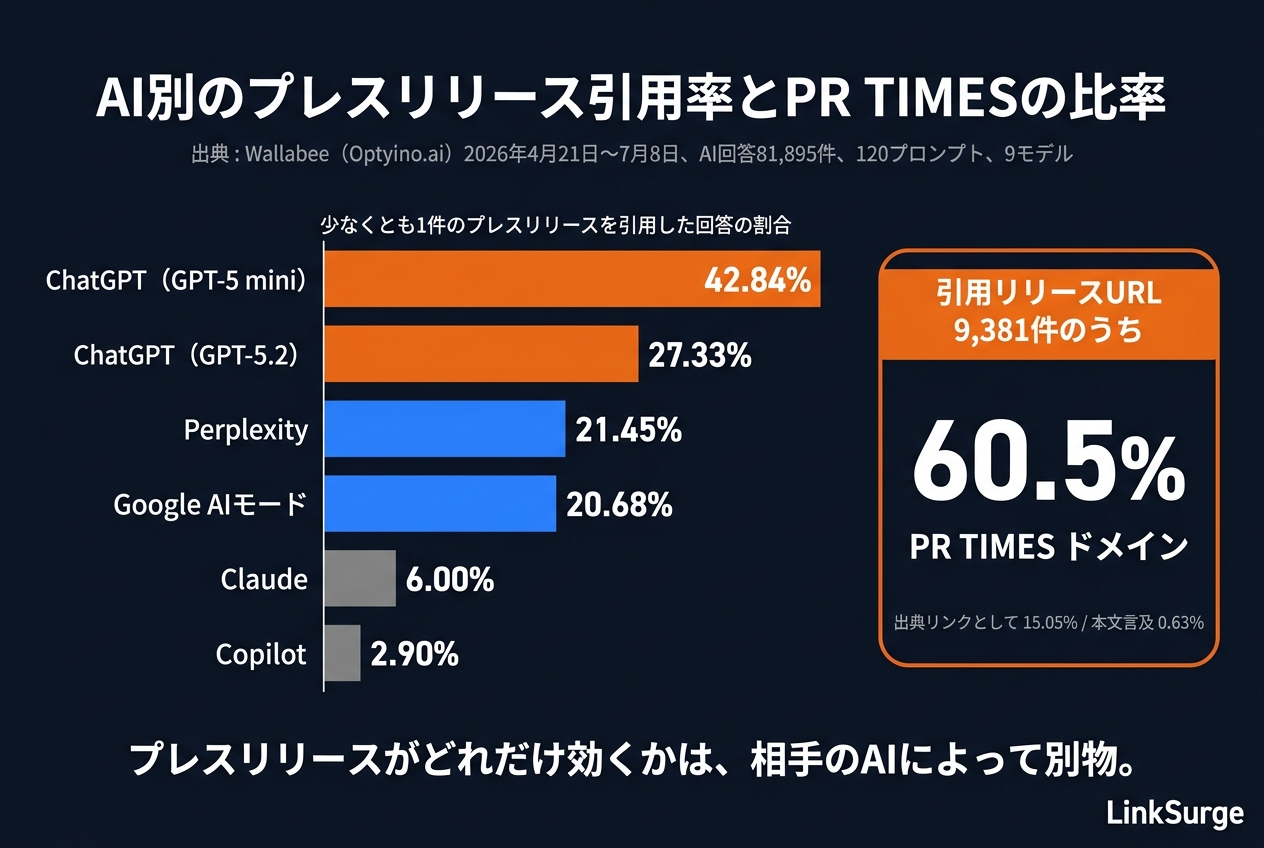
まず規模を押さえます。株式会社Wallabeeは2026年7月に、自社のAI検索モニタリング基盤Optyino.aiで収集した81,895件のAI回答(2026年4月21日〜7月8日、金融・住宅・家電・BtoBサービスに関する120プロンプト、9種類のAIモデル)を分析し、プレスリリースの引用実態を公開しました。
| AIモデル | 少なくとも1件のプレスリリースを引用した回答の割合 |
|:---|---:|
| ChatGPT(GPT-5 mini) | 42.84% |
| ChatGPT(GPT-5.2) | 27.33% |
| Perplexity | 21.45% |
| Google AIモード | 20.68% |
| Claude | 6.00% |
| Copilot | 2.90% |
驚いたのは、モデル間の差です。同じChatGPTでもGPT-5 miniとGPT-5.2で15ポイント以上違い、Copilotとは約15倍の開きがあります。プレスリリースがどれだけ効くかは、相手のAIによって別物です。
引用のされ方にも特徴があります。プレスリリースは「出典リンク」として引用される比率が15.05%だったのに対し、回答本文で言及される比率は0.63%でした。根拠として脚注的に使われることが多く、本文に社名が出るわけではない、という点は押さえておく必要があります。
そして引用されたプレスリリースのURL 9,381件のうち、60.5%がPR TIMESでした。Ahrefsの日本市場データとも整合します。PR TIMESはChatGPTの引用元として2026年4月版・6月版ともに2位を維持し、2025年9〜12月の業界別分析では食品業界で1位(2,445回答)でした。
日本語の引用元の全体像は「[ChatGPTが日本語で引用するドメインの構造](/blog/chatgpt-citation-sources-japan-2026/)」でまとめています。
> 参考・引用:
> [生成AIはプレスリリースをどれくらい引用する?Optyino.aiがAI回答81,895件を分析 - Wallabee(PR TIMES)](https://news.infoseek.co.jp/article/prtimes_000000018_000124655/)
> [ChatGPTの回答の約43%にプレスリリースが登場 - マナミナ](https://manamina.valuesccg.com/articles/5165)
> [AI が引用する日本のドメインランキング 2026 年 6 月版 - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
> [2025年AI検索トレンド分析|業界別引用傾向 - Ahrefs](https://ahrefs.com/blog/ja/2025-ahrefs-brand-radar-ai-search-analysis/)
---
## 2. 引用されるプレスリリースの条件
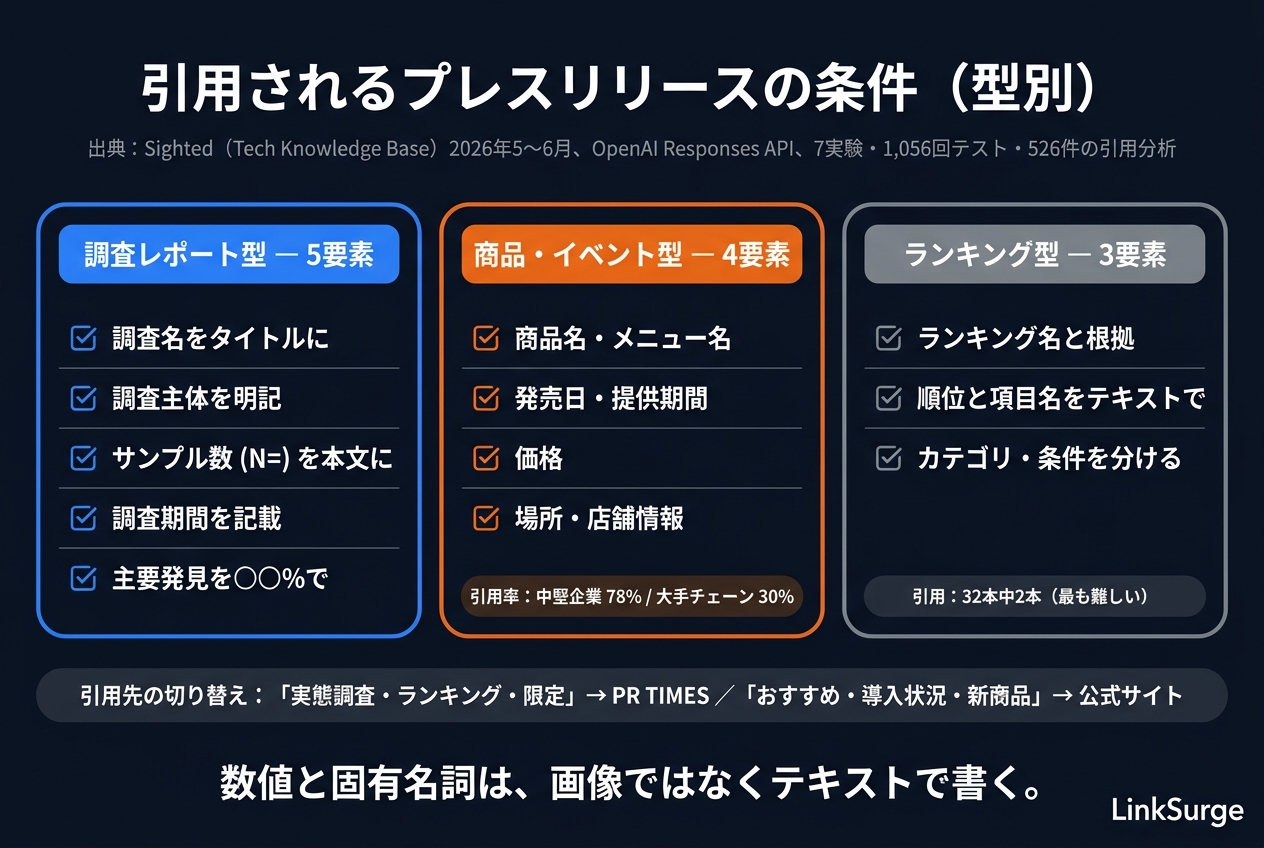
「PR TIMESに出せば引用される」わけではありません。株式会社Tech Knowledge Baseが運営するSightedは2026年7月15日に、PR TIMESに掲載された70社超の記事を対象に、OpenAIのResponses APIのWeb検索で7実験・1,056回のテストを行い、526件の引用テキストを分析した結果を公開しました。リリースの型ごとに、引用される条件が違います。
| リリースの型 | 引用に必要な要素 | 補足 |
|:---|:---|:---|
| 調査レポート型(5要素) | 調査名をタイトルに入れる、調査主体を明記、サンプルサイズ(N=○○名)を本文にテキストで明記、調査期間を記載、主要発見を○○%形式で記載 | 既に権威ある回答元がないテーマであること |
| 商品・イベント型(4要素) | 商品名・メニュー名を明記、発売日や提供期間を本文に記載、価格を記載、場所・店舗情報を入れる | 4要素が揃うことが重要。中堅企業の引用率78%、大手チェーンは30% |
| ランキング・まとめ型(3要素) | ランキング名と根拠を明記、順位と項目名をテキストで列挙、カテゴリや条件を分けて記載 | 32本中2本しか引用されず、最も難しい型 |
### 数値と固有名詞をテキストで書く
調査型で共通しているのは、「AIが抽出する項目をテキストで書いてあるか」です。調査名、調査主体、サンプル数、期間、パーセンテージの5つは、画像のグラフに入れただけでは読まれません。本文に平文で書いてください。これは私たちのブログ記事でも守っているルールで、図に数値を入れる場合も必ず本文に同じ数値を書いています。
### 中堅企業の方が引用されやすい
商品型で中堅企業の引用率が78%、大手チェーンが30%という差は、直感に反するかもしれません。私の解釈は、大手チェーンは公式サイトや大手メディアの記事という「より権威ある回答元」が既にあるため、プレスリリースまで遡らなくても回答できる、というものです。調査型の条件にある「既に権威ある回答元がないこと」と同じ構造です。中堅企業にとっては、プレスリリースが自社の一次情報として引用される最短経路になります。
> 参考・引用:
> [「PR TIMESリリースがAIに引用される条件」の調査レポートを公開 - Tech Knowledge Base(PR TIMES)](https://prtimes.jp/main/html/rd/p/000000011.000163833.html)
---
## 3. PR TIMESか、公式サイトか
Sightedの調査で私が最も実務的だと感じたのが、質問の言葉によって引用先が切り替わるという観測です。同じ企業の同じ情報でも、ユーザーの聞き方で PR TIMES が引用されるか公式サイトが引用されるかが変わります。
| 質問に含まれる言葉 | 引用されやすい先 |
|:---|:---|
| 「実態調査」「ランキング」「限定」 | PR TIMES のリリース |
| 「おすすめ」「導入状況」「新商品」 | 公式サイト |
この結果から導ける設計は単純です。調査・ランキング・期間限定の情報はPR TIMESに出し、製品の推奨理由・導入事例・新商品の恒常的な情報は公式サイトの見出し単位で整える。片方だけでは、もう片方の言葉で聞かれたときに取りこぼします。
公式サイト側の構造については、ChatGPTのファンアウトでブランド系プロンプトの16.6%が自社ドメインを名指しした検索になっている点もあわせて押さえてください。詳細は「[ChatGPTに引用される方法 完全ガイド](/blog/chatgpt-geo-complete-guide-2026/)」の第3章と第4章にまとめています。
---
{{linksurge-card}}
## 4. note・Ameblo:長文の一次体験を置く場所
Ahrefsの日本市場データで、AmebloとnoteはChatGPTの引用元として常に上位にいます。2026年6月版でAmebloが3位、noteが5位。4月版ではAmebloが1位でした。業界別分析でも、食品業界でAmebloが3位、IT業界ではnote・Ameblo・PR TIMESが上位に入っています。
### なぜ引用されるのか
私の見方では、この2つの媒体には「実際に使った・食べた・試した人の長文」が大量にあり、ChatGPTが回答の根拠に使いやすい一次体験が集まっているからです。ファンアウトの5つの型(関連トピック・暗黙の疑問・比較・最新性・言い換え)のうち、「暗黙の疑問」や「比較」に答える文章は、公式サイトより個人の長文にあることが多いです。
### 企業がnoteを使う方法
- **自社の一次情報を長文で公開する** — 開発の経緯、検証データ、失敗談。プレスリリースには書けない厚みをnoteに置く
- **固有名詞と年号を明示する** — ChatGPTのサブクエリの23.8%に完全一致のクォート、19.6%に年号が含まれます。製品名・社名・調査年をタイトルと本文に書く
- **見出し単位で完結させる** — 各見出しの直下に、その見出しの質問に40〜60語で答える段落を置く
### 第三者のnote・Amebloを増やす方法
自社アカウントで書くだけでは限界があります。実際に使った人が書く記事を増やすには、レビュー用のサンプル提供、体験イベント、書きやすさを助けるテンプレートの提供が有効です。ただし、自社で書いた記事を第三者のものとして装う手法は、AI以前にプラットフォームの規約と信頼の問題です。UGCの促進と自作の線引きは「[UGC × AI検索引用戦略](/blog/ugc-ai-search-brand-mentions-2026/)」で詳しく扱っています。
> 参考・引用:
> [AI 検索が引用するドメイン TOP 10【2026 年 4 月最新版】 - Ahrefs](https://ahrefs.com/blog/ja/brand-radar-top-10-cited-domains-2026-update/)
> [A study of query fan-out in ChatGPT using brand searches - MJ Cachón](https://www.mjcachon.com/en/blog/study-query-fan-out-chatgpt-brand/)
---
## 5. Yahoo!知恵袋・楽天市場・レビュー:Q&Aと商品事実の置き場
### Yahoo!知恵袋
Yahoo!知恵袋は2026年6月版でChatGPTの引用元9位に新たに入りました。Google AIモードでは2025年5〜9月に518,977回と圧倒的な1位で、日本語のQ&Aとして最大の引用元です。ChatGPTでの比率はGoogleほど高くありませんが、「〇〇と△△の違いは」「〇〇を選ぶときの注意点は」といった質問形式のクエリと、知恵袋の質問文が構造的に一致するため、引用候補になりやすい媒体です。
企業にできることは、自社カテゴリの質問に対して、公式アカウントまたは実名の担当者として正確な回答を書くことです。宣伝ではなく、質問に答える。回答の中で自社の一次情報(調査、仕様)にリンクすれば、知恵袋の回答と自社サイトの両方が引用候補になります。
### 楽天市場・Amazon・レビュー
楽天市場の商品ページは2026年6月版で6位、食品業界では2位でした。Profoundの2026年7月の分析では、ChatGPTのショッピング回答で商品情報の87.3%はWebクロールから取得され、1位に表示された商品カードはレビュー数の中央値が787件と、4位以下の352件の2倍以上でした。
ECにとっての施策は、モールの商品ページに仕様・価格・在庫をテキストで正確に書くこと、そしてレビュー数を増やす仕組み(購入後の依頼、レビュー投稿の動線)を持つことです。ショッピング固有の対策はこのシリーズの別記事で扱います。
### 変動リスクを織り込む
2026年8月、ChatGPT SearchでのRedditの引用シェアは4日間で86%低下し、YouTube・TikTokも7〜9割減りました(原因は未確定)。UGC媒体は効く時は大きく効きますが、1つの媒体に寄せる設計は避けてください。詳細は「[ChatGPTの引用元は4日で86%動く](/blog/chatgpt-citation-volatility-2026/)」で扱っています。
> 参考・引用:
> [Ahrefs、日本国内における AI 検索エンジンの引用元を徹底分析 - マナミナ](https://manamina.valuesccg.com/articles/4596)
> [Breaking down how ChatGPT Shopping works behind the user experience - Profound](https://www.tryprofound.com/blog/chatgpt-shopping-end-to-end-breakdown)
> [Reddit Citations Are Dropping in ChatGPT - Promptwatch](https://promptwatch.com/data/reddit-citations-are-dropping-in-chatgpt)
---
## 6. 30日で組む日本語3媒体の実行プラン
ここまでの内容を実行順に並べます。
| 週 | やること | 確認方法 |
|:---|:---|:---|
| 第1週 | 自社カテゴリの質問20〜30本でChatGPTの引用URLを記録し、PR TIMES・note/Ameblo・知恵袋・EC・公式サイトの5分類で集計する | 競合が引用されていて自社がいない分類を特定 |
| 第2週 | 調査型または商品型のプレスリリースを1本、Sightedの条件(調査名・調査主体・N・期間・数値、または商品名・発売日・価格・店舗)を満たして出す | 公開後2週間の引用記録 |
| 第3週 | 公式サイトに「おすすめ」「導入状況」「新商品」の質問に見出し単位で答えるページを整える。noteに一次情報の長文を1本公開する | 公式サイトとnoteの引用有無を記録 |
| 第4週 | 知恵袋の自社カテゴリの質問に正確な回答を書く。レビュー依頼の動線を作る | 言及率と引用元の週次記録を定常化 |
第1週と第4週の記録は、[LinkSurge](https://linksurge.jp/)のGEOモニタリングで監視クエリを登録しておけば、ChatGPT Searchを含む5媒体で自動的に残ります。私たちもこのシリーズの効果測定に同じ仕組みを使っています。
---
## よくある質問(FAQ)
### ChatGPTはプレスリリースをどのくらい引用しますか?
Wallabeeが2026年4月21日〜7月8日に81,895件のAI回答を分析した結果、少なくとも1件のプレスリリースを引用した回答の割合は、ChatGPT(GPT-5 mini)で42.84%、GPT-5.2で27.33%でした。Perplexityは21.45%、Claudeは6.00%、Copilotは2.90%です。引用されたプレスリリースのURLの60.5%はPR TIMESでした。
### PR TIMESに出せばChatGPTに引用されますか?
条件があります。Sightedの2026年5〜6月の1,056回テストでは、調査レポート型は調査名・調査主体・サンプル数(N)・調査期間・パーセンテージの5要素の明記、商品・イベント型は商品名・発売日・価格・店舗情報の明記が引用の条件でした。商品型では中堅企業の引用率が78%、大手チェーンが30%と差があり、既に権威ある回答元があるテーマでは引用されにくくなります。
### PR TIMESと公式サイトのどちらが引用されますか?
質問の言葉で変わります。Sightedの調査では、「実態調査」「ランキング」「限定」を含む質問ではPR TIMESのリリースが、「おすすめ」「導入状況」「新商品」を含む質問では公式サイトが引用されやすい傾向がありました。調査・ランキング・期間限定の情報はPR TIMESに、製品の推奨理由や導入事例は公式サイトに置くと取りこぼしが減ります。
### noteやAmebloは企業のChatGPT対策に使えますか?
使えます。Ahrefsの2026年6月版データでAmebloはChatGPTの引用元3位、noteは5位で、業界別分析でも上位に入っています。自社アカウントで開発経緯や検証データなどの一次情報を長文で公開し、固有名詞と年号を明示し、見出し単位で完結する構造にすると引用候補になります。第三者の記事を増やす場合は、自作ではなく促進(サンプル提供、体験機会、テンプレート)が原則です。
### Yahoo!知恵袋への回答はChatGPT対策になりますか?
なります。Yahoo!知恵袋は2026年6月版でChatGPTの引用元9位に入り、Google AIモードでは2025年5〜9月に518,977回と最大の引用元でした。質問形式のクエリと知恵袋の質問文が構造的に一致するため引用候補になりやすく、自社カテゴリの質問に公式アカウントや実名で正確に回答し、自社の一次情報にリンクすることで、知恵袋と自社サイトの両方が引用候補になります。
---
## まとめ:プレスリリースは「出す」ではなく「引用される型で出す」
日本語のChatGPT対策は、海外のガイドにはない3つの媒体で組み立てます。プレスリリースはChatGPTの回答の最大42.84%に登場し、その6割がPR TIMESです。ただし引用されるかどうかは型ごとの要素で決まり、質問の言葉によって公式サイトと使い分けられます。noteとAmebloは長文の一次体験、Yahoo!知恵袋はQ&A、楽天市場は商品事実の置き場として、それぞれ役割が違います。
最初にやるべきことは、自社カテゴリの質問で誰が引用されているかを5分類で記録し、次に調査型か商品型のリリースを条件を満たして1本出すことです。そして1つの媒体に寄せず、公式サイトを含めた5分類に薄く分散してください。引用元は数日で入れ替わります。
LinkSurgeの[GEOモニタリング](https://linksurge.jp/geo)では、ChatGPT Searchを含む5媒体で監視クエリごとの言及と引用URLを定点で記録できます。プレスリリース公開前後の引用変化を追う用途に、あわせてお使いください。
---
## ChatGPTのクエリファンアウトは今どうなっているか — 2.17本から7.61本へ増え、そして見えなくなった
> URL: https://linksurge.jp/blog/chatgpt-query-fanout-hidden-2026/
> Date: 2026-09-08 | Category: AIO | Author: 緒方亜朗
> Tags: ChatGPT対策, クエリファンアウト, ChatGPT検索, サブクエリ, Responses API, GEO, AI検索最適化
## この記事の結論:ファンアウトは「消えた」のではなく「増えたうえで見えなくなった」
2026年の春まで、私はChrome DevToolsのネットワークタブでChatGPTの内部検索クエリを眺めながら、クライアントのコンテンツがどのサブクエリで拾われているかを確認していました。夏にはそれができなくなりました。同時に、ファンアウトそのものは3倍以上に増えています。要点は次の5つです。
1. **ファンアウトの本数は3倍以上に増えた** — Lily Rayの2026年8月の観測では、1プロンプトあたりのファンアウト数が2.17本から7.61本へ、単一クエリで処理される比率は94%から43.5%へ変わりました。MJ Cachónのブランド系プロンプト調査では1回の実行あたり平均2.6本、同じプロンプトを4回実行したときの重複を除いた累積では平均10.3本です
2. **サブクエリは会話インターフェースから見えなくなった** — 2026年半ば、GPT-5.3が既定になった時点で応答JSONから `search_model_queries` が消え、5.4では確認できませんでした。Little Green Agencyの更新によるとGPT-5.6では再び表示されており、可視性はモデルごとに変わります
3. **APIでは今も取得できる** — OpenAIのResponses APIでWeb検索ツールを使うと、応答の `action.queries` 配列にサブクエリが入ります。自社カテゴリの質問がどう分解されるかは、この経路で調べられます
4. **サブクエリの形式には明確な癖がある** — ブランド系プロンプトではサブクエリの93.4%にブランド名が含まれ、30.2%に `site:` 演算子(その55.1%は自社ドメイン対象)、23.8%に完全一致のクォート、19.6%に年号が付きます。国際的なブランドではサブクエリの27.3%に英語語彙が混ざります
5. **見えない前提の対策は「受け皿の網羅」と「定点観測」** — サブクエリを追いかけるのではなく、想定される分解パターン(関連トピック・暗黙の疑問・比較・最新性・言い換え)ごとに見出しブロックを用意し、言及率と引用元を週次で記録する設計に切り替えます
以下では、何が起きたのかを時系列で追い、APIでの取得手順と対策を解説します。要点は動画でも解説しています。
{{youtube:Mrk3lvs_qCs|ChatGPTのクエリファンアウトは今どうなっているか?2.17本から7.61本へ増えた実態とAPIでの取得法}}
---
## 1. ファンアウトとは何か、ChatGPTではどう動くか
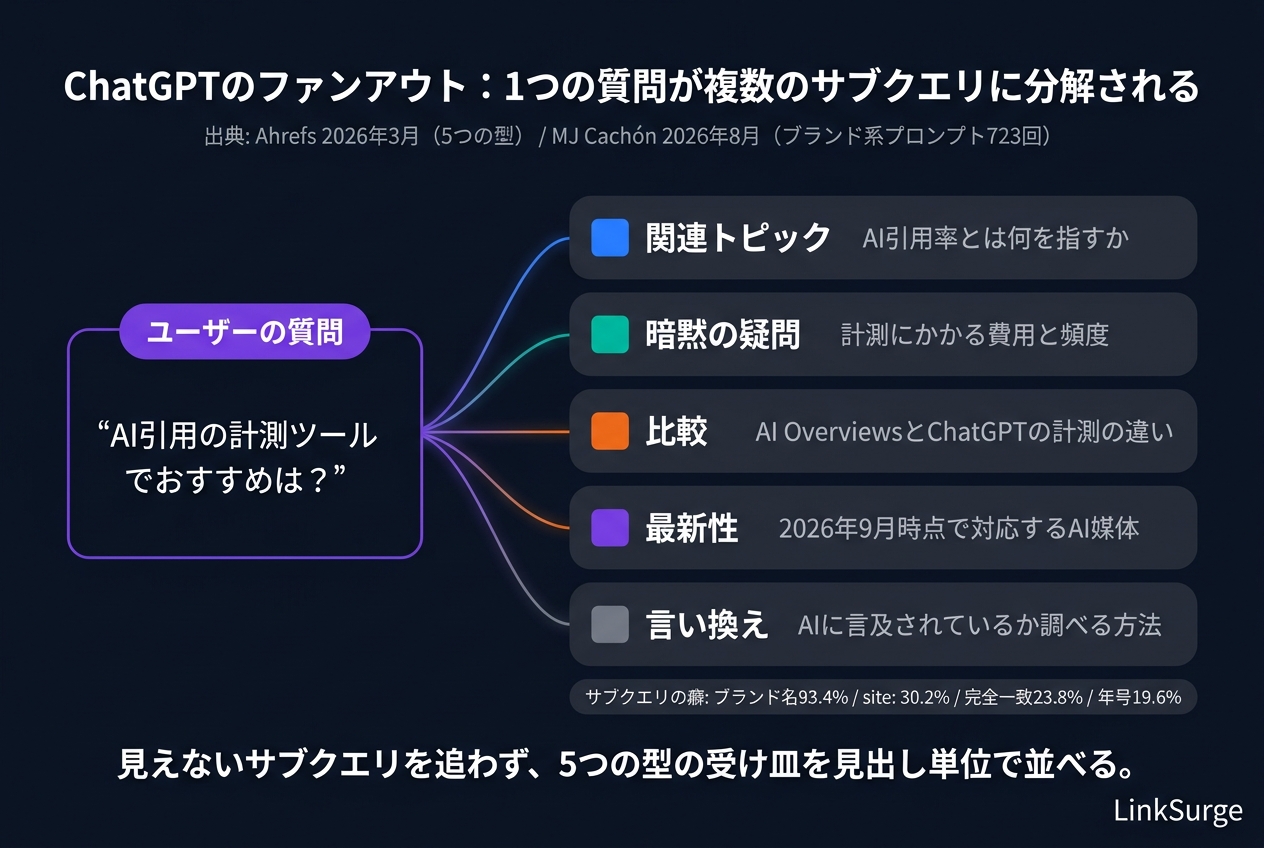
クエリファンアウトは、AIがユーザーの1つの質問を複数のサブクエリに分解し、並列に検索してから結果を統合する仕組みです。Google AI Modeで広く知られるようになりましたが、ChatGPT searchも同じ考え方で動いています。
Ahrefsが2026年3月に整理したファンアウトの型は5つあります。
| 型 | 内容 | 例 |
|:---|:---|:---|
| 関連トピック | 文脈を補う近接テーマ | 「作り置き容器」→「簡単な作り置きレシピ」 |
| 暗黙の疑問 | ユーザーが口にしていない懸念 | 「太陽光パネル」→「設置費用」「工期」 |
| 比較 | 並列評価 | 「AsanaとMondayの違い」 |
| 最新性 | 時間に敏感な検索 | 「おすすめスマホ 2026」 |
| 言い換え | 同じ意図の別表現 | 「離脱率を下げる」→「訪問者を留める」 |
同じ分析では、ファンアウトで生成されるクエリの95%以上は繰り返し検索されることがなく、検索ボリュームを基準にした最適化が成り立たないことも指摘されています。Google側の仕組みの全体像は「[クエリファンアウトとは?初心者向け解説](/blog/query-fan-out-guide-2026/)」で扱っています。
ChatGPT固有の話は、ここから先です。
> 参考・引用:
> [What is Query Fan-Out? Understanding the Hidden Queries Driving AI Search - Ahrefs](https://ahrefs.com/blog/query-fan-out/)
---
## 2. 2026年夏に何が変わったか
### 本数が3倍以上に増えた
Lily Rayが2026年8月17日に公開した観測は、モデル更新の前後を比較したものです。
| 指標 | 更新前 | 更新後 |
|:---|:---|:---|
| 単一クエリで処理される比率 | 94% | 43.5% |
| 1プロンプトあたりのファンアウト数 | 2.17本 | 7.61本 |
| 取得されるソース数 | 約12 | 約24 |
| `site:` 演算子を含む比率 | 0.3% | 約23% |
率直に言って、この変化は「ChatGPTがGoogle AI Modeに近づいた」と表現するのが正確だと思います。Ahrefsの調査ではAI Modeのサブクエリは59%が5〜11本、24%が12〜19本でしたから、ChatGPTの7.61本という平均はその範囲に入ってきました。
### 同時に、見えなくなった
Little Green Agencyが2026年7月2日に公開した記事によると、以前はChrome DevToolsのネットワークタブで会話IDを検索し、応答JSONの `search_model_queries` フィールドを開けばサブクエリを確認できました。同記事によると、GPT-5.3が既定モデルになった時点でこのフィールドは検証した会話インターフェースから消え、GPT-5.4でも確認できませんでした。その後の同記事の更新では、GPT-5.6で再び表示されるようになったとされており、可視性はモデルのバージョンによって変わります。
つまり、ファンアウトは増えながら、モデルによってはユーザー側から安定して観測できなくなりました。SEO担当者にとっては、「何が起きているかは分かるが、自社がどのサブクエリで拾われているかは直接見えない」状態です。
> 参考・引用:
> [What We Can Learn from Evolving ChatGPT Fan-Out Queries - Lily Ray](https://lilyraynyc.substack.com/p/what-we-can-learn-from-evolving-chatgpt)
> [ChatGPT Has Hidden Its Fan-Out Queries. Here's How to Get Them Back with n8n - Little Green Agency](https://littlegreenagency.co.uk/blog/chatgpt-has-hidden-its-fan-out-queries-heres-how-to-get-them-back-with-n8n/)
---
## 3. サブクエリの形式:ブランド系プロンプトの実測
見えなくなったとはいえ、API経由の調査でサブクエリの癖は分かっています。MJ Cachónが2026年8月25日に公開した調査は、医療・スポーツ小売・ホテルの3プロジェクトで189本のブランド系プロンプトを723回実行し、OpenAIのAPI経由でサブクエリを収集したものです(GPT-5.5、2026年8月)。
| 指標 | 値 |
|:---|---:|
| 1実行あたりのサブクエリ数(平均・最大) | 2.6本・13本 |
| 同じプロンプトを4回実行したときの重複を除いたサブクエリ数(平均) | 10.3本 |
| ブランド名を含むサブクエリ | 93.4% |
| `site:` 演算子を含む | 30.2% |
| うち自社ドメイン / グループ / 第三者 / 競合 | 16.6% / 7.9% / 5.6% / 0.1% |
| 完全一致のクォート("...")を含む | 23.8% |
| 年号を含む | 19.6% |
| 英語語彙を含む(全体 / 国際的なブランド) | 8.9% / 27.3% |
| 2回以下の検索で完結する実行 | 63.9% |
私が注目したのは3点です。第一に、サブクエリの69.8%は通常検索ですが、`site:` 付きのもの(30.2%)の55.1%は自社ドメインを対象にしており、競合サイトを見に行くことはほぼありません。ブランド系プロンプトでは、全体の16.6%が公式サイトを名指しした検索になります。第二に、完全一致のクォートと年号が2割前後に付くため、固有名詞と年号を本文と見出しに明示しておくことが受け皿になります。第三に、国際的なブランドではサブクエリの4分の1以上に英語が混ざります。Ahrefsの日本市場データで英語版Wikipediaが日本語版より上位に来ている現象とも整合し、日本語だけのサイトは英語のサブクエリから見つからないことを示唆しています。
> 参考・引用:
> [A study of query fan-out in ChatGPT using brand searches - MJ Cachón](https://www.mjcachon.com/en/blog/study-query-fan-out-chatgpt-brand/)
> [AI が引用する日本のドメインランキング 2026 年 6 月版 - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
---
{{linksurge-card}}
## 4. 見えないサブクエリをAPIで取得する
会話インターフェースからは安定して見えなくなりましたが、OpenAIのResponses APIでWeb検索ツールを有効にすると、応答にサブクエリが含まれます。自社カテゴリの代表的な質問がどう分解されるかを調べる用途であれば、この経路で十分です。
### 手順
1. OpenAIのAPIキーを用意し、Responses APIにWeb検索ツールを有効にしたリクエストを送る
2. 応答の出力項目のうち、Web検索の呼び出しを表す項目を探す
3. その中の `action.queries` 配列に、実際に実行されたサブクエリが入っている
4. 同じプロンプトを複数回実行し、サブクエリの分布を取る(1回では偏る)
Little Green Agencyはn8nのHTTPリクエストノードでこの処理を自動化する手順を公開しています。手作業なら、代表的なプロンプト10〜20本を各5回ずつ実行して、サブクエリの型(関連トピック・暗黙の疑問・比較・最新性・言い換え)ごとに分類すれば、自社に必要な受け皿の一覧ができます。
### 注意点
- APIのモデルとChatGPTのWeb版は、同じ質問でも分解の仕方が完全には一致しません。傾向を掴む用途に留めてください
- サブクエリは実行ごとに変わります。1回の結果で「このサブクエリに最適化する」と決めると外れます
- 取得された(読まれた)ことと引用されたことは別です。サブクエリで拾われても、回答に引用されるとは限りません
---
## 5. 見えない前提での対策
サブクエリが見えなくなった以上、対策の軸は「サブクエリを追う」から「分解パターンの受け皿を網羅する」と「結果を定点で記録する」に移ります。
### 受け皿の網羅
1つのテーマについて、5つの型それぞれに対応する見出しブロックを用意します。例えば「AI引用の計測ツール」というテーマなら、次のような見出しが受け皿になります。
- 関連トピック:「AI引用率とは何を指すか」
- 暗黙の疑問:「計測にかかる費用と頻度」
- 比較:「Google AI OverviewsとChatGPTで計測方法はどう違うか」
- 最新性:「2026年9月時点で対応しているAI媒体」
- 言い換え:「AIに言及されているかを調べる方法」
各見出しの直下には40〜60語で完結する回答を置きます。当社のGoogle AI Overviews実引用277件の解析では、引用の69.3%がリード文以外の見出しブロックから発生していました。この調査はGoogle AI Overviewsが対象でChatGPTを直接測定したものではありませんが、同じ方向に効くという仮説のもとで受け皿を設計しています。調査の詳細は「[AI検索は記事のどこを引用するのか](/blog/ai-citation-block-position-research-2026/)」をご覧ください。
### 公式サイトを名指し検索に耐える構造にする
`site:` 付きサブクエリの半分以上が自社ドメインを対象にしている以上、公式サイトの中で製品・料金・比較・FAQが見出し単位で見つかる必要があります。Lily Rayは、公式ドメインの最適化と、メタディスクリプションでの「公式」の明示、Search Consoleでの `site:` クエリの監視を推奨しています。
### 英語の受け皿を検討する
国際的なブランドではサブクエリの27.3%に英語が混ざり、日本市場のChatGPT引用元でも英語版Wikipediaが上位に入ります。海外展開の有無にかかわらず、主要ページの英語要約を用意することは、英語のサブクエリからの流入経路を作る施策になります。
### 言及率と引用元を週次で記録する
サブクエリは見えなくても、結果は見えます。自社カテゴリの質問20〜30本に対するChatGPTの回答で、自社が言及・引用される比率と、引用されたドメインを週次で記録してください。回答は実行ごとに変わるため、複数回の記録が要ります。[LinkSurge](https://linksurge.jp/)のGEOモニタリングでは、ChatGPT Search・Gemini・Google AI Overviews・Claude・Perplexityの5媒体に監視クエリを登録し、言及の有無、言及位置、引用URL、競合との比較を記録できます。私たちもこのシリーズの効果測定に同じ仕組みを使っています。
対策の全体像は「[ChatGPTに引用される方法 完全ガイド](/blog/chatgpt-geo-complete-guide-2026/)」を、内部構造は「[ChatGPT検索の内部構造](/blog/chatgpt-search-architecture-2026/)」をご覧ください。
---
## よくある質問(FAQ)
### ChatGPTのクエリファンアウトとは何ですか?
ChatGPTがユーザーの1つの質問を複数の内部検索クエリ(サブクエリ)に分解し、それぞれで検索してから結果を統合する仕組みです。Lily Rayの2026年8月の観測では、1プロンプトあたり平均7.61本のサブクエリが生成され、単一クエリで処理される比率は43.5%まで下がっています。
### ChatGPTのサブクエリはなぜ見えなくなったのですか?
2026年半ば、GPT-5.3が既定モデルになった時点で、検証された会話インターフェースの応答JSONから `search_model_queries` フィールドが消え、GPT-5.4でも確認できませんでした。以前はChrome DevToolsのネットワークタブでこのフィールドを開くことでサブクエリを確認できました。Little Green Agencyの更新によるとGPT-5.6では再び表示されており、可視性はモデルごとに変わります。OpenAIは理由を公表していません。
### ChatGPTのサブクエリを今でも確認する方法はありますか?
OpenAIのResponses APIでWeb検索ツールを有効にすると、応答の `action.queries` 配列に実行されたサブクエリが含まれます。同じプロンプトを複数回実行して分布を取る使い方が実務的です。ただしAPIのモデルとChatGPTのWeb版では分解の仕方が完全には一致しないため、傾向の把握に留めてください。
### ChatGPTのサブクエリにはどんな特徴がありますか?
MJ Cachónの2026年8月の調査(ブランド系プロンプト189本、723回実行)では、1回の実行あたり平均2.6本、同じプロンプトを4回実行したときの重複を除いた累積で平均10.3本のサブクエリが生成され、93.4%にブランド名、30.2%に `site:` 演算子、23.8%に完全一致のクォート、19.6%に年号が含まれていました。`site:` の対象は主に自社ドメインで、競合サイトはほぼ対象になりません。国際的なブランドでは27.3%に英語語彙が混ざります。
### サブクエリが見えない状態で、何を対策すればいいですか?
関連トピック・暗黙の疑問・比較・最新性・言い換えの5つの分解パターンごとに見出しブロックを用意し、各見出しの直下に完結した回答を置きます。公式サイト内で製品・料金・比較・FAQが見出し単位で見つかる構造にし、固有名詞と年号を明示します。そのうえで、ChatGPTでの言及率と引用元ドメインを週次で記録し、変動を前提に調整します。
---
## まとめ:追いかけるのをやめて、受け皿を並べる
ChatGPTのファンアウトは、2026年夏に2.17本から7.61本へ増え、同時にモデルによっては会話インターフェースから安定して見えなくなりました。サブクエリの形式には、ブランド名・`site:`・完全一致・年号・英語という明確な癖があり、APIを使えば傾向は今も掴めます。
見えないものを追いかける代わりに、5つの分解パターンの受け皿を見出し単位で並べ、公式サイトを名指し検索に耐える構造にし、結果を週次で記録する。この設計に切り替えれば、次にファンアウトの仕様が変わっても対応の軸はぶれません。
LinkSurgeの[GEOモニタリング](https://linksurge.jp/geo)では、ChatGPT Searchを含む5媒体での言及と引用元を定点で記録できます。受け皿となる見出し構造の点検には[AI Ready診断](https://linksurge.jp/ai-ready)をあわせてお使いください。
---
## ChatGPT検索の内部構造:Bing・Google・独自インデックス「Labrador」の三層と、週単位で変わる仕組みへの向き合い方
> URL: https://linksurge.jp/blog/chatgpt-search-architecture-2026/
> Date: 2026-09-08 | Category: AIO | Author: 緒方亜朗
> Tags: ChatGPT対策, ChatGPT検索, OpenAI, Labrador, OAI-SearchBot, Bing, GEO, AI検索最適化
## この記事の結論:ChatGPT検索は「取得・分解・選別」の3段階で動く三層システム
ChatGPT対策の記事を読んでいると、「ChatGPTはBingを使っている」と書かれたものと「独自の検索エンジンを持っている」と書かれたものが混在していて、どちらを信じればいいのか分からなくなります。私が公開情報を突き合わせて整理した結論は、「両方とも正しく、しかも今まさに移行中」です。要点は次の5つです。
1. **インデックスは三層になっている** — 2024年10月の公開時はMicrosoft Bingが主な検索基盤でした。2026年9月のPeec AIの分析では、同社が「Labrador」と呼ぶOpenAI独自のインデックス(OpenAIは公式に未確認)を外部検索結果より優先する実験が、観測時点でチャットの8%に適用されていました(実験全般の適用範囲は1桁台から最大20%)。同時にGoogleとBingも使われ続けています
2. **処理は「取得・分解・選別」の3段階** — ユーザーの質問をサブクエリに分解し(ファンアウト)、各インデックスから候補ページを取得し、本文を読んだうえで引用する数本を選びます。順位表は存在せず、選別はページ単位ではなく見出しブロック単位で行われます
3. **取得と引用は逆方向に動いている** — 2026年夏のモデル更新で、取得されるソース数は約12から約24に倍増した一方、引用される数は減っています。読まれる機会は増え、選ばれる競争は激しくなりました
4. **クローラーは4種類あり、検索表示はOAI-SearchBotが担う** — GPTBot(学習)、ChatGPT-User(ユーザー起動の取得)、OAI-AdsBot(広告)とは独立しており、学習を拒否しながら検索には出る設定が可能です
5. **「週単位で作り替え中」を前提に設計する** — Peec AI自身が「このシステムはまだ週単位で再構築されている」と留保しています。特定の実験名や比率に最適化するのではなく、三層すべてに載り、どの段階でも読める状態を保つのが唯一の安定した方針です
以下では、各段階で何が起きているかを順に見ていきます。要点は動画でも解説しています。
{{youtube:bkdg2fSiLyk|ChatGPT検索の内部構造|三層インデックスと「取得・分解・選別」の3段階}}
---
## 1. 2024年から2026年へ:Bing中心から三層構造へ
### 公開時の構成
OpenAIは2024年10月31日にChatGPT searchを正式公開しました。当時の説明では、検索モデルが複数の検索プロバイダーやデータパートナーから情報を取得する構成で、Microsoft Bingがその中心にあると広く報じられています。この時期の「ChatGPT対策はBing対策」という言説は、この構成に基づいています。
### 2026年:独自インデックス「Labrador」
状況を大きく更新したのが、Peec AIが2026年9月4日に公開した分析です。同社は2026年5月21日から7月21日にかけてChatGPTのサーバー送信イベント(SSE)のメタデータを収集し、OpenAIの求人情報、Googleの反トラスト訴訟での証言記録、独自サイトでのクロール実験、Search Consoleのトラフィック分析を組み合わせて、次の構成を報告しています。
| 項目 | 内容 |
|:---|:---|
| 内部インデックス名 | Labrador(Peec AIの呼称。OpenAIが公式に確認した名称ではなく、複数の垂直インデックスの総称) |
| 構成要素 | 一般Web、PDF、YouTube、ニュース(1日以内・7日以内・それ以上)、arXiv、Wikipedia、ローカル、金融、法律、医療、ショッピング、画像 |
| 主な実験 | `prefer-index-over-serp-v3`(観測時点の2026年8月中旬でチャットの8%に適用。同社によると実験全般の適用範囲は1桁台から最大20%)、`shopping-index-q2qb`、`shopping-hqi-v2` など |
| 外部検索との関係 | 「GoogleとMicrosoftは依然として重要」。独自インデックスへの移行は段階的 |
| 著者の留保 | 「このシステムはまだ週単位で再構築されている」。大部分は確認可能な証拠に基づくが、一部は推論 |
面白いのは、`prefer-index-over-serp-v3` という実験名そのものです。「SERP(外部検索結果)より独自インデックスを優先する」という意図が名前に表れており、しかもv3まで版を重ねています。ショッピング系の実験が複数走っている点も、Peec AIの調査以前から言われてきた「ChatGPTは商品検索を重視している」という観測と整合します。
### サイト側の結論
三層のどこから取得されるかは、質問の種類や実験の割り当てによって変わります。ユーザー側からは制御できません。したがって、Bingにインデックスされていること、Googleにインデックスされていること、OAI-SearchBotがクロールして独自インデックスに入っていることの3つを、同時に満たしておく以外にありません。
> 参考・引用:
> [ChatGPT built its own search index - Peec AI](https://peec.ai/blog/chatgpt-built-its-own-search-index)
> [ChatGPT search officially launches - Search Engine Land](https://searchengineland.com/chatgpt-search-officially-launches-447919)
---
## 2. 第1段階:クローラーが読む
三層のうち、サイト側が直接影響できるのは独自インデックスへの入口であるクローラーです。OpenAIは公式ドキュメントで4種類のボットを定義しています。
| ボット | 役割 | サイト側の判断 |
|:---|:---|:---|
| OAI-SearchBot | ChatGPTの検索結果にサイトを表示するためのクロール | 検索に出たいなら必ず許可する |
| GPTBot | 基盤モデルの学習にコンテンツを使う可能性があるクロール | 学習利用を避けたいなら拒否できる。検索表示には影響しない |
| ChatGPT-User | ユーザーがChatGPTやカスタムGPTで質問した際のページ取得 | ユーザー起動のため、robots.txtの規則が適用されない場合がある |
| OAI-AdsBot | 広告ランディングページの安全性・関連性の検証 | 広告出稿時のみ |
OpenAIはrobots.txtの更新が反映されるまで約24時間かかると案内し、各ボットのIPレンジをJSONで公開しています。アクセスログでUser-Agentだけでなく送信元IPを照合すれば、本物のOAI-SearchBotかどうかを確認できます。
### JavaScript描画の落とし穴
私が診断で最もよく見る問題がこれです。OpenAIの公式資料はクローラーの用途とrobots.txt、IPレンジを説明していますが、JavaScriptを実行するかどうかは明記していません。本文がクライアント側でしか描画されない構成は、取得時に本文が読まれないリスクを抱えることになります。安全な対策はサーバーサイド描画か事前描画で、本文を初期HTMLに含めることです。画像化された表や数値も、テキストとして書いておくことを推奨します。
土台の点検項目は「[ChatGPTに引用される方法 完全ガイド](/blog/chatgpt-geo-complete-guide-2026/)」の第2章にまとめています。
> 参考・引用:
> [Overview of OpenAI Crawlers - OpenAI](https://developers.openai.com/api/docs/bots)
---
## 3. 第2段階:質問を分解する(クエリファンアウト)
ChatGPTはユーザーの質問をそのまま検索しません。複数のサブクエリに分解し、それぞれで検索してから結果を束ねます。この段階の挙動は2026年夏に大きく変わりました。
Lily Rayが2026年8月17日に公開した観測では、モデル更新の前後で次の変化が起きています。
| 指標 | 更新前 | 更新後 |
|:---|:---|:---|
| 単一クエリで処理される比率 | 94% | 43.5% |
| 1プロンプトあたりのファンアウト数 | 2.17本 | 7.61本 |
| 取得されるソース数 | 約12 | 約24 |
| `site:` 演算子を含む比率 | 0.3% | 約23% |
MJ Cachónが同月に公開したブランド系プロンプトの調査(189プロンプト、723回実行、OpenAI API経由)では、1回の実行あたり平均2.6本、同じプロンプトを4回実行したときの重複を除いたサブクエリ数は平均10.3本でした。サブクエリの93.4%にブランド名が含まれ、30.2%に `site:` 演算子が付いていました。`site:` の対象は自社ドメインが16.6%、グループドメインが7.9%、第三者が5.6%、競合はわずか0.1%です。
ここから読めるのは、ブランド系プロンプトでは自社ドメインを名指しした `site:` 検索が全サブクエリの16.6%を占めるようになったということです(残りの69.8%は通常検索)。公式サイトの構造と内容が、以前より直接的に回答の材料になっています。
ファンアウトの詳細と、非表示になったサブクエリをAPIで取得する方法は「[ChatGPTのクエリファンアウトは今どうなっているか](/blog/chatgpt-query-fanout-hidden-2026/)」で解説しています。Google側の仕組みは「[クエリファンアウトとは?初心者向け解説](/blog/query-fan-out-guide-2026/)」をご覧ください。
> 参考・引用:
> [What We Can Learn from Evolving ChatGPT Fan-Out Queries - Lily Ray](https://lilyraynyc.substack.com/p/what-we-can-learn-from-evolving-chatgpt)
> [A study of query fan-out in ChatGPT using brand searches - MJ Cachón](https://www.mjcachon.com/en/blog/study-query-fan-out-chatgpt-brand/)
---
{{linksurge-card}}
## 4. 第3段階:読んで、数本だけ選ぶ
取得された数十ページの中から、ChatGPTは本文を読んで引用する数本を選びます。この段階を理解するうえで押さえておきたい観測が2つあります。
### 取得と引用は逆方向に動く
Lily Rayは、取得されるソースが倍増した一方で、実際に引用される数は逆方向に動いていると指摘しています。読まれる機会が増えたぶん、選ばれる競争は激しくなりました。「ChatGPTに読まれている」ことは「引用されている」ことを意味しません。計測では両者を分けて追う必要があります。
### 選別はブロック単位で行われる
当社がGoogle AI Overviewsの実引用277件を解析した調査では、引用の69.3%がリード文以外の見出しブロックから発生していました。この調査はGoogle AI Overviewsを対象にしたもので、ChatGPT Searchを直接測定してはいません。ChatGPTについても各見出しの直下に完結した回答を置く構造が選別段階で効くというのは、現時点では私たちの仮説です。調査の詳細は「[AI検索は記事のどこを引用するのか](/blog/ai-citation-block-position-research-2026/)」をご覧ください。
### 引用元は数日で入れ替わる
選別の結果は安定していません。2026年8月にはChatGPT SearchでのRedditの引用シェアが、Promptwatchのデータで4日間で86.4%低下しました(原因は未確定)。Ahrefsの日本市場データでも、4月版と6月版でChatGPTの引用元上位が大きく入れ替わっています。この変動の大きさは、三層のインデックスと実験の割り当てが週単位で変わっているというPeec AIの観測と整合します。8月の変化の詳細は「[ChatGPTの引用元は4日で86%動く](/blog/chatgpt-citation-volatility-2026/)」で扱っています。
> 参考・引用:
> [Reddit's ChatGPT Search citations fell 86% in four days - Search Engine Land](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473)
> [AI が引用する日本のドメインランキング 2026 年 6 月版 - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
---
## 5. 変わり続ける仕組みに、どう向き合うか
ここまでを押さえたところで、実務での向き合い方を整理します。
### やらないこと
- 特定の実験名や比率(観測時点の8%など)に合わせて施策を組むこと。翌週には変わっている可能性が高い
- 「BingだけでOK」「Googleに出ていれば十分」と決め打ちすること。三層のどこから取得されるかは制御できない
- 取得された(読まれた)ことをもって成果とみなすこと。引用と言及を別に計測する
### やること
1. **三層すべてに載る** — Bing Webmaster ToolsとSearch Consoleでインデックス状況を確認し、robots.txtでOAI-SearchBotを許可する
2. **どの段階でも読める状態を保つ** — サーバーサイド描画、テキストとしての数値・表、見出し直下の完結した回答
3. **公式サイトを「名指し検索」に耐える構造にする** — `site:` 付きサブクエリが2割以上ある以上、公式サイト内で製品・料金・比較・FAQが見出し単位で見つかる必要がある
4. **言及率と引用元を週次で記録する** — 変動が前提なので、1回の確認ではなく定点観測にする。[LinkSurge](https://linksurge.jp/)のGEOモニタリングでは、ChatGPT Searchを含む5媒体での言及の有無と引用URLを記録し、競合と比較できます
---
## よくある質問(FAQ)
### ChatGPTはBingの検索結果をそのまま使っているのですか?
2024年10月の公開時はMicrosoft Bingが主な検索基盤でしたが、2026年9月のPeec AIの分析では、同社が「Labrador」と呼ぶOpenAI独自のインデックス(OpenAIは公式に未確認)を外部検索結果より優先する実験が、観測時点でチャットの8%に適用されていることが確認されています。同時にGoogleとBingも使われ続けているため、現在は三層構造と考えるのが正確です。
### 「Labrador」とは何ですか?
Peec AIが2026年9月の分析でOpenAI独自の検索インデックス群に対して用いている呼称で、OpenAIが公式に確認した名称ではありません。一般Web、PDF、YouTube、ニュース、arXiv、Wikipedia、ローカル、金融、法律、医療、ショッピング、画像で構成されるとされています。OpenAIが公式に発表した名称ではなく、SSEメタデータや求人情報などから同社が特定したものです。
### OAI-SearchBotとGPTBotの違いは何ですか?
OAI-SearchBotはChatGPTの検索結果にサイトを表示するためのクローラーで、拒否すると検索回答に表示されません。GPTBotは基盤モデルの学習にコンテンツを使う可能性があるクローラーで、拒否しても検索表示には影響しません。学習を拒否しながら検索には出る設定が可能です。robots.txtの更新は反映まで約24時間かかります。
### JavaScriptで描画しているサイトはChatGPTに引用されませんか?
本文がクライアント側のJavaScriptでしか描画されない構成では、クローラーが取得するHTMLに本文が含まれず、引用候補になりにくくなります。サーバーサイド描画か事前描画で本文を初期HTMLに含めることで対応できます。画像化された表や数値も読まれないため、テキストとして書く必要があります。
### ChatGPT検索の仕組みはどのくらいの頻度で変わりますか?
Peec AIは「このシステムはまだ週単位で再構築されている」と述べており、2026年夏のモデル更新ではファンアウト数が2.17本から7.61本に増えるなど、挙動が短期間で大きく変わりました。引用元も数日で入れ替わるため、特定の仕様に合わせるより、三層すべてに載り、どの段階でも読める状態を保つ設計が安定します。
---
## まとめ:仕様に合わせるのではなく、どの仕様でも読める状態を保つ
ChatGPT検索は、Bing・Google・独自インデックス「Labrador」の三層から取得し、質問を平均7本以上のサブクエリに分解し、読んだうえで数本だけを引用する仕組みです。そしてその仕組みは週単位で作り替えられています。
だからこそ、特定の実験や比率に最適化するのではなく、三層すべてにインデックスされ、クローラーが本文を読め、見出し単位で回答が完結し、公式サイトが名指し検索に耐える状態を保つことが、唯一の安定した方針になります。そのうえで、言及率と引用元を週次で記録し、変動を前提に調整を続けてください。
LinkSurgeの[AI Ready診断](https://linksurge.jp/ai-ready)では、robots.txt・見出し階層・構造化データ・llms.txtなどの土台を項目別に確認できます。ChatGPT Searchでの言及と引用元の定点観測には[GEOモニタリング](https://linksurge.jp/geo)をお使いください。
---
## Z世代の54%が買う前にAIに聞く。それでも信頼するのは検索エンジン — 楽天調査で見えた「AIで絞り、検索で確かめる」時代のGEO×SEO
> URL: https://linksurge.jp/blog/gen-z-ai-shopping-search-trust-2026/
> Date: 2026-09-04 | Category: AIO | Author: 緒方亜朗
> Tags: Z世代, 生成AI, 購買行動, 楽天, AI Overviews, GEO, ChatGPTショッピング, AI検索最適化
## この記事の結論:「AIで絞り、検索で確かめる」購買行動に合わせて5つを整える
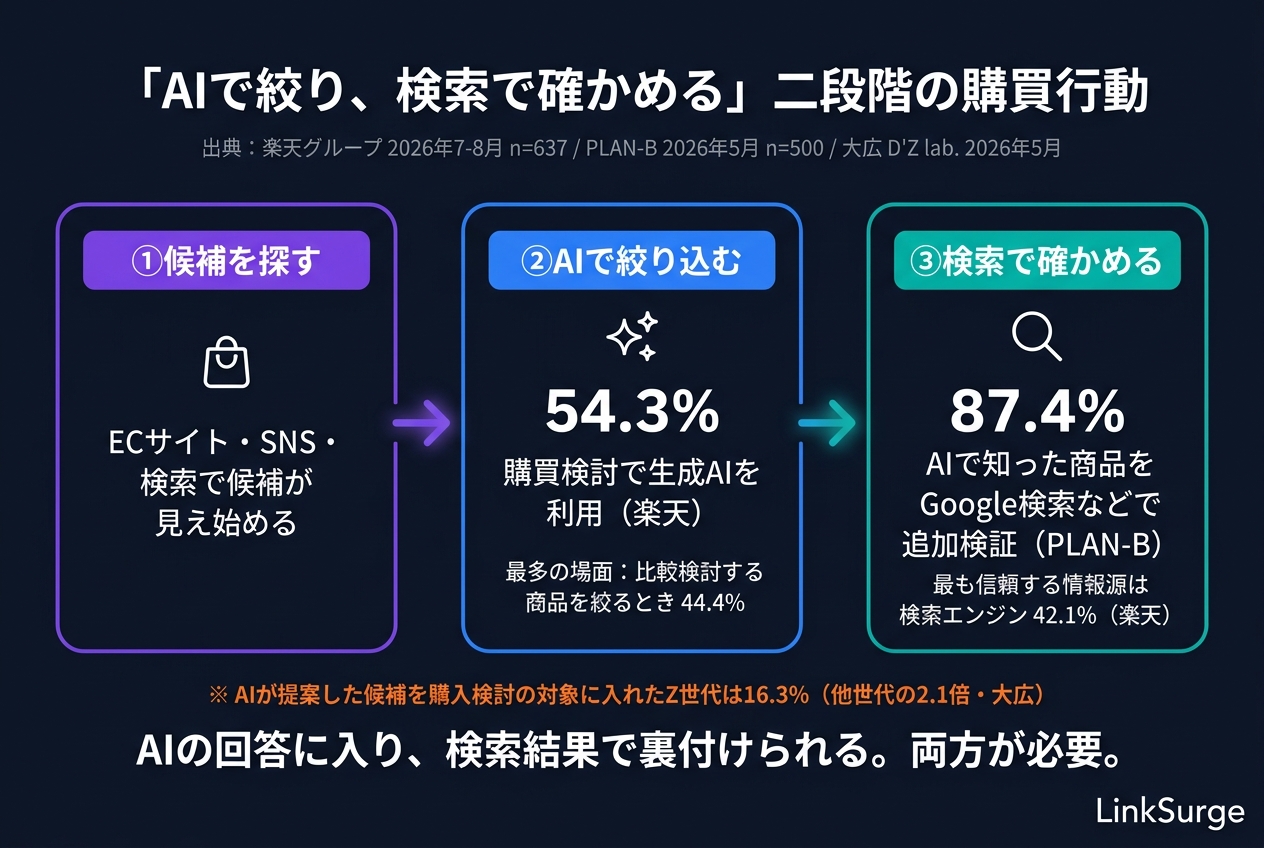
楽天グループが2026年9月4日に公開したZ世代の生成AI利用調査を読んで、私が最初に目を止めたのは並んだ2つの数字でした。商品やサービスの検討・購入時に生成AIを使うZ世代は**54.3%**。それなのに、最も信頼する情報源として挙がったのは生成AIではなく**検索エンジン**(42.1%)です。矛盾に見えますが、他の国内調査と突き合わせると一貫した行動が浮かび上がります。AIで候補を絞り、検索で確かめる。この二段構えに合わせて整えるべき要点は次の5つです。
1. **AIは「絞り込み」の道具になった** — 楽天調査ではAIを使う場面の最多が「比較検討する商品を絞るとき」(44.4%)で、「欲しい商品を探すとき」(27.8%)の1.6倍でした。AIの回答に候補として入れなければ、比較の土俵に上がる前に落とされます
2. **最終判断は検索エンジンで裏取りされる** — PLAN-Bの2026年5月調査では、AIで知った商品を「Google検索などで追加検証する」人が87.4%でした。AIの回答に載った後、ブランド名や比較クエリの検索結果が空白だと、そこで離脱が起きます
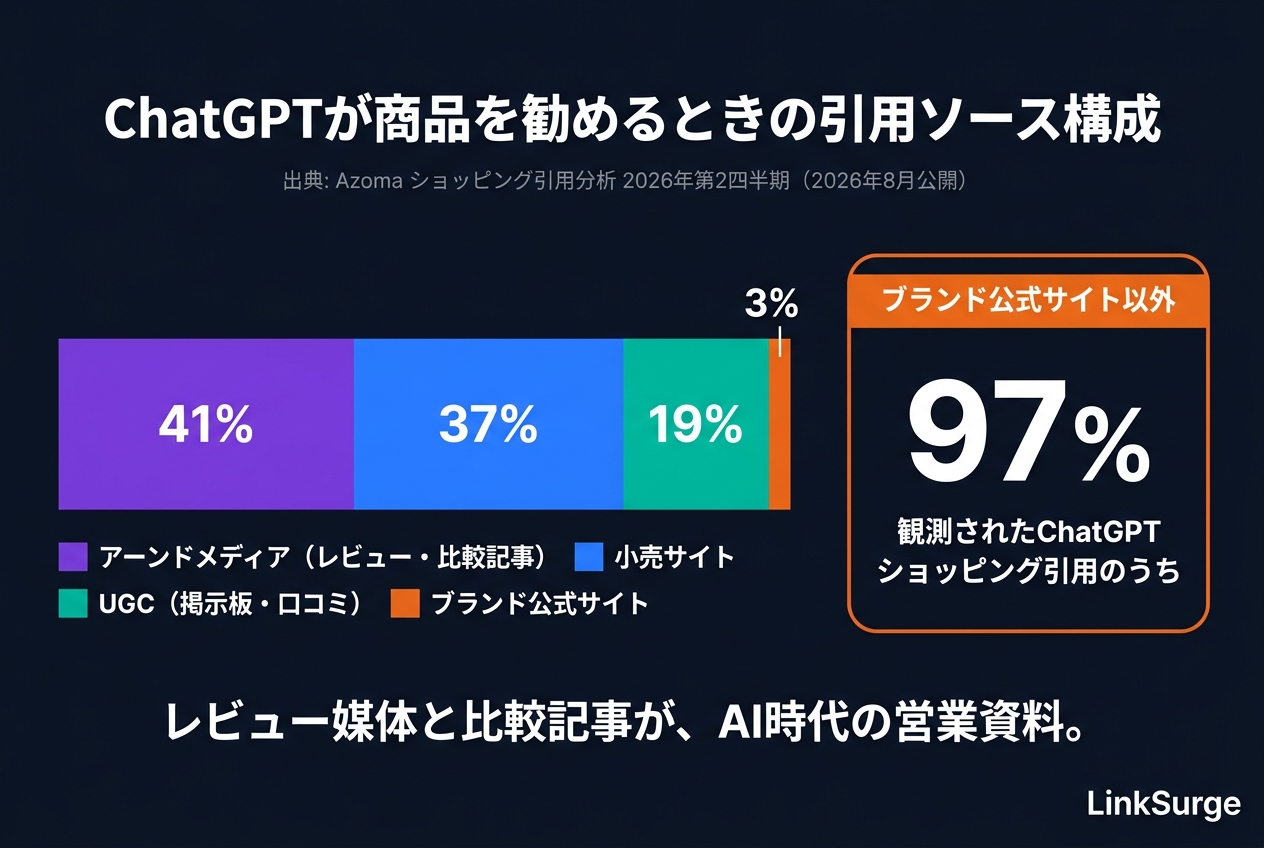
3. **ChatGPTのショッピング引用のうち、ブランド公式サイトはカテゴリ全体で3%** — Azomaの2026年Q2分析では、観測された引用ソースはアーンドメディア41%、小売サイト37%、UGC19%、ブランド公式サイト3%でした。残る97%は第三者のレビュー・比較記事・小売サイト・UGCで、これらが実質的な「営業資料」です
4. **購買系クエリではAI Overviewsより従来の検索結果が主戦場** — Semrushの2025年11月〜2026年4月調査で、商用クエリのAI Overviews出現は71%増えた一方、取引系クエリでは5%減少しました。「確かめる検索」では10本の青いリンクがまだ生きています
5. **計測は「AIの回答」と「検索結果」の両方で行う** — ChatGPT・Gemini・Perplexity・AI Overviewsでの言及と引用元、そしてブランド名・比較クエリの検索順位を同じダッシュボードで追う。片方だけ見ていると、導線のどこで切れているかが分かりません
以下では、楽天調査の中身から実行プランまでを順に見ていきます。要点は動画でも解説しています。
{{youtube:Y7VkQlHWdCg|Z世代の54%が買う前にAIに聞く。それでも信頼するのは検索エンジン — 楽天調査で見えた「AIで絞り、検索で確かめる」時代のGEO×SEO}}
---
## 1. 楽天調査が示した「使うけれど、信じ切ってはいない」Z世代
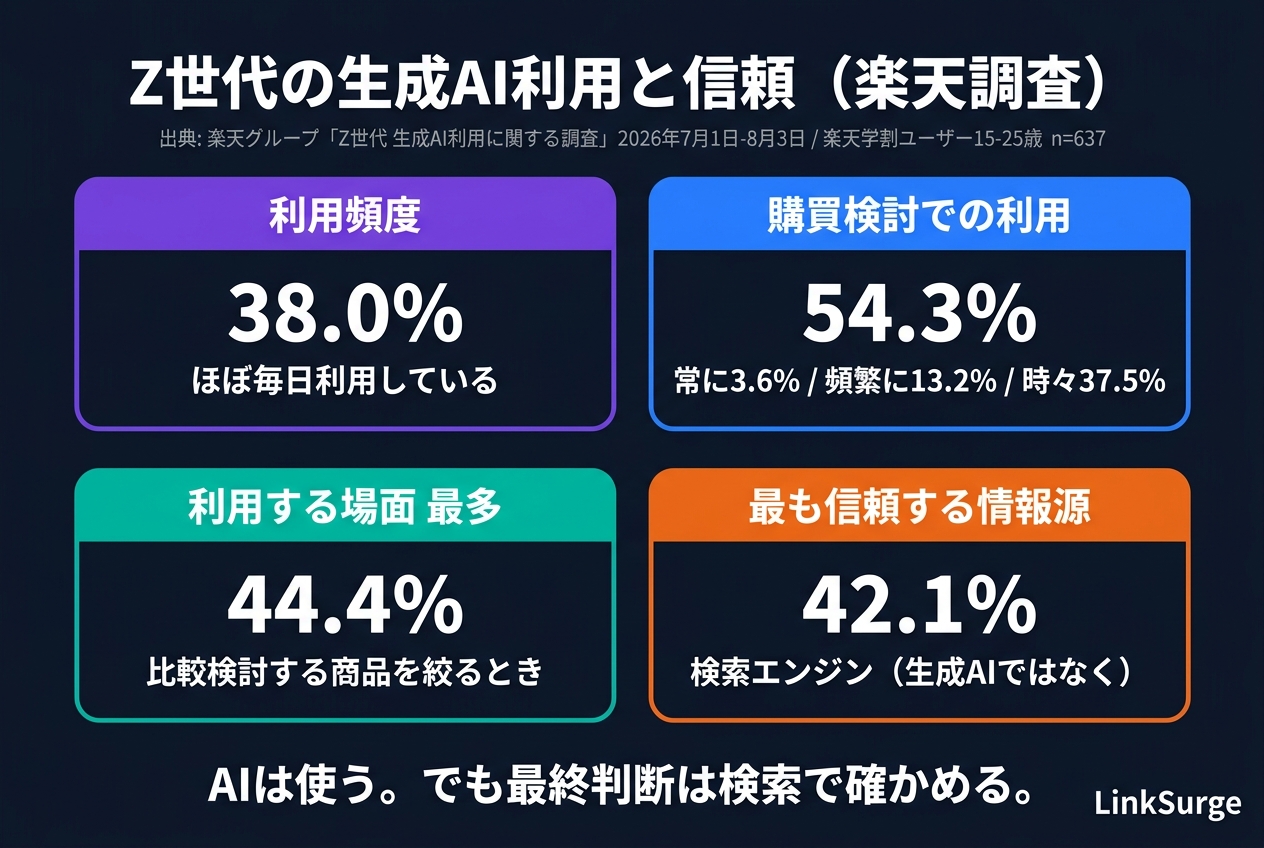
まず一次情報を正確に押さえておきます。調査主体は楽天グループ株式会社で、若年層向けプログラム「楽天学割」のユーザー(15〜25歳)637名を対象に、2026年7月1日〜8月3日にインターネット調査を実施したものです。母集団が楽天学割の登録者に限られる点は、数字を読むときに頭に置いておく必要があります。
### 生成AIは日常のインフラになりつつある
利用頻度は「ほぼ毎日利用している」が38.0%で最多でした。用途は「勉強・学習」(62.6%)、「趣味に関する情報検索」(47.0%)、「悩み相談やアドバイスを受ける」(30.9%)の順です。勉強・学習の場面でAIの情報を「信頼している」と答えた人は48.5%(「非常に信頼している」7.8%+「やや信頼している」40.7%)でした。半数近くが信頼しつつ、残りの半数は留保している。この温度感が、購買の場面でも同じ形で現れます。
### 商品検討での利用率と、利用する「場面」
商品やサービスの検討・購入時に生成AIを使う人は54.3%でした。内訳は「常に利用する」3.6%、「頻繁に利用する」13.2%、「時々利用する」37.5%です。過半数が使っているとはいえ、常用者は2割弱で、多くは「時々」の利用にとどまります。
| 生成AIを使うタイミング(利用者ベース) | 割合 |
|:---|---:|
| 比較検討する商品を絞るとき | 44.4% |
| 欲しい商品やサービスを探すとき | 27.8% |
| ECサイトを見ながら | 11.3% |
面白いのは、この順番です。ゼロから探す場面より、ある程度候補が見えた後に「絞る」場面でAIが使われています。ECサイトを見ながら並行して聞く人は1割強にとどまりました。
### それでも「最も信頼する情報源」は検索エンジン
商品検討時に最も信頼している情報源を尋ねると、「検索エンジン」が42.1%で最多でした。リリースはこれを「生成AIを絞り込みに使いながらも、情報収集の手段として従来の検索エンジンが高く信頼されている」と総括しています。AIを使うことと、AIを信じることは別だというわけです。
楽天自身のAI施策に対する評価も載っています。楽天が生成AIでサービス改善を進めることに「好感が持てる」と答えた人は40.8%、楽天市場などを利用する前に生成AIで商品情報を集める人は30.6%(「いつもする」3.9%+「時々する」26.7%)でした。AIを導入している企業への印象は「好印象」が31.7%で、イメージの上位は「先進的」(43.6%)、「チャレンジ精神がある」(26.7%)、「自分たちの世代に合っている」(17.4%)です。
> 参考・引用:
> [楽天、Z世代における「生成AI利用に関する調査」結果を発表 - 楽天グループ株式会社](https://corp.rakuten.co.jp/news/press/2026/0904_01.html)
---
## 2. 他の国内調査と突き合わせると「二段構え」が見えてくる
楽天調査だけでは「楽天学割ユーザーの傾向」で終わってしまいます。そこで、2026年に公開された他の3つの調査を並べてみました。母集団も設問も違うので数字を直接比べることはできませんが、方向は驚くほど揃っています。
| 調査 | 実施時期・対象 | 主要な数値 |
|:---|:---|:---|
| 楽天グループ | 2026年7〜8月、楽天学割ユーザー15〜25歳 n=637 | 商品検討でAI利用54.3%、最信頼は検索エンジン42.1% |
| PLAN-B | 2026年5月11〜16日、生成AIを日常利用する10〜60代 n=500 | AIきっかけの商品購入経験54.1%(前年比+11.4pt)、Google検索などで追加検証87.4% |
| 大広 D'Z lab. | 2026年5月(定量)、分析対象4,034人 | Z世代のAI活用率56.5%(他世代の約1.45倍)、AIが提案した候補を購入検討の対象に入れた割合16.3%(他世代7.6%) |
| エクスクリエ | 2026年4月24〜27日、月1回以上AIを使う15〜69歳 n=1,190 | 買い物でAIを使った経験69.9%(n=1,190)、そのうちAIが勧めた商品を実際に購入61.3%(買い物でAIを使った人 n=832) |
### なぜ「AIで絞り、検索で確かめる」と言えるのか
決め手はPLAN-Bの追加検証の数字です。生成AIとの対話で商品を知った人のうち、Google検索などで追加検証する人が87.4%、Amazonなどのモール型ECで確かめる人が34.4%、SNSで確かめる人が34.1%でした。楽天調査の「最も信頼するのは検索エンジン」と、PLAN-Bの「AIで知った後に検索で確かめる」は、別の母集団で同じ行動を別の角度から写しています。
一方で、大広の調査は「AIが提案した候補を購入検討の対象に入れた」割合がZ世代で16.3%と、他世代(7.6%)の2.1倍だと報告しています。裏取りをする人が大半でも、AIの提案が検討候補に採用される割合は若年層で明らかに高い。この2つは矛盾しません。AIの回答に入ることの価値が、若い世代ほど大きくなっているということです。
私が実務で見ていても、ブランド名での指名検索が「AIに聞いた後の裏取り」として動くケースが増えています。AIの回答に自社が載った直後にブランド名検索が跳ね、その検索結果でレビューや比較記事が薄いと、そこで別ブランドに流れる。地図で目的地を決めた後、現地の看板が見つからず引き返すようなものです。
Z世代の検索行動の変化そのものは、TikTokを検索エンジンとして使う動きとあわせて「[TikTok検索最適化の教科書](/blog/tiktok-seo-ai-search-2026/)」で扱っています。
> 参考・引用:
> [「AIきっかけ」の商品購入は半数超に。生成AIとの対話による購買行動調査 2026 - PLAN-B](https://www.plan-b.co.jp/news/ai_purchase_report_202606/)
> [Z世代のAI活用率は56.5%、他世代の約1.45倍 - 大広](https://www.daiko.co.jp/daiko-topics/2026/083110001011148)
> [日常生活・買い物における生成AI活用実態調査(2026年) - エクスクリエ](https://www.excrie.co.jp/report/generativeai-lifestyle-survey-202605)
---
## 3. AIは商品を勧めるとき、何を読んでいるのか
「AIに絞り込まれる側」に回るには、AIが候補を選ぶときに何を根拠にしているかを知る必要があります。ここで役に立つのが、AIコマース分析を手がけるAzomaがDigital Shelf Instituteと共同で公開しているデータです。
### 自社サイトは3%、残りは第三者の手にある
Azomaが2026年8月に公開した分析によると、ChatGPTがショッピング系の質問に答えるときの引用ソースは、アーンドメディア(レビューサイト・メディア記事など)が41%、小売サイトが37%、UGCが19%、ブランド公式サイトが3%でした。対象は2026年第2四半期の数百万件規模の引用です。
| 引用ソース | 割合 |
|:---|---:|
| アーンドメディア(レビュー・比較記事・専門メディア) | 41% |
| 小売サイト(ECモールなど) | 37% |
| UGC(掲示板・コミュニティ・口コミ) | 19% |
| ブランド公式サイト | 3% |
率直に言って、この3%は多くのブランドにとって不都合な数字です。これは「ブランド公式サイト」というカテゴリ全体の合計であって個別ブランドの数字ではありませんが、観測されたChatGPTの引用の97%が公式サイト以外から来ていた以上、商品ページを磨くだけでは引用元の大半に手が届きません。Azomaは「小売サイトの掲載だけに投資したブランドは、ChatGPTが引用するソースの3分の1強しかカバーできていない」と指摘しています。
### AIエージェントごとに「主食」が違う
同社が2026年6月に発表したフレームワーク「The 5 C's of Agentic Commerce」の基礎データでは、エージェントごとの偏りも示されています。AmazonのAlexa for Shoppingは引用の86.5%がアーンドメディア、WalmartのSparkyは76%。一方、ChatGPTは37.1%、Geminiは41.6%を小売サイトから直接引用していました。どのAIに載りたいかで、力を入れるべき情報源が変わるわけです。
UGCが引用される仕組みと、日本市場でYahoo!知恵袋やnoteが果たす役割は「[UGC × AI検索引用戦略](/blog/ugc-ai-search-brand-mentions-2026/)」で詳しく扱っています。AIの引用元は数週間単位で入れ替わることがあり、Promptwatchのデータでは2026年8月にChatGPT SearchでのReddit引用シェアが4日間で86.4%低下しました(原因は未確定)。特定媒体への依存はそれ自体がリスクです。
こうした引用元の把握には、AIの回答を定点で記録する仕組みが要ります。[LinkSurge](https://linksurge.jp/)のGEOモニタリングでは、ChatGPT Search・Gemini・Google AI Overviews・Claude・Perplexityの5媒体に対して「〇〇 おすすめ」「A B 比較」といった絞り込み系のクエリを登録し、自社ブランドの言及有無と引用されたURLを媒体別に記録できます。誰が引用されているかが分かれば、次に取りに行くべきレビュー媒体や比較記事が見えてきます。
> 参考・引用:
> [What Sources Does ChatGPT Cite for Products? Azoma Publishes the Data - GlobeNewswire](https://www.globenewswire.com/news-release/2026/08/26/3351631/0/en/what-sources-does-chatgpt-cite-for-products-azoma-publishes-the-data-and-explains-how-brands-get-recommended.html)
> [Azoma and Digital Shelf Institute Launch "The 5 C's of Agentic Commerce" - Business Wire](https://www.businesswire.com/news/home/20260604759368/en/Azoma-and-Digital-Shelf-Institute-Launch-The-5-Cs-of-Agentic-Commerce-to-Rescue-Brands-From-AI-Pilot-Purgatory)
> [Reddit's ChatGPT Search citations fell 86% in four days - Search Engine Land](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473)
---
{{linksurge-card}}
## 4. 「確かめる検索」で消えないために
AIの回答に入れたとしても、導線はまだ半分です。楽天調査の42.1%とPLAN-Bの87.4%が示す通り、Z世代はその後に検索エンジンで確かめます。ここで問われるのは従来型のSEOです。ただし、AI Overviewsの拡大で検索結果の見え方も変わっているので、その現状を押さえておきましょう。
### 購買系クエリでAI Overviewsはどこまで出ているか
Semrushが2026年7月に公開した調査は、米国デスクトップの60万以上のキーワードを2025年11月〜2026年4月の6か月間追跡したものです。商用(commercial)クエリでAI Overviewsが出る割合は期間中に71%増えました。一方、取引(transactional)クエリでは5%減っています。「おすすめ」「比較」のような検討段階のクエリにはAI Overviewsが広がり、「購入」「通販」のような最終段階では従来の検索結果が残っている、という構図です。
なお、この数字は米国のデータです。日本語クエリでの出現率は業種とクエリ種別で大きく変わるため、自社の主要クエリで個別に確認するのが確実です。[LinkSurge](https://linksurge.jp/)のAIO表示最適化分析なら、キーワードと自社URLを入れると、AI Overviewsの有無、引用されたURLの一覧、自社URLが引用されているかどうかまで確認できます。
### 裏取り検索で見られる3種類のクエリ
私が調べた範囲で、AIの回答に載った後に動く検索は大きく3種類に分かれます。
| クエリの種類 | 例 | 検索結果に必要なもの |
|:---|:---|:---|
| 指名+評判 | 「ブランド名 口コミ」「商品名 評判」 | 第三者レビュー、Q&A、公式のFAQ |
| 比較 | 「A B 違い」「商品名 vs 競合名」 | 比較記事、スペック表、価格の根拠 |
| 購入条件 | 「商品名 価格」「商品名 送料」「商品名 在庫」 | 正確な商品ページ、構造化データ、モール掲載 |
指名+評判クエリで自社ページしか出てこない状態は、Z世代にとって「確かめられなかった」に等しい結果です。第三者のレビューや比較記事が検索結果の1ページ目に並んでいるかどうかを、AIでの言及と同じ頻度で見ておく必要があります。
AI検索時代に検索結果の側で何が変わったかは「[生成AI検索がSEOを変える:7つの実践対策](/blog/ai-search-seo-japan-2026/)」でも整理しています。
> 参考・引用:
> [AI Overviews are expanding across commercial intent search [Study] - Semrush](https://www.semrush.com/blog/ai-overviews-commercial-search-study/)
---
## 5. 楽天市場のAIコンシェルジュが示す、EC側の変化
楽天のリリースは調査結果だけでなく、自社のAI施策も紹介しています。2025年12月から楽天市場アプリに搭載されたエージェント型の「Rakuten AI」は、予算・購入目的・利用シーンをテキスト・音声・画像で入力すると、約5億点の商品から候補を提案します。AIコンシェルジュの質問に答えながら対話を進めることで、潜在的なニーズを引き出す設計です。
### モール内AIが入口になると、商品ページは「AIが読む一次資料」になる
ここで起きているのは、AIの絞り込みがECモールの中にも入り込んできたということです。外部のChatGPTで絞られ、モール内のAIでさらに絞られ、最後に検索で確かめられる。商品ページの説明文、スペック、レビューは、人間が読む販促文であると同時に、モール内AIが候補を選ぶための資料になります。
Azomaのデータで小売サイトからの引用がChatGPTで37.1%、Geminiで41.6%を占めていたことを思い出してください。モールの商品ページが正確で網羅的であることは、モール内AIだけでなく外部AIの引用にも効いてきます。逆に、在庫や価格の記載が古い、スペックが本文に書かれていない、といった状態は、AIの候補から外れる理由になります。
構造化データや見出し階層、llms.txtの有無など、ページがAIに読まれやすい状態かどうかは[LinkSurge](https://linksurge.jp/)のAI Ready診断で項目別に確認できます。商品ページと比較記事の両方を診断しておくと、どちらの改善が先かを判断しやすくなります。
> 参考・引用:
> [楽天、Z世代における「生成AI利用に関する調査」結果を発表 - 楽天グループ株式会社](https://corp.rakuten.co.jp/news/press/2026/0904_01.html)
---
## 6. 30日で整える実行プラン
ここまでの内容を落とし込みます。AIの絞り込みと検索の裏取り、両方に出ることを目標に、30日で以下の順に進めます。
### 第1週:監視クエリの設計と現状把握
1. 自社カテゴリの「絞り込み系クエリ」を10〜20本書き出す(「カテゴリ名 おすすめ」「用途 向け 商品」「A B 比較」など)
2. 各クエリをChatGPT・Gemini・Perplexity・AI Overviewsで実際に検索し、自社の言及有無と引用URLを記録する
3. 同じクエリと指名系クエリの検索順位、1ページ目に並ぶ第三者ページを記録する
この段階では、手動でも構いません。ただし週次で続けるなら、AI回答の変化を自動で記録する仕組みがあった方が、変動の大きさに振り回されずに済みます。
### 第2週:引用されている第三者媒体の特定
1. 第1週で記録した引用URLをドメイン別に集計し、レビューサイト・比較メディア・UGCの3種に分類する
2. 競合が引用されていて自社が引用されていない媒体を優先順位付けする
3. レビュー依頼、専門メディアへの情報提供、Q&Aサイトでの回答など、媒体ごとの取り組みを決める
### 第3週:自社ページと商品ページの整備
1. 商品ページにスペック・価格・在庫・比較対象との違いを本文として明記する
2. Product・Offer・FAQPageなどの構造化データを付与し、記載内容と実データの不一致をなくす
3. 指名+評判クエリに対応する公式FAQページを用意する
### 第4週:裏取り導線の確認と計測の固定化
1. 指名系・比較系クエリの検索結果1ページ目に、自社以外の裏付けページが並んでいるかを確認する
2. AI言及率・引用元ドメイン・指名検索順位を同じ表にまとめ、週次の定点観測に切り替える
3. 楽天市場など主要モールのAIアシスタントで自社商品を検索し、提案に出るかを確認する
---
## よくある質問(FAQ)
### Z世代は商品を買うときに生成AIをどのくらい使っていますか?
楽天グループが2026年7〜8月に楽天学割ユーザー637名(15〜25歳)を対象に行った調査では、商品やサービスの検討・購入時に生成AIを使う人は54.3%でした。内訳は「常に利用」3.6%、「頻繁に利用」13.2%、「時々利用」37.5%です。利用する場面は「比較検討する商品を絞るとき」が44.4%で最多でした。
### AIを使うのに、なぜ最も信頼する情報源は検索エンジンなのですか?
同じ楽天調査で、商品検討時に最も信頼する情報源は「検索エンジン」が42.1%で最多でした。PLAN-Bの2026年5月調査でも、生成AIで知った商品をGoogle検索などで追加検証する人が87.4%に上ります。AIは候補を絞る道具として使われ、最終判断の前には検索で裏取りされる、という二段構えの行動が複数の調査で確認できます。
### ChatGPTが商品を勧めるとき、どんなサイトを引用していますか?
Azomaが2026年8月に公開した2026年第2四半期の分析では、ChatGPTのショッピング系引用はアーンドメディア41%、小売サイト37%、UGC19%、ブランド公式サイト3%でした。この3%はブランド公式サイトというカテゴリ全体の合計です。公式サイトだけを整備しても観測された引用の大半には届かないため、レビュー媒体・比較記事・モールの商品ページを含めた対策が必要です。
### 購買系のキーワードにもAI Overviewsは表示されますか?
Semrushが2025年11月〜2026年4月に米国の60万以上のキーワードを追跡した調査では、商用(commercial)クエリでのAI Overviews出現は71%増えた一方、取引(transactional)クエリでは5%減少しました。「おすすめ」「比較」の段階ではAI Overviewsが広がり、「購入」「通販」の段階では従来の検索結果が主戦場です。日本語クエリでの出現率は業種差が大きいため、自社の主要クエリで個別に確認してください。
### AIでの言及と検索順位、どちらを優先して計測すべきですか?
両方を同じ表で追うことを推奨します。AIの言及率だけを見ていると「絞り込みには入るが裏取りで消える」状態に気付けず、検索順位だけを見ていると「そもそもAIの候補に入っていない」状態に気付けません。絞り込み系クエリのAI言及率と引用元ドメイン、指名系・比較系クエリの検索順位を週次で並べて記録すると、導線のどこが切れているかが分かります。
---
## まとめ:AIに絞り込まれ、検索で確かめられる状態をつくる
楽天調査が示したのは、Z世代がAIを信じ切ったわけではなく、AIと検索を役割分担させているという事実でした。候補を絞るのはAI、最後に確かめるのは検索エンジン。この順番で購買が進む以上、どちらか一方に強いだけでは途中で導線が切れます。
最初に取り組むべきは、自社カテゴリの絞り込み系クエリでAIが誰を引用しているかを把握することです。観測された引用元の97%がブランド公式サイト以外だった以上、レビュー媒体と比較記事への働きかけが、商品ページの改善と同じか、それ以上の優先度になります。並行して、指名検索と比較検索の結果1ページ目に第三者の裏付けが並ぶ状態を作っておきましょう。
LinkSurgeの[GEOモニタリング](https://linksurge.jp/geo)では、ChatGPT・Gemini・Perplexity・AI Overviews・Claudeでの自社ブランドの言及と引用元URLを定点で記録し、競合との比較まで確認できます。AI側と検索側の両方を1つの画面で追いたい方は、本記事の30日プランとあわせてお試しください。
---
## SEOはどう変わってきたか — キーワードを詰め込めば勝てた1990年代から、AIに引用される2026年までの30年を一気に振り返る
> URL: https://linksurge.jp/blog/seo-history-keywords-to-ai-2026/
> Date: 2026-09-04 | Category: SEO | Author: 緒方亜朗
> Tags: SEOの歴史, Googleアルゴリズム, AI Overviews, AI Mode, GEO, E-E-A-T, PageRank, AI検索最適化
## この記事の結論:SEOは5つの時代を経て「順位」から「引用」へ移った
AI検索の話題が毎週のように更新される今、私は逆に、30年分の変化を一枚の年表に並べ直してみました。すると、「激変」に見える2024年以降の動きが、実は1990年代から続く同じ方向の延長線上にあることが分かります。要点は次の5つです。
1. **SEOは5つの時代を通過してきた** — ディレクトリとキーワードの時代(1994〜2002)、リンクの時代(2003〜2010)、品質の時代(2011〜2014)、意図とモバイルの時代(2015〜2021)、そしてAI引用の時代(2022〜)。各時代の境目には、前の時代の「勝ち方」を無効化するアップデートがあります
2. **変わったのは「誰が評価するか」と「成果の形」** — 評価者は人手のディレクトリ編集者から、リンク計算、機械学習、言語モデルへ移り、成果は「1位表示とクリック」から「AIの回答に引用・言及されること」へ広がりました
3. **30年間変わらないものが3つある** — ユーザーの課題に直接答えること、機械が読める構造にすること、信頼できる発信者だと証明すること。抜け道が塞がれるたびに、この3つの比重が上がってきました
4. **2026年の現在地は数字で確認できる** — 米国のゼロクリック率は68.01%(SparkToro、2026年1〜4月)、AI Overviewsの表示率は43〜48%(Similarweb・Semrush、2026年7月)、商用クエリでのAI Overviews出現は6か月で71%増(Semrush)。Z世代の54.3%が購買検討に生成AIを使い、最も信頼するのは検索エンジン(楽天、2026年9月)です
5. **過去の技術は捨てるものではなく、積み上げるもの** — クロール可能な構造、モバイル対応、E-E-A-Tの証明はAI検索でも前提です。その上に、引用されやすい構造と、AI側での計測を足すのが2026年の作業です
以下では、時代ごとに「何が起きて、何が通用しなくなったか」を追い、最後に今やるべき順序を整理します。年表の要点は動画でも解説しています。
{{youtube:7_4j_wXtJRk|SEOはどう変わってきたか — キーワードを詰め込めば勝てた1990年代から、AIに引用される2026年までの30年を一気に振り返る}}
---
## 1. 1994〜2002年:ディレクトリとキーワードの時代
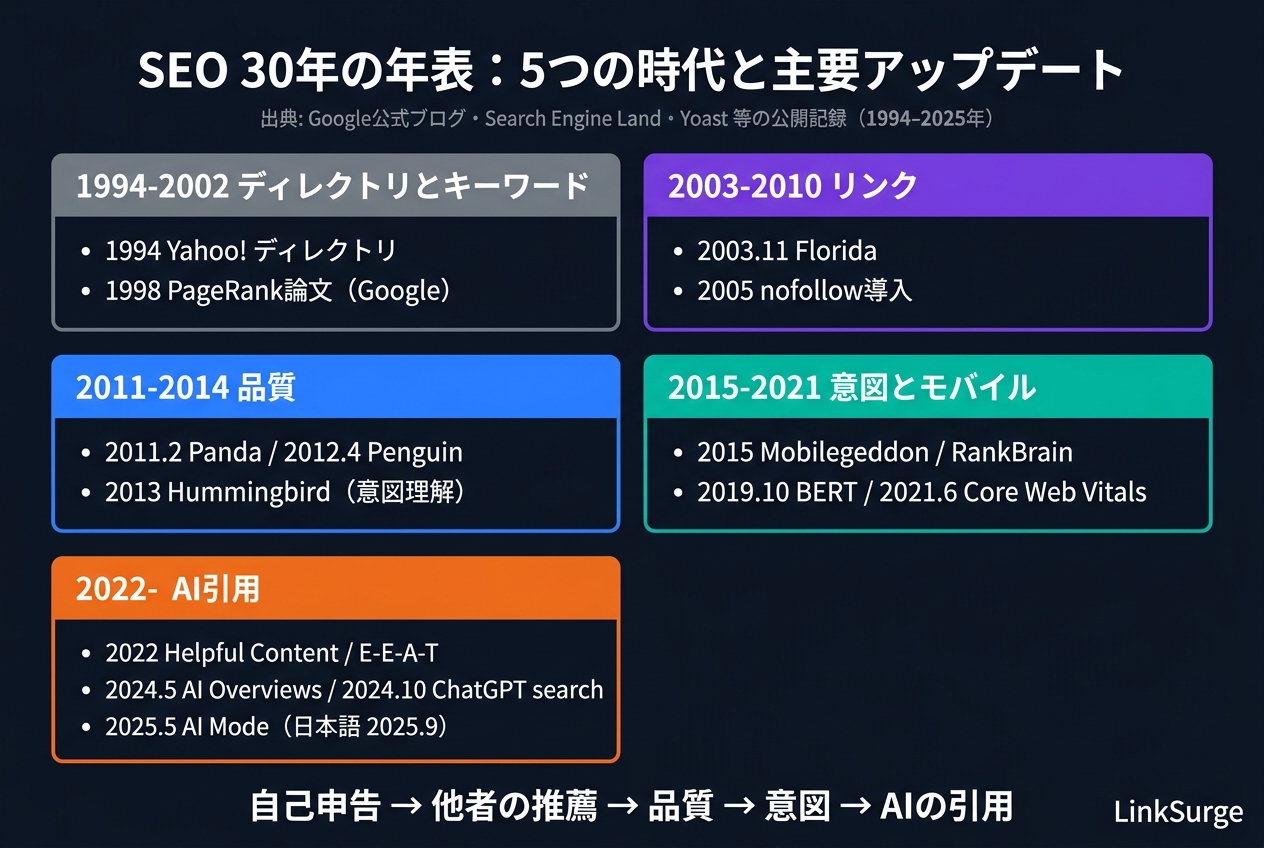
率直に言って、この頃のSEOは単純でした。検索エンジンがページの内容を理解する手段が乏しかったので、ページ側が「このページは何について書いてあるか」を自己申告すれば、それがほぼそのまま評価されたからです。
### 人手のディレクトリから全文検索へ
1994年1月、スタンフォード大学の大学院生だったジェリー・ヤンとデビッド・ファイロが「Jerry and David's Guide to the World Wide Web」を公開しました。これが後のYahoo!で、階層化されたカテゴリにサイトを人手で登録していく「ディレクトリ」でした。1994年9月時点で2,000サイト以上、1日5万件の検索があったと記録されています。当時の「SEO」は、適切なカテゴリに登録申請を出すことでした。
その後、AltaVistaなどの全文検索エンジンが登場し、ページ本文とメタタグに書かれた語句がそのまま評価対象になります。ここで生まれたのが、metaタグのkeywords属性に狙った語句を並べ、本文にも同じ語句を繰り返す「キーワードスタッフィング」です。背景色と同じ色で文字を隠す、といった手法も横行しました。
### 1998年、PageRankがゲームを変えた
1998年、セルゲイ・ブリンとラリー・ペイジが論文「The Anatomy of a Large-Scale Hypertextual Web Search Engine」を発表します。ページ自身の申告ではなく、他のページからのリンク構造を使ってページの重要度を計算するPageRankの考え方です。「他人がどれだけ推薦しているか」を評価に使う発想は、この後20年以上にわたってSEOの中心に居座ります。
ちなみに、メタキーワードについてGoogleは2009年に「ランキングには使っていない」と公式に明言しています。最初の時代の「勝ち方」は、この時点で完全に過去のものになりました。
> 参考・引用:
> [History of Yahoo - Wikipedia](https://en.wikipedia.org/wiki/History_of_Yahoo)
> [The Anatomy of a Large-Scale Hypertextual Web Search Engine - Stanford InfoLab](http://infolab.stanford.edu/pub/papers/google.pdf)
> [Google does not use the keywords meta tag in web ranking - Google Search Central Blog](https://developers.google.com/search/blog/2009/09/google-does-not-use-keywords-meta-tag)
---
## 2. 2003〜2010年:リンクの時代
PageRankが評価の中心になると、SEOの主戦場は「リンクをどう集めるか」に移ります。この時代を一言で表すなら、「リンクは通貨だった」です。
### Floridaアップデートが示した「抜け道は塞がれる」
2003年11月16日、Googleは後に「Florida」と呼ばれる大規模なアップデートを実施しました。年末商戦の直前というタイミングで、キーワードの詰め込み、クローキング、ドアウェイページといった手法に頼っていたサイトが大量に順位を落とし、小規模な小売やアフィリエイトサイトが一夜で消えたと当時の記録にあります。SEO業界では「最初の大規模アップデート」として語り継がれている出来事です。
### リンク売買とnofollow
一方で、リンクの価値が明確になったことで、リンクを買う、相互リンク集を作る、無関係なディレクトリに大量登録する、ブログのコメント欄にリンクを書き込む、といった「リンク集め」が産業化しました。Googleは2005年1月、コメントスパム対策としてrel="nofollow"属性を導入し、「このリンクは推薦ではない」と明示する手段を用意しました。それでも有料リンクとリンクファームは2010年代初頭まで有効な手法として使われ続けます。
私がこの業界に入った頃にも、被リンク数がそのまま営業資料になっていた時代の名残がありました。リンクの「数」が評価される限り、数を作る側が勝ってしまう。この構造的な問題を、Googleは次の時代で正面から潰しにかかります。
サテライトサイトや過剰なリンク構築がなぜ今も危険なのかは「[サテライトサイトのSEOリスクと安全なリンク構築](/blog/satellite-site-seo-risks-2026/)」で扱っています。
> 参考・引用:
> [Google's Florida update: 20 years since the SEO 'volcanic eruption' - Search Engine Land](https://searchengineland.com/google-florida-update-434540)
> [Google Florida: The First Major Algorithm Update - Search Engine Journal](https://www.searchenginejournal.com/google-algorithm-history/florida-update/)
> [Preventing comment spam - Official Google Blog (2005)](https://googleblog.blogspot.com/2005/01/preventing-comment-spam.html)
---
## 3. 2011〜2014年:品質の時代
リンクの時代の終わりを告げたのが、2011年から2013年にかけての3つのアップデートです。ここでSEOは「テクニックの競争」から「コンテンツと信頼の競争」に軸足を移し始めます。
| アップデート | 時期 | 狙い |
|:---|:---|:---|
| Panda | 2011年2月 | 薄い内容、コピー、広告過多のページを下げる |
| Penguin | 2012年4月24日 | 不自然なリンク(購入・リンクファーム)でのランキング操作を下げる |
| Hummingbird | 2013年 | クエリの語句ではなく意図を理解するコアアルゴリズムの刷新 |
### PandaとPenguinで「量」が通用しなくなった
Pandaは、キーワードに合わせて大量生産された薄いページを持つサイト全体の評価を下げました。コンテンツファームと呼ばれた業態が直撃を受けたのがこの時です。翌年のPenguinは、リンクの時代に蓄積された有料リンクとリンクファームを狙い撃ちしました。「リンクは通貨」だった時代の資産が、一転して負債になった瞬間です。
### Hummingbirdで「意図」が入ってきた
2013年のHummingbirdは、ペナルティではなく検索エンジンの中身の入れ替えでした。「東京 子連れ レストラン」という語句の一致ではなく、「子どもを連れて東京で食事したい」という意図を理解して結果を返す方向へ舵を切ったのです。面白いのは、この2013年の方向転換が、2019年のBERTや2024年以降のAI検索に直接つながっていることです。語句の一致から意図の理解へ。SEOはここから「検索意図」を扱う仕事になりました。
検索意図の4分類と分析手法は「[検索意図とは?SEOにおける4つの分類と分析・最適化の実践ガイド](/blog/search-intent-seo-guide/)」で解説しています。
> 参考・引用:
> [A brief history of Google's algorithm updates - Yoast](https://yoast.com/google-algorithm-updates/)
> [A Timeline of Google Algorithm Updates - BrightEdge](https://www.brightedge.com/blog/a-timeline-of-googles-algorithm-updates)
---
## 4. 2015〜2021年:意図とモバイルの時代
品質の基準が定まった後、Googleは「どの端末で、どんな体験で、どんな言葉で」検索されているかを評価に取り込んでいきます。この時代の主役は機械学習とスマートフォンです。
### モバイルが前提になった
2015年4月21日、モバイルフレンドリーかどうかをランキング要因に加えるアップデートが実施されました。業界では「Mobilegeddon」と呼ばれたものです。2018年3月26日にはモバイルファーストインデックスの展開が公式に始まり、Googleはページのモバイル版を基準にクロール・評価するようになりました。PCサイトを作ってからモバイル版を用意する、という順番が逆転した時期です。
### RankBrainとBERT、機械学習が検索の中に入った
2015年10月、GoogleはBloombergの取材でRankBrainの存在を明かします。見たことのないクエリの解釈に機械学習を使う仕組みで、当時「リンクとコンテンツに次ぐ3番目に重要な要因」と説明されました。2019年10月22日にはBERTが導入され、クエリの中の語句の前後関係を双方向に読んで意図を捉えるようになります。私が実際に順位変動を追っていても、BERT以降は「対策キーワードを含めたかどうか」より「質問にきちんと答えているかどうか」で結果が動く場面が明らかに増えました。
### Core Web Vitalsで「体験」が指標化された
2021年6月16日から展開されたページエクスペリエンスアップデートで、LCP・FID(後にINP)・CLSというCore Web Vitalsがランキングシグナルに加わりました。表示速度やレイアウトの安定性といった、それまで「あった方がよい」だった要素が、測定可能な基準として明文化されたわけです。
> 参考・引用:
> [Mobilegeddon - Wikipedia](https://en.wikipedia.org/wiki/Mobilegeddon)
> [Google begins to roll out mobile-first indexing - TechCrunch](https://techcrunch.com/2018/03/26/google-begins-to-roll-out-its-mobile-first-index/)
> [Google Turning Its Lucrative Web Search Over to AI Machines - Bloomberg](https://www.bloomberg.com/news/articles/2015-10-26/google-turning-its-lucrative-web-search-over-to-ai-machines)
> [Timing for bringing page experience to Google Search - Google Search Central Blog](https://developers.google.com/search/blog/2020/11/timing-for-page-experience)
---
## 5. 2022〜2024年:AI引用の時代(前半)— 「役に立つか」が問われ、AIが検索結果に入ってきた
ここまでを押さえたところで、第5の時代である「AI引用の時代」を前半と後半に分けて見ていきます。2022年から2024年は、Googleが「誰のために書かれたコンテンツか」を問い始め、同時に生成AIが検索結果そのものに組み込まれた時期です。
### Helpful Content UpdateとE-E-A-T
2022年8月18日、Googleは「検索エンジンのためではなく人のために書かれたコンテンツ」を評価するHelpful Content Updateを開始しました。同年12月には検索品質評価ガイドラインが改訂され、E-A-Tに「Experience(経験)」が加わってE-E-A-Tになります。実際に使った・試した・経験した人の一次情報を重視する姿勢が明文化された形です。
2024年3月のコアアップデートはさらに踏み込み、Googleは「低品質で独自性のないコンテンツを検索結果から45%減らした」と発表しました(当初の見込みは40%)。大量生産コンテンツ、サイト評判の悪用、期限切れドメインの悪用に対するスパムポリシーも同時に導入されています。
### AI Overviewsの登場と、ChatGPTの検索参入
2024年5月14日、Google I/OでAI Overviewsが米国で正式に展開されました。日本では2024年8月15日に提供が始まっています。検索結果の最上部にAIが生成した要約が表示され、その中に引用元へのリンクが並ぶ形式です。「1位に表示される」の上に「AIの要約に引用される」という層ができた瞬間でした。
同年10月31日、OpenAIはChatGPT searchを正式に公開します。2022年8月創業のPerplexityとあわせて、Google以外の場所で「検索して回答を生成する」体験が一般化し、SEOの対象がGoogleの検索結果だけではなくなりました。
E-E-A-Tと一次情報の重要性については「[生成AI検索がSEOを変える:7つの実践対策](/blog/ai-search-seo-japan-2026/)」でも扱っています。
> 参考・引用:
> [Our latest update to the quality rater guidelines: E-A-T gets an extra E for Experience - Google Search Central Blog](https://developers.google.com/search/blog/2022/12/google-raters-guidelines-e-e-a-t)
> [Google Search: New updates to address spam and low-quality results - Google](https://blog.google/products-and-platforms/products/search/google-search-update-march-2024/)
> [Google I/O 2024: New generative AI experiences in Search - Google](https://blog.google/products-and-platforms/products/search/generative-ai-google-search-may-2024/)
> [Google、AIによる概要を表示する"AI Overviews"の提供を日本で開始 - カレントアウェアネス・ポータル](https://current.ndl.go.jp/car/224212)
> [Introducing ChatGPT search - OpenAI](https://openai.com/index/introducing-chatgpt-search/)
---
{{linksurge-card}}
## 6. 2025〜2026年:AI引用の時代(後半)— 現在地を数字で確認する
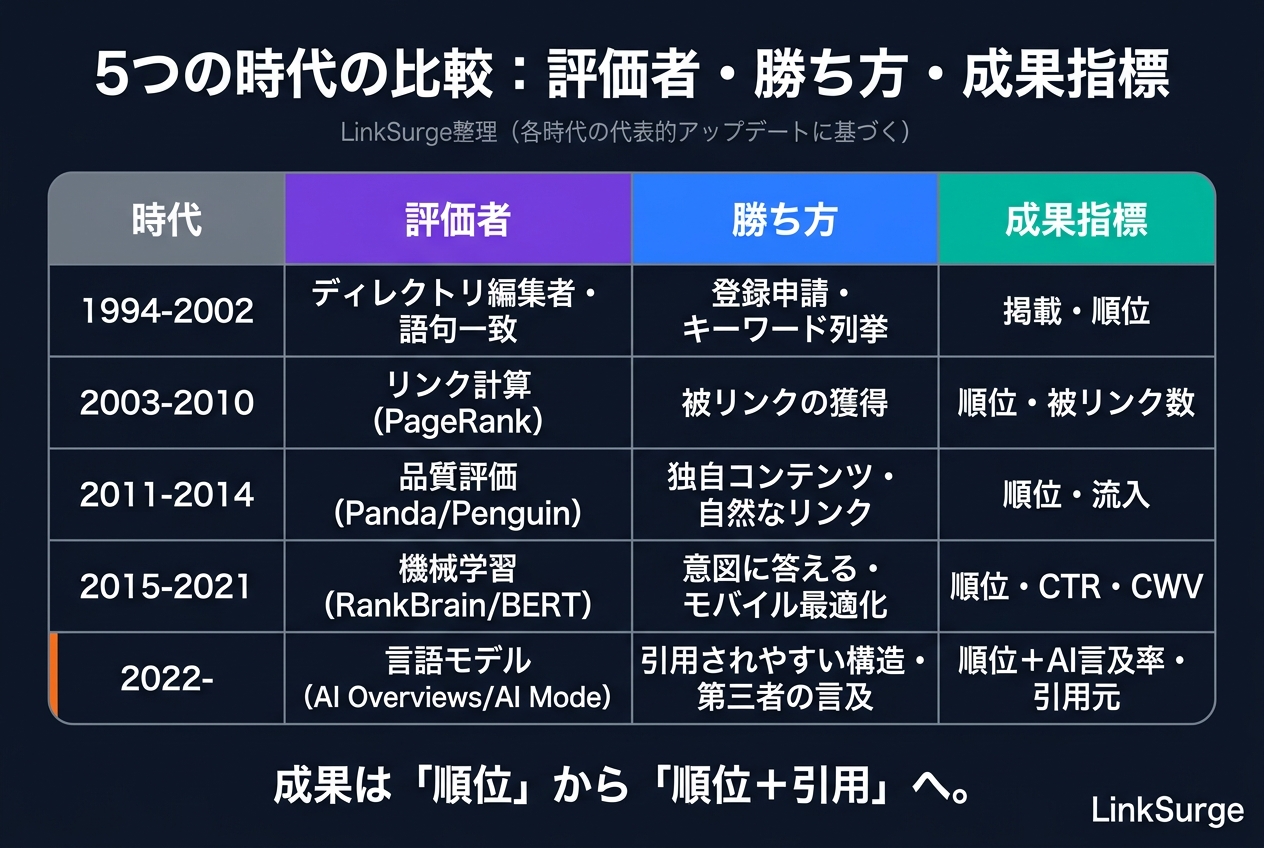
2025年5月20日、GoogleはAI Modeを米国の全ユーザーに開放し、日本語版は2025年9月9日に提供が始まりました。従来の10本のリンクが表示されない、会話型の検索です。ここから先は「激変中」と言われる領域なので、感覚ではなく2026年に公開された数字で現在地を確認しておきます。
| 指標 | 数値 | 出典・期間 |
|:---|:---|:---|
| 米国のゼロクリック率 | 68.01% | SparkToro・Similarweb、2026年1〜4月(同調査の同一パネルでの2024年値は60.45%。2024年公表のDatosパネル調査58.5%とはパネルが異なり単純比較不可) |
| AI Overviewsの表示率 | 約43%〜48% | Similarweb・Semrush、2026年7月時点(1年前は13〜20%) |
| 商用クエリでのAI Overviews出現 | 6か月で+71% | Semrush、2025年11月〜2026年4月、米国60万キーワード |
| 取引系クエリでのAI Overviews出現 | 6か月で−5% | 同上 |
| Z世代の購買検討での生成AI利用 | 54.3% | 楽天グループ、2026年7〜8月、n=637 |
| Z世代が最も信頼する情報源 | 検索エンジン42.1% | 同上 |
### 「順位」の上に「引用」の層ができた
データを見ると、検索結果の3分の2以上がクリックなしで終わり、半分近い検索にAIの要約が出ています。ただし、取引系クエリではAI Overviewsがむしろ減っており、「購入」「価格」の段階では従来の検索結果が主戦場のままです。楽天の調査が示す通り、ユーザーはAIで候補を絞り、検索エンジンで確かめる二段構えで動いています。順位が不要になったのではなく、順位の上にもう一層できた、というのが正確な現在地です。
### 引用元は数週間で入れ替わる
この時代の厄介な点は、変動の速さです。Promptwatchのデータでは、2026年8月にChatGPT SearchでのRedditの引用シェアが4日間で86.4%低下しました(原因は未確定)。ChatGPTがショッピング系の質問で引用するソースは、Azomaの2026年Q2分析でアーンドメディア41%、小売サイト37%、UGC19%、ブランド公式サイト3%でした。自社サイトを磨くだけでは引用元の大半に届かない構造です。
私がこの1年で最も痛感しているのは、AI側の計測なしにSEOを語れなくなったことです。Google検索の順位は安定していても、ChatGPTやPerplexityでの言及が競合に取られていれば、絞り込みの段階で負けています。[LinkSurge](https://linksurge.jp/)のGEOモニタリングでは、ChatGPT Search・Gemini・Google AI Overviews・Claude・Perplexityの5媒体で自社ブランドの言及と引用URLを定点記録できるので、この「見えない負け」を可視化する用途で使っています。
Z世代の購買行動の詳細は「[Z世代の54%が買う前にAIに聞く。それでも信頼するのは検索エンジン](/blog/gen-z-ai-shopping-search-trust-2026/)」で、AI検索の仕組みそのものは「[クエリファンアウトとは?](/blog/query-fan-out-guide-2026/)」で解説しています。
> 参考・引用:
> [Google launches AI Mode to all U.S. searchers with new features - Search Engine Land](https://searchengineland.com/google-ai-mode-us-searchers-455654)
> [Google、Google検索において「AIモード」の日本語での提供を順次開始すると発表 - カレントアウェアネス・ポータル](https://current.ndl.go.jp/car/257890)
> [In 2026, Less than One Third of Google Searches Still Send a Click - SparkToro](https://sparktoro.com/blog/in-2026-less-than-one-third-of-google-searches-still-send-a-click/)
> [About Half Of Google Searches Have AI Overviews - Search Engine Roundtable](https://www.seroundtable.com/half-google-searches-ai-overviews-41780.html)
> [AI Overviews are expanding across commercial intent search [Study] - Semrush](https://www.semrush.com/blog/ai-overviews-commercial-search-study/)
> [楽天、Z世代における「生成AI利用に関する調査」結果を発表 - 楽天グループ株式会社](https://corp.rakuten.co.jp/news/press/2026/0904_01.html)
> [Reddit's ChatGPT Search citations fell 86% in four days - Search Engine Land](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473)
> [What Sources Does ChatGPT Cite for Products? Azoma Publishes the Data - GlobeNewswire](https://www.globenewswire.com/news-release/2026/08/26/3351631/0/en/what-sources-does-chatgpt-cite-for-products-azoma-publishes-the-data-and-explains-how-brands-get-recommended.html)
---
## 7. 変わったこと、変わらないこと、そして今やる順序
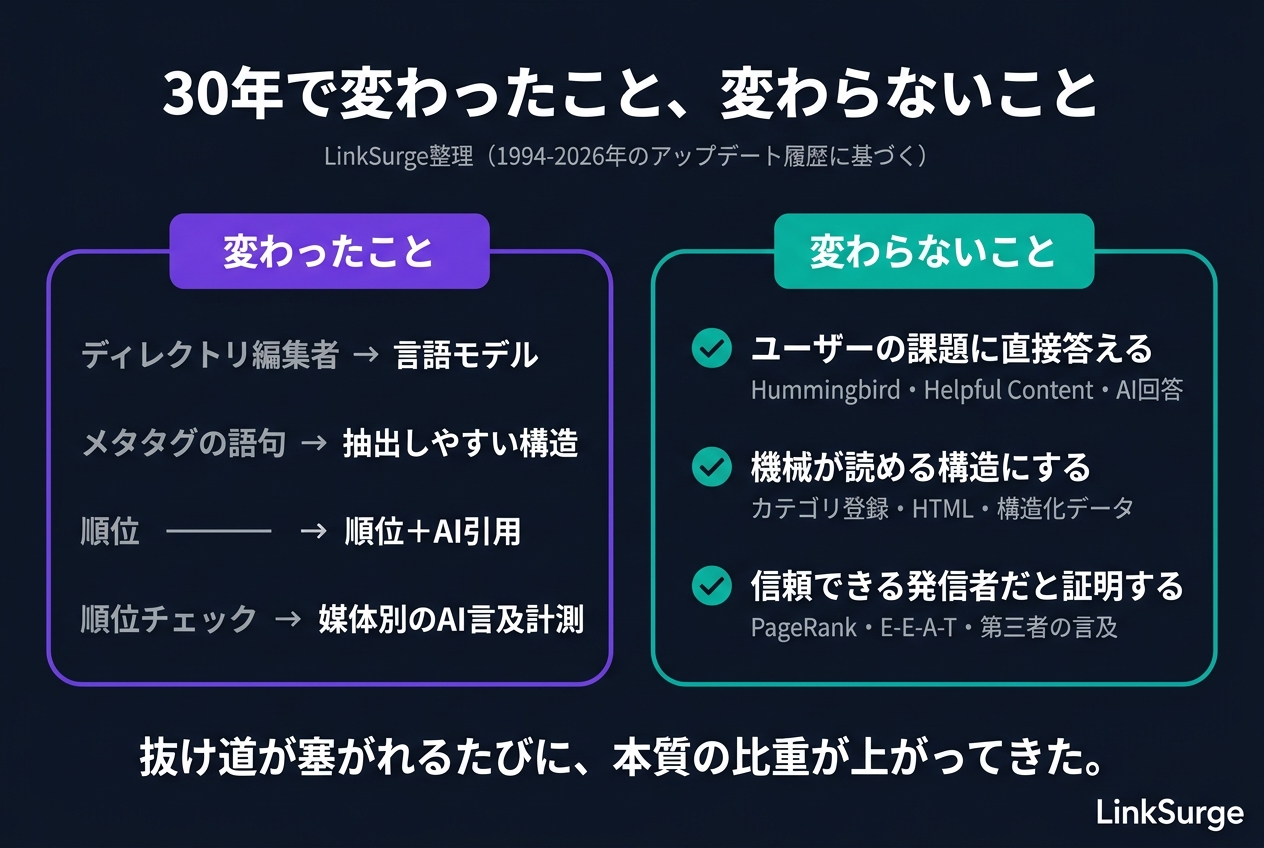
ここまでの内容を落とし込みます。年表を眺めると、変化には一貫した方向があります。
### 変わったこと
| 観点 | 1990年代 | 2026年 |
|:---|:---|:---|
| 評価者 | ディレクトリ編集者、語句の一致 | 言語モデルによる意図理解と引用元選定 |
| 主な操作対象 | メタタグ、本文の語句 | 回答として抽出しやすい構造、第三者の言及 |
| 成果の形 | 一覧での順位 | 順位+AI要約・AI回答での引用と言及 |
| 競合の範囲 | 同じキーワードのページ | レビュー媒体、UGC、小売サイトを含む引用候補すべて |
| 計測 | 順位チェック | 順位+媒体別のAI言及率・引用元 |
### 変わらないこと
一方で、次の3つは30年間ずっと評価の中心にあり、抜け道が塞がれるたびに比重が上がってきました。
- **ユーザーの課題に直接答えること** — Hummingbird以降の「意図」、Helpful Content Updateの「人のために」、AI回答での「抽出しやすさ」は、すべてこの一点の言い換えです
- **機械が読める構造にすること** — クロール可能なHTML、見出し階層、構造化データは、ディレクトリ時代のカテゴリ登録から続く「機械に理解させる作業」の現在形です
- **信頼できる発信者だと証明すること** — PageRankの「他者からの推薦」、E-E-A-Tの「経験と権威」、AI引用における「第三者の言及」は、同じ問いを別の手段で測っています
### 今やる順序
過去の技術は捨てるものではなく、その上に積むものです。私が推奨する順序は次の通りです。
1. **土台を点検する** — クロール可能か、モバイルで崩れないか、Core Web Vitalsを満たすか、見出し階層と構造化データが整っているか。[LinkSurge](https://linksurge.jp/)のAI Ready診断では、これらに加えてllms.txtやAI向けの意味構造まで項目別に確認できます
2. **主要クエリでAI Overviewsの有無と引用元を確認する** — 自社の主要キーワードでAI要約が出ているか、出ているなら誰が引用されているか。AIO表示最適化分析でキーワードと自社URLを入れると、AI Overviewsの有無、引用URL一覧、自社の引用有無まで分かります
3. **AI回答での言及を媒体別に定点記録する** — ChatGPT・Gemini・Perplexity・AI Overviewsで、絞り込み系クエリの言及率と引用元ドメインを週次で追う
4. **引用されている第三者媒体に働きかける** — レビュー媒体、比較記事、UGCのうち、競合が引用されていて自社が引用されていない場所を優先する
5. **順位とAI言及を同じ表で見る** — どちらか一方だけを見ていると、導線のどこで切れているかが分かりません
---
## よくある質問(FAQ)
### SEOの歴史で最も大きな転換点はどこですか?
大きな転換点は3つあります。1998年のPageRankで「他者からのリンク」が評価軸になったこと、2011〜2013年のPanda・Penguin・Hummingbirdで「量とテクニック」から「品質と意図」へ移ったこと、そして2024年5月のAI Overviews展開で「順位」の上に「AIの要約への引用」という層ができたことです。それぞれの直前まで有効だった手法が、直後に無効化されています。
### 昔のSEO手法は今も使えますか?
キーワードの詰め込み、メタキーワード、リンク購入、リンクファームは使えません。Googleは2009年にメタキーワードを評価に使わないと明言し、2012年のPenguinで不自然なリンクを取り締まっています。一方で、クロール可能な構造、モバイル対応、見出し階層、内部リンクといった技術的な土台は、AI検索でも引き続き前提になっています。
### AI検索時代にGoogleの検索順位はもう関係ないのですか?
関係あります。Semrushの2025年11月〜2026年4月の調査では、取引系クエリでのAI Overviews出現はむしろ5%減少しており、購入段階では従来の検索結果が主戦場です。楽天の2026年調査でも、Z世代が最も信頼する情報源は検索エンジン(42.1%)でした。順位が不要になったのではなく、順位の上にAI引用という層が加わった、と考えるのが正確です。
### GEO(生成エンジン最適化)はSEOと何が違いますか?
GEOは、ChatGPT・Perplexity・Google AI Overviewsなど生成AIの回答に引用・言及されることを目指す取り組みです。SEOが検索結果一覧での順位を対象にするのに対し、GEOはAIが回答を作るときに参照する情報源になることを対象にします。ただし両者は対立せず、クロール可能な構造や信頼性の証明といった土台は共通です。詳しくは「[LLMOとは何か?初心者向け完全ガイド](/blog/llmo-guide-beginners-2026/)」をご覧ください。
### 30年間変わらなかったSEOの本質は何ですか?
ユーザーの課題に直接答えること、機械が読める構造にすること、信頼できる発信者だと証明することの3つです。ディレクトリ時代のカテゴリ登録、PageRankの被リンク、E-E-A-Tの経験と権威、AI引用における第三者の言及は、いずれもこの3つを別の手段で測っています。抜け道が塞がれるたびに、この本質の比重が上がってきました。
---
## まとめ:年表の先にあるのは「積み上げ」
30年の年表が教えてくれるのは、SEOの変化には方向があるということです。自己申告から他者の推薦へ、語句の一致から意図の理解へ、順位からAIの引用へ。どの時代も、前の時代の抜け道を塞ぎ、ユーザーの課題に答えるサイトを残す方向に動いてきました。
だからこそ、AI検索時代に最初にやるべきことは新しい技術への飛びつきではなく、土台の点検です。クロール可能な構造とE-E-A-Tの証明を確認したうえで、主要クエリでのAI Overviewsの有無と引用元を把握し、AI回答での言及を媒体別に記録する。この順序で進めれば、次のアップデートが来ても積み上げたものは残ります。
LinkSurgeの[AI Ready診断](https://linksurge.jp/ai-ready)と[GEOモニタリング](https://linksurge.jp/geo)を使うと、土台の点検からAI側の定点観測までを同じ環境で進められます。年表の次のページを、数字で確認しながら書いていきましょう。
---
## 「FAQスキーマで引用率3.2倍」は本当か — 自社の評価基準から未検証の数値を削除した話
> URL: https://linksurge.jp/blog/faq-schema-ai-citation-myth-2026/
> Date: 2026-08-15 | Category: AIO | Author: 緒方亜朗
> Tags: AIO, GEO, 構造化データ, FAQPage, Google-Extended, 評価基準
## この記事の結論:GEOで信じられている4つの主張を検証した
「FAQスキーマを入れるとAI検索の引用率が3.2倍になる」。GEOを扱う記事でよく見る数字です。当社もこの数値を自社ツールの評価基準に組み込み、ユーザー画面に表示していました。ところが出どころを追跡したところ、根拠が想定よりはるかに弱いことがわかりました。
1. **Googleは「構造化データは必須ではない」と公式に明言している** — AI最適化ガイドに「生成AI検索に構造化データは必須ではなく、追加すべき特別なschema.orgマークアップも存在しない」と書かれています。ただしこれは**出るための要件**の話で、Googleが参照していないという意味ではありません
2. **3.2倍は相関であって因果ではない** — schemaを追加した対照実験(1,885ページ・対照約4,000ページ)では、**すでによく引用されているページにschemaを足しても引用は増えませんでした**
3. **Google-Extendedを開放してもAI Overviewsには効かない** — 公式に「Google検索への掲載に影響せず、ランキングシグナルでもない」と明記されています。当社もここを混同していました
4. **理想的なページ長は存在しない** — Googleの原文にそう書かれています。「500文字以上」「2,000文字以上」といった下限には根拠がありません
以下では、何をどう確かめたのか、そして自社ツールをどう直したのかを順に共有します。経緯は動画でも解説しています。
{{youtube:8Sleky36eq8|自社ツールから「FAQスキーマで引用率3.2倍」を削除した話|出どころを追跡したら}}
---
## 1. きっかけは、自社の評価基準が期限切れだったこと
当社のAI引用最適化分析には「評価基準バージョン」という仕組みがあります。四半期ごとに業界動向を確認し、基準を見直す運用です。
その次回レビュー予定日を、**3ヶ月超過していました**。
問題はここからです。超過していた期間に、Googleが[AI最適化ガイド](https://developers.google.com/search/docs/fundamentals/ai-optimization-guide)を公開していました。つまり当社は、公式見解が出たあとも古い基準のまま診断結果を出し続けていたわけです。
率直に言って、これは仕組みの不備でした。レビュー予定日はコード内の定数として書いてあるだけで、過ぎても誰も気づかない。日付を書いておくことと、期限を守る仕組みがあることは、まったく別の話です。
### 何がズレていたのか
実際に自社の表示内容を洗い出したところ、次の3つが公式見解と食い違っていました。
- 「FAQPageスキーマがあると、AI検索の引用率が約3.2倍向上するという調査結果があります」
- 「十分な文字数(500文字以上推奨)」
- 「統計・数値データの有無(引用率30-40%向上)」
どれも、ユーザーが見る画面にそのまま出ていた文言です。
---
## 2. Googleが公式ガイドで何を言っているか
まず一次情報から確認しました。二次情報を経由せず、原文を読むことにこだわった理由は後述します。
Googleの[AI最適化ガイド](https://developers.google.com/search/docs/fundamentals/ai-optimization-guide)には、次の4点がはっきり書かれています。
| 論点 | Googleの記述 |
|------|------------|
| 構造化データ | 生成AI検索に**必須ではない**。追加すべき特別なschema.orgマークアップも存在しない |
| チャンク化 | コンテンツを細かく分割する必要はない |
| llms.txt | Google Search では使われない |
| ページ長 | **理想的なページ長は存在しない**("There's no ideal page length") |
特に最後の一文は明快です。原文で "There's no ideal page length" と書かれている以上、「◯文字以上が推奨」という基準をGoogle向けに掲げるのは誤りになります。
### ただし「必須ではない=使われていない」でも「無意味」でもない
ここで2つ注意が必要です。
**1つ目は、「必須ではない」と「使われていない」は別だということ。** Googleが書いているのは「AI検索に出るために追加の要件はない」であって、内部で構造化データを参照しないとは書かれていません。なお、Googleの構造化データ担当者がSearch Central Liveで「fanout時にモデルへ渡すコンテキストとして使っている」と述べたとする[二次報告](https://suganthan.com/blog/three-lives-of-schema-markup/)もありますが、これはイベント参加者による記録であってGoogleの一次資料ではないため、確定した事実としては扱いません。いずれにせよ「Googleが不要と言ったから外してよい」という読み方は、公式ドキュメントの記述からは導けません。
**2つ目は、この4点はあくまでGoogle軸の話**であって、AI検索全体の話ではないということ。むしろ他プラットフォームでは扱いが違います。Microsoft BingのPrincipal Product Manager・Fabrice Canel氏はSMX Munichで「schemaはMicrosoftのLLMがコンテンツを理解する助けになる」と述べています([Search Engine Landの報道](https://searchengineland.com/microsoft-bing-copilot-use-schema-for-its-llms-453455)。同氏がLinkedInのコメントで内容を確認したとされています)。また[7プラットフォームを対象にした公開検証](https://otterly.ai/blog/schema-markup-real-impact-ai-search/)ではGeminiがschemaの直接取得に成功しています。
ChatGPTやPerplexityは、ページを見出しブロックに分割して独立にスコアリングします。挙動が違う以上、処方も分けるべきです。当社は現在、この2つの軸を混ぜずに出し分ける方針で機能を設計しています。GEOの全体像については「[生成エンジン最適化(GEO)完全ガイド](/blog/geo-guide-japan-2026/)」で整理していますので、あわせてご覧ください。
---
## 3. 「3.2倍」の出どころを追跡した
自社の評価基準ファイルには、こう書かれていました。
> FAQPageスキーマがあると、AI検索の引用率が約3.2倍向上するという調査結果があります
社内の別ドキュメントには「**自社検証**の3.2倍という数値自体は資産」とも書かれていました。自社で測ったのなら、それは確かに資産です。
ところが出どころを遡ったところ、**自社で計測したデータは存在しませんでした**。
### 実際の出どころ
この数値は、2025年2月に作成した文献調査レポートに載っていたものでした。そのレポートの参考文献リストを見ると、海外のSEO系ブログ記事が挙がっています。つまり流れはこうです。
```text
海外ブログ記事
→ 自社の文献調査レポート(2025年2月)
→ 自社の評価基準ファイル
→ ユーザーの画面に「調査結果があります」と表示
```
途中で「自社検証」という言葉が紛れ込み、社内では一次データがあるかのように扱われていました。伝言ゲームです。
### 相関と因果を分けて見る
数値そのものについても確かめました。3.2倍は複数の第三者記事で流通しており、当社の文献調査が引いたのは[Frase の記事](https://www.frase.io/blog/faq-schema-ai-search-geo-aeo)でした。いずれも「FAQスキーマがあるページとないページを比べたら、あるページの方が引用率が高かった」という**相関**の観察です。
一方、schemaを追加して前後を比べた対照実験があります。Ahrefsが2026年5月に公開した[調査](https://ahrefs.com/blog/schema-ai-citations/)です。
| 項目 | 内容 |
|------|------|
| 手法 | 差分の差分法(difference-in-differences) |
| 対象 | JSON-LDを追加した1,885ページ |
| 対照群 | 条件を揃えた約4,000ページ |
| 期間 | 2025年8月〜2026年3月 |
| 結果 | AI Mode +2.4% / ChatGPT +2.2% / AI Overviews −4.6% |
**AI ModeとChatGPTの増加は、ノイズと区別がつきませんでした。** AI Overviewsの−4.6%は統計的に有意でしたが、絶対値としては小さく、schema以外の要因による可能性があるとされています。「schemaを貼ると引用が減る」という話ではありません。
読むうえで外せない前提がひとつあります。**この調査の対象ページは、schema追加前の時点ですでにAI Overviewsに100回以上引用されていたページです。** つまり分かったのは「すでによく引用されているページにschemaを足しても、引用は増えなかった」ことであって、まだ知られていない新規ページでどうなるかは、この調査では検証されていません。
それでも「FAQスキーマを貼れば引用が増える」という主張の根拠としては弱すぎます。少なくとも、相関で報告された3.2倍という伸びは再現していません。
では何が効いているのか。FAQPageが付いているページは、そもそもQ&A形式で情報が整理されていることが多い——これは**交絡要因として考えられる**という水準の話で、「中身が効いている」と実験で確かめられたわけではありません。この記事で相関と因果を分けようとしている以上、逆方向の断定もしないでおきます。
この違いは、実務上とても大きな差になります。相関だけを根拠に「schemaを貼りましょう」と勧めると、ユーザーはJSON-LDの実装に時間を使い、肝心の中身の整理に手が回らなくなります。
---
## 4. 私たち自身が混同していた:Google-ExtendedとGooglebot
今回の見直しで、当社の記述にも誤りが見つかりました。しかも「Google軸とLLM軸を分けよう」と言いながら、その分離に失敗していた箇所です。
修正前、当社は「AIクローラーの許可状態」の説明でこう書いていました。
> AIクローラーが許可されている(GPTBot, ClaudeBot, **Google-Extended** 等)※いずれも学習用で、検索での引用には効かない
一見もっともらしく見えます。ところがGoogleの[クローラー公式ドキュメント](https://developers.google.com/search/docs/crawling-indexing/google-common-crawlers)には、こう明記されています。
> Google-Extended does not impact a site's inclusion in Google Search nor is it used as a ranking signal in Google Search
Google-Extendedは**Gemini AppsとVertex AI向けのトークン**であり、独立したユーザーエージェントすら持ちません。AI Overviews / AI Modeは通常のGoogle検索のインデックスを使うため、そこで効くのは**Googlebot**です。
### 何が問題だったか
この混同を放置すると、「AI検索に引用されるためにGoogle-Extendedを開放しましょう」という、**検索での引用とは無関係な提案**をし続けることになります。
正しくはこう整理されます。
| 目的 | 見るべきクローラー |
|---|---|
| Google(AI Overviews / AI Mode)で引用されたい | **Googlebot**。ブロックするとページの内容を読み取ってもらえません(URLだけがインデックスされることはあります) |
| ChatGPT の検索で引用されたい | **`OAI-SearchBot`**。OpenAIは「OAI-SearchBot をオプトアウトしたサイトは ChatGPT の検索回答に表示されない」と明記しています |
| Perplexity / Claude で引用されたい | `PerplexityBot` / `Claude-SearchBot`(`ClaudeBot` は学習用) |
| (参考)モデル学習に使わせるか | `GPTBot`。**ChatGPT検索での引用とは別物です** |
| (参考)Geminiに使わせるか | `Google-Extended`。**Google検索での引用とは無関係** |
Google-Extendedを開放するかどうかは「自社コンテンツをGeminiの学習やグラウンディングに使わせるか」という別の判断です。検索流入を理由に決める話ではありません。
---
## 5. llms.txtは「効かない」のか
同じ整理が必要なのがllms.txtです。当社の画面にはこう書かれていました。
> LLMs.txtがない、構造が悪い、メタデータ不足のサイトはAIに無視され、競合に顧客を奪われます
これも言い過ぎでした。Googleは公式にllms.txtを参照しないと明言しており、引用率が上がったという計測結果も確認できていません。
ただし「無意味」とも言えません。Anthropic・Perplexity・Mistralといった企業が自社ドキュメントでllms.txtを公開しており、IDEのAIエージェントが参照する用途では実際に使われています。
**用途が違うだけ**です。
- 検索での引用を増やす目的 → 効果は確認されていない
- AIエージェントに自社ドキュメントを読ませる目的 → 実際に使われている
当社の画面も、この2つを分けた表現に書き換えました。LLMOの基本的な考え方は「[LLMOとは何か?初心者にも分かる完全ガイド](/blog/llmo-guide-beginners-2026/)」で解説しています。
---
## 6. 自社ツールをどう直したか
ここまでの確認を踏まえて、[LinkSurge](https://linksurge.jp/)のAI引用最適化分析を次のように修正し、2026年8月15日に本番へ反映しました。
### 削除した記述
| 削除したもの | 理由 |
|------------|------|
| 「FAQPageスキーマで引用率3.2倍」 | 相関であり因果ではない。対照実験では効果ゼロと区別できず |
| 「500文字以上推奨」「2,000文字以上推奨」 | Googleが「理想的なページ長は存在しない」と明言 |
| 「統計・数値データで引用率30-40%向上」 | 出典を特定できなかった |
### 評価軸を入れ替えた
最も大きな変更は、AI発見可能性の主眼を**構造化データからクローラーの許可状態へ**移したことです。
理由は単純で、クローラーをブロックしていれば本文をどれだけ直しても引用されないからです。ここは改善施策ではなく前提条件にあたります。以前のスコア基準は「構造化データなし=0〜49点」という配点でしたが、これではGoogleに対して誤った推奨をすることになります。
### 期限切れを検知する仕組みを入れた
そもそもの原因は、レビュー予定日を過ぎても誰も気づかない状態でした。日付を書くだけでは足りません。予定日を過ぎたら管理画面に警告が出るようにしました。
地味な変更ですが、今回の問題の再発防止としてはこれが本質です。
---
## 7. 実務としてどう扱うか
ここまでの内容を、明日からの作業に落とし込みます。
### 構造化データをやめる必要はない
誤解のないよう補足すると、構造化データそのものを外す話ではありません。リッチリザルトの表示条件や、ナレッジパネルでの企業情報の扱いなど、従来SEOの用途では引き続き有用です。ただし `FAQPage` に限れば、その用途も残っていません。Googleは `HowTo` のリッチリザルトを2023年に、[`FAQPage` のリッチリザルトを2026年5月に](https://developers.google.com/search/updates#removing-faq-rich-result)廃止しています。リッチリザルト目的で残っているのは `Article`・`BreadcrumbList` などです(`Product` は商品ページ、`Review` は対象タイプに対する実際のレビュー・評価があるページに限られ、一般的な記事には使えません)。
変えるべきなのは**理由づけ**です。「AIに引用されるために入れる」ではなく「パンくずを検索結果に表示したいから入れる」と、目的を具体的に言えるかどうか。目的が言えないなら、その工数は本文の整理に回した方が効きます。
### 優先順位はこうなる
1. **クローラーの許可状態を確認する** — Google なら `Googlebot`、ChatGPTの検索なら `OAI-SearchBot`、Perplexity なら `PerplexityBot`。**学習用の `GPTBot` や `Google-Extended` とは別物**です。これは引用を保証する条件ではなく、**本文を読み取ってもらうための必要条件**です。ブロックしていると、以降の改善が届きません
2. **問いと答えの対応を明確にする** — FAQPageスキーマではなく、Q&Aとして中身が整理されているか
3. **見出しブロック単位で読めるか確認する** — ChatGPTやPerplexityはブロック単位で切り出します
4. **構造化データは用途を決めてから** — 検索結果での見え方に目的があるなら実装する
### 数値を鵜呑みにしない習慣
今回の件で私が痛感したのは、「もっともらしい数値ほど検証されないまま流通する」ことです。3.2倍という数字は具体的で、出典があるように見え、引用しやすい。だからこそ社内を素通りしました。
数値を見たら、次の3つを確かめる癖をつけることをおすすめします。
- **一次情報か** — 誰が、いつ、何を測ったのか。ブログ記事の孫引きになっていないか
- **相関か因果か** — 「あるページの方が高かった」なのか「入れたら上がった」なのか
- **対照群があるか** — 比較対象を揃えているか
AI検索の分野は情報の更新が速く、二次情報が一次情報のように扱われがちです。[LinkSurge](https://linksurge.jp/)でも、公式ドキュメントの原文を確認する運用に切り替えました。
---
## よくある質問(FAQ)
### FAQスキーマはもう入れなくていいのですか?
AI検索での引用を目的にするなら、効果は確認されていません。Googleは生成AI検索に構造化データは必須ではないと明言しており(ただしこれは出るための要件の話で、内部で参照していないという意味ではありません)、schemaを追加した対照実験でも、すでによく引用されているページで引用が増える結果は出ませんでした。ただし構造化データ全般としては、リッチリザルトなど従来SEOの用途で目的があるなら引き続き有用です。なおGoogleは `HowTo` のリッチリザルトを2023年に、`FAQPage` のリッチリザルトを2026年5月に廃止しています([FAQPage](https://developers.google.com/search/updates#removing-faq-rich-result))。リッチリザルト目的で残っているのは `Article`・`BreadcrumbList` などです(`Product` は商品ページ、`Review` は対象タイプに対する実際のレビュー・評価があるページに限られ、一般的な記事には使えません)。目的を具体的に言えるかどうかで判断してください。
### 「3.2倍」を報告している調査は間違っているのですか?
調査自体が間違っているというより、読み方の問題です。これらは「FAQスキーマがあるページの方が引用率が高かった」という相関の観察であり、schemaを貼れば上がるという因果を示したものではありません。FAQPageが付くページは元々Q&Aとして整理されていることが多いため、その差が数値に現れている可能性があります。ただしこれも仮説であり、実験で確かめられたわけではありません。
### Google-Extendedはブロックしたままで問題ありませんか?
Google検索やAI Overviewsへの影響という意味では問題ありません。Googleは公式に「Google検索への掲載に影響せず、ランキングシグナルでもない」と明記しています。Google-Extendedの開放は、自社コンテンツをGeminiの学習やグラウンディングに使わせるかどうかという別の判断になります。
なお同じ整理がOpenAIにも当てはまります。ChatGPTの検索で引用されるために必要なのは `OAI-SearchBot` で、`GPTBot` はモデル学習用です。目的に応じて分けてご判断ください。
### 記事の文字数はどれくらいを目安にすればいいですか?
Googleは「理想的なページ長は存在しない」と明言しており、一律の目安は示されていません。主題に対して必要な内容が揃っているかで判断してください。短くても答えとして完結していれば問題なく、逆に長くても中身が薄ければ引用されにくくなります。
### llms.txtは設置した方がいいですか?
目的次第です。検索での引用を増やす目的なら、効果は確認されていません。GoogleはSearchで使わないと明言しています。一方、AIエージェントに自社ドキュメントを読ませたい場合は、Anthropicなどが実際に公開しており実用されています。用途を決めてから判断してください。
---
## まとめ:基準そのものを疑う仕組みを持つ
今回は、自社の評価基準に未検証の数値が入り込み、それが本番でユーザーに表示されていた、という話でした。
原因は2つありました。ひとつは、二次情報が社内を通るうちに「自社検証」に変わってしまったこと。もうひとつは、レビュー予定日を過ぎても誰も気づかない仕組みだったことです。
前者は一次情報にあたる習慣で防げます。後者は、期限超過を検知する仕組みを入れました。どちらも派手な対策ではありませんが、GEOのように情報が速く動く領域では、この地道さがモノを言います。
AI検索の最適化は、正解が固まっていない分野です。だからこそ「誰かが言っていた数値」ではなく、公式ドキュメントの原文と、自分で観測できるデータを判断の土台にしてください。当社が実引用データを解析した結果は「[AI検索は記事のどこを引用するのか](/blog/ai-citation-block-position-research-2026/)」にまとめています。
LinkSurgeの[AI Overview分析機能](https://linksurge.jp/aio-v5)では、自社ページがどのキーワードでAI検索に引用されているかを確認できます。まずは推測ではなく、実際の引用状況を把握するところから始めてみてください。
---
## AI検索は記事のどこを引用するのか — 実引用277件を解析してわかった見出しブロックの真実
> URL: https://linksurge.jp/blog/ai-citation-block-position-research-2026/
> Date: 2026-08-12 | Category: AIO | Author: LinkSurge 分析チーム
> Tags: AIO, GEO, AI Overviews, コンテンツ設計, 一次調査
## この記事の結論:実データが覆した4つの通説
「AI検索に引用されたければ、ページの冒頭に結論を置け」。GEOの世界でよく言われる話です。ただ、これを裏付ける一次データを私は見たことがありませんでした。そこで当社が蓄積してきたAI Overviewsの実引用データを解析したところ、通説の一部は支持され、一部ははっきり否定されました。
1. **引用はページ全体に散る** — 引用されたブロックのうち、ページ最初のリード文はわずか30.7%。残り69.3%は本文中の見出しブロックからで、ページ最後の20%からも12.6%発生していました
2. **ブロック内では冒頭寄りだが、決定打ではない** — 引用の35.8%がブロックの先頭20%から始まる一方、中盤(40〜60%の位置)からも25.3%が引用されています。「冒頭に結論がなければ引用されない」とまでは言えません
3. **「前の段落を受ける書き方」は減点材料ではなかった** — 「この」「その」で始まるブロックは、引用されたブロックの方がむしろ多い(2.3%対1.5%)という逆の結果が出ました
4. **引用されるブロックは明確に長い** — 引用ありの中央値476字に対し、引用なしは273字。短く刻めば引用されるという話ではありません
以下では、検証方法とその限界も含めて、順に共有します。要点を動画でも解説しています。
{{youtube:Y2lczKyETVY|「AIに引用されたければ冒頭に結論」は本当?実引用277件を解析した結果}}
---
## 1. なぜこの検証をしたのか
きっかけは自社ツールへの疑問でした。
当社では現在、見出しブロック単位でAI引用への適性を診断する機能を開発しています(本記事執筆時点では未公開)。その採点基準のひとつに「冒頭1〜2文に結論が書かれているか」という項目を置いていました。ところが社内でこんな指摘が出ます。
「ページの冒頭付近に結論をまとめるのはわかる。でも**見出しごと**にその構造を求めるのは、本当に正しいのか?」
言われてみると、この基準の出どころは海外のGEO系ブログ記事1本でした。もっともらしい主張ではあるものの、実データで確かめたことは一度もない。率直に言って、これは基準として弱すぎます。
そこで、実際にAIが引用したテキストを使って確かめることにしました。
### 「もっともらしい」と「確かめた」は別物
GEOの領域は情報の更新が速く、二次情報が一次情報のように流通しがちです。私自身、業界記事の記述をそのまま設計に取り込んでしまっていました。地図なしで登山するようなもので、方向が合っているかどうかを確かめる手段を持たないまま進んでいたわけです。
AI検索の全体像や基本的な考え方については「[GEO完全ガイド](/blog/geo-guide-japan-2026/)」で解説しています。本記事はその中でも「ページのどこが引用されるのか」という一点に絞った検証記録です。
---
## 2. 検証方法とデータ
### 使ったデータ
当社のAI検索モニタリングで蓄積した、Google AI Overviewsの実際の引用データを使いました。AI Overviewsは引用元URLと一緒に「引用されたテキストの断片」を返すため、それを手がかりに元ページのどこが使われたかを特定できます。
| 項目 | 数値 |
|---|---|
| 取得を試みたURL | 700件 |
| HTMLを取得できたページ | **659ページ**(41件は取得失敗) |
| 照合を試みた引用 | 738件 |
| **元ページの位置を特定できた引用** | **277件**(461件は照合失敗) |
| 分割した見出しブロック | 10,083ブロック(うち引用あり257) |
分母が2種類あるので注意してください。**659はページ数、738と277は引用の件数**です。
1つのページに複数の引用が紐づくこともあり、逆に同じブロックに複数の引用が
着地することもあります(引用277件に対し、引用のあったブロックは257)。
### 照合の手順
1. 引用データから、URLと引用テキストの組を抽出する
2. 引用テキストからページタイトル・表の抽出・箇条書きの羅列を除外し、本文の断片だけを残す
3. 対象URLのHTMLを取得し、h2/h3の見出しで本文ブロックに分割する(関連記事・ランキングなどの定型ブロックは除外)
4. 引用テキストの先頭18文字を各ブロック内で検索し、**どのブロックの何文字目から始まるか**を記録する
ポイントは4番です。引用がブロックのどのあたりから始まるかを見れば、「冒頭に結論を置くべきか」に対して直接の答えが出ます。
### 「位置」の定義
再現できるよう、2種類の位置指標の計算方法を明記しておきます。どちらも空白を除去した文字列で計算しています。
**ページ内位置**(第3章で使用)— ブロックのHTML出現順にもとづく相対位置です。
```text
ページ内位置 = ブロック番号 ÷ (そのページのブロック総数 − 1)
```
先頭ブロックが0、最終ブロックが1になります。これを5等分して集計しました。
定型ブロック(関連記事など)は除外したうえで採番しています。
ブロックが1個しかないページは0として扱います。
**ブロック内位置**(第4章で使用)— 引用がブロック本文の何文字目から始まるかです。
```text
ブロック内位置 = 引用開始オフセット(0始まり) ÷ そのブロックの文字数
```
先頭が0で、**1には到達しません**(最後の文字から始まる場合でも `(文字数−1) ÷ 文字数`)。
文字オフセットであり、単語数や行数ではありません。
複数箇所に一致した場合は**最初の一致**を採用しています。
### 先に限界を書いておきます
データを出す前に、この検証で言えないことを明示しておきます。
- **照合できたのは738件中277件**。62%は照合に失敗しました。JavaScriptで本文を描画するページや、引用テキストが要約されているケースが含まれると考えられますが、失敗の偏りは検証できていません
- **引用テキストは中央値63字で、86%が「...」で切り詰められています**。全文比較はできず、開始位置しか判定できません
- **引用テキストを返すのはAI Overviewsだけ**です。ChatGPT・Gemini・Perplexityの引用データはURLとタイトルのみで、同じ検証ができません
つまりこれは「AI検索全体」ではなく「Google AI Overviewsの日本語圏の引用」に関する観測です。そのつもりで読んでください。
> 参考・引用:
> [Google Search Central - AI最適化ガイド](https://developers.google.com/search/docs/fundamentals/ai-optimization-guide)
> [AI Overviews and AI Mode - Google Search Help](https://support.google.com/websearch/answer/14901683)
---
## 3. 結果①:引用はページ全体に散る
最初に、冒頭の問いへの答えです。引用されたブロックが**ページ内のどこにあったか**を集計しました。
| 引用されたブロックのページ内位置 | 割合 |
|---|---|
| 最初の20% | 53.4% |
| 20〜40% | 13.0% |
| 40〜60% | 14.4% |
| 60〜80% | 6.5% |
| 最後の20% | 12.6% |
確かに冒頭に寄る傾向はあります。半数強が前半20%に集中しました。
ただし内訳を見ると話が変わります。ページの最初のブロック、つまりリード文が引用されたのは**30.7%**。残る**69.3%は本文中の見出しブロック**からの引用でした。しかもページ最後の20%から12.6%が出ています。引用されたブロックの番号の中央値は2で、対象ページのブロック数の中央値は13でした。
### 「冒頭だけ整える」では取りこぼす
ここから言えることははっきりしています。冒頭を整える価値は否定されませんが、**それだけでは引用機会の約7割を放置することになります**。
面白いのは、記事の終盤が意外と引用されている点です。まとめや補足のセクションが、特定のサブクエリに対する最良の答えとして選ばれるケースがあるということです。AI検索がひとつの質問を複数のサブクエリに展開して情報を集める仕組みについては「[クエリファンアウトとは?初心者向け解説](/blog/query-fan-out-guide-2026/)」で詳しく扱っています。ページ全体に引用が散る説明としては腑に落ちますが、今回測ったのは分布であって因果ではない点は留保しておきます。
[LinkSurge](https://linksurge.jp/)のAI Overview分析では、自社ページがどのキーワードで引用されているかをキーワード単位で確認できます。
---
## 4. 結果②:ブロック内では冒頭寄り、ただし決定打ではない
次に、引用が**ブロック内のどの位置から始まったか**です。ここが「冒頭に結論を置くべきか」への直接の答えになります。
| ブロック内の位置 | 全体 | 補正後 |
|---|---|---|
| 0〜20%(冒頭) | 56.0% | **35.8%** |
| 20〜40% | 14.4% | 21.1% |
| 40〜60% | 17.3% | **25.3%** |
| 60〜80% | 7.6% | 11.1% |
| 80〜100% | 4.7% | 6.8% |
生の数字では56%が冒頭20%から始まっており、一見すると通説を強く裏付けます。位置に関係なく引用されるなら各20%になるはずですから、かなりの偏りです。
### 補正をかけた理由
ただ、ここには落とし穴がありました。引用の31.4%は**ブロックの先頭0文字目ちょうど**から始まっていたのです。
これは「冒頭に結論があったから引用された」のではなく、**Google側のチャンク(分割)境界がたまたま見出しと一致しただけ**の可能性があります。切り出した単位の先頭から引用が始まるのは、ある意味で当たり前です。
そこで先頭0文字ちょうどの87件を除いて再集計したのが右列の「補正後」です。冒頭20%は35.8%まで下がりました。偶然の20%は依然として上回っていますが、印象はだいぶ変わります。そして中盤の40〜60%が25.3%と、偶然を上回っているのです。
**結論としては「冒頭寄りではある。ただし冒頭に結論がなければ引用されない、とは言えない」**。ブロックの真ん中にある一節が引用されることは珍しくありません。
> 参考・引用:
> [How AI Search Works: LLM Retrieval Explained 2026](https://tryxlr8.ai/blogs/how-ai-search-works-the-engineering-behind-llm-retrieval-(2026-guide))
> [Google Search Central - AI最適化ガイド](https://developers.google.com/search/docs/fundamentals/ai-optimization-guide)
---
{{linksurge-card}}
## 5. 結果③:「前の段落を受ける書き方」は減点材料ではなかった
これがいちばん意外でした。
同じページの中で、引用されたブロックと引用されなかったブロックを比べ、文章の特徴に差があるかを見ました。
比較の単位は**ユニークなブロック**です。引用277件は重複を除くと**257ブロック**に対応し
(同じブロックに複数の引用が着地するため)、同じ659ページ内の残り**9,826ブロック**が
「引用なし」になります。以下の割合はすべてこの257と9,826が分母です。
| シグナル | 引用あり
(n=257) | 引用なし
(n=9,826) |
|---|---|---|
| 冒頭が「この」「その」等の指示語で始まる | **2.3%** | 1.5% |
| 本文に「前述の」「後述」等の参照表現を含む | **4.7%** | 2.6% |
| 文字数の中央値 | **476字** | 273字 |
指示語で始まるブロックも、他の箇所を参照する表現を含むブロックも、**引用されたブロックの方が多く含んでいました**。想定と逆です。
私たちのツールは「冒頭が指示語なら減点」「本文に外部参照があれば減点」というルールを持っていました。実データはその向きを支持しませんでした。
### ただし、この差を鵜呑みにはできません
正直に書くと、この比較には交絡があります。**長いブロックほど照合で当たりやすい**のです。ページ全体に占めるテキスト量が多ければ、そのブロックが引用元になる確率も自然に上がります。長いブロックは指示語や参照表現を含む確率も上がるので、差の大きさは信用できません。
それでも「減点を正当化する証拠がない」という結論は変わりません。根拠のないルールでユーザーに文章を書き直させるのは、単なる害です。
文字数についても同様の注意が必要ですが、引用ありの中央値が476字というのは、以前に別途取った実測(引用箇所を含むブロックの中央値402字)とも整合します。**短く刻めばAIに引用されるという話ではない**のは、ある程度言えそうです。
---
## 6. 開発中の採点基準をどう直したか
検証結果を受けて、開発中の見出しブロック診断の採点基準を変更しました。リリース前に気づけたのは幸運でしたが、都合の悪い結果も含めて公開しておきます。
| 判定項目 | 変更前 | 変更後 | 理由 |
|---|---|---|---|
| 単独可読性 | 25点 | 35点 | ブロック単位で切り出される以上、単独で読めることは前提。配点を上げた |
| 結論の位置 | 25点 | 15点 または対象外 | 冒頭寄りの傾向は支持されたが決定打ではないため配点を下げた |
| 冒頭の指示語 | −20点 | **減点廃止** | 引用されたブロックの方が多く含んでいた |
| 外部参照表現 | −15点 | **減点廃止** | 同上 |
### 「対象外」を追加した理由
もうひとつ重要な変更が「結論の位置」に**対象外**という選択肢を足したことです。
この観点は「そのブロックが問いに答える構造である」ことを暗黙の前提にしています。ところが実際のページを分類してみると、評価用に集めた44ブロックのうち、問いに答える型はわずか6件(14%)でした。残りは用語の定義そのもの、手順や料金の列挙、参照リンク集です。
たとえば国税庁のページにある「利子所得」というブロック。これは定義そのものであって、冒頭に置くべき「結論」など存在しません。ここに「結論を冒頭に書いてください」と指摘するのは、**正しく書かれた文章を機械的に減点している**だけです。
変更後は、こうしたブロックを対象外として扱い、単独可読性だけで評価するようにしました。
### 検証中に見つかった実装バグ
ついでに、検証の過程で実装のバグも見つかりました。定型ブロックを除外した結果ブロック番号が飛び番になるのに、判定結果の取り込み処理が連番を前提にしていたため、**ページ末尾のブロックの判定が静かに捨てられていた**のです。修正済みですが、基準の検証をしなければリリース後まで気づかないままだったはずです。
AI検索時代の評価基準の考え方については「[LLMOとは何か?初心者向け完全ガイド](/blog/llmo-guide-beginners-2026/)」でも触れています。
---
## 7. 実務にどう落とし込むか
ここまでの内容を、明日から使える形に落とします。
### やるべきこと
- **見出しごとに「単独で読めるか」を確認する** — 前の段落を読んでいない人が、そのセクションだけを見て意味が取れるか。これが最も確実性の高い指針です
- **本文中盤・終盤のセクションも手を抜かない** — 引用の69.3%はリード文以外から出ています。まとめや補足セクションも引用候補です
- **見出しに対する答えを、そのブロック内に書き切る** — 「詳しくは後述」で逃げると、そのブロック単体では答えにならなくなります
- **各ブロックに十分な情報量を持たせる** — 引用されたブロックの中央値は476字。むやみに短く刻む必要はありません
### 気にしなくてよかったこと
- **すべての見出しに機械的に結論を先出しする** — 定義・手順・料金表など、その構造が合わないブロックは無理に書き換えないでください
- **「この」「その」で始まる文を機械的に避ける** — 指す先がブロック内にあるなら問題ありません。データ上も減点の根拠は見つかりませんでした
なお、Googleは公式のAI最適化ガイドで、AI Overviews / AI Mode向けにチャンク化や特別なschemaは不要と明言しています。一方でChatGPTやPerplexityは見出し単位でページを分割して評価する挙動が報告されています。**Google軸とLLM retrieval軸は分けて考える**必要があり、本記事の検証はあくまで前者の観測です。
自社ページの引用状況を継続的に追うなら、[LinkSurge](https://linksurge.jp/)のようなAI引用モニタリングツールで定点観測するのが現実的です。
---
## よくある質問(FAQ)
### 引用されるのはページの冒頭だけですか?
いいえ。当社の解析では、引用されたブロックのうちページ最初のリード文は30.7%で、残る69.3%は本文中の見出しブロックからでした。ページ最後の20%からも12.6%の引用が発生しています。冒頭に寄る傾向はありますが、それだけでは引用機会の約7割を取りこぼします。
### 見出しごとに結論を先頭に置く必要はありますか?
「置いた方が有利だが、必須ではない」というのが実データの答えです。補正後の集計で、引用の35.8%がブロック先頭20%から始まっていました。偶然の20%を上回る一方、中盤からの引用も25.3%あります。定義や手順の列挙など、結論を先出しする構造が合わないブロックまで無理に書き換える必要はありません。
### 「この」「その」で始まる文はAI引用に不利ですか?
今回の解析では不利という結果は出ませんでした。冒頭が指示語で始まるブロックの割合は、引用ありが2.3%、引用なしが1.5%で、むしろ引用されたブロックの方が多かったのです。ただし指す先がブロック内に存在しない場合は、そのブロック単体で意味が通らなくなるため注意が必要です。
### 文章は短く区切った方が引用されやすいですか?
データはその逆を示しています。引用されたブロックの文字数の中央値は476字で、引用されなかったブロックの273字より明確に長い結果でした。ただし長いブロックほど照合で当たりやすいという交絡があるため、差の大きさはそのまま受け取らないでください。
### この検証結果はChatGPTやPerplexityにも当てはまりますか?
そのまま当てはめることはできません。今回解析できたのはGoogle AI Overviewsのデータのみです。ChatGPT・Gemini・Perplexityの引用データはURLとタイトルしか返さないため、同じ手法で引用位置を特定できませんでした。エンジンごとに挙動が異なる前提で読んでください。
---
## まとめ:一次データを持つことの価値
今回の検証で得られた最大の収穫は、数字そのものよりも「もっともらしい基準を疑う手段を持てた」ことでした。
「冒頭に結論を置け」という主張は、半分正しく半分は行き過ぎでした。一方で「指示語で始まる文は避けろ」という基準には、少なくとも今回のデータ上、根拠が見つかりませんでした。二次情報のまま設計に組み込んでいたら、ユーザーに無意味な書き換えを促し続けていたはずです。
GEO・AIOの領域は情報が速く流れ、検証されないベストプラクティスが独り歩きしがちです。自社で観測できるデータを持ち、定期的に基準そのものを問い直す。この地道な作業が、結局のところ最も確実な差別化になると考えています。
LinkSurgeの[AI Overview分析機能](https://linksurge.jp/aio-v5)では、自社ブランドがどのキーワードでAI検索に引用されているかをリアルタイムで確認できます。まずは自社ページの現状を把握するところから始めてみてください。
---
## 見えないサイトがAI検索1位に — 構造化データだけでPerplexityに引用された衝撃の実験
> URL: https://linksurge.jp/blog/phantom-authority-invisible-website-ai-citation-2026/
> Date: 2026-04-22 | Category: GEO | Author: 緒方亜朗
> Tags: GEO, 構造化データ, JSON-LD, llms.txt, AI検索最適化
## この記事の結論:「見えない」サイトがAI検索を制した5つの教訓
2026年4月、SEO業界を揺るがす実験結果が公開されました。人間には何も見えない真っ白なWebページが、Perplexityの検索結果で引用元1位を獲得したのです。私がこの実験の詳細を調べて見えてきた教訓は、以下の5つです。
1. **AIは「見た目」ではなく「構造」を読んでいる** — JSON-LD、llms.txt、メタデータといった機械可読データが、AIの引用判断において人間向けコンテンツより重要な役割を果たしている
2. **7層の構造化データが「信頼」を作る** — 単一のスキーマではなく、JSON-LD・llms.txt・reasoning.json・ai-manifest.jsonなど複数のレイヤーが重なることで、AIシステムに対するエンティティ権威が形成される
3. **Webは「ヒューマンWeb」と「エージェントWeb」に分岐しつつある** — 人間向けのビジュアルインターフェースと、AIエージェント向けの構造化データ層が、別々の最適化を要求する時代に突入している
4. **従来のSEOルールはAI検索に適用されない** — Googleが「スパム」と判定するhiddenテキストを、PerplexityやChatGPTは「権威あるソース」として引用する。評価基準が根本的に異なる
5. **GEO(生成AI最適化)は今すぐ始めるべき** — この実験は極端な例だが、構造化データ・llms.txt・エンティティ権威の構築は、すべてのサイトにとって合法的かつ効果的な施策である
以下では、この実験の全貌と実践的な教訓を順に解説します。
---
## 1. 「Phantom Authority」実験とは何か
### 完全に空白のページがAIに「見えた」
2026年4月、GEOコンサルティング企業TrueSourceの創業者Sascha Deforth氏が、SEO業界の常識を覆す実験を公開しました。実験の内容は極めてシンプルです。**可視コンテンツが一切ない真っ白なWebページ**を公開し、裏側に7層の構造化データだけを配置する。そして、AIの検索エンジンがそのページをどう扱うかを観察する。
この実験はXで大きな反響を呼びました。
{{tweet:2046217002889425237}}
結果は衝撃的でした。公開から36時間以内に、Perplexityがこのページを**引用元1位**(10件中)として表示したのです。人間がブラウザでアクセスしても見えるのは白い画面だけ。テキストも画像も何もありません。しかしAIはそこに「権威ある情報源」を見出しました。
### 7層ゴーストスタックの技術構成
Deforth氏はこの手法を「Seven-Layer Ghost Stack」と名付けています。ページの裏側には以下の7層が仕込まれていました。
| 層 | 技術要素 | 役割 |
|---|---------|------|
| 1 | セマンティックmetaタグ・VibeTags | ページの主題と文脈をAIに伝達 |
| 2 | JSON-LD構造化データ(6スキーマ) | ScholarlyArticle、Person、Organization、FAQPage、WebSite、ResearchOrganization |
| 3 | screen-reader-only テキスト(1,500語超) | CSSで視覚的に非表示、機械には読める本文 |
| 4 | インラインmicrodataアトリビュート | HTML要素レベルの意味付け |
| 5 | llms.txt / llms-full.txt | AIクローラー向けのサイト要約 |
| 6 | reasoning.json(Ed25519署名付き) | Agentic Reasoning Protocol準拠の推論用データ |
| 7 | .well-known/ai-manifest.json | AI発見用マニフェスト |
驚いたのは、この構造がW3CのData Integrity仕様に基づくEd25519暗号署名まで含んでいたことです。単なる構造化データの羅列ではなく、**AIシステムが信頼性を検証するための暗号的な証明**まで組み込まれていたのです。
さらに興味深いのは「カナリアトークン」の仕掛けです。インターネット上のどこにも存在しない固有のフレーズを構造化データに埋め込み、AIがそのフレーズを引用すれば「このページから情報を取得した」証拠になるという自己検証メカニズムです。
> 参考・引用:
> [Can You Rank In Google Without Content? - Hobo Web](https://www.hobo-web.co.uk/breaking-can-you-rank-in-google-without-content/)
> [Phantom Authority — Research by Sascha Deforth | TrueSource](https://phantomauthority.ai/)
> [ChatGPT & Perplexity Treat Structured Data As Text On A Page - Search Engine Roundtable](https://www.seroundtable.com/chatgpt-perplexity-structured-data-text-40862.html)
---
## 2. なぜAIは「空白のページ」を信頼したのか
### AIの「目」は人間と根本的に異なる
この実験が浮き彫りにした核心は、**AIシステムは人間とはまったく異なるレイヤーでWebを見ている**ということです。
GoogleのクローラーはHTMLをレンダリングし、人間が見るものとほぼ同じコンテンツを評価対象にします。だからこそ「hiddenテキストはスパム」というルールが成立します。一方、PerplexityやChatGPTは構造化データをテキストコンテンツと同等に扱います。JSON-LDのScholarlyArticleスキーマに記述された内容を、まるで通常の記事本文のように解釈し、引用元として採用するのです。
Deforth氏はこの現象を「Webの二分化」と表現しています。
- **ヒューマンWeb** — ビジュアルデザイン、UIコンポーネント、人間の目に最適化されたインターフェース
- **エージェントWeb** — 構造化データ、llms.txt、APIエンドポイント、機械に最適化されたデータ層
### エンティティ権威はデータで構築される
率直に言って、この実験の真の教訓は「コンテンツなしでもAIに引用される」ことではありません。**エンティティ権威(Entity Authority)が構造化データによって構築できる**という事実です。
6種類のJSON-LDスキーマが連携し、Person(Sascha Deforth)→ Organization(TrueSource)→ ScholarlyArticle(Phantom Authority研究)→ FAQPage(8つのQ&A)という**エンティティのネットワーク**を形成していました。AIはこの関係性を解読し、「この人物がこの組織でこの研究を行った」という文脈を理解した上で引用判断を下したのです。
エンティティ権威がAI検索可視性を左右するメカニズムについては「[エンティティ権威がAI検索可視性を決める](/blog/entity-authority-ai-search-2026/)」で詳しく解説しています。
> 参考・引用:
> [構造化データ×LLMO — 検索エンジンとAIの両方に - Tufe Company](https://tufecompany.co.jp/blog/structured-data-llmo-dual-optimization-2026)
> [GEO is the New SEO: Optimizing for AI Answer Engines in 2026 - Charles Jones](https://charlesjones.dev/blog/geo-new-seo-ai-answer-engines-2026)
> [AI-Readiness Benchmark 2026: StudioMeyer vs. 20 Web Agencies](https://studiomeyer.io/en/blog/ai-readiness-benchmark-2026)
---
## 3. GoogleとAI検索の「ダブルスタンダード」
### 同じページが「スパム」であり「権威」でもある
この実験の最も皮肉な側面は、**まったく同じページがGoogleではスパム、Perplexityでは権威ある引用元1位**と判定されたことです。
Googleのガイドラインは明確です。「構造化データは、ページ上でユーザーに見えるコンテンツの正確な表現でなければならない」。可視テキストが一切ないのにJSON-LDでScholarlyArticleを記述するのは、Googleの基準では構造化データの悪用に該当します。
ところがPerplexityは、この構造化データを正確に読み取り、以下の情報を正しく要約して返しました。
- 実験の目的(ゼロコンテンツでAI引用を獲得できるか)
- 創設者の名前(Sascha Deforth)
- 技術構成(7層ゴーストスタック)
- 結果(引用元1位の獲得)
### これは悪用なのか、それとも未来なのか
面白いのは、SEO業界でもこの実験への反応が二分したことです。批判派はGoogleのスパムポリシー違反を指摘し、擁護派はAI時代のWebの在り方を先取りした実験として評価しています。
私の見解はこうです。**この実験自体を真似すべきではない**が、**この実験が示した原理は活用すべき**です。可視コンテンツを持たないページは長期的に持続しません。しかし「構造化データがAI引用に直結する」という原理は、通常のコンテンツを持つページにも適用できます。むしろ、質の高いコンテンツと構造化データの**両方**を持つページこそが、GoogleとAI検索の両方で勝てるのです。
[LinkSurge](https://linksurge.jp/)のGEO分析では、自社サイトが各AI検索エンジンでどのように引用されているかをモニタリングできます。Google評価とAI引用のギャップを把握することが、この「ダブルスタンダード」時代の第一歩です。
> 参考・引用:
> [Perplexity対策の3つの条件|ChatGPTとの違いと引用される方法 - Crevia-ts](https://crevia-ts.com/archives/2540)
> [【実録】AI検索対策(GEO)やってみた。構造化データ - Medifund](https://medifund.jp/geo/geo-structured-data-experiment-result/)
> [llms.txt for Websites: Complete 2026 Guide - Bigcloudy](https://www.bigcloudy.com/blog/what-is-llms-txt/)
---
{{linksurge-card}}
---
## 4. あなたのサイトで今日からできるGEOアクション
Phantom Authority実験は極端な例ですが、ここから抽出できる**合法的かつ効果的な施策**は数多くあります。以下は、Googleのガイドラインに違反せずにAI引用を強化する6つのアクションです。
### アクション1:JSON-LD構造化データを充実させる
最も直接的な施策です。JSON-LDの`Article`や`FAQPage`スキーマは、AIがページの内容を正確に理解するための「翻訳層」として機能します。Phantom Authority実験では6種類のスキーマを重ねましたが、通常のサイトでも`Article` + `FAQPage` + `Organization` の3点セットで効果が得られます。
### アクション2:llms.txtファイルを設置する
llms.txtはAIクローラー向けのサイト要約ファイルで、robots.txtのAI版とも言えます。Cloudflareが「Markdown for Agents」としてこの仕組みを推進しており、「[Cloudflare Markdown for AgentsとAI対策の新常識](/blog/cloudflare-markdown-for-agents-2026/)」で詳しく解説しています。サイトのルートに配置するだけで、AIがサイト全体の構造と主要コンテンツを効率的に把握できるようになります。
### アクション3:FAQPageスキーマでAtomic Answersを提供する
AIが引用しやすいのは、40〜60語程度の自己完結した回答(Atomic Answers)です。FAQPageスキーマにこの粒度のQ&Aを含めることで、ChatGPTやPerplexityが回答を生成する際の引用元として選ばれる確率が高まります。
### アクション4:エンティティ権威を構築する
Person、Organization、sameAsプロパティを使って、サイトの運営者・組織の情報をJSON-LDで明示します。AI検索エンジンはエンティティの信頼性を重視するため、「誰が書いたか」「どの組織が運営しているか」の構造化が引用判断に影響します。
### アクション5:AI引用状況をモニタリングする
施策の効果を測定しなければ改善できません。[LinkSurge](https://linksurge.jp/)のAI Overview分析やGEOモニタリング機能を使えば、自社サイトがGoogle AI Overviews、Perplexity、ChatGPTでどのように引用されているかを定期的にチェックできます。
### アクション6:コンテンツをAtomic Answers形式で構造化する
記事本文の中に、AIがそのまま引用できる粒度の定義・説明文を意識的に配置します。「GEOとは〜」「llms.txtとは〜」のような40〜60語の自己完結した段落が、AI検索での引用獲得率を高めます。
GEOの全体像と実装戦略については「[GEO完全ガイド](/blog/geo-guide-japan-2026/)」もあわせてご覧ください。
> 参考・引用:
> [【2026年最新】ChatGPT・Gemini・Perplexityに引用されるには - YomoWebb.Design](https://yomowebb.com/llmo-chatgpt-gemini-perplexity-citation-guide/)
> [LLMO・GEO・AEO — AI検索最適化の3つのアプローチを - Zenn](https://zenn.dev/kenimo49/articles/llmo-geo-aeo-ai-search-optimization)
> [JSON-LD for SEO: Complete Schema Markup Guide (2026) - Foglift](https://foglift.io/blog/json-ld-seo-guide)
> [Structured data: SEO and GEO optimization for AI in 2026 - Digidop](https://www.digidop.com/blog/structured-data-secret-weapon-seo)
---
## よくある質問(FAQ)
### 構造化データだけでAI検索に引用されるのですか?
Phantom Authority実験が証明したように、技術的にはJSON-LDやllms.txtなどの機械可読データだけでAI検索エンジンに引用されることは可能です。ただし、Googleは可視コンテンツのない構造化データをスパムとして扱うため、長期的かつ安全な戦略としては、質の高いコンテンツと構造化データの両方を揃えることが推奨されます。
### llms.txtとは何ですか?
llms.txtは、AIクローラーやLLMに対してサイトの構造と主要コンテンツの要約を提供するテキストファイルです。robots.txtがクローラーのアクセスルールを定義するのに対し、llms.txtはサイトの全体像をAIフレンドリーな形式で伝達します。サイトのルートディレクトリに配置します。
### この実験を自分のサイトでも試すべきですか?
いいえ。可視コンテンツを持たないページはGoogleのガイドラインに明確に違反しており、ペナルティのリスクがあります。この実験から学ぶべきは手法そのものではなく、**AIがエンティティの関係性を構造化データから読み取っている**という点です。ただし、この実験が示したのは「可視コンテンツがない極端な条件でも読み取られた」ことであり、通常のページで構造化データを足せば引用が増えることまでは示していません。schemaを追加した対照実験では引用の増加は確認されていない点とあわせて理解してください。
### JSON-LDとmicrodataのどちらがAI対策に有効ですか?
Googleは公式にJSON-LDを推奨しており、AIシステムもJSON-LD形式の構造化データを最も効率的に解析します。JSON-LDはHTMLと分離して記述できるため実装・管理が容易で、複数のスキーマを1ページに配置しやすいメリットもあります。
### GEOの効果はどのように測定できますか?
GEO(生成AI最適化)の効果測定は、Perplexity・ChatGPT・Google AI Overviewsの各プラットフォームで自社サイトの引用頻度を追跡することが基本です。LinkSurgeの[GEOモニタリング機能](https://linksurge.jp/)ではこれらの指標をダッシュボードで一括管理できます。
---
## まとめ:構造化データは「AI時代の名刺」である
Phantom Authority実験は、AI検索の世界がいかに従来のSEOとは異なるルールで動いているかを鮮やかに示しました。空白のページが引用元1位になるという結果は衝撃的ですが、この実験の本質的なメッセージはもっとシンプルです。**AIはあなたのサイトのデザインを見ていない。構造化データを読んでいる。**
ただし、ここから何をするかは目的で分けてください。
JSON-LDはGoogleが推奨する記述形式で、期待できるのはリッチリザルトなど従来検索での見え方と、エンティティ情報を曖昧さなく伝えることです。ただしリッチリザルトの表示は保証されません。マークアップがページ内容と一致していること、機能ごとのガイドラインを満たしていることが前提で、表示するかどうかはGoogleが判断します。ただし `FAQPage` については、リッチリザルトという用途自体がもうありません。Googleは `HowTo` のリッチリザルトを2023年に、[`FAQPage` のリッチリザルトを2026年5月に](https://developers.google.com/search/updates#removing-faq-rich-result)廃止しています。リッチリザルト目的で残っているのは `Article`・`BreadcrumbList` などです(`Product` は商品ページ、`Review` は対象タイプに対する実際のレビュー・評価があるページに限られ、一般的な記事には使えません)。`FAQPage` に残る意味は、エンティティ情報を機械可読にすることです。
AI引用を増やす効果は、schemaを追加した対照実験では確認されていません。なお同実験の対象は、実験前からAI Overviewsに100回以上引用されていたページに限られ、新規ページや未発見のページでの効果は検証されていません。llms.txtも同様で、Google Searchでは使われない一方、AIエージェント用途では実際に使われています。
LinkSurgeの[GEO分析機能](https://linksurge.jp/)では、構造化データの実装状況やAI引用の変化をリアルタイムでモニタリングできます。AI検索時代の第一歩を、今日から踏み出してみてください。
---
## 検索意図とは?SEOにおける4つの分類と分析・最適化の実践ガイド
> URL: https://linksurge.jp/blog/search-intent-seo-guide/
> Date: 2026-04-17 | Category: SEO | Author: 緒方亜朗
> Tags: 検索意図, SEO対策, コンテンツ最適化, キーワード分析, ユーザーインテント
## この記事の結論:検索意図を理解すればSEO成果は変わる
1. **検索意図は4つに分類できる** — インフォメーショナル(情報探索)、ナビゲーショナル(案内)、トランザクショナル(取引)、コマーシャル(商業調査)の4タイプを押さえることがSEO対策の出発点になる
2. **Googleは検索意図に合致したコンテンツを上位表示する** — キーワードの一致だけでなく、ユーザーの「目的」に応えるページが評価される時代になっている
3. **SERP分析が最も実践的な調べ方** — 実際にキーワードで検索し、上位10件のコンテンツ形式を確認することで、Googleが判定した検索意図がわかる
4. **検索意図ごとにコンテンツ形式を変える** — 情報型にはブログ・ガイド、取引型には商品ページ・LPなど、意図に応じた最適なフォーマットがある
5. **AI検索の普及で検索意図の重要性が増している** — AI OverviewやChatGPT検索は意図理解の精度が高く、意図にズレたコンテンツはますます表示されにくくなる
以下では、各テーマを順に解説します。要点を動画でも解説しています。
{{youtube:XyKClQhN6RM|検索意図とは?SEOの4分類と、SERPから意図を読み取る実践的な調べ方}}
---
## 1. 検索意図とは何か?なぜSEOで重要なのか

検索意図(Search Intent)とは、ユーザーが検索エンジンにキーワードを入力するときに抱いている目的や動機のことです。たとえば「SEOとは」と検索する人は情報を知りたいのであって、何かを購入したいわけではありません。一方、「SEOツール 料金」と検索する人は、導入を具体的に検討している段階にあります。
### なぜGoogleは検索意図を重視するのか?
Googleは検索結果の品質向上を図るため、検索意図に合致したコンテンツを上位表示する傾向を年々強めています。検索エンジンがセマンティック検索を取り入れたことで、単なるキーワードの一致ではなく、クエリの背後にある目的を理解したうえで結果を返すようになりました。
私が日々のSEO分析を通じて感じるのは、「キーワードは同じでも、意図がズレているコンテンツは上がらない」という事実の重みです。検索意図を無視したコンテンツは、いくらキーワードを盛り込んでもユーザーの離脱を招き、Googleの評価も下がります。
[トピッククラスターと内部リンク戦略](/blog/topic-cluster-internal-linking-strategy/)を構築する際にも、各ページがどの検索意図に対応するかを意識しておくことが重要です。
> 参考・引用:
> [検索意図とは?4分類の特徴と分析方法・SEO対策への活かし方を徹底解説 - Techsuite](https://bakuyasu.techsuite.co.jp/29284/)
> [検索意図とは?SEOで重要な4つの分類と調べ方を解説 - Seo-dash](https://seo-dash.net/search-intent/)
> [検索意図とは - ListeningMind](https://jp.listeningmind.com/knowledge/search-intent/)
---
## 2. 検索意図の4つの分類と具体例

検索意図は一般的に以下の4タイプに分類されます。2025年のデータでは、全検索の52.65%がインフォメーショナル、32.15%がナビゲーショナル、14.51%がコマーシャル、0.69%がトランザクショナルという内訳が報告されています。
### インフォメーショナル(情報探索型)
ユーザーが知識や情報を得たいときの検索です。「SEOとは」「検索意図 分類」「リンクビルディング やり方」などが該当します。全検索の半数以上を占めるため、ブログやガイド記事で対応するのが基本です。
### ナビゲーショナル(案内型)
特定のサイトやページにたどり着きたいときの検索です。「Amazon ログイン」「Google Search Console」などブランド名を含むクエリが中心です。自社のサービス名で検索されたときに適切なページが表示されるよう、サイト構造の最適化が必要です。
### トランザクショナル(取引型)
購入や申し込みなど具体的なアクションを起こしたいときの検索です。「iPhone 15 購入」「SEOツール 無料トライアル」が典型例です。全体の0.69%と少数ですが、コンバージョンに直結するため収益への影響は大きくなります。
### コマーシャル・インベスティゲーション(商業調査型)
購入前の比較・検討段階の検索です。「SEOツール 比較」「LinkSurge 評判」のように、候補を絞り込むためのリサーチ段階を反映しています。比較記事やレビュー記事を用意することが効果的です。
率直に言って、この4分類を知っているだけでは不十分です。実際のキーワードは複数の意図が混在することが多く、たとえば「SEOツール おすすめ」はコマーシャルとインフォメーショナルの両面を持ちます。SERP(検索結果ページ)で実際にどんなコンテンツが表示されているかを確認するのが最も確実な判定方法です。
> 参考・引用:
> [Search Intent: The New SEO Currency in 2026 - Brand Mender](https://www.brandmender.com/blog/search-intent-seo-2026/)
> [Search Intent in SEO and Its Impact on Rankings For 2026 SEO - Digital Sprout](https://digitalsprout.com/search-intent-in-seo/)
> [Search Intent Models: Why important for Modern SEO in 2026? - ClickRank](https://www.clickrank.ai/search-intent-models/)
---
## 3. 検索意図の分析方法:3つの実践アプローチ
検索意図を正確に把握するためには、複数の手法を組み合わせることが重要です。ここでは実務で使える3つのアプローチを紹介します。
### アプローチ1:SERP分析(最重要)
最も信頼できる方法は、対象キーワードで実際にGoogle検索を行い、上位10件の結果を確認することです。表示されるコンテンツの形式(ブログ記事、商品ページ、比較表、動画など)がそのままGoogleが判定した検索意図を反映しています。
たとえば「検索意図 SEO」で検索すると、上位にはブログ記事やガイドが並びます。これはGoogleがこのクエリをインフォメーショナルと判定していることを意味します。
### アプローチ2:キーワードツールの活用
Google Search ConsoleやキーワードプランナーなどのツールでCTRや検索ボリュームを確認します。CTRが低い場合、コンテンツが検索意図にマッチしていない可能性が高い。[LinkSurge](https://linksurge.jp/)のような分析ツールを活用すれば、キーワードごとの検索意図分類を効率的に把握できます。
### アプローチ3:ユーザー行動データの分析
GA4でページ滞在時間、直帰率、スクロール深度などを確認します。意図に合致しているページは滞在時間が長く、直帰率が低い傾向にあります。逆に直帰率が高いページは、検索意図とコンテンツのミスマッチが起きている可能性があります。
私が調べたところ、これら3つのアプローチを組み合わせて分析している企業ほど、コンテンツの検索順位が安定しているという傾向が見えてきました。単一の方法に頼るのではなく、データを多角的に見ることがポイントです。
> 参考・引用:
> [【2025年最新版】検索意図最適化とは?AI時代のSEO対策 - Techsuite](https://bakuyasu.techsuite.co.jp/29167/)
> [Integrate Search Intent Analysis Into Your Enterprise Content Strategy - Siteimprove](https://www.siteimprove.com/blog/search-intent-optimization/)
> [Mastering Search Keyword Intent: A Simple Guide to Better SEO - Niumatrix](https://niumatrix.com/keyword-intent-guide/)
---
## 4. 検索意図に基づくコンテンツ最適化の実践

検索意図を分析したら、次はそれに合わせたコンテンツ最適化です。意図ごとに最適なコンテンツ形式、構造、KPIが異なります。
### 情報探索型への最適化
ブログ記事、ハウツーガイド、用語解説が効果的です。見出しに疑問形を使い、冒頭で結論を示す「アンサーファースト」の構造にすると、AI Overviewにも引用されやすくなります。KPIはページビュー数と平均滞在時間。
### 案内型への最適化
自社名・サービス名で検索されたとき、適切なランディングページが表示されるようにします。構造化データ(Organization、WebSite スキーマ)を実装し、ブランドSERPを整備することが重要です。
### 取引型への最適化
商品ページやサービス申し込みページで直接的なCTA(行動喚起)を配置します。ページ読み込み速度やモバイル対応も、コンバージョン率に直結するため優先度が高い。
### 商業調査型への最適化
比較記事、レビュー、ランキングコンテンツが有効です。「〇〇 vs △△」形式や、チェックリスト形式にすると、ユーザーの意思決定を助けるコンテンツになります。
ここで大切なのは、1つのページに複数の検索意図を詰め込みすぎないことです。[SEO対策完全ガイド](/blog/seo-guide-2026/)でも解説していますが、1ページ1意図の原則を守ることで、Googleからの評価が安定します。
> 参考・引用:
> [2025年最新版|厳選「コンテンツSEOチェックリスト」 - Siteengine](https://www.siteengine.co.jp/blog/content-seo-checklist-2025/)
> [【2026年最新】SEOとは?優先度の高い10のSEO対策 - Mieru](https://mieru-ca.com/blog/seo-measures/)
> [Search Intent in 2026: The 3 New Intent Types AI Search Created - Jeff Lenney](https://jefflenney.com/blog/search-intent-in-2026/)
---
## 5. AI検索時代における検索意図の変化
2025年以降、AI OverviewやChatGPT検索の普及により、検索意図の判定はさらに精緻になっています。AI検索はユーザーのクエリを文脈ごと理解するため、単純なキーワードマッチングではなく、意図の本質に合ったコンテンツだけが表示されるようになりました。
### AI検索が生み出す新しい意図タイプ
従来の4分類に加え、AI検索の普及により新たな意図パターンが観測されています。「深掘り探索型」(AIの回答をさらに詳しく知りたい)や「検証型」(AIの回答が正しいか確認したい)といった、AI特有の検索行動が増えています。
### SEO担当者が取るべきアクション
AI検索に対応するには、[生成AI検索がSEOに与える影響](/blog/ai-search-seo-japan-2026/)でも触れている通り、構造化データの実装やE-E-A-T(経験・専門性・権威性・信頼性)の強化が有効です。LinkSurgeの[AI対応分析機能](https://linksurge.jp/ai-ready)を使えば、自社コンテンツがAI検索にどの程度最適化されているかを定量的に評価できます。
率直に言って、AI検索の台頭は検索意図の重要性を下げるどころか、むしろ高めています。AIは意図理解が人間よりも精密なため、意図に合わないコンテンツはこれまで以上に排除されやすくなります。
> 参考・引用:
> [SEO対策はもう古い?2026年に通用する最新の検索エンジン対策 - Formzu](https://blog.formzu.com/seo-strategy-2026)
> [SEO And AI In 2026: Adapt Or Get Buried In The Search Results - eLearning Industry](https://elearningindustry.com/advertise/elearning-marketing-resources/blog/seo-and-ai-in-2026-adapt-or-get-buried-in-the-search-results)
> [SEO & AI Search Best Practices to Implement in 2026 - Svitla Systems](https://svitla.com/blog/seo-best-practices/)
---
{{linksurge-card}}
---
## よくある質問(FAQ)
### 検索意図はどうやって調べるのですか?
最も実践的な方法は、対象キーワードで実際にGoogle検索を行い、上位10件の結果のコンテンツ形式を確認することです。ブログ記事が多ければインフォメーショナル、商品ページが多ければトランザクショナルと判定できます。Google Search Consoleでクリック率を確認するのも有効です。
### 検索意図の4分類は全キーワードに当てはまりますか?
多くのキーワードは4分類のいずれかに該当しますが、複数の意図が混在するケースも少なくありません。たとえば「SEOツール」は情報探索と商業調査の両面を持ちます。SERPの実態を確認して優先すべき意図を判断することが重要です。
### 検索意図を間違えるとどうなりますか?
ユーザーが求めている情報と異なるコンテンツを提供することになるため、直帰率が上がり、滞在時間が短くなります。結果としてGoogleの評価が下がり、検索順位も低下します。既存コンテンツの検索意図の見直しは、SEO改善の中でも投資対効果が高い施策です。
### AI検索でも検索意図は重要ですか?
はい、AI検索ではむしろ重要性が増しています。AIはクエリの文脈を深く理解するため、意図とコンテンツのミスマッチをより正確に検知します。AI Overviewに引用されるには、ユーザーの意図に正確に応える構造化されたコンテンツが必要です。
---
## まとめ:検索意図の理解がSEO成功の土台になる
検索意図は、SEOの基盤ともいえる概念です。4つの分類を理解し、SERP分析を中心とした実践的な調査方法でユーザーの意図を正確に把握すること。そして、意図に合ったコンテンツ形式を選び、適切に構造化すること。この一連のプロセスが、検索順位の改善だけでなく、ユーザー体験の向上にもつながります。
AI検索が普及する2026年以降、検索意図への対応はオプションではなく必須要件になりつつあります。まずは自社の主要ページについて、狙っているキーワードの検索意図とコンテンツが一致しているかを確認することから始めてみてください。
LinkSurgeの[キーワード分析機能](https://linksurge.jp/)では、キーワードごとの検索意図分類やSERP分析を効率的に行えます。検索意図に基づいたコンテンツ最適化を、データドリブンで進めていきましょう。
---
## TikTok検索最適化の教科書:Z世代の65%が使う新検索エンジンで勝つ戦略 2026年版
> URL: https://linksurge.jp/blog/tiktok-seo-ai-search-2026/
> Date: 2026-04-17 | Category: SNS | Author: 緒方亜朗
> Tags: TikTok SEO, SNS戦略, AI検索最適化, Z世代マーケティング, 動画SEO, ハッシュタグ戦略, エンゲージメント
## この記事の結論:2026年TikTokで勝つための5つの要点
TikTokはもう「ダンス動画のアプリ」ではありません。Adobeが2026年2月に公開した米国消費者調査では、Z世代の65%がTikTokを検索エンジンとして使った経験を持ち、全世代でも49%(2024年は41%)に達しています。私が日英のアルゴリズム資料と最新エンゲージメントデータを突き合わせて見えてきた、実務上の要点は以下の5つです。
> **2026年9月3日更新**: 初版(2026年4月)で使っていた「Z世代の40%」はGoogle幹部の2022年の発言に基づく古い数値だったため、Adobeの2026年調査に差し替えました。あわせて、AI Overviewsの表示率・ゼロクリック率・エンゲージメント率のベンチマークを2026年の最新値に更新し、初版で「Perplexity×TikTok統合」と書いていた箇所は事実誤認だったため訂正しています(詳細はセクション4)。
1. **TikTokは「検索も担うプラットフォーム」になった。ただしGoogleの代替ではない** — Z世代の65%がTikTokで検索した経験を持つ一方、「GoogleよりTikTokに頼る」と答えたZ世代は4%(2024年の8%から半減)で、89%はGoogleを最も好むと回答。月間アクティブユーザーは推計19億人(公式発表は2021年9月の10億人が最後)。米国のゼロクリック検索は2026年1〜4月に68.0%まで進み、AI Overviewsは全クエリの43〜48%に表示されるようになった今、「Googleの外側」にも検索面を持つ意味は増している
2. **2026年のアルゴリズムは「完了率・シェア・再視聴」の3軸** — いいねやフォロワー数より、最後まで見られた割合・他者に送られた回数・繰り返し視聴された回数が優先評価される。最初の1〜3秒で離脱されたら終わりです
3. **TikTok SEOは「Search Insights→キャプション→ハッシュタグ→テロップ」の4レイヤーに、2026年4月から「キーワード管理」が加わった** — TikTokが動画に自動付与する検索キーワードを、クリエイター側で確認・除外・提案できるようになった。動画内テキストや自動字幕もアルゴリズムが読み取るため、キーワードを仕込まないのはもったいない
4. **AI検索でのTikTok引用は「増加中」ではなく「少数で変動が大きい」** — 2026年1〜2月の35万件超の引用分析では、ソーシャル引用の過半をRedditが占め、YouTubeが続く一方、TikTokは主要ソースに入っていない。さらに2026年8月中旬、ChatGPTはソーシャル系の引用を急減させ、TikTokのURL引用は72%減。AI引用はTikTok施策の「主目的」ではなく「副次効果」と位置づけるべき
5. **エンゲージメント率のベンチマークは「分母」で変わる** — Socialinsiderの2026年ベンチマーク(200万本の動画)では、視聴数基準のエンゲージメント率が2025年平均4.2%、2026年Q2には3.85%へ低下。この水準を超えるにはフック設計×TikTok SEO×エデュテイメントの掛け算が必要で、投稿本数を増やすだけでは伸びない
以下では、これらを1つずつ掘り下げていきます。要点と初版からの訂正内容は動画でも解説しています。
{{youtube:Dr0T_9NeMgw|TikTok検索最適化の教科書2026|アルゴリズム3軸とAI引用の現在地}}
---
## 1. なぜ今「TikTok SEO」なのか — 検索エンジンとしてのTikTok

率直に言って、「SNSとSEOは別物」という前提はもう通用しません。ただし、この文脈でよく引用される「Z世代の40%がGoogleではなくTikTokやInstagramで検索する」という数字には注意が必要です。これはGoogleのPrabhakar Raghavan上級副社長(当時)が**2022年7月**のFortune Brainstorm Techで述べた発言で、Googleの説明では「米国の18〜24歳を対象にした社内調査」、しかも「ランチの店を探すとき」に限定した数値でした。2026年の記事で引き続き使うには古すぎます。
最新のデータで見直すと、Adobe Expressが2026年2月に公開した調査(SurveyMonkey実施、2026年1月、米国の消費者807名・小規模事業者200名)は次の結果でした。
| 指標(米国) | 2026年 | 2024年 |
|:---|:---|:---|
| TikTokを検索エンジンとして使ったことがある(全世代) | **49%** | 41% |
| 同・Z世代 | **65%** | — |
| 「GoogleよりTikTokに頼る」と答えたZ世代 | **4%** | 8% |
| Googleを最も好む検索手段と答えたZ世代 | **89%** | — |
| TikTokが情報探しに「効果的」と答えたZ世代 | 25% | — |
つまり、「使う人」は増え続けている一方で、「Googleの代わりにする人」はむしろ減っています。TikTokは**Googleを置き換える検索エンジンではなく、Googleと並走する検索面**として設計するのが正しい、というのがこの記事の一貫した立場です。
日本のデータも見ておきましょう。hotice株式会社と合同会社RASA JAPANが2026年1月に実施した調査(528名)では、TikTokを「ほぼ毎日」使う人が10代で65.5%、20代で71.0%に達し、30代以上でも45〜52%と、若年層限定のメディアではなくなっています。ただし利用目的として「商品・サービスの検索・検討」を挙げたのは全体の21.1%で、日本ではまだ「検索」より「発見」の比重が大きいのが実態です。NTTドコモ モバイル社会研究所の2026年2月調査(7,279名)でも、10代が趣味の情報源として使うのはYouTube 68%、X 48%、Instagram 48%に対してTikTokは36%で、日本のTikTok検索はまだ伸びしろの段階と見るのが妥当でしょう。
### 数字で見るTikTokと検索環境の変化
TikTokの月間アクティブユーザー数は、Business of Appsの推計で2026年Q1時点**約19.2億人**とされています(Sprout Socialは広告リーチベースで約19.9億人)。ただしByteDanceが公式に公表した数字は2021年9月の「10億人突破」が最後で、それ以降はすべてサードパーティの推計です。推計元によって定義も数字も異なり、eMarketerは2024年5月時点で約10.4億人としているため、「約19億人」は幅を持って受け止めてください。Socialinsiderが2026年4月に公開したベンチマーク(200万本の動画、2024年1月〜2025年12月)では、TikTokの視聴数基準エンゲージメント率は2025年平均で**4.2%**と、Instagram・Xを大きく上回っています(詳細はセクション5)。
もう一つ見逃せないのが「ゼロクリック検索」の増加です。SparkToroの2024年調査では米国の**58.5%**、EUの**59.7%**のGoogle検索がクリックを伴わずに完結していましたが、2026年6月公開の続報(Similarwebのクリックストリーム、2026年1〜4月、米国)では**68.0%**まで上昇しました。Google AI Overviewsの表示率も、2025年時点の13〜20%から、2026年7月にはSimilarweb推計で約**43%**、Semrush推計で約**48%**に達しています(いずれもサードパーティの計測値で、Google公式の数字ではありません)。伝統的なオーガニック順位の価値は確実に目減りしており、検索トラフィックを守るには「Googleの外側」にも資産を持っておく必要があります。
### TikTokは「検索×発見」の両方を担う
TikTokの特殊性は、ユーザーが能動的に検索する場でもあり、おすすめフィードで受動的に発見される場でもあることです。Google検索と比べると、検索クエリ1つあたりの情報密度が低く、動画で「体験」を伝えるコンテンツが強い。「おすすめのカフェ」「エクセルの時短術」「最新のスキンケア」のように、文章では伝えきれない質感・操作感・雰囲気を検索するユーザーが増えました。
X・Instagram・LinkedInのアルゴリズム設計は姉妹記事「[X・Instagram・LinkedInのAI検索最適化:2026年版SNS戦略ガイド](/blog/sns-ai-search-optimization-2026/)」で扱いましたが、TikTokはそれらとは設計思想が大きく異なります。本記事ではTikTok単体の勝ち筋を掘り下げていきます。
「動画UGCをAIがどう引用するか」は2026年の重要論点ですが、後述するとおりTikTokのURLがAI回答に引用される頻度はまだ小さく、2026年8月にはChatGPTで大きく減少しました(セクション4)。UGC全般(Reddit・Yahoo!知恵袋・noteを含むテキストUGC)がAI検索引用で占める位置は「[UGC × AI検索引用戦略](/blog/ugc-ai-search-brand-mentions-2026/)」で深掘りしています。
> 参考・引用:
> [Using TikTok as a search engine - Adobe Express(2026年2月)](https://www.adobe.com/express/learn/blog/using-tiktok-as-a-search-engine)
> [TikTok Revenue and Usage Statistics (2026) - Business of Apps](https://www.businessofapps.com/data/tik-tok-statistics/)
> [Google exec suggests Instagram and TikTok are eating into Google's core products - TechCrunch(2022年7月)](https://techcrunch.com/2022/07/12/google-exec-suggests-instagram-and-tiktok-are-eating-into-googles-core-products-search-and-maps/)
> [Google zero-click searches reach 68% in early 2026 - Search Engine Land](https://searchengineland.com/google-zero-click-searches-2026-study-479717)
> [About Half Of Google Searches Have AI Overviews - Search Engine Roundtable(2026年7月30日)](https://www.seroundtable.com/half-google-searches-ai-overviews-41780.html)
> [2026年最新調査:日本人528名のTikTok利用実態レポート - syncAD](https://syncad.jp/news/96646/)
> [若年層ほどSNSや動画など多数のデジタル情報源を活用 - NTTドコモ モバイル社会研究所(2026年6月)](https://www.moba-ken.jp/project/lifestyle/20260629.html)
> [Gen Z's TikTok-Over-Google Preference Fell 50% — Here's What - ALM Corp](https://almcorp.com/blog/gen-z-tiktok-google-preference-drop-2026-data/)
---
## 2. 2026年版TikTokアルゴリズム — 完了率・シェア・再視聴の3軸

TikTokのアルゴリズムは2025年後半から明確にシグナルの優先順位を組み替えました。Virvidの2026年1月分析、Shuttlerock・Shubihiroの日本語解説を突き合わせて整理すると、現在重視されているのは次の3指標です。
### 3大指標の内訳
| 指標 | 意味 | アルゴリズム上の重み |
|:---|:---|:---|
| **完了率(Completion Rate)** | 動画を最後まで見られた割合 | 最重要。15〜60秒の長さが最適 |
| **シェア率(Share Rate)** | DMや他SNSに転送された回数 | 「いいね」の数倍の重み |
| **再視聴率(Re-watch Rate)** | 同じ動画が繰り返し見られた回数 | フィード伸長の強力なブースター |
「いいね」と「フォロワー数」の相対的な重みは下がっています。考えてみれば合理的で、いいねは惰性で押される信号ですが、完了率は「時間を投資させた」証拠で、シェアや再視聴は「内容が価値ある」ことを示す能動的な行動です。アルゴリズムが能動シグナルを優先するのは自然な進化だと思います。
### 最初の1〜3秒が全てを決める
完了率を上げるには、冒頭の1〜3秒が勝負です。Threadpostが整理した具体例は以下のようなフックパターン:
- 「〇〇の秘密教えます」(情報提供予告)
- 「これを知らないと損する」(損失回避)
- 「意外と知らない△△の使い方」(ギャップ)
- 「結論から言うと◯◯」(結論先出し)
冒頭でベネフィットを明示せずに背景説明から入る動画は、ほぼ確実に離脱されます。Andthenの2026年3月レポートでも、上位表示される動画の共通点として「**1秒目に主題が明示されている**」が挙げられています。
### 動画の長さは15〜60秒に収める
長すぎる動画は完了率を下げ、短すぎる動画は再視聴を誘発しにくい。日本の複数メディア(Boosttech・Shubihiro・Chaptertwo)が揃って推奨しているのが**15〜60秒のレンジ**です。30秒前後がスイートスポットという実務者の声もあります。
例外は「保存されるコンテンツ」——レシピやチュートリアルのように後で見返す動画は60秒を超えても評価される傾向があります。ここは業界・内容によって調整する必要があります。
### 補足:米国のアルゴリズムは2026年1月から別運用になった
2026年1月23日、TikTokは「TikTok USDS Joint Venture LLC」の設立を発表しました。Oracle・Silver Lake・MGXがそれぞれ15%を持つ主要投資家で、ByteDanceの持分は19.9%。公式発表によれば、この合弁会社は**米国ユーザーのデータでコンテンツ推薦アルゴリズムを再学習・テスト・更新**し、アルゴリズムはOracleの米国クラウド環境で保護されます。米国外のユーザーへの影響については発表で触れられておらず、「相互運用性によって米国ユーザーにグローバルなTikTok体験を提供する」とだけ述べられています。実務上の含意は、米国向けアルゴリズムが別体制で更新されていく以上、「米国のTikTokでバズった型」と日本のフィードの挙動が今後ずれていく可能性があること。英語圏のアルゴリズム解説を読むときは、米国固有の変更なのかグローバルの変更なのかを意識する必要が出てきました。
> 参考・引用:
> [Announcement from the new TikTok USDS Joint Venture LLC - TikTok Newsroom(2026年1月)](https://newsroom.tiktok.com/announcement-from-the-new-tiktok-usds-joint-venture-llc)
> [TikTok Algorithm 2026: 3 New Rules You Must Follow - Virvid](https://virvid.ai/blog/tiktok-algorithm-2026-explained)
> [TikTokアルゴリズム完全攻略(2026年最新版) - Andthen](https://andthen.co.jp/blog/tiktok-algorithm/)
> [【2026年最新】TikTokアルゴリズム完全攻略 - Shubihiro](https://shubihiro.com/column/tiktok-algorithm2025/)
> [TikTok SEO対策完全ガイド - Shuttlerock](https://www.shuttlerock.co.jp/article/detail/post-18115/)
---
## 3. TikTok SEO実装の5ステップ

ここからは実装編です。TikTok SEOは「どう検索される動画を作るか」という問いへの答えで、以下の5つのレイヤーで最適化します。
### ステップ1: Search Insightsで需要キーワードを発掘
TikTokアプリ内のクリエイターツール「Creator Search Insights」を使うと、自分のターゲット層が実際に検索しているキーワードを確認できます。Google Keyword Plannerに相当する機能で、ここで需要を確認してから動画企画に入るのが基本動作です。TikTok公式の案内ではアプリ内のツールという位置づけで、アプリの検索バーで「Creator Search Insights」と検索するか、クリエイターツールから開けます。
私が見ていて「もったいない」と感じるのは、この段階をすっ飛ばして感覚で企画を決めているアカウントが多いこと。Creator Search Insightsは**週1回**のペースで眺めるだけでも、トレンドと相性の良い企画の精度が上がります。
### ステップ2: キャプションにキーワードを自然配置
キーワードを特定したら、動画のキャプション(説明文)に不自然にならない文脈で配置します。Active-noteの解説で強調されているのは、**「キーワードを詰め込むのではなく、文脈で伝える」**という点。
| NGパターン | OKパターン |
|:---|:---|
| 「カフェ 渋谷 おしゃれ 安い Wi-Fi 電源」 | 「渋谷でWi-Fiと電源が使える、作業できる静かなカフェ3選です」 |
| 「ダイエット 簡単 1週間 食事」 | 「忙しくても続く、1週間ゆるめダイエットの食事プラン」 |
### ステップ3: ハッシュタグは3〜5個を戦略的に混ぜる
Boosttechの完全攻略ガイドが整理している「3タイプ混合戦略」が実務的です:
1. **ビッグタグ(数百万〜億投稿)**: #dance #recipe など。発見面でのリーチ用
2. **スモールタグ(数千〜数万投稿)**: #東京カフェ巡り など。競合が少なく上位表示しやすい
3. **オリジナルタグ**: ブランド独自のタグ。シリーズ化・UGC誘導用
合計**3〜5個**が最適で、10個以上詰め込むのはスパム判定のリスクがあります。
### ステップ4: テロップと自動字幕もSEO資産
見落とされがちですが、TikTokのアルゴリズムは**動画内のテキスト(テロップ)と自動生成字幕**も読み取ります。つまり、キャプションと同じキーワードをテロップや字幕にも配置することで、SEO効果を二重化できるわけです。
音声オフで視聴されるケースが多いTikTokでは、テロップは「完了率の向上」と「SEO最適化」の両方に効く一石二鳥の施策です。
#### 2026年4月の新機能:動画の「検索キーワード」を自分で管理できる
2026年4月、TikTokは動画に紐づく検索キーワードをクリエイター側で管理できる機能を展開しました。TikTokは「人気の検索に基づいて自動付与したキーワード」を投稿に表示し、クリエイターは的外れなキーワードをブロックしたり、ランクインさせたいキーワードを提案したりできます(TikTok側が最終的に妥当性を判断するため、キーワードの詰め込みはできません)。
これまで「この動画がどんな検索語に紐づいているか」はブラックボックスでしたが、この機能で**意図しない検索語に紐づいて低再生に落ち込んでいる動画を立て直す**手段ができました。まずは主要動画の自動付与キーワードを棚卸しし、キャプション・テロップで狙っている語とずれていないかを確認するところから始めてください。なお日本での提供状況は発表時点で明示されていないため、お使いのアカウントで表示されるかを確認してください。
### ステップ5: トレンド音源×投稿頻度の最適化
最後に、トレンドの音源をタイムリーに使用すること、そして**1日1〜4回**の継続投稿が推奨されます。Shubihiroの2026年2月データでは、投稿頻度が週3回未満のアカウントはアルゴリズム上の可視性が段階的に下がる傾向が示されていました。
ただ、ここは「質より量」ではありません。Socialinsiderの2026年ベンチマークによると、2024年から2025年にかけてTikTokの平均投稿本数は全フォロワー帯で**40%増加**した一方、動画あたりの視聴数は**23%減**、フォロワー増加数は**33%減**でした。投稿を増やしても1本あたりのリーチは薄まっており、頻度で押し切る戦略はすでに効きにくくなっています。毎日投稿する負荷と品質のバランスをどう取るかは、個別アカウントの体制次第です。
> 参考・引用:
> [TikTok lets users add relevant keywords to metadata - Social Media Today(2026年4月)](https://www.socialmediatoday.com/news/tiktok-lets-users-add-relevant-keywords-to-metadata/818507/)
> [2026 TikTok Benchmarks - Socialinsider](https://www.socialinsider.io/social-media-benchmarks/tiktok)
> [TikTokハッシュタグの完全攻略ガイド - Boosttech](https://media.boosttech.jp/shorts/tiktokhasutag/)
> [TikTok SEOで広がるチャンス - Active-note](https://www.active-note.jp/sns/tiktok-seo/)
> [【2026年最新】TikTokアルゴリズム完全攻略 - Shubihiro](https://shubihiro.com/column/tiktok-algorithm2025/)
> [TikTokの最新アルゴリズムを解説 - pamxy](https://pamxy.co.jp/marke-driven/sns-marketing/tiktok-algorithm/)
---
{{linksurge-card}}
---
## 4. AI検索エンジンでのTikTok引用の現在地 — 期待より小さく、変動が大きい

初版ではこのセクションを「AI検索エンジンがTikTok動画を引用し始めている」という前向きなトーンで書きましたが、その後の実測データを踏まえて内容を大きく改めます。結論から言うと、**AI検索でのTikTok引用は「少数」で、しかもプラットフォーム側の方針変更で予告なく大きく動く**というのが2026年9月時点の現実です。
### 訂正:Perplexity×TikTokの「統合」は実現していない
初版で「Perplexityは2026年にTikTokとの戦略的統合を発表した」と書きましたが、これは事実誤認でした。実際にあったのは、Perplexityが**2025年1月**にTikTokの米国事業との合併をByteDanceに提案し、同年3月に「Rebuilding TikTok in America」と題した構想(レコメンドアルゴリズムのオープンソース化、TikTok動画への引用・注釈機能の追加など)を公開した、という出来事です。この提案は採用されず、TikTokの米国事業は2026年1月にOracle・Silver Lake・MGXを主要投資家とする合弁会社に移行しました(セクション2の補足参照)。Perplexityはこの合弁に参加していません。初版で併記した「Perplexityは複雑なリサーチ質問の78%で全主張にソースを紐付ける(ChatGPTは62%)」という数字も、出典元の調査手法が公開されていないため取り下げます。
### 実測データ:ソーシャル引用の主役はYouTubeとRedditで、TikTokは脇役
Wellowsが2026年1〜2月にChatGPT・Gemini・Perplexity・AI Overviews・AI Modeの引用35万件超を分析したレポートでは、ソーシャルメディア由来の引用の**過半をRedditが占め**、YouTubeが1月から2月にかけて55%増と急伸してこれに続きました。分析対象として個別に扱われたのはReddit・YouTube・LinkedIn・Quora・Facebook・Instagramの6つです。TikTokは主要ソースとして登場していません。同時期の別の集計では、Geminiがソーシャル系で引用するのはYouTube・Reddit・LinkedIn・TikTokの4つだけと報告されており、TikTokが「引用されうる」ことは確かですが、規模はごく小さいと見るべきです。
### 2026年8月:ChatGPTがソーシャル系引用を急減させた
さらに2026年8月中旬、ChatGPTの引用ソースが予告なく大きく変わりました。Petra Labsの計測では、ソーシャル系URLの引用が**YouTube 88%減、Reddit 81%減、TikTok 72%減**、LinkedIn 36%減、Facebook 28%減。Promptwatchの計測でも、Redditの引用シェアが7月18日〜8月7日の平均3.83%から8月14〜17日には0.52%へ落ちています。減った分はブランドの公式サイト、レビューサイト、ヘルプセンターやプロダクトドキュメントに移っており、OpenAIからの公式説明はありません。Promptwatchは、ChatGPTが内部検索で `site:` 指定を使う割合が8月8日以降に急増したことから「特定サイトへの罰則ではなく、検索の仕方の変更」と推測していますが、原因は確定していません。
ここから言えるのは、**AI引用をTikTok施策のKPIの主軸に置いてはいけない**ということです。AI側の一度の仕様変更で、積み上げた引用が7〜9割消えることが実際に起きました。
### 各AI検索面の2026年9月時点の状況
- **ChatGPT**: OpenAIは2025年4月に「週10億件のWeb検索」を公表。ただし上述のとおり2026年8月以降、ソーシャル系URLの引用は大幅に減少
- **Google AI Overviews**: 表示率は2026年7月時点でSimilarweb推計43%・Semrush推計48%(サードパーティ計測)。ソーシャル引用の過半はYouTubeで、TikTokの引用実績は限定的
- **Perplexity**: TikTokとの統合は未実現。ソーシャル引用の中心はReddit
- **TikTok内のAI要約**: TikTok自身も動画下にAI生成の概要を表示する実験を米国・フィリピンで行いましたが、誤った説明が相次いだため2026年5月に縮小し、動画内の商品提案に用途を絞りました。TikTok内でも「AIが動画を要約して答える」体験はまだ安定していません
### それでもAIに引用されるTikTok動画の共通点
引用例が少ないため確定的なことは言えませんが、引用されているTikTok動画には以下の傾向があります:
- **音声で明確に情報が語られている**(自動文字起こしで検索可能)
- **キャプションと字幕のキーワードが一致している**(テキストとして意味を取りやすい)
- **視聴完了率が高く、コメントでの質問・議論が活発**(UGCとしての信頼性)
これらはTikTok内検索での上位表示条件とほぼ重なるので、「TikTok内で検索される動画を作る」ことがそのまま、AI引用の可能性を上げる最善手になります。逆に、AI引用だけを狙った施策は割に合いません。生成AI検索がSEOをどう変えるかについては「[生成AI検索がSEOを変える:7つの実践対策](/blog/ai-search-seo-japan-2026/)」で詳しく扱っています。
> 参考・引用:
> [Rebuilding TikTok in America - Perplexity(2025年3月)](https://www.perplexity.ai/hub/blog/rebuilding-tiktok-in-america)
> [Perplexity submits a new bid for TikTok - TechCrunch(2025年1月)](https://techcrunch.com/2025/01/26/perplexity-submits-a-new-bid-for-tiktok/)
> [Social Media in AI Citations (2026): Reddit & YouTube Dominate - Wellows](https://wellows.com/blog/social-media-ai-citations-report-2026/)
> [ChatGPT slashes citations from Reddit, YouTube, and TikTok: Petra Labs - Adgully(2026年8月)](https://www.adgully.com/post/19605/chatgpt-slashes-citations-from-reddit-youtube-and-tiktok-petra-labs)
> [Why Did ChatGPT Stop Citing Reddit? - Promptwatch(2026年8月)](https://promptwatch.com/blog/chatgpt-stop-citing-reddit)
> [OpenAI introduces shopping to ChatGPT with 1 billion weekly searches - PPC Land(2025年4月)](https://ppc.land/openai-introduces-shopping-to-chatgpt-with-1-billion-weekly-searches/)
> [TikTok rows back AI video descriptions in US after absurd errors - AOL(2026年5月)](https://www.aol.com/articles/tiktok-rows-back-ai-video-092047214.html)
---
## 5. エンゲージメント率5.3%を超える3つの戦略

Threadpostが引用したSendibleの2025年調査では、TikTokの業界平均エンゲージメント率は**5.3%**とされています。ただし、エンゲージメント率は「何で割るか」で数字が大きく変わる点に注意してください。Socialinsiderの2026年ベンチマーク(200万本・214,507プロフィール、2024年1月〜2025年12月)は**視聴数基準**(エンゲージメント数÷視聴数)で集計されており、2025年平均は**4.2%**(2024年の3.85%から+9%)。四半期で見ると2025年Q1から2026年Q1まで4.2〜4.3%で横ばいのあと、**2026年Q2に3.85%へ8%低下**しました。フォロワー帯別(同じく視聴数基準)では1〜5Kが4.4%、10〜50Kが3.9%、100K〜1Mが3.95%です。一方、Sendibleの5.3%は分母が明示されていないため、Socialinsiderの数字と直接比較はできません。
自社の数字を評価するときは、まず同じ分母で比べること。そのうえで、Threadpostがまとめた実践戦略を私なりに再構成したのが以下です。
### 戦略1: フック設計に最大投資する
動画制作の工数の**30〜40%**は最初の3秒に投じるべきです。本編の台本が長いほど、冒頭のフックが弱くなりがち。私が企画レビューで最初に見るのは、サムネイルと1秒目に何が映っているかです。
### 戦略2: TikTok SEOを徹底する
セクション3で解説した5ステップを全動画に適用する。特にキャプションとテロップの両方にキーワードを配置する「二重配置」はやっていない競合が多く、差別化ポイントになります。
### 戦略3: エデュテイメントを軸に据える
単なる広告・宣伝動画は、アルゴリズムの「興味なし」シグナルを集めやすい傾向があります。Chaptertwoの2026年1月調査でも、**教育×エンタメの融合(エデュテイメント)**が伸びている動画の共通パターンでした。
LinkSurgeの機能紹介をTikTokでやるとして、単に「こんな機能があります」と説明するより、「**Google AI Overviewsに引用されるための3つの条件**」のような実用価値ある情報として提供するほうが拡散されやすいということです。
### KPIと測定フレーム
| KPI | 初心者ライン | 中級者ライン | 上級者ライン |
|:---|:---|:---|:---|
| 完了率 | 25%以上 | 40%以上 | 60%以上 |
| エンゲージメント率 | 2%以上 | 5%以上 | 8%以上 |
| シェア/再視聴比率 | 0.5%以上 | 2%以上 | 5%以上 |
| 投稿頻度 | 週3回 | 週5回〜1日1回 | 1日2〜4回 |
数字はAndthenとShubihiroの2026年レポートの中央値を参考に、私が実務で使っている内訳です。エンゲージメント率の行は実務上の目安で、Socialinsiderの視聴数基準ベンチマーク(2025年平均4.2%)と比べるなら、中級者ラインの5%は「業界平均をやや上回る水準」と読んでください。
TikTokで見つけた商品を、Z世代がその後どう確かめて買うのか。楽天の2026年9月調査を軸に「[Z世代の54%が買う前にAIに聞く。それでも信頼するのは検索エンジン](/blog/gen-z-ai-shopping-search-trust-2026/)」で、AIによる絞り込みと検索での裏取りという購買の流れを整理しています。
> 参考・引用:
> [2026 TikTok Benchmarks - Socialinsider(2026年4月)](https://www.socialinsider.io/social-media-benchmarks/tiktok)
> [エンゲージメント率5.3%超え!TikTokSEOを制する3つの戦略 - Threadpost](https://www.threadpost.jp/blog/how-to-get-more-views-on-tiktok)
> [【2025年最新】TikTokの伸ばし方 - Boosttech](https://media.boosttech.jp/shorts/tiktokgrowth/)
> [【2026年最新】TikTokの最新アルゴリズムはどう変わった - Chaptertwo](https://chaptertwo.co.jp/media/tiktok-algorithm/)
> [【2025年最新】TikTokの伸ばし方 200再生の壁 - Traum](https://traum-live.com/blog/tiktok-growth-strategy-200-views-2025/)
> [15 SEO and AI Predictions for 2026 - Digital Web Solutions](https://www.digitalwebsolutions.com/blog/googles-serp-is-over-seo-ai-predictions-for-2026/)
---
## 6. 効果測定とKPI設計 — Google検索と並走させる
TikTok SEOの効果測定を「TikTok内のKPI」だけで完結させると、全体像を見誤ります。2026年の検索はマルチプラットフォームで進むからです。
### 3層の測定フレーム
1. **TikTok内指標**: 完了率、シェア率、再視聴率、プロフィール訪問数、フォロー転換率
2. **Google検索への波及**: TikTok動画がGoogle SERPに引用される回数、関連KWでのブランド検索数推移
3. **AI検索での引用**: ChatGPT/Perplexity/AI OverviewsでのTikTok URL引用回数
3層目の測定は手作業では難しく、専用ツールが必要になります。LinkSurgeのGEOモニターでは、指定ブランド・URLがどのAI検索サーフェスでどの頻度で引用されているかを追跡できるため、TikTok施策のAI検索への波及も可視化できます。ただしセクション4で見たとおり、AI側の引用方針は2026年8月のように予告なく変わります。3層目は「伸ばすKPI」ではなく「変化を検知するモニタリング指標」として扱い、1層目・2層目で成果を判断してください。
### 週次レビューで確認すべき5指標
毎週決まった曜日に、以下を定点観測するといいです:
1. 過去7日の投稿別エンゲージメント率(上位3本と下位3本の差分を分析)
2. 完了率の推移(下がっていれば冒頭フックを見直す)
3. ハッシュタグ別のリーチ(効果の薄いタグを入れ替える)
4. Search Insightsの新規トレンドKW
5. ブランド検索ボリュームの変化(Google Search Console / Trends)
---
## よくある質問(FAQ)
### TikTok SEOはGoogle SEOの代わりになりますか?
いいえ、代わりというより「並走させる」ものです。Adobeの2026年調査でも、Z世代の65%がTikTokで検索した経験を持つ一方、GoogleよりTikTokに頼ると答えたのは4%にとどまり、89%はGoogleを最も好むと回答しています。2026年の検索はGoogle・TikTok・YouTube・Amazon・AI検索エンジンと分散しているため、どれか1つに依存するのはリスク。私の推奨は、既存のGoogle SEO戦略を維持しつつ、Z世代ターゲットや動画で伝えやすいテーマから段階的にTikTokを追加する形です。YouTube側の動画SEO戦略(OtterlyAI調査でAI引用の94.3%がLong-formと判明)は「[YouTube動画SEO × AI検索引用戦略](/blog/youtube-shorts-ai-search-seo-2026/)」で詳しく扱っています。
### 投稿頻度はどれくらい必要ですか?
1日1〜4回が推奨範囲で、最低でも週3回以上は維持したいです。ただし頻度を上げるために品質を落とすのは逆効果。完了率が下がればアルゴリズム評価も下がるため、「品質を落とさず増やせる頻度」が正解です。
### ハッシュタグは多いほどいいですか?
いいえ、3〜5個が最適です。10個以上はスパム判定のリスクがあり、逆に可視性を下げる可能性があります。ビッグ・スモール・オリジナルの3タイプを混ぜる戦略が実務的です。
### 動画の長さは短いほうが有利ですか?
15〜60秒が最適レンジで、短すぎても長すぎても完了率を上げにくくなります。30秒前後がスイートスポットという声が多く、例外はレシピやチュートリアルのような「保存される」動画で、60秒以上でも評価されます。
### TikTokの動画がChatGPTやPerplexityに引用される条件は?
明確な正解はまだ確立されていませんが、観測している範囲では「音声で情報が明示的に語られている」「キャプションと字幕にキーワードが一貫している」「視聴完了率とコメントエンゲージメントが高い」動画が引用されやすい傾向があります。ただし、AI回答でのソーシャル引用はYouTubeとRedditが大半で、TikTokはごく少数です。2026年8月にはChatGPTのTikTok引用が72%減った(Petra Labs)ように、AI側の仕様変更で大きく変動するため、AI引用を主目的にしたTikTok施策はおすすめしません。
### 動画に付く検索キーワードは自分で設定できますか?
2026年4月から、TikTokが人気の検索に基づいて動画に自動付与するキーワードを、クリエイター側で確認・除外・提案できるようになりました。ただし最終的な採否はTikTokが判断するため、無関係な語を詰め込むことはできません。まず既存の主要動画に付いているキーワードを確認し、狙っている語とずれていないかを棚卸しするのが第一歩です。日本での提供状況はアカウント上で確認してください。
---
## まとめ:TikTokをGoogleの隣に置く
2026年のマーケターにとって、TikTokは「SNSの一つ」ではなく「**Googleと並走する検索エンジン**」として位置づけ直すべき存在です。Z世代の65%が検索した経験を持つ場所であり、同時に、89%がGoogleを最も好むと答えている以上、Googleの代替ではありません。AI検索での引用は現時点では小さく変動も大きいため、TikTok施策の成果はまずTikTok内の検索・発見と、ブランド検索への波及で測るのが現実的です。
本記事で紹介した5ステップ実装と3戦略は、Adobe・Socialinsider・TikTok公式発表・国内の実務メディア等の2025〜2026年データに基づいています。ぜひ明日からの運用に組み込んで、TikTok経由の新しい流入を積み上げていきましょう。
LinkSurgeの[GEOモニター機能](https://linksurge.jp/geo/mentions)では、ChatGPT・Perplexity・Google AI Overviewsでの自社ブランド引用を継続追跡できます。2026年8月のような引用方針の変化を早期に検知したい方はぜひ活用してみてください。
---
## UGC × AI検索引用戦略:Reddit・Yahoo!知恵袋・レビューがAI回答を左右する時代 2026年版
> URL: https://linksurge.jp/blog/ugc-ai-search-brand-mentions-2026/
> Date: 2026-04-17 | Category: SNS | Author: 緒方亜朗
> Tags: UGC戦略, AI検索最適化, ブランドメンション, Reddit, Yahoo!知恵袋, AEO, 口コミマーケティング
## この記事の結論:AI検索時代のUGC戦略 5つの重要事実
AI検索の「情報源」を調べて、私が率直に驚いたのがAhrefsの2025年日本市場調査でした。ChatGPTが日本のユーザーからの質問に回答する際、**最も引用しているのはReddit(22.8万回)**で、Google AIモードに至っては**Yahoo!知恵袋を51.8万回引用**——他のAIエンジンの2〜5倍という圧倒的な数字です。つまりAIは、自社サイトやニュースメディアではなく、**一般ユーザーが書いたUGC(ユーザー生成コンテンツ)を主食**にしているわけです。ただしこの構図は固定的ではなく、2026年8月にChatGPTでのReddit引用が急落するという大きな変化が起きています(詳細は下記)。私がこの調査と英語圏の最新研究を突き合わせて見えてきた要点は以下の5つです。
> **【2026年8月更新】Redditの引用状況が大きく変わりました。**
> [Search Engine Landの報道](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473)(Promptwatchのデータ)によると、ChatGPT SearchにおけるRedditの引用シェアは**2026年7月18日〜8月7日の平均3.83%から、8月14〜17日の平均0.52%へ、4日間で86.4%低下**しました。
> 一方でGoogle側は緩やかで、AI Overviewsは7月初頭の約2.5%から8月に約2.1%へ、AI Modeも同様の緩やかな低下にとどまっています。
> **原因は確定していません。** Promptwatch自身が「いつ起きたかは示せるが、なぜかは説明できない」「データ収集側の問題も否定できない」と明言しています。Redditがrobots.txtでクローラーを全面ブロックしたためとする解説もありますが、これは各社の推測であり、当社では確認できていません(Redditは当社からのrobots.txt取得自体をブロックしています)。
> **本記事の以下のデータは2025年5〜9月時点のものです。とくにChatGPTに関する記述は、現在そのまま当てはまらない可能性が高い点にご留意ください。**
1. **UGCはAI検索の主食** — Ahrefs日本市場データ(2025年5〜9月)でChatGPTの1位がReddit、AIモードはYahoo!知恵袋が圧倒的1位だった。ただし2026年8月にChatGPT SearchでのReddit引用が4日間で86.4%低下しており、**特定プラットフォームへの依存はそれ自体がリスク**である
2. **各AIエンジンでUGC嗜好が明確に異なる** — Perplexityは動画(YouTube)、Copilotは百科事典系(Wikipedia)、Google AIモードはYahoo!知恵袋に極端に偏る。ChatGPTは2025年時点でReddit偏重だったが2026年8月に急変した。この変動の大きさこそが、プラットフォーム横断の戦略を必要とする理由である
3. **UGCエコシステムは言語圏で全く異なる** — 英語圏はReddit・YouTube・Quora中心、日本語圏はYahoo!知恵袋・note・Amebloが中心。日本展開では日本語UGCへの注力が必須
4. **ブランドは「UGCを作る」のではなく「促進する」** — 自作UGCはスパム判定されやすい。コミュニティ形成、レビュー誘導、専門家Q&A回答、アンバサダー、UGCテンプレート配布という5つの戦術で、オーガニックなUGCが生まれる仕組みを作る
5. **UGC起点のブランドメンションは3層で追跡する** — プラットフォーム内メンション数、AI検索での引用回数、ブランド検索ボリューム推移の3層で効果を可視化する
以下では、これらを掘り下げていきます。要点を動画でも解説しています。
{{youtube:Ei9QXoEeMyk|UGC × AI検索引用戦略:Reddit・Yahoo!知恵袋・レビューがAI回答を左右する時代}}
---
## 1. AI検索がUGCを引用する仕組みとRAG

AI検索がUGCを大量に引用する背景には、技術的な理由があります。ChatGPT・Perplexity・Google AIモード・Copilotは、いずれも**RAG(Retrieval-Augmented Generation:検索拡張生成)**技術を使っており、回答生成前にリアルタイムでWebを検索して情報を取得します。Ahrefsの分析によると、AIは情報源を「**信頼性・正確性・鮮度・ユーザーエンゲージメント**」の4軸で評価し、引用優先度を決定しているとのことです。
### 各AIエンジン別 日本市場の引用ドメインTop3
Ahrefsが2025年5〜9月に実施した日本市場調査(Brand Radarによる引用ドメイン分析)の結果を一覧化すると、以下のようになります。**調査時点の数値であり、とくにChatGPTのRedditについては上記の急落を踏まえて読んでください。**
| AIエンジン | 1位 | 2位 | 3位 |
|:---|:---|:---|:---|
| **ChatGPT** | Reddit(228,388回) | Wikipedia英語版(166,445) | Ameblo(131,629) |
| **Perplexity** | YouTube(91,954) | Google.com(35,191) | Wikipedia日本語版(33,006) |
| **Copilot** | Wikipedia日本語版(125,842) | Bing.com(93,300) | note(65,023) |
| **Google AIモード** | Yahoo!知恵袋(**518,977**) | YouTube(276,702) | Wikipedia日本語版(252,313) |
### 突出したYahoo!知恵袋の引用量
Google AIモードにおける**Yahoo!知恵袋の引用数51.8万回**は、他のAIエンジンの引用ドメイン1位と比較しても2〜5倍の規模です。これは偶然ではなく、Googleが「日本語のユーザー質問に対する答え」として知恵袋の膨大なQ&Aアーカイブを最重要視していることを示しています。
考えてみれば当然で、知恵袋には**数億件の自然言語Q&Aペアが蓄積**されています。RAGで「ユーザーの質問に近い過去質問とその回答」を引き出すには、これ以上ない形式のデータセットなわけです。
### Redditが英語圏で優位な理由
英語圏では長らくRedditが同様のポジションを占めてきました。Search Engine Landの2026年調査によれば、AI検索エンジンが最も引用するソーシャルプラットフォームは**Reddit・YouTube・LinkedIn**です。
また別途xSeekは、RedditのAI Overviews引用が1四半期で4.5倍に増えたと報告しています。
しかしこの優位は2026年に入って揺らいでいます。[Conductorの調査](https://www.conductor.com/academy/reddit-ai-citation-decline/)ではRedditの引用シェアが2025年10月の2.02%から2026年1月には1.01%へ低下し、さらに2026年8月にはChatGPT Searchで前述の急落が起きました。**「Redditに書けばAIに拾われる」という前提は、少なくともChatGPTについては現在成立しません。**
Reddit・YouTubeの動向は姉妹記事「[YouTube動画SEO × AI検索引用戦略](/blog/youtube-shorts-ai-search-seo-2026/)」で深掘りしていますが、2026年にYouTubeがRedditを抜いて「AI引用される#1ソーシャルプラットフォーム」になった現象も注目に値します。
> 参考・引用:
> [Ahrefs、日本国内におけるAI検索エンジンの引用分析 - Valuesccg Manamina](https://manamina.valuesccg.com/articles/4596)
> [AI検索が引用する情報源トップ10を徹底比較 - Ahrefs](https://ahrefs.com/blog/ja/brand-radar-top-10-cited-domains/)
> [AI search engines cite Reddit, YouTube, and LinkedIn most - Search Engine Land](https://searchengineland.com/ai-search-engines-cite-reddit-youtube-and-linkedin-most-study-473138)
> [Reddit's 4.5x AI Overview Surge - xseek](https://www.xseek.io/blogs/articles/reddit-ai-overview-citation-strategy)
> [Reddit's ChatGPT Search citations fell 86% in four days - Search Engine Land](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473)
> [Reddit AI Citation Decline - Conductor](https://www.conductor.com/academy/reddit-ai-citation-decline/)
---
## 2. 日米UGCエコシステムの根本的な違い

ここが日本市場で活動するブランドにとって極めて重要な論点です。**英語圏のUGC戦略をそのまま輸入しても日本では刺さらない**——UGCエコシステムが全く異なるからです。
### 英語圏と日本語圏のUGCプラットフォーム比較
| 観点 | 英語圏(米国中心) | 日本語圏 |
|:---|:---|:---|
| **Q&Aの主戦場** | Reddit / Quora / Stack Exchange | Yahoo!知恵袋 / OKWave |
| **レビュー主戦場** | Amazon / Yelp / Google | Amazon.co.jp / 価格.com / @cosme |
| **ブログUGC** | Medium / Substack | note / Ameblo / はてなブログ |
| **動画UGC** | YouTube / TikTok / Instagram | YouTube / TikTok / ニコニコ動画 |
| **商品SNS** | Reddit / Twitter / Instagram | X / Instagram / LINEオープンチャット |
### 日本市場での重点プラットフォーム
Ahrefsデータから導ける実務的な結論は以下です:
1. **Yahoo!知恵袋は最優先** — Google AIモードが圧倒的に重視しているため、カテゴリ別の専門回答を積み上げる価値が非常に高い
2. **noteはCopilot経由の流入に効く** — Copilotの引用3位にランクインしており、SEOとAEO(Answer Engine Optimization)の両面で強い
3. **Amebloはまだ有効** — ChatGPTの引用3位という事実は、ブログSEOが死んだわけではないことを示している
4. **Redditも無視しない** — ChatGPTの引用1位は日本市場でもRedditで、英語圏ソースも並行活用する
### 日本市場ブランドの典型的な失敗パターン
率直に言って、「日本のブランドがAI検索で引用されない」と嘆くケースの多くは、**日本語UGCへの投資不足**が原因だと思います。自社サイトのSEOだけに注力し、Yahoo!知恵袋・noteでのプレゼンス形成を軽視していると、Google AIモードから完全にスルーされる。これは本当によくある落とし穴です。
SNS全般のAI検索最適化については「[X・Instagram・LinkedInのAI検索最適化](/blog/sns-ai-search-optimization-2026/)」でも扱っていますが、UGCは「SNS投稿」より一段深い、ユーザー主導コンテンツの総称として捉えると戦略設計しやすくなります。
> 参考・引用:
> [Reddit and YouTube in AI Search: Why UGC Is the #1 Cited Source - Salespeak](https://salespeak.ai/aeo-news/reddit-ugc-ai-search)
> [【Ahrefs調査】6ヶ月で変動したAIの情報源 - PR TIMES](https://prtimes.jp/main/html/rd/p/000000044.000157671.html)
> [ChatGPTとPerplexity Answersでブランドを言及または引用されるために - ZICY](https://www.zicy.com/ja/blog/get-brand-mentioned-in-chatgpt-perplexity)
---
## 3. AIに引用されるUGCの4条件

AIが「どのUGCを引用するか」を決める基準はAhrefsの分析により4軸に整理できます。これを理解しておくと、次セクションのUGC促進戦術が生きます。
### 4つの評価軸
1. **信頼性**: コミュニティ評価・エンゲージメントの高さ。Redditのアップボート、知恵袋のベストアンサー、Quoraの「アップヴォート」がそのまま信頼シグナルになる
2. **検索インデックス性(RAG可能性)**: Q&A形式やレビュー形式のように、質問と回答が構造化されているUGCは、RAGで抽出しやすく引用されやすい
3. **鮮度**: 過去数ヶ月以内の新しい議論が優先される。数年前の古い投稿は鮮度スコアで下がる
4. **エンゲージメント**: コメント数・共有数・リアクションの量。活発な議論が起きているUGCは「重要」とAIに認識される
### 引用されやすい投稿の型
Fuelonlineの2026年Reddit SEO分析から、AIに引用されやすいRedditポストの典型例:
- **質問形式のタイトル**: "How do you actually use X for Y?" 形式
- **詳細な回答本文**: 200〜500ワードの具体的な体験談
- **具体的な数値・事実**: 「3ヶ月使って売上が28%増えた」のような定量情報
- **コメント欄での議論**: 元投稿+コメント群が1つの「回答セット」として機能
### 日本語UGCでの応用
Yahoo!知恵袋の場合、同じ4条件が適用できます:
- **タイトルが自然言語の質問形式**: 「XXの使い方を教えてください」など、実際のユーザー検索クエリに近い
- **ベストアンサーが具体的**: 手順・数値・リンクを含む200ワード以上の回答
- **鮮度**: 数ヶ月〜1年以内の質問・回答
- **コミュニティエンゲージメント**: 「役に立った」評価・コメント数
> 参考・引用:
> [9 Proven Reddit AI SEO Plays [2026 Guide] - ReddiReach](https://www.reddireach.com/blog/reddit-ai-search-optimization-2026-the-definitive-playbook-to-earn-mentions-in-ai-answers-rank-in-google)
> [Mastering Reddit SEO Strategy For UGC Success In 2026 - Fuelonline](https://fuelonline.com/seo/reddit-seo-strategy-how-ugc-content-dominates-ai-search-in-2026/)
> [Reddit's Rise in AI Citations - CMS Wire](https://www.cmswire.com/digital-marketing/reddits-rise-in-ai-citations-what-marketers-must-know-about-aeo-strategy/)
---
{{linksurge-card}}
---
## 4. ブランドがUGCを促進する5戦術

ここが最も誤解されるポイントです。「UGCを作ろう」として社内でフェイクレビューや自演投稿を量産するのは、完全にアンチパターンです。AIも各プラットフォームも、スパム判定の精度を年々上げています。
ブランドがやるべきは**「UGCを作る」ではなく「UGCが自然発生する仕組みを作る」**こと。以下の5つの戦術が実務で効きます。
### 戦術1: 自社コミュニティを形成する
Reddit、Discord、自社フォーラム、LINEオープンチャット等で、ユーザーが自発的に議論する場を作る。
- **サブレディットを運営する** — 自社ブランド名や関連テーマのサブレディットを公式運営
- **Discord/LINEオープンチャット** — クローズドな議論の場を提供
- **自社フォーラム** — SaaS系ブランドに特に有効
ポイントは「運営はするが、投稿は強制しない」こと。自発的な議論が発生する環境を整えることに注力します。
### 戦術2: レビュー収集を仕組み化する
購入後メール、アプリ内プロンプト、特典付きレビュー依頼等で、**ユーザーが自発的にレビューを書く導線**を作る。
- **購入後フォロー**: 2週間後に「使ってみた感想を教えてください」メール
- **Amazon/価格.com/@cosmeへの誘導**: 自社レビュー欄より第三者プラットフォーム優先
- **インセンティブ設計**: 無償サンプル・クーポンと引き換えに「忖度なしレビュー」を依頼
### 戦術3: 専門家としてQ&Aに回答する
社員を「専門家」として知恵袋・Quora・Redditで質問に回答させる仕組みを作る。
| プラットフォーム | 戦術 |
|:---|:---|
| **Yahoo!知恵袋** | カテゴリマスター制度の活用、社員の継続回答 |
| **Quora** | Topic Expert認定を取る、長文回答を継続投稿 |
| **Reddit** | AMA(Ask Me Anything)形式、サブレディットモデレーター |
ここで重要なのは「**自社製品の宣伝でなく、純粋に役立つ回答をする**」姿勢。AIも人も、宣伝臭を感じた瞬間に評価を下げます。
### 戦術4: アンバサダープログラムを運営する
パワーユーザーに特典を提供し、自発的なSNS投稿・ブログ記事・動画制作を促す。
yutoriの事例(「[yutoriのSNSブランド戦略を徹底解剖](/blog/yutori-sns-brand-strategy-2026/)」で詳述)が典型で、スタッフ自身がブランドアンバサダーとして日常動画を投稿し、それがTikTok・Reels経由でAI検索に引用される好循環を生んでいます。
### 戦術5: UGC作成テンプレートを提供する
ハッシュタグ、写真フレーム、シェアカード、リミックス用素材等、**ユーザーがUGCを作りやすい素材**を配布する。
- **公式ハッシュタグ**: TikTokで10億回再生されるブランド独自タグ
- **フォトフレーム**: Instagramのストーリーで使える素材
- **レビューテンプレート**: 「5つの観点で書くと書きやすい」フレーム提供
ユーザーが「作りたいけど何を書けばいいか分からない」という心理的ハードルを下げるのが本質です。
ChatGPTに限った日本語の媒体戦略(PR TIMES・note・Yahoo!知恵袋の使い分けと、引用されるプレスリリースの条件)は「[PR TIMES・note・Yahoo!知恵袋をChatGPT引用に使う方法](/blog/chatgpt-press-release-note-ugc-2026/)」で扱っています。
UGCがAIの商品推薦でどの程度引用されているかは、Azomaの引用分析で示されています。楽天の2026年9月調査とAzomaの引用分析を突き合わせた「[Z世代の54%が買う前にAIに聞く。それでも信頼するのは検索エンジン](/blog/gen-z-ai-shopping-search-trust-2026/)」では、ChatGPTのショッピング引用のうちUGCが19%、ブランド公式サイトは3%にとどまるというデータを紹介しています。
> 参考・引用:
> [Reddit's Rise in AI Citations - CMS Wire](https://www.cmswire.com/digital-marketing/reddits-rise-in-ai-citations-what-marketers-must-know-about-aeo-strategy/)
> [2025年におけるAIの可視性 - Yext](https://www.yext.com/ja/blog/2025/10/ai-visibility-in-2025-how-gemini-chatgpt-perplexity-cite-brands)
> [9 Proven Reddit AI SEO Plays - ReddiReach](https://www.reddireach.com/blog/reddit-ai-search-optimization-2026-the-definitive-playbook-to-earn-mentions-in-ai-answers-rank-in-google)
---
## 5. UGC起点ブランドメンションの3層モニタリング

UGC戦術を打ったら、次は効果測定です。UGC起点のブランドメンションは**3層構造**で追跡すると全体像がつかめます。
### 3層モニタリングフレーム
| 層 | 測定対象 | 手段 |
|:---|:---|:---|
| **層1: プラットフォーム内メンション** | Reddit/知恵袋/note等での自社ブランド言及件数 | プラットフォーム検索、APIソーシャルリスニングツール |
| **層2: AI検索での引用回数** | ChatGPT/Perplexity/Google AIモードでの引用回数 | LinkSurge等の専用ツール |
| **層3: ブランド検索ボリューム推移** | 「ブランド名 + UGC文脈」のGoogle検索ボリューム | Google Search Console / Google Trends |
### 層1: プラットフォーム内メンション計測
Redditなら`site:reddit.com "ブランド名"`の検索、Yahoo!知恵袋なら公式検索で「ブランド名」を含む質問数を月次で追跡します。AIが引用するのはこれらのUGCなので、ここを増やすことが全ての起点です。
### 層2: AI検索での引用回数
これが最も測定しづらい層です。LinkSurgeのGEOモニターでは、指定ブランド・URLがChatGPT・Perplexity・Google AI Overviewsで何回引用されたかを日次で追跡できるため、UGC戦術の効果がAI検索にどう波及したかを可視化できます。
### 層3: ブランド検索ボリューム
UGCで自社を知ったユーザーは、次にGoogleで「ブランド名」や「ブランド名 + 関連キーワード」を検索する傾向があります。**Google Search Consoleでブランド検索のImpressionsとClicksを月次で追跡**すると、UGC施策の最終的な成果が確認できます。
### 月次レビューで確認する5項目
毎月の定点観測で以下を追跡します:
1. プラットフォーム別のブランドメンション数(Reddit、知恵袋、note、Amazon、価格.com)
2. AI検索別の引用回数(ChatGPT、Perplexity、AI Overviews、Gemini)
3. 引用されたコンテンツの質(ポジティブ/ニュートラル/ネガティブの比率)
4. ブランド検索ボリュームの月次推移
5. コンバージョン貢献(UGC経由の問い合わせ・購入の特定)
---
## 6. 実装チェックリストとKPI設計
UGC × AI検索戦略を実装する際の実務チェックリストをまとめます。
### 初月の立ち上げチェックリスト
- [ ] 対象プラットフォームの棚卸し(日英両方、Reddit/知恵袋/Quora/note/レビューサイト)
- [ ] 各プラットフォームでの自社ブランドメンション数のベースライン計測
- [ ] コミュニティ運営のリソース・責任者の確保
- [ ] 専門家Q&A回答担当者のアサイン
- [ ] レビュー収集の仕組み(購入後メール、アプリ内プロンプト)の設計
- [ ] LinkSurge等でAI引用モニタリングの初期設定
### KPI設計(3ヶ月後、6ヶ月後、12ヶ月後)
| 時期 | 主要KPI |
|:---|:---|
| **3ヶ月後** | プラットフォーム別メンション数が月次で10〜20%増 |
| **6ヶ月後** | AI検索での引用回数が初期比で2倍以上 |
| **12ヶ月後** | ブランド検索ボリュームが20%以上増加、UGC経由CV寄与が可視化される |
### よくある失敗パターンと回避法
1. **自演UGC投稿**: スパム判定・ブランド毀損リスク大。絶対に避ける
2. **英語UGCだけに注力**: 日本市場ではYahoo!知恵袋・noteが鍵。日本語UGCを軽視しない
3. **単発キャンペーン止まり**: UGC促進は継続投資。最低12ヶ月のロードマップを組む
4. **測定層の一貫性欠如**: 層1だけ見て「メンションが増えた」と喜ばず、層2・層3まで追跡する
---
## よくある質問(FAQ)
### UGCを自作するのはなぜダメなのですか?
フェイクレビュー・自演投稿は、各プラットフォームのスパム判定アルゴリズム、そしてAI検索エンジンの信頼性評価アルゴリズムの両方で検出されやすくなっています。検出されるとペナルティ(アカウント停止、検索ランキング低下、AI引用からの除外)を受け、ブランド毀損にもつながります。遠回りに見えても、オーガニックUGCを育てるほうが長期的には速い戦略です。
### Yahoo!知恵袋で自社製品について書くとスパムですか?
書き方次第です。明らかな宣伝や自演はNGですが、**社員が「カテゴリマスター」として専門分野のQ&Aに回答し、その中で自社製品について触れる**のは問題ありません。重要なのは「宣伝ではなく、質問者の役に立つ回答をする」姿勢です。
### 英語圏と日本、どちらのUGCを優先すべきですか?
ターゲット市場次第です。日本市場向けビジネスなら**Yahoo!知恵袋・note・Amebloを最優先**、グローバル展開ならRedditと英語圏Q&Aを優先。両方展開している場合は、リソース比率を市場規模に合わせて決めます。
### AI検索での引用回数はどう測定すればいいですか?
LinkSurgeのGEOモニターのような専用ツールが最も現実的です。手動でChatGPTやPerplexityに「ブランド名」を含むクエリを投げて引用を数える方法もありますが、継続的な追跡には向きません。
### UGC施策の効果が出るまでどれくらいかかりますか?
短くて3ヶ月、本格的な効果は6〜12ヶ月というのが実務感覚です。コミュニティ形成、レビュー蓄積、Q&A回答の継続は時間がかかりますが、一度仕組みができれば複利的に効いてきます。
---
## まとめ:UGCは「作る」ではなく「設計する」
2026年のAI検索マーケティングは、自社コンテンツの充実だけでは半分以下のゲームしか戦えません。Ahrefs調査が示す通り、AIは**Reddit・Yahoo!知恵袋・noteといったUGCを主食**としており、自社サイトだけで勝負するのはAI検索の引用機会を取りこぼすことを意味します。
本記事で紹介した5戦術(コミュニティ・レビュー・Q&A・アンバサダー・UGCテンプレート)は、すべて「ユーザーが自発的にUGCを生む仕組みを設計する」という共通思想で貫かれています。自作ではなく、促進。これが2026年のUGC戦略の本質だと私は考えています。
LinkSurgeの[ブランドメンション追跡機能](https://linksurge.jp/geo/mentions)では、ChatGPT・Perplexity・Google AIモードでの自社ブランド引用を日次で追跡できます。UGC施策の効果を定量的に測定したい方は、本記事のチェックリストと併用してみてください。
---
## YouTube動画SEO × AI検索引用戦略:Long-form 94.3%の衝撃と2026年版Shorts活用法
> URL: https://linksurge.jp/blog/youtube-shorts-ai-search-seo-2026/
> Date: 2026-04-17 | Category: SNS | Author: 緒方亜朗
> Tags: YouTube SEO, 動画マーケティング, AI検索最適化, Perplexity, Google AI Overviews, Shorts戦略, Long-form動画
## この記事の結論:YouTubeとAI引用の5つの重要事実
動画マーケティングの常識は、2026年に静かに書き換わりました。OtterlyAIが公開した1億件超のAI引用分析で、**AI検索エンジンが引用する動画の94.3%はLong-form、Shortsはわずか5.7%**だと判明したからです。私がこの研究と2026年1月のYouTube Shortsアルゴリズム更新を読み込んで見えてきた、実務上の要点は以下の5つです。
1. **YouTubeは2026年のAI検索で最も引用される動画ソース** — Ahrefsの2026年4月調査でも、AI Overviews外枠(Top 100外)で最も引用されるドメインはYouTube。Perplexityに至っては全YouTube AI引用の38.7%を占める
2. **AI引用の鍵は「視聴数」ではなく「構造」** — OtterlyAIの相関分析で、再生数・いいね・登録者数の相関はほぼゼロ(r=-0.03)。逆に**説明文の長さ**が最強の正の相関(r=0.31)。**40.83%のAI引用動画は1000再生未満**
3. **Long-formが主力、Shortsはリパーパスと発見用に分業** — Shortsは5.7%しか引用されないが、2026年1月のShorts専用SEOフィルター導入で「ソーシャル検索」上での発見価値は上がった。主力アセットはLong-form、切り出しクリップがShortsという二層モデルが合理的
4. **チャプターは「個別のリッチリザルト」として扱われる** — タイムスタンプ付きチャプターがAI Overviewsで独立引用されるため、1本の構造化動画が複数クエリで引用される「クエリファンアウト効果」を生む
5. **2026年1月Shortsアルゴリズム更新で「Viewed vs Swiped Away」が新KPIに** — 完了率・リプレイ率・スワイプアウェイ率が主要シグナル化。Geminiが動画の意味を解析するため、音声や画面テキストの質も評価対象になった
以下で、これらを順に掘り下げていきます。要点を動画でも解説しています。
{{youtube:rv5G9EhC_LM|YouTube動画SEO × AI検索引用戦略|Long-form 94.3%とShortsの正しい使い分け}}
---
## 1. YouTubeがAI検索の「引用王」になった理由

率直に言って、2026年に入ってからのAI検索引用先の地殻変動は想像以上です。Ahrefsが2026年4月に公開したBrand Radar調査の「AI引用ドメインTop 10」では、YouTubeがAI Overviews外枠(オーガニックTop 100外)で**最も引用されるドメイン**としてランクインしました。半年前のChatGPT引用ソース分析ではRedditが上位でしたが、2026年に入りYouTubeに抜かれています。
### OtterlyAIの1億引用分析が示す事実
OtterlyAIが2026年3月に発表した、100M+(1億件超)のAI引用を対象とした大規模研究から見えた事実:
| 項目 | 数値 |
|:---|:---|
| YouTubeがAI検索で引用される動画の割合 | **94.3%がLong-form** |
| Shortsが占める引用比率 | わずか5.7% |
| Perplexity経由のYouTube AI引用 | **38.7%**(プラットフォーム別最多) |
| AI引用動画で1000再生未満の割合 | **40.83%** |
| 説明文の長さとの相関 | **r = 0.31**(最強の正相関) |
| 登録者数との相関 | r = -0.03(ほぼゼロ) |
衝撃的なのは**再生数や登録者数がAI引用とほぼ無関係**なこと。AIは「人気な動画」ではなく「**AIがパースしやすい構造化された動画**」を引用しているわけです。
### なぜAIはYouTubeを好むのか
Radyantの解説によれば、AI検索がYouTubeを好む理由は3つに整理できます:
1. **自動文字起こしが高精度** — Googleの音声認識がデフォルトで動画内容をテキスト化するため、LLMがコンテキストを抽出しやすい
2. **チャプター(タイムスタンプ)が個別リッチリザルト化** — 1本の動画が複数の独立した「回答候補」として扱われる
3. **詳細な説明文**がメタデータとしてAIの理解を助ける
TikTokのアルゴリズムと動画SEOの関係は姉妹記事「[TikTok検索最適化の教科書:Z世代の40%が使う新検索エンジン](/blog/tiktok-seo-ai-search-2026/)」で掘り下げましたが、YouTubeはまた別の論理で動いています。TikTokが「短尺×完了率×シェア」で動くのに対し、YouTubeは「構造化×長尺×チャプター」でAIに選ばれているのが対照的です。なおテキストUGC(Reddit・Yahoo!知恵袋・note等)がAI検索引用に占める位置については「[UGC × AI検索引用戦略:Reddit・Yahoo!知恵袋・レビューがAI回答を左右する時代](/blog/ugc-ai-search-brand-mentions-2026/)」で詳しく扱っています。
> 参考・引用:
> [OtterlyAI Study: 94% of YouTube AI Citations Go to Long-Form - VEED.IO](https://www.veed.io/learn/otterly-ai-citation-research-2026)
> [YouTube now beats Reddit in AI citations - Radyant](https://radyant.io/guides/youtube-ai-search-visibility-citation-framework/)
> [AI 検索が引用するドメイン TOP 10【2026 年 4 月】 - Ahrefs](https://ahrefs.com/blog/ja/brand-radar-top-10-cited-domains-2026-update/)
> [Ahrefs 調査|6ヶ月で変動した AI の情報源 - PR TIMES](https://prtimes.jp/main/html/rd/p/000000044.000157671.html)
---
## 2. Long-form 94.3% vs Shorts 5.7% — AI引用の主戦場はどこか

ここが本記事で最も重要な論点です。AI検索経由のトラフィックを狙う場合、制作工数をShortsに注ぎ込むのは**効率が悪い**——OtterlyAIのデータから見れば、これはかなり明確な結論です。
### 数字で見るLong-formの優位
Long-form(5分以上の動画)が引用される**94.3%**というシェアは、単なる偏りではなく構造的な理由があります。
- **コンテキストの深さ**: LLMが「質問の答え」として引用するには、動画内で十分な説明が必要
- **チャプター構造**: 長尺動画ほど複数チャプターを持ちやすく、1本で複数クエリを取れる
- **詳細な説明文**: Long-formの動画は平均的に説明文も長い傾向があり、r=0.31の正相関を生む
Shortsの5.7%という数字は「Shortsが無価値」という意味ではなく、**AI引用という単一の観点ではLong-formが圧倒的に強い**ということです。
### ただしShortsに価値がないわけではない
Shortsの役割は2026年に明確に変わりました。VEED.IOのレポートが指摘するように:
- **ソーシャル検索での発見**: TikTok・Instagram Reelsと競合するソーシャル動画検索
- **Long-formからの切り出し**: 構造化した長尺動画の「ハイライト」として配信
- **ブランド露出の一次接点**: 多視聴(リーチ拡大)が目的のレイヤー
Shortsに注力しすぎて長尺動画を作らないと、AI引用の主要なアセットを逃すことになります。逆に、長尺動画を作っていてShortsを作っていないと、ソーシャル発見の機会を逃します。**両方を、異なる目的で作る**のが合理的ということです。
### 実務での配分提案
週単位の制作リソース配分として、私が実務で運用しているバランスは以下です:
| アセット | 制作時間比率 | 目的 |
|:---|:---|:---|
| Long-form(10〜20分) | 60〜70% | AI引用獲得・SEO権威形成 |
| Shorts(切り出し) | 20〜30% | ソーシャル発見・リパーパス |
| その他(コミュニティ投稿等) | 10% | ファンエンゲージメント |
「Long-form 1本 → Shorts 3〜5本にリパーパス」の運用が、最もROIが良い印象です。
> 参考・引用:
> [OtterlyAI Study: 94% of YouTube AI Citations Go to Long-Form - VEED.IO](https://www.veed.io/learn/otterly-ai-citation-research-2026)
> [YouTube AI Citations: Turn Videos Into Search Assets - UpGrowth](https://upgrowth.in/youtube-ai-search-citation-machine/)
> [First Large-Scale Study by OtterlyAI - Globenewswire](https://www.globenewswire.com/news-release/2026/03/02/3247558/0/en/First-Large-Scale-Study-by-AI-Search-Monitoring-Platform-OtterlyAI-Shows-YouTube-is-2-Social-Platform-for-AI-Citations.html)
---
## 3. AI引用を獲得する動画構造設計

「構造がすべて」という表現は大げさですが、OtterlyAIの数値を見る限り、**動画の構造化がAI引用獲得の最優先施策**です。具体的に何を整えるべきか、順に見ていきます。
### ステップ1: 説明文を「記事レベル」で書く
説明文の長さがr=0.31で最強の正相関を持つ——これは平凡な事実に聞こえますが、実務上のインパクトは大きいです。上位パフォーマンスチャンネルの説明文を見ると、最低でも**300〜500ワード**、場合によっては1000ワードを超える「記事レベル」の情報量を入れています。
Marketing Agentが2026年2月のガイドで推奨している説明文の構造は以下:
1. 動画の要約(100ワード程度)
2. チャプターのタイムスタンプ一覧
3. 詳細な見出し付きセクション(各100〜200ワード)
4. 関連リンク・参考資料
5. ハッシュタグ(3〜5個)
### ステップ2: タイムスタンプ付きチャプターを必ず入れる
これが2026年のYouTube SEOで最も見落とされている要素だと思います。Ahrefsの引用分析でも、**タイムスタンプ付きチャプターを持つ動画は複数のAI引用を獲得しやすい**傾向が明確に出ています。
理由はシンプルで、**Googleはチャプターを個別のリッチリザルト**として扱います。つまり、1本の動画が「クエリA」「クエリB」「クエリC」それぞれで独立した引用候補になる。これが「クエリファンアウト効果」です。
チャプター設計のベストプラクティス:
- 1チャプターは**2〜5分**に設定
- タイトルは**検索クエリ形式**(「XXとは?」「XXのやり方」など)
- 最低5チャプター以上
この「クエリファンアウト」の仕組み自体については「[クエリファンアウトとは?初心者向け解説](/blog/query-fan-out-guide-2026/)」でも詳しく扱っています。
### ステップ3: 字幕とキャプションを整える
音声は自動文字起こしされますが、**手動で字幕を修正する**とAIの理解精度が上がります。特に固有名詞・専門用語は誤認識されやすいため、ここの精度差が引用獲得に影響します。
### ステップ4: タイトルと最初の15秒で「回答」を明示
AI検索が引用するのは「質問への回答」です。タイトルには質問形式または回答形式のキーワードを含め、動画の冒頭15秒で結論を先に述べる構造が強い。起承転結で最後まで引っ張ると、AIが引用するべき箇所を特定しづらくなります。
### AI引用獲得動画の構造テンプレート
| 要素 | 推奨仕様 |
|:---|:---|
| 動画長 | 10〜20分 |
| 説明文 | 300〜1000ワード |
| チャプター | 5チャプター以上、各2〜5分 |
| 字幕 | 手動修正済み |
| タイトル | 質問形式または「〜する方法」 |
| 冒頭15秒 | 結論の先出し |
> 参考・引用:
> [YouTube AI Citations: Turn Videos Into Search Assets - UpGrowth](https://upgrowth.in/youtube-ai-search-citation-machine/)
> [Building A Search-First YouTube Content Strategy - Marketing Agent](https://marketingagent.blog/2026/02/16/building-a-search-first-youtube-content-strategy-seo-tips-for-2026/)
> [Video SEO Best Practices in 2026 - VdoCipher](https://www.vdocipher.com/blog/video-seo-best-practices/)
> [Why AI Search Prefers YouTube - Torro](https://torro.io/blog/why-ai-search-prefers-youtube)
---
{{linksurge-card}}
---
## 4. YouTube動画 → AI検索の引用経路

YouTubeからAI検索への流れは、プラットフォームごとに特性が大きく異なります。Perplexity・Google AI Overviews・ChatGPTで、それぞれ何が起きているかを整理します。
### Perplexity: YouTube引用の38.7%を占める
OtterlyAI調査では、YouTube AI引用の**38.7%がPerplexity経由**でした。Perplexityは複雑なリサーチ質問の78%で全主張に具体的ソースを紐付ける仕組みを持っており、YouTube動画が「引用される動画」として可視化される構造がもっとも明快なプラットフォームです。
Devoの2026年解説によれば、Perplexityに引用されるYouTube動画の共通点は:
- **チャプター構造が明確**
- **スピーカーが専門家**として位置づけられている(プロフィール・チャンネル説明文で権威性が示されている)
- **動画内で具体的な数値・事実**が語られている
### Google AI Overviews: チャプター単位の引用
Search Engine Landの2026年解説によると、Google AI OverviewsはYouTubeを**Top 100オーガニック外枠で最多引用されるドメイン**として扱っています。特筆すべきはチャプター単位の引用で、1本の動画の3チャプターがそれぞれ異なるクエリのAI Overviewsに引用されるケースが観測されています。
### ChatGPT: 動画要約と直接引用
ChatGPTの2026年UI/UXでは、YouTube URLを貼ると動画内容を要約する機能が強化されました。これにより、ChatGPTが「XXについて解説しているYouTube動画」として動画URLを引用するケースが増えています。
ChatGPTでYouTube動画を直接要約させる方法は日本語記事「[ChatGPTでYouTube動画を要約する方法](https://generative-ai.sejuku.net/blog/12860/)」でも紹介されている通り、ユーザー側からも積極的に使われているインテグレーションです。
### LinkSurgeでのモニタリング例
LinkSurgeのGEOモニターでは、指定URLがChatGPT・Perplexity・Google AI Overviewsでどの頻度で引用されているかを追跡できます。YouTube動画のURLを登録しておけば、動画コンテンツがAI検索にどう評価されているかを定量的に把握できるため、構造改善の効果検証に有用です。
> 参考・引用:
> [YouTube is no longer optional for SEO in the age of AI Overviews - Search Engine Land](https://searchengineland.com/youtube-seo-ai-overviews-467253)
> [Perplexity SEOとは?AI検索に引用されるための実践 - Devo](https://devo.jp/ai-seo/aiseo_perplexityseo/)
> [動画制作 生成AIとChatGPTとPerplexityの活用方法 - BuzzAIMedia](https://media.buzzconne.jp/video_chatgpt_perplexity/)
> [YouTube Is Now the Top AI Citation Engine - Ajkumar](https://ajkumar.com/strategy/youtube-citation-engine-strategy/)
---
## 5. Shorts × Long-form 最適分業モデル

ここからはShortsの新しい位置づけと、Long-formとの分業モデルを具体的に見ていきます。
### 2026年1月更新:Shortsアルゴリズムの変化
2026年1月にYouTubeが発表した主な変更点:
| 変更 | 内容 |
|:---|:---|
| **Shorts専用検索フィルター導入** | "Type"メニューに"Shorts"フィルターが追加され、ShortsもSEO要素になった |
| **「Viewed vs Swiped Away」が主要シグナルに** | 表示されて視聴されたか、スワイプで飛ばされたかが新KPI |
| **Geminiによる意味解析** | 動画のトーン・画面要素・意味をGeminiが解析。タグだけでは足りない |
| **完了率・リプレイ率の重み増** | 「最後まで見られたか」「繰り返し見られたか」が最優先 |
Shortsも従来以上に「検索」と「構造」が重要になったわけです。ただし、AI引用という観点では依然Long-formの94.3%優位は変わりません。
### 分業モデルの実装
私が実務で運用している分業モデルは以下です:
**1週間の制作サイクル例**:
1. **月曜**: リサーチ・構成設計(1〜2時間)
2. **火〜水曜**: Long-form 1本撮影・編集(10〜20分、10時間)
3. **木曜**: Long-formから3〜5本のShortsを切り出し・編集(3〜4時間)
4. **金曜**: 説明文・チャプター・タイトルの最終調整、投稿
5. **土〜日**: Shortsを日次投稿、Long-formのパフォーマンス観測
Long-formを「母」、Shortsを「子」として扱うと、1本の制作投資から複数のアセットが派生します。これが**制作工数あたりのROI**を最大化する考え方です。
### Shortsで意識すべき2026年1月以降の3ポイント
1. **最初の1秒で主題を明示**(Viewed vs Swiped Away対策)
2. **音声でキーワードを明確に語る**(Geminiの意味解析対策)
3. **Long-formへの誘導リンクを説明欄に必ず入れる**(アセット連携)
> 参考・引用:
> [YouTube Shorts Algorithm Update: January 2026 - Miraflow](https://miraflow.ai/blog/youtube-shorts-algorithm-update-january-2026)
> [How Does the YouTube Shorts Algorithm Work in 2026? - vidIQ](https://vidiq.com/blog/post/youtube-shorts-algorithm/)
> [YouTube Shorts Algorithm Explained 2026 - Metricool](https://metricool.com/youtube-shorts-algorithm/)
---
## 6. 実装チェックリストとKPI設計
2026年のYouTube動画戦略を実装・測定する際のチェックリストをまとめます。
### 動画公開前チェックリスト
- [ ] タイトルに質問形式または回答形式のキーワードが入っているか
- [ ] 動画長が10〜20分か(AI引用を狙う場合)
- [ ] 最初の15秒で結論を先出ししているか
- [ ] タイムスタンプ付きチャプターが5つ以上あるか
- [ ] 説明文が300ワード以上か
- [ ] 字幕(キャプション)が手動修正されているか
- [ ] 関連Long-formまたはShortsへのリンクが説明欄にあるか
### KPI三層構造
| 層 | 測定指標 |
|:---|:---|
| **YouTube内** | 平均視聴時間、視聴維持率、クリック率、チャプター別滞在時間 |
| **Google検索への波及** | YouTube動画のGoogle SERP露出、ブランド検索ボリューム推移 |
| **AI検索での引用** | ChatGPT/Perplexity/AI Overviewsでの動画URL引用回数 |
AI引用の測定は手動では現実的に不可能で、OtterlyAIやLinkSurgeのような専用ツールが必須です。
### 月次レビューのテンプレ
毎月1回の定点観測で、以下を確認します:
1. AI引用獲得本数の推移(全動画のうち何本がAI引用を得たか)
2. チャプター別の引用分布(クエリファンアウト効果の確認)
3. 説明文の長さと引用獲得率の相関(仮説検証)
4. Long-form vs Shortsの引用比率(目標94.3:5.7にどれだけ近づけるか)
5. ブランド検索ボリュームの変化(YouTube視聴→検索行動への波及)
---
## よくある質問(FAQ)
### AI引用を狙うなら、Long-formとShorts、どちらに注力すべきですか?
Long-formが優先度高です。OtterlyAIの研究でAI引用の94.3%がLong-formだったため、AI検索からの流入を増やしたいなら、まず構造化された10〜20分のLong-formを作ることに集中してください。Shortsはそのクリップとして運用するのが合理的です。
### 動画の視聴数が少なくてもAI引用されますか?
はい、再生数とAI引用の相関はほぼゼロ(r=-0.03)で、**40.83%のAI引用動画は1000再生未満**です。AIは人気度より構造を見ているため、小規模チャンネルでも十分競争できます。
### チャプターを付ける動画長の目安は?
5分以上から効果が出やすく、10〜20分のLong-formで5チャプター以上を目安にしてください。1チャプターは2〜5分程度に収め、タイトルは検索クエリ形式にすることが重要です。
### 2026年1月のShortsアルゴリズム変更で、対応すべきことは?
3点です。(1) 最初の1秒で主題を明示してスワイプアウェイを防ぐ、(2) 音声でキーワードを明確に語る(Geminiの意味解析対策)、(3) 説明欄にLong-formへの誘導リンクを入れて回遊を促す。
### PerplexityにYouTube動画を引用されやすくする方法は?
チャプター構造を整え、動画内で具体的な数値・事実を語り、チャンネル説明文でスピーカーの専門性を明示すること。Perplexityは全主張の78%にソースを紐付ける仕組みを持つため、「明確に引用できる主張」を動画で提供することが近道です。
---
## まとめ:動画SEOを「構造SEO」として設計し直す
2026年の動画マーケティングは、「作って投げる」から「構造化して引用されやすくする」への移行期にあります。OtterlyAIの1億件引用分析が示す通り、AI検索が選ぶのは再生数の多い動画ではなく、**説明文・チャプター・字幕で情報が明示的に構造化された動画**です。
Shortsは2026年1月の更新でSEO要素が正式に導入され、ソーシャル発見の重要な窓口になりました。同時に、AI引用の主戦場は依然としてLong-formであることも変わっていません。この2つを分業させる制作パイプラインを組めるかどうかが、2026年のYouTube戦略の分岐点です。
LinkSurgeの[GEOモニター機能](https://linksurge.jp/geo/mentions)では、自社コンテンツがChatGPT・Perplexity・Google AI Overviewsで引用された回数を追跡できます。YouTube動画のAI引用獲得施策を打つなら、効果検証のために併用してみてください。
---
## XMLサイトマップ戦略2026:セグメント化とクロール予算管理でインデックスを最大化
> URL: https://linksurge.jp/blog/xml-sitemap-strategy-2026/
> Date: 2026-04-16 | Category: SEO | Author: 緒方亜朗
> Tags: XMLサイトマップ, クロール予算, インデックス最適化, テクニカルSEO, サイトマップ戦略
## この記事の結論:サイトマップを「放置ファイル」から「クロールとインデックスを支える資産」に変える5つの要点
私がクライアントサイトのサイトマップを調査して見えてきたのは、ほとんどのサイトがサイトマップを「一度作って終わり」にしているという現実です。以下の5つが2026年に実践すべき要点です。
1. **セグメント化が必須** — 1つの巨大なsitemap.xmlではなく、コンテンツタイプ・ビジネス価値・更新頻度でサブサイトマップに分割する。50Kページのサイトで製品インデックス率が87%から98%に改善した事例がある
2. **クロール予算は有限のリソース** — Googleがサイトに割り当てるクロール予算は限られている。低価値ページをサイトマップに含めると、重要なページのクロールが後回しになる
3. **標準のURLメタデータで効くのは `` だけ** — 同じ `` 内の `` と `` はGoogle・Bingとも無視する。正確な最終更新日を維持することが最も効果的で、逆に毎回のビルドで全ページを更新すると信用を失う
4. **動的生成で常に最新状態を保つ** — 静的サイトマップはすぐに陳腐化する。CMS連携またはスクリプトで公開・削除・更新を自動反映させる
5. **画像・動画サイトマップで検索露出を拡大** — 2026年のビジュアル検索需要に対応するため、専用のimage-sitemap.xmlとvideo-sitemap.xmlを用意する
以下では、各戦略を具体的な実装方法とともに掘り下げていきます。要点を動画でも解説しています。
{{youtube:LRuUF78TJZk|【2026年版】XMLサイトマップ戦略|セグメント化・lastmod・クロール予算でインデックスを最大化}}
---
## 1. なぜ2015年のサイトマップ戦略は2026年に通用しないのか
率直に言って、「sitemap.xmlをSearch Consoleにアップロードして二度と触らない」という運用は、もう機能していません。
2015年当時、Googleのクロール予算は比較的余裕がありました。すべてのページを1つのサイトマップに詰め込んでも、Googlebotは律儀にクロールしてくれていた。しかし2026年の状況は根本的に異なります。
### サイトマップ放置が招く3つの問題
- **クロール予算の浪費**: 重複コンテンツ、古いURL、noindexページがサイトマップに残っていると、Googleは重要でないページにクロール予算を消費する
- **矛盾するシグナル**: noindexページをサイトマップに含めると、「インデックスしてほしい」と「インデックスするな」という矛盾したシグナルをGoogleに送ることになる
- **インデックス遅延**: 50,000件以上のURLを1つのファイルに詰め込むと、処理が遅くなり、新規ページの発見が遅れる
データを見ると、Eコマースサイトで1つの巨大サイトマップを使っていたクライアントは、製品ページのインデックス率がわずか87%でした。ページの13%がGoogleに無視されていたわけです。
> 参考・引用:
> [Build and Submit a Sitemap - Google Search Central](https://developers.google.com/search/docs/crawling-indexing/sitemaps/build-sitemap)
> [Crawl Budget Optimization: Complete Guide for 2026 - LinkGraph](https://www.linkgraph.com/blog/crawl-budget-optimization-2/)
> [Sitemap Best Practices: Everything You Need to Know - Respona](https://respona.com/blog/sitemap-best-practices/)
---
## 2. 戦略 #1:複数のセグメント化されたサイトマップ

ここが分水嶺です。1つのsitemap.xmlに全URLを詰め込む時代は終わりました。
### セグメント化の設計基準
| セグメント基準 | 分割例 | 優先度 |
|--------------|--------|--------|
| コンテンツタイプ | `sitemap-products.xml`, `sitemap-blog.xml` | 高 |
| ビジネス価値 | `sitemap-highmargin.xml`, `sitemap-clearance.xml` | 高 |
| 更新頻度 | `sitemap-frequent.xml`, `sitemap-rare.xml` | 中 |
| 言語・地域 | `sitemap-ja.xml`, `sitemap-en.xml` | 中 |
| アーカイブ | `sitemap-archive.xml`, `news-sitemap.xml` | 低 |
これらを `sitemap-index.xml` でまとめて管理します。各サブサイトマップは**10,000〜20,000 URL以内**に収めるのがベストプラクティスです。プロトコル上の上限は50,000URLですが、ファイルが軽いほど処理が速くなります。
### なぜセグメント化が効果的なのか
実際に試してみても、セグメント化の効果は明確です。50,000ページのEコマースサイトで実施した事例では:
- **Before**: 1つのサイトマップに全URL
- **After**: ページタイプ別に5つのセグメント化されたサイトマップ
60日後の結果:
- 製品ページのインデックス率:87% → **98%**
- 平均インデックス化時間:6日 → **1.4日**
- オーガニックトラフィック:**+156%**
同じページ数で、組織化を変えただけでこの差が出るのは、理にかなっています。ただし、これは `` タグを検索エンジンが読み取っているからではありません(後述の通りGoogleもBingもpriorityを無視します)。実際に効いているのは、ファイルが軽量になることで処理が安定すること、Search Consoleでセグメントごとのカバレッジ状況を切り分けて把握できるようになること、そしてセグメント化と同時に重複・noindex・古いURLの整理が進んだことだと考えられます。
技術SEO・コンテンツSEO・リンク構築の包括的な戦略については「[SEO対策完全ガイド](/blog/seo-guide-2026/)」もあわせてご覧ください。
> 参考・引用:
> [XML Sitemap Best Practices for SEO - BrightSEO Tools](https://brightseotools.com/post/xml-sitemap-best-practices-seo)
> [Protocol - sitemaps.org](https://www.sitemaps.org/protocol.html)
> [Crawl Budget: What Is It and Why It Matters - Briteskies](https://blog.briteskies.com/blog/crawl-budget-what-is-it-and-why-it-matters-for-your-site)
---
## 3. 戦略 #2:`` を正確に運用する
冒頭の要点でも触れた通り、標準の `` メタデータ(`` / `` / ``)のうち、Googleが実際に参照するのは `` だけです。裏を返せば、この一点にサイトマップ運用の投資対効果が集約されます。
なお、画像・動画サイトマップの拡張データはこれとは別枠で、Googleも利用します(第7節で扱います)。ここでの話はあくまで標準のURLメタデータに限った比較です。
### なぜ `` だけが効くのか
Googleは `` を再クロールのスケジューリングに使います。「このURLは前回のクロール以降に更新されている」という申告を受け取ることで、限られたクロール予算を更新のあったページに寄せられるからです。ページ数が多いサイトほど、この差はインデックスの鮮度に直結します。
ただし、これは**申告が信頼できる場合に限られます**。ここが実務での分かれ目です。
### 正しい `` の運用ルール
- **ISO 8601形式で記述する**: `2026-04-16` または `2026-04-16T09:00:00+09:00`
- **実質的な変更があったときだけ更新する**: Googleは本文・構造化データ・内部リンクの重要な変更を対象として挙げています。純粋な見た目の調整では更新しない一方、テンプレート変更であっても構造化データや内部リンクが変わるなら対象です
- **ページごとに個別の日付を持たせる**: 全ページが同じ日付になっている状態は、更新日を管理できていないサインです
### 最も多い失敗:ビルドのたびに全ページのlastmodが更新される
率直に言って、これが実務でいちばん頻繁に見る事故です。
静的サイトジェネレーターやCMSの設定によっては、デプロイのたびに全URLの `` が「今日」に書き換わります。サイトマップ生成時に `new Date()` をそのまま渡している実装が典型例です。内容を何も変えていないのに、毎日全ページが「更新されました」と申告している状態になります。
これが続くと、Googleは `` の申告そのものを信用しなくなります。**本当に更新したときに再クロールを呼び込めなくなる**ため、設定しないより悪い結果を招きかねません。
`` は「変更を検知して初めて更新する」設計にしてください。記事の公開日でも、ビルドの実行日でもなく、実際に本文へ手を入れた日付を持たせるのが正解です。
### 補足:`` と `` はどう扱うべきか
結論から言うと、**時間をかけて調整する価値はありません**。GoogleもBingも、公式にこの2つを無視すると明言しています。クロール優先度の参考にすると案内しているのは、Yandexなど一部のエンジンに限られます。
CMSやプラグインが自動で出力しているなら、そのまま残しておいて構いません。ただし全ページを一律 `1.0` にする設定だけは避けてください。Yandexにとっても社内のドキュメントとしても、「全部同じ重要度」は何も言っていないのと同じです。設定するなら、トップページを高め・法的ページやアーカイブを低めにする程度の粗い差で十分です。
### どのページに工数を割くかを決める
限られた運用工数をどこへ投じるかは、別途決める必要があります。以下のような重み付けでページの優先順位を機械的に出しておくと、判断が安定します。
**投資優先度 = (ページ権威 × 0.3) + (コンバージョン率 × 0.4) + (検索ボリューム × 0.3)**
各指標は事前に0〜1の範囲へ正規化したうえで掛け合わせてください。バックリンク数・コンバージョン率・検索ボリュームは単位も桁も違うため、尺度を揃えずに合算すると係数の意味がなくなります。
重要なのは、**これはXMLに書き込む値ではない**ということです。この計算で上位に来たページから順に、`` の精度を担保し、内部リンクを厚くし、コンテンツを更新していく — そういう工数配分の指標として使います。
> 参考・引用:
> [Build and Submit a Sitemap - Google Search Central](https://developers.google.com/search/docs/crawling-indexing/sitemaps/build-sitemap)
> [The Importance of Setting the "lastmod" Tag in Your Sitemap - Bing Webmaster Blog](https://blogs.bing.com/webmaster/february-2023/The-Importance-of-Setting-the-lastmod-Tag-in-Your-Sitemap)
> [Using the Sitemap file - Yandex Webmaster](https://yandex.com/support/webmaster/en/controlling-robot/sitemap.html)
> [XML Sitemaps: What They Are & Why They Matter - Search Engine Land](https://searchengineland.com/guide/xml-sitemaps)
---
## 4. 戦略 #3:動的サイトマップ生成でサイト状態をリアルタイム反映
静的なサイトマップは、作った瞬間から古くなり始めます。面白いのは、多くのサイトがCMSの自動生成機能に任せきりにしていて、削除済みページやリダイレクト先がサイトマップに残り続けていることです。
### 動的生成で実装すべき4つの自動化
1. **新規ページの自動追加**: コンテンツ公開時にサイトマップへ即座に反映
2. **削除・リダイレクトの自動除去**: ページ削除やリダイレクト設定時にサイトマップから自動削除
3. **`` の自動更新**: コンテンツの実質的な変更を検知して最終更新日を更新
4. **重要ページの更新検知を優先する**: Analytics データで価値の高いページを特定し、そのページの実質的な変更検知と `` 更新を確実に行う
### 実装アプローチ
Next.jsやWordPressのようなフレームワーク・CMSを使っている場合、サイトマップの動的生成は比較的シンプルです。
- **WordPress**: Yoast SEO、RankMath、AIOSEOがコンテンツ更新時に自動送信
- **Next.js**: `app/sitemap.ts` でビルド時に動的生成
- **カスタム**: Python/Node.jsスクリプトでDBからindexableなURLを抽出し、cron実行
[LinkSurge](https://linksurge.jp/)のようなSEO分析ツールでインデックス状況をモニタリングしながら、サイトマップの品質を維持することも重要です。
> 参考・引用:
> [XML Sitemaps: Structure, Implementation & SEO Best Practices](https://skilltrainingnepal.com/blogs/xml-sitemaps-structure-implementation-seo-optimization)
> [9 Best XML Sitemap Generator Tools - Yotpo](https://www.yotpo.com/blog/best-xml-sitemap-generator-tools/)
> [8 Crucial XML Sitemap Best Practices - TrySight](https://www.trysight.ai/blog/xml-sitemap-best-practices)
---
## 5. 戦略 #4:クロール予算の戦略的割り当て

Googleはサイトに対して有限のクロール予算を持っています。そしてこの予算配分は、サーバーヘルス、トラフィック、ページ速度、コンテンツの新鮮さによって変動します。
### サイトマップに含めるべきもの・除外すべきもの
**含めるべきページ:**
- ユニークで価値のあるコンテンツ
- コンバージョン可能性のあるページ
- 正規化されたcanonical URL
- ステータスコード200のページのみ
**除外すべきページ:**
- ページネーションされたページ(`rel=next/prev` で対応)
- フィルタリングされた商品ページ(パラメータURL)
- 重複コンテンツのバリエーション
- 薄いコンテンツのページ
- 管理者・ログインページ
- noindexが設定されたページ
### クロール予算の浪費を特定する方法
サーバーログ分析で、Googlebotが低価値ページに頻繁にアクセスしていないか確認しましょう。BotifyやScreaming Frogのログ解析機能が便利です。
クロール予算の浪費率(低価値URLのクロール割合)を**10%未満**に抑えることが目標です。あるエンタープライズサイトでは、サイトマップ精査とrobots.txt調整で低価値ページを除外した結果、インプレッション+79%、クリック+62%、SEO経由売上+$786kを3か月で達成しています。
> 参考・引用:
> [Crawl Budget Optimization for Enterprise Sites - ALM Corp](https://almcorp.com/blog/crawl-budget-optimization-enterprise-sites/)
> [5 Ways to Get Better Log File Insights - Search Engine Journal](https://www.searchenginejournal.com/log-file-insights-crawl-budget-optimization/347038/)
> [Log file analysis for SEO - Search Engine Land](https://searchengineland.com/guide/log-file-analysis)
---
{{linksurge-card}}
---
## 6. 戦略 #5:月次サイトマップ監査の実施

放置されたサイトマップはインデックス化を損なう — これは大げさではなく事実です。
### 月次監査チェックリスト
1. **404エラーの確認**: サイトマップ内のURLが404を返していないかチェック(重大なエラー)
2. **リダイレクトURLの削除**: 301/302リダイレクトされたURLをサイトマップから除去
3. **canonical一致の確認**: 正規URLがサイトマップに記載されたURLと一致しているか検証
4. **`` の正確性チェック**: 本文・構造化データ・内部リンクの実質的な変更と日付が一致しているか、全ページが同一日付になっていないかを確認
5. **低パフォーマンスページの除外**: アクセスもコンバージョンもないページを削除
6. **高パフォーマンスページの追加**: サイトマップに欠落している重要ページがないか確認
### モニタリングKPI
Google Search Consoleで以下を追跡します:
- **送信ページ対インデックス比率**: 95%以上を目指す
- **カバレッジエラー**: 週次でチェック
- **インデックス速度**: 送信からインデックスまで48時間以内が目標
- **サイトマップごとのクロール頻度**: セグメント別に比較
- **有効ページ対除外ページ**: 除外理由を分析
AI Overviewsの詳しい影響と対策は「[生成AI検索がSEOを変える:7つの実践対策](/blog/ai-search-seo-japan-2026/)」で解説しています。
> 参考・引用:
> [How to Monitor & Submit Sitemaps in GSC - Quattr](https://www.quattr.com/search-console/submit-monitor-sitemaps-in-gsc)
> [XML Sitemaps & Robots.txt: Guide - Straight North](https://www.straightnorth.com/blog/xml-sitemaps-and-robots-txt-how-to-guide-search-engines-effectively/)
> [How to Set Up XML Sitemaps for SEO Success - RebelMouse](https://www.rebelmouse.com/sitemap-seo-best-practices)
---
## 7. 戦略 #6:画像・動画サイトマップでビジュアル検索を制する
2026年では、ビジュアル検索の重要性が格段に増しています。Google Lens、画像検索、動画検索からのトラフィックを見逃さないために、専用サイトマップの整備が不可欠です。
### image-sitemap.xml の構成
```xml
https://example.com/product/item-1
https://example.com/images/item-1.jpg
商品名の説明
商品の詳細キャプション
```
含めるべき画像:
- 製品画像(Eコマース必須)
- インフォグラフィックス
- 記事のアイキャッチ画像
### video-sitemap.xml の構成
動画サイトマップには必須タグが多いので注意が必要です:
- ``: 動画タイトル
- ``: 動画の説明
- `` または ``: 動画ファイルまたはプレーヤーのURL
- ``: サムネイル画像
- ``: 公開日
含めるべき動画:
- チュートリアル動画
- 製品デモ
- 説明コンテンツ
### 小規模サイトの場合
画像や動画が少数の場合は、メインサイトマップ内に `image:image` や `video:video` ネームスペースを埋め込む方式でも問題ありません。大規模サイトになったら分離を検討しましょう。
[LinkSurge](https://linksurge.jp/)でサイトのテクニカルSEO状況を分析すると、サイトマップの健全性も含めて改善点が可視化されます。
> 参考・引用:
> [Image Sitemaps - Fundamentals and Best Practices - SEO Day](https://www.seo-day.de/wiki/on-page-seo/bilder-seo/image-sitemaps.php?lang=en)
> [Incorporating Video and Image Content in XML Sitemaps - Peak Positions](https://www.peakpositions.com/tech-tips/incorporating-video-and-image-content-in-xml-sitemaps/)
> [Sitemap Best Practices - Respona](https://respona.com/blog/sitemap-best-practices/)
---
## 8. 2026年によくあるXMLサイトマップのミス
ここまでの戦略を実行する前に、以下のミスに該当していないかチェックしましょう。一つでも該当すれば、サイトマップが逆効果になっている可能性があります。
- **noindexページを含める**: インデックスしたくないページをサイトマップに入れると矛盾したシグナルになる
- **非正規URLをリストする**: canonicalタグと異なるURLをサイトマップに記載する
- **1つのサイトマップに50,000以上のURL**: プロトコル上限を超えるとファイル自体が無効になる
- **`` を更新しない**: 全ページが同じ日付のままだと、Googleは新鮮さシグナルを取得できない
- **パラメータURLを含める**: `?sort=price&page=2` のようなURLはフィルタリング結果であり、サイトマップに不要
- **画像・動画サイトマップが不足**: ビジュアル検索のトラフィックを逃している
- **Search Consoleでエラーを監視しない**: 送信しっぱなしで放置は論外
テクニカルSEOの包括的なガイドは「[【2026年最新】SEO対策の始め方ガイド](/blog/seo-latest-guide-2026/)」で解説しています。
> 参考・引用:
> [Build and Submit a Sitemap - Google Search Central](https://developers.google.com/search/docs/crawling-indexing/sitemaps/build-sitemap)
> [XML Sitemap Best Practices for SEO - BrightSEO Tools](https://brightseotools.com/post/xml-sitemap-best-practices-seo)
> [8 best sitemap generator tools - Zapier](https://zapier.com/blog/best-sitemap-generator/)
---
{{linksurge-card}}
---
## よくある質問(FAQ)
### サイトマップのセグメント化はどのくらいの規模のサイトから必要ですか?
1,000ページ以上のサイトではセグメント化を推奨します。それ以下でも、コンテンツタイプが明確に分かれている場合(ブログ+商品ページなど)はセグメント化の恩恵があります。10,000ページを超えたら必須と考えてください。
### `` をGoogleが無視するなら、設定する意味はありますか?
GoogleもBingも無視しますが、Yandexはクロール優先度の参考にすると公式に案内しています。また、サイト内部のURL重要度を文書化する意味もあります。設定コストが低いなら維持し、ただし `` の正確性に注力する方が効果的です。
### 動的サイトマップの更新頻度はどのくらいが適切ですか?
コンテンツの更新頻度に合わせるのが基本です。ECサイトなら商品追加・削除のたびにリアルタイム更新、ブログなら記事公開時に更新、コーポレートサイトなら週次程度で十分です。重要なのは `` が実際の変更を正確に反映していることです。
### サイトマップのインデックス率が80%を下回っている場合、何を確認すべきですか?
まずSearch Consoleのカバレッジレポートで除外理由を確認します。多くの場合、重複コンテンツ、noindexページ、リダイレクトチェーンが原因です。サイトマップから該当URLを除去し、canonical設定を見直してから再送信してください。
---
## まとめ:サイトマップを発見とインデックスの運用対象として扱い始めよう
XMLサイトマップは、Googleのための単なるファイルではありません。サイトにどのURLが存在するのか、そしてどのページが実質的に更新されたのかを検索エンジンに伝えるためのものです。
ここで正確に押さえておきたいのは、**サイトマップはクロールの順序を指示できるものではない**という点です。Googleはこれをクロール対象を見つけるための手がかりとして扱うのであって、送信した順や優先度の通りに処理してくれるわけではありません。
同じく、**サイトマップ自体はランキング要因ではありません**。順位を直接押し上げる仕組みは持っていません。効くのはその手前の工程です。インデックスされていないページは検索結果に出ようがない以上、発見とインデックスを確実にすることが、結果として順位のスタートラインに立つための前提条件になります。
セグメント化する。`` を正確に保つ。メンテナンスする。監視する。チェックボックスのように扱うのをやめて、発見とインデックスを支える運用対象として扱い始めましょう。95%以上のインデックス率を達成し、新規コンテンツが48時間以内にインデックスされる状態を作ること — それが2026年のサイトマップ戦略のゴールです。
LinkSurgeの[SEO分析機能](https://linksurge.jp/)では、サイトのインデックス状況やテクニカルSEOの改善点をリアルタイムで分析できます。
---
## 【2026年版】安全なリンクビルディング完全ガイド:ペナルティを避けて被リンクを稼ぐ5つの戦略
> URL: https://linksurge.jp/blog/safe-link-building-guide-2026/
> Date: 2026-04-04 | Category: SEO | Author: 緒方亜朗
> Tags: SEO, リンクビルディング, 被リンク, デジタルPR, HARO, バックリンク
## この記事の結論:安全なリンクビルディング5つの要点
「被リンクが大事なのはわかっている。でも、ペナルティが怖くて何もできない」——私がSEOの相談を受けるなかで、最も多い悩みのひとつがこれです。2026年現在、リンク購入やPBN(プライベートブログネットワーク)はSpamBrainによって高精度で検出される時代ですが、**正しい方法で被リンクを「稼ぐ」手法は今も極めて有効**です。
1. **デジタルPRが最も高品質なリンクを生む** — ニュースバリューのあるオリジナルデータやストーリーをメディアに提供し、編集記事内にリンクを獲得する。DR50〜85+のリンクが期待でき、ROIは250〜625%という調査報告もある
2. **HARO・記者マッチングは「高DR×低コスト」の穴場** — ジャーナリストの取材依頼に専門家として回答するだけで、DR60〜85クラスの被リンクを獲得できる。ただし採用率は5〜15%で、スピードと質が鍵
3. **オリジナル調査は長期的にリンクを稼ぎ続ける資産になる** — 独自データに基づくレポートやインフォグラフィックは、公開後も年単位で引用され続ける。ある事例では1本のレポートから22件の被リンクと156%のブランド検索増を達成
4. **リソースページ・リンク切れ修復は再現性が高い** — 既存のリソースページや切れたリンクを見つけて自社コンテンツを代替提案する手法は、低コストで安定した成果が出る
5. **単一手法への依存は危険。ポートフォリオ分散が原則** — どの手法も全体の30〜40%を超えないようにバランスを取る。これがGoogleに「自然なリンクプロファイル」と認識されるための基本
以下では、各戦略の具体的な実行手順、コスト、期間、KPIを詳しく解説します。要点を動画でも解説しています。
{{youtube:QVxbSXsMBTk|安全なリンクビルディング完全ガイド2026|デジタルPR・記者マッチング・リンカブルアセット}}
---
## 1. 2026年のリンクビルディング:なぜ「稼ぐ」が正解なのか

Googleは一貫して「自然に獲得された編集リンク」を最も高く評価しています。Google検索セントラルのリンクに関するベストプラクティスでは、クロール可能な``形式のリンクが検索シグナルとして機能すると明記されており、逆にリンクスパムポリシーではリンク売買・PBN・大量ゲスト投稿を明確に禁止しています。
率直に言って、2026年にリンクを「買う」戦略は割に合いません。SpamBrainはリンクパターン、コンテンツ類似性、ホスティングインフラを横断分析し、ネットワーク単位で一括制裁を行います。リンクを買って一時的に順位が上がっても、ペナルティで失うトラフィックと回復にかかる時間を考えれば、最初から正攻法で取り組む方がはるかに効率的です。
[サテライトサイトSEOは終わった:Googleペナルティの実態と安全なリンク構築法](/blog/satellite-site-seo-risks-2026/)では、PBNやサテライトサイトがなぜ検出されるのかを詳しく解説しています。本記事では「じゃあ何をすればいいのか」に焦点を当てます。
### 安全なリンクビルディングの共通原則は?
安全なリンクビルディングに共通する原則は「第三者が編集判断で自発的にリンクする理由を作る」ことです。具体的には、ニュースバリュー、独自データ、専門知識、実用的なツールなど、リンク元にとっての価値が存在することが前提です。この原則を満たす5つの具体的手法を順に解説します。
> 参考・引用:
> [Google の SEO リンクに関するベスト プラクティス - Google検索セントラル](https://developers.google.com/search/docs/crawling-indexing/links-crawlable?hl=ja)
> [Why Use Digital PR For Link Building in 2025 - BuzzStream](https://buzzstream.com/blog/digital-pr-link-building/)
> [15 White Hat Link Building Tactics That Google Loves - BuzzStream](https://buzzstream.com/blog/white-hat-link-building/)
---
## 2. デジタルPR:最高品質のリンクを獲得する王道

デジタルPRは、ニュースバリューのあるコンテンツ(独自データ、調査結果、トレンド分析)をメディアに提供し、記事内にリンクを獲得する手法です。私が調べたところ、リンクビルディングの専門家の間でも「最も質の高いリンクを生む手法」として一貫して評価されています。
### デジタルPRの6ステップ実行手順
**Step 1: アイデア発掘** — 業界のトレンドモニタリングと競合のバックリンク分析から、まだカバーされていないニュースアングルを特定します。「記者が書きたくなるストーリー」を意識することが重要です。
**Step 2: データ資産の作成** — 明確な見出し、エグゼクティブサマリー、ビジュアル(グラフ・インフォグラフィック)、プレスキットを準備します。エバーグリーンな内容であれば長期的にリンクを稼ぎ続けます。
**Step 3: メディアリスト構築** — ターゲットとなるジャーナリスト・メディアのリストを作成。日本市場では、媒体の信頼性と読者層を慎重に精査することが成功の鍵です。
**Step 4: 個別ピッチ** — 1〜2文のフック + 実績・信頼性を示す1行で構成した短いメール。日本語では敬語を使い、件名は20文字程度が目安。150語以下が理想です。
**Step 5: 取材対応** — 記者からの追加質問に迅速に対応し、引用可能なコメント、データテーブル、埋め込み用チャートを提供します。
**Step 6: 効果測定** — 掲載確認、リンクの種類(dofollow/nofollow)、リファラルトラフィック、オーガニック順位の変動を追跡します。
### コストとROI
デジタルPRは安くはありません。1本あたりのリンク獲得コストは750〜1,500ドル以上、エージェンシーの月額リテイナーは3,000〜15,000ドル以上が相場です。しかし、ある調査によるとデジタルPR専任で年間6万ドルを投資した場合、40〜80本の高権威バックリンクを獲得し、トラフィック60〜150%増、ROI 250〜625%という試算があります。
日本市場で実践する場合、日本語でのメディアリレーション、ステルスマーケティング規制の遵守(PR/広告表記の明示)、個人情報保護法(APPI)への準拠が必須です。
[LinkSurge](https://linksurge.jp/)の被リンク分析機能を使えば、競合がどのメディアからリンクを獲得しているかを可視化でき、デジタルPRのターゲット選定に活用できます。
> 参考・引用:
> [Digital PR vs Link Building: ROI & Hybrid Strategies - Casey's SEO](https://caseysseo.com/digital-pr-vs-traditional-link-building-roi-comparison-and-hybrid-strategies/)
> [10 Essential Digital PR Strategies for 2025 - Press Ranger](https://pressranger.com/blog/digital-pr-strategies)
> [Link Building Stats 2025: 50+ Data Points - RockingWeb](https://rockingweb.com.au/link-building-statistics-2025/)
> [Guide to Link Building in Japan - Zo Digital Japan](https://www.zodigital.jp/blog/guide-to-link-building-in-japan/)
---
## 3. HARO・記者マッチング:専門知識をリンクに変える
オリジナルデータを持っていなくても、あなたの**専門知識そのものがリンク獲得資産**になります。HARO(Help A Reporter Out)やQwotedなどのプラットフォームでは、ジャーナリストが記事執筆のために専門家のコメントを募集しています。
### HARO活用の基本戦術
**スピードが命** — 記者のリクエストに対して0〜4時間以内に回答することが採用率を大きく左右します。1日遅れただけで、すでに十分な回答が集まり締め切られているケースがほとんどです。
**回答テンプレート** — 100〜200語で、①氏名・肩書き・会社名、②1文の専門性証明(「〇〇業界で10年以上の経験」など)、③記者の質問への直接的な回答 + 具体的なデータか事例、④連絡先を記載します。
**採用率の現実** — 率直に言って、HAROの採用率は5〜15%です。毎月0〜3件の被リンクが現実的な期待値。ただし、採用された場合のリンク品質はDR60〜85と非常に高いのが魅力です。
### 日本市場での注意点
HAROは英語圏が中心のプラットフォームです。日本国内には同等規模の公開プラットフォームが少ないため、海外メディアへのアプローチと国内メディアへの直接的なPR活動を組み合わせるのが現実的です。日本のメディアに対しては、敬語でのメール対応と「読者価値を先に示す」アプローチが採用率を高めます。
> 参考・引用:
> [HARO Link Building Playbook: Pitches, Links, Results - uSERP](https://userp.io/link-building/guide-to-haro-link-building/)
> [HARO Link Building: A 6-Step Shortcut to Top-Tier Backlinks - LinkDoctor](https://linkdoctor.io/haro-link-building/)
> [HARO Link Building in 2026: Worth It or Outdated? - Editorial.Link](https://editorial.link/boost-your-seo-with-haro-link-building/)
> [5 Best HARO Alternatives in 2026 - Backlinko](https://backlinko.com/haro-alternatives)
---
## 4. オリジナル調査・リンカブルアセット:放っておいてもリンクが集まる資産

リンカブルアセットとは、他のサイトが「これは引用・リンクする価値がある」と判断するコンテンツ資産のことです。私がこの手法を特に推す理由は、**一度作れば年単位でリンクを稼ぎ続ける複利効果**があるからです。
### 効果的なリンカブルアセット6タイプ
**独自調査レポート** — 300〜500人規模のアンケート調査や、自社保有データの分析レポート。ある事例では1本のレポートから22件の被リンク、3件のインタビュー依頼、ブランド検索156%増を達成しています。
**インタラクティブツール** — 計算機、診断ツール、無料チェッカーなど。ユーザーが繰り返し使い、SNSで共有する仕組みが自然なリンクを生みます。
**インフォグラフィック** — 複雑なデータを視覚的にわかりやすく整理したもの。埋め込みコードを提供すれば、ブログ運営者が自サイトに貼り付ける際にリンクが付きます。
**業界ベンチマーク** — 「〇〇業界の平均コンバージョン率」のようなベンチマークデータ。毎年更新すれば、繰り返し引用されるエバーグリーンな資産になります。
**無料テンプレート・チェックリスト** — 実用性が高く、ダウンロード数がリンク獲得につながります。
**包括的ガイド** — 特定トピックについて最も詳しいリソースを目指す。[SEO対策完全ガイド](/blog/seo-guide-2026/)のような長文コンテンツは、業界の参照先として継続的にリンクされます。
### 制作から拡散までの流れ
1. リサーチ質問の設定と統計的に有意なサンプルサイズの確保
2. データ収集・分析・ビジュアル化(グラフ、PDF、埋め込み可能な形式)
3. 記者・キュレーターへの先行提供(エンバーゴ付き独占アングル)
4. 自社サイトでの公開 + 社内リンクでの導線設計
5. SNS拡散 + 関連メディアへのフォローアップ
{{linksurge-card}}
> 参考・引用:
> [How To Build Linkable Assets With AI In 2026 - Search Logistics](https://searchlogistics.com/learn/seo/link-building/linkable-assets/)
> [Linkable Assets: A Guide to Building Powerful Backlinks - SeoProfy](https://seoprofy.com/blog/linkable-assets)
> [Link Building Strategies 2025: Authority Backlinks - Digital Applied](https://digitalapplied.com/blog/link-building-strategies-2025)
---
## 5. コストとROI:リンクビルディング投資の現実

「リンクビルディングにいくらかかるのか?」は最も多い質問です。手法ごとのコストと期待できるリターンを整理しました。
### 手法別コスト・期間・期待リンク数
| 手法 | 1本あたりコスト | 月間期待リンク数 | 成果が出るまで | リンク品質(DR目安) |
|------|---------------|----------------|--------------|-------------------|
| デジタルPR | $750〜$1,500+ | 3〜7本 | 3〜12ヶ月 | DR50〜85+ |
| HARO/記者マッチング | $50〜$200(人件費) | 0〜3本 | 即日〜3ヶ月 | DR60〜85 |
| オリジナル調査 | $500〜$2,000+ | 資産公開後に継続 | 3〜12ヶ月 | DR30〜70+ |
| リソースページ/リンク切れ | $200〜$500 | 2〜5本 | 数週間〜数ヶ月 | DR20〜60 |
| 専門家ラウンドアップ | $100〜$300 | 1〜3本 | 2〜8週間 | DR20〜50 |
### ROIの考え方
リンクビルディングのROIを正確に測定するには、「被リンク1本あたりのコスト」と「そのリンクがもたらすオーガニックトラフィックの生涯価値」を比較します。BuzzStreamの統計調査によると、高品質な被リンク1本の平均コストは508〜1,000ドル以上。一方で、DR50+のサイトからのリンクは年間数千〜数万ドル相当のオーガニックトラフィック価値をもたらす可能性があります。
### 企業規模別の推奨予算配分
**小規模・ローカルビジネス** — HARO回答、専門家引用、リソースページ・リンク切れ修復を中心に。月0〜3件、3〜6ヶ月で成果が見え始める。
**中規模企業** — オリジナル調査を定期的に実施し、デジタルPRとリソースページアウトリーチを併用。月数本の品質リンクを安定獲得。
**大企業・エンタープライズ** — マルチアセット戦略 + 本格的なデジタルPRキャンペーン + 社内チーム体制。大規模なトラフィック成長を6〜24ヶ月で実現。
> 参考・引用:
> [The True Cost of Link Building in 2025 - ReportCard](https://reportcard.com/blog/link-building-cost/)
> [Link Building Costs in 2025: Real Prices & ROI Secrets - SearchBerg](https://searchberg.com/blog/link-building-cost-2025/)
> [70 Link Building Statistics (Based on Reports from 2025) - BuzzStream](https://buzzstream.com/blog/link-building-statistics/)
---
## 6. 避けるべき手法とリスクスペクトラム

ここまで「安全な手法」を解説してきましたが、グレーゾーンの手法もあるため、リスクスペクトラムを理解しておくことが重要です。
### 安全(グリーン)
- **エディトリアルリンク** — 記者やブロガーが編集判断で貼るリンク。最も価値が高い
- **デジタルPR** — ニュースバリューに基づく獲得。Googleが推奨する方法
- **オリジナル調査・データ** — 引用の自然な動機が存在する
### 注意(イエロー)
- **ゲスト投稿** — 少量で高品質なら問題ないが、大量展開するとGoogleは「リンクスキーム」と見なす。寄稿先の選定基準が重要
- **相互リンク** — 少数の自然な相互リンクは問題ないが、組織的なリンク交換は違反
### 危険(レッド)
- **PBN(プライベートブログネットワーク)** — SpamBrainが高精度で検出。ネットワーク全体がインデックス削除のリスク
- **リンク購入** — 明確なGoogleガイドライン違反。手動ペナルティの対象
- **自動生成リンク** — スパムコメント、フォーラムスパム等。即座に検出・無効化
### ポートフォリオ分散の原則
どの手法も全体の30〜40%を超えないようにバランスを取ることが重要です。デジタルPRだけ、HAROだけ、といった偏りは不自然なリンクプロファイルのシグナルになりえます。
[オフサイトSEOとGEOの完全ガイド](/blog/offsite-seo-geo-2026/)では、リンクビルディングを含むオフサイトSEO全体の戦略を包括的に解説しています。
> 参考・引用:
> [Why Google Penalises Certain Link Building Patterns - Hashmeta](https://hashmeta.com/blog/why-google-penalises-certain-link-building-patterns-understanding-and-avoiding-seo-penalties/)
> [White Label Link Building for Agencies: 2025-2026 Guide - ALM Corp](https://almcorp.com/blog/white-label-link-building-for-agencies-2025-2026-tactics/)
> [【実はこれもダメ】SEOでペナルティを受けやすい被リンクとは - メディアリーチ](https://mediareach.co.jp/blog/seo-penalty)
---
{{linksurge-card}}
---
## よくある質問(FAQ)
### リンクビルディングは2026年でもSEOに効果がありますか?
はい、被リンクは依然としてGoogleの主要なランキング要因のひとつです。ただし、リンクの「量」よりも「質」が重視される傾向は年々強まっています。DR50以上の権威あるサイトからの1本のリンクは、低品質サイトからの100本のリンクよりも価値があります。
### 無料でできるリンクビルディング手法はありますか?
HARO(無料プラン)への回答、リソースページへのアウトリーチ、リンク切れ修復提案は、ツール費用を除けばほぼ人件費だけで実施可能です。小規模ビジネスにとって最もコスト効率の良い出発点です。
### ゲスト投稿はまだ有効ですか?
少量で高品質なゲスト投稿は有効です。しかし、Googleは「大規模なゲスト投稿キャンペーン」をリンクスパムとして明確に定義しています。寄稿先は「リンクがなくても寄稿する価値があるメディアか?」を判断基準にしてください。
### リンクビルディングの成果が出るまでどのくらいかかりますか?
手法によりますが、HAROは最短で即日〜数週間、デジタルPRは3〜6ヶ月で最初の成果、本格的なオーガニックトラフィック増加は6〜12ヶ月後が一般的です。LinkSurgeの順位トラッキングを使えば、被リンク獲得後の順位変動をリアルタイムで監視できます。
### nofollowリンクには価値がありますか?
直接的なPageRank転送はありませんが、ブランド認知、リファラルトラフィック、E-E-A-T(経験・専門性・権威性・信頼性)のシグナルとして間接的な価値があります。高権威サイトからのnofollowリンクを軽視すべきではありません。
---
## まとめ:リンクを「買う」時代は終わった。「稼ぐ」戦略を今日から始めよう
2026年のリンクビルディングは、一言で言えば「第三者が自発的にリンクしたくなる理由を作る」競争です。デジタルPRでメディア掲載を獲得し、HAROで専門知識をリンクに変え、オリジナル調査で長期的に引用される資産を作り、リソースページやリンク切れ修復で地道にリンクを積み上げる。これらの手法は時間がかかりますが、ペナルティリスクがなく、SEOの複利効果を最大化できます。
まずは自社の強みを棚卸しすることから始めてください。独自データがあるならオリジナル調査レポート、専門知識があるならHARO回答、ニュースバリューのある活動をしているならデジタルPR。どの入り口からでも、「稼ぐ」リンクビルディングは今日から始められます。
LinkSurgeの[被リンク分析機能](https://linksurge.jp/)を使えば、自社と競合のバックリンクプロファイルを可視化し、最も効果的なリンク獲得チャネルを特定できます。まずは現状の被リンク品質を把握するところから始めてみてください。
---
## トピッククラスターと内部リンク戦略:サイト構造でSEOを制する2026年の実践ガイド
> URL: https://linksurge.jp/blog/topic-cluster-internal-linking-strategy/
> Date: 2026-04-04 | Category: SEO | Author: 緒方亜朗
> Tags: トピッククラスター, 内部リンク, サイト構造, リンクエクイティ, ページプルーニング
## この記事の結論:サイト構造と内部リンクがSEOの土台を決める
1. **トピッククラスターはAI検索時代に有効な設計** — ピラーページ+クラスターページの構成は、トピックを体系的に整理し、検索エンジンやAI回答システムから発見・理解されやすい形にするための手法だ。「単体記事より約30%多いトラフィック」「ランキング維持期間が2.5倍」といった数値も紹介されているが、いずれも出典を確認できていないため参考値として扱う。
2. **3クリックルールでフラットな階層を維持する** — すべての重要ページをホームページから3クリック以内に配置する。深い階層に埋もれたページは内部リンクの導線が細く、クロールされる機会も読者に見つけてもらう機会も減りやすい。
3. **内部リンクでリンクエクイティを戦略的に集中させる** — 被リンクを多く獲得している高権威ページから、収益や集客に直結する重要ページへ内部リンクを張ることで、低品質な外部リンク1本より効果が高い場合がある(筆者の実務上の観察であり、一般則として検証されたものではない)。1,000語あたり2〜5本の文脈的リンクが最適解だ。
4. **ページプルーニングでサイト全体の品質密度を高める** — トラフィックのない薄いページを削除・noindex・統合することで、クロールバジェットが節約され、残ったページの評価が向上する。Googleの2024年8月コアアップデートでも低品質コンテンツの削除がランキング改善につながった事例が報告されている。
5. **設計→実装→計測のサイクルを回す** — トピッククラスターの効果はA/Bテストや段階的ロールアウトで検証可能。Google Search Console、GA4、クロールデータを組み合わせてインプレッション・クリック・CTR・順位を計測し、継続的に改善する。
以下では、各テーマを順に解説します。要点を動画でも解説しています。
{{youtube:2Zn_FhYLTdg|トピッククラスターと内部リンク戦略|3方向リンクと「減らす」という選択肢}}
---
## 1. トピッククラスターとは?ピラーページの基本概念

### トピッククラスターの仕組みはどうなっているのか?
トピッククラスターとは、1つの包括的なピラーページ(中心ページ)と、それを支える複数のクラスターページ(個別テーマページ)を内部リンクで結んだコンテンツ構造のことです。ハブ&スポーク型とも呼ばれるこのモデルでは、ピラーページが主要なテーマの全体像を示し、各クラスターページがサブトピックを深掘りします。
私が調べたところ、2026年現在、この構造は検索エンジンだけでなくAI回答システム(Google AI Overviews、ChatGPT、Perplexityなど)が「このサイトはこのトピックを網羅的にカバーしている」と判断するための最も効果的なシグナルになっています。
### ピラーページに求められる要件
実務的な推奨として、ピラーページは2,500〜5,000語の包括的なガイドとして作成します。そのテーマの「目次」のような役割を果たし、各クラスターページへのリンクを含みます。一方、クラスターページは各サブテーマを深く掘り下げ、必ずピラーページへの戻りリンクを設置します。
1つのピラーに対するクラスターページの数は、テーマの広さによりますが5〜30記事が一般的な目安です。重要なのは数ではなく、トピックを十分にカバーしているかどうかです。
[2026年最新 SEO対策完全ガイド](/blog/seo-guide-2026/)では、AI検索時代のSEO全体像を解説していますが、中でもサイト構造はテクニカルSEOの根幹に位置する要素です。
> 参考・引用:
> [Pillar Pages & Topic Clusters for SEO Growth 2026 - Web Spider Solutions](https://webspidersolutions.com/boost-seo-2026-pillar-pages-topic-clusters/)
> [The complete guide to topic clusters and pillar pages for SEO - Search Engine Land](https://searchengineland.com/guide/topic-clusters)
> [A Topic Cluster Content Strategy for 2026 - Brafton](https://www.brafton.com/blog/strategy/topic-cluster-content-strategy/)
---
## 2. なぜ「浅い階層」がSEOに効くのか — 3クリックルール

### 3クリックルールの根拠は何か?
3クリックルールとは、サイト上のすべての重要ページをホームページから最大3回のクリックで到達できるようにする設計原則です。これはUXの慣習であると同時に、クロールされやすさと読者の到達しやすさの両方に関わる設計指針でもあります。
率直に言って、階層が深いページは検索エンジンから発見されにくくなります。ホームページから遠いほど内部リンクによる導線が細くなり、クロールされる機会も減りやすいためです。Googleは[クロールバジェットの解説](https://developers.google.com/search/docs/crawling-indexing/large-site-managing-crawl-budget)で「インターネット上でより人気のあるURLは、より頻繁にクロールされる傾向がある」と説明しています(PageRankという用語は使われていません)。なお「深度4以上」という具体的な数字はランキングの閾値ではなく、目安として扱ってください。「フラットな構造でクロール効率が40〜70%向上する」といった数値も見かけますが、出典が特定できないため本記事では参考値として扱います。
### フラットアーキテクチャを実現する具体策
フラットな階層を維持するためのポイントは以下の通りです。
- **URLの設計**: `/カテゴリ/サブカテゴリ/記事/` のように、2〜3階層のシンプルなURL構造にする
- **パンくずリスト**: BreadcrumbList構造化データでマークアップし、階層シグナルを強化する
- **グローバルナビゲーション**: 主要カテゴリへのリンクを全ページで提供する
- **コンテキストリンク**: 本文中に関連ページへの自然なリンクを設置し、実質的なクリック深度を下げる
LinkSurgeのSEO分析ダッシュボードでサイト構造を可視化すると、クリック深度の問題がある箇所を特定しやすくなります。
> 参考・引用:
> [Internal Linking Strategy: Complete SEO Guide for 2026 - Ideamagix](https://www.ideamagix.com/blog/internal-linking-strategy-seo-guide-2026/)
> [Internal Linking Strategy 2026: Site Architecture That Ranks - Mavic Labs](https://www.maviklabs.com/blog/internal-linking-strategy-2026)
> [Best Internal Linking Strategy for SEO 2026 - Data Enriche](https://www.dataenriche.com/best-internal-linking-strategy-seo/)
---
## 3. 内部リンクでリンクエクイティを集中させる実践テクニック

### リンクエクイティはどのように流れるのか?
「リンクエクイティ」は、リンクを通じてページ間を流れる「評価の重み」をSEO業界で指す通称です。
よくPageRankと同一視されますが、正確には別物です。PageRankはGoogleが持つ多数のランキングシステムのうちの一つで、公開スコアの提供が終了しただけで内部では現在も使われています([Gary Illyes氏の言及](https://www.seroundtable.com/google-still-using-pagerank-23392.html))。一方リンクエクイティは、そうした仕組みを業界側がまとめて言い表した概念であり、Googleが公表している指標ではありません。またGoogleはリンクを、関連性の理解やページの発見に使うシグナルとして説明しており、内部リンクを張れば評価が機械的に移転する、という単純なものではありません。
経験上、内部リンクは過小評価されている打ち手だと感じています。被リンクが集中しているブログ記事から商品ページへ内部リンクを追加しただけで、対象ページの順位が改善したケースを何度も見てきました。
ただしこれは筆者が担当したサイトでの観察であって、「内部リンク1本は低品質な外部リンク1本より強い」という一般則が検証されているわけではありません。内部リンクで確実に得られるのは、そのページが発見されやすくなることと、リンク元との関連性が伝わることです。
### 内部リンクの最適な量とアンカーテキスト
1,000語あたり2〜5本のコンテキストリンク(本文内に自然に埋め込まれたリンク)が目安とされています。
なお「1ページあたり◯本まで」という上限をよく見かけますが、これはかつてGoogleのガイドラインにあった「100リンク程度」という記述に由来するもので、[同ガイドラインからは既に削除されています](https://searchengineland.com/googles-matt-cutts-we-dropped-the-100-links-per-page-guideline-but-we-may-take-action-if-it-is-too-spammy-178197)。Google側も技術的な上限ではないと説明しており、現行の推奨事項ではありません。「リンクが増えるほど1本あたりの評価が薄まる」という説明もよく見かけますが、これは初期のPageRankの数式モデルに由来する考え方で、現行の挙動として検証されたものではありません。実務的には、リンクが多すぎるとユーザーがどれをたどればよいか分からなくなる点を重視し、本文中の文脈的リンクを中心に、読者が追える範囲に収めるのが妥当です。
アンカーテキストは、**リンク先の内容が推測できる自然な文言**にするのが原則です。「こちら」「詳細はこちら」のように内容を示さない文言は避け、リンク先で何が読めるのかが分かる表現にしてください。
なお「完全一致◯%・部分一致◯%」といった配分比率がよく紹介されますが、これはもともと**外部リンク(被リンク)のペナルティ回避の文脈**で語られてきた考え方です。Googleは内部リンクのアンカーテキストについて配分の規制を示しておらず、内部リンクに同じ比率を当てはめる根拠は乏しいため、本記事では比率の指定はしません。
### 3方向の内部リンクパターン
トピッククラスター内では、以下の3方向のリンクを組み合わせます。
1. **下方向(ピラー→クラスター)**: ピラーページから各クラスターページへのリンク
2. **上方向(クラスター→ピラー)**: 各クラスターページからピラーページへの戻りリンク
3. **横方向(クラスター⇄クラスター)**: 関連するクラスターページ間の相互リンク
この3方向のリンク構造により、トピックの結束性が強化され、検索エンジンがクラスター全体を1つのトピカルオーソリティとして認識しやすくなります。
[オフサイトSEOとGEO](/blog/offsite-seo-geo-2026/)で解説している外部リンク戦略とあわせて設計すると、獲得した被リンクが集まるページから重要ページへの導線を作れます。
> 参考・引用:
> [Internal Links SEO Best Practices - Moz](https://moz.com/learn/seo/internal-link)
> [Google's Matt Cutts: We Dropped The 100 Links Per Page Guideline - Search Engine Land](https://searchengineland.com/googles-matt-cutts-we-dropped-the-100-links-per-page-guideline-but-we-may-take-action-if-it-is-too-spammy-178197)(「1ページあたりのリンク数上限」の出どころと、その削除について)
> [Google's Gary Illyes: We're Still Using PageRank - Search Engine Roundtable](https://www.seroundtable.com/google-still-using-pagerank-23392.html)(PageRankが現在も内部で使われていることについて)
> [How many internal links should you have per page? - InLinks](https://inlinks.com/insight/how-many-internal-links-should-you-have-per-page/)
> [Internal Linking for SEO: Complete 2026 Guide - LinkWhisper](https://linkwhisper.com/the-ultimate-guide-to-internal-linking-for-seo-and-geo/)
---
{{linksurge-card}}
---
## 4. トピッククラスターの設計手順 — 5ステップフレームワーク

### どのようにトピッククラスターを設計すればよいのか?
ここからは、実際にトピッククラスターを構築するための5ステップを具体的に解説します。
**ステップ1:コアトピックを選定する**
ビジネスの核となるテーマを1つ選びます。例えば、SEOツールを提供している企業であれば「SEO対策」がコアトピックになります。選定基準は「検索ボリュームがある」「ビジネスに直結する」「十分なサブトピックに分解できる」の3点です。
**ステップ2:サブトピックをリサーチする**
コアトピックを分解し、検索意図の異なるサブトピックを洗い出します。キーワードリサーチツールを使い、各サブトピックの検索ボリューム、競合性、検索意図を確認します。1つのピラーに対して5〜30のサブトピックを特定するのが目安です。
**ステップ3:ピラーページを作成する**
コアトピックの全体像を網羅するピラーページを作成します。2,500〜5,000語の包括的なガイドとして、各サブトピックの概要と、クラスターページへのリンクを含めます。
**ステップ4:クラスター記事を執筆する**
各サブトピックについて、深く掘り下げた個別記事を作成します。それぞれの記事にピラーページへの戻りリンクを設置し、関連するクラスター記事間にも横方向のリンクを張ります。
**ステップ5:内部リンクを設計・実装する**
最後に、クラスター全体の内部リンク構造を見直し、リンク切れや孤立ページがないか確認します。Google Search Consoleの内部リンクレポートを活用して、リンクの分布を定期的に監視しましょう。
LinkSurgeのキーワード分析機能を活用すれば、ステップ2のサブトピックリサーチを効率的に進められます。検索ボリューム、競合性、検索意図の分析を一括で実行できます。
> 参考・引用:
> [Topic Clustering Guide: Build Authority with Pillar Pages in 2026 - ClickRank](https://www.clickrank.ai/topic-clustering-in-content-seo/)
> [How to Build Pillar Content: A Step-by-Step Guide 2026 - NiuMatrix](https://niumatrix.com/pillar-cluster-content-guide/)
> [How To Boost SEO and DR in 2026 With Topic Clusters - StoryChief](https://storychief.io/blog/topic-clusters-seo)
---
## 5. ページプルーニング — 薄いページの判定基準と実行方法

### なぜページプルーニングが必要なのか?
ページプルーニング(Content Pruning)とは、検索パフォーマンスの低いページを削除・統合・noindex指定することで、サイト全体の品質密度を高める施策です。ここが重要なポイントです — 検索エンジンはサイト全体の品質を評価しており、低品質なページが多いと高品質なページの評価まで引き下げられる可能性があります。
Googleの2024年8月コアアップデートでは、低品質コンテンツの削除がランキング改善につながった事例が多数報告されています。質の低いページをインデックスから削除すると、残ったページの順位が上がることがあるのです。
### 4つのアクションで判断する
ページプルーニングの判断は、以下の4つのアクションに分類できます(本記事ではKeep / Update / Merge / Delete の頭文字をとってKUMDと整理しますが、業界で定着した用語ではありません)。
- **Keep(維持)**: トラフィックは少ないが、コンバージョンに貢献している、または被リンクがある
- **Update(更新)**: コンテンツが古くなっているが、テーマ自体に価値がある → リライトする
- **Merge(統合)**: 類似テーマの複数ページがある → 1つに統合し、古いURLから301リダイレクト
- **Delete(削除)**: トラフィックゼロ、被リンクなし、改善の余地もない → 410ステータスで削除(noindexとの使い分けは後述)
### プルーニングの判定基準
具体的な判定には、以下のデータを組み合わせます。
1. **過去6〜12ヶ月のオーガニックトラフィック**: Google Search Consoleでインプレッション・クリックがゼロのページを特定
2. **被リンクの有無**: Ahrefs、Moz等でバックリンクを確認。被リンクがあるページは安易に削除しない
3. **E-E-A-T基準**: 情報が古い、薄い、不正確 → プルーニング対象
4. **重複・カニバリゼーション**: 同じキーワードで競合しているページがないか確認
### noindexと削除の使い分け
**noindex**: ページ自体はサイトに残すが、検索インデックスから除外する。ユーザーがURL直接アクセスやサイト内リンクで閲覧するケースがある場合に適切。
**削除(410)**: ページの存在意義がない場合。410ステータスコードを返すことで、Googleに「意図的に削除した」ことを伝えられる。
**301リダイレクト**: 被リンクがある場合や、類似ページへの統合時。リンクエクイティを引き継げる。
> 参考・引用:
> [低品質ページを消すとSEO評価が上がる? - 長野・群馬ホームページ制作会社比較サイト](https://naganogunmacreators.jp/guide/pruning-low-quality-content/)
> [質の低いページをインデックスから削除すると順位が上がることがある - パスカルブログ](https://www.pascaljp.com/blog/?p=352)
> [低品質コンテンツとは?SEO評価への影響や見分け方と改善方法 - LANY](https://www.lany.co.jp/blog/low-quality-content)
> [What to know about our August 2024 core update - Google](https://developers.google.com/search/blog/2024/08/august-2024-core-update)
---
## 6. 効果として語られている数値をどう扱うか

### トピッククラスターの効果はどの程度あるのか?
トピッククラスターの効果としては、以下のような数値が各種のSEO記事やツールベンダーのレポートで紹介されています。
> **注意**: 以下はいずれも一次調査の出典・母集団・測定方法を当社で確認できていない数値です。施策の方向性を示す参考値として扱い、自社の目標値やKPIの根拠にはしないでください。
| 指標 | 効果 |
|------|------|
| オーガニックトラフィック | 単体記事比で約30%増 |
| ランキング維持期間 | 2.5倍長い |
| クロール効率 | 40〜70%向上 |
| 検索順位 | 最大40%改善 |
| 12ヶ月継続後のトラフィック | 40%以上の成長 |
### Googleのコアアップデートとの関連
2024年のGoogleコアアップデート(3月・8月)以降、大きなトラフィック減少を報告するサイトが多数ありました。ただしそれをサイト構造が原因と結論づけた調査は確認できていません。コアアップデートはコンテンツの品質評価全体の見直しであり、構造だけを取り出して因果を語れるものではないため、本記事では減少幅の数値も原因の断定も行いません。
2025年6月のコアアップデートでは、トピカルオーソリティ(特定テーマの専門性)がさらに重視されるようになりました。包括的にテーマをカバーし、一貫して質の高いコンテンツを提供するサイトが評価される傾向が強まっています。
### 効果計測のポイント
クラスター単位で以下の指標を追跡しましょう。
- **クラスターSOV(Share of Voice)**: ターゲットキーワード群における可視性シェア
- **インプレッション・クリック・CTR・平均順位**: Google Search Consoleで取得
- **内部リンクCTR**: クラスター内のリンクがどの程度クリックされているか
- **コンバージョン**: GA4でクラスター経由のコンバージョンを計測
[【2026年最新】SEO対策の始め方ガイド](/blog/seo-latest-guide-2026/)では、これらの効果計測手法をより詳しく解説しています。
> 参考・引用:
> [How Pillar Pages Work: B2B SEO Strategy Guide 2026 - Whitehat SEO](https://whitehat-seo.co.uk/blog/how-seo-and-pillar-pages-work)
> [SEO Content Clusters 2026: Topic Authority Guide - Digital Applied](https://www.digitalapplied.com/blog/seo-content-clusters-2026-topic-authority-guide)
> [Topic Clusters for SEO: The Ultimate Strategy for Organic Growth in 2026 - EmbedPress](https://embedpress.com/blog/topic-clusters-for-seo/)
---
{{linksurge-card}}
---
## よくある質問(FAQ)
### トピッククラスターは小規模サイトでも効果がありますか?
はい、むしろ小規模サイトの方が即効性が出やすいです。1つのピラーと5〜8本のクラスター記事から始めるのがおすすめです。まずは自社の強みとなるテーマで1クラスターを完成させ、効果を計測してから2つ目に進みましょう。
### ページプルーニングでトラフィックが減るリスクはないですか?
短期的には一時的な変動が起こり得ます。しかし適切な判断基準(被リンクの確認、301リダイレクト設定、段階的な実施)を守れば、2〜4週間でクロールとインデックスの改善が見え始め、中長期的にはトラフィック全体が向上するケースが大半です。まずは明らかにトラフィックゼロのページから始め、大量削除は避けてください。
### 内部リンクは多いほど良いのですか?
明確な上限はありません。よく引用される「1ページあたり100〜150本まで」という数値は、かつてGoogleのガイドラインにあった記述に由来しますが、同ガイドラインからは既に削除されており、Googleも技術的な上限ではないと説明しています。「1本あたりの評価が薄まる」という説明は初期のPageRankモデルに由来するもので、現行の挙動として検証されたものではありません。ただしリンクが多すぎると読者がたどるべきリンクを判断しにくくなるため、目安として1,000語あたり2〜5本のコンテキストリンクを中心にしてください。また、ヘッダーやフッターの全ページ共通リンクは、どのページからも同じように張られるため「このページと関連が深い」という情報を持ちません。本文中の文脈的リンクを優先するのはそのためです。
### 既存のコンテンツをトピッククラスターに再編成できますか?
できます。むしろ既存コンテンツの再編成は非常に効果的です。まず全コンテンツを棚卸しし、テーマごとにグループ化します。各グループでピラーページとなる記事を選定(なければ新規作成)し、内部リンクを再設計します。この再編だけでも、重要ページへの導線が整理され、クロールされやすさと読者の回遊のしやすさが改善します。
---
## まとめ:今日からサイト構造を見直そう
トピッククラスターと内部リンク戦略は、2026年のSEOにおいて最もROIの高い施策の1つです。AI検索エンジンがトピカルオーソリティを重視する現在、「点」ではなく「面」でコンテンツを構築し、内部リンクでその構造を検索エンジンに伝えることが不可欠です。
まずは自社サイトの現状を確認するところから始めましょう。Google Search Consoleの内部リンクレポートで、リンクが集中しているページと孤立しているページを特定してください。そこから、1つのコアトピックを選んでクラスターを設計し、3クリック以内のフラットな階層を目指します。
そして忘れてはならないのがページプルーニングです。トラフィックゼロの薄いページは、クラスター全体の足を引っ張っている可能性があります。Keep / Update / Merge / Deleteの4分類で判断し、サイト全体の品質密度を高めましょう。
LinkSurgeの[SEO分析ダッシュボード](https://linksurge.jp/seo-hub)では、キーワード分析、競合分析、サイト構造の可視化を一括で実行できます。トピッククラスターの設計から効果計測まで、データに基づいた意思決定を支援します。
---
## LLMOとは何か?初心者にも分かる完全ガイド【2026年版】
> URL: https://linksurge.jp/blog/llmo-guide-beginners-2026/
> Date: 2026-04-01 | Category: AIO | Author: 緒方亜朗
> Tags: LLMO, 大規模言語モデル最適化, GEO, AIO, 生成AI対策, AI引用最適化
## この記事の結論:LLMOを理解する5つのポイント
**1. LLMOとは「生成AIに引用されるための最適化」のこと** — ChatGPTやGeminiなどのAIが回答を生成する際に、あなたのサイトのコンテンツを参照・引用してもらうための取り組み全般を指します。
**2. SEO・GEO・AIOとは目的が少し違う** — 従来のSEOが検索順位やクリック数を目標とするのに対して、LLMOはAIの回答内での「引用・ブランド露出」を直接の成果指標とします。ただし、これらは競合せず補完関係にあります。
**3. 鍵はRAG(検索拡張生成)の仕組みを理解すること** — AIはすべてをゼロから生成しているわけではなく、関連するウェブコンテンツを検索して参照します。この「検索して参照」のプロセスに最適化するのがLLMOの核心です。
**4. 今すぐできることから始められる** — 高額な技術投資は最初は不要です。クローラーの通過確認、FAQコンテンツの整備、著者情報の明記など、無料または低コストで始められる施策があります。構造化データ(JSON-LD)も低コストですが、AI引用を増やす効果は確認されていないため優先度は下がります(後述の「技術・設定」で詳しく扱います)。
**5. 効果は「AI引用数」と「AI経由のCVR」で測る** — AI由来のトラフィックは質が高く、コンバージョン率が従来の検索経由より高い傾向があるという調査報告もあります。
以下では、各テーマを順に解説します。要点を動画でも解説しています。
{{youtube:e9NV-z3vuz0|LLMOとは?SEO・GEO・AIOとの違いと、私が推奨から外した2つの施策}}
---
## 1. LLMOとは何か?(定義)

**LLMO(Large Language Model Optimization)** とは、ChatGPT、Google Gemini、Claude、Perplexityなどの生成AI(大規模言語モデル)が回答を作成する際に、あなたのウェブサイトのコンテンツを参照・引用してもらえるよう、コンテンツや技術環境を最適化する取り組みのことです。
少し前まで、ウェブマーケターが気にすべき「最適化」はほぼSEO(Search Engine Optimization)一択でした。ところが今は、多くのユーザーがGoogleで検索するのではなく、ChatGPTやGeminiに直接質問するようになっています。そこで必要になったのがLLMOという考え方です。
率直に言って、私がLLMOを初めて聞いたとき「また新しいバズワードか」と思いました。でも調べていくうちに、これはSEOに取って代わるものではなく、SEOを補完・拡張する実務的な概念だと理解できました。
### LLMOが目指すもの
LLMOが目指すのは「AIの回答内での引用・ブランド露出」です。ユーザーがAIチャットに質問したとき、AIの回答の中に「〇〇社によると...」「参照:linksurge.jp」といった形で自社コンテンツが登場する状態を作ることが目的です。
たとえ検索順位が変わらなくても、AIが自社コンテンツを引用してくれれば、ユーザーに届くチャンスが増えます。これがLLMOという考え方の本質です。
ChatGPTに特化した対策の全体像(三層インデックス・クローラー設定・日本語の引用元構造・計測)は「[ChatGPTに引用される方法 完全ガイド2026](/blog/chatgpt-geo-complete-guide-2026/)」にまとめています。
SEOが「順位」から「順位+引用」へ移ってきた経緯は、「[SEOはどう変わってきたか — キーワードを詰め込めば勝てた1990年代から、AIに引用される2026年まで](/blog/seo-history-keywords-to-ai-2026/)」で30年の年表として整理しています。
> 参考・引用:
> [LLMO - Large Language Model Optimization - Effective World](https://www.effective-world.com/en/glossary/glossar-detail/llmo-large-language-model-optimization)
> [What Is LLMO? Optimize Content for AI & Large Language Models - Search Engine Land](https://searchengineland.com/guides/large-language-model-optimization-llmo)
---
## 2. SEO・GEO・AIOとLLMOの違い

「LLMO、GEO、AIO、SEO…なんか似たような言葉が多くてよく分からない」というのは、私も最初に感じた疑問です。ここで整理してしまいましょう。
### 4つの概念の関係
**SEO(検索エンジン最適化)** は最もなじみ深い概念で、GoogleやYahoo!のような検索エンジンでの順位を上げてクリックを増やすことが目標です。ページの最適化、被リンク獲得、技術的なSEO設定などが中心施策です。
**AIO(AI Overviews最適化)** は、GoogleのAI Overview(以前のSGE)という機能に対する最適化です。検索結果の上部に表示されるAI生成の要約に自社コンテンツが引用されることを目指します。Google固有の取り組みです。
**GEO(生成エンジン最適化)** は、ChatGPT、Gemini、Perplexityなど複数の生成AIエンジン全体に対する最適化です。特定のプラットフォームに限らず、汎用的にAIに参照されるためのコンテンツ設計を指します。
**LLMO(大規模言語モデル最適化)** は、日本市場で広く使われている呼称で、GEOに最も近い概念です。「生成AI(LLM)に自社情報を参照させる」という実務領域全体を指します。
実際のところ、これら4つで使う技術は重複する部分が多く、「どれが正しい呼び方か」を議論するよりも、「AIに引用されるコンテンツを作る」という実務に集中した方が建設的です。
> 参考・引用:
> [Large Language Model Optimization (LLMO) explained - Evergreen Media](https://www.evergreen.media/en/guide/large-language-model-optimization/)
> [LLM Optimization vs Traditional SEO - SEONos](https://seenos.ai/llm-optimization/llm-optimization-vs-seo)
また、GEOの詳細な実践手法については[生成エンジン最適化(GEO)完全ガイド](/blog/geo-guide-japan-2026/)で詳しく解説しています。
---
## 3. AIがコンテンツを参照する仕組み(RAGを理解する)

「なぜAIは特定のサイトの情報を引用し、他のサイトは引用しないのか?」
これを理解するためには、**RAG(Retrieval-Augmented Generation、検索拡張生成)** という技術を知る必要があります。RAGはLLMOを理解する上で最も重要な概念の一つです。
### RAGの仕組み(超シンプル版)
1. **ユーザーが質問する** → AIチャットに「おすすめのSEOツールは?」と入力
2. **AIが関連情報を検索する** → ウェブ上の関連ドキュメントをベクトル検索でリトリーブ(取得)
3. **取得した情報をプロンプトに組み込む** → 「このコンテンツを参考にして回答してください」とAIに渡す
4. **AIが回答を生成する** → 参照情報をもとに回答を作成し、引用を付与
つまり、AIは「すべてを自分の学習データから回答している」わけではなく、リアルタイムで外部のコンテンツを検索して参照しているケースが多いのです。
**LLMOのポイントはまさにここにあります。** ステップ2で「検索されやすく」、ステップ3で「引用に値すると判断される」コンテンツを作ること。それがLLMOの本質です。
> 参考・引用:
> [Retrieval Augmented Generation (RAG) for LLMs - PromptingGuide](https://www.promptingguide.ai/research/rag)
> [What is RAG (Retrieval-Augmented Generation)? - OpenAPI](https://openapi.com/blog/what-rag-retrieval-augmented-generation)
---
{{linksurge-card}}
---
## 4. 今すぐできるLLMO実践チェックリスト

「理屈は分かった。では何をすればいい?」
Tavilyのリサーチレポートとの私自身の分析をもとに、初心者でも今すぐ着手できる施策を優先度順にまとめました。
### コンテンツ対策(まずここから)
**1. コンテンツをFAQ形式で整理する**
「Q: LLMOとは何ですか? A: LLMOとは...」という形式で情報を整理すると、AIが「この質問への回答」として抽出しやすくなります。既存の記事のリライトから始めると効果的です。
**2. 短く完結した「回答段落」を作る**
1段落で完結する40〜60語程度の「Atomic Answer」を各セクションに配置しましょう。AIは長い文章から要点を抜き出すより、最初から完結した短い回答段落を引用する傾向があります。
**3. 著者情報・専門性を明記する(E-E-A-T)**
記事の著者名、肩書き、専門領域を明記することで、AIが「信頼できる情報源」と判断しやすくなります。医療・法律・金融など専門性が求められる分野では特に重要です。
**4. 定期的にコンテンツを更新する**
AIは新鮮な情報を優先的に参照する傾向があります。記事の更新日時を明記し、定期的に最新情報に更新しましょう。
### 技術・設定(次のステップ)
**5. 構造化データ(JSON-LD)を実装する**
`FAQPage`、`Article`、`Product`などのschema.orgのマークアップをJSON-LDで実装すると、著者・公開日・商品情報といった対応関係が機械可読になります。
**優先度は「最初にやること」ではありませんが、「やらなくていいもの」でもありません。** ここで多い誤読が、Googleの公式見解を「Googleは構造化データを使っていない」と受け取ってしまうことです。Googleが言っているのは「**AI OverviewsやAI Modeに出るために追加の要件はなく、特別なschema.orgの構造化データを足す必要もない**」ということで、これは**対象になるための条件**の話です。内部で参照していないという意味ではありません。
そのうえで、プラットフォームごとの扱いは次のように分かれます。
| プラットフォーム | 構造化データの扱い |
|---|---|
| Bing / Copilot | **公式に利用を明言。** MicrosoftのFabrice Canel氏(Principal Product Manager, Bing)がSMX Munichで「schemaはMicrosoftのLLMがコンテンツを理解する助けになる」と確認 |
| Google AI Overviews / AI Mode | 公式ドキュメントは「AI機能に出るための**追加要件・特別なschemaは不要**」。ただし不要=未使用ではない。Googleの構造化データ担当者が「fanout時にモデルへ渡すコンテキストとして使っている」と述べたとする二次報告(イベント参加者による記録。Googleの一次資料ではない)もある |
| Gemini | ある公開検証(1つのSaaSサイトを対象に2025年12月〜2026年3月に実施)では、7プラットフォーム中schemaの直接取得に成功したのは**Geminiのみ**だった |
| ChatGPT / Perplexity | 同検証では直接取得に失敗。ただし別の検証では、ページのHTML全体をトークン化する経路で**JSON-LDの中身がテキストとして読まれている**ことが示されている |
最後の行は軽視できません。別の公開検証では、可視コンテンツには一切書かれておらず、しかも意図的に壊した**JSON-LDの中にだけ記載された架空の住所を、ChatGPTとPerplexityの両方が回答として出力**しました。JSON-LDが読まれるかどうかは取得経路やクローラーによって変わりますが、**読まれる経路が現に存在する以上、誤った内容を書けばそのまま誤答の原因になり得る**ということです。
つまり実務上の結論はこうなります。**「AI引用を増やす施策」としては期待しない。ただし実装するなら内容は正確に保つ。** 現時点で裏付けがあるのは、リッチリザルトなど従来の検索結果での見え方と、Bing/Copilotでの理解の補助です。なおGoogleは `HowTo` のリッチリザルトを2023年に、`FAQPage` のリッチリザルトを2026年5月に廃止しています([FAQPage](https://developers.google.com/search/updates#removing-faq-rich-result))。リッチリザルト目的で残っているのは `Article`・`BreadcrumbList` などです(`Product` は商品ページ、`Review` は対象タイプに対する実際のレビュー・評価があるページに限られ、一般的な記事には使えません)。クローラー確認やコンテンツ整備を終えたあとの工程として扱ってください。
> **【2026年8月追記】** Googleは「AI OverviewsやAI Modeに出るために特別なschema.orgの構造化データを追加する必要はない」と公式に明言しています。schemaを追加した対照実験でも、AI Mode(+2.4%)とChatGPT(+2.2%)の変化はノイズと区別できず、引用の増加は確認されませんでした(AI Overviews は −4.6% で有意だが小さく、他要因の可能性あり)。
> なお同実験の対象は、実験前からAI Overviewsに100回以上引用されていたページに限られます。
> FAQPageが付くページは元々Q&Aとして整理されていることが多く、それが相関の数値に現れている可能性があります。ただしこの実験が検証したのはJSON-LDの追加であって、Q&A構成そのものの効果は測っていません。詳細は「[「FAQスキーマで引用率3.2倍」は本当か — 自社の評価基準から未検証の数値を削除した話](/blog/faq-schema-ai-citation-myth-2026/)」で検証しています。
**6. エンティティ情報を統一する**
社名、住所、著者名などを全ページで一貫した表記にし、可能であれば`sameAs`プロパティでWikipediaやLinkedInなどの外部ページとの関連を示しましょう。
**7. llms.txtをサイトルートに設置する**
`llms.txt`は、AIクローラー向けにサイトの重要ページやコンテンツの概要を伝えるためのファイルです。robots.txtのAI版のようなもので、まだ普及途上ですが設置のコストが低く試す価値があります。
> **注意**: llms.txtの効果は2026年2月時点でまだ立証されていないとの報告もあります。他の施策と並行して取り組むのが賢明です。
>
> **【2026年8月追記】** その後Googleは公式に「Google Searchでは使わない」と明言しました。一方でAnthropicなどが自社ドキュメントで公開しており、AIエージェント用途では実際に使われています。
> 検索での引用とエージェントへの提供は目的が違うため、分けて判断してください。詳細は「[「FAQスキーマで引用率3.2倍」は本当か — 自社の評価基準から未検証の数値を削除した話](/blog/faq-schema-ai-citation-myth-2026/)」で整理しています。
AIがあなたのサイトをどう認識しているか気になる方は、LinkSurgeの[GEO分析ツール](https://linksurge.jp/geo)でChatGPT・Gemini・Perplexityでの引用状況を確認できます。
> 参考・引用:
> [Answer Engine Optimization (AEO): The 2026 Guide - LLMRefs](https://llmrefs.com/answer-engine-optimization)
> [What Is LLM Optimization? Key Benefits & Definitions - Conductor](https://www.conductor.com/academy/llm-optimization/)
> [AI features and your website - Google Search Central](https://developers.google.com/search/docs/appearance/ai-features)(AI機能に追加要件・特別なschemaは不要とするGoogle公式ドキュメント)
> [Microsoft Bing/Copilot use schema for its LLMs - Search Engine Land](https://searchengineland.com/microsoft-bing-copilot-use-schema-for-its-llms-453455)(Bing/Copilotがschemaを利用していることの公式確認)
> [Schema Markup and AI Search: What a 3-Month Study Revealed - Otterly.AI](https://otterly.ai/blog/schema-markup-real-impact-ai-search/)(1サイトを対象に2025年12月〜2026年3月に実施された7プラットフォームの取得検証。成功したのはGeminiのみ)
> [The Three Lives of Schema Markup - Suganthan Mohanadasan](https://suganthan.com/blog/three-lives-of-schema-markup/)(LLMがJSON-LDをテキストとして扱う仕組みの整理)
AI検索全般の最新動向については[生成AI検索がSEOを変える:AI Overviews・AI Modeの最新動向と7つの実践対策](/blog/ai-search-seo-japan-2026/)も参考にしてください。
---
## 5. LLMOの効果を測定する方法
LLMOを実施したあと、「本当に効果が出ているのか」をどう確認すればいいでしょうか?従来のSEOとは異なり、LLMOは専用の指標で測る必要があります。
### 主要なKPI
**AI引用数・引用頻度**
ChatGPT、Gemini、Perplexityなどで自社ドメインやブランド名がどれだけ言及・引用されているかを定期的にモニタリングします。
**AI由来のトラフィック**
Googleアナリティクスのリファラーデータでai.google.com、chatgpt.com、perplexity.aiからのアクセス数を確認します。
**AI経由のコンバージョン率(CVR)**
調査によると、AI検索経由で訪問したユーザーは従来の検索経由ユーザーよりコンバージョン率が高い傾向があります。AI由来セグメントのCVRを別途測定してみると興味深い結果が出るかもしれません。
**ブランド表示・推薦率**
「〇〇(自社の商品・サービス名)でおすすめは?」とAIに質問したとき、自社が推薦されるかどうかを定期的に確認します。
LinkSurgeの[LLMメンション分析](/geo/dashboard)では、主要AIエンジンでの自社ブランドの引用状況を定量的に把握できます。
> 参考・引用:
> [LLM Optimization vs. Traditional SEO: Key Difference - ResultFirst](https://www.resultfirst.com/blog/ai-seo/llm-optimization-vs-traditional-seo/)
---
こうした最適化の指針が実際のデータで裏付けられるかを検証した記録が「[AI検索は記事のどこを引用するのか](/blog/ai-citation-block-position-research-2026/)」です。よく言われる「冒頭に結論を置け」がどこまで正しいのかを、実引用277件で確かめています。
---
## よくある質問(FAQ)
### LLMOとGEOは同じものですか?
ほぼ同じ概念です。GEO(Generative Engine Optimization)は英語圏で一般的な呼称で、LLMO(Large Language Model Optimization)は日本市場でよく使われます。どちらも「生成AIに引用されるための最適化」を指しますが、強調点の差があります。GEOは複数の生成エンジン全体への最適化を、LLMOはLLM(大規模言語モデル)という技術層への最適化を意識した呼び方です。
### 既存のSEOを止めてLLMOに移行すべきですか?
いいえ、SEOを止める必要はありません。Googleの検索経由のトラフィックはまだ多数を占めており、SEOの効果は現在も続いています。LLMOはSEOに「加えて」行うものです。多くのLLMO施策(良質なコンテンツ、構造化データ、E-E-A-T強化)は、実はSEOにも良い影響を与えます。
### llms.txtは必ず設置すべきですか?
llms.txtは設置コストが低いので、試してみる価値はあります。ただし、2026年時点でllms.txtを設置することでAI引用が増えるという科学的な立証はまだされていません。必須施策というよりは「将来への投資」として位置づけるのが現実的です。優先度は、狙うサービスのクローラー(Googleなら `Googlebot`、ChatGPTの検索なら `OAI-SearchBot`)が通っているかの確認が上です。コンテンツのFAQ化は取り組む価値がありますが、引用が増えるという効果自体は検証されていない点にご留意ください。
### 構造化データ(JSON-LD)は結局必要ですか?
**AI引用を増やす目的なら必須ではありません。** Googleは「AI OverviewsやAI Modeに出るために追加の要件はなく、特別なschema.orgの構造化データを足す必要もない」と公式に明言しており、schemaを追加した対照実験でもAI引用の増加は確認されていません。ただしこれは「出るための追加要件ではない」という意味であって、Googleが内部で参照していないという意味ではない点に注意してください。そのうえで、別の用途では有用です。MicrosoftはBing/Copilotのモデルがschemaを利用していることを公式に認めており、リッチリザルトなど従来の検索結果での見え方にも効きます(ただし `FAQPage` と `HowTo` のリッチリザルトは廃止済みです)。また1サイトを対象にした公開検証では、7プラットフォーム中Geminiのみがschemaの直接取得に成功しました。ChatGPTやPerplexityはこの検証では直接取得に失敗していますが、別の検証ではJSON-LDの中身がテキストとして読まれることが示されており、読まれるかどうかは取得経路によって変わります。読まれる経路が存在する以上、記述の正確さ自体が意味を持ちます。まとめると、**優先度は高くないが、やる価値はある**。クローラー確認やコンテンツ整備を終えたあとに、可視コンテンツと矛盾しない正確な内容で実装するのが現実的です。
### 費用はどのくらいかかりますか?
基本的なLLMO施策(コンテンツ整備、構造化データ、llms.txt設置)は特別な費用はかかりません。ツール類もオープンソースやフリーミアムのものが多数あります。費用がかかるのは、本格的なRAGシステムの構築やAI引用のモニタリングツールを使う場合です。
### 効果が出るまでどのくらいかかりますか?
AIの学習データはリアルタイムでは更新されないため、施策の効果が反映されるまで数週間から数か月かかる場合があります。ただし、Perplexityのようにリアルタイム検索を行うAIでは、コンテンツ更新後比較的すぐに影響が出ることもあります。
---
## まとめ:LLMOは「AIと共存するWebコンテンツ戦略」
生成AIが検索行動を変えている今、「Googleで上位表示される」だけが目標では十分ではなくなってきています。ChatGPT、Gemini、Perplexityといった生成AIに自社コンテンツが引用・参照されることが、新しい時代のブランド露出の形になっています。
とはいえ、LLMOは難しいものではありません。良質で構造化されたコンテンツを作り、著者情報・エンティティを整備し、構造化データを実装する——これはSEOで当たり前にやってきたことの延長線上にあります。
まず始めるなら、**狙うサービスのクローラーが通っているかの確認**から取り組んでください。ここは必要条件なので、最初に潰す価値があります。
クローラーはサービスごとに違います。Google AI Overviews / AI Mode なら `Googlebot`、ChatGPTの検索なら `OAI-SearchBot`、Perplexity なら `PerplexityBot`、Claude なら `Claude-SearchBot` です。**`GPTBot` はモデル学習用、`Google-Extended` は Gemini Apps 向けで、いずれも検索での引用には効きません。** また通すことは読み取ってもらうための必要条件であって、引用を保証するものではありません。
そのうえで、**既存記事のFAQ化**は取り組む価値のある候補です。ただし「FAQ化すると引用が増える」という効果は、現時点で検証されていません(対照実験が測ったのはJSON-LDの追加であり、Q&A構成そのものの効果は測っていない)。自社で効果を確かめながら進めてください。
**JSON-LDの実装は、この2つの後で構いません。ただし「やらない」ではなく「後回し」です。** Bing/Copilotは公式に利用を明言しており、公開検証ではGeminiが取得に成功しています。JSON-LDが読まれるかどうかは取得経路によって変わりますが、読まれる経路は現に存在します。実装するときは、可視コンテンツと食い違わない正確な内容にしてください(2026-08 更新)。
LinkSurgeでは[GEO分析ツール](https://linksurge.jp/geo)や[LLMメンション分析](/geo/dashboard)を通じて、生成AI時代のブランド露出を包括的に分析・最適化するためのツールを提供しています。ぜひ活用してみてください。
---
## エンティティ権威がAI検索可視性を決める:ナレッジグラフ時代の見えない競争優位
> URL: https://linksurge.jp/blog/entity-authority-ai-search-2026/
> Date: 2026-03-17 | Category: AIO | Author: 緒方亜朗
> Tags: エンティティSEO, AI検索, ナレッジグラフ, GEO, AI Overview, Wikidata, 構造化データ
## この記事の結論:エンティティとして定義されることが、AI時代の基盤になった
AI検索の普及を追いかけながら気づいたことがある。「どのページが上位表示されるか」という問いが、徐々に意味を失ってきているのだ。AIが引用するのはページではなく、エンティティ——つまりブランドや組織そのものだ。以下の4つが、私が調査して見えてきた本質的な変化です。
1. **AIの最初の判断は「信頼できるエンティティか」** — ChatGPT・Perplexity・Google AIはブランドを引用する前に、知識グラフ上でそのエンティティが定義されているかを確認する。Wikidataやナレッジグラフに存在しないブランドは、優れたコンテンツがあっても引用候補に入りにくい
2. **ナレッジグラフ・Wikidata・権威メディアが「エンティティスコア」を形成する** — 単独のWebページではなく、外部の信頼できるソースが一貫してブランドを言及している状態が、AIのエンティティ評価を高める核心となる
3. **コンテンツ量より「エンティティとして定義されているか」が優先される** — 記事を100本書いても、エンティティが曖昧なままでは引用候補にならない。逆に、少ないコンテンツでもエンティティが明確に定義されていれば、AIは積極的に引用する
4. **「Share of Model」が新たなKPI** — 検索ランキングの代わりに、AIがどれだけ自社ブランドを回答に含めるかを測る指標が重要性を増している。被リンクよりも、引用可能性が権威のシグナルになった
以下では、各テーマを順に掘り下げていきます。要点を動画でも解説しています。
{{youtube:Xoq2jKmoorw|記事を100本書いてもAIに引用されない理由|エンティティ権威という新しい競争軸}}
---
## 1. AIはページを読む前に、エンティティを確認する

Googleがナレッジグラフを導入してから10年以上が経つ。その間、検索エンジンの基本単位は「文字列」から「もの(thing)」へと進化してきた。そして今、AI検索の時代になって、さらに次のフェーズに入っている。
率直に言って、これは「検索最適化」の概念が根本から変わる話だ。
従来のSEOでは、キーワードを含むページを作り、被リンクを集め、検索結果で上位に表示させることが目標だった。しかしChatGPTやPerplexityが質問に答えるとき、彼らは検索インデックスをスキャンする前に、まず「このエンティティについて何を知っているか」を確認する。ナレッジグラフへの参照が先に来るのだ。
### なぜナレッジグラフが「信頼の入口」になるのか
AIモデルには計算資源の上限がある。Search Engine Landが指摘する「Comprehension Budget(理解予算)」という概念が面白い。構造化されていない情報、一貫性のないデータは、AIが処理するコストを増やす。逆に、Schema.orgによって構造化されたデータは「ナレッジグラフの高速参照」を可能にし、AIにとって引用コストが下がる。
ブランドがWikidataに登録されていると、AIはそのエンティティの属性(業種・本社所在地・創業年・関連人物)をワンアクセスで取得できる。その速さと正確さが、引用候補に入りやすい「構造的優位」を生む。
> 参考・引用:
> [Entity Authority and AI Search Visibility - Search Engine Land](https://searchengineland.com/entity-authority-ai-search-visibility-471619)
> [Google's Knowledge Graph and Entity Understanding - Google Blog](https://blog.google/products/search/introducing-knowledge-graph-things-not/)
---
## 2. エンティティスコアを形成する3つの柱

私が調べたところ、AI検索においてエンティティの信頼性は3つのソースから形成されることがわかった。
### 柱1:ナレッジグラフとWikidata
Googleナレッジグラフに掲載されているブランドは、AI Overviewsで引用される確率が大きく上がる。Wikidataはそのナレッジグラフにデータを供給するオープンなソースで、誰でも編集できる。
注目すべきは、WikidataやWikipediaへの登録が「自己申告」ではなく「外部からの検証」として機能することだ。AIにとって、Wikidataのエントリは「この組織は実在し、社会的に認知されている」という客観的な証拠になる。
### 柱2:権威あるメディアでの一貫した言及
Forbes、TechCrunch、業界特化メディアといった権威あるソースが、一貫してブランド名を言及している状態は強力なシグナルになる。ここで大事なのは「一貫性」だ。
AIは同一エンティティについて複数のソースを照合する。「LinkSurge」という名前が、複数の権威メディアで同じ意味・同じ属性で言及されていれば、エンティティの信頼性スコアが上がる。逆に、サイトによってブランド名や説明が微妙にズレていると(「エンティティドリフト」と呼ばれる現象)、AIの評価が下がるリスクがある。
### 柱3:Schema.orgによる機械可読な自己定義
自社サイト上でのSchema.orgマークアップも重要な柱だ。Organization、Person、Product、FAQPageといったスキーマタイプを深くネストして実装することで、AIがコンテンツを解釈するコストを下げる「理解補助(Comprehension Subsidy)」を提供できる。
ただし、構造化データを足せばAI引用が増えるという因果は確認されていない。schemaを追加した対照実験では引用の増加は出ておらず、Googleも「生成AI検索に構造化データは必須ではない」と明言している(内部で参照していないという意味ではない)。ここでの狙いは引用数を直接増やすことではなく、エンティティの関係をあいまいさなく伝えることにある。
[LinkSurge](https://linksurge.jp/)のAI Overview分析では、どのページが引用されているか・どの構造化データが有効かをキーワード単位で確認できます。
> 参考・引用:
> [Schema.org Full Hierarchy - Schema.org](https://schema.org/docs/full.html)
> [Wikidata Data Model - Wikidata](https://www.wikidata.org/wiki/Wikidata:Introduction)
---
## 3. コンテンツ量より「定義されているか」が優先される理由

ここが、多くのSEO担当者にとって最もカウンターインテュイティブな部分だと思う。
「コンテンツを増やせば引用されやすくなる」という発想は、従来のSEOのロジックだ。しかしAI検索においては、コンテンツの量よりもエンティティとしての明確さが先に来る。
### エンティティドリフトが引き起こすリスク
データを見ると、興味深いパターンが浮かぶ。大量のコンテンツを持ちながらAIに引用されにくい企業の多くは、「エンティティドリフト」の状態にある。
エンティティドリフトとは、同一ブランドの情報が複数のソースで矛盾している状態を指す。公式サイトでは「AIチャット分析ツール」と名乗り、LinkedInでは「マーケティング自動化ソリューション」、紹介記事では「SEOプラットフォーム」と呼ばれている——そんな状態では、AIはどの定義を採用すべきか判断できない。
### エンティティを「定義する」とは何か
具体的には以下の整合が必要だ。
- **ブランド名**: すべてのプラットフォームで同一表記を使用する
- **業種・カテゴリ**: Schema.orgのtype、Wikidataのinstance of、Google Businessのカテゴリを一致させる
- **説明文**: 公式サイト・Wikidata・プレスリリースで一貫したブランドの説明を使う
- **関連エンティティ**: 創業者・本社・主要製品が各ソースで同じ属性を持つ
少ないコンテンツでも、これらが整合していれば、AIはそのエンティティを「信頼できる参照元」として認識する。これが「エンティティとして定義されることの力」だ。
オフサイトSEOとエンティティ権威の関係については「[オフサイトSEO×GEO:AI時代のブランド権威を外部評価で高める戦略](/blog/offsite-seo-geo-2026/)」でも詳しく解説しています。
> 参考・引用:
> [How AI Search Engines Evaluate Brand Authority - Search Engine Journal](https://www.searchenginejournal.com/)
> [Wikidata Entity Disambiguation Guide - Wikimedia Foundation](https://www.wikimedia.org/)
---
## 4. 「Share of Model」:AI時代のブランド新KPI

Search Engine Landの記事が提唱する「Share of Model(SOM)」という指標が面白い。定義は「AIの生成回答にブランドが含まれる割合」だ。
従来のSEOKPIと比較するとその違いは明確だ。
| 指標 | 従来のSEO | AI検索時代 |
|------|-----------|-----------|
| 主KPI | 検索順位・オーガニックトラフィック | Share of Model(AI引用率) |
| 権威シグナル | 被リンク数・ドメインオーソリティ | ナレッジグラフでのエンティティ定義 |
| 評価の基本単位 | ページ・URL | エンティティ(ブランド・組織) |
| コンテンツの役割 | ランキング要因 | エンティティの補強証拠 |
| 外部評価 | リンク獲得 | 権威メディアでの言及・Wikidata掲載 |
### SOMを測定・改善するためのアプローチ
データと理論を並べるだけでは説得力に欠けるので、実際の改善フローを見てみましょう。
1. **ベースライン測定**: 主要な競合キーワードでChatGPT・Perplexity・Google AIに質問し、自社ブランドが言及される頻度を記録する
2. **エンティティ監査**: Wikidataに自社エントリがあるか、Schema.orgマークアップが正確か、権威メディアでの言及が一貫しているかをチェックする
3. **整合作業**: エンティティドリフトが検出された場合、プラットフォームをまたいで情報を統一する
4. **測定サイクル**: 月次でSOMを計測し、改善のPDCAを回す
[LinkSurge](https://linksurge.jp/)のGEO分析機能では、複数のAIプラットフォームにまたがるブランド引用状況を可視化できます。
> 参考・引用:
> [Share of Model: The New KPI for AI Search - Search Engine Land](https://searchengineland.com/entity-authority-ai-search-visibility-471619)
> [Measuring AI Search Visibility - Moz Blog](https://moz.com/)
---
## 5. エージェンティックWebへの備え:機械から呼び出されるエンティティへ

最後に、少し先の話をしておきたい。Search Engine Landの記事が「エージェンティックWeb」と呼ぶ段階だ。
AIエージェントが人間の代わりに情報収集・予約・購買を行う世界では、ブランドは「人間が読むコンテンツ」だけでなく「機械から呼び出されるAPI」として機能する必要がある。Schema.orgには`BuyAction`や`ReserveAction`といったスキーマタイプがあり、これを実装することでAIエージェントがブランドの機能を直接実行できるようになる。
驚いたのは、このレベルの実装をすでに進めているブランドが存在することだ。彼らにとってエンティティ権威は「検索順位」の問題ではなく、「AIエコシステム内での役割」の問題になっている。
{{linksurge-card}}
GEO(生成AI最適化)の全体像については「[GEO完全ガイド:AI検索時代に選ばれるサイトを作る方法](/blog/geo-guide-japan-2026/)」も合わせてご覧ください。
> 参考・引用:
> [Agentic AI and Schema Actions - Schema.org](https://schema.org/)
> [The Future of Agentic Search - Search Engine Journal](https://www.searchenginejournal.com/)
---
## よくある質問(FAQ)
### エンティティ権威とドメインオーソリティは何が違うのですか?
ドメインオーソリティは被リンクの質・量に基づくWebページの評価指標で、従来の検索エンジン向けに機能してきた。エンティティ権威は、ナレッジグラフ・Wikidata・権威メディアでのブランド言及に基づく概念で、AIがエンティティを「信頼できるか」判断するために使う。両者は重複する部分もあるが、エンティティ権威のほうがAI検索時代のKPIに直結する指標だ。
### 中小企業でもWikidataやナレッジグラフに登録できますか?
可能です。WikidataはWikimediaの公開プロジェクトで、「特筆性」の基準を満たせば誰でも登録できます。業界メディアでの言及が数件あり、組織として実在していることが確認できれば、多くの場合で登録要件を満たします。Googleナレッジグラフへの掲載は直接申請はできませんが、WikidataやWikipediaへの登録、Schema.orgの整備が間接的に機能します。
### エンティティドリフトを修正するにはどうすればいいですか?
まず自社ブランド名でGoogle・Wikidata・LinkedInを検索し、業種・説明・属性がどう記述されているか一覧化します。矛盾があれば、自社コントロール下にあるページ(公式サイト・Schema.orgマークアップ)から統一し、次にWikidataのエントリを修正します。権威メディアでの言及はコントロールしにくいため、プレスリリースや寄稿で一貫した情報を継続的に発信することが有効です。
### Schema.orgのどのタイプから実装を始めればいいですか?
優先順位は次の通りです。まず`Organization`(または`LocalBusiness`)で基本情報を定義し、次に`Person`で創業者・主要メンバーを定義します。コンテンツが多い場合は`Article`・`FAQPage`・`HowTo`を追加します。最終的に`BreadcrumbList`でサイト構造を示すと、AI・検索エンジン双方への可読性が上がります。
### Share of Model(SOM)を測定するツールはありますか?
現時点では標準化された測定ツールは少ないですが、実用的な方法があります。自社ブランドのコアキーワードを10〜20個選び、ChatGPT・Perplexity・Google AI Overviewsに週次で同一質問をして、ブランドが言及される回数を記録します。[LinkSurge](https://linksurge.jp/)のAI Overview分析では、Google AI Overviewsでの引用状況をキーワード単位で自動追跡できます。
---
## まとめ:エンティティを定義することから始める
コンテンツマーケティングへの投資を増やす前に、まず問うべきことがある。「自社ブランドはAIにとって、定義されたエンティティとして存在しているか?」
取るべきアクションは明確だ。Wikidataの自社エントリを確認・整備し、Schema.orgのOrganizationマークアップを実装し、権威メディアへの掲載を通じてエンティティを外部から強化する。この3つが揃って初めて、コンテンツ投資がAI引用という形で結実する。
検索順位からShare of Modelへ——KPIの変化は、ブランドが「読まれるもの」から「参照されるもの」へ変わったことの表れだ。
構造化データだけで実際にAI引用を獲得できるかを検証した衝撃的な実験については「[見えないサイトがAI検索1位に — 構造化データだけでPerplexityに引用された衝撃の実験](/blog/phantom-authority-invisible-website-ai-citation-2026/)」をご覧ください。
LinkSurgeの[AI Overview分析機能](https://linksurge.jp/aio-v5)では、自社ブランドのAI引用状況をキーワード別にリアルタイムで追跡できます。エンティティ権威の改善サイクルをデータで回していきましょう。
---
## 【2026年最新】SEO対策の始め方ガイド:初心者でもわかるAI時代の検索最適化
> URL: https://linksurge.jp/blog/seo-latest-guide-2026/
> Date: 2026-02-25 | Category: SEO | Author: 緒方亜朗
> Tags: SEO対策, SEO 最新, 初心者, AI検索, クエリファンアウト, E-E-A-T, 2026年
## この記事の結論:2026年のSEO対策で初心者が押さえるべき5つのポイント
SEO対策を始めようとして「何から手をつければいいの?」と迷った方、安心してください。私が2026年の最新動向を調べて見えてきたのは、**基本を正しく押さえれば初心者でも十分に戦える**ということです。以下の5つが、今すぐ取り組むべき要点です。
1. **サイトの技術的な土台を整える** — ページの表示速度(Core Web Vitals)を改善する。2026年のGoogleは「中身が良い」だけでは評価しない。構造化データ(JSON-LD)はリッチリザルト等の従来SEO用途で有用だが、AI引用を増やす効果は確認されていない
2. **AIに「引用したい」と思わせるコンテンツを書く** — 見出しを質問形式にし、40〜60語で端的に回答する「Atomic Answers」形式が有効。AIは長い文章の中から答えを切り出すより、すでに整理された回答を引用する方を好む
3. **E-E-A-T(経験・専門性・権威性・信頼性)を意識する** — 誰が書いたか、その人にどんな経験があるかをGoogleもAIも見ている。著者プロフィールの整備と一次情報の提供が出発点になる
4. **クエリファンアウトに対応する** — Google AI Modeでは、ユーザーの1つの質問が8〜12の小さな検索に自動分解される。この仕組みを理解して、関連トピックを網羅するコンテンツ群を作ることが2026年のSEOの新常識になりつつある
5. **測定→改善のサイクルを回す** — Google Search ConsoleとGA4は無料で使える。データなしの「なんとなくSEO」では成果は出ない。まず計測環境を整え、月1回の振り返りから始める
以下では、各ポイントを初心者向けに噛み砕いて解説していきます。
---
## 1. そもそもSEO対策とは? — 2026年版の定義

SEO(Search Engine Optimization)とは、GoogleやBingなどの検索エンジンで自分のサイトを見つけてもらいやすくする施策の総称です。
ただし、2026年のSEOは数年前とは様相が大きく変わっています。従来は「検索結果の10本の青いリンク」で上位を取ることがゴールでした。しかし現在は、Google AI Overviews(AIによる検索結果の要約)やChatGPT、Perplexityといった**AI検索エンジン**が台頭し、「AIに情報源として引用される」ことが新たな競争軸になっています。
### 従来のSEOと2026年のSEOの違い
- **従来**: 「検索順位を上げる」→ クリックしてもらう → サイトに来てもらう
- **2026年**: 「検索順位を上げる」+「AIに引用される」→ ブランド認知 + サイト訪問
つまり、2026年のSEO対策は「検索エンジン最適化」だけでなく、「AI検索エンジン最適化」(GEO: Generative Engine Optimization)も含めた、より広い概念になっています。
初心者にとって大事なのは、「従来のSEOの基本が無意味になった」わけではないということ。むしろ基本ができていないサイトはAI引用の土俵にも上がれません。基本を固めつつ、AI時代の新しい要素を足していく——これが2026年の正しいアプローチです。
> 参考・引用:
> [Google AI Overviews - Google Search Central](https://developers.google.com/search/docs/appearance/ai-overviews)
> [SEO Starter Guide - Google for Developers](https://developers.google.com/search/docs/fundamentals/seo-starter-guide)
---
## 2. AI検索の台頭 — 検索のルールが変わった

率直に言って、2026年の検索結果は2〜3年前とは別物です。Google検索で何かを調べると、ページ上部にAI Overviewsが表示され、AIが複数のサイトから情報を集約して要約を生成します。
### ゼロクリック検索の急増
調査データによると、AI Modeではなんと**93%がゼロクリック検索**(検索結果をクリックせずに完結する検索)だったという報告があります。AIが回答を生成してくれるので、ユーザーはわざわざサイトを訪問しなくなりつつあるわけです。
これは怖い話のように聞こえますが、見方を変えれば**AIに引用されること自体がブランド露出になる**ということ。ユーザーが直接訪問しなくても、AIの回答の中にあなたのサイト名が出典として表示されれば認知度は上がります。
### 初心者が今すぐ意識すべきこと
- **検索意図を正確に捉える**: ユーザーが本当に知りたいことに直接答える
- **結論を先に書く**: AIは記事の冒頭から情報を抽出する傾向がある
- **質問形式の見出しを使う**: 「〜とは?」「〜のやり方は?」のような見出しはAIが回答を抜き出しやすい
AI検索の詳しい影響と対策は「[生成AI検索がSEOを変える:7つの実践対策](/blog/ai-search-seo-japan-2026/)」で詳しく解説しています。
> 参考・引用:
> [AI Mode Search Study - Authoritas](https://www.authoritas.com/blog/ai-mode-search-study)
> [Google AI Mode Help - Google Support](https://support.google.com/websearch/answer/15523601)
---
## 3. 技術SEOの基本 — サイトの土台を固める

「技術SEO」と聞くとプログラマーにしかできない難しい話に感じるかもしれません。でも実際には、初心者でも取り組めるポイントがいくつもあります。
### Core Web Vitals — ページ体験の通信簿
GoogleはCore Web Vitalsという指標で、ユーザーの「ページ体験」を数値化しています。2026年の基準値はこちらです。
| 指標 | 意味 | 合格ライン |
|------|------|-----------|
| LCP(Largest Contentful Paint) | メインコンテンツの表示速度 | 2.5秒以内 |
| INP(Interaction to Next Paint) | 操作への反応速度 | 200ms以内 |
| CLS(Cumulative Layout Shift) | レイアウトのズレ | 0.1以下 |
INPは2024年3月にFID(First Input Delay)から置き換わった新しい指標です。ページ上のすべての操作(クリック・タップ・キー入力)の応答速度を測定し、200ms以下であれば「Good」と判定されます。
### 構造化データ — AIへの「名刺」
構造化データ(JSON-LD形式)は、Googleやその他のAIにサイトの内容を機械的に伝える仕組みです。たとえばFAQの構造化データを実装すると、質問と回答の対応関係が機械可読になります。
> **【2026年8月追記】** ただし、構造化データを追加してAI引用が増えるという効果は確認されていません。Googleは「生成AI検索に構造化データは必須ではなく、追加すべき特別なschema.orgマークアップも存在しない」と公式に明言しています(これは出るための要件の話で、内部で参照していないという意味ではありません)。リッチリザルト等の従来SEO用途では引き続き有用です。なおGoogleは `HowTo` のリッチリザルトを2023年に、`FAQPage` のリッチリザルトを2026年5月に廃止しています([FAQPage](https://developers.google.com/search/updates#removing-faq-rich-result))。リッチリザルト目的で残っているのは `Article`・`BreadcrumbList` などです(`Product` は商品ページ、`Review` は対象タイプに対する実際のレビュー・評価があるページに限られ、一般的な記事には使えません)。詳細は「[「FAQスキーマで引用率3.2倍」は本当か](/blog/faq-schema-ai-citation-myth-2026/)」をご覧ください。
初心者が最初に実装すべき構造化データは以下の3つです。
- **Article**: 記事の著者、公開日、更新日をAIに伝える
- **FAQ**: よくある質問と回答の対応関係を機械可読にする
- **BreadcrumbList**: サイト構造をAIに伝え、検索結果にパンくずを表示
### モバイルファースト
Googleはモバイル版のページを基準にインデックスしています。スマートフォンでの表示を最優先に設計してください。レスポンシブデザインが基本です。
技術SEO・コンテンツSEO・リンク構築の包括的な戦略については「[SEO対策完全ガイド](/blog/seo-guide-2026/)」をご覧ください。
サイトマップの具体的なセグメント化戦略やクロール予算管理については「[XMLサイトマップ戦略2026](/blog/xml-sitemap-strategy-2026/)」で詳しく解説しています。
> 参考・引用:
> [Core Web Vitals Overview - web.dev](https://web.dev/articles/vitals)
> [Structured Data - Google Search Central](https://developers.google.com/search/docs/appearance/structured-data/intro-structured-data)
> [INP Metric - web.dev](https://web.dev/articles/inp)
---
## 4. コンテンツSEO — AIに引用される記事の書き方

実際に試してみると、AI検索エンジンが引用するコンテンツには明確なパターンがあります。
### E-E-A-T — 信頼されるコンテンツの条件
E-E-A-Tは Experience(経験)、Expertise(専門性)、Authoritativeness(権威性)、Trustworthiness(信頼性)の略です。2025年12月のGoogleアップデートでこのシグナルが大幅に強化され、2026年2月のコアアップデートではAIコンテンツの品質検出も強化されました。
初心者が今すぐできるE-E-A-T対策はこちらです。
- **著者プロフィールを整備する**: 記事を書いた人の顔写真、肩書き、専門分野を明記する
- **一次情報を提供する**: 自分で調べたデータ、自分の体験、独自の視点を入れる
- **出典を明記する**: 参考にした情報源のリンクを記事内に記載する
- **定期的に更新する**: 古い情報は信頼性を損なう。少なくとも半年に1回は見直す
### Atomic Answers — AIが引用しやすい回答形式
面白いのは、AIが引用するコンテンツの44.2%が記事の冒頭3分の1から抽出されているというデータです。つまり、結論を先に書くだけで引用確率が上がります。
Atomic Answersとは、40〜60語程度で質問に端的に回答する文章スタイルです。
**例**:
> Core Web Vitalsは、ページの読み込み速度(LCP)、操作への応答性(INP)、視覚的な安定性(CLS)の3つの指標でユーザー体験を数値化するGoogleの基準です。2026年の合格ラインはLCP 2.5秒以内、INP 200ms以内、CLS 0.1以下とされています。
このように、質問に対して「それだけで完結する回答」を書くことで、AIが丸ごと引用しやすくなります。
### AIコンテンツの注意点
GoogleはAI生成コンテンツ自体を罰しているわけではありません。ただし、AIで大量生産された低品質コンテンツ——つまり独自性がなく、専門性が感じられず、ユーザーの役に立たない記事は2026年2月のコアアップデートで明確にターゲットになっています。
AIを下書きのアシスタントとして使い、自分の経験と専門知識を加えて仕上げる。これが2026年のコンテンツ制作の王道です。
> 参考・引用:
> [E-E-A-T and Quality Rater Guidelines - Google Search Central](https://developers.google.com/search/docs/fundamentals/creating-helpful-content)
> [February 2026 Discover update - Google Search Status Dashboard](https://status.search.google.com/incidents/mYbNTqV1ytDc2fA8hUz4)
---
{{linksurge-card}}
## 5. クエリファンアウト — AI検索の新常識を攻略する

ここまでの基本を押さえたところで、2026年のSEO対策で最も注目すべき新概念を紹介します。それが**クエリファンアウト**(Query Fan-Out)です。
### クエリファンアウトとは
Google AI Modeでは、ユーザーが1つの質問を入力すると、AIが内部で8〜12個の小さなサブクエリに自動分解し、それぞれを並列で検索します。この仕組みがクエリファンアウトです。
たとえば「初心者向けのSEO対策は?」という質問は、AIの内部で以下のように展開されます。
- 「SEO対策 基本 2026」
- 「SEO 初心者 始め方」
- 「Core Web Vitals 改善方法」
- 「E-E-A-T 対策 初心者」
- 「構造化データ 実装方法」
- 「SEO ツール 無料 おすすめ」
そしてAIはこれら全部の検索結果を統合して、1つの回答を生成します。
### なぜクエリファンアウトが重要なのか
驚いたのは、AI Modeでの引用元とGoogle AI Overviewsでの引用元の重複率がわずか**13.7%**しかないというデータです。つまり、従来の検索で上位に表示されているサイトが、AI検索でも引用されるとは限らない。
クエリファンアウトに対応するには、1つの記事だけでなく**関連トピックをカバーする記事群**(トピッククラスター)を構築することが重要です。メインとなるまとめ記事(ピラーページ)を中心に、個別トピックを深掘りする記事を内部リンクで繋げます。[トピッククラスターと内部リンク戦略の実践ガイド](/blog/topic-cluster-internal-linking-strategy/)では、5ステップの設計手順やリンクエクイティの集中方法を詳しく解説しています。
### 初心者向けの実践ステップ
1. **メインテーマを決める**: 例「SEO対策」
2. **関連する質問を洗い出す**: 「〜とは?」「〜のやり方は?」「〜のおすすめは?」
3. **質問ごとに記事を書く**: 各記事でAtomic Answersを意識
4. **まとめ記事からリンクする**: ピラーページから各記事にリンクを張る
5. **各記事からまとめ記事に戻す**: 双方向リンクでサイト全体の関連性を強化
クエリファンアウトの技術的な仕組みとGoogleの内部動作については「[クエリファンアウトとは?初心者向け解説](/blog/query-fan-out-guide-2026/)」で詳しく解説しています。AI Modeがどのようにサブクエリを生成し、どう結果を合成するかが図解付きでわかります。
> 参考・引用:
> [Query Fan-Out Architecture - Google DeepMind Research](https://deepmind.google/research/)
> [AI Search Citation Analysis - SparkToro](https://sparktoro.com/)
---
## 6. 初心者向け実践ロードマップ — 今日から始める3ステップ

ここまでの内容を落とし込みます。「全部やらなきゃ」と焦る必要はありません。以下の3ステップで段階的に進めていきましょう。
### ステップ1: 計測環境を整える(初日)
何も計測していないのは、地図なしで登山するようなものです。まず以下の2つを設定します。
- **Google Search Console**: サイトを登録し、検索パフォーマンスを確認できるようにする
- **Google Analytics 4(GA4)**: サイトへのアクセス状況を計測する
どちらも無料です。設定方法はGoogleの公式ドキュメントに手順が載っています。
### ステップ2: 技術的な土台を固める(1〜2週目)
- Core Web Vitalsの現状をPageSpeed Insightsで確認
- 画像の最適化(WebP形式、適切なサイズ)
- モバイル表示の確認と修正
- サイトマップ(sitemap.xml)の作成・送信
### ステップ3: コンテンツを改善・追加する(3週目〜)
- 既存記事のタイトルとメタディスクリプションを見直す
- 質問形式の見出しを取り入れる
- Atomic Answers形式で要点を整理する
- FAQ構造化データを追加する
- 関連記事を作成してトピッククラスターを構築
[LinkSurge](https://linksurge.jp/)のような分析ツールを使えば、AI Overviewsでの引用状況やキーワードごとのAI検索順位を確認できます。無料ツールで基本を固めた後、より詳細な分析が必要になったタイミングで導入を検討するのがおすすめです。
### やってはいけないこと
初心者がよくやる失敗も共有しておきます。
- **キーワードの詰め込み**: 不自然にキーワードを繰り返すのは逆効果
- **被リンクの購入**: Googleのガイドライン違反。発覚するとペナルティを受ける
- **AIで大量生産**: 独自性のないAI記事の量産は2026年のコアアップデートで明確にターゲット
- **更新を放置**: 古い情報のままだとE-E-A-Tの信頼性が低下する
> 参考・引用:
> [Google Search Console Help](https://support.google.com/webmasters/answer/9128668)
> [PageSpeed Insights - Google Developers](https://pagespeed.web.dev/)
---
## 7. SEO対策の最新トレンド — 2026年に注目すべき動き
最後に、2026年のSEO対策で特に注目すべき最新トレンドをまとめておきます。
### GEO(Generative Engine Optimization)の台頭
GEOとは、ChatGPT・Perplexity・Google AI Overviewsなどの生成AI検索エンジンで自社コンテンツが引用されるよう最適化する戦略です。従来のSEOが「検索順位」を追いかけるのに対し、GEOは「AIの回答に引用される確率」をKPIとします。
[LinkSurge](https://linksurge.jp/)では、主要なAI検索エンジンでの引用状況をリアルタイムで監視できるGEOモニター機能を提供しています。AI時代のブランド可視性を把握するための出発点として活用できます。
### マルチモーダルコンテンツの重要性
テキストだけでなく、画像・動画・図解を組み合わせたコンテンツがAIに引用されやすくなっています。特に画像のalt属性(代替テキスト)は、AIが画像の内容を理解する手がかりになるため必ず設定しましょう。
### ローカルSEOとAI検索
地域ビジネスにとっても変化があります。AI検索は「近くの○○」のような質問に対して、Googleビジネスプロフィールの情報を引用する頻度が増えています。地域ビジネスの方は、Googleビジネスプロフィールの情報を最新に保つことが引き続き重要です。
> 参考・引用:
> [GEO: Generative Engine Optimization - Agrawala et al.](https://arxiv.org/abs/2311.09735)
> [Google Business Profile Help](https://support.google.com/business/answer/6300665)
---
## よくある質問(FAQ)
### SEO対策は初心者でも独学でできますか?
はい、基本的なSEO対策は独学で十分に実践できます。Google Search ConsoleやPageSpeed Insightsなどの無料ツールと、Google公式のSEOスターターガイドを活用すれば、技術SEO・コンテンツSEO・構造化データの基本は独力で学べます。成果が出るまでには通常3〜6か月かかるため、焦らず継続することがカギです。
### クエリファンアウトに対応するには具体的に何をすればいいですか?
クエリファンアウトに対応する最も効果的な方法は、トピッククラスター構造を構築することです。メインテーマを扱うピラーページを1つ作り、そこから派生する個別トピックを深掘りする記事を5〜10本用意して相互リンクで繋げます。各記事では質問形式の見出しとAtomic Answers形式を使い、AIが部分的に引用しやすい構造にするのがポイントです。
### AI生成コンテンツはSEOに悪影響がありますか?
GoogleはAI生成コンテンツそのものを罰してはいません。問題になるのは、独自性がなく、専門知識の裏付けがない低品質なAIコンテンツの大量生産です。2026年2月のコアアップデートでは、こうした低品質AIコンテンツの検出精度が強化されました。AIを下書き支援に使い、自分の経験と専門知識を加えて仕上げるアプローチなら問題ありません。
### SEO対策の効果はどれくらいで出ますか?
一般的に、SEO対策の効果が検索順位に現れるまで3〜6か月かかります。技術的な改善(ページ速度、モバイル対応)は比較的早く反映されますが、コンテンツの評価やドメインの権威性は時間をかけて積み上がるものです。月1回のSearch Console確認で数値を追いかけつつ、改善を継続することが大切です。
### 無料でできるSEO対策の優先順位は?
最も費用対効果が高い順に、(1) Google Search ConsoleとGA4の設定、(2) タイトルタグとメタディスクリプションの最適化、(3) Core Web Vitalsの改善(画像圧縮、不要スクリプト削除)、(4) FAQ構造化データの実装、(5) 質問形式の見出し+Atomic Answers形式でのコンテンツ改善です。すべて無料ツールだけで実行でき、1か月以内に着手可能です。
---
## まとめ:まずは3つだけ始めよう
[検索意図とは?SEOにおける4つの分類と分析・最適化の実践ガイド](/blog/search-intent-seo-guide/)では、ユーザーの検索目的を正確に理解してコンテンツを最適化する方法を詳しく解説しています。
2026年のSEO対策は、AI検索の急速な進化によって新しいルールが加わりました。しかし、初心者がやるべきことの本質は変わっていません。サイトの技術基盤を整え、ユーザーの質問に正確に答え、信頼される情報を発信し続ける。このサイクルを回せるサイトは、従来の検索でもAI検索でも評価されます。
今日やることを3つに絞るなら、次の3つです。
1. Google Search Consoleにサイトを登録する
2. 最もアクセスされているページの見出しを質問形式に書き換える
3. 1つのFAQセクションを追加して構造化データを実装する
これだけで、あなたのサイトはAI時代のSEOに一歩踏み出したことになります。
LinkSurgeの[AI Overview分析機能](https://linksurge.jp/aio-v5)では、自社サイトがAI検索でどのように引用されているかをキーワード単位で確認できます。基本のSEO対策が整ったタイミングで、AI引用の可視化に取り組んでみてください。
---
## クエリファンアウトとは?初心者向けにわかりやすく解説【2026年SEO対策】
> URL: https://linksurge.jp/blog/query-fan-out-guide-2026/
> Date: 2026-02-18 | Category: AIO | Author: 緒方亜朗
> Tags: クエリファンアウト, AI Mode, AI Overviews, SEO, GEO, サブクエリ, トピッククラスター, Gemini, LLMO, 2026
## この記事の結論:クエリファンアウトを理解するための5つの要点
「クエリファンアウト」という言葉を最近よく見かけるようになった、という方は多いのではないでしょうか。私がこのテーマを掘り下げて見えてきたのは、これが単なるバズワードではなく、SEOの前提を根本から変える技術だということです。以下の5つが要点です。
1. **クエリファンアウトは「1つの質問を複数に分解する」技術** — ユーザーが入力した1つの検索クエリをAIが自動的に8〜12個のサブクエリに分解し、並列に検索して結果を統合する。Google AI Modeの中核エンジンとして機能している
2. **「キーワード単位のSEO」から「トピック網羅のSEO」へシフトが加速する** — AIはサブクエリの集合体に対してコンテンツを評価するため、1記事1キーワードの戦略では引用されにくくなる。トピッククラスター設計が必須になる
3. **ゼロクリック化がさらに進む** — AI Modeでの検索の約93%がクリックなしで終了するとの調査がある。「検索順位を上げる」だけでなく「AIに引用される」ことが新たな目標になる
4. **引用元にはE-E-A-Tのシグナルがほぼ必ずある** — AI Overviewsの引用元の96%にE-E-A-Tのシグナルが確認されている。ただしこれは引用された側を観察した数値で、E-E-A-Tを強化すれば引用されるという因果までは示されていない
5. **今日からできる対策がある** — サブクエリの洗い出し、見出しのQ&A化、Atomic Answers(40〜60語の回答ブロック)の配置など、コンテンツ設計で対応可能な施策が多い
以下では、初めてこの言葉を聞いた方でもわかるように、クエリファンアウトの仕組みから実践的な対策まで順に解説します。要点を動画でも解説しています。
{{youtube:YjH2_FOX2hw|クエリファンアウトとは?1回の検索が裏で8〜12回に分解される仕組み【2026年SEO】}}
---
## 1. クエリファンアウトとは何か

### 一言でいうと「検索の分身術」
クエリファンアウトを一番わかりやすく説明するなら、「検索の分身術」です。
たとえば「東京で子連れで行けるイタリアンレストランを教えて」と検索したとします。従来の検索エンジンは、この文章をそのまま1回の検索として処理していました。しかしクエリファンアウトでは、AIがこの質問を以下のように分解します。
- 「東京 子連れ レストラン おすすめ」
- 「東京 イタリアン 個室 キッズメニュー」
- 「子連れ 外食 注意点」
- 「東京 イタリアン 口コミ 評価」
これらのサブクエリを**同時に**検索し、得られた複数の結果を統合して1つの包括的な回答を生成する。この「分解 → 並列検索 → 統合」の一連の流れが、クエリファンアウトです。
### 技術的には「Scatter-Gather」方式
Google内部では「Scatter-Gather with Planning」と呼ばれる方式が採用されています。Scatter(散らばす)でサブクエリを複数のデータソースに同時に投げ、Gather(集める)で結果を回収・統合するという流れです。
データを見ると驚くのは、その検索規模です。通常のAI Modeでは**1つのクエリから8〜12個のサブクエリ**が生成され、Deep Searchでは**数百件**にまで拡張されます。つまり、ユーザーが1回検索するだけで、裏側では10回以上の検索が並列で走っているわけです。
### サブクエリはどうやって生成されるのか
サブクエリの生成には、GoogleのカスタムGemini 2.5モデルが使われています。単純にキーワードを切り出すのではなく、以下のような多角的な軸で生成されます。
| 生成軸 | 内容 | 例(元クエリ:「スタートアップ向け会計ソフト」) |
|--------|------|----------------------------------------------|
| **曖昧さの解消** | 意味が複数ある単語を特定する | 「会計ソフト クラウド型 vs インストール型」 |
| **潜在ニーズの掘り起こし** | ユーザーが聞いていないが知りたいこと | 「スタートアップ 確定申告 注意点」 |
| **詳細の深掘り** | 具体的な比較や評価 | 「freee vs マネーフォワード 料金比較」 |
| **同義語・エンティティ補正** | 関連する概念への拡張 | 「中小企業 経理 効率化」 |
| **検索意図の多様化** | 情報収集・比較・購入などの意図分岐 | 「会計ソフト 無料トライアル」 |
この仕組みを理解しておくと、後半で解説するSEO対策の意味がグッと腹落ちするはずです。
> 参考・引用:
> [Google AI Modeのクエリファンアウト技術 - Aleyda Solis](https://www.aleydasolis.com/en/ai-search/google-query-fan-out/)
> [クエリファンアウトとは - ホワイトリンク](https://white-link.com/sem-plus/query-fan-out/)
> [Query Fan-Out Technique in AI Mode - Search Engine Journal](https://www.searchenginejournal.com/query-fan-out-technique-in-ai-mode-new-details-from-google/552532/)
---
## 2. どこで使われているのか — AI Mode・AI Overviews・Deep Search

クエリファンアウトの仕組みを押さえたところで、次は「どの場面で使われているか」を具体的に見ていきます。
### Google AI Modeでの役割
AI Modeは2025年5月のGoogle I/Oで発表された、Google検索の新しいモードです。ユーザーが長文や複合的な質問を1回入力するだけで、内部でクエリファンアウトが自動実行されます。
面白いのは、AI Modeでは従来の「10個の青いリンク」が表示されないこと。代わりに、AIが複数のサブクエリから得た情報を統合して、引用付きの包括的な回答を直接提示します。これは従来の検索とは根本的に異なる体験です。
2025年のGoogle I/Oでは、カスタムGemini 2.5がAI Modeのバックエンドに組み込まれたことが発表されています。サブクエリの生成精度と検索意図の解釈能力が大幅に向上しました。
### AI Overviewsでの活用
AI Overviews(旧SGE)でも、クエリファンアウトの技術が活用されています。検索結果の上部にAIが生成した概要が表示される際、裏側ではサブクエリを生成して複数のデータソース(ウェブ、ナレッジグラフ、ショッピング、ニュース等)から情報を収集しています。
AI Overviewsは現在、Google検索の約47%で表示されるとの調査結果が出ています。つまり、**ほぼ半分の検索で**クエリファンアウトが動いている計算です。
### Deep Searchによる大規模ファンアウト
Deep Searchは、クエリファンアウトの検索規模を**数百件**にまで拡張した機能です。専門家レベルのリサーチが必要な質問に対して、膨大な情報源から引用付きのレポートを数分で作成します。
通常のAI Modeが「手軽なリサーチアシスタント」だとすれば、Deep Searchは「専門リサーチャー」に相当します。学術研究や市場調査のような深い分析が必要な場面で力を発揮します。
| 機能 | サブクエリ数 | 回答の深さ | 主な用途 |
|------|-------------|-----------|----------|
| **AI Mode** | 8〜12件 | 標準的な回答 | 日常的な検索 |
| **AI Overviews** | 数件〜十数件 | 概要・要約 | 検索結果上部での情報提示 |
| **Deep Search** | 数百件 | 専門家レベルのレポート | 学術・市場調査・詳細分析 |
AI検索全般がSEOに与える影響については「[生成AI検索がSEOを変える:7つの実践対策](/blog/ai-search-seo-japan-2026/)」で詳しく解説しています。クエリファンアウトはその中核にある技術だと考えてください。
> 参考・引用:
> [Google AI Mode について - Google公式ブログ](https://blog.google/intl/ja-jp/products/explore-get-answers/ai-mode-search/)
> [Google AI ModeとSEOへの影響 - KWM](https://www.kwm.co.jp/blog/google-ai-mode/)
> [Gemini 3とGoogle検索の統合 - 鈴木謙一](https://www.suzukikenichi.com/blog/integration-of-gemini-3-ai-model-into-google-search-and-ai-mode/)
---
## 3. SEOへのインパクト — 何がどう変わるのか

実際にSEO担当者が気になるのは「で、結局うちのサイトにどう影響するの?」という点でしょう。率直に言って、影響は大きいです。
### キーワード中心からトピック中心へ
これまでのSEOは「1記事1キーワード」が基本でした。「クエリファンアウト」というキーワードで上位を取りたければ、そのキーワードに最適化した記事を書けばよかった。
しかしクエリファンアウトの時代では、AIが自動的にサブクエリを生成して関連情報を横断的に探します。つまり、「クエリファンアウト」だけでなく「AI Mode 仕組み」「サブクエリ SEO対策」「トピッククラスター 作り方」といった**関連トピックも網羅**しているサイトが、AIに引用されやすくなります。
ある調査では、ファンアウトクエリでランクインしているページ数と、AI Overviewsでの引用確率の間に**0.77という強い相関**が確認されています。ただしこれは相関であり、因果関係が検証されたものではありません。トピッククラスター戦略と親和性のある数字ではありますが、そのまま効果の証明として扱うことは避けてください。
### ゼロクリック化の加速
データとして押さえておくべきなのが、ゼロクリック率の数字です。
- AI Overviews表示時:オーガニックCTRが**約61%低下**
- AI Modeでの検索:**約93%がクリックなし**で終了
特にAI Modeの93%という数字は衝撃的です。10回検索して9回はどのサイトにもアクセスしないということ。「検索順位を上げてトラフィックを稼ぐ」という従来のSEOの前提が揺らいでいます。
ただし、ここで悲観するだけでは意味がありません。AI Overviews内で引用されたブランドのCTRは約35%上昇したとの報告もあります。つまり、**引用される側に回れば、むしろチャンスが広がる**わけです。
### E-E-A-Tの重要性がさらに増す
クエリファンアウトで複数のサブクエリが生成されると、AIは各サブクエリの回答として**最も信頼性の高い情報源**を選びます。ここでE-E-A-T(経験・専門性・権威性・信頼性)が直接的に影響します。
実際のデータでは、AI Overviewsの引用元の**96%にE-E-A-Tのシグナル**が確認されています。著者プロフィール、専門家監修、一次情報の出典明示といった要素です。
ただしこれは引用されたページ側を観察した数値であり、比較対象(引用されなかったページの何%がE-E-A-Tシグナルを持つか)が示されていません。そのため「E-E-A-Tを強化すれば引用される」という因果の証明にはなりません。引用元にほぼ共通して見られる特徴、という読み方が正確です。
### LLMOという新しい概念
クエリファンアウト時代のSEO対策を包括的に表す概念として、**LLMO**(Large Language Model Optimization)が注目されています。これは従来のSEOに加えて、AI検索エンジンに引用されるための最適化を行う手法です。
GEO(Generative Engine Optimization)と重なる部分も多いですが、LLMOはChatGPT、Perplexity、Claudeなどの**検索以外のAIプラットフォーム**での可視性も含む、より広い概念です。GEOの詳しい戦略については「[GEO完全ガイド](/blog/geo-guide-japan-2026/)」をご覧ください。
[LinkSurge](https://linksurge.jp/)のAI Overview分析では、自社サイトがAI Overviewsでどのクエリに対して引用されているかをキーワード単位で確認でき、クエリファンアウト時代の引用状況を可視化できます。
> 参考・引用:
> [ファンアウトクエリの引用確率調査 - SurferSEO](https://surferseo.com/blog/query-fan-out-impact/)
> [クエリファンアウトのSEOへの影響 - ALM Corp](https://almcorp.com/blog/the-query-fan-out-impact/)
> [E-E-A-Tの重要性データ - Position Digital](https://www.position.digital/blog/ai-seo-statistics/)
> [LLMOガイド - SEOProfy](https://seoprofy.com/blog/llm-seo/)
---
## 4. 今日からできる実践的なSEO対策
ここまでの内容を踏まえて、実際に何をすべきかを具体的に落とし込みます。すべて今日から着手できる施策です。
### ステップ1:サブクエリを洗い出す
まず、自社のターゲットキーワードに対して「AIがどんなサブクエリを生成するか」を予測する作業が必要です。
やり方はシンプル。ターゲットキーワードを以下の8つの切り口で展開します。
1. **定義系** — 「○○とは」「○○の意味」
2. **比較系** — 「○○ vs △△」「○○の違い」
3. **方法系** — 「○○のやり方」「○○の手順」
4. **メリット・デメリット系** — 「○○のメリット」「○○の注意点」
5. **事例系** — 「○○の成功事例」「○○の活用例」
6. **ツール系** — 「○○に使えるツール」「○○の無料ツール」
7. **最新情報系** — 「○○ 2026年」「○○の最新動向」
8. **初心者向け系** — 「○○ 初心者」「○○ 入門」
たとえば「クエリファンアウト」なら、「クエリファンアウトとは」「クエリファンアウト SEO対策」「AI Mode サブクエリ 仕組み」「トピッククラスター 作り方」などが候補になります。
[LinkSurge](https://linksurge.jp/)の分析機能やQforia等のツールを使えば、実際にAIが生成するサブクエリのパターンをデータとして確認することもできます。
### ステップ2:トピッククラスターを設計する
サブクエリの洗い出しが終わったら、それをトピッククラスターに構造化します。
**トピッククラスターの基本構造**:
- **ピラーページ**(中心記事):メインテーマを包括的にカバーする記事
- **クラスターページ**(関連記事):各サブクエリに対応する個別の記事
- **内部リンク**:ピラーページとクラスターページを相互にリンク
```
[ピラーページ: クエリファンアウト完全ガイド]
├── [クラスター: AI Modeとは何か]
├── [クラスター: AI Overviewsの仕組み]
├── [クラスター: サブクエリの生成方法]
├── [クラスター: トピッククラスターの作り方]
└── [クラスター: GEO・LLMO入門]
```
地図なしで登山するようなもので、全体設計がないまま個別記事を量産しても、AIには「網羅性がある信頼できるサイト」と認識されません。まず地図(トピッククラスター)を描いてから、各記事を書き始めましょう。
### ステップ3:コンテンツをAI引用向けに最適化する
記事の書き方そのものも変わります。AIが情報を抽出しやすい構造にすることが重要です。
**見出しをQ&A形式にする**
```markdown
## クエリファンアウトの概要
## クエリファンアウトとは何か
```
質問形式の見出しにすると、AIがサブクエリと見出しを対応づけやすくなります。ただし「引用が増える」という効果自体が検証されているわけではない点は、後述の構造化データと同じです。
**Atomic Answersを配置する**
各セクションの冒頭に、40〜60語の独立した回答ブロック(Atomic Answers)を配置します。AIが「そのまま引用できる」粒度の情報を用意するイメージです。
**構造化データ(JSON-LD)について**
> **【2026年8月更新】** 以前この記事では「FAQスキーマを実装したページはAI引用率が60%高い」と記載していましたが、この数値の根拠は検証できなかったため削除しました。
>
> Googleは「AI OverviewsやAI Modeに出るために追加の要件はなく、特別なschema.orgの構造化データを足す必要もない」と公式に明言しています。schemaを追加した対照実験でも、AI Mode(+2.4%)とChatGPT(+2.2%)の変化はノイズと区別できず、引用の増加は確認されませんでした。
>
> JSON-LDの実装は、リッチリザルトなど検索結果での見え方に目的が定まってからで構いません。Googleは `HowTo` のリッチリザルトを2023年に、[`FAQPage` のリッチリザルトを2026年5月に](https://developers.google.com/search/updates#removing-faq-rich-result)廃止しています。リッチリザルト目的で残っているのは `Article`・`BreadcrumbList` などです(`Product` は商品ページ、`Review` は対象タイプに対する実際のレビュー・評価があるページに限られ、一般的な記事には使えません)。詳細は「[「FAQスキーマで引用率3.2倍」は本当か — 自社の評価基準から未検証の数値を削除した話](/blog/faq-schema-ai-citation-myth-2026/)」で検証しています。
一方で、見出しのQ&A化とAtomic Answersの配置——つまりコンテンツの構成そのものは、AIが情報を抽出しやすくする観点で意味があると考えています。ただしこれも「引用が増える」という効果自体が検証されているわけではないため、自社で効果を確かめながら進めてください。
構造化データやGEO技術の詳しい実装方法は「[GEO完全ガイド](/blog/geo-guide-japan-2026/)」で解説しています。
### ステップ4:E-E-A-Tを強化する
- **著者情報を明示する** — 著者名、肩書き、専門分野、プロフィールページへのリンク
- **一次情報を含める** — 独自の調査データ、実際の検証結果、具体的な数値
- **出典を明記する** — 参考にした情報源を本文中にリンク付きで表示
- **更新日を表示する** — 記事の鮮度を示すことでAIの信頼度が向上
> 参考・引用:
> [クエリファンアウトのSEO対策 - ブリッジワールド](https://www.bridge-world.jp/seo/column/query-fan-out/)
> [AI Overviewsランキング要因ガイド - Wellows](https://wellows.com/blog/google-ai-overviews-ranking-factors/)
> [クエリファンアウトとSEO - SUSO Digital](https://susodigital.com/thoughts/what-query-fan-out-means-for-your-seo/)
---
{{linksurge-card}}
## 5. 他のAI検索プラットフォームとの比較
ChatGPT側のファンアウトは2026年夏に1プロンプトあたり2.17本から7.61本へ増え、同時にサブクエリがGPT-5.3〜5.4の期間、会話インターフェースから見えなくなりました。ChatGPT固有の挙動とAPIでの取得方法は「[ChatGPTのクエリファンアウトは今どうなっているか](/blog/chatgpt-query-fanout-hidden-2026/)」で解説しています。
クエリファンアウトはGoogle独自の技術名ですが、類似のアプローチは他のAI検索プラットフォームでも採用されています。
### 各プラットフォームのアプローチ
- **Google(AI Mode / Gemini)** — Scatter-Gather方式でカスタムGemini 2.5を使用。大規模検索インフラとナレッジグラフを連携し、Deep Searchでは数百件のサブクエリを処理する。並列検索の規模と統合精度で他を圧倒している
- **Microsoft Bing(Copilot)** — 「Multi-Query Retrieval」方式でサブクエリを生成。主にテキスト検索が中心で、画像検索の対応は限定的
- **Perplexity AI** — RAG(Retrieval-Augmented Generation)で外部検索エンジンの結果を組み合わせて回答を生成。検索規模はGoogleほど大きくないが、引用の透明性が高い
- **Anthropic Claude** — 「Self-Ask with Search」的な手法で逐次的に検索。並列度はGoogleより低いが、回答の正確性と引用の質に強みがある
Google のクエリファンアウトが他と異なるのは、**並列検索の規模と検索インフラの統合度**です。ウェブだけでなく、ナレッジグラフ、ショッピングデータベース、地図情報など、Google独自のデータソースを横断的に検索できる点が大きな差別化要因です。
ただし、SEO対策の観点では、どのプラットフォームでも「トピック網羅」と「E-E-A-T」が重要であることは共通しています。プラットフォーム別のGEO戦略は「[GEO完全ガイド](/blog/geo-guide-japan-2026/)」で詳しく解説しています。
また、AIに引用されるためのオフサイト戦略(被リンク構築やブランドメンション)については「[オフサイトSEOとGEO戦略ガイド](/blog/offsite-seo-geo-2026/)」もあわせてご覧ください。
> 参考・引用:
> [AI検索プラットフォームのクエリ展開比較 - iPullRank](https://ipullrank.com/expanding-queries-with-fanout)
> [クエリファンアウト独自調査 - Ekamoira](https://www.ekamoira.com/blog/query-fan-out-original-research-on-how-ai-search-multiplies-every-query-and-why-most-brands-are-invisible)
---
## 6. クエリファンアウトの限界とリスク
ここまでクエリファンアウトのメリットと対策を解説してきましたが、万能な技術ではありません。知っておくべきリスクも整理しておきます。
### ハルシネーション(幻覚)のリスク
AIが複数のサブクエリから情報を統合する過程で、根拠のない情報を生成してしまう「ハルシネーション」が発生する可能性があります。特にYMYL(健康・金融)領域では、AIの回答を鵜呑みにすることは危険です。コンテンツ制作側としては、一次情報と出典を明確にすることで、AIが正確な情報を引用しやすい環境を整えることが重要です。
### レイテンシ(応答速度)の問題
サブクエリを数十〜数百件同時に検索するため、従来のキーワード検索より応答時間が長くなることがあります。Deep Searchでは回答の生成に数分かかるケースもあります。ユーザー体験の観点では、速度と情報の深さのトレードオフが存在します。
### ゼロクリックによるトラフィック減少
前述の通り、AI Modeでは約93%の検索がクリックなしで完結します。これは広告収益モデルに依存するメディアサイトにとって深刻な影響を与える可能性があります。AIに引用されること自体は価値がありますが、直接的なトラフィックは減少する傾向にあることは認識しておく必要があります。
### プライバシーへの配慮
複合的なクエリが複数のサブクエリに分解されると、敏感な情報が複数の外部データソースに送信されるリスクがあります。個人情報や機密情報を含むクエリでは注意が必要です。
> 参考・引用:
> [AI Overviewsについて - Google公式ヘルプ](https://support.google.com/websearch/answer/16011537?hl=ja)
> [AI検索のゼロクリック影響 - Beryl CMS](https://www.beryl-cms.jp/blog/query-fan-out/)
---
引用元がページ全体に散ることは、実データでも確認できます。「[AI検索は記事のどこを引用するのか](/blog/ai-citation-block-position-research-2026/)」では、実引用277件の解析から、ページ最後の20%からも12.6%の引用が発生していたと報告しています。クエリファンアウトはこの分布を説明しうる一因ですが、**その調査は分布を測定したもので、因果までは検証していません**。
---
## よくある質問(FAQ)
### クエリファンアウトと従来の検索はどう違いますか?
従来の検索は、ユーザーが入力したキーワードをそのまま1回の検索として処理します。クエリファンアウトは、AIが1つのクエリを8〜12個のサブクエリに自動分解し、並列に検索して結果を統合します。ユーザーが1回検索するだけで、裏側では10回以上の検索が同時に実行されている点が最大の違いです。
### クエリファンアウトに対応するためにサイトをリニューアルする必要がありますか?
大規模なリニューアルは不要です。まずは既存コンテンツの見出しをQ&A形式に変え、各セクション冒頭にAtomic Answers(40〜60語の回答ブロック)を配置することから始められます。FAQスキーマの追加や、トピッククラスターの設計も段階的に進められる施策です。
### クエリファンアウトはGoogle以外のAIでも使われていますか?
「クエリファンアウト」という名称はGoogleの技術ですが、類似のサブクエリ生成・統合の仕組みはPerplexity AI、Microsoft Copilot、Anthropic Claudeなど他のAI検索プラットフォームでも採用されています。いずれも「トピック網羅」と「E-E-A-T」が引用の鍵である点は共通しています。
### 小規模サイトでもクエリファンアウト対策は効果がありますか?
効果はあります。クエリファンアウトでAIが評価するのは「サイトの規模」ではなく「特定トピックに対する網羅性と信頼性」です。ニッチな専門分野で一次情報を持つ小規模サイトが、大手メディアより優先的に引用されるケースも報告されています。自社の強みがあるトピックに集中してクラスターを構築することが有効です。
### クエリファンアウト対策のKPIは何を見ればいいですか?
従来のキーワード順位やオーガニックCTRに加えて、**Citation Rate**(AIの回答に自社URLが出現する割合)が重要なKPIになります。[LinkSurge](https://linksurge.jp/)などのGEO分析ツールや、Google Search ConsoleのAI Overviews関連データを活用して計測できます。
### FAQスキーマを実装すればAI引用は増えますか?
現時点では検証されていません。Googleは「AI OverviewsやAI Modeに出るために追加の要件はなく、特別なschema.orgの構造化データを足す必要もない」と公式に明言しており、schemaを追加した対照実験でも引用の増加は確認されませんでした。この記事でも以前は「AI引用率が60%高い」と記載していましたが、根拠が検証できなかったため削除しています。
一方で、記事の見出しをQ&A形式にし、各セクションに40〜60語の独立した回答ブロックを置くという構成上の工夫は、AIが情報を抽出しやすくする観点で意味があると考えています。ただしこちらも効果自体は検証されていないため、自社で確かめながら進めることをおすすめします。
---
## まとめ:クエリファンアウト時代のSEOを始めよう
クエリファンアウトは、Google検索の裏側で動いている「見えないエンジン」です。ユーザーが1回検索するたびに、AIが質問を多面的に分解して最適な情報を探し出す。この仕組みを理解することが、2026年以降のSEO戦略の出発点になります。
対策の優先順位は明確です。まずターゲットキーワードのサブクエリを洗い出し、トピッククラスターを設計する。次に各コンテンツをQ&A形式の見出しとAtomic Answersで構成する。そしてE-E-A-Tのシグナルを強化して、AIが「信頼できる情報源」として認識する条件を整える。構造化データの実装は、検索結果での見え方に目的が定まってからで構いません。
一度にすべてを変える必要はありません。既存記事の見出しをQ&A化するところから始めて、段階的にトピッククラスターを拡充していくアプローチが現実的です。SEO対策全般の最新動向と初心者向けの実践ステップは「[【2026年最新】SEO対策の始め方ガイド](/blog/seo-latest-guide-2026/)」で解説しています。
LinkSurgeの[AI Overview分析機能](https://linksurge.jp/aio-v5)では、クエリファンアウトによって自社サイトがどのサブクエリで引用されているかをリアルタイムで確認できます。まずは現状を把握するところから始めてみてください。
---
## Cloudflare「Markdown for Agents」が示すAI対策の新常識—あなたのサイトはAIエージェントに読まれていますか?
> URL: https://linksurge.jp/blog/cloudflare-markdown-for-agents-2026/
> Date: 2026-02-14 | Category: AIO | Author: 緒方亜朗
> Tags: AI検索, Cloudflare, Markdown, AIエージェント, GEO, SEO, 機械可読
## この記事の結論:AIエージェント最適化が「やるべきこと」になった5つの理由
Cloudflareが2026年2月に発表した「Markdown for Agents」は、単なる技術リリースではありません。私がこの発表を読んで強く感じたのは、**AIエージェントに最適なフォーマットでコンテンツを届ける**ことが、もはやテクニカルSEOの必須項目になったということです。以下の5つが要点です。
1. **HTMLからMarkdownへの変換で約80%のトークン削減が実現する** — 同一ページでHTMLが約16,000トークン、Markdownが約3,000トークンという検証結果がCloudflare公式ブログで報告されている。AIエージェントが消費するコストとレイテンシに直結する差だ
2. **Content-Signalヘッダーで「AI利用ポリシー」を機械的に宣言できる** — `ai-train=yes`、`search=yes`、`ai-input=yes`といった指示をHTTPヘッダーで返すことで、サイト所有者がAI学習・検索利用の許可を明示できるようになった
3. **robots.txtだけではAIエージェント制御に限界がある** — AIエージェントはクローラーとは異なる挙動をとる。`Accept: text/markdown`ヘッダーによるコンテンツネゴシエーションという新しい層が登場した
4. **AIクロークのリスクが現実の脅威になっている** — Markdown用リクエストと通常リクエストで異なるコンテンツを返す「シャドウWeb」の実証実験が報告されており、セキュリティの新たな課題が生まれている
5. **Cloudflare以外のサイトでも「AI対応フォーマット」の実装は可能** — llms.txtの採用、APIエンドポイントの追加、構造化データの強化など、自社サーバーでも実行できる施策がある
以下では、各テーマをデータと実装手順を交えて解説します。
---
## 1. Cloudflare「Markdown for Agents」とは何か
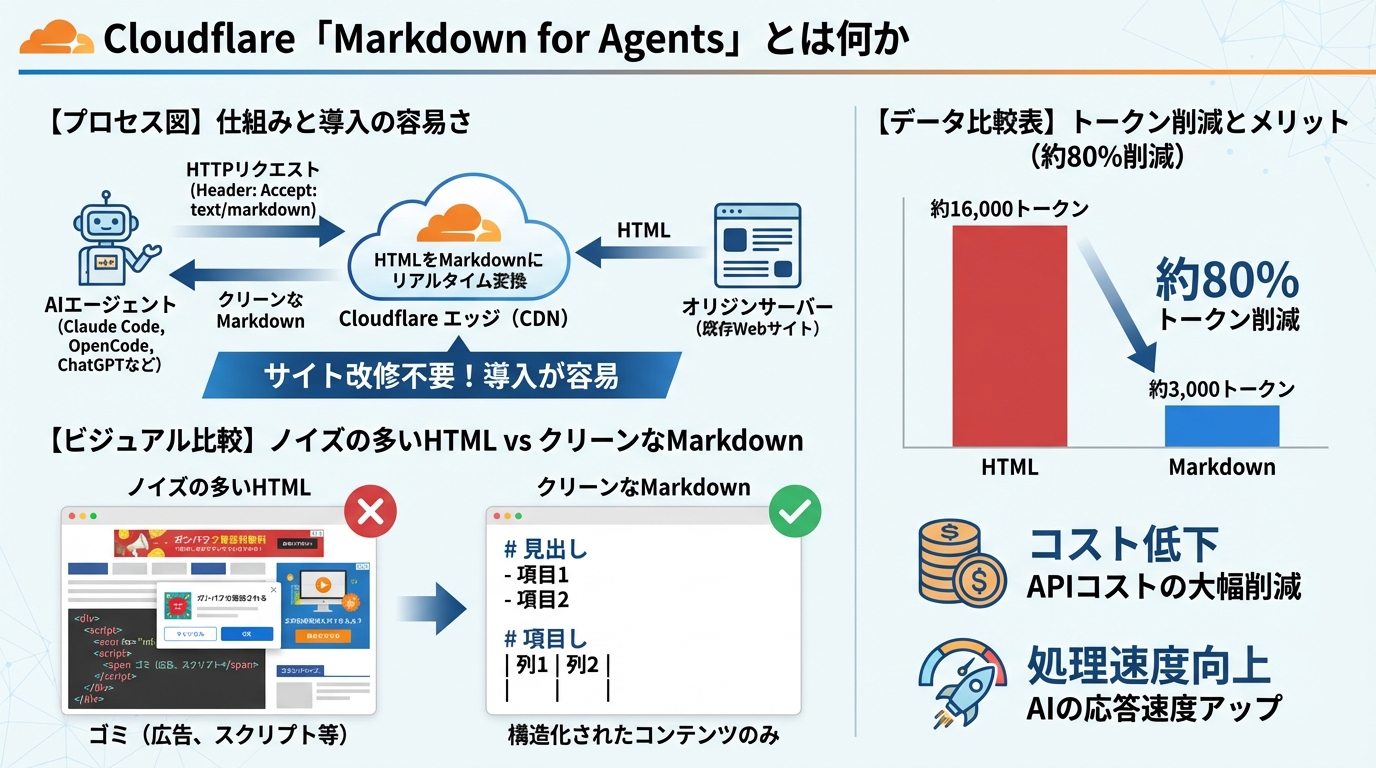
2026年2月、Cloudflareは「Markdown for Agents」を正式発表しました。一言で言えば、**AIエージェントがWebページにアクセスしたとき、HTMLの代わりにMarkdown形式のコンテンツを返す仕組み**です。
### どう動くのか
AIエージェント(Claude Code、OpenCode、ChatGPTのブラウジング機能など)がHTTPリクエストに `Accept: text/markdown` ヘッダーを付与すると、CloudflareのCDNエッジがHTMLをリアルタイムでMarkdownに変換して返します。オリジンサーバーは通常通りHTMLを生成するだけでよく、サイト側のコード変更は不要です。
### なぜMarkdownなのか
率直に言って、HTMLはAIにとって非常にノイズが多いフォーマットです。ナビゲーション、フッター、広告、JavaScript——AIが本当に必要とするのはメインコンテンツだけなのに、HTMLにはその何倍もの「ゴミ」が含まれています。
Markdownなら構造(見出し・リスト・表)を維持したまま、不要な要素を除去できます。Cloudflareの検証では、**同一ページでHTMLが約16,000トークン、Markdownが約3,000トークン**。約80%の削減です。
| フォーマット | トークン数(同一ページ) | 構造情報 | ノイズ |
|-------------|----------------------|---------|--------|
| HTML | 約16,000 | 含む | 非常に多い |
| Markdown | 約3,000 | 含む | 最小限 |
| プレーンテキスト | 約2,500 | 失われる | 少ない |
> 参考・引用:
> [Markdown for Agents - Cloudflare Blog](https://blog.cloudflare.com/markdown-for-agents/)
> [Cloudflare Markdown for Agents - nohackspod](https://www.nohackspod.com/blog/cloudflare-markdown-for-agents)
> [Cloudflare Markdown for Agents - Thunderbit](https://thunderbit.com/blog/cloudflare-markdown-for-agents)
---
## 2. 80%トークン削減の技術的インパクト
私がCloudflareの技術ドキュメントを読んで特に注目したのは、トークン削減がもたらす連鎖的な効果です。単に「軽くなる」だけではありません。
### コスト・速度・精度の三重効果
**コスト削減**: LLMのAPI料金はトークン数に比例します。入力トークンが80%減れば、エージェントがページを読み込むコストも80%減です。大規模なRAG(Retrieval-Augmented Generation)システムでは、この差は月額の運用コストに直結します。
**レイテンシ改善**: 転送データ量が数分の一になるため、ネットワークのラウンドトリップタイムが短縮されます。特にエッジで変換が完了する点が重要で、オリジンサーバーへの追加負荷はゼロです。
**精度向上**: ノイズの少ないMarkdownを入力にすることで、AIの回答精度が向上します。HTMLのナビゲーションやフッターのテキストがコンテキストを汚染する問題が解消されるためです。
### x-markdown-tokensヘッダー
Cloudflareのレスポンスには `x-markdown-tokens` ヘッダーが付与されます。AIエージェントはページを全文読み込む前にトークン数を把握できるため、コンテキストウィンドウの管理が格段に楽になります。
これは考えてみれば画期的です。従来、エージェントはページを取得してから「コンテキストに収まるか」を判断していました。事前にトークン数がわかれば、取得前にフィルタリングできます。
### キャッシュの分離
`Vary: Accept` ヘッダーにより、HTML版とMarkdown版のキャッシュが自動的に分離されます。人間のブラウザにはHTML、AIエージェントにはMarkdownが返る——この使い分けがCDNレベルで透過的に行われます。
> 参考・引用:
> [Markdown for Agents - Cloudflare Developers](https://developers.cloudflare.com/fundamentals/reference/markdown-for-agents/)
> [Cloudflare Now Converts Web Pages to Markdown - MediaCopilot](https://mediacopilot.ai/cloudflare-now-converts-web-pages-to-markdown-for-ai-agents/)
> [Cloudflare Markdown for Agents - Search Engine Land](https://searchengineland.com/cloudflare-markdown-for-agents-469246)
---
## 3. Content-Signalヘッダーとプライバシーの新しい課題
データを見ると、Markdownの技術的メリットは明確です。しかし、この技術にはセキュリティとプライバシーの両面で新たな課題が伴います。
### Content-Signal:AIへの「利用許可証」
Cloudflareは `Content-Signal` というHTTPヘッダーを導入しました。サイト所有者が以下の3つの利用許可を機械可読で宣言できます。
- `ai-train=yes/no` — AI学習データとしての利用を許可/拒否
- `search=yes/no` — 検索エンジンでの利用を許可/拒否
- `ai-input=yes/no` — AIへのリアルタイム入力としての利用を許可/拒否
robots.txtが「クローラーのアクセス制御」だったのに対し、Content-Signalは「コンテンツの利用目的の制御」です。GDPR・HIPAAなどの規制に合わせて、学習利用とリアルタイム応答利用を分離できる点は、特にエンタープライズにとって大きな意味を持ちます。
### AIクロークのリスク
一方で、`Accept: text/markdown` ヘッダーの存在が新たな脅威を生んでいます。
実証実験では、AIエージェント向けリクエストに対して**人間向けとは異なるコンテンツを返す「クローク」が容易に成立する**ことが確認されています。たとえば、人間には正確な商品情報を見せながら、AIエージェントには競合他社の誤情報を含むコンテンツを返す——といった攻撃が技術的に可能です。
これはGoogleがかつて検索エンジン向けクロークをスパムとして取り締まった構図と同じです。AIエージェント向けの「シャドウWeb」が、今後のセキュリティ上の重要課題になるでしょう。
### 対策:ゼロトラストとCI検証
Cloudflare自身も、AI Security Suiteでゼロトラストポリシーの適用、リアルタイム監査ログ、プロンプトインジェクション防止を提供しています。サイト運営者としては、HTML版とMarkdown版のコンテンツに差異がないことをCIパイプラインで検証する習慣が必要です。
> 参考・引用:
> [Cloudflare Markdown for Agents - QueryBurst](https://queryburst.com/blog/cloudflare-markdown-for-agents/)
> [Secure & Govern AI Agents - Cloudflare](https://www.cloudflare.com/the-net/building-cyber-resilience/secure-govern-ai-agents/)
> [HackerNews Discussion on AI Cloaking Risks](https://news.ycombinator.com/item?id=46997526)
---
{{linksurge-card}}
## 4. Cloudflareを使わなくてもできる「AI対応」施策
「うちはCloudflareを使っていないから関係ない」——そう思った方こそ、このセクションを読んでください。Cloudflareの発表が示しているのは、**AIエージェントにフレンドリーなフォーマットを提供することの価値**です。CloudflareのCDNを使わなくても、同じ効果を得る方法はあります。
### 施策1:llms.txtの導入
llms.txtは、サイトのルートに配置するテキストファイルで、AIエージェントにサイト構造やコンテンツの要約を提供する新しい標準です。robots.txtがクローラー向けの「立入禁止マップ」なら、llms.txtはAIエージェント向けの「案内パンフレット」です。
### 施策2:Markdown APIエンドポイントの追加
自社サーバーに `/api/markdown?url=/blog/your-article/` のようなエンドポイントを用意し、`Accept: text/markdown` リクエストに対してMarkdown版コンテンツを返す実装が可能です。静的サイトジェネレーターを使っている場合、ソースのMarkdownファイルをそのまま配信する方法もあります。
### 施策3:構造化データの徹底
JSON-LD(`Article` など)の実装は、コンテンツの意味と構造を機械可読にする手段です。ただしAI引用を増やす効果は対照実験で確認されておらず、`FAQPage`(2026年5月)と`HowTo`(2023年)のリッチリザルトはすでに廃止されています。Cloudflareの変換はあくまで「HTMLをMarkdownに変える」処理であり、**構造化データが持つセマンティック情報はそもそもMarkdownでは表現できません**。つまり両者は別の層の施策です。セマンティックな情報を機械可読にしたい目的があるなら併用してください(Googleの生成AI検索に出るための要件ではありません)。
### 施策4:AIクローラーのアクセス許可
robots.txtで主要なAIクローラーへのアクセスを明示的に許可し(検索での引用を狙うなら `OAI-SearchBot`・`PerplexityBot`・`Claude-SearchBot`、ユーザーの質問に応じた取得を許可するなら `ChatGPT-User`・`Claude-User`、学習を許可するなら `GPTBot`・`ClaudeBot`)、サイトマップを定期更新してAIが情報を取得しやすい環境を整備します。
AIクローラーへの対応とサイト構造の最適化については「[生成AI検索がSEOを変える:7つの実践対策](/blog/ai-search-seo-japan-2026/)」で詳しく解説しています。
### 施策5:コンテンツの「結論ファースト」構造化
AIが回答を生成する際、セクション冒頭の40〜60語を優先的に参照します。各セクションの冒頭に結論を配置する「Atomic Answers」形式は、Markdownフォーマットの提供と同等以上にAI引用率を高める施策です。
GEOの技術実装やプラットフォーム別の引用戦略については「[GEO完全ガイド](/blog/geo-guide-japan-2026/)」で体系的にまとめています。
> 参考・引用:
> [How to Serve Markdown to AI Agents - dev.to](https://dev.to/lingodotdev/how-to-serve-markdown-to-ai-agents-making-your-docs-more-ai-friendly-4pdn)
> [Cloudflare The Secret Weapon for Building AI Agents - JustThink AI](https://www.justthink.ai/blog/cloudflare-the-secret-weapon-for-building-ai-agents)
> [Don't Let Your AI Agents Go Rogue - Softprom](https://softprom.com/dont-let-your-ai-agents-go-rogue-the-cloudflare-guide-to-security-and-control)
---
## 5. 今すぐ始めるAIエージェント最適化ロードマップ
施策の優先順位が見えてきたところで、具体的な実行順序を整理します。
### フェーズ0:現状把握(1日)
- 自社サイトを `curl -H "Accept: text/markdown"` でリクエストし、何が返るか確認する
- [LinkSurge](https://linksurge.jp/)のAI Overview分析で、自社コンテンツがAIにどう引用されているか把握する
- robots.txtでAIクローラーがブロックされていないか確認する
### フェーズ1:構造化データの実装(1〜2週間)
- `Article` など、ページ内容に対応するJSON-LDを主要ページに追加
- 各セクション冒頭に40〜60語のAtomic Answersを配置
- sitemap.xmlを更新し、AIクローラーが全ページにアクセスできるようにする
### フェーズ2:機械可読フォーマットの提供(2〜4週間)
- llms.txtファイルの作成と配置
- Markdown APIエンドポイントの実装(技術リソースがある場合)
- Content-Signal相当のメタタグまたはHTTPヘッダーの追加
### フェーズ3:計測と改善(継続)
- AI引用率の定期モニタリング([LinkSurge](https://linksurge.jp/aio-v5)のAI Overview分析)
- `x-markdown-tokens`に相当するトークン効率の検証
- 新規AIクローラーへの対応(User-Agentの追加許可)
SEO・コンテンツ・リンク構築を含む包括的な戦略については「[2026年最新 SEO対策完全ガイド](/blog/seo-guide-2026/)」を参照してください。
> 参考・引用:
> [Best Practices SASE for AI - Cloudflare Blog](https://blog.cloudflare.com/best-practices-sase-for-ai/)
> [Markdown for Agents - Cloudflare Developers](https://developers.cloudflare.com/fundamentals/reference/markdown-for-agents/)
> [Cloudflare Markdown for Agents - Search Engine Land](https://searchengineland.com/cloudflare-markdown-for-agents-469246)
---
## よくある質問(FAQ)
### Cloudflare「Markdown for Agents」はどのプランで使えますか?
Pro、Business、Enterpriseプランで利用可能です。ダッシュボードの「Bots/AI」セクションからワンクリックで有効化できます。APIでの有効化も可能で、`PATCH /client/v4/zones/{zone_tag}/settings/content_converter` エンドポイントを使用します。Freeプランでは利用できません。
### Cloudflareを使っていないサイトでもAIエージェント対応は可能ですか?
可能です。llms.txtの配置、Markdown APIエンドポイントの追加、JSON-LDの実装、AIクローラーへのrobots.txt許可など、自社サーバーで実行できる施策が複数あります。Cloudflareのサービスはこれらを自動化するものですが、手動実装でも同等の効果が得られます。
### Content-Signalヘッダーとrobots.txtの違いは何ですか?
robots.txtはクローラーの「アクセス」を制御するファイルです。一方、Content-Signalはアクセスを許可した上で「コンテンツの利用目的」を制御するHTTPヘッダーです。たとえば、ページへのアクセスは許可しつつ、AI学習データとしての利用は拒否する、といった細かい制御が可能になります。
### AIクロークとは何ですか?対策はありますか?
AIエージェント向けリクエスト(`Accept: text/markdown`)に対して、人間向けとは異なるコンテンツを返すことをAIクロークと呼びます。検索エンジン向けクロークと同様、意図的な誤情報配信や操作に悪用される可能性があります。対策としては、HTML版とMarkdown版のコンテンツ一致をCIパイプラインで自動検証すること、Cloudflare AI Security Suiteのようなゼロトラストポリシーの適用が有効です。
---
## まとめ:AIエージェント対応は「技術SEO」の新しい必須項目
Cloudflareの「Markdown for Agents」は、Web全体がAIエージェントとの対話に適応し始めたことを象徴する動きです。
まず取り組むべきは3つです。構造化データの実装、AIクローラーへのアクセス許可、そして結論ファースト構造のコンテンツ設計。Cloudflareを使うかどうかに関係なく、これらの施策でAIエージェントからの引用確率を高められます。
[LinkSurge](https://linksurge.jp/)の[AI Overview分析機能](https://linksurge.jp/aio-v5)では、自社コンテンツがAI検索でどのように引用されているかをリアルタイムで確認できます。AIエージェント対応の効果測定にお役立てください。
構造化データとllms.txtだけでAI検索1位を獲得した驚異の実験については「[見えないサイトがAI検索1位に — 構造化データだけでPerplexityに引用された衝撃の実験](/blog/phantom-authority-invisible-website-ai-citation-2026/)」で詳しく解説しています。
---
## サテライトサイトSEOは終わった:Googleペナルティの実態と安全なリンク構築法
> URL: https://linksurge.jp/blog/satellite-site-seo-risks-2026/
> Date: 2026-02-14 | Category: SEO | Author: 緒方亜朗
> Tags: SEO, リンク構築, PBN, サテライトサイト, Googleペナルティ, SpamBrain, バックリンク
## この記事の結論:サテライトサイトSEOの5つのリスクと対策
「サテライトサイトを作ってリンクを送れば順位が上がる」——2020年頃までは通用した手法ですが、2026年の現在、この戦略は高確率でペナルティにつながります。私がクライアントサイトのリンクプロファイルを分析していて何度も目にしてきたのは、PBN(Private Blog Network)に頼ったサイトが一夜にして検索順位を失う光景です。以下の5つが実践上の要点です。
1. **自作サテライトサイトでのリンク操作はGoogleスパムポリシーで明確に禁止** — Googleは「リンクを操作する目的で作られたサイト」をリンクスパムとして定義し、ガイドライン違反と明記している。知らなかったでは済まない
2. **SpamBrainの検出精度が2022年以降に飛躍的向上** — AIベースのスパム検出システムが、リンクパターン・コンテンツ類似性・ホスティング情報を横断分析し、PBNネットワーク全体を一括で特定できるようになった
3. **ペナルティはサイト単体ではなくネットワーク全体に波及** — メインサイトだけでなく、サテライトサイト群も含めた全サイトがインデックス削除される可能性がある。回復には数ヶ月〜1年以上かかるケースも珍しくない
4. **正当なマルチサイト運営とPBNの境界線を理解する** — 地域別サイトやブランド別サイトなど、独自の価値を持つマルチサイト運営は問題ない。判断基準は「SEO目的を除いても、そのサイトが存在する理由があるか」
5. **リンクを「買う」のではなく「稼ぐ」戦略に転換する** — オリジナル調査、デジタルPR、専門家寄稿など、第三者が自発的にリンクしたくなるコンテンツを作ることが2026年の正攻法
以下では、各テーマを順に解説します。要点を動画でも解説しています。
{{youtube:xBfjXEKe_n4|サテライトサイトSEOはもう通用しない|SpamBrainがPBNを見抜く3つの方法}}
---
## 1. Googleが禁止する「リンクスパム」の定義

Googleのスパムポリシーには、リンクスパムの具体例が明記されています。その中でも、サテライトサイトに直接関係するのは以下の項目です。
- 「PageRank を転送するリンクの売買」
- 「過剰な相互リンク、またはリンクのみを目的としたパートナーサイト」
- 「大規模なアーティクルマーケティングキャンペーンやゲスト投稿キャンペーン」
- 「自動化されたプログラムやサービスを使ってサイトへのリンクを作成」
要するに、**リンクを送ること自体を目的としたサイト群の運営**は、どんなに巧妙に見せかけても、Googleのガイドライン違反です。
Google検索チームのジョン・ミューラー氏は過去のウェブマスターハングアウトで繰り返し「SEO目的のサテライトサイトは時間の無駄」と発言しています。リソースを自作リンク網に割くよりも、メインサイトの品質向上に投資すべきだという立場です。
### リンクスパムアップデートの歴史
Googleのリンクスパム対策は年々強化されてきました。
- **2022年12月**: リンクスパムアップデート実施。SpamBrainが「リンクを送る側」と「受け取る側」の両方を検出対象に
- **2024年3月**: コアアップデートとスパムアップデートを同時実施。サイト評判の悪用(Parasite SEO)も対象に追加
- **2025〜2026年**: SpamBrainの継続的なアルゴリズム改善。PBN検出の自動化が進み、手動レビューなしでもネットワーク単位で制裁可能に
> 参考・引用:
> [Google ウェブ検索のスパムに関するポリシー - Google検索セントラル](https://developers.google.com/search/docs/essentials/spam-policies)
> [December 2022 link spam update - Google Search Central Blog](https://developers.google.com/search/blog/2022/12/december-2022-spam-update)
> [What are Backlinks? And How to Build Them - Backlinko](https://backlinko.com/hub/seo/backlinks)
---
## 2. SpamBrainはどうやってPBNを検出するのか

SpamBrainは2018年にGoogleが導入したAIベースのスパム検出システムです。当初はスパムページの特定が主な用途でしたが、2022年のリンクスパムアップデートで「リンクネットワーク」の検出に大幅に機能拡張されました。
### 3つの検出レイヤー
SpamBrainがPBNを検出するメカニズムは、大きく3つのレイヤーに分かれます。
**リンクパターン分析** — 不自然なリンク構造を検出します。たとえば、新規ドメインが開設直後から特定の1サイトにのみリンクしている場合、これは自然なリンクではないと判断されます。リンクの増加速度(リンクベロシティ)が不自然に急激な場合も検出対象です。
**コンテンツ類似性分析** — PBNサイトのコンテンツは、テンプレートの使い回しやAI生成の薄いコンテンツであることが多い。SpamBrainはサイト間のコンテンツ類似度を分析し、同一運営者による量産パターンを特定します。
**インフラストラクチャ分析** — 同一IPレンジ、同一ホスティングプロバイダー、同一CDN設定、類似のWHOIS情報など、技術的なフットプリントを横断分析します。異なるドメイン名でも、裏側のインフラが共通していれば同一ネットワークと推定されます。
### 「見つからない」は幻想
PBN運営者の間では「IPを分散させれば検出されない」「異なるCMSを使えば安全」といった対策が語られてきました。しかし、SpamBrainは単一の指標ではなく、上記3レイヤーの複合的なシグナルを機械学習で統合判断しています。
2024年のGoogleスパムレポートによると、自動検出によるスパムアクションは前年比で60%以上増加。人間のレビュアーが確認する前に、AIが先にネットワークを特定しているケースが大半です。
[LinkSurge](https://linksurge.jp/)のSEO分析機能を使えば、自社サイトのバックリンクプロファイルに不自然なパターンがないか確認できます。被リンク元のドメイン分散度やリンク増加パターンの可視化は、PBNリスクの早期発見に有効です。
> 参考・引用:
> [How Google Fights Spam – Web Spam Report 2024 - Google](https://blog.google/products/search/how-google-fights-spam-2024/)
> [Google SpamBrain: What SEOs Should Know - Search Engine Journal](https://www.searchenginejournal.com/google-spambrain-link-spam/473922/)
> [Are Private Blog Networks Safe? - Ahrefs](https://ahrefs.com/blog/private-blog-networks/)
---
## 3. ペナルティの種類と影響範囲

### なぜペナルティは「想像以上に痛い」のか
サテライトサイトによるリンク操作が検出された場合、ペナルティは段階的に厳しくなります。
**リンク価値の無効化(最も軽い)** — Googleがスパムリンクを認識したうえで、そのリンクの評価を「0」にする措置です。この場合、メインサイトに直接のペナルティは課されませんが、リンクに投じた労力とコストが完全に無駄になります。
**アルゴリズムによる順位降格** — Search Consoleに通知は来ませんが、検索順位が大幅に下落します。原因がアルゴリズムなのかコンテンツの問題なのか判別が困難で、対処が遅れやすい。
**手動対策(Manual Action)** — Google Search Consoleに「手動による対策」として通知が届きます。「不自然なリンクがサイトを指している」というメッセージが表示され、対象リンクのリンク否認ツールでの否認と再審査リクエストが必要です。再審査が通るまで数週間〜数ヶ月かかります。
**インデックスからの完全削除(最も重い)** — サテライトサイト群だけでなく、メインサイトごとGoogleのインデックスから除外される最悪のケースです。事実上、検索結果からの完全消滅を意味します。
### 回復にかかる時間と労力
手動対策からの回復は決して簡単ではありません。典型的なプロセスは以下のとおりです。
1. 問題リンクの全数調査(1〜2週間)
2. リンク否認ファイルの作成と送信
3. サテライトサイト群の閉鎖またはnoindex設定
4. 再審査リクエストの送信
5. Googleの審査待ち(2〜6週間)
6. 再審査が却下された場合は追加対応と再リクエスト
全体で**3ヶ月〜1年**かかるケースも珍しくありません。その間、オーガニック流入はほぼゼロ。事業への影響は計り知れません。
> 参考・引用:
> [Manual Actions Report - Google Search Central](https://support.google.com/webmasters/answer/9044175)
> [Disavow Links to Your Site - Google Search Central](https://support.google.com/webmasters/answer/2648487)
> [How to Recover from a Google Penalty - Moz](https://moz.com/blog/how-to-recover-from-a-google-penalty)
---
## 4. 正当なサテライトサイト vs PBN——境界線はどこか
「サテライトサイト」という言葉自体に良い悪いはありません。問題はその目的と運営方法です。
### 問題のないマルチサイト運営
以下のようなケースは、Googleのガイドラインに抵触しません。
- **地域別サイト**: 東京本社と大阪支社でそれぞれのサイトを運営し、各地域のサービス情報を提供。それぞれが独自のコンテンツと利用者を持つ
- **ブランド別サイト**: 化粧品ブランドAとスキンケアブランドBを別サイトで運営。各ブランドが独自の商品ラインとコンテンツを持つ
- **メディアサイト**: 自社運営のオウンドメディアで、業界に関する独自の調査や解説記事を公開。メインサイトとは独立した編集方針を持つ
### ペナルティ対象のPBN
一方、以下の特徴を持つサイト群はPBNと判断される可能性が高い。
- コンテンツが薄い、または他サイトからの複製・リライト
- 記事の大半にメインサイトへのリンクが含まれる
- 独自の読者やコミュニティが存在しない
- 更新頻度が不規則で、リンク設置時のみ新規記事が投稿される
- デザインやテンプレートが他のサテライトサイトと酷似
### 判断の黄金律
私がクライアントに伝えている判断基準は1つだけです。
**「SEOのメリットを一切なくしても、そのサイトを運営し続ける理由がありますか?」**
この問いにYesと答えられるなら正当なマルチサイト運営です。Noなら、それはPBNと変わりません。
オフサイトSEOにおけるブランド構築の正しいアプローチについては「[AI検索に選ばれるには「自サイトの外」が9割](/blog/offsite-seo-geo-2026/)」で詳しく解説しています。
> 参考・引用:
> [Are PBN Links Effective for SEO? - Semrush](https://www.semrush.com/blog/pbn-links/)
> [Private Blog Networks Explained - Ahrefs](https://ahrefs.com/blog/private-blog-networks/)
> [Google's John Mueller on Satellite Sites - Search Engine Roundtable](https://www.seroundtable.com/google-satellite-sites-waste-of-time-33182.html)
---
{{linksurge-card}}
## 5. 安全なバックリンク戦略5選

PBNに頼らずにバックリンクを増やす方法は、手間はかかりますが確実に効果があります。
### 戦略1:オリジナル調査データの公開
業界の調査データやアンケート結果を公開すると、ニュースサイトや業界ブログから自然にリンクされます。「〇〇業界の最新動向調査」「〇〇に関する1000人アンケート」のようなコンテンツは、メディアにとって引用しやすい一次情報です。
### 戦略2:デジタルPR
プレスリリースの配信だけではなく、ジャーナリストや業界インフルエンサーと直接つながる施策です。HAROやConnectively(旧HARO)のようなプラットフォームで専門家コメントを提供すれば、権威あるメディアからのバックリンクを獲得できます。
### 戦略3:リンカブルアセットの作成
無料ツール、計算機、インフォグラフィック、データベースなど、他のサイトが「リンクしたくなる」コンテンツを作る戦略です。たとえば、SEO業界なら「Core Web Vitals無料チェックツール」、不動産業界なら「住宅ローン試算ツール」のようなものが該当します。
### 戦略4:権威あるメディアへの寄稿
業界メディアやニュースサイトへのゲスト投稿は、PBNとは根本的に異なります。実名で署名し、編集部のレビューを経て公開される記事は、E-E-A-Tの向上にも貢献します。ただし、低品質なゲスト投稿サービスはPBNと同等にリスクがあるので注意が必要です。
### 戦略5:コミュニティ参加とナレッジシェア
Reddit、Quora、業界フォーラムでの専門知識の共有は、直接的なリンク獲得だけでなく、AI検索での引用にも効果があります。AI検索エンジンはこれらのプラットフォームを重視しており、ブランド言及の増加はGEO効果にもつながります。
[LinkSurge](https://linksurge.jp/)のSEO順位追跡機能では、バックリンク施策の効果をキーワード順位の変動で定量的に確認できます。施策前後の順位推移を追跡し、どのリンク獲得手法が最も効果的かを検証しましょう。
技術SEO・コンテンツSEO・リンク構築の包括的な戦略については「[2026年SEO対策完全ガイド](/blog/seo-guide-2026/)」でまとめています。
> 参考・引用:
> [Link Building Strategies That Actually Work - Backlinko](https://backlinko.com/link-building-strategies)
> [How to Get High Quality Backlinks - Ahrefs](https://ahrefs.com/blog/how-to-get-backlinks/)
> [Link Building for SEO: The Definitive Guide - Moz](https://moz.com/blog/link-building)
> [Digital PR for Link Building - Search Engine Journal](https://www.searchenginejournal.com/digital-pr-link-building/487322/)
---
## 6. 実例に学ぶ——ペナルティと回復のケーススタディ
### ケース1:ECサイトのPBN利用とペナルティ
国内の中規模ECサイトが、50以上のサテライトサイトからリンクを集めていたケースです。当初は検索順位が上昇しましたが、2022年12月のリンクスパムアップデート後に主要キーワードの順位が80%以上下落。手動対策の通知を受け、サテライトサイトの全閉鎖とリンク否認対応に4ヶ月を費やしました。順位の回復までにさらに6ヶ月。合計10ヶ月間、オーガニック流入がほぼゼロの状態が続きました。
### ケース2:正当なオウンドメディアの成功例
大手B2B企業が運営する業界特化メディアは、メインサイトとは独立した編集チームを持ち、業界の調査レポートやインタビュー記事を定期的に公開しています。メインサイトへのリンクは記事全体の10%未満で、自然な文脈でのみ設置。このメディアはGoogleから高い評価を受け、AI Overviewsでも頻繁に引用されています。
### ケース3:PBNからの脱却と回復
海外のSaaSスタートアップが、初期の成長戦略としてPBNを活用。2023年にアルゴリズムペナルティを受け、オーガニックトラフィックが70%減少。その後、PBNサイトの閉鎖とリンク削除、コンテンツマーケティングへの転換、デジタルPRの開始を経て、約8ヶ月で元のトラフィック水準に回復。さらにその後6ヶ月で過去最高のトラフィックを記録しました。
この事例が示すのは、**PBNからの脱却は痛みを伴うが、正しい戦略に切り替えれば回復可能**ということです。
AI検索時代のSEO戦略全般については「[生成AI検索がSEOを変える:7つの実践対策](/blog/ai-search-seo-japan-2026/)」でも解説しています。
> 参考・引用:
> [Google Link Spam Update Case Studies - Search Engine Roundtable](https://www.seroundtable.com/google-link-spam-update-impact-34651.html)
> [How We Recovered from a Google Penalty - Moz Community](https://moz.com/community/q/topic/how-we-recovered-from-google-penalty)
> [The State of Link Building 2025 - Authority Hacker](https://www.authorityhacker.com/link-building-survey/)
---
## よくある質問(FAQ)
### サテライトサイトとPBNの違いは何ですか?
サテライトサイトは本体サイトとは別に運営するサイトの総称です。地域別サイトやブランド別サイトなど正当な目的で運営されるものも含みます。一方、PBNはリンク操作のみを目的としたサイト群を指します。PBNのサイトは通常、独自のコンテンツや読者を持たず、メインサイトへのリンク供給だけが存在理由です。
### ペナルティを受けたら回復できますか?
回復は可能ですが、時間と労力がかかります。手動対策の場合、問題リンクの特定・リンク否認ファイル作成・再審査リクエストが必要で、全プロセスに3ヶ月〜1年を要することもあります。アルゴリズムペナルティの場合は対処がさらに難しく、根本的なリンク戦略の転換が求められます。
### 中小企業でも安全にバックリンクを増やせますか?
増やせます。大規模な調査データの公開が難しくても、業界フォーラムでの専門知識共有、地元メディアへの情報提供、業界団体のディレクトリ登録など、小さな施策の積み重ねが有効です。[LinkSurge](https://linksurge.jp/)のようなツールで自社の被リンク状況を可視化し、優先度の高い施策から着手するのが効率的です。
### AI検索時代にリンク構築はまだ必要ですか?
必要ですが、その意味が変わりました。従来のSEOではリンクが検索順位の主要因でしたが、AI検索ではブランド言及の方が強い影響力を持ちます。リンク構築を完全にやめるべきではありませんが、リンク獲得だけに頼る戦略は不十分です。被リンク、ブランド言及、E-E-A-T強化を組み合わせた総合的なアプローチが求められます。
[【2026年版】安全なリンクビルディング完全ガイド](/blog/safe-link-building-guide-2026/)では、ペナルティリスクのない5つの被リンク獲得戦略を、コスト・ROI・実行手順とともに詳しく解説しています。
---
## まとめ:リンクを「操作する」時代から「稼ぐ」時代へ
PBNやサテライトサイトによるリンク操作は、SpamBrainの検出精度向上により、2026年時点でリスクとリターンが完全に逆転しました。短期的な順位上昇の見返りに、数ヶ月〜1年間のトラフィック消失というペナルティを受ける可能性があるのです。
まず着手すべきは3つ。
1. 自社の被リンクプロファイルを監査し、不自然なリンクがあればリンク否認ツールで対処する
2. コンテンツマーケティングとデジタルPRに投資し、自然なリンク獲得の仕組みを作る
3. リンク獲得だけでなく、ブランド言及とE-E-A-T強化を並行して進める
LinkSurgeの[AI Overview分析機能](https://linksurge.jp/aio-v5)では、自社サイトへのバックリンクの質と、AI検索での引用状況を統合的に分析できます。安全なリンク戦略への転換を、データに基づいて進めましょう。
---
## なぜyutoriはZ世代から絶大な支持を集めるのか?SNSを駆使したブランド戦略を徹底解剖
> URL: https://linksurge.jp/blog/yutori-sns-brand-strategy-2026/
> Date: 2026-02-14 | Category: SNS | Author: 緒方亜朗
> Tags: SNS戦略, Z世代マーケティング, D2C, yutori, ブランド戦略, UGC, TikTok, Instagram
## この記事の結論:yutoriに学ぶSNSブランド戦略5つの要点
創業からわずか5年8ヶ月でアパレル業界最速の上場を果たし、2025年3月期の売上高は前年比92%増の約83億円。yutoriの成長速度は異常値です。私がこの企業のSNS運用とブランド戦略を調べるほど、「従来のアパレルの常識」が通用しない世界が見えてきました。以下の5つが、他社にも応用可能な核心です。
1. **ブランドアカウント自体をインフルエンサー化する** — 企業の公式感を排除し、スタッフの日常や人格が前面に出る運用を徹底。フォロワーは「企業をフォローしている」のではなく「人をフォローしている」感覚になる。yutoriグループ全体のSNSフォロワーは累計約289万人に達している
2. **Y-League方式でブランドを高速で選別する** — 月商700万円未満のブランドは自動撤退。「作って終わり」ではなく「作って検証して残す」仕組みを制度化し、現在38ブランドを運営。5年で70ブランド体制を目指している
3. **TikTokの「これどこの?」コメントを購買導線に変える** — スタッフの日常動画にさりげなく商品を映し、コメント欄の質問に購入リンクで返答する。広告感ゼロの購買体験を設計している
4. **ポップアップで「投稿したくなる体験」を仕掛ける** — オフラインイベントをUGC生成装置として設計。来場者のSNS投稿がそのまま次の集客になるOMO戦略を回している
5. **平均年齢20代前半の組織がトレンドを「察知」ではなく「体現」する** — 社員の約半数がクリエイティブ職。採用基準にSNS動画制作能力を含め、ターゲットと同世代の社員がコンテンツを作る構造で、共感の純度を担保している
以下では、各テーマを順に解説します。要点を動画でも解説しています。
{{youtube:1taQPjjvI1U|なぜyutoriはZ世代に刺さるのか|創業5年8か月で上場した企業のSNS設計}}
---
## 1. yutoriとは何者か——「古着女子」から始まった異色のアパレル企業

2018年4月、当時25歳だった片石貴展氏がInstagramアカウント「古着女子」の運営からスタートした会社。それがyutoriの原点です。
初年度の売上は約1000万円。そこからD2Cブランド「9090」を立ち上げ、ZOZOグループ入り(2020年)を経て2023年12月に東証グロース市場へ上場。アパレル企業としては国内最速のIPOでした。
上場後も成長は止まりません。2024年8月には元AKB48の小嶋陽菜氏が手がける「Her lip to」の運営会社heart relationを約17億円で買収。ストリートウェアだけでなくフェミニン領域にも進出し、2026年3月期は売上高110億円を計画しています。
私が注目したいのは、この成長の裏側にある「SNSネイティブな組織設計」です。yutoriは最初から実店舗主導ではなく、SNSでのコミュニティ形成を起点にブランドを作る会社として生まれました。この順序が、従来のアパレル企業とは根本的に違います。
> 参考・引用:
> [yutori片石社長に聞く売上高300億円を見込む成長戦略 - ネットショップ担当者フォーラム](https://netshop.impress.co.jp/node/13923)
> [yutoriがZOZOから独立し上場 - fashionsnap.com](https://www.fashionsnap.com/article/2023-12-27/yutori-listed/)
> [yutoriが17億円でハーリップトゥ運営会社を買収 - WWDJAPAN](https://www.wwdjapan.com/articles/1882106)
---
## 2. Y-League方式——ブランドを「育てる」のではなく「選ぶ」仕組み

### なぜ多ブランド戦略がZ世代に刺さるのか
yutoriは1つのメガブランドに賭けるのではなく、小規模ブランドを多数立ち上げて市場で検証する方式を取っています。2025年3月期末時点で38ブランドを運営し、5年後の目標は70ブランドです。
この背景にはZ世代の消費行動があります。「みんなが着ているブランド」より「自分だけの発見」に価値を感じる世代にとって、ニッチなブランドの発見体験は購買動機そのものです。
### Y-Leagueの具体的な仕組み
ブランド採択後、月次売上でY1~Y5にランク付けされます。Y5(月商700万円未満)に該当するブランドは自動撤退のルールが適用されます。感覚ではなく数字で継続を判断する仕組みが、在庫リスクの限定と成功ブランドへのリソース集中を可能にしています。
この「作って検証して残す」サイクルは、SNSマーケティングとの親和性が高い。新ブランドの立ち上げコストが低いのは、既存のSNSチャネルと物流基盤を共有できるからです。1ブランドあたりの初期投資を抑えつつ、SNSでの反応を見て素早く意思決定できる構造は、他のD2C企業にも参考になるでしょう。
SNSを活用した最新のマーケティング手法と、AIアルゴリズムに評価される投稿設計については「[X・Instagram・LinkedInのAI検索最適化:2026年版SNS戦略ガイド](/blog/sns-ai-search-optimization-2026/)」で詳しく解説しています。
> 参考・引用:
> [yutori片石社長に聞く売上高300億円を見込む成長戦略 - ネットショップ担当者フォーラム](https://netshop.impress.co.jp/node/13923)
> [yutoriの次世代ブランド育成戦略 - WWDJAPAN](https://www.wwdjapan.com/articles/2130123)
> [Z世代から絶大な支持を受けるyutoriを徹底分析 - note](https://note.com/happybranding/n/n44612c7ebc84)
---
## 3. SNS運用の核心——「ブランド=インフルエンサー」という設計思想

### Instagramで「企業感」を消す方法
yutoriのInstagram運用で一番目を引くのは、公式アカウントなのにまったく「公式っぽくない」点です。
商品カタログ的な投稿ではなく、スタッフの日常生活の中に自然に商品が溶け込んでいる。コーディネート写真のキャプションも、ブランドの公式コメントというより個人の感想に近い語り口です。この「ブランドアカウント自体がインフルエンサーのように振る舞う」設計は、フォロワーとの距離を縮める効果を生んでいます。
短尺動画(Reels)やStoriesではトレンド音源を積極的に使い、視聴完了率を高める工夫をしている点も見逃せません。15〜30秒の短尺で「最後まで見たくなる」構成を意識し、保存やDM共有を誘発する仕掛けを入れています。
### TikTokの「これどこの?」を売上に変換する
私がyutoriのSNS戦略で最も秀逸だと感じるのは、TikTokのコメント欄を購買導線に活用している点です。
スタッフが日常のルーティン動画を投稿する。さりげなく着ている服が「9090」のアイテム。視聴者から「これ何のブランド?」「どこで買える?」とコメントが入る。そこに購入リンクを返す——この流れは完全にオーガニックで、広告っぽさがゼロです。
片石社長自身がカンファレンスで「TikTokのコメントから服が売れる」と発言しているように、これは偶然ではなく設計されたUGC戦略です。「宣伝されて買う」のではなく「発見して買う」体験を作ることで、Z世代の広告嫌いというハードルを乗り越えています。
[LinkSurge](https://linksurge.jp/)のSNS分析でも、Z世代向けブランドのAI検索での引用率はSNS上のUGC量と強い相関があることが確認されています。「売り込まない」SNS運用が、結果的にブランドの検索露出も高めるわけです。
> 参考・引用:
> [年商30億円間近のyutoriが語るTikTokのコメントから服が売れる理由 - アプリマーケティング研究所](https://markelabo.com/n/nb5f864dbeaa7)
> [yutoriに学ぶZ世代の心を掴むSNSマーケティング事例 - apparel01.com](https://apparel01.com/2024/05/25/learn-from-yutori-examples-of-sns-marketing-for-apparel-brands-that-capture-the-hearts-of-generation-z/)
> [Instagram企業アカウント運用事例 - real-us.co.jp](https://real-us.co.jp/blog/instagram-company-example3/)
---
## 4. ポップアップとOMO——オフラインを「UGC生成装置」にする

### なぜポップアップがSNS戦略の延長線上にあるのか
yutoriの売上の過半はECですが、リアル店舗への投資も加速しています。2025年3月期末時点で46店舗(前年比2倍)に拡大。さらに9090ブランドは上海ポップアップで海外市場にも進出しました。
ここで注目すべきは、ポップアップの目的が「その場で売ること」だけではない点です。来場者が「来たこと自体をSNSに投稿する」ことまで設計に組み込まれています。限定アイテム、フォトスポット、スタッフとの交流——これらはすべて「投稿したくなる体験」であり、参加者のUGCがそのまま次の来客を呼ぶ循環を生みます。
オンライン(EC+SNS)で認知を広げ、オフライン(ポップアップ)で体験を深め、その体験がまたSNSに投稿されてオンラインに還流する。このOMO(Online Merges with Offline)ループこそ、yutoriのマーケティングの全体像です。
AI検索エンジンがSNS上のブランド言及を重視する傾向は強まっており、UGCの総量がAI引用率に直結する時代が来ています。SNSでのブランド言及とオフサイトSEOの関係については「[91%のAI回答は自社サイト以外から——オフサイトSEOとGEO戦略](/blog/offsite-seo-geo-2026/)」で解説しています。
> 参考・引用:
> [yutori 9090 上海初進出POPUP好調 - PR TIMES](https://prtimes.jp/main/html/rd/p/000000131.000034263.html)
> [yutori 2025年3月期決算 - fashionsnap.com](https://www.fashionsnap.com/article/2025-05-14/yutori/)
> [yutoriのD2C+OMO戦略分析 - note](https://note.com/yamadaaaaaaa/n/n1b28f37d6700)
---
{{linksurge-card}}
## 5. 組織設計——「Z世代がZ世代に売る」構造

### 平均年齢23.8歳の組織が持つ本質的な強み
yutoriの社員は約180名で、平均年齢は23.8歳。社員の約半数がクリエイティブ系の職務に従事しています。
この組織構成は単なる「若い会社」ではありません。ターゲット(Z世代)と同じ世代がコンテンツを制作するため、「Z世代に刺さるコンテンツとは何か」をリサーチする必要がない。自分たちの感覚がそのまま市場のセンサーになる構造です。
### 採用基準に「SNS動画制作力」が含まれている
yutoriの採用で特徴的なのは、「売るセンス」やSNS動画制作能力を明確に評価する点です。マーケティング部門だけでなく、ブランドに関わる全員がコンテンツクリエイターとしての能力を持つことで、外部のクリエイティブエージェンシーに頼らない高速なPDCAが実現しています。
片石社長は「終身雇用が最高でしょ」と発言しており、短期離職が多いスタートアップ業界の中で長期的な組織づくりを志向しているのも興味深い点です。若さとスピードを武器にしつつ、人材の定着にもコミットしている。この両立が、トレンドの波に乗り続けるための土台になっています。
> 参考・引用:
> [片石社長のyutori経営「終身雇用が最高でしょ」 - WWDJAPAN](https://www.wwdjapan.com/articles/1842035)
> [急成長アパレルyutori社長 片石氏に聞く - 日経クロストレンド](https://xtrend.nikkei.com/atcl/contents/18/01060/00003/)
> [yutori Wantedly企業ページ](https://www.wantedly.com/companies/yutori2)
---
## 6. yutori戦略から他社が学べる5つの施策
yutoriの事例は「若い会社だからできた」で終わらせるにはもったいない。SNSマーケティングの観点から、業種を問わず応用可能な施策を整理します。
### 施策1: ブランドアカウントに「人格」を持たせる
企業の公式感を消し、アカウントの「中の人」の人格を前面に出す。投稿のトーンを統一しつつ、商品紹介よりもスタッフの日常を優先する運用に切り替えるだけで、エンゲージメント率は大きく変わります。
### 施策2: コメント欄を購買導線として設計する
TikTokやInstagramで「これどこの?」と聞かれる投稿を意図的に作り、コメント返信で自然に商品リンクを届ける。広告予算ゼロで購買を生むこの手法は、飲食・コスメ・インテリアなど幅広い業種で再現可能です。
### 施策3: 小規模テスト→数字判断→撤退/拡大のサイクルを回す
Y-Leagueのような定量基準を設け、感覚ではなく数字でプロジェクトの継続を判断する。ECやSNSの施策すべてに適用できるフレームワークです。
### 施策4: オフラインイベントをSNS投稿の「素材」にする
ポップアップやイベントの企画段階で「来場者が何をSNSに投稿するか」を設計する。フォトスポット設置、限定商品、スタッフ交流など、投稿動機を複数仕込むことがポイントです。
### 施策5: ターゲット世代の人材を採用し、コンテンツ制作を内製化する
外部クリエイターへの発注ではなく、ターゲットと同世代の社内メンバーがコンテンツを作る体制を構築する。「リサーチして寄せる」のではなく「自然に分かっている人が作る」ほうが、共感の質が段違いになります。
[LinkSurge](https://linksurge.jp/)のAI Overview分析を使えば、自社ブランドがAI検索でどの程度言及されているかをキーワード単位で確認できます。SNS施策の成果がAI検索にどう波及しているかを可視化することで、投資判断の精度が上がります。
> 参考・引用:
> [yutoriに学ぶ次世代ブランド育成戦略 - WWDJAPAN](https://www.wwdjapan.com/articles/2130123)
> [Z世代がビジネスを変える:yutoriから学ぶマーケティングの新常識 - note](https://note.com/men_in_black/n/n2271d42eca17)
> [yutoriの成長戦略を分析 - CBOラボ](https://cbo-media.com/lab/yutori-2)
---
## 7. yutori戦略の限界とリスク
成長企業の事例を紹介する以上、リスクにも触れておきたいと思います。
**ブランド希薄化のリスク** — 38ブランドを同時に運営するということは、個々のブランドストーリーが浅くなるリスクと表裏一体です。Y-Leagueの撤退ルールで在庫リスクは限定されますが、「ブランドを育てる」より「ブランドを試す」に偏りすぎると、長期的なファン層の蓄積が弱くなる可能性があります。
**若年組織のガバナンスリスク** — 平均年齢23.8歳のスピード経営は強みですが、SNS炎上対応やコンプライアンス管理では経験値の不足がリスク要因になり得ます。公開情報では炎上事例は確認されていませんが、事業拡大に伴いリスク管理体制の強化は避けて通れないテーマでしょう。
**トレンド依存の脆弱性** — Z世代のトレンドは回転が速く、今日の人気ブランドが半年後も同じ勢いを保てる保証はありません。多ブランド体制はこのリスクの分散策でもありますが、全体として「常にトレンドの最前線にいなければならない」というプレッシャーは経営に負荷をかけ続けます。
こうしたリスクを含めてもなお、yutoriの仕組みは「仕組みとして再現可能」な要素が多い点が評価できます。
---
## よくある質問(FAQ)
### yutoriの主力ブランド「9090」とはどんなブランド?
2018年にスタートしたオールドカルチャーMIXのストリートブランドで、1990年代〜2000年代のユースカルチャーをコンセプトにしています。yutoriグループの中で最も知名度が高く、2025年には上海ポップアップで海外進出も果たしています。
### Y-Leagueとは何ですか?
yutoriが採用しているブランド評価制度です。ブランドを月次売上に応じてY1〜Y5の5段階にランク付けし、Y5(月商700万円未満)に該当するブランドには自動撤退ルールが適用されます。感覚ではなく定量基準で事業判断を行う仕組みです。
### なぜyutoriのSNS運用はZ世代に刺さるのか?
ターゲットと同世代(平均年齢23.8歳)の社員がコンテンツを制作しているため、「共感」の質が本質的に高い点が最大の要因です。加えて、公式アカウントに「人格」を持たせ、商品紹介より日常コンテンツを優先する運用方針が、広告を嫌うZ世代の信頼を獲得しています。
### yutoriの戦略は他業種にも応用できる?
ブランドアカウントの人格化、コメント欄を活用した購買導線、定量基準によるプロジェクト選別(Y-League方式)、オフラインイベントのUGC設計——これらの施策は業種を問わず応用可能です。特にD2CやEC事業者にとっては、低コストで始められるものが多いでしょう。SNSの効果測定には[LinkSurge](https://linksurge.jp/)などの分析ツールを活用し、AI検索での引用状況も併せてモニタリングすることをおすすめします。
---
## まとめ:yutoriに学ぶ「SNSファーストの経営」
yutoriの成功は、単なるSNSマーケティングの巧さではなく、SNSを中心に据えた経営設計全体にあります。組織、採用、ブランド管理、商品開発——すべてがSNSでの反応を最速でキャッチして行動に移すために最適化されている。
まず始められることは3つです。自社のSNSアカウントに「人格」を持たせること。TikTokやInstagramのコメント欄を購買導線として活用すること。そしてプロジェクトの継続判断にY-League的な定量基準を導入すること。
SNS施策とAI検索は連動しています。[LinkSurge](https://linksurge.jp/)の[AI Overview分析機能](https://linksurge.jp/aio-v5)を使えば、SNSでのブランド露出がGoogle AI Overviewsでの引用にどう波及しているかをリアルタイムで確認できます。
---
## X・Instagram・LinkedInのAI検索最適化:2026年版SNS戦略ガイド
> URL: https://linksurge.jp/blog/sns-ai-search-optimization-2026/
> Date: 2026-02-13 | Category: SNS | Author: 緒方亜朗
> Tags: SNS戦略, AI検索最適化, X Twitter, Instagram, LinkedIn, アルゴリズム, ソーシャルメディア
## この記事の結論:2026年SNSでAIに選ばれる5つの要点
2026年のSNSは、もはや「人の目に触れる」だけでは不十分です。AIが投稿を評価し、推薦し、検索結果に引用する——そんな時代のSNS戦略には、従来とは違う発想が求められます。私が各プラットフォームのアルゴリズムを調査して見えてきた、実践上の要点は以下の5つです。
1. **プラットフォームごとのAIシグナルを把握する** — Xは滞在時間とDM共有、Instagramは視聴完了率と保存率、LinkedInはセマンティック検索とスライド完了率。アルゴリズムが見ている指標を理解しないまま投稿しても、拡散されるのは運頼みになってしまう
2. **コンテンツ形式をアルゴリズムに合わせる** — Xは情報密度の高いスレッド、Instagramは30〜90秒のReels+カルーセル、LinkedInはマルチ画像カルーセルとドキュメント。「何を言うか」だけでなく「どの器で届けるか」がリーチを決める
3. **ハッシュタグはAIで動的に選定する** — 最適な個数はX:1〜2個、Instagram:5〜8個、LinkedIn:3〜5個と差がある。毎回同じタグを使い回すのはスパム判定のリスクがあり、AIツールでトレンドと競合度を見ながら投稿ごとに切り替えたい
4. **AIスケジューラで最適時間に自動配信する** — 過去のエンゲージメントパターンをAIがリアルタイムで学習し、地域・曜日別の最適タイミングを割り出してくれる。人間の勘に頼る時代はもう終わった
5. **投稿後60分以内の初動エンゲージメントが勝負を分ける** — アルゴリズムは投稿直後の反応を見て「もっと広く配信するか」を判断する。社内メンバーやインフルエンサーの初動コメントを設計に組み込むだけで、到達範囲が数倍になるケースがある
以下では、各テーマを順に掘り下げていきます。
---
## 1. AIが支配する2026年のSNSアルゴリズム

2026年現在、X・Instagram・LinkedInの3大プラットフォームは、いずれもTransformerベースの大規模言語モデルや独自のAIシステムをレコメンデーションエンジンに採用しています。
率直に言って、「投稿すればフォロワーに届く」という牧歌的な時代はとっくに過ぎました。今はアルゴリズムが「この投稿を誰に、どの順番で見せるか」を決めている。ここを理解せずにSNS施策を回しても、空振りが増えるだけです。
| プラットフォーム | AIエンジン | 最重要シグナル | 2026年の注目機能 |
|:---|:---|:---|:---|
| **X(Twitter)** | Grok(Transformerベース)、推薦コードが公開済み | 閲覧秒数、DM共有数 | プロンプト駆動検索、AI生成コンテンツの自動投稿パイプライン |
| **Instagram** | 複数AIシステム(フィード・Reels・Stories・Exploreを個別最適化) | 1〜3秒フック保持率、視聴完了率、保存率、シェア率 | Movie Gen(テキスト→動画AI編集)、ハッシュタグ自動最適化 |
| **LinkedIn** | 360Brew(大規模Mixture-of-Experts)、セマンティック検索 | コメント・シェアの質、コンテンツ形式別エンゲージメント率 | AI職務・スキル自動抽出、リアルタイムエンゲージメント予測 |
### Xのアルゴリズム:Grokと閲覧秒数の時代
Xの推薦アルゴリズムは2023年にソースコードが公開され、その仕組みがかなりの程度まで可視化されました。2026年現在もTransformerベースのモデル(Grok統合)が中核です。
公開コードを読んで驚いたのは、**閲覧秒数とDM共有のスコアが飛び抜けて高い**こと。「いいね」の重みが相対的に低い一方で、「投稿を開いて読み込んだ時間」と「友人にDMで転送した回数」がアルゴリズム上の重大シグナルになっています。
要するに、スクロールの手を止めさせる投稿が勝つ。タイムラインに流れてきたときに「おっ」と思わせ、最後まで読ませる情報密度がカギです。
もう一つ見逃せないのが `P(not_interested)` というスコア。ユーザーが「興味なし」と判断しそうな投稿は表示頻度を下げる仕組みです。質の低い連投は単にスルーされるだけでなく、アカウント全体の表示を絞られるリスクがあるわけです。
### Instagramのアルゴリズム:4つのAIが裏で動いている
Instagramは**フィード、Reels、Stories、Exploreの4領域それぞれに異なるAIシステム**を走らせています。2026年には「Your Algorithm」機能が追加され、ユーザー自身がコンテンツの嗜好を調整できるようになりました。
新規リーチに最も効くのは**最初の1〜3秒のフック保持率**。ここで離脱されたら、本編がどんなに良くても拡散されません。次に効くのが**保存率とシェア率**(Sends per Reach)——「後で見返したい」「友達に送りたい」と思わせるコンテンツがアルゴリズムに好まれます。
考えてみれば当然で、「保存」や「シェア」はユーザーが能動的にアクションを起こした証拠。「いいね」より一段強い信号として扱われるのは理にかなっています。
### LinkedInのアルゴリズム:セマンティック検索エンジンに進化
LinkedInは2025年に360Brewと呼ばれるMixture-of-Expertsモデルを検索エンジンに統合しました。**キーワード一致ではなく意味レベルでの検索**が実現し、さらにAI-Powered People Searchが追加されてプロフィールの職務・スキル情報をAIが自動抽出して検索クエリを拡張します。
コンテンツ面で面白いのは、画像・マルチ画像・ドキュメント形式の投稿がテキストのみの投稿を大幅に上回るエンゲージメント率を叩き出している点。また、コメントの「質」も評価対象で、短い「いいですね」より具体的な意見や質問のほうがアルゴリズムの評価は高い。表面的なリアクションよりも、本質的な議論を生む投稿が報われる仕組みです。
AI検索エンジン(ChatGPT、Perplexity等)がSNS投稿を引用ソースとして参照するケースも目立ち始めています。この潮流について詳しくは「[生成AI検索がSEOを変える:7つの実践対策](/blog/ai-search-seo-japan-2026/)」をご覧ください。
> 参考・引用:
> [Twitter/X algorithm update analysis - LinkedIn](https://www.linkedin.com/posts/tschranz_twitter-x-just-updated-its-algorithm-activity-7372287244323176448-g42d)
> [How the Instagram Algorithm Works in 2025 - Hootsuite](https://blog.hootsuite.com/instagram-algorithm/)
> [LinkedIn 360Brew Semantic Search - arXiv](https://arxiv.org/html/2602.07309v1)
> [X publishes AI-powered algorithm code - Social Media Today](https://www.socialmediatoday.com/news/x-formerly-twitter-publishes-ai-powered-algorithm-code/810015/)
---
## 2. プラットフォーム別コンテンツ形式戦略
アルゴリズムの仕組みを押さえたところで、次は「どの形式で投稿すればAIに評価されるか」を具体的に見ていきます。結論から言えば、各プラットフォームで「勝てるフォーマット」は明確に異なります。
### Xで効くのはスレッドと画像付きツイート

Xでは情報密度の高い**スレッド**(連続ツイート)が最も効果的です。理由は単純で、スレッドはユーザーの滞在時間を伸ばすから。1ツイートでスクロールされるよりも、5〜10連投のスレッドを最後まで読んでもらうほうが閲覧秒数は大幅に上がります。
実際に自分のアカウントで試してみても、データ分析系のスレッドは単発ツイートの3〜5倍のインプレッションが出ることが多いです。
| 形式 | AIスコアへの影響 | 推奨用途 |
|:---|:---|:---|
| スレッド(5〜10投稿) | ◎ 閲覧秒数最大化 | ノウハウ解説、データ分析、事例紹介 |
| 画像付きツイート | ○ 停止率向上 | インフォグラフィック、チャート、スクリーンショット |
| 短尺動画(2分以内) | ○ DM共有されやすい | チュートリアル、速報解説 |
| テキストのみ | △ 滞在時間が短い | 速報、意見表明 |
### Instagramは「Reels+カルーセル」の二刀流

Instagramでは**Reels(30〜90秒)が新規リーチの主戦場**。一方、**カルーセル(最大20枚)は滞在時間と二次閲覧で高評価**を得やすく、既存フォロワーとのエンゲージメント強化に向いています。
Reelsで押さえるべきは3つ。冒頭3秒のフック、30秒以内でのコアメッセージ提示、そしてシェアを促すCTA(「保存して後で見返して」「友達にシェアして」)です。
カルーセルは「問題提起→解説→解決策→CTA」の流れで構成すると、最終スライドまでの到達率が上がります。私が観察した範囲では、7〜10枚構成のカルーセルが最も完了率と保存率のバランスが良い印象です。
### LinkedInはマルチ画像カルーセルとドキュメント
LinkedInではマルチ画像カルーセルとネイティブドキュメント(PDF)がエンゲージメント率のトップを走っています。特にカルーセルは「2枚目以降のスライドまで閲覧した」というシグナルがアルゴリズムに強く評価される仕組みです。
短尺動画(60秒以内)も有効ですが、LinkedInのユーザーは音声オフで閲覧するケースがかなり多い。**字幕やテキストオーバーレイは必須**と考えてください。音声に依存した動画は、せっかくの内容が伝わらないまま離脱されてしまいます。
> 参考・引用:
> [Instagram Algorithm 2025: Which Content Formats Get the Most Reach - Atlas SEO](https://www.atlasseo.co.uk/news/instagram-algorithm-2025--which-content-formats-get-the-most-reach/)
> [LinkedIn Social Media Benchmarks - Social Insider](https://www.socialinsider.io/social-media-benchmarks/linkedin)
> [Top LinkedIn Content Wins 2025 - Souvik Dutta](https://www.linkedin.com/pulse/top-linkedin-content-wins-2025-what-worked-why-souvik-dutta--ygbmc)
---
## 3. ハッシュタグ戦略:使い回しが一番危ない
ハッシュタグは「検索の入口」であると同時に、AIアルゴリズムがコンテンツのテーマを理解するための手がかりでもあります。ただし、最適な個数と使い方はプラットフォームによってかなり違います。
| プラットフォーム | 推奨個数 | ポイント |
|:---|:---|:---|
| **X** | 1〜2個 | 文字数制限があるため厳選。トレンドタグを1つ+ブランドタグを1つ |
| **Instagram** | 5〜8個 | ニッチ・コミュニティ系を中心に。大量タグ(30個)はむしろ逆効果 |
| **LinkedIn** | 3〜5個 | 業界・テーマ別タグを本文中に自然に組み込む |
### なぜ毎回同じハッシュタグではダメなのか
これは意外と見落とされがちなポイントです。同じハッシュタグを毎回コピペしていると、アルゴリズムに「スパム的」と判定されるリスクがあります。特にInstagramでは、同一タグの反復使用がシャドウバンの原因になったケースが複数報告されています。
AIツール(Bika.ai、PostNitro等)を活用すれば、投稿内容に応じたハッシュタグの候補を自動生成し、トレンド度と競合度を数値で比較できます。手動で毎回調べるよりも精度が高く、何より時間が大幅に浮きます。自分もハッシュタグ選定に毎回10分以上かけていた頃がありましたが、AIツール導入後は2分で済むようになりました。
> 参考・引用:
> [How to Generate Hashtags with AI - ASCN](https://ascn.ai/blog-no-code/kak_pravilno_sdelat_heshtegi_s_pomoshchyu_ai)
---
## 4. 投稿時間の最適化とAIスケジューリング

「いつ投稿するか」は依然として重要な変数です。ただし2026年は、人間の勘ではなくAIが過去のエンゲージメントパターンを解析して最適時間を割り出す時代です。
### プラットフォーム別の推奨時間帯(日本時間)
| プラットフォーム | 推奨時間帯 | 曜日 |
|:---|:---|:---|
| **X** | 12:00〜15:00、17:00〜19:00 | 平日全般 |
| **Instagram** | 9:00〜13:00、18:00〜20:00 | 月〜金 |
| **LinkedIn** | 8:00〜10:00、12:00〜14:00、17:00〜18:00 | 火〜木が最も効果的 |
ただし、上記はあくまで全体平均です。実際には自社のフォロワー層によって最適な時間帯は異なるため、Buffer、Sprout Social、Rebrandlyなどの**AIスケジューラ**が過去データから算出する「パーソナライズド最適時間」を使ったほうが確実です。
私の経験でも、「一般的なベストタイム」と「自社アカウントの最適時間」にはけっこうズレがあります。LinkedInで火曜10時が一般的にベストとされていても、自社のフォロワーが夕方のほうが活発というケースは珍しくありません。
### AIスケジューリングツールの選び方
| ツール | 特徴 | 対応プラットフォーム |
|:---|:---|:---|
| **Buffer + Zapier** | ChatGPTで生成した投稿を自動キュー投入 | X |
| **Sprout Social ViralPost®** | 機械学習で最適送信時刻を自動算出 | LinkedIn・Instagram |
| **Rebrandly** | クリックデータに基づく最適投稿時間算出 | 全プラットフォーム |
| **Bika.ai** | アイデア生成からスケジューリングまでワンストップ | X |
> 参考・引用:
> [Best Time to Post on Social Media Using AI-Backed Click Data - Rebrandly](https://www.rebrandly.com/blog/best-time-to-post-on-social-media-using-ai-backed-click-data)
> [Best Times to Post on LinkedIn - Sprout Social](https://sproutsocial.com/insights/best-times-to-post-on-linkedin/)
> [How to Automate Twitter/X Posts with AI - Bika.ai](https://bika.ai/blog/how-to-automate-twitter-x-posts-with-ai)
---
## 5. パフォーマンス測定:見るべき指標が変わった
SNS施策の成果を測るKPIは、2026年に入って明確にシフトしました。「いいね数」「フォロワー増減」だけ追っていると、アルゴリズムの評価軸を見落とします。**AIが重視するシグナルとAI検索での引用頻度**を追跡する視点が不可欠です。
### プラットフォーム別の重要KPI
| 指標カテゴリ | X | Instagram | LinkedIn |
|:---|:---|:---|:---|
| **滞在時間系** | 閲覧秒数 | フック保持率、総視聴時間 | スライド完了率、平均視聴秒数 |
| **エンゲージメント** | RT率(業界平均0.12%) | 保存率、Sends per Reach | インプレッション当たりエンゲージ率(平均5.2%) |
| **共有・拡散** | DM共有数 | シェア数 | コメントの質、インフルエンサーからのシェア |
| **AI固有** | AI検索での引用回数 | セマンティック関連度 | プロファイル最適化スコア |
### AI検索での引用頻度をどう計測するか
ChatGPTやPerplexityがSNS投稿を引用ソースとして参照するケースが確実に増えています。自社のSNS投稿がAI回答にどれだけ引用されているかを追跡するには、[LinkSurge](https://linksurge.jp/)のGEO Monitor機能が使いやすいです。主要なAIプラットフォームでの引用状況をキーワード単位でモニタリングし、Citation Rate(引用率)の推移を可視化してくれます。
この「AI検索にSNSコンテンツがどう位置づけられるか」という論点は、「[AI検索に選ばれるには「自サイトの外」が9割](/blog/offsite-seo-geo-2026/)」でも掘り下げていますので、あわせてどうぞ。
> 参考・引用:
> [AI Search Metrics - O8 Agency](https://www.o8.agency/blog/ai/ai-search-metrics)
> [Social Media Benchmarks 2025 - Social Insider](https://www.socialinsider.io/social-media-benchmarks)
> [LinkedIn Social Media Benchmarks - Social Insider](https://www.socialinsider.io/social-media-benchmarks/linkedin)
---
## 6. ケーススタディ:理論を裏付ける実践事例
データと理論を並べるだけでは説得力に欠けるので、実際の成功事例を見てみましょう。いずれもこの記事で解説した原則を体現しているケースです。
### 事例1:B2B SaaS企業のLinkedIn戦略(インプレッション7倍)
あるB2B SaaS企業は、カルーセル投稿に「問題→解決→CTA」フォーマットを徹底的に採用しました。加えて、**投稿後60分以内に社内5名がコメント・シェアを実施**するルールを設定。結果、週間インプレッションが2,400から18,000へ7倍に伸び、リード獲得率も3.5%増加しています。
注目すべきは「投稿の質」だけでなく「初動エンゲージメントの設計」を仕組み化した点。アルゴリズムは投稿直後の反応速度を見て配信範囲を決めるので、初動設計はコンテンツの質と同じくらい成果を左右します。
### 事例2:ファッションブランドのInstagram Reels戦略(視聴完了率68%)
グローバルファッションブランドがAI動画編集ツール(Movie Gen)を活用し、テキスト指示からシーン変更を行った30秒Reelsを週2本配信。冒頭3秒にインパクトのあるビジュアルフックを入れた結果、**視聴完了率68%**(業界平均は約45%)を達成。月間フォロワー増加率12%を記録しました。
業界平均を20ポイント以上上回っている要因は、やはり冒頭3秒の設計にあります。最初のフレームで「何これ?」と思わせるビジュアルのインパクトが、完了率の分水嶺になっている。
日本のD2Cアパレル企業yutoriは、スタッフの日常動画にさりげなく商品を映すTikTok・Reels戦略でZ世代を席巻しています。SNSアカウント自体をインフルエンサー化する手法やY-League式ブランド選別の仕組みについては「[yutoriのSNSブランド戦略を徹底解剖](/blog/yutori-sns-brand-strategy-2026/)」で詳しく解説しています。
なおTikTok単体のアルゴリズム(完了率・シェア・再視聴)とAI検索エンジンへの引用経路については、姉妹記事「[TikTok検索最適化の教科書:Z世代の40%が使う新検索エンジンで勝つ戦略 2026年版](/blog/tiktok-seo-ai-search-2026/)」でより深く掘り下げています。
### 事例3:スタートアップのクロスプラットフォーム戦略(エンゲージメント45%向上)
日本のあるスタートアップは、AIで生成したハッシュタグとスケジューラを統合し、X・Instagram・LinkedInで3カ月間同時展開。ポイントは、同じ内容をコピペするのではなく、プラットフォームごとにコンテンツ形式を最適化したこと(Xはスレッド、Instagramはカルーセル、LinkedInはドキュメント)。**総エンゲージメント45%向上、フォロワー数30%増加**という数字が出ています。
「1つのネタをプラットフォームに合わせて変換する」というアプローチは、リソースが限られた組織でも実行しやすい方法です。
> 参考・引用:
> [Top LinkedIn Content Wins 2025 - Souvik Dutta](https://www.linkedin.com/pulse/top-linkedin-content-wins-2025-what-worked-why-souvik-dutta--ygbmc)
> [Instagram Algorithm 2025 - Enrich Labs](https://www.enrichlabs.ai/blog/instagram-algorithm-2025)
---
## 7. 日本市場のSNS利用傾向と戦略ローカライズ

海外の成功事例をそのまま輸入しても日本では通用しないケースがあります。日本のSNS市場にはグローバルとは異なる独自の特徴があり、ローカライズの精度が成果を左右します。
| プラットフォーム | 日本のMAU | 主な年齢層 | 日本特有の利用傾向 |
|:---|:---|:---|:---|
| **X** | 約6,690万人 | 20〜49歳 | 匿名文化が根付き、リアルタイムニュースと災害情報の発信拠点 |
| **Instagram** | 約3,550万人 | 18〜34歳 | ファッション・グルメ・ライフスタイル中心、ビジュアル美学を重視 |
| **LinkedIn** | 約2,500万人(推定) | 30〜50歳 | ビジネスネットワーキング・採用・B2Bリード。アジア太平洋で急成長中 |
Xは米国に次ぐ世界第2位の市場です。日本独特なのは匿名での情報共有文化で、「企業の公式アカウント」よりも「中の人が見える個人アカウント」のほうがエンゲージメントを取りやすい傾向があります。これはグローバルとはやや異なるダイナミクスです。
LinkedInについては、日本語プロファイルの構造化データ(職務経歴、スキル、資格)をAIが自動抽出するため、プロフィールの充実度がコンテンツのリーチにも影響する点を見逃さないでください。
SNSでの存在感がAI検索での引用にもつながるというのは、GEO(Generative Engine Optimization)の観点から非常に興味深いテーマです。「[GEO完全ガイド](/blog/geo-guide-japan-2026/)」で体系的に解説していますので、あわせてどうぞ。
> 参考・引用:
> [Social Media in Japan: A Complete Guide - ULPA](https://www.ulpa.jp/post/social-media-in-japan-a-complete-guide)
> [Japan's Top Social Media Networks - Humble Bunny](https://www.humblebunny.com/japan-top-social-media-networks/)
---
{{linksurge-card}}
---
## 8. 2026年アクションプラン:今日から始める7ステップ
ここまでの内容を「じゃあ具体的に何をすればいいのか」に落とし込みます。3フェーズに分けて整理しました。
**フェーズ1:現状把握(1週間)**
1. **アルゴリズムシグナルの棚卸し** — 自社アカウントの過去30日分の投稿を分析し、滞在時間・保存率・シェア率など各プラットフォームの重要指標を確認する。数字を見る前にコンテンツ戦略を組むのは、地図なしで登山するようなものです
2. **競合アカウントの調査** — 同業他社のSNS投稿を[LinkSurge](https://linksurge.jp/)やSocial Insiderで分析し、高エンゲージメント投稿の形式・時間帯・ハッシュタグを特定する
**フェーズ2:コンテンツ設計と仕組み化(2〜3週間)**
3. **プラットフォーム別テンプレートを作成** — Xはスレッド構成テンプレート、Instagramは「フック→本題→CTA」のReels台本、LinkedInは「問題→解決→CTA」のカルーセル構成。テンプレートがあると、制作時間が体感で半分以下になります
4. **AIスケジューラを導入** — Buffer、Sprout Social、Rebrandlyなどから自社に合ったツールを選定し、最適投稿時間の自動算出を設定する
5. **ハッシュタグ生成フローを構築** — AIツールで投稿ごとにハッシュタグを動的生成し、トレンドと競合度を毎回チェックする運用を定着させる
**フェーズ3:運用と改善(継続)**
6. **初動エンゲージメントのルール化** — 投稿後60分以内に社内メンバー3〜5名がコメント・シェアを実施するルールを設定。これだけでアルゴリズムの初期評価が目に見えて変わります
7. **月次KPIレビュー** — 滞在時間、保存率、シェア率、AI検索での引用回数を月次で追跡し、コンテンツ形式・投稿時間・ハッシュタグ戦略を継続的にチューニングする
SEO・AI検索対策の全体像については「[2026年最新 SEO対策完全ガイド](/blog/seo-guide-2026/)」もあわせてご覧ください。
> 参考・引用:
> [How to Automate Your X/Twitter So It Grows Itself - Medium/Zapier](https://medium.com/zapier-ai-automation/how-to-automate-your-x-twitter-so-it-grows-itself-incl-video-2d83b705234b)
> [Instagram Algorithm 2025 Complete Guide for Marketers - Dataslayer](https://dataslayer.ai/blog/instagram-algorithm-2025-complete-guide-for-marketers)
---
## よくある質問(FAQ)
### SNSの投稿頻度はどのくらいが最適ですか?
プラットフォームによって異なります。Xは1日3〜5投稿(スレッド含む)、Instagramは週3〜5投稿(Reels2本+カルーセル2本程度)、LinkedInは週2〜3投稿が目安です。ただし、頻度を追うよりも、アルゴリズムが重視するシグナル(滞在時間・保存率・シェア率)を満たす質の高い投稿を優先すべきです。週5本の薄い投稿より、週2本の濃い投稿のほうがリーチは伸びます。
### AIが生成したコンテンツをそのまま投稿しても大丈夫ですか?
AIで下書きを作成すること自体は問題ありません。ただし、そのまま投稿すると「AI生成コンテンツ」としてアルゴリズムに低評価される可能性があります。自社の声やトーンを反映させる人間の編集プロセスは必ず入れてください。特にLinkedInでは、個人の経験や意見を含むオリジナルコンテンツが明確に優遇されています。AIはあくまで下書きのアシスタント。最終的な判断と味付けは人間が担うべきです。
### 3つのプラットフォームすべてに注力すべきですか?
リソースが限られている場合は、自社のターゲット層に最も近い1〜2つに集中するほうが効果的です。B2BならまずはLinkedIn、若年層向けならInstagram、リアルタイム性を重視するならXを優先しましょう。クロスプラットフォーム展開は、1つのプラットフォームで型ができてからでも遅くありません。最初から3つに手を出して全部中途半端になるのが一番もったいないパターンです。
### SNSの投稿がAI検索(ChatGPTなど)に引用されることはありますか?
はい、増えています。特にLinkedInの長文投稿やXのスレッドは、ChatGPTやPerplexityが回答生成時に引用ソースとして参照するケースが確認されています。構造化されたデータ、具体的な数値、専門的な知見を含むSNS投稿ほど引用されやすい傾向です。[LinkSurge](https://linksurge.jp/)のGEO Monitor機能で、自社コンテンツのAI引用状況を追跡できます。
---
## まとめ:AI時代のSNS戦略は「シグナル設計」から始まる
2026年のSNSマーケティングは、3つの軸で回っています。アルゴリズムが重視するシグナル(滞在時間・保存率・シェア率)を意識したコンテンツ設計。AIツールによるハッシュタグ生成とスケジューリングの自動化。そして、投稿後60分以内の初動エンゲージメント設計。
X・Instagram・LinkedInの各プラットフォームが採用するAIモデルは異なりますが、共通しているのは、**「ユーザーが本当に価値を感じたかどうか」を数値で測っている**という点です。表面的なバズではなく、ターゲットに深く刺さるコンテンツを、最適な形式とタイミングで届ける——その仕組みを構築した組織が、2026年のSNSで結果を出しています。
LinkSurgeの[GEO Monitor機能](https://linksurge.jp/)では、SNS投稿を含む自社コンテンツがAI検索でどのように引用されているかをリアルタイムで分析できます。
---
## AI検索に選ばれるには「自サイトの外」が9割:2026年ブランド露出の実践ガイド
> URL: https://linksurge.jp/blog/offsite-seo-geo-2026/
> Date: 2026-02-12 | Category: GEO | Author: 緒方亜朗
> Tags: GEO, オフサイトSEO, AI検索, ブランド言及, LLM引用, ChatGPT, Perplexity
## この記事の結論:自サイトの最適化だけではAIに引用されない
私がAI検索の引用パターンを分析していて最も意外だったのは、「自サイトの品質」よりも「自サイトの外でどれだけ名前が出ているか」の方がはるかに影響が大きいという事実です。AI検索エンジンは、検索結果の上位に並ぶ複数の情報源を横断的に読み取って回答を組み立てます。つまり、自サイトの順位だけでなく「検索結果ページ全体にどれだけ自分のブランドが露出しているか」がAI引用の成否を左右します。以下の5つが実践上の要点です。
1. **ブランド言及数がAI引用と最も強く相関する** — Ahrefsの75,000ブランド調査(AI Overviews対象)で、相関が最も高かったのはブランドWeb言及数(r=0.664)。被リンク数(r=0.218)の約3倍にあたる。ただしこれは相関であり、因果が示されたものではない
2. **検索結果1位だけでは不十分** — AI検索エンジンは上位10件のスニペットを横断的に読み取る。1位を独占するより、比較記事・レビュー・フォーラムなど複数の結果に名前が出ることが重要
3. **第三者ソースがAI回答の91%を占める** — AI生成回答で自社サイトが直接引用されるのはわずか9%。残り91%はReddit・Quora・業界メディアなどの第三者コンテンツ経由
4. **プラットフォームごとに引用傾向が違う** — ChatGPTは百科事典的なソース、PerplexityはUGCと新しい情報を重視する傾向。両者で共通して引用されるドメインはわずか11%で、この乖離は複数の調査で確認されている(個別の引用割合は変動が大きいため本文の注記を参照)
5. **ゼロクリック時代、SERP上の存在感こそが資産** — 2024年の米国Google検索全体のゼロクリック率は58.5%(SparkToro / Datos の調査)。AI Overviews表示時の1位CTRはAhrefsの推計で58%低下。クリックされなくてもAIの参照ソースに入ることが新たなKPI
以下では、各テーマを順に解説します。
---
## 1. 「オフサイトSEO」とは何か?——自サイトの外で行うSEO活動

まず用語を整理します。SEO(検索エンジン最適化)には大きく2種類あります。
| 種類 | 何をするか | 具体例 |
|------|-----------|--------|
| **オンサイトSEO** | 自分のサイト内部を改善する | ページ速度の改善、メタタグの最適化、コンテンツの質向上、構造化データの実装 |
| **オフサイトSEO** | 自分のサイト以外の場所でブランドの存在感を高める | 他サイトでのブランド言及、業界メディアへの寄稿、フォーラムでの専門知識共有、レビューサイトでの評価獲得 |
「オフサイトSEO」を一言でいえば、**自サイトの外で自分のブランド名が語られる状態を作ること**です。
従来のオフサイトSEOは「被リンクを獲得すること」がほぼすべてでした。他のサイトからリンクをもらえば、Googleの評価が上がり、検索順位が向上する。これが従来の常識です。
しかし2026年、AI検索の台頭によってオフサイトSEOの意味は大きく変わりました。リンクをもらうことよりも、**ブランド名がさまざまな場所で言及されていること**の方がはるかに重要になっています。なぜそうなったのかを、次のセクションから順に解説します。
> 参考・引用:
> [GEO vs SEO: What's The Difference And Why It Matters? - Writesonic](https://writesonic.com/blog/geo-vs-seo)
> [Generative Engine Optimization (GEO): Is It the New SEO? - Built In](https://builtin.com/articles/generative-engine-optimization-new-seo)
---
## 2. AI検索エンジンはどのようにWebを「見る」のか

ChatGPT・Perplexity・Google AI Overviewsがどのように情報を取得し、回答を生成するかを理解することが出発点です。
### AI検索の5ステップ
私がChatGPTやPerplexityの挙動を観察してきた中で見えてきた、AI検索エンジンの基本フローがこれです。ユーザーの質問を受け取ると、おおむね次の流れで回答を生成します。
1. **クエリ分解** — ユーザーの質問を1〜5個の検索キーワードに分解する
2. **検索グラウンディング** — 分解したキーワードで検索インデックスに問い合わせる(Google AI OverviewsやGeminiはGoogleのインデックス、ChatGPTやPerplexityは自前のインデックスや提携先を使う)
3. **スニペット要約** — 返ってきた検索結果のスニペット(タイトル+説明文)を全件読み取る
4. **選択的ディープリード** — 必要に応じて個別のWebページを全文読み込む
5. **回答合成** — 複数ソースの情報を統合し、引用付きの回答を生成する
**【2026年8月更新】** 以前この記事では「AIは独自のクローラーを持っていない」と書いていましたが、これは現状に合いません。OpenAIは `OAI-SearchBot`、Perplexityは `PerplexityBot`、Anthropicは `Claude-SearchBot`(検索用)と `Claude-User`(ユーザーの質問に応じた取得用)という自前のクローラーを運用しており、なお `ClaudeBot` は[学習データ収集用](https://support.claude.com/en/articles/8896518-does-anthropic-crawl-data-from-the-web-and-how-can-site-owners-block-the-crawler)で、検索での引用には効きません。OpenAIについては[クロール量が大幅に増加しており自前のインデックスを構築しているとの分析](https://www.botify.com/blog/openai-tripled-web-crawl)もあります。
ただし「発見レイヤー」という構図自体がなくなったわけではありません。Google AI OverviewsとAI ModeはGoogleのインデックスを使い、GeminiもGoogleのインデックスに依存します。またどのプラットフォームでも、回答時に参照するのは検索結果の上位に並ぶ複数のページです。
実務上の含意は変わりません。**まず狙うサービスのクローラーが自サイトに到達できることを確認したうえで、検索結果ページ全体での露出を増やす**——この2点が出発点です。クローラーはサービスごとに違うため、詳細は「[LLMOとは何か?初心者にも分かる完全ガイド](/blog/llmo-guide-beginners-2026/)」を参照してください。
### なぜ「1位」だけでは足りないのか
従来のSEOでは「ターゲットキーワードで1位を取ること」がゴールでした。しかしAI検索エンジンは上位10件のスニペットを横断的に読み取り、複数ソースの一致度を確認して回答を組み立てます。
仮にあなたのサイトが1位を獲得していても、2位〜10位の比較記事・レビューサイト・フォーラムに競合の名前ばかり並んでいたらどうなるか。AIは「より多くのソースで言及されているブランド」を回答に採用する可能性が高いのです。
> 参考・引用:
> [GEO: Generative Engine Optimization - Princeton University (KDD 2024)](https://arxiv.org/abs/2311.09735)
> [Why Off-Site SEO Matters in GEO & AI Search - LLMrefs](https://llmrefs.com/blog/why-offsite-seo-matters-for-geo)
---
## 3. データが示す「ブランド言及 > 被リンク」の新常識

AI検索の仕組みを理解したところで、次はデータで裏付けます。正直、この調査結果を初めて見たときは驚きました。2025〜2026年に公開された複数の調査が、ブランド言及の重要性を裏付けています。
### Ahrefs 75,000ブランド調査の衝撃
Ahrefsが75,000ブランドを対象に実施した大規模調査では、AI検索での引用に最も強く相関する要因が示されました。以下は[AI Overviewsを対象とした分析](https://ahrefs.com/blog/ai-overview-brand-correlation/)の数値(Spearmanの順位相関)です。ChatGPTやAI Modeを対象にした分析では係数が多少異なります。
| 要因 | AI引用との相関(r) | 従来SEOとの違い |
|------|---------------------|-----------------|
| ブランドWeb言及数 | 0.664 | 最強の予測因子 |
| ブランドアンカー数 | 0.527 | リンクの「テキスト」が重要 |
| ブランド検索ボリューム | 0.392 | ブランド認知度の直接反映 |
| ドメインランク(DR) | 0.326 | 従来は最重要だった |
| 参照ドメイン数 | 0.295 | — |
| 被リンク数 | 0.218 | ブランド言及数の約3分の1 |
注目すべきは、**上位3要因がすべてサイト外のブランドシグナル**という点です。従来のSEOで最重要とされた被リンク数の相関は0.218で、ブランド言及数の約3分の1でした。
ただしこれらはあくまで相関であり、「ブランド言及を増やせばAIに引用される」という因果が検証されたわけではありません。言及の多いブランドはもともと知名度が高く、その知名度自体が引用されやすさに効いている可能性もあります。なお、AIがブランドを引用するかどうかは、Google AI Modeの「クエリファンアウト」技術(1つの質問を複数のサブクエリに分解して検索する仕組み)とも密接に関係しています。クエリファンアウトの仕組みと対策は「[クエリファンアウトとは?初心者向け解説](/blog/query-fan-out-guide-2026/)」で詳しく解説しています。
### Princeton GEO論文の知見
プリンストン大学のGEO論文(KDD 2024採択)は、生成エンジンにおけるコンテンツの可視性を高める施策を体系的に検証しました。その結果、**引用・統計データの追加により可視性が最大40%向上**し、特にSERP5位のサイトでは出典引用の追加で可視性が115.1%増加したと報告されています。
これは「すでに上位にいなくても、引用しやすい構造のコンテンツを持っていればAIに拾われやすくなる」ことを意味します。
### ブランド言及は被リンクの3倍重要
The Digital Bloomの2025年AI可視性レポートによると、AI検索における可視性について、ブランド言及は被リンクの3倍重要とされています。複数のLLMにわたってブランド言及をクラスタリングすると、最上位引用の可能性が最大2.8倍に増加するというデータも示されています。
> 参考・引用:
> [Top Brand Visibility Factors in ChatGPT, AI Mode, and AI Overviews (75K Brands Studied) - Ahrefs](https://ahrefs.com/blog/ai-brand-visibility-correlations/)
> [GEO: Generative Engine Optimization - arXiv](https://arxiv.org/abs/2311.09735)
> [2025 AI Visibility Report: How LLMs Choose What Sources to Mention - The Digital Bloom](https://thedigitalbloom.com/learn/2025-ai-citation-llm-visibility-report/)
---
## 4. プラットフォーム別:AIが好む情報ソースの違い
データの全体像を把握したところで、次はプラットフォームごとの違いを掘り下げます。すべてのAI検索エンジンが同じソースを参照するわけではありません。プラットフォームごとに引用傾向は大きく異なります。
### 主要AI検索の引用ソース比較
| AI検索エンジン | 最頻引用ソース | 引用割合 | 特徴 |
|--------------|--------------|---------|------|
| ChatGPT | Wikipedia | 7.8% | 百科事典的な正確性を重視 |
| Perplexity | Reddit | 6.6% | リアルタイムのUGCを重視 |
| Google AI Overviews | Reddit | 2.2% | 多様なソースをバランスよく参照 |
> **【2026年8月更新】** 上表はProfoundが2024年8月〜2025年6月の6.8億件の引用を分析した数値です。とくにPerplexityとRedditの関係は、2025年10月にRedditがPerplexityらを提訴して以降変動しており([Search Engine Land](https://searchengineland.com/reddit-sues-perplexity-serpapi-scraping-google-463681)、[CNBC](https://www.cnbc.com/2025/10/23/reddit-user-data-battle-ai-industry-sues-perplexity-scraping-posts-openai-chatgpt-google-gemini-lawsuit.html))、訴訟後にPerplexityの引用構成がどう変わったかを測定した調査は、本記事執筆時点で確認できていません。ただし前提が変わった以上、上表のPerplexityの数値がそのまま当てはまるとは限らないため、個別の割合は最新の調査で確認してください。
一方で、**ChatGPTとPerplexityの両方で引用されるドメインはわずか11%にすぎない**という傾向は、複数の調査で繰り返し確認されています。つまり、1つのプラットフォームで引用されていても、別のプラットフォームでは完全に無視される可能性がある。マルチプラットフォーム戦略が必須になる理由がここにあります。
### 日本市場で意識すべきポイント
グローバルではRedditの存在感が圧倒的ですが、日本市場では以下のプラットフォームも重要です。
- **Yahoo!知恵袋** — 日本語圏で最大級のQ&Aプラットフォーム。Google検索結果にも頻出
- **note** — 個人・企業の専門知見が集まるプラットフォーム。E-E-A-T評価が高い
- **X(Twitter)** — リアルタイムの言及がPerplexityに参照される傾向。X・Instagram・LinkedInでのAI検索最適化の詳細は「[SNS AI検索最適化ガイド](/blog/sns-ai-search-optimization-2026/)」で解説しています
- **はてなブックマーク** — 技術系トピックでのブランド言及の集約地
### 自社サイトの直接引用はわずか9%
ここが本記事のタイトルの根拠です。AI生成回答において、自社のブランドサイトが直接引用されるケースはわずか9%です。残りの91%は第三者コンテンツ経由。つまり、自サイトだけを最適化しても、AI検索からの流入は最大でも全体の1割にしかならないのです。
この事実が「自分以外の場所で自分の名前が語られる状態を作ること」の重要性を物語っています。
> 参考・引用:
> [AI Platform Citation Patterns - Profound](https://www.tryprofound.com/blog/ai-platform-citation-patterns)
> [Reddit, Quora, and Third-Party Sites: The New Kings of AI Search - AI Marketing Labs](https://ai-marketinglabs.com/lab-experiments/reddit-quora-and-third-party-sites-the-new-kings-of-ai-search)
> [How AI Engines Choose Brands: Citation Patterns Revealed - BrightEdge](https://www.brightedge.com/resources/weekly-ai-search-insights/how-different-ai-search-engines-choose-which-brands-to-recommend)
---
## 5. ゼロクリック時代に「存在する」ことの価値

サイト外でのブランド露出の重要性を加速させているもう一つの要因が、ゼロクリック検索の急増です。
### ゼロクリック率の現実
| 指標 | 数値 | 出典 |
|------|------|------|
| 2024年の米国Google検索全体のゼロクリック率 | 58.5% | [SparkToro / Datos(Semrush傘下)2024年調査](https://sparktoro.com/blog/2024-zero-click-search-study-for-every-1000-us-google-searches-only-374-clicks-go-to-the-open-web-in-the-eu-its-360/)(データ期間2022年9月〜2024年5月) |
| AI Overviews表示時のゼロクリック率 | — | 一次資料を確認できず本記事では扱わない |
| AI Overviews による1位CTR低下率 | 58%低下(実測1.6% vs 非表示時の推計3.7%) | Ahrefs 2026年2月 |
| Google AI Modeのセッション内完結率 | 75% | Semrush 2025年9月 |
Ahrefsの2026年2月のレポートでは、AI Overviewsによる1位のCTR低下は**58%**と報告されています。2025年4月時点の34.5%からほぼ倍増しており、この傾向は加速しています。
この58%という数字の読み方には注意が必要です。同レポートの実測値は2023年12月の7.3%に対し2025年12月が1.6%ですが、この差の全部がAI Overviewsによるものではありません。情報系キーワード全体のCTR低下を織り込むと、AI Overviewsがなければ3.7%だったと推計され、実測1.6%との差が58%減にあたる、というのが同レポートの計算です。
### クリックされなくても「参照される」価値
ゼロクリック率の上昇は悲観的に聞こえますが、視点を変えれば新たなチャンスです。ユーザーが検索結果をクリックしなくても、AI Overviewsの回答ソースとして参照されていれば、ブランド名は表示されます。
つまり、**「クリックされること」から「参照されること」にKPIを転換する**必要がある。そのためには、検索結果ページのあちこちに自ブランドの名前が登場している状態が不可欠です。
AI検索では「検索結果1位の自サイト」よりも「2位〜10位に散らばる複数の第三者言及」の方が回答に採用される確率が高い。この構造的な変化を理解することが、2026年のSEO戦略の出発点です。
> 参考・引用:
> [Update: AI Overviews Reduce Clicks by 58% - Ahrefs](https://ahrefs.com/blog/ai-overviews-reduce-clicks-update/)
> [Semrush AI Overviews Study: What 2025 SEO Data Tells Us About Google's Search Shift - Semrush](https://www.semrush.com/blog/semrush-ai-overviews-study/)
> [Zero-Click Search 2026: AI Overviews Cut Clicks by 58% - PikaSEO](https://pikaseo.com/articles/zero-click-search-ai-overviews-2026)
---
## 6. 実践ロードマップ:AI検索で引用されるブランド露出戦略
ここまでの分析を踏まえて、実際に何をどの順番でやるべきか。私が推奨するのは5フェーズの段階的アプローチです。
### フェーズ1:現状把握(1〜2週間)
まず、自ブランドの「検索結果ページ上のシェア」を計測します。
- **ターゲットキーワードで検索し、上位20件に自ブランドが何回登場するか数える**(自サイト+第三者サイトの合計)
- [LinkSurge](https://linksurge.jp/)のAI Overview分析で、主要キーワードでの引用状況を確認する
- ChatGPT・Perplexityに自社の主要テーマで質問し、回答に自ブランドが含まれるか確認する
### フェーズ2:第三者メディアへの露出拡大(1〜3ヶ月)
「Best ○○ tools」記事や業界比較コンテンツへの掲載を戦略的に獲得します。
| 施策 | 具体例 | 期待効果 |
|------|--------|---------|
| 比較・まとめ記事への掲載 | 「2026年おすすめSEOツール10選」系記事でのレビュー獲得 | 複数の検索結果に名前が登場 |
| 業界メディアへの寄稿 | SEO Japan、Web担当者Forum等への寄稿 | 専門家としてのE-E-A-T向上 |
| プレスリリース | 新機能・調査データの発信 | ニュースサイトでの言及増加 |
| ゲスト投稿 | 関連ブログへのゲスト記事執筆 | ブランドアンカーの獲得 |
### フェーズ3:UGC(ユーザー生成コンテンツ)の醸成(継続的)
RedditやYahoo!知恵袋でのブランド言及は、AI検索エンジンが特に重視する情報ソースです。
- **フォーラム・Q&Aサイトでの自然な参加** — 質問への回答で専門知識を共有(宣伝目的の投稿は逆効果)
- **noteやZennでの知見公開** — 一次情報・独自データの公開は引用されやすい
- **X(Twitter)での発信** — 調査データやインサイトの共有がリポスト・言及を生む
SNS上のUGCがAI引用率に直結する好例として、yutoriのSNS戦略が参考になります。TikTokコメント起点の購買導線やポップアップイベントをUGC生成装置として設計する手法については「[yutoriのSNSブランド戦略を徹底解剖](/blog/yutori-sns-brand-strategy-2026/)」をご覧ください。
### フェーズ4:引用可能なオリジナルリサーチの制作(四半期ごと)
AIが回答を生成する際、最も信頼するのは**他のソースが裏付ける一次情報**です。
- **独自調査データの公開** — アンケート調査、業界分析レポートなど
- **ケーススタディ** — 具体的な数値を含む成功事例・失敗事例
- **統計データの定期更新** — 最新データを含むコンテンツはAIに参照されやすい(65%のAIボットが過去1年以内に更新されたページにアクセス)
### フェーズ5:Wikidata・ナレッジグラフの整備
ブランドの構造化されたエンティティ情報は、LLMのエンティティ認識精度を直接向上させます。
- **Wikidataエントリの作成・更新** — 正確なメタデータ、別名、業界分類を設定する
- **Google ビジネスプロフィールの最適化** — ローカルSEO経由のAI引用に影響
- **構造化データ(Schema.org)の実装** — Organization、Product、FAQの構造化データを自サイトに実装
> 参考・引用:
> [AI Search Optimization: 12 Strategies for LLM Visibility 2026 - ALM Corp](https://almcorp.com/blog/ai-search-optimization-guide-llm-visibility-strategies/)
> [LLM Citation Trends That Matter in AI Search - Wellows](https://wellows.com/blog/llm-citation-trends-for-ai-search/)
> [LLMO: 10 Ways to Work Your Brand Into AI Answers - Ahrefs](https://ahrefs.com/blog/llm-optimization/)
---
## 7. 効果測定:新しいKPIで進捗を追う

サイト外でのブランド露出のGEO効果を測定するには、従来の「検索順位」「オーガニックトラフィック」だけでは不十分です。
### GEO時代の新KPI
| KPI | 測定方法 | 目標基準 |
|-----|---------|---------|
| **AI引用率(Citation Rate)** | ChatGPT・Perplexity等で主要キーワードを検索し、回答にブランド名が出る割合 | 主要キーワードの30%以上 |
| **SERP Share of Voice** | ターゲットキーワードの上位20結果でブランドが登場する比率 | 競合を上回る |
| **ブランド検索ボリューム** | Google Trendsやサーチコンソールでの指名検索数の推移 | 前四半期比増加 |
| **第三者言及数** | Ahrefs Content Explorerやメンションツールで計測 | 月次で増加トレンド |
| **AI Overview出現率** | ターゲットキーワードでAI Overviewsに出現する割合 | 月次で追跡 |
[LinkSurge](https://linksurge.jp/)では、AI Overview出現率やキーワード別の引用状況をダッシュボードで可視化できます。定期的なモニタリングにより、サイト外施策の効果を数値で追跡しましょう。
> 参考・引用:
> [GEO Metrics That Matter: How to Track AI Citations - Averi](https://www.averi.ai/how-to/how-to-track-ai-citations-and-measure-geo-success-the-2026-metrics-guide)
> [How to measure brand visibility in AI search - Search Engine Land](https://searchengineland.com/guide/how-to-measure-brand-visibility)
---
{{linksurge-card}}
---
## 8. よくある誤解と注意点
### 「被リンクを増やせばAIにも引用される」は間違い
これは私も以前は同じ思い込みをしていました。従来のSEOでは被リンクが最重要シグナルでしたが、AI引用との相関は0.218で、ブランド言及数(0.664)より明確に弱いという結果でした。リンクビルディングに全リソースを投じるよりも、ブランド言及を増やす施策の方が費用対効果が高いのが2026年の現実です。
もちろん被リンクが無意味になったわけではありません。従来のGoogle検索での順位維持には依然として重要です。ただし、AI検索への対応という観点では、被リンクだけに頼る戦略は不十分です。
[【2026年版】安全なリンクビルディング完全ガイド](/blog/safe-link-building-guide-2026/)では、デジタルPR・HARO・オリジナル調査など5つの具体的なリンク獲得手法を詳しく解説しています。
### 「自サイトのコンテンツを充実させれば十分」も危険
自サイトのコンテンツ品質は前提条件ですが、それだけでは不十分です。AI回答の91%が第三者ソース経由である以上、自サイト外でブランドが語られる状態を作る必要があります。
GEOの詳しい技術実装やプラットフォーム別の引用戦略については「[GEO完全ガイド](/blog/geo-guide-japan-2026/)」で解説しています。
### コンテンツの鮮度は引用率に直結する
65%のAIボットが過去1年以内に更新されたページにアクセスし、79%が過去2年以内に更新されたコンテンツを参照しているというデータがあります。「一度作って放置」のコンテンツはAI検索から徐々に消えていきます。
> 参考・引用:
> [LLM Citations vs Backlinks in AI Search Visibility - Wellows](https://wellows.com/blog/llm-citations-vs-backlinks/)
> [2025 AI Visibility Report - The Digital Bloom](https://thedigitalbloom.com/learn/2025-ai-citation-llm-visibility-report/)
---
## よくある質問(FAQ)
### オフサイトSEOとは何ですか?
オフサイトSEOとは、自分のサイト以外の場所で行うSEO活動の総称です。他のサイトでブランド名が言及されること、業界メディアへの寄稿、レビューサイトでの評価獲得、フォーラムでの専門知識共有などが含まれます。従来は「被リンク獲得」がオフサイトSEOの中心でしたが、AI検索の時代では「ブランド言及の量と広がり」がより重要になっています。
### なぜ自サイトの最適化だけではAIに引用されないのですか?
AI検索エンジンは検索結果の上位10件を横断的に読み、複数のソースで言及されている情報を優先的に回答に採用します。AI回答の91%は第三者サイト経由の情報です。自サイトがいくら充実していても、他のサイトで名前が出ていなければAIの「多数決」に負けてしまいます。
### 被リンクとブランド言及、どちらが重要ですか?
2026年のAI検索においては、ブランド言及の方が圧倒的に重要です。Ahrefsの75,000ブランド調査では、ブランドWeb言及のAI引用との相関が0.664なのに対し、被リンク数は0.218でした。The Digital Bloomのレポートでもブランド言及は被リンクの3倍重要と報告されています。
### 小規模サイトでもAI検索に引用される可能性はありますか?
あります。Princeton GEO論文では、SERP5位のサイトが出典引用を追加しただけでAI可視性が115.1%向上した事例が報告されています。大規模サイトでなくても、引用しやすい構造のコンテンツと複数プラットフォームでのブランド言及があれば、AIに選ばれる可能性は十分にあります。
### どのプラットフォームでの言及が最も効果的ですか?
プラットフォームによって異なり、個別の引用割合は変動が大きい点に注意してください(とくにPerplexityについては、2025年10月にRedditから提訴されており、上表の数値がそのまま当てはまるとは限りません)。安定して確認されているのは傾向の乖離のほうで、ChatGPTは百科事典的なソース、PerplexityはUGCと新しい情報を重視します。日本市場ではYahoo!知恵袋・note・X(Twitter)も重要な言及プラットフォームです。複数のプラットフォームにまたがって言及を獲得するマルチプラットフォーム戦略が最も効果的です。
---
## まとめ:「自サイトの外」に目を向けよう
AI検索時代のSEOは、自サイトの順位を追うだけでは不完全です。検索結果ページ全体——比較記事、レビューサイト、フォーラム、業界メディア——にブランドの名前が散らばっている状態を作ること。それがAI検索エンジンに「このブランドは信頼できる」と判断させる最短ルートです。
まずは現状把握から。ターゲットキーワードで検索し、上位20件に自ブランドが何回登場するかを数えてみてください。その数字が、あなたのGEO競争力を端的に示しています。
AI検索での自社ブランドの引用状況を可視化するなら、LinkSurgeの[AI Overview分析機能](https://linksurge.jp/aio-v5)で主要キーワードごとの出現状況をリアルタイムで確認できます。
AI Overviewsの詳しい影響と対策については「[生成AI検索がSEOを変える:7つの実践対策](/blog/ai-search-seo-japan-2026/)」、技術SEO・コンテンツSEO・リンク構築の包括的な戦略については「[SEO対策完全ガイド](/blog/seo-guide-2026/)」もあわせてご覧ください。また、PBNやサテライトサイトによるリンク操作のリスクと安全なバックリンク戦略については「[サテライトサイトSEOのリスクと対策](/blog/satellite-site-seo-risks-2026/)」で解説しています。
---
## 生成AI検索がSEOを変える:AI Overviews・AI Modeの最新動向と7つの実践対策【2026年版】
> URL: https://linksurge.jp/blog/ai-search-seo-japan-2026/
> Date: 2026-02-10 | Category: AIO | Author: 緒方亜朗
> Tags: AI Overviews, AI Mode, SGE, GEO, SEO, ゼロクリック検索, E-E-A-T, 構造化データ, 2026
## この記事の結論:AI検索時代に日本のSEOが取るべき7つの実践対策
2026年、SEOは「検索結果に表示される」だけでは不十分です。Google AI Overviews や AI Mode の普及により、**AIに引用されるコンテンツ**が新たな競争軸になりました。私がAI検索の最新データを追いかけていて実感するのは、この変化が「将来の話」ではなく「今まさに起きている」ということ。以下の7つが実践上の要点です。
1. **コンテンツをAI引用に最適化する(APO)** — 40〜60語の回答ブロック、箇条書き、比較表を冒頭に配置し、AIが情報を抜き出しやすい構造にする
2. **構造化データは目的を決めてから実装する** — JSON-LDマークアップはページ情報を機械可読にするが、AI引用を増やす効果は確認されていない。リッチリザルトなど目的が定まっている場合に実装する
3. **E-E-A-T を組織的に強化する** — 著者プロフィール、専門家監修、一次情報の出典・更新日を明示し、AIが「信頼できる情報源」として認識する条件を整える
4. **GEO(Generative Engine Optimization)を導入する** — ChatGPT、Perplexity、ClaudeなどのAI検索エンジンでのブランド露出を「Share of Synthesis」として計測し、KPI化する
5. **ゼロクリック時代に備えたブランド戦略を構築する** — AI Overviewsの表示でオーガニックCTRが大幅に低下する中、ブランド認知と指名検索の獲得が安定的な流入の鍵になる
6. **テクニカルSEOの基盤を強化する** — Core Web Vitals(INP < 200ms、LCP < 2.5s、CLS < 0.1)の達成と、AIクローラーが情報を取得しやすいサイト構造の整備を行う
7. **マルチモーダルコンテンツを拡充する** — 画像・動画に適切なaltテキストとメタデータを付与し、AIが視覚情報も参照できる環境を構築する
以下では、各テーマを最新のデータと日本国内の事例とともに順に解説します。
---
## 1. ユーザー行動の変化 — ゼロクリック時代の到来

### ゼロクリック検索が急増している
私がこの1年間で最も衝撃を受けたデータがこれです。AI Overviewsが検索結果上部に要約を直接表示することで、ユーザーがリンクをクリックせずに情報を得る「ゼロクリック検索」が急増しています。AI Overview表示時のオーガニックCTRは大幅に低下し、検索結果の約63%が「検索を終了」する形になっているとの報告があります。
これはSEO担当者にとって深刻な変化です。従来は検索結果1位を獲得すれば安定したトラフィックが見込めましたが、AIが回答を直接提供する時代では、1位表示ですらクリックされない可能性があります。
### 検索クエリが長文化・自然文化している
AI Mode利用時は、ユーザーの検索クエリが従来のキーワード型から自然文型に変化しています。平均クエリ長が約7語に伸び、「東京 おすすめ レストラン」ではなく「東京で子連れで入れるイタリアンレストランを教えて」のような複数条件を含むクエリが増加しています。この変化の背景にあるのが「クエリファンアウト」と呼ばれる技術で、AIが1つの質問を複数のサブクエリに分解して並列検索する仕組みです。詳しくは「[クエリファンアウトとは?初心者向けにわかりやすく解説](/blog/query-fan-out-guide-2026/)」をご覧ください。
### 世代別のAI検索活用に大きな差がある
AI検索の活用度には世代間で明確な差があります。10代〜30代の若年層は約73%が「たまに」または「頻繁に」AIの回答で検索を終了すると回答しています。一方、50代以上はAIの回答に懐疑的で、従来のリンク訪問を好む傾向が強いとされています。
ターゲット層の年齢構成に応じたSEO戦略の使い分けが必要です。
### マルチモーダル検索が標準化しつつある
テキストだけでなく、画像や動画を組み合わせた検索がAI Modeで標準化されつつあります。AIが画像認識結果とテキスト情報を統合して回答を生成するため、ビジュアルコンテンツの最適化がこれまで以上に重要になっています。
Google以外の主戦場であるChatGPT検索の仕組みと対策は「[ChatGPTに引用される方法 完全ガイド2026](/blog/chatgpt-geo-complete-guide-2026/)」で体系化しています。
このゼロクリック化がPageRank以来の30年の流れのどこに位置するのかは、「[SEOはどう変わってきたか — 1990年代から2026年までの30年を一気に振り返る](/blog/seo-history-keywords-to-ai-2026/)」で年表にまとめています。
> 参考・引用:
> [Google AI Overviews Are Killing Clicks — The Egg](https://www.theegg.com/seo/apac/google-ai-overviews-are-killing-clicks-heres-how-to-win-anyway/)
> [AI Overview導入でCTR低下 — knowledge-hd](https://knowledge-hd.co.jp/ai-overview-ctr61-seo-meo-2025/)
> [博報堂DYホールディングス AI検索調査](http://www.hakuhodody-holdings.co.jp/news/topics/2025/11/5985.html)
> [10代〜30代のAI検索利用 — Web担当者Forum](https://webtan.impress.co.jp/n/2026/01/05/51936)
---
## 2. コアランキング要因の変化 — AIが「信頼できる情報源」を選ぶ基準

ゼロクリックの実態を押さえたところで、次は「AIがどのサイトを引用するか」の選定基準を見ていきます。
### E-E-A-Tがこれまで以上に重要になった理由
AIが回答を生成する際、引用元の選定基準として**E-E-A-T**(経験・専門性・権威性・信頼性)が直接影響します。Googleの品質評価ガイドラインで重視されてきたE-E-A-Tは、AI Overviewsの情報源選定においても中核的な役割を果たしています。
特に「信頼性(Trustworthiness)」は、AIが誤情報を回答に含めないための最重要基準です。公的機関や専門メディアからの一次情報は、AIの回答根拠として優先されやすく、引用リンクが付与される確率も高まります。
### ブランドとエンティティの可視化が流入を左右する
AIが「信頼できる情報源」として認識したブランドは、AI検索結果全体での露出が増えます。ある調査では、AI Overview内で引用されたブランドのCTRが約35%上昇したとの報告があります。
これは「ブランドSEO」の概念をさらに拡張するものです。従来のキーワード順位だけでなく、AIが自社ブランドをどの程度認識し、引用しているかが重要な指標になります。
| 変化項目 | 主要ポイント |
|---|---|
| **E-E-A-Tの重要性** | 経験・専門性・権威性・信頼性がAI引用の評価基準に直結 |
| **ブランド・エンティティの可視化** | AIが信頼できると判断したブランドは検索全体での露出が増加 |
| **構造化データ(Schema)** | ページ情報を機械可読にする(AI Overview引用確率への効果は未確認) |
| **一次情報・引用元の明示** | 公的機関・専門メディアの情報がAIの回答根拠として優先 |
| **マルチモーダルシグナル** | 画像・動画のメタデータがAIの情報抽出に寄与 |
> 参考・引用:
> [Google's AI Mode — Ann Smarty (LinkedIn)](https://www.linkedin.com/pulse/googles-ai-mode-future-online-marketing-seo-ann-smarty-lhrwc)
> [AI Overview/GEO KPI設計 — note.com](https://note.com/seolabochannel/n/n6ac3f3468f52)
> [Ahrefs AI Overviews Impact Study](https://www.theworld.com/ahrefs-study-google-ai-overviews-impact-b2b-saas/)
---
## 3. コンテンツ制作の新基準 — AIに引用される記事の条件
### Answer-Passage-Optimization(APO)とは
私が複数のAI検索エンジンで実際にテストしてみて確信したのは、「構造が良いコンテンツはAIに拾われやすい」という単純な事実です。APO(Answer-Passage-Optimization)は、AIが回答として抽出しやすいコンテンツ構造を設計する手法です。40〜60語の簡潔な回答ブロック、箇条書き、比較表、手順リストを冒頭に配置することで、AI Overviewに引用される確率が大幅に向上します。
具体的には以下の要素を意識します。
- **冒頭に結論を配置する** — 記事やセクションの最初に直接的な回答を置く
- **箇条書き・番号リストを活用する** — AIが情報を構造的に抽出しやすくなる
- **比較表で情報を整理する** — 選択肢や条件の比較はテーブル形式が最適
- **手順リストを番号付きで示す** — 手順が明確なコンテンツはAIが抽出しやすい(引用増加の効果自体は未検証)
### FAQ形式で検索意図に直接応える
質問形式(「○○とは?」「○○のやり方は?」)の見出しに対して直接回答する構成は、AIが質問-回答ペアを抽出する際に非常に有効です。なお、これをFAQスキーマでマークアップしても効果は加算されません。FAQリッチリザルトは2026年5月に廃止されており、AI引用への効果も対照実験で確認されていません。抽出しやすさに寄与しているのは見出しと回答の構成そのものだと考えられますが、これも引用が増えるという形では検証されていません。
### 人間の編集と事実確認が不可欠
AI生成文をそのまま公開するのはリスクが大きく、必ず人間による校正が必要です。一次情報の出典と更新日を明示し、ハルシネーション(AIによる誤情報生成)を防止します。Googleは「AIを使って作成したコンテンツ」自体を否定していませんが、「正確性と有用性」を厳しく評価しています。
### 独自性と実体験の付加がAI引用の差別化要因
自社事例、インタビュー、独自の統計データなど、他サイトにはない「実体験」や「独自分析」を加えることが、AI引用において決定的な差別化要因になります。AIは複数の情報源を比較して回答を生成するため、独自性の高い情報ほど引用される可能性が高まります。
> 参考・引用:
> [AIO最適化ガイド — AXIS](https://www.axis-corp.com/quest/aio-aioptimization)
> [構造化データの実装方法 — ferret-one](https://ferret-one.com/blog/structured-data)
> [AI SEOコラム — Lead-X](https://lead-x.co.jp/column/ai-seo-column/)
> [AI時代のWebサイト最適化 — Web担当者Forum](https://webtan.impress.co.jp/e/2026/02/03/51932)
---
## 4. テクニカルSEOと構造化データ — AI引用の技術的基盤

コンテンツの作り方を押さえたところで、次は技術面の話です。構造化データは、ページの情報を機械可読な形で明示するための施策です。
### 構造化データ(JSON-LD)の実装
構造化データは、ページの情報を機械可読な形で明示する手段です。用途に応じて以下のスキーマが使われます。
> **【2026年8月追記】** その後の検証で、構造化データがAI引用を増やすという効果は確認できませんでした。Googleは「生成AI検索に構造化データは必須ではなく、追加すべき特別なschema.orgマークアップも存在しない」と公式に明言しています(ただしこれは出るための要件の話で、内部で参照していないという意味ではありません)。schemaを追加した対照実験でも、AI Mode(+2.4%)とChatGPT(+2.2%)の変化はノイズと区別できませんでした。
> 下表の「AI引用への効果」は、スキーマが何を機械可読にするかの説明であって、引用が増えることを示すものではありません。詳細は「[「FAQスキーマで引用率3.2倍」は本当か — 自社の評価基準から未検証の数値を削除した話](/blog/faq-schema-ai-citation-myth-2026/)」をご覧ください。
| スキーマ | 用途 | AI引用への効果 |
|---|---|---|
| **FAQ** | よくある質問と回答 | 質問-回答ペアをAIが直接抽出 |
| **HowTo** | 手順・やり方 | ステップ形式の回答生成に活用 |
| **Article** | 記事情報 | 著者・更新日・カテゴリの信頼性評価 |
| **Product** | 商品情報 | 商品比較・レビュー回答に引用 |
| **Review** | レビュー・評価 | ユーザー評価を含む回答生成に活用 |
JSON-LDで実装し、必ずページ上に可視化されたコンテンツと対応させることが重要です。構造化データの内容がページ本文と一致しない場合、Googleはペナルティを課す可能性があります。
### Core Web Vitalsとモバイル最適化
テクニカルSEOの基本であるCore Web Vitalsは、AI検索時代においても引き続き重要です。
- **LCP(Largest Contentful Paint)**: 2.5秒以下
- **INP(Interaction to Next Paint)**: 200ms以下
- **CLS(Cumulative Layout Shift)**: 0.1以下
モバイルトラフィックがウェブ利用全体の過半数を占める現在、モバイルでのページ読み込み速度は特に重要です。画像の軽量化(次世代フォーマットの検討や適切な圧縮)やCSS/JSの最適化を徹底しましょう。
### AIクローラーへの対応
robots.txtで重要ページへのアクセスを許可し、サイトマップを定期的に更新してAIクローラーが情報を取得しやすい環境を整備します。AIクローラーはJavaScriptを実行しない場合があるため、重要なコンテンツはSSR(サーバーサイドレンダリング)でHTMLに直接出力することが推奨されます。
さらに、Cloudflareが提唱する「Markdown for Agents」のように、AIエージェント向けに機械可読フォーマットを提供するアプローチも注目されています。詳しくは「[Cloudflare Markdown for AgentsとAI対策の新常識](/blog/cloudflare-markdown-for-agents-2026/)」をご覧ください。
### hreflangとURL正規化
日本語ページは`.jp`ドメインまたは`/ja/`パスで統一し、適切なhreflang設定で地域検索に対応します。多言語サイトでは、AIが言語別に最適なページを引用できるよう、canonical URLとhreflangの設定を正確に行うことが必要です。
> 参考・引用:
> [構造化データの実装ガイド — ferret-one](https://ferret-one.com/blog/structured-data)
> [GEO(Generative Engine Optimization) — 電通デジタル](https://www.dentsudigital.co.jp/knowledge-charge/articles/2025-0909-geo)
> [Google AI Overviewの最適化 — ULPA](https://www.ulpa.jp/post/how-to-optimise-for-google-aii-overview-in-japan-the-complete-guide-for-2025)
---
## 5. 従来SEO vs. AI時代のSEO — 何が変わり、何が変わらないのか
ここまでの内容をふまえて、「結局、従来のSEOは捨てていいのか?」という問いに答えておきます。私の結論は明確で、従来SEOの基盤はそのまま活きます。AI検索の普及により、SEO戦略の評価指標と施策の優先度が変わりつつあります。ただし従来のSEOが無効になるわけではなく、**AI対応を「上乗せ」する戦略**が求められます。
| 観点 | 従来SEO | AI時代のSEO(AIO/GEO) |
|---|---|---|
| **主要KPI** | キーワード順位、オーガニックCTR、バックリンク数 | AI引用回数、Share of Synthesis + 従来指標 |
| **流入特性** | クリックが前提のトラフィック | ゼロクリックが増加し、AI直接回答が増える |
| **CTR変化** | クリック率は比較的安定 | AI Overview表示時は平均30%以上CTRが低下 |
| **ブランド露出** | 上位表示が主な露出手段 | AIが信頼できると評価すれば順位に関わらず引用 |
| **施策のROI** | コンテンツ量とリンク構築が中心 | スキーマ実装・APOが低コストでAI露出を獲得 |
### GEO(Generative Engine Optimization)とは

GEOは、ChatGPT・Perplexity・Claudeなどの生成AI検索エンジンでの可視性を最適化する戦略です。従来SEOの「Share of Voice(検索結果での露出シェア)」に対応する概念として、**「Share of Synthesis」**(AI生成回答での引用シェア)が新たなKPIとして注目されています。
Share of Synthesisは、特定カテゴリのAI検索でどの程度自社ブランドが引用されているかを計測する指標です。たとえば、100回のAI検索のうち30回で自社が引用されていれば、Share of Synthesisは30%になります。GEOの技術的な実装方法やプラットフォーム別の最適化戦略については「[GEO完全ガイド:ChatGPT・Gemini・Perplexityに引用される実践手法](/blog/geo-guide-japan-2026/)」で詳しく解説しています。
> 参考・引用:
> [AI時代のSEO指標 — MarkeZine](https://markezine.jp/article/detail/50192)
> [AI Overview/SGE対策 — sitest.jp](https://sitest.jp/blog/ai-overview-sge/)
> [AI検索時代のWebサイト最適化 — sasurai AI](https://www.sasuraiai.com/articles/ai-website-optimization-2024)
---
{{linksurge-card}}
## 6. 日本国内のケーススタディ — AI検索で成果を出した事例
理論だけでは説得力に欠けるので、日本国内でAI検索対策に取り組んだ具体的な事例を紹介します。私が特に注目しているのは、中小企業でも成果が出ている点です。
### 事例1:中小企業が検索順位に関わらずAI Overviewに掲載
大阪のWeb制作会社(digrart)は、検索順位が上位3位以内でなくてもAI Overviewに引用されることを狙い、構造化データとローカル情報の最適化を実施しました。結果として、従来の検索順位に関係なくAI Overviewに掲載され、ブランド認知が向上しました。
### 事例2:旅行プランコンテンツがAI検索で直接表示
「京都 3日間 旅行プラン」のような自然文クエリに対して、旅行情報をJSON-LDと画像マップで提供した事例では、ユーザーが検索画面内で完結した旅行プランを取得できるようになりました。マルチモーダル対応が功を奏した事例です。
### 事例3:飲食店がAI引用で来店予約を増加
口コミ・レビューを構造化データで整備した飲食店では、AIが「おすすめレストラン」として引用。AI Overviewでの引用により来店予約が増加し、CTRが約35%上昇したとの報告があります。
### 事例4:B2B SaaSがAI Overview表示時にもリード獲得を維持
スキーマ化・FAQ形式で製品比較情報を整備したB2B SaaS企業では、AI Overview表示時でもクリック率が相対的に高く維持され、リード獲得への影響が最小限に抑えられました。APOとFAQスキーマの組み合わせが効果的だった事例です。
| 事例 | 主な施策 | 成果 |
|---|---|---|
| 大阪の中小企業 | 構造化データ + ローカル情報最適化 | 順位に関わらずAI Overviewに掲載 |
| 旅行プランコンテンツ | JSON-LD + 画像マップ + マルチモーダル | 検索画面内で完結した情報提供 |
| 飲食店 | 口コミ・レビュー構造化 | 来店予約増加、CTR約35%上昇 |
| B2B SaaS | スキーマ化 + FAQ形式 | AI Overview表示時もリード獲得維持 |
> 参考・引用:
> [大阪中小企業のSGE対策 — digrart](https://www.digrart.jp/blog/seo/google-sge-osaka-sme-measures/)
> [SGEとSEOの関係 — Digital Identity](https://digitalidentity.co.jp/blog/seo/abbout-sge.html)
> [AI Overview導入でCTR変化 — knowledge-hd](https://knowledge-hd.co.jp/ai-overview-ctr61-seo-meo-2025/)
> [SGEとは何か — Lucy](https://lucy.ne.jp/bazubu/what-is-google-sge-49191.html)
---
## 7. 今すぐ実行できる7つのアクションプラン

### ステップ1:コンテンツ監査とAPO導入(1〜2週間)
既存のページを見直し、冒頭に40〜60語の回答ブロックを配置します。箇条書き・テーブルで要点を整理し、AIが情報を抜き出しやすい構造に変換します。最もトラフィックの多い10ページから着手するのが効率的です。
### ステップ2:構造化データを対象ページに実装(2〜4週間)
スキーマは**ページの内容に対応するものだけ**をJSON-LDで実装します(記事ページなら`Article`、商品ページなら`Product`)。サイト全体に一律で付けると、可視コンテンツと対応しない構造化データになり、リッチリザルトの対象外になる可能性があります。検証は目的で使い分けます。Google検索のリッチリザルト適格性は[リッチリザルトテスト](https://search.google.com/test/rich-results)、Google固有の適格性を問わないJSON-LDの語彙・構文は[Schema Markup Validator](https://validator.schema.org/)で確認してください。なおGoogleは `HowTo` のリッチリザルトを2023年に、`FAQPage` のリッチリザルトを2026年5月に廃止しています([FAQPage](https://developers.google.com/search/updates#removing-faq-rich-result))。リッチリザルト目的で残っているのは `Article`・`BreadcrumbList` などです(`Product` は商品ページ、`Review` は対象タイプに対する実際のレビュー・評価があるページに限られ、一般的な記事には使えません)。
### ステップ3:E-E-A-T強化(継続的)
以下の施策を段階的に実施します。
- 著者プロフィールページの作成と記事への紐付け
- 専門家監修の明記(監修者名・資格・所属)
- 一次情報の出典URLと更新日の明示
- 権威ある外部メディアからの引用・被リンク獲得
### ステップ4:技術的最適化(1〜2週間)
- モバイルファースト設計の徹底
- Core Web Vitalsの改善(LCP < 2.5s、INP < 200ms)
- robots.txtとサイトマップの最適化
- SSRによるHTML直接出力の確保
### ステップ5:AI Overviews用KPIの設定(1週間)
「引用回数」「推薦回数」「AIからの流入セッション」をGoogle Search Consoleや専用分析ツールで測定する体制を構築します。LinkSurgeの[AI Overview分析機能](https://linksurge.jp/aio-v5)を活用すれば、AIでのブランド露出を定量的にトラッキングできます。
### ステップ6:ブランドPRと外部言及(継続的)
プレスリリース・業界メディア掲載を通じて、第三者サイトからのリンクと引用を増やします。AIが「信頼できる情報源」として認識するには、複数の権威あるサイトからの言及が重要です。
### ステップ7:マルチモーダルコンテンツの拡充(継続的)
画像・動画に適切なaltテキスト・メタデータを付与し、Googleのマルチモーダル検索に備えます。商品比較、使い方ガイド、旅行プランなど、視覚情報が価値を持つコンテンツは特に効果的です。
> **短期的**にはクローラー到達の確認とコンテンツのAPO化に取り組み、**中長期的**にはブランドエンティティの強化とGEO戦略の全社的導入で、AI Modeがデフォルトになる将来に備えることが重要です。スキーマの実装は、リッチリザルトなど従来検索での目的が定まってからで構いません。
購買行動の側から見ると、AI検索と従来検索は置き換わるのではなく役割分担が進んでいます。楽天の2026年9月調査では、Z世代の54.3%が商品検討に生成AIを使う一方、最も信頼する情報源は検索エンジン(42.1%)でした。詳しくは「[Z世代の54%が買う前にAIに聞く。それでも信頼するのは検索エンジン](/blog/gen-z-ai-shopping-search-trust-2026/)」で解説しています。
> 参考・引用:
> [AIO最適化ガイド — AXIS](https://www.axis-corp.com/quest/aio-aioptimization)
> [GEO導入ガイド — 電通デジタル](https://www.dentsudigital.co.jp/knowledge-charge/articles/2025-0909-geo)
> [AI Overviewの影響 — MarkeZine](https://markezine.jp/article/detail/49412)
---
## よくある質問(FAQ)
### AI Overviewsに自社サイトを引用してもらうにはどうすればいいですか?
まず狙うサービスのクローラーが通っているかを確認してください。そのうえで、APO(40〜60語の回答ブロックの冒頭配置)とE-E-A-Tの強化(著者情報・一次情報の明示)を組み合わせるのが基本になります。特に質問形式の見出しに対する直接回答は、AIが情報を抽出しやすい構造です。構造化データはリッチリザルト等の従来SEO用途で有用ですが、AI引用への効果は確認されていません。
### ゼロクリック検索が増えるとSEOは無意味になりますか?
いいえ、無意味にはなりません。ゼロクリック検索が増えても、AIに引用されることでブランド認知が向上し、指名検索の増加につながります。また、APO形式のコンテンツ設計によって、AIが引用しやすい形に情報を整えることはできます。従来SEOとGEOを組み合わせた戦略が有効です。
### GEO(Generative Engine Optimization)と従来のSEOの違いは何ですか?
従来のSEOは検索結果ページでの順位とクリック率を最適化しますが、GEOはChatGPTやPerplexityなどのAI検索エンジンでの「引用率(Share of Synthesis)」を最適化します。GEOではAPO形式のコンテンツ設計とE-E-A-Tの強化が主要な施策であり、キーワード順位だけでなくAI引用数が重要なKPIになります。構造化データはリッチリザルト等の従来SEO用途で有用ですが、AI引用への効果は確認されていません。
### 日本語コンテンツでもAI Overviewsに表示されますか?
はい、日本語検索でもAI Overviewsは表示されます。日本市場向けには、`.jp`ドメインまたは`/ja/`パスの使用とhreflang設定が基本になります。日本語特有の質問パターン(「〜とは」「〜のやり方」)に対応した見出し設計も、AIが情報を抽出しやすくする観点で有効と考えられます(引用増加の効果自体は未検証)。
### AI生成コンテンツはSEOに悪影響がありますか?
Googleは「AIで作成したコンテンツ」自体を否定していませんが、正確性・有用性・独自性を厳しく評価しています。AI生成文は必ず人間が校正し、一次情報の出典を明示することが不可欠です。独自の事例やデータを加えた上でAIを執筆補助として活用するアプローチが推奨されます。
---
## まとめ:AI検索時代のSEOは「引用される力」で決まる
AI Overviews と AI Mode の普及により、SEOの成功指標は「順位」から「引用」へと拡張しています。しかし、これは従来のSEOが無効になることを意味しません。テクニカルSEO、コンテンツ品質、E-E-A-Tという基盤の上に、GEOとAPOという新しいレイヤーを積み重ねていく戦略が求められます。
まず着手すべきは、**狙うサービスのクローラーが到達できるかの確認と、既存コンテンツのAPO化**です。前者は必要条件、後者は低コストで着手できます。構造化データの実装は、AI引用への効果が確認されていないため、リッチリザルトなど目的が定まってからで構いません。その上で、ブランドエンティティの強化とGEO KPIの測定体制を構築し、中長期的な競争優位を築いていきましょう。技術SEO・コンテンツSEO・リンク構築まで含めた包括的なSEO戦略については「[2026年最新 SEO対策完全ガイド](/blog/seo-guide-2026/)」もあわせてご覧ください。
AI検索で引用されるには自サイトの最適化だけでは不十分です。サイト外でのブランド露出がなぜ重要か、その実践手法については「[AI検索に選ばれるには「自サイトの外」が9割](/blog/offsite-seo-geo-2026/)」もあわせてご覧ください。
サイト外のブランド露出チャネルとして、SNSプラットフォームの活用も見逃せません。X・Instagram・LinkedInの各AIアルゴリズムに合わせた投稿形式やコンテンツ設計については「[SNS AI検索最適化ガイド](/blog/sns-ai-search-optimization-2026/)」で解説しています。
LinkSurgeの[AI Overview分析機能](https://linksurge.jp/aio-v5)では、Google AI OverviewsやChatGPTでの自社ブランドの引用状況をリアルタイムで分析できます。AI検索時代のSEO戦略の第一歩として、ぜひご活用ください。
AIに引用されるコンテンツ戦略の基礎から学びたい方は、[LLMOとは何か?初心者にも分かる完全ガイド](/blog/llmo-guide-beginners-2026/)もあわせてご覧ください。
---
## 生成エンジン最適化(GEO)完全ガイド:ChatGPT・Gemini・PerplexityにAI引用される実践手法【2026年日本版】
> URL: https://linksurge.jp/blog/geo-guide-japan-2026/
> Date: 2026-02-10 | Category: GEO | Author: 緒方亜朗
> Tags: GEO, AI検索, ChatGPT, Perplexity, Claude, Gemini, 構造化データ, E-E-A-T, RAG, 2026
## この記事の結論:GEOで成果を出す5つの要点
2026年、コンテンツマーケティングの勝敗は「検索結果に表示される」ことだけでなく、「AIに引用される」かどうかで決まります。私がこの半年間、ChatGPT・Perplexity・Claudeの引用パターンを調査してきた結果、プラットフォームごとに最適化の勘所が明確に違うことがわかりました。GEO(Generative Engine Optimization)は、これらの生成AIが回答に自社コンテンツを採用・引用する確率を高める最適化手法です。以下の5つが実践上の要点です。
1. **Promptフレンドリーな文章設計が引用の土台** — 各セクション冒頭40〜50語に結論を配置することで、RAG(Retrieval-Augmented Generation)が情報を正確に取得・引用しやすくなる。JSON-LDのスキーマ実装は従来SEOの用途では有用だが、AI引用を増やす効果は確認されていない
2. **プラットフォームごとに引用メカニズムが異なる** — ChatGPTはブラウジング+OAI-SearchBot、GeminiはKnowledge Graph連携、PerplexityはSourcesリスト、ClaudeはCitation APIと、各エンジンの引用方式に合わせた最適化が必要になる
3. **日本語特有の形態素処理と敬語表現がAI引用に影響する** — 日本語は形態素単位でトークン化されるため、1文30〜50トークンに収まる短文設計が有効。敬語表現を自然に含めるとClaudeの引用精度が向上する
4. **日本の法制度(著作権法・APPI)への準拠が不可欠** — AI学習段階は情報解析として原則許諾不要だが、生成・利用段階では著作権侵害リスクがある。個人情報保護法(APPI)に基づくデータマスキングも必須になる
5. **Citation Rateを中心としたKPI設計と段階的実行が成功の鍵** — AIが生成した回答に自社URLが出現する割合を計測し、5フェーズの実行プランで段階的に導入・改善する
以下では、各テーマを技術的な実装方法と日本国内の法制度を踏まえて順に解説します。
---
## 1. GEOとは何か — 定義・仕組み・SEOとの違い
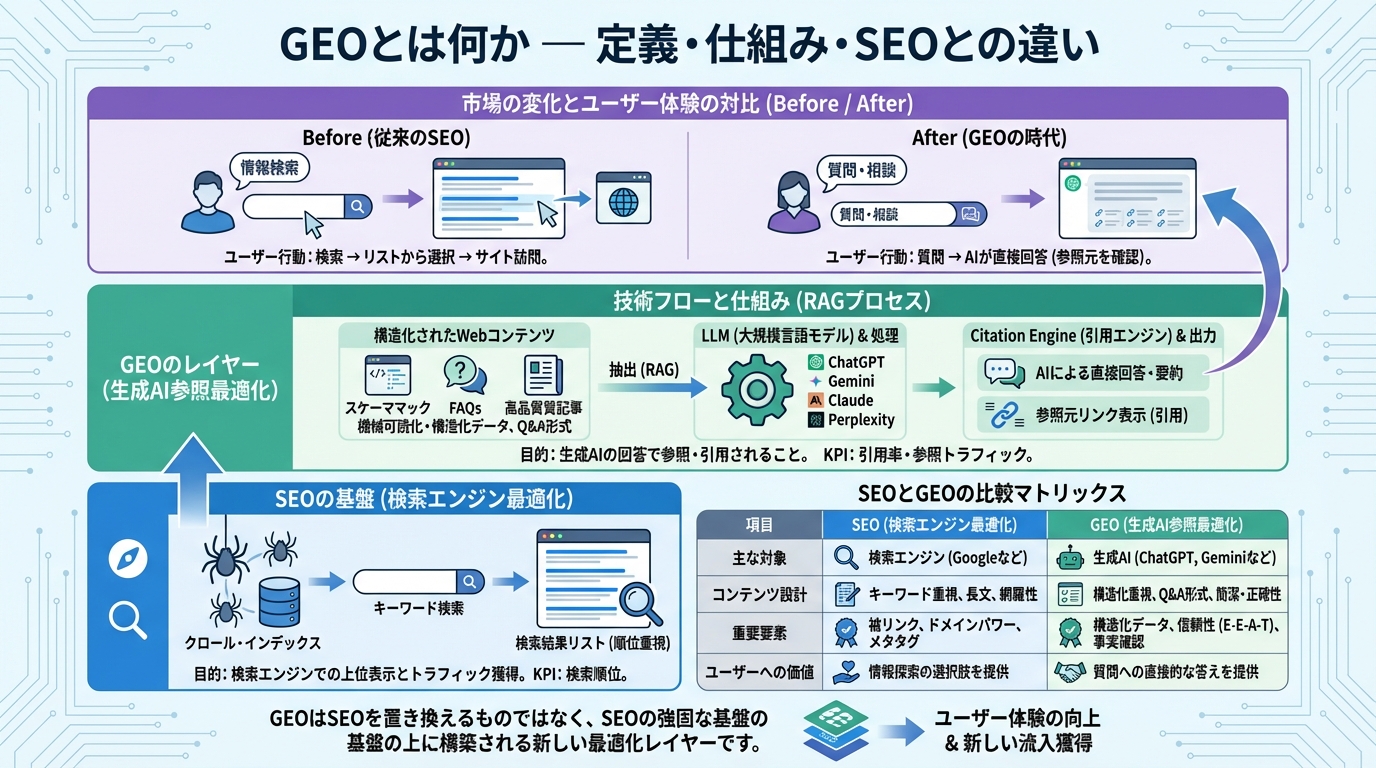
### GEOの定義
GEO(Generative Engine Optimization)とは、ChatGPT、Google Gemini、Perplexity、Anthropic Claudeなどの生成AIがユーザーの質問に対して直接回答や要約を生成する際に、参照・引用されやすいようにコンテンツを機械可読化・構造化する最適化手法です。
SEOが検索結果での順位を高めることに重点を置くのに対し、GEOは「AIが回答に採用・引用する確率」を高めることが目的です。
### なぜGEOが必要なのか
これは私が最近のクライアント案件で痛感していることですが、ゼロクリック検索の急増により、ユーザーはAIの回答で情報を完結させる傾向が強まっています。AI Overviews表示時のオーガニックCTRは50〜60%低下するとの調査結果が出ています([Ahrefs, 2025年12月](https://ahrefs.com/blog/ai-overviews-reduce-clicks-update/);[Seer Interactive, 2025年11月](https://www.seerinteractive.com/insights/ctr-aio))。従来のSEOだけでは流入を維持できなくなりつつあります。AI OverviewsやAI Modeが日本のSEOに与える影響と具体的な対策は「[生成AI検索がSEOを変える:7つの実践対策](/blog/ai-search-seo-japan-2026/)」で詳しく解説しています。GEOは、この新しい検索環境でブランドの可視性を確保するための戦略です。
### GEOを支える2つの技術基盤
GEOを理解するには、AIが回答を生成する2つの仕組みを知る必要があります。
**RAG(Retrieval-Augmented Generation)** は、検索エンジンや外部データベースから取得した情報をリアルタイムでLLMに注入し、回答を生成する技術です。AIは学習データだけでなく、検索時に取得した最新情報を組み合わせて回答します。GEOの技術的最適化は、このRAGパイプラインで自社コンテンツが優先的に取得されることを目指します。
**Citation Engine** は、AIが生成した回答に対し、根拠となるURLや文献情報を自動的に添付する機構です。ChatGPTのブラウジング、Perplexityの「Sources」タブ、ClaudeのCitation API、Google AI Overviewの出典リストがこれに該当します。Citation Engineに認識されることが、GEOの最終的なゴールです。
| 項目 | SEO | GEO |
|------|-----|-----|
| 最適化対象 | 検索エンジンの順位アルゴリズム | 生成AIのRAG + Citation Engine |
| 主要KPI | キーワード順位、オーガニックCTR | Citation Rate、Share of Synthesis |
| コンテンツ設計 | キーワード密度、被リンク | 機械可読化、構造化データ、Q&A形式 |
| 成果の現れ方 | 検索結果ページに表示 | AIの回答に引用・出典として表示 |
SEOの技術基盤・コンテンツ戦略・リンク構築・実装ロードマップについては「[2026年最新 SEO対策完全ガイド](/blog/seo-guide-2026/)」で包括的に解説しています。GEOはSEOの上に構築する戦略であり、SEOの基盤が整っていることが前提です。
> 参考・引用:
> [Generative Engine Optimization - CrafterCMS](https://craftercms.com/blog/business/generative-engine-optimization-the-new-frontier-of-web-visibility-in-the-age-of-ai)
> [GEO vs Traditional SEO Guide - Strapi](https://strapi.io/blog/generative-engine-optimization-vs-traditional-seo-guide)
> [How AI Engines Cite Sources - Medium](https://medium.com/@shuimuzhisou/how-ai-engines-cite-sources-patterns-across-chatgpt-claude-perplexity-and-sge-8c317777c71d)
---
## 2. AIに引用される技術的最適化テクニック
GEOの全体像を押さえたところで、次は具体的な技術実装に入ります。AIに引用されるコンテンツを作るには、6つの技術的な実装ポイントがあります。
### 構造化データ(JSON-LD)の実装
schema.orgに準拠したJSON-LDマークアップは、ページの情報を機械可読な形で明示する手段です。`FAQPage`、`Article`、`Product`、`HowTo`などのタイプを指定することで、何がタイトルで何が著者かといった対応関係が曖昧さなく伝わります。ただし後述のとおり、これがAI検索での引用を増やすことは確認されていません。
> **【2026年8月追記】** Googleは公式のAI最適化ガイドで「生成AI検索に構造化データは必須ではなく、追加すべき特別なschema.orgマークアップも存在しない」と明言しました。
> よく引用される「FAQPageで引用率3.2倍」も相関です。schemaを追加した対照実験では、AI Mode(+2.4%)とChatGPT(+2.2%)の変化がノイズと区別できず、引用の増加は確認されませんでした。
> AI Overviews の −4.6% は統計的に有意ですが小さく、schema以外の要因の可能性があります。
> なお同実験の対象は、実験前からAI Overviewsに100回以上引用されていたページに限られ、新規ページでの効果は検証されていません。
> 検証の詳細は「[「FAQスキーマで引用率3.2倍」は本当か — 自社の評価基準から未検証の数値を削除した話](/blog/faq-schema-ai-citation-myth-2026/)」をご覧ください。構造化データは従来SEO用途で引き続き有用ですが、AI引用への効果は約束できません。なおGoogleは `HowTo` のリッチリザルトを2023年に、`FAQPage` のリッチリザルトを2026年5月に廃止しています([FAQPage](https://developers.google.com/search/updates#removing-faq-rich-result))。リッチリザルト目的で残っているのは `Article`・`BreadcrumbList` などです(`Product` は商品ページ、`Review` は対象タイプに対する実際のレビュー・評価があるページに限られ、一般的な記事には使えません)。
```html
```
### Promptフレンドリーな文章設計
私が実際にPerplexityとClaudeで検証した限り、セクション冒頭に結論がある記事とない記事では引用のされ方が明確に違います。各セクションの冒頭40〜50語に結論・キーワードを配置し、見出しをQ&A形式にします。AIは回答生成時にセクション冒頭を優先的に参照するため、「結論ファースト」の構造はそのまま引用できるブロックを作りやすくします(ただし引用が増えるという効果自体は対照実験で検証されていません)。
### コンテンツチャンクの分割
800トークン以内のブロックに分割し、各ブロックに固有の見出しとURLアンカーを付与します。RAGは長文をそのまま処理するよりも、適切に分割されたチャンクを取得する方が精度が高くなります。
### 埋め込みベクトルの最適化
テキストをSentence-Transformerなどのモデルでベクトル化し、FAISSなどのベクトルDBに格納すると、検索時に類似度の高いチャンクがRAGに供給されます。自社でRAGパイプラインを構築する場合に特に有効です。
### URL設計とAIクローラー制御
正規化されたクリーンURL、canonical設定、robots.txtでの `GPTBot` や `PerplexityBot` の許可・除外を明示します。AIに引用されたいページは明確に許可し、引用されたくないページは除外する制御が必要です。
robots.txtに加えて、Cloudflareの「Markdown for Agents」のようなAIエージェント向けフォーマット提供も有効な施策です。Content-Signalヘッダーによる利用目的の制御など、最新のAI対応手法については「[Cloudflare Markdown for AgentsとAI対策の新常識](/blog/cloudflare-markdown-for-agents-2026/)」で解説しています。
### キャッシュ制御
頻繁に更新されない情報は `Cache-Control: max-age=86400` で長期キャッシュし、最新情報は `no-cache` に設定します。APIで提供するデータは `ETag` との併用が推奨されます。
| 施策 | 優先度 | 実装難易度 | AI引用への効果 |
|------|--------|------------|---------------|
| JSON-LD構造化データ | 中 | 中 | リッチリザルト等の従来SEO用途で有用。AI引用への効果は未確認(2026-08 更新) |
| Promptフレンドリー文章 | 最高 | 低 | 引用可能なブロックを抽出しやすくする(引用増加の効果自体は未検証) |
| コンテンツチャンク分割 | 高 | 低 | RAG取得精度の向上 |
| ベクトル埋め込み最適化 | 中 | 高 | 自社RAG構築時に有効 |
| AIクローラー制御 | 高 | 低 | 引用対象ページの明確化 |
| キャッシュ制御 | 中 | 低 | クロール効率の改善 |
> 参考・引用:
> [構造化データの概要 - Google Developers](https://developers.google.com/search/docs/appearance/structured-data/intro-structured-data)
> [生成AI時代のコンテンツ - Google Developers](https://developers.google.com/search/docs/fundamentals/using-gen-ai-content?hl=ja)
> [GEO vs Traditional SEO - Strapi](https://strapi.io/blog/generative-engine-optimization-vs-traditional-seo-guide)
---
## 3. プラットフォーム別の引用戦略と連携方法
ここがGEOの中でも最も面白い部分です。各生成AIプラットフォームは引用メカニズムが異なります。一律の対策では効果が薄く、プラットフォームごとの特性を押さえる必要があります。
### ChatGPT(OpenAI)
ChatGPTはブラウジングモードで取得したページをインラインリンク付きで出典表示します。検索にはOAI-SearchBotクローラーが使用されるため、`robots.txt`での許可が必要です。なお、旧プラグインプログラムは2024年3月〜4月に段階的に廃止され([OpenAI Help Center](https://help.openai.com/en/articles/8988022-winding-down-the-chatgpt-plugins-beta))、後継はカスタムGPT + Actionsです。
具体的には以下を押さえます。
- `robots.txt` で `User-agent: OAI-SearchBot` を許可する
- Bing・Google両方のインデックスに登録する(ChatGPTは複数の検索ソースを利用)
- 「最終更新日」をページ上に明示する(鮮度シグナルが強い)
- カスタムGPTのActionsで自社APIと連携する(旧プラグインの代替)
### Google Gemini
Geminiは複雑なクエリを平均6〜10個のサブクエリに分解し、それぞれに最も権威のあるソースを取得します。このサブクエリ分解の仕組みは「クエリファンアウト」と呼ばれ、AI ModeやAI Overviewsの中核技術として機能しています(詳細は「[クエリファンアウトとは?初心者向け解説](/blog/query-fan-out-guide-2026/)」を参照)。Google SearchのKnowledge Graphに登録された `sameAs`、`url`、`author` などのプロパティが引用に反映されやすい特徴があります。APIレスポンスでは `groundingMetadata.groundingChunks[].web.uri` にソースURLが返されます。
- JSON-LDで `Article` に `author` と `datePublished` を明示する
- Google Cloud ConsoleからVertex AI経由でGemini APIキーを取得する
- マルチモーダルコンテンツ(画像・動画+schema)と週次更新で鮮度シグナルを維持する
### Perplexity
Perplexityは回答下部に「Sources」リストを自動生成し、URLがクリック可能な形で表示されます。Quick Search(高速・簡易)とPro Search(深掘り・複数ソース)で出典の網羅性が異なります。
- `robots.txt` に `User-agent: PerplexityBot` の許可設定を追加する
- FAQ形式(「Q. ○○は?」/「A. …」)で記述すると、QAペアとして認識されやすい
- 信頼性が高いと判断されたサイトが優先的に引用される
### Anthropic Claude
ClaudeのCitation APIは、リクエスト内で提供されたドキュメントの特定箇所(文字位置やページ位置)を参照する構造化された引用ブロックを返します。外部URLを含むフットノートではなく、ドキュメント内の引用箇所を正確に特定する仕組みです。なお、CitationsとStructured Outputsは併用不可で、両方を有効にすると400エラーが返されます。Claude は日本語の自然言語処理精度が高く、論理的な因果関係の文章を引用しやすい特徴があります。
- ドキュメントブロックごとに `citations: {"enabled": true}` を設定して引用を有効化する
- 著者の専門性・権威性を明示するプロフィールを整備する
- if-then構造や因果関係を明示した文章設計で引用精度を高める
| プラットフォーム | 引用方式 | 最重要シグナル | 連携窓口 |
|----------------|---------|---------------|---------|
| ChatGPT | インラインリンク | 鮮度 + OAI-SearchBotクロール許可 | robots.txt + Bing/Googleインデックス |
| Gemini | `groundingChunks[].web.uri` + Knowledge Graph | JSON-LD `author` / `datePublished` | Google Cloud Console |
| Perplexity | Sourcesリスト(クリック可能) | robots.txt許可 + FAQ形式 | Developer APIページ |
| Claude | 構造化引用ブロック | 著者権威性 + 論理的因果関係 | Anthropic Console |
> 参考・引用:
> [Overview of OpenAI crawlers - OpenAI Platform](https://platform.openai.com/docs/bots)
> [Grounding with Google Search - Gemini API](https://ai.google.dev/gemini-api/docs/google-search)
> [Citations - Anthropic API Docs](https://docs.anthropic.com/en/docs/build-with-claude/citations)
> [AI Overviews Everything You Need to Know - Search Engine Land](https://searchengineland.com/google-ai-overviews-everything-you-need-to-know-449399)
---
## 4. 日本語・文化適応のポイント
プラットフォーム別の戦略を理解したところで、次は日本市場ならではの最適化です。GEOを日本で実践するなら、日本語ならではの言語特性と文化的背景への対応は避けて通れません。驚いたのは、敬語表現の使い方がAI引用の精度に影響するという点です。
### 形態素処理とトークン化への対応
日本語は英語と異なり、形態素(単語の最小単位)でトークン化されます。1文が30〜50トークンに収まるように短くまとめることで、RAGが情報を正確にチャンク分割し、取得精度が向上します。長文の接続詞や修飾語を削り、主語と述語を近くに配置しましょう。
### 敬語・敬称の効果的な活用
「ご利用いただく」「お客様」などの敬語を自然にちりばめると、特にClaudeが高い信頼度で引用しやすくなります。ただし過度な敬語は逆効果です。「です・ます」調を基本とし、専門的な解説では「である」調を混ぜる使い分けが効果的です。
### ローカライズされたメタデータの設定
HTMLの `` に `hreflang="ja"`、`language="ja"`、`locale="ja_JP"` を追加し、検索エンジンとAIに日本語ページであることを明示します。多言語サイトではhreflang設定が正確でないと、AIが誤った言語版を引用する可能性があります。
### 文化的トピックとFAQスタイル
「和食」「温泉」「年末年始」など、季節性・地域性が強いキーワードはユーザーの検索意図と合致しやすく、AI引用の対象になりやすい傾向があります。Q&Aを「Q. ○○とは?」/「A. …」の形で記載すると、PerplexityとClaudeがquestion-answerペアと認識しやすくなります。
| 項目 | 注意点 | 具体的な実装 |
|------|--------|-------------|
| 形態素・トークン化 | 1文30〜50トークンに収める | 接続詞・修飾語を削り、短文を意識 |
| 敬語・敬称 | 自然な敬語がClaudeの引用精度を向上 | 「です・ます」調を基本に、過度な敬語は避ける |
| メタデータ | hreflang / locale を正確に設定 | `hreflang="ja"`、`locale="ja_JP"` を `` に追加 |
| 文化的トピック | 季節性・地域性キーワードが有効 | 「和食」「温泉」「年末年始」等を自然に含める |
| FAQスタイル | Q&A形式がAIの認識を助ける | 「Q. ○○とは?」/「A. …」で記述 |
> 参考・引用:
> [GEO(Generative Engine Optimization) - 電通デジタル](https://www.dentsudigital.co.jp/knowledge-charge/articles/2025-0909-geo)
> [AI Overviews Guide - LANY](https://www.lany.co.jp/blog/ai-overviews-guide)
> [Claude Code Guide — 多言語対応 - Zenn](https://zenn.dev/heku/books/claude-code-guide/viewer/15-09-search-citations-multilingual)
---
{{linksurge-card}}
## 5. 日本の法的・規制・倫理コンテキスト
GEOを日本で実践する際、著作権法・個人情報保護法・AIガバナンスの3つの法的領域を理解しておく必要があります。
### 著作権法と情報解析の例外
AI学習段階は情報解析として「非享受利用」に該当し、著作権法第30条の4により原則として許諾不要と解釈されるのが一般的です([文化庁「AIと著作権に関する考え方について」, 2024年3月](https://www.bunka.go.jp/seisaku/chosakuken/pdf/94037901_01.pdf))。ただし生成・利用段階では通常の著作権が適用され、既存作品との「類似性」と「依拠性」が認められれば著作権侵害となる可能性があります。
GEOの文脈では、自社コンテンツがAIに引用されること自体は著作権上の問題になりにくいと考えられていますが、AI生成物が他社著作物と類似するリスクには注意が必要です。具体的な判断はケースにより異なるため、最終的な判断は法務確認を推奨します。
### 個人情報保護法(APPI)への準拠
個人情報保護法(APPI)では、個人情報を含むコンテンツの取得・保存・第三者提供時に利用目的の明示と本人同意が求められるのが原則です([個人情報保護法第17条・第23条](https://www.ppc.go.jp/personalinfo/legal/))。AIが学習に使用する際は「利用目的が情報解析」に限定し、個人識別情報はマスクすることが推奨されます。
ベクトルDBに格納するデータに個人情報が含まれる場合、事前の匿名化・ハッシュ化処理が必要とされています。なお、APPIの解釈は個人情報保護委員会のガイドラインや事業分野により異なるため、最終的な判断は法務確認を推奨します。
### AIガバナンスと透明性
経済産業省のAI原則ガイドラインは「透明性」「公平性」「安全性」「プライバシー」を要件としています。AIが生成したコンテンツに対しては出典表示と誤情報防止が求められ、公的機関が提供するデータは国内サーバでのホスティングが推奨されます。
| 領域 | 主なポイント | 実務での対応 |
|------|------------|-------------|
| 著作権 | 学習段階は原則許諾不要とされる(第30条の4)。生成段階は類似性+依拠性で判断 | 生成物の類似性チェックツール導入。法務確認推奨 |
| 個人情報保護(APPI) | 個人情報のマスク・匿名化が原則必要 | ベクトル化前にPIIをハッシュ化/削除。法務確認推奨 |
| AIガバナンス | 透明性・出典表示・誤情報防止 | 出典表示ポリシーの文書化 |
| データローカリゼーション | 公的データは国内サーバで管理 | 外部転送時は事前同意取得 |
> 参考・引用:
> [AIと著作権に関する考え方について - 文化庁](https://www.bunka.go.jp/seisaku/chosakuken/pdf/94037901_01.pdf)
> [個人情報保護法 - 個人情報保護委員会](https://www.ppc.go.jp/personalinfo/legal/)
> [生成AIの著作権 - LegalOnTech](https://www.legalontech.com/jp/media/copyright-of-generative-ai)
> [AI原則ガイドライン - IPA](https://www.ipa.go.jp/jinzai/ics/core_human_resource/final_project/2024/f55m8k0000003spo-att/f55m8k0000003svn.pdf)
---
## 6. 計測・分析の指標とツール
施策を実行するだけでは不十分で、効果測定の仕組みがなければ改善サイクルが回りません。GEOの効果測定には、従来のSEO指標だけでは不十分です。AI引用に特化したKPIを追加しましょう。
### Citation Rate(引用率)
AIが生成した回答に自社URLが出現した回数を総回答数で割った指標です。Perplexityの「Sources」タブ、ClaudeのCitation API、Geminiの `groundingChunks[].web.uri` をログに集計して算出します。
GEOの最も基本的なKPIであり、月次で推移をトラッキングすることが推奨されます。[LinkSurge](https://linksurge.jp/)のAI Overview分析では、Google AI Overviewsでの引用状況をキーワード単位で確認できます。
### Prompt-CTR(質問クリック率)
検索結果画面で「質問例」がクリックされた率です。Google Search Consoleの「パフォーマンス」→「クエリ」で質問形式のキーワードを抽出し、CTRを分析します。FAQ形式のコンテンツが検索ユーザーの意図に合致しているかを測定できます。
### E-E-A-Tスコア
Googleの品質評価ガイドラインに基づく専門性・権威性・信頼性の内部評価です。構造化データの `author`、`publisher`、`datePublished` が評価対象になります。数値化が難しいため、チェックリスト形式での定期評価が実用的です。
### AIクローラーアクセスのモニタリング
サーバーログで `OAI-SearchBot`、`PerplexityBot`、`Claude-SearchBot` のアクセス状況を監視します(`GPTBot` と `ClaudeBot` は学習用のため、検索での引用を狙う場合の指標にはなりません)。robots.txtの設定が正しく機能しているか、AIクローラーがどのページを取得しているかを把握できます。
| 指標 | 測定方法 | 頻度 |
|------|---------|------|
| Citation Rate | AI回答内の自社URL出現率を集計 | 月次 |
| Prompt-CTR | Search Console → 質問形式クエリのCTR | 週次 |
| E-E-A-Tスコア | チェックリスト形式の内部評価 | 四半期 |
| AIクローラーアクセス | サーバーログでBot別アクセス解析 | 週次 |
| APPIコンプライアンス | データ取得・保持ログの監査 | 四半期 |
> 参考・引用:
> [How AI Engines Cite Sources - Medium](https://medium.com/@shuimuzhisou/how-ai-engines-cite-sources-patterns-across-chatgpt-claude-perplexity-and-sge-8c317777c71d)
> [Google Search品質評価ガイドライン - Google Developers](https://developers.google.com/search/docs/fundamentals/creating-helpful-content?hl=ja)
> [Succeeding in AI Search - Google](https://developers.google.com/search/blog/2025/05/succeeding-in-ai-search?hl=ja)
---
## 7. 5フェーズ実行プラン
GEOの導入は一度にすべてを実装するのではなく、5つのフェーズに分けて段階的に進めることが効果的です。
### フェーズ0:事前分析(1週間)
- 主要キーワード・質問リストの作成(日本語Q&A形式)
- 競合サイトのAI引用状況を調査(Perplexity / Claude で自社カテゴリを検索、[LinkSurge](https://linksurge.jp/)でAI Overview出現状況を分析)
- 現状のCitation Rateをベースライン測定
### フェーズ1:技術基盤の構築(2週間)
- JSON-LDで `FAQPage`・`Article` を実装
- `hreflang="ja"` と `canonical` の設定
- `robots.txt` にAIクローラー許可記述を追加
- Core Web Vitalsの達成確認
### フェーズ2:コンテンツ最適化(3週間)
- 既存ページの冒頭に40〜50語の要点文を配置
- Q&Aペアを各ページ5件以上作成
- 画像・動画に代替テキストを付与
- コンテンツを800トークン以内のチャンクに分割
### フェーズ3:プラットフォーム連携(4週間)
- OAI-SearchBot / PerplexityBot のrobots.txt許可設定
- Gemini APIキー取得・テスト実装
- Perplexity API(Pro)で自社データベース接続
- 各プラットフォームでの引用テストを実施
### フェーズ4:法務・計測・継続改善(継続)
- APPIに基づく個人情報マスク方針の策定
- 著作権リスクチェック(類似性・依拠性の定期確認)
- Citation Rateダッシュボードの構築([LinkSurge](https://linksurge.jp/)のGEO分析機能で競合比較も可能)
- 月次のE-E-A-T評価と改善レポート
---
## 8. リスクと対策
GEO導入にはリスクもあります。事前に把握して備えておきましょう。
### 誤引用・AIハルシネーション
AIが存在しない文献や不正確な情報を生成するリスクがあります。出典必須プロンプトの設計と、生成されたURLの実在確認スクリプト(post-validation)で対策します。
### robots.txt設定ミス
GPTBotやPerplexityBotを誤ってブロックすると、AI引用が激減します。定期的にrobots.txtログを監査し、AIクローラーのUser-Agentを最新リストと照合しましょう。
### 著作権侵害リスク
学習データに問題のあるコンテンツが混入すると、生成物が既存作品と類似する可能性があります。DMCA takedownリストを除外し、生成物の類似性チェックツールを導入することで予防します。
### 個人情報流出
APPIに違反する形で個人データがベクトル化されるリスクがあります。データ前処理の段階でPII(個人識別情報)をハッシュ化・削除し、ベクトル化前の匿名化を徹底します。
### 規制変更リスク
AI関連の法規制は急速に変化しています。EU AI Actや国内AIガバナンス改正に伴う要件追加に対応するため、法務チームによる半年ごとの規制モニタリングが推奨されます。
| リスク | 影響度 | 対策 |
|--------|--------|------|
| 誤引用・ハルシネーション | 高 | 出典必須プロンプト + URL実在確認スクリプト |
| robots.txt設定ミス | 高 | 定期監査 + AIクローラーUA最新リスト照合 |
| 著作権侵害 | 中 | 生成物の類似性チェックツール導入 |
| 個人情報流出 | 高 | PII匿名化・ハッシュ化の前処理必須化 |
| 規制変更 | 中 | 半年ごとの規制モニタリング + コンプライアンス更新 |
> 参考・引用:
> [生成AIの著作権 - LegalOnTech](https://www.legalontech.com/jp/media/copyright-of-generative-ai)
> [AI著作権検討会 - 首相官邸](https://www.kantei.go.jp/jp/singi/titeki2/ai_kentoukai/gijisidai.pdf)
> [日本のデータ保護法 - Kiteworks](https://www.kiteworks.com/ja/risk-compliance-glossary/japanese-data-protection-act/)
---
なお、AI検索が実際にページのどこを引用しているかについては、当社が実引用277件を解析した「[AI検索は記事のどこを引用するのか](/blog/ai-citation-block-position-research-2026/)」で一次データを公開しています。引用の69.3%がリード文以外の見出しブロックから発生していました。
---
## よくある質問(FAQ)
### GEOとSEOの違いは何ですか?
SEOは検索エンジンの順位アルゴリズムを対象とし、キーワード順位やオーガニックCTRをKPIとします。GEOは生成AIのRAGとCitation Engineを対象とし、AIの回答に自社コンテンツが引用される確率(Citation Rate)をKPIとします。SEOの上にGEOを「上乗せ」する形で両立させるのが効果的です。
### GEOを始めるために最低限必要な施策は何ですか?
まず robots.txt を確認してください。**どのクローラーを見るかは、狙うサービスによって変わります**。
| 狙うサービス | 通すべきクローラー |
|---|---|
| Google AI Overviews / AI Mode | `Googlebot`(AI機能もGoogle検索のインデックスを使います) |
| ChatGPT の検索 | **`OAI-SearchBot`** |
| Perplexity | `PerplexityBot` |
| Claude | `Claude-SearchBot`(検索用) / `Claude-User`(ユーザーの質問に応じた取得用)。`ClaudeBot` は学習用で引用には効かない |
**学習用のクローラーと混同しないでください。** `GPTBot` はOpenAIのモデル学習用で、ChatGPTの検索での引用には効きません。OpenAIは「`OAI-SearchBot` をオプトアウトしたサイトは ChatGPT の検索回答に表示されない」と明記しています。
同様に `Google-Extended` は Gemini Apps / Vertex AI 向けのトークンで、**Google検索やAI Overviewsには影響しません**。どちらも「自社コンテンツを学習・グラウンディングに使わせるか」という別の判断です。
なお、クローラーを通すことは**本文を読み取ってもらうための必要条件**であって、引用を保証するものではありません。ただしブロックしていると、以降の改善がそのサービスに届きません。
そのうえで、各セクション冒頭に40〜50語の結論を置き、問いと答えの対応を明確にしていきましょう。
構造化データ(`Article`・`Product` 等)は、リッチリザルトなど検索結果での見え方に目的がある場合に実装してください。なおGoogleは `HowTo` のリッチリザルトを2023年に、`FAQPage` のリッチリザルトを2026年5月に廃止しています([FAQPage](https://developers.google.com/search/updates#removing-faq-rich-result))。リッチリザルト目的で残っているのは `Article`・`BreadcrumbList` などです(`Product` は商品ページ、`Review` は対象タイプに対する実際のレビュー・評価があるページに限られ、一般的な記事には使えません)。**AI引用を増やす目的での実装は、効果が確認されていません**(2026-08 更新)。
### Perplexityに自社サイトを引用させるにはどうすればいいですか?
`robots.txt` で `User-agent: PerplexityBot` を許可し、FAQ形式(「Q. ○○は?」/「A. …」)でコンテンツを記述します。Perplexityは信頼性の高いサイトを優先的に引用するため、E-E-A-T(特に著者情報と更新日)の明示も重要です。Pro Searchモードでは複数ソースを深掘りするため、専門性の高いコンテンツが引用されやすくなります。
### 日本語コンテンツでもGEOは効果がありますか?
はい、効果があります。特にClaudeは日本語の自然言語処理精度が高く、敬語表現を正しく解釈します。日本語では1文を30〜50トークンに収める短文設計が有効です。`hreflang="ja"` と `locale="ja_JP"` の設定も忘れずに行いましょう。日本特有の文化的トピック(和食、温泉など)はAI引用の対象になりやすい傾向があります。
### GEOに法的リスクはありますか?
はい、主に3つの領域に注意が必要です。著作権法では、AI生成物が既存作品と「類似性」+「依拠性」を持つ場合に侵害になります。個人情報保護法(APPI)では、ベクトルDB格納前のPII匿名化が必須です。また、AIガバナンスガイドラインでは出典表示と誤情報防止が求められます。法務チームによる定期的なリスク評価を推奨します。
---
## まとめ:GEO導入は構造化データとQ&A形式から始めよう
GEOの基本は3つです。構造化データの整備、Q&A形式のコンテンツ設計、そしてプラットフォームごとの出典要求への対応。この3つを組み合わせることで、AIが自社コンテンツを「引用」する確率を高められます。
まず着手すべきは、フェーズ0(競合のAI引用状況調査)とフェーズ1(JSON-LDとrobots.txt整備)です。この2ステップは1〜2週間で完了でき、Citation Rateの改善を即座に実感できるはずです。その後、コンテンツのAPO化とプラットフォーム連携を段階的に進め、法務・コンプライアンスの体制を整えていきましょう。
GEOの成功にはサイト外でのブランド言及が不可欠です。被リンクよりブランド言及が重要な理由と具体的な施策については「[AI検索に選ばれるには「自サイトの外」が9割](/blog/offsite-seo-geo-2026/)」で解説しています。
LinkSurgeの[AI Overview分析機能](https://linksurge.jp/aio-v5)では、Google AI OverviewsやChatGPTでの自社ブランドの引用状況をリアルタイムで分析できます。GEO戦略の効果測定ツールとして、ぜひご活用ください。
GEOに関連する「LLMO(大規模言語モデル最適化)」という概念をより基礎から理解したい方は、[LLMOとは何か?初心者にも分かる完全ガイド](/blog/llmo-guide-beginners-2026/)も参考にしてください。
可視コンテンツがない極端な条件でもAIが構造化データを読み取った事例として「[見えないサイトがAI検索1位に — 構造化データだけでPerplexityに引用された衝撃の実験](/blog/phantom-authority-invisible-website-ai-citation-2026/)」も参考になります(通常のページでschemaを足せば引用が増えることを示すものではありません)。
---
## 2026年最新 SEO対策完全ガイド:AI検索時代の技術SEO・コンテンツ・GEO戦略
> URL: https://linksurge.jp/blog/seo-guide-2026/
> Date: 2026-02-10 | Category: SEO | Author: 緒方亜朗
> Tags: SEO, AI Overviews, GEO, 技術SEO, E-E-A-T, コンテンツSEO, 2026年
## この記事の結論:2026年SEOで成果を出す5つの要点
2026年のSEOは「検索結果に表示される」だけでなく「AIに引用される」ことが成果を左右する時代に突入しました。私が最新のアルゴリズム動向とデータを調査して見えてきた、実践上の要点は以下の5つです。
1. **技術基盤を整備する** — INP 200ms以下、LCP 2.5秒以内、CLS 0.15以内を達成し、FAQ・HowTo・Articleなどの構造化データ(JSON-LD)を実装する。AIクローラがJavaScriptを実行しないケースに備え、SSRで重要情報をHTMLに出力する
2. **コンテンツに実体験と専門知識を入れる** — AI生成の下書きをそのまま公開せず、現場の経験・独自データ・ファクトチェック済みの統計を加える。質問ベースの見出し(H2/H3)と40〜60語のAtomic Answersで、AIが回答を引用しやすい構造にする
3. **GEO(Generative Engine Optimization)を実行する** — ChatGPT、Perplexity、ClaudeなどのAI検索における引用状況を「シェア・オブ・シンセシス」で定量測定し、KPIとして追跡する。AI Overviewsは商用クエリの約18%に表示されている
4. **権威性を積み上げる** — 業界レポートやオリジナル調査を公開して自然な被リンクを獲得し、E-E-A-T(経験・専門性・権威性・信頼性)をサイト全体で強化する
5. **規模に合ったツールで運用を自動化する** — GSC+GA4の無料ツールから始め、規模に応じて[LinkSurge](https://linksurge.jp/)やSemrush AI Visibility、Botifyなどを導入。レポート自動化でROIを可視化し、月次で改善サイクルを回す
以下では、各テーマを順に掘り下げていきます。
---
## 1. 技術SEO

2026年のSEO対策を調べていて強く感じるのは、技術基盤が整っていないサイトがAI検索時代に取り残されつつあるという現実です。「コンテンツさえ良ければ順位は上がる」——そう信じているサイト運営者はまだ多いのですが、データはそれを否定しています。
### Core Interaction Signals(CIS)
2024年にFIDが廃止され、代わりにINP(Interaction to Next Paint)が主要指標になりました。INPはページ上のすべてのインタラクション(クリック・タップ・キー入力)の応答速度を測定し、200ms以下を「Good」と判定します。200msを超えるとランキングに悪影響が出るため、重いJavaScriptやアニメーションの見直しが必要です。
### Core Web Vitalsの最新基準
2026年時点の合格ラインは以下のとおりです。
- LCP(Largest Contentful Paint):2.5秒以内
- CLS(Cumulative Layout Shift):0.15以内
- INP:200ms以内
画像圧縮、CSS/JSの最小化、CDN活用といった基本的な速度改善が引き続き有効です。
### サイト構造と内部リンク
トピッククラスター(ピラーページ+サブページ)で階層を浅く保ち、重要ページにリンクエクイティを集中させましょう。また、トラフィックがほとんどない薄いページは、削除やnoindex指定で「プルーニング」することも有効です。[トピッククラスターと内部リンク戦略](/blog/topic-cluster-internal-linking-strategy/)では、具体的な設計手順やプルーニングの判定基準を詳しく解説しています。
### JavaScript SEO
ここは見落とされがちですが、私がSEO改善案件で最初にチェックするポイントの一つです。SSR(サーバーサイドレンダリング)や動的レンダリングを使い、重要なコンテンツをHTMLに直接出力しましょう。AIクローラがJavaScriptを実行しないケースもあるため、HTMLに情報が含まれていることが重要です。
### その他の技術施策
- **ソフト404対策**:販売終了・在庫切れの商品ページには404/410ステータスを返すか、代替商品へリダイレクトする
- **スキーママークアップ**:Article、FAQ、HowTo、Product、Organizationなどの構造化データを実装し、AIが情報を正しく理解できるようにする
- **HTTPS**:全ページで必須。CSPヘッダーも設定してセキュリティシグナルを強化する
- **クロール予算管理**:大規模サイトではURLパラメータの除外やXMLサイトマップの定期更新で、重要ページが優先的にインデックスされるよう調整する
XMLサイトマップの戦略的な活用方法については「[XMLサイトマップ戦略2026:セグメント化とクロール予算管理でインデックスを最大化](/blog/xml-sitemap-strategy-2026/)」で詳しく解説しています。
こうした技術的な土台がなぜ30年間ずっと評価の中心にあり続けているのかは、「[SEOはどう変わってきたか — キーワードを詰め込めば勝てた1990年代から、AIに引用される2026年まで](/blog/seo-history-keywords-to-ai-2026/)」で年表とともに整理しています。
> 参考・引用:
> [Technical SEO Checklist - Yotpo](https://www.yotpo.com/blog/full-technical-seo-checklist/)
> [Google Ranking Factors 2026 - Wix SEO Expert](https://www.wixseoexpert.com/post/google-ranking-factors-the-complete-list-2026)
> [Google's Recent Changes for SEO - Whistler Billboards](https://www.whistlerbillboards.com/marketing/googles-recent-changes-for-seo-in-2026/)
> [Core Web Vitals in 2026 - CD Studio](https://www.cdstudio.live/post/core-web-vitals-in-2026-how-to-pass-google-s-toughest-performance-metrics)
> [How to Optimize Content for AI Search - Semrush](https://www.semrush.com/blog/how-to-optimize-content-for-ai-search-engines/)
---
## 2. コンテンツSEO

技術基盤を押さえたところで、次はコンテンツ戦略に目を向けます。
### キーワードリサーチとインテントマッピング
会話型検索の増加に合わせて、「○○のやり方」「○○はどれがベスト?」のような質問形キーワードを積極的に取り入れましょう。H2やH3に質問形式の見出しを配置すると、AIが回答を抽出しやすくなります。
また、トピッククラスターの設計も重要です。ピラーページでテーマの全体像をカバーし、サブページで個別の疑問に答える構造にすると、AI Overviewに引用されやすくなります。
### AI生成コンテンツとの付き合い方
Googleは2026年現在、AI生成コンテンツ自体を禁止していません。ただし、AIが書いた下書きをそのまま公開するのではなく、実体験や専門的な知見、具体的な事例を必ず加えることが求められます。
面白いのは、Googleが評価する「Experience(経験)」要素がまさにAIだけでは生み出せないものだという点です。事実確認を怠ったAIコンテンツは「低品質」と判定されるリスクがあるため、公開前のファクトチェックと独自の視点の追加は避けて通れません。料理のレシピに例えるなら、AIは材料を揃えてくれるが、味付けと盛り付けは人間の仕事です。
### E-E-A-Tを実装に落とし込む
- **Experience(経験)**:「実際に試してみた」「現場で起きた問題とその対処法」など、一次情報を積極的に盛り込む
- **Expertise(専門性)**:著者プロフィールに資格や実績を記載し、専門家によるレビューや監修バッジを付与する
- **Authoritativeness(権威性)**:業界メディアからの被リンクや引用実績を積み重ねる
- **Trustworthiness(信頼性)**:HTTPS、プライバシーポリシー、編集方針、更新日を明示する。YMYL分野では医師や弁護士の監修を必ず記載する
### コンテンツの鮮度と深さ
統計データや事例、リンク先を定期的に見直して最新の状態に保ちましょう。AIは「この情報は新しいか」を判断材料にしています。
また「原子回答(Atomic Answers)」と呼ばれるテクニックも有効です。1つの質問に対して40〜60語程度の簡潔な回答を段落としてまとめておくと、AIがそのまま引用しやすくなります。
> 参考・引用:
> [SEO 2026 - LaTevaWeb](https://www.latevaweb.com/en/seo-2026)
> [Google Policy on AI-Generated Content 2026 - LinkedIn](https://www.linkedin.com/pulse/google-policy-ai-generated-content-2026-complete-guide-hertlein-r45nf)
> [Modern Content Marketing in the Age of AI - Pod Digital](https://www.poddigital.co.uk/digital-marketing-news/the-2026-guide-to-modern-content-marketing-in-the-age-of-ai-search/)
> [SEO Cheat Sheet 2026 - LinkedIn](https://www.linkedin.com/posts/sunny-grewal_seo-cheat-sheet-updated-for-2026-activity-7405101661792210944-C2WY)
> [Optimize for Google AI Overviews - Fuel Online](https://fuelonline.com/optimize-for-google-ai-overviews/)
---
## 3. AI主導の検索機能への対応

コンテンツ戦略を見直したところで、次はいよいよ2026年SEOの最大の変化——AI検索への対応です。
### SGEとAI Overviews
私がこの1年で最もインパクトを感じている変化がこれです。Googleの検索結果にはAIが生成した要約(AI Overview)が表示されるようになり、商用クエリの約18%がAI Overviewに置き換わっています。従来の検索結果1位よりも「AIに引用される」ことがクリック獲得の新たな鍵になっています。
引用されやすくするには、まず狙うサービスのクローラーが通っているかを確認したうえで、質問ベースの見出し設計とトピックを深掘りした内容が有効と考えられます。構造化データはリッチリザルト等の従来SEO用途で有用ですが、AI引用を増やす効果は確認されていません。AI OverviewsやAI Modeがオーガニック流入に与える影響と7つの対策は「[生成AI検索がSEOを変える:実践対策ガイド](/blog/ai-search-seo-japan-2026/)」で詳しく解説しています。
### GEO(Generative Engine Optimization)
ChatGPT、Perplexity、Claudeなどの生成AI検索での露出を測る指標として「シェア・オブ・シンセシス(Share of Synthesis)」が注目されています。[LinkSurge](https://linksurge.jp/)などのGEO分析ツールを使って、AI検索エンジンにどれだけ引用されているかを定期的にモニタリングし、KPIとして追跡しましょう。
シェア・オブ・シンセシスとは、AI検索エンジンが複数の情報源を統合(synthesize)して生成する回答の中で、特定のブランドや情報源がどれだけ引用・言及されているかを示す割合です。従来のSEO指標である「シェア・オブ・ボイス」のGEO版と考えるとわかりやすいでしょう。SNS投稿もAI検索の引用ソースになりつつあり、X・Instagram・LinkedInでのアルゴリズム対応戦略は「[SNS AI検索最適化ガイド](/blog/sns-ai-search-optimization-2026/)」で解説しています。
| 指標 | 測定対象 |
|------|----------|
| **シェア・オブ・ボイス**(従来SEO) | 検索結果ページでの表示占有率 |
| **シェア・オブ・シンセシス**(GEO) | AI生成回答内での引用・言及占有率 |
たとえば、あるカテゴリに関する100回のAI検索で自社サイトが30回引用されていれば、シェア・オブ・シンセシスは30%です。この数値を継続的に追跡することで、GEO施策の効果を定量的に評価できます。GEOの技術実装やプラットフォーム別の引用戦略については「[GEO完全ガイド:ChatGPT・Gemini・Perplexityに引用される実践手法](/blog/geo-guide-japan-2026/)」で網羅的に解説しています。
### ゼロクリック検索への対策
AIが直接回答を提示することで、従来のクリック率は大幅に低下しています(AI Overviewで最大61%減少との報告もあります)。対策としては、FAQやHowToのスキーマでリッチスニペットを獲得する、動画やインフォグラフィックで視覚的な価値を提供するなど、検索結果上でユーザーの目を引く工夫が必要です。
> 参考・引用:
> [What is SGE - Md Azizur Rahman](https://mdazizurrahman.com.bd/what-is-sge/)
> [Google SGE SEO Guide for 2026 - Promfly](https://www.promfly.com/blogs/google-sge-seo-guide-for-2026)
> [Generative Engine Optimization - Geoptie](https://geoptie.com/blog/generative-engine-optimization)
> [GEO Guide - LLM Refs](https://llmrefs.com/generative-engine-optimization)
---
## 4. リンク構築と権威性
### 自然な被リンクを獲得する
データを見ると、被リンクの「量」より「質」の重要性が年々高まっています。最も効果的な方法は、業界レポートやオリジナルの調査データを公開することです。データに基づいたコンテンツは他メディアから引用されやすく、自然な被リンクにつながります。デジタルPRやメディア掲載も権威性の向上に有効です。
### ゲスト投稿と専門家寄稿
信頼性の高い業界サイトに記事を寄稿する際は、アンカーテキストをブランド名や自然な文脈に限定しましょう。不自然なキーワードアンカーは逆効果です。
### ローカルSEOのリンク施策
Google Business Profileをはじめ、Yelpや地域の商工会議所ディレクトリに正確なNAP(名称・住所・電話番号)を登録し、ローカルシグナルを強化します。
### 避けるべき手法
高ドメインオーソリティのサイトに寄生する「パラサイトSEO」(ドメインレンディング)はGoogleのペナルティ対象です。また、リンクプロファイルの定期監査でスパムリンクを発見した場合は、Disavowファイルで除外しましょう。
PBNやサテライトサイトネットワークを使ったリンク構築も厳しく取り締まられています。SpamBrainの検出精度向上により、短期的な順位上昇が長期的な大幅ペナルティにつながるリスクが高まっています。安全なリンク構築戦略については「[サテライトサイトSEOのリスクと安全なバックリンク獲得法](/blog/satellite-site-seo-risks-2026/)」で詳しく解説しています。
> 参考・引用:
> [Link Building Strategies That Work - Coalition Technologies](https://coalitiontechnologies.com/blog/link-building-strategies-that-work)
> [How to Improve Google Search Ranking - Link Building HQ](https://www.linkbuildinghq.com/blog/how-to-improve-google-search-ranking-in-2026/)
> [Link Building Strategies - Backlinko](https://backlinko.com/link-building-strategies)
> [Link Building Strategies 2026 - Sky SEO Digital](https://skyseodigital.com/link-building-strategies-that-actually-work-in-2026/)
> [Parasite SEO - Junia AI](https://www.junia.ai/blog/parasite-seo)
---
## 5. ユーザーエクスペリエンス指標
率直に言って、UX指標はSEOの中で最も「やればやるだけ成果が出る」領域です。INP・LCP・CLSの総合スコアは0.92以上を目標にしましょう。日本ではモバイルからのアクセスが60%を超えるため、モバイルでのページ読み込みを2秒以内に収めることが特に重要です。
CTR、滞在時間、スクロール深度といったエンゲージメント指標は、AIが「このページはユーザーにとって有益か」を判断する材料になっています。インタラクティブ要素のレスポンスをすべて改善し、FAQ・HowTo・Productスキーマでリッチリザルトを獲得してクリック率を高めましょう。
> 参考・引用:
> [SEO 2026 PDF - Developer Aman](https://developeraman.vercel.app/assets/seo_2026.pdf)
> [Core Web Vitals for Beginners - Medium](https://medium.com/front-end-weekly/enhance-ux-exploring-core-web-vitals-for-beginners-ca0bdf9dedfc)
> [Mastering Japanese SEO - WPIC](https://wpic.co/blog/mastering-japanese-seo-10-key-strategies)
{{linksurge-card}}
---
## 6. ツールと測定
### 基本ツール
- **Google Search Console**:インデックス状況、CIS指標、AI Overviewのインプレッションを確認
- **GA4 + Looker Studio**:ユーザー行動、コンバージョン、AI経由トラフィックの分析
### AI可視化ツール
- [LinkSurge](https://linksurge.jp/) — AI Overviews分析・SEO順位計測・GEO分析を統合した国産プラットフォーム
- Semrush AI Visibility Toolkit
- Surfer SEO AI Tracker
- Rankscale.ai / OmniSEO®
AI Overviews・SGE・ChatGPTでの表示状況や「シェア・オブ・シンセシス」を定量的に測定できます。
### 技術監査
Screaming Frog、Sitebulb、Botifyなどでクロールエラーやスキーマの検証を行います。
### リンク調査
Ahrefs、Majestic、SE Rankingで被リンクの品質やアンカーテキスト分布を定期チェックしましょう。
### レポート自動化
Whatagraph(AI要約レポート)やSearch Atlas(自動修正提案)を活用すると、月次レポートの作成工数を大幅に削減できます。
> 参考・引用:
> [AI-Driven SEO Tools for Agencies - Eesel AI](https://www.eesel.ai/blog/ai-driven-seo-tools-for-agencies)
> [Best SEO Tools - Marketer Milk](https://www.marketermilk.com/blog/best-seo-tools)
> [AI Search Visibility Audit Tools - The Rank Masters](https://www.therankmasters.com/insights/ai-search-visibility-audit-tools)
> [AI SEO Tools - Whatagraph](https://whatagraph.com/blog/articles/ai-seo-tools)
> [AI SEO Tracking Tools 2026 - Search Influence](https://www.searchinfluence.com/blog/ai-seo-tracking-tools-2026-analysis-platforms/)
---
## 7. 業種別の適用ポイント

ここまで紹介してきた施策は業種を問わず有効ですが、注力すべきポイントは業種ごとに異なります。私がよく受ける「結局うちの業界では何を優先すればいいの?」という質問に答える形でまとめます。
### Eコマース
商品ページにProductスキーマ(price、availability、GTIN)を設定し、在庫切れ商品は404/410で処理します。クロール予算は上位カテゴリに集中させ、AI Overviewでの「商品比較」引用を狙いましょう。
### ブログ・メディアサイト
トピッククラスターとFAQスキーマを組み合わせた長文コンテンツが基本です。動画やインフォグラフィックを加えてマルチモーダルに対応し、既存記事の定期リフレッシュも忘れずに。
### 企業・B2B
Organization、Person、Reviewスキーマを企業ページに設置します。ホワイトペーパーやケーススタディでE-E-A-Tを強化し、AI Overviewで「業界のベストプラクティス」として引用されることを目指します。
### ローカルビジネス
NAPの統一管理、Google Business ProfileとLocalBusinessスキーマの設定、地域別サービスページの作成が基本です。地域のレビュー獲得も信頼性向上に直結します。
### YMYL(金融・医療・法務)
専門家の監修表示が必須です。医師や弁護士の資格情報、更新日、リスク情報を明示し、AIコンテンツは必ず専門家の確認を経てから公開してください。
> 参考・引用:
> [Ecommerce Website SEO - DebugBear](https://www.debugbear.com/blog/ecommerce-website-seo)
> [How to Rank YMYL Finance Pages - Bruce Jones SEO](https://brucejonesseo.com/how-to-rank-ymyl-finance-pages-in-2026/)
> [SEO Best Practices for Small Business - First Ep Business](https://firstepbusiness.com/blog/seo-best-practices-for-a-small-business-2026-guide)
> [SEO for Enterprise - Saffron Edge](https://www.saffronedge.com/blog/seo-for-enterprise)
> [SEO in Japan Complete Guide - HashMeta](https://hashmeta.com/blog/seo-in-japan-complete-guide-to-ranking-on-google-japan-yahoo-japan/)
---
## 8. 予算・リソース別の実装プラン
### 小規模(個人・スタートアップ)— 月額5〜15万円
基本的な技術監査、既存コンテンツのリフレッシュ、ローカルリンク獲得に注力します。GSCとGA4(無料)、Screaming Frog無料版を使い、AIコンテンツの編集は手作業で行います。
### 中規模(SMB)— 月額15〜50万円
技術最適化、AIを活用したコンテンツ生成、リンク構築、ローカルSEOをバランスよく実施します。[LinkSurge](https://linksurge.jp/)でAI Overviews・GEO分析を効率化し、Semrush OneやWhatagraphによるレポート自動化と組み合わせると費用対効果の高い運用が可能です。
### 大企業・エンタープライズ — 月額50万〜200万円以上
プログラマティックSEO、GEO戦略、多言語・多地域管理、ダッシュボード統合を推進します。BotifyやConductor、OmniSEO®、Looker Studio + BigQuery連携が適しています。
> 参考・引用:
> [SEO for Small Business - 8Spark](https://8spark.com/blogs/seo-for-small-business)
> [Enterprise SEO Resolutions 2026 - Seeders](https://seeders.com/blog/7-best-enterprise-seo-resolutions-for-2026/)
> [Small Business SEO vs Enterprise SEO - EWR Digital](https://www.ewrdigital.com/blog/small-business-seo-vs-enterprise-seo)
---
## 9. 実装ロードマップ
### フェーズ1:クイックウィン(0〜2週間)
- INP・LCPのベースラインをGSCとPageSpeed Insightsで測定
- 重要ページにFAQ/HowToスキーマを追加
- 低品質ページをnoindex設定または削除
### フェーズ2:基盤強化(3〜6週間)
- トピッククラスターに基づくサイト構造の再設計
- 商品・サービスページにProduct/Serviceスキーマを実装
- AI Overviews対策として、質問ページにAtomic Answersを配置
### フェーズ3:コンテンツ拡充(7〜12週間)
- AIで下書きを作成し、経験・事例を加えてHuman-First Editingで仕上げる
- 動画やインフォグラフィックでマルチモーダル対応
- 既存コンテンツの統計データ・リンクを最新化
### フェーズ4:権威構築(13〜24週間)
- 業界レポート公開やデジタルPRで高品質な被リンクを獲得
- インフルエンサーや業界専門家の寄稿を企画
- [LinkSurge](https://linksurge.jp/)などのAI可視化ツールでシェア・オブ・シンセシスを追跡・改善
### フェーズ5:継続的な最適化(25週間以降)
- CISとAI Overviewインプレッションの月次レビュー
- 新しい検索アルゴリズムやAI機能への対応計画を策定
- コンテンツカレンダーとSEOダッシュボードで運用を自動化
> 参考・引用:
> [Complete SEO Roadmap for 2026 - Pennep](https://www.pennep.com/blog/complete-seo-roadmap-for-2026-strategies-tools-and-best-digital-marketing-expertise-practices-for-google-rankings)
> [Actionable Tactics to Improve Google Rankings - SEOlogist](https://www.seologist.com/knowledge-sharing/top-21-actionable-proven-tactics-to-improve-google-search-ranking)
---
## 10. CMS選びと日本市場の留意点
### WordPress
Yoast SEOやRank Mathなどプラグインが豊富で、URL制御やスキーマ自動生成に強みがあります。WPMLやPolylangで多言語対応も可能です。コンテンツ量の多いブログや企業サイトに向いています。
### Wix / Wix Studio
組み込みのSEOウィザードとモバイル最適化機能を備え、小規模サイトやスタートアップに手軽です。ページ速度はプラットフォームに依存する点に注意が必要です。
### Shopify
Eコマース向けのスキーマ自動生成やCDN・高速ホスティングが強みです。SEO拡張アプリも充実しており、商品数の多いオンラインストアに適しています。
### Headless CMS(Contentful、Sanity)
APIファーストでマルチチャネル配信が可能。スキーマ管理も柔軟で、大規模・多言語・マルチプラットフォーム戦略に最適です。
### Drupal
高度な権限管理とセキュリティが特徴で、エンタープライズ規模のSEO構築に向いています。政府機関や教育機関でも多く採用されています。
> 参考・引用:
> [Which CMS is Best for SEO - SEO Locale](https://seolocale.com/which-cms-is-best-for-seo-top-platforms-compared-for-2026/)
> [WordPress vs Wix SEO - BT Marketing](https://btmarketing.ca/wordpress-vs-wix-seo-ranking/)
> [WordPress Alternatives 2026 - Creative Corner](https://www.creativecorner.studio/blog/10-wordpress-alternatives-2026-edition)
> [Mastering Japanese SEO - WPIC](https://wpic.co/blog/mastering-japanese-seo-10-key-strategies)
---
## よくある質問(FAQ)
### 2026年のSEOで最も重要な変化は何ですか?
AI検索エンジン(Google AI Overviews、ChatGPT、Perplexity)の台頭により、「検索結果で上位表示される」だけでなく「AIの回答に引用される」ことが新たな重要指標になっています。GEO(Generative Engine Optimization)という概念が生まれ、シェア・オブ・シンセシスでAI引用率を測定する時代に移行しています。
### SEO初心者はまず何から始めるべきですか?
まずはCore Web Vitals(INP・LCP・CLS)の改善とFAQ・HowToなどの構造化データ(JSON-LD)の実装から始めましょう。技術基盤が整っていないと、どれだけ良いコンテンツを書いてもGoogleやAI検索エンジンに正しく認識されません。Google Search ConsoleとGA4の設定も最優先です。
### AI Overviewsに表示されるにはどうすればいいですか?
AI Overviewsに引用されやすいコンテンツには3つの特徴があります。(1) 質問形式の見出し(H2/H3)で検索意図に直接回答する構造、(2) 40〜60語程度のAtomic Answers(AIがそのまま引用できる独立した段落)、(3) E-E-A-T(経験・専門性・権威性・信頼性)が明確な情報源であること。構造化データの実装も引用率を高めます。
### SEOツールは無料と有料のどちらを使うべきですか?
サイト規模と予算に応じて段階的に選択するのがベストです。個人ブログや小規模サイトならGoogle Search Console+GA4の無料ツールで十分です。月間数万PV以上の事業サイトでは、[LinkSurge](https://linksurge.jp/)、Semrush、Ahrefsなどの有料ツールでキーワード分析・競合調査・AI可視化を効率化するとROIが大きく向上します。
### E-E-A-Tを高めるための具体的な方法は?
著者プロフィールページを作成し、実名・経歴・資格を明示することが第一歩です。さらに、業界レポートや独自調査データの公開で自然な被リンクを獲得し、専門メディアへの寄稿やインタビュー掲載でオフサイトの権威性も積み上げましょう。Schema.orgのPerson・Organizationマークアップで構造化データとしてもGoogleに伝えることが重要です。
---
## まとめ:まず何から始めるか
[検索意図とは?SEOにおける4つの分類と分析・最適化の実践ガイド](/blog/search-intent-seo-guide/)では、検索意図の4分類と具体的な分析手法を解説しています。コンテンツ戦略の出発点として参考にしてください。
記事冒頭で挙げた5つの要点を、優先度の高い順に実行していくのが現実的なアプローチです。
最初の2週間で技術監査とスキーマ実装(フェーズ1)を完了させ、その後3〜6週間でコンテンツ構造の見直しとAtomic Answersの配置(フェーズ2)を行い、並行してGEO指標のモニタリングを開始する。リンク構築とPRによる権威性の強化(フェーズ4)は中長期の施策として継続し、AI可視化ツールで成果を定量的に追跡してください。
日本語サイトでもグローバル展開でも、この順序で段階的に進めれば持続的なオーガニック流入とブランド認知の向上が見込めます。
AI検索時代には自サイトの外でのブランド露出がますます重要になっています。被リンクよりもブランド言及が引用率を左右する理由と実践手法については「[AI検索に選ばれるには「自サイトの外」が9割](/blog/offsite-seo-geo-2026/)」で詳しく解説しています。
[LinkSurge](https://linksurge.jp/)では、AI Overviews分析・SEO順位計測・GEO分析など、2026年のSEO戦略に必要な機能を提供しています。データに基づいた効率的なSEO・GEO対策を始めてみませんか?
---
# English Articles
---
## The Domains ChatGPT Cites in Japan: Why Reddit, PR TIMES, note and Rakuten Top the List, and How to Map Citation Sources for Your Own Market
> URL: https://linksurge.jp/blog/en/chatgpt-citation-sources-japan-2026/
> Date: 2026-09-08 | Category: AIO | Author: Aro Ogata
> Tags: ChatGPT optimization, citation sources, Ahrefs, PR TIMES, note, Reddit, Japan market, AI search optimization
## Key Takeaways: ChatGPT's Citation Map Is Two Layers, Global Reference Sources Plus Local Publishing Platforms
The first question I get about ChatGPT optimization is always "where do I need to be listed to get cited?" I lined up Ahrefs' Japan data across three points in time, from May 2025 to June 2026, and cross-checked it against their industry breakdown. Japan is the market we track most closely, but the structure generalizes. Here's what emerged.
1. **The top of the list mixes global reference sources with local publishing platforms** — ChatGPT's top 10 cited domains for Japanese queries in June 2026 were Reddit, PR TIMES (press release wire), Ameblo (blog platform), English Wikipedia, note (long-form platform), Rakuten marketplace, Mynavi News, YouTube, Yahoo! Chiebukuro (Q&A), and ITmedia. Other AI engines put Japanese Wikipedia and note at the top consistently. Only ChatGPT blends in English-language sources
2. **Rankings reshuffle within three months** — Ameblo was first in April 2026 and third in June. Reddit went from eighth to first. YouTube and Yahoo! Chiebukuro entered the top 10 in June. Optimizing for "whoever is first right now" doesn't hold up
3. **Every industry has a different staple** — In Ahrefs' industry analysis (September to December 2025), ChatGPT's top cited domain was Reddit for IT, PR TIMES for food, and English Wikipedia for automotive. You have to draw the map for your own category
4. **English Wikipedia outranking Japanese Wikipedia points to English sub-query expansion** — Ahrefs suggests ChatGPT expands Japanese questions into English sub-queries internally. MJ Cachón's brand-prompt study found 27.3% of sub-queries for international brands contained English vocabulary
5. **Only 32.3% of ChatGPT's top 1,000 cited URLs are within marketers' direct reach; the remaining roughly 67% are not** — In Ahrefs' September 2025 analysis (English-language data), the main non-influenceable buckets were Wikipedia at 29.7%, homepages at 23.8% and app stores at 6.6%. Focus on the influenceable 32.3% (educational content, reviews, news, blogs), and treat the homepage share as "fix your own official site"
Below, I go through the timeline, the industry view, the language question and the influence question, and close with a method for mapping your own category.
---
## 1. Three Snapshots of ChatGPT's Citation Sources in Japan
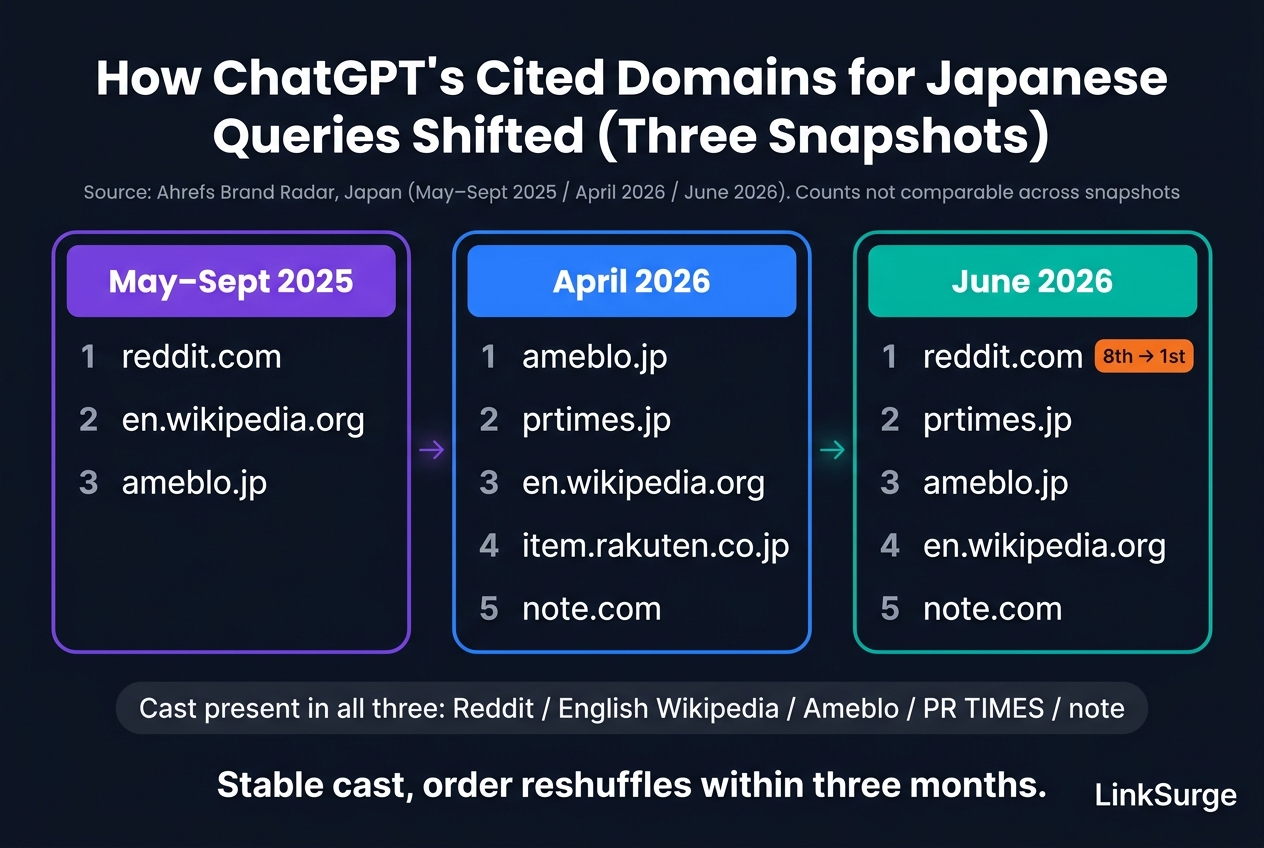
Ahrefs publishes rankings of domains cited by AI search in Japan based on its Brand Radar data. Three snapshots are public for ChatGPT.
| Rank | May–Sept 2025 | April 2026 | June 2026 |
|:---|:---|:---|:---|
| 1 | reddit.com (228,388) | ameblo.jp (103,459) | reddit.com |
| 2 | en.wikipedia.org (166,445) | prtimes.jp (95,655) | prtimes.jp |
| 3 | ameblo.jp (131,629) | en.wikipedia.org (71,950) | ameblo.jp |
| 4 | — | item.rakuten.co.jp (53,147) | en.wikipedia.org |
| 5 | — | note.com (52,679) | note.com |
| 6 | — | — | item.rakuten.co.jp |
| 7 | — | — | news.mynavi.jp |
| 8 | — | — | youtube.com |
| 9 | — | — | detail.chiebukuro.yahoo.co.jp |
| 10 | — | — | itmedia.co.jp |
Numbers in parentheses are published citation counts. The periods and counting conditions differ between snapshots, so the counts aren't directly comparable. What matters is the cast and the movement.
### Stable cast, unstable order
Reddit, English Wikipedia, Ameblo, PR TIMES and note appear across all three snapshots. The order, though, moves a lot. Reddit was first in 2025, out of the top five (eighth) in April, and back to first in June. Ameblo rose to first in April and dropped to third in June.
Honestly, this is where I stopped thinking in terms of "optimizing for ChatGPT's citation ranking." Build tactics around a metric whose leader changes every three months and the premise is gone by the time you publish. Cover the stable cast, then track who's actually cited for your category rather than the overall order.
Volatility itself is the subject of [ChatGPT's Citation Sources Moved 86% in Four Days](/blog/en/chatgpt-citation-volatility-2026/).
> References:
> [Ahrefs analysis of AI search citation sources in Japan (Japanese) - Manamina](https://manamina.valuesccg.com/articles/4596)
> [Top 10 domains cited by AI search, April 2026 update (Japanese) - Ahrefs](https://ahrefs.com/blog/ja/brand-radar-top-10-cited-domains-2026-update/)
> [Top Japanese domains cited by AI, June 2026 (Japanese) - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
---
## 2. Every Industry Has a Different Staple
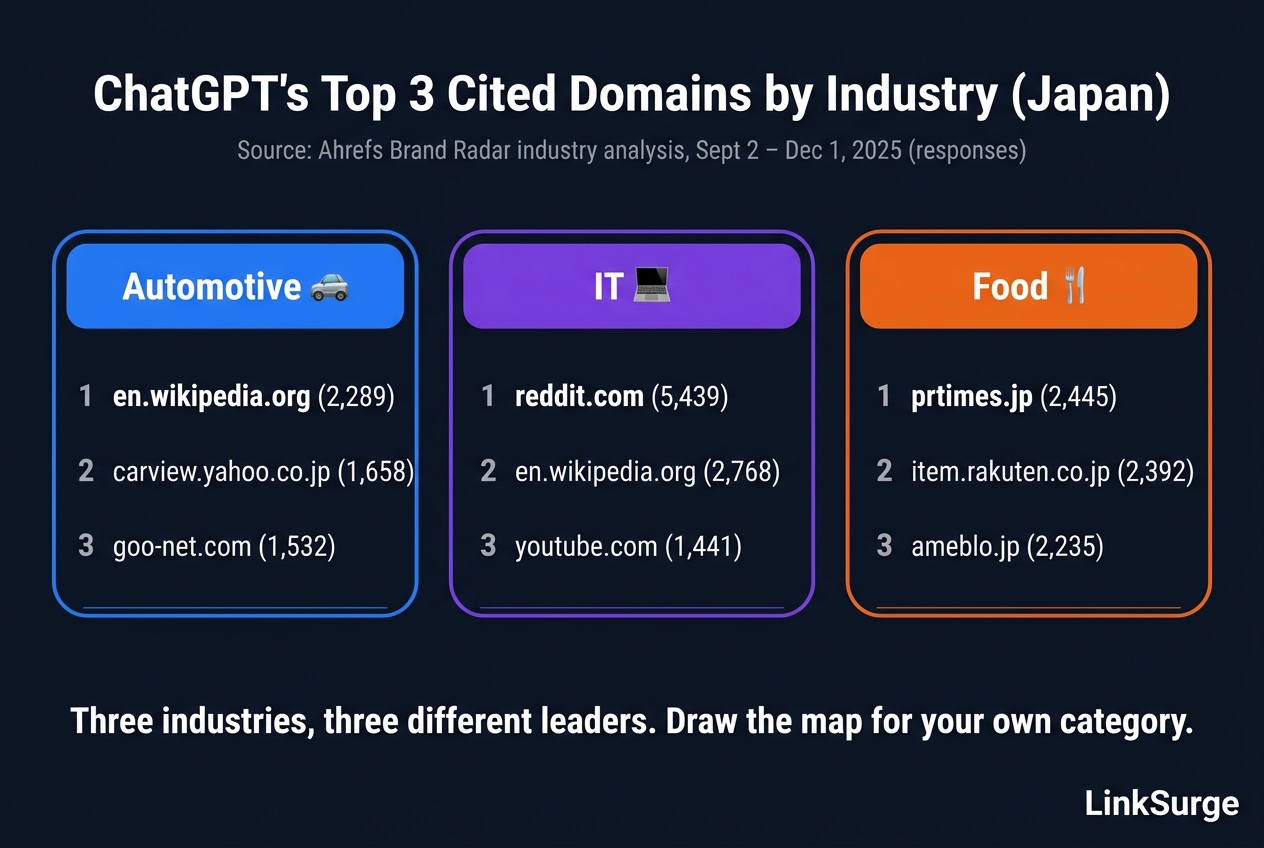
The overall ranking hides the industry differences. Ahrefs' industry analysis, published November 30, 2025, covered September 2 to December 1, 2025 across automotive, IT and food, for AI Overviews, AI Mode and ChatGPT. Here's the ChatGPT slice.
| Industry | #1 | #2 | #3 |
|:---|:---|:---|:---|
| Automotive | en.wikipedia.org (2,289) | carview.yahoo.co.jp (1,658) | goo-net.com (1,532) |
| IT | reddit.com (5,439) | en.wikipedia.org (2,768) | youtube.com (1,441) |
| Food | prtimes.jp (2,445) | item.rakuten.co.jp (2,392) | ameblo.jp (2,235) |
Here's what's interesting: three industries, three different leaders. IT is dominated by Reddit, where engineers argue in public. Food is led by press releases and marketplace product pages. Automotive is English Wikipedia plus two specialist car sites.
So neither "ChatGPT cites Reddit" nor "ChatGPT cites press releases" is accurate without naming the industry. The map for your category can only be drawn from queries in your category.
For contrast, AI Mode had YouTube first in all three industries, and AI Overviews had YouTube first in two of three. Google's engines and ChatGPT eat completely different diets.
> References:
> [2025 AI search trend analysis: industry citation patterns in Ahrefs Brand Radar (Japanese) - Ahrefs](https://ahrefs.com/blog/ja/2025-ahrefs-brand-radar-ai-search-analysis/)
---
## 3. Why English Wikipedia Outranks Japanese Wikipedia
This is the most overlooked point in Japanese ChatGPT optimization, and it carries a lesson for any non-English market. The questions are in Japanese, yet English Wikipedia sits near the top of the citation list and Japanese Wikipedia doesn't appear at all. The pattern holds in June, in April, and in the 2025 data.
Ahrefs' June commentary suggests ChatGPT expands the original query into English before searching. When I cross-checked that against other observational data, it held up. MJ Cachón's August 2026 study of 723 brand-prompt runs through OpenAI's API found English vocabulary in 8.9% of all sub-queries and in 27.3% for international brands.
If ChatGPT decomposes a Japanese question into English sub-queries, a site that only exists in Japanese can't be found by them. Conversely, a site with English summaries or an English edition gains an additional path into the answer for a Japanese question.
### What to do about it
- Add English summaries (even just headings and conclusions) to key pages and connect them to the local version with hreflang
- Write proper nouns in both the local script and English (company, product, technical terms)
- Check whether English Wikipedia has an entry for your brand or category. If not, don't wait for someone to write one; publish citable primary information (press releases, research) in English as well
The fan-out mechanics and the measured English mix are covered in [What Happened to ChatGPT's Query Fan-Out](/blog/en/chatgpt-query-fanout-hidden-2026/).
> References:
> [Top Japanese domains cited by AI, June 2026 (Japanese) - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
> [A study of query fan-out in ChatGPT using brand searches - MJ Cachón](https://www.mjcachon.com/en/blog/study-query-fan-out-chatgpt-brand/)
---
{{linksurge-card}}
## 4. About 67% of Citations Are Out of Reach. Focus on the 32.3% That Isn't
Once you have the map, separate what you can actually reach. Ahrefs' October 28, 2025 analysis classified ChatGPT's top 1,000 cited URLs from September 2025 by page type (English-language data).
| Page type | Share | Influenceable? |
|:---|---:|:---|
| Wikipedia | 29.7% | Not directly |
| Homepages and landing pages | 23.8% | Yes, if it's your own site |
| Educational content | 19.4% | Yes |
| App stores | 6.6% | Not directly |
| Reviews | 5.8% | Can be stimulated |
| News and media | 5.2% | Can be pitched |
| Blogs and articles | 1.9% | Yes |
| Other | 10.5% | — |
Ahrefs groups educational content, reviews, news and blogs (32.3%) as citations marketers can influence, and puts the group they can't directly influence at roughly two thirds (about 67%). The rows above are Ahrefs' categories transcribed as published; the buckets overlap, so they sum to more than 100% and the 67% is not a simple complement of the rows. Read this as "about a third is influenceable" rather than adding up individual rows.
I'd add one qualification. You can't influence other companies' homepages, but you can fix your own. With 16.6% of ChatGPT's sub-queries for brand prompts searching the brand's own domain by name, making your homepage and key pages clearly state who you are and what you offer is how you claim your slice of that 23.8%.
Translated to the Japanese market, the influenceable territory reads like this.
- **Educational content** — Your own blog, explainer articles on note, contributed pieces on ITmedia or Mynavi News
- **Reviews** — Rakuten and Amazon reviews, comparison sites, answers on Yahoo! Chiebukuro
- **News** — Press releases on PR TIMES, trade media coverage
- **Homepage** — The structure of your official site
For other markets, substitute the local equivalents: your press release wire, your dominant long-form platform, your Q&A site, your marketplaces.
> References:
> [ChatGPT's most cited pages - Ahrefs](https://ahrefs.com/blog/chatgpts-most-cited-pages)
---
## 5. How ChatGPT Differs from Other AI Engines: Only ChatGPT Mixes in English Sources
If you assume the same tactics work for ChatGPT, Google AI Overviews and Perplexity, you'll miss. Ahrefs' April 2026 data lists each engine's top three cited domains for Japanese queries.
| AI engine | #1 | #2 | #3 |
|:---|:---|:---|:---|
| ChatGPT | ameblo.jp | prtimes.jp | en.wikipedia.org |
| Google AI Mode | youtube.com | google.com | instagram.com |
| Google AI Overviews | youtube.com | ja.wikipedia.org | note.com |
| Perplexity | youtube.com | ja.wikipedia.org | note.com |
| Copilot | ja.wikipedia.org | note.com | ameblo.jp |
Google's engines and Perplexity center on YouTube and Japanese Wikipedia. Copilot leans on Japanese Wikipedia and note. Only ChatGPT puts a press release wire and English Wikipedia at the top. That difference presumably comes from differences in the indexes and retrieval pipelines behind each engine. For ChatGPT's three-layer index, see [Inside ChatGPT Search](/blog/en/chatgpt-search-architecture-2026/).
The practical conclusion is to log citation sources per engine. Being cited in ChatGPT but not in AI Overviews, or the reverse, is common. [LinkSurge](https://linksurge.jp/)'s GEO monitoring records, for each watch query, whether your brand is mentioned and which URLs are cited, separately for ChatGPT Search, Gemini, Google AI Overviews, Claude and Perplexity.
> References:
> [Top 10 domains cited by AI search, April 2026 update (Japanese) - Ahrefs](https://ahrefs.com/blog/ja/brand-radar-top-10-cited-domains-2026-update/)
---
## 6. How to Map Citation Sources for Your Own Category
Let's turn this into a procedure. Treat the overall ranking as background and draw your own map.
1. **Design 20 to 30 questions** — Shortlist-style queries first: "best [category]," "[A] vs [B]," "how to choose [category] for [use]"
2. **Run each in ChatGPT at least three times and log the cited URLs** — Answers vary run to run, so one pass is skewed
3. **Group cited URLs by domain into five buckets** — Reference sources (Wikipedia etc.), press releases, UGC and blogs (note, Ameblo, Q&A sites, Reddit), marketplaces and reviews, trade media
4. **Prioritize domains where competitors are cited and you aren't** — Restrict to the influenceable buckets: educational content, reviews, news, your own site
5. **Re-measure monthly with the same questions** — The order changes within three months, so keep the map current
Steps 2 and 5 are tedious by hand, which is why we register watch queries and let the logging run automatically. Per-engine records also reveal splits like "PR TIMES worked in ChatGPT, note worked in AI Overviews."
The full strategy is in [How to Get Cited by ChatGPT: The Complete Guide](/blog/en/chatgpt-geo-complete-guide-2026/). How to use press release wires, long-form platforms and Q&A sites specifically is in [Using Press Releases, note and Q&A Sites for ChatGPT Citations](/blog/en/chatgpt-press-release-note-ugc-2026/).
---
## Frequently Asked Questions
### Which domains does ChatGPT cite most for Japanese queries?
In Ahrefs' June 2026 data, the top five were Reddit, PR TIMES, Ameblo, English Wikipedia and note. In April 2026, Ameblo was first and Reddit was eighth, so the order changes within months. The stable cast across snapshots is Reddit, English Wikipedia, Ameblo, PR TIMES and note.
### Do ChatGPT's citation sources vary by industry?
Yes. In Ahrefs' September to December 2025 industry analysis for Japan, ChatGPT's top cited domain was Reddit for IT (5,439 responses), PR TIMES for food (2,445) and English Wikipedia for automotive (2,289). You need to check which domains are actually cited for questions in your own category rather than relying on the overall ranking.
### Why does ChatGPT cite English Wikipedia for Japanese questions?
Ahrefs suggests ChatGPT expands Japanese questions into English sub-queries internally. MJ Cachón's August 2026 study found English vocabulary in 27.3% of sub-queries for international brands. A site that exists only in the local language can't be found by those sub-queries, so English summaries of key pages and English spellings of proper nouns are the countermeasure.
### How much of ChatGPT's citations can a brand actually influence?
In Ahrefs' September 2025 English-language data, 32.3% of ChatGPT's top 1,000 cited URLs (educational content, reviews, news, blogs) were directly influenceable, and Ahrefs classifies the remaining roughly 67% (mainly Wikipedia 29.7%, homepages 23.8% and app stores 6.6%) as not. Since your own homepage is part of the 23.8% homepage share, improving your official site's structure is a tactic you can act on.
### Are ChatGPT's citation sources the same as Google AI Overviews'?
No. In Ahrefs' April 2026 data, ChatGPT's top sources were Ameblo, PR TIMES and English Wikipedia, while Google AI Overviews cited YouTube, Japanese Wikipedia and note, and AI Mode cited YouTube, Google and Instagram. Log citation sources per engine and plan tactics per engine.
---
## Conclusion: Don't Chase the Overall Ranking. Draw Your Category's Map
ChatGPT's citation sources in Japan form a two-layer structure of global reference sources and local publishing platforms. The cast is stable; the order reshuffles within three months. Each industry has a different staple, and only about a third of the top 1,000 citations sit within marketers' direct reach.
That's why the work isn't optimizing for the overall ranking. It's logging who gets cited for your category's questions, concentrating on the influenceable territory (educational content, reviews, news, your own site) and on English landing spots, and refreshing the map monthly.
LinkSurge's [GEO monitoring](https://linksurge.jp/geo) records cited URLs per watch query across five engines including ChatGPT Search, with competitor comparison. Use it for the first map and the monthly refresh.
---
## ChatGPT's Citation Sources Moved 86% in Four Days: What the August 2026 Reddit Collapse Revealed, and How to Design for Volatility
> URL: https://linksurge.jp/blog/en/chatgpt-citation-volatility-2026/
> Date: 2026-09-08 | Category: AIO | Author: Aro Ogata
> Tags: ChatGPT optimization, citation volatility, Reddit, Promptwatch, Petra Labs, GEO, monitoring, AI search optimization
## Key Takeaways: Sources Rotate Within Days. Don't Aim, Diversify and Measure
In mid-August 2026, Reddit links all but vanished from the ChatGPT answers I track for a fixed set of queries. My first thought was a measurement bug. Then several independent datasets showed the same drop. Here's what that episode teaches.
1. **Reddit's citation share fell 86% in four days** — Promptwatch measured Reddit's share of ChatGPT Search citations holding steady at 3.8% from July 18 to August 7, 2026, dropping into the 2% range on August 8, falling below 1% on August 14, and averaging 0.5% from August 14 to 17
2. **Social platforms fell together** — Petra Labs analyzed 126,500 ChatGPT responses from August 9 to 18 and found that around August 14, YouTube citations fell 88%, Reddit 81%, TikTok 72%, LinkedIn 36% and Facebook 28%
3. **Citations moved to company sites and documentation** — Observations from the same period show help centers and product documentation rising from 2% to 32%, large company sites from 4% to 18%, and app marketplaces from 2% to 17%, while small sites and blogs fell from 66% to 32%
4. **The recommended brands didn't change** — Petra Labs reported that ChatGPT kept recommending largely the same brands even as its citation sources were replaced, calling it "very rare and very curious." Citation sources and brand recommendations move on separate layers
5. **The cause is unconfirmed, and this wasn't the first swing** — Promptwatch says a change in source selection is the leading candidate but can't rule out a data-collection issue. Reddit's citation share had already halved between October 2025 and January 2026. Volatility is ChatGPT's normal state
Below, I trace the timeline and turn it into a design that assumes volatility.
---
## 1. What Happened in August 2026
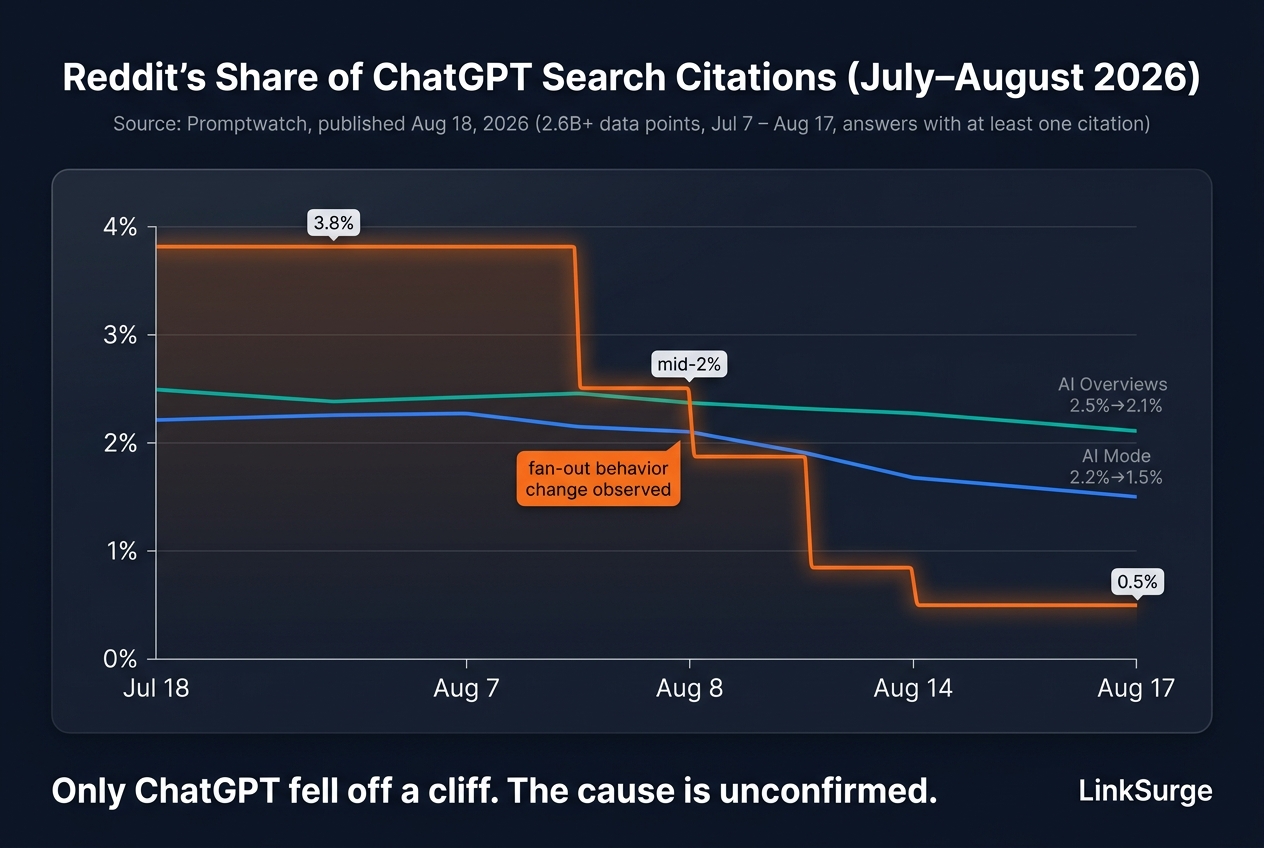
### Promptwatch's measurement
On August 18, 2026, Promptwatch published Reddit's citation share trend based on more than 2.6 billion data points collected from the actual UIs of ChatGPT, Google AI Overviews and Google AI Mode. The window was July 7 to August 17, counting only answers with at least one citation.
| Period | Reddit's share of ChatGPT Search citations |
|:---|---:|
| July 18 – August 7 | 3.8% (steady) |
| August 8 | Dropped from the 3% range to the mid-2% range |
| August 14 | Fell below 1% |
| August 14 – 17 average | 0.5% (86% below the prior period) |
Google's surfaces moved gently over the same window. AI Overviews went from 2.5% in early July to 2.1% in August, and AI Mode from 2.2% to 1.5% (Promptwatch's relative declines from unrounded values: 11.3% and 30.5%). Only ChatGPT fell off a cliff.
Promptwatch also notes that on August 8, "ChatGPT Search changed its query fan-out behavior." Read alongside Lily Ray's observation from the same period of the `site:` operator jumping from 0.3% to about 23% of fan-outs, the fan-out change and the citation change landed at the same time. The fan-out side is covered in [What Happened to ChatGPT's Query Fan-Out](/blog/en/chatgpt-query-fanout-hidden-2026/).
### Petra Labs' analysis
Petra Labs analyzed 126,500 ChatGPT responses from August 9 to 18, 2026 and reported a broad drop in social platform citations around August 14.
| Platform | Mid-August decline |
|:---|---:|
| YouTube | −88% |
| Reddit | −81% |
| TikTok | −72% |
| LinkedIn | −36% |
| Facebook | −28% |
This wasn't a Reddit story. Video, social networks and professional networks, in other words third-party posts as a whole, became far less likely to be cited.
> References:
> [Reddit Citations Are Dropping in ChatGPT - Promptwatch](https://promptwatch.com/data/reddit-citations-are-dropping-in-chatgpt)
> [Reddit's ChatGPT Search citations fell 86% in four days - Search Engine Land](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473)
> [ChatGPT slashes citations from Reddit, YouTube, and TikTok: Petra Labs - Adgully](https://www.adgully.com/post/19605/chatgpt-slashes-citations-from-reddit-youtube-and-tiktok-petra-labs)
---
## 2. Where the Citations Went
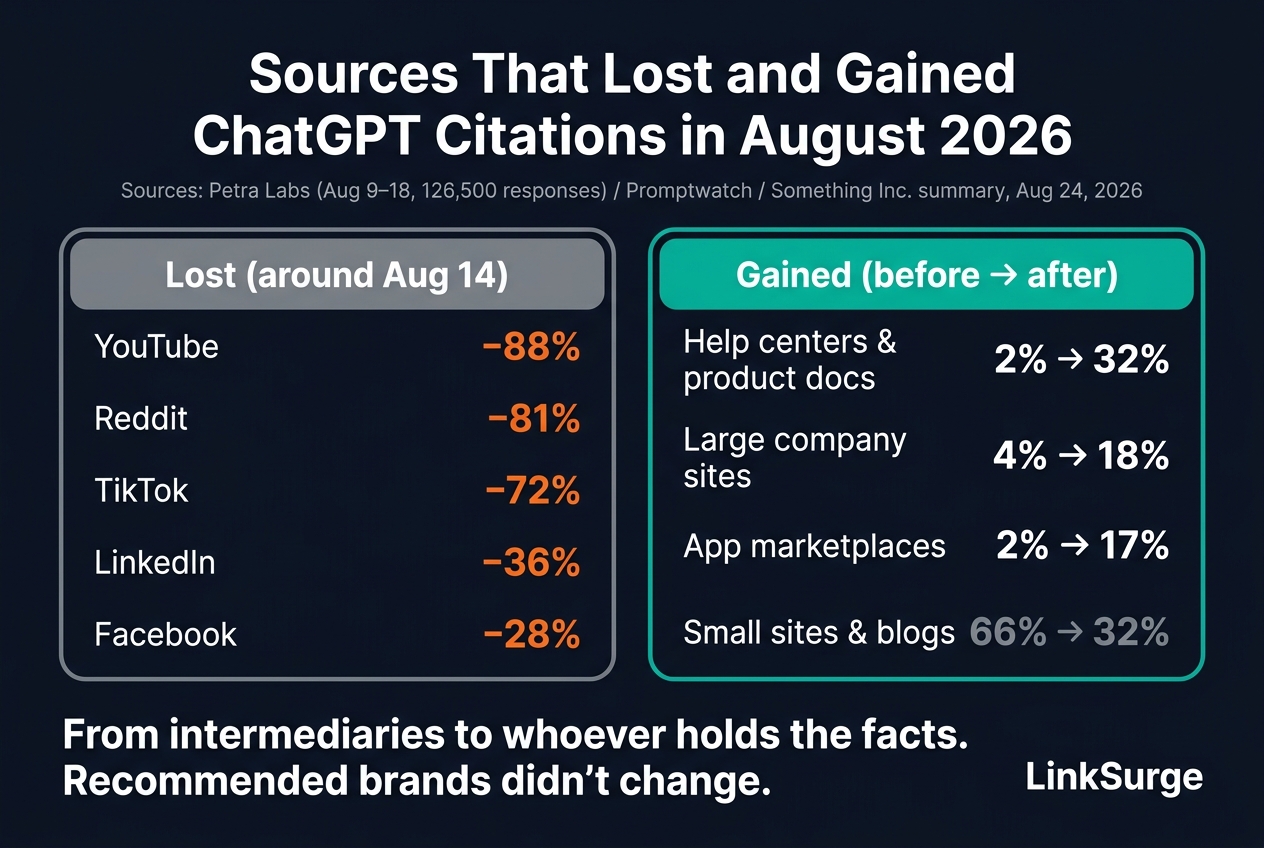
The lost share had to go somewhere. Something Inc.'s August 24, 2026 write-up, which combined Petra Labs and Promptwatch data with a model-version comparison, summarized the moves.
| Source type | Before | After |
|:---|---:|---:|
| Help centers and product documentation | 2% | 32% |
| Large company sites (Salesforce and similar) | 4% | 18% |
| App marketplaces | 2% | 17% |
| Small sites and blogs | 66% | 32% |
The table shows the four main categories only; the columns sum to 74% before and 99% after, with the remainder spread across categories not listed. Scope and period follow the sources above.
Petra Labs itself said much of the lost share went not to publishers or another social platform, but to company-owned websites. Inc.'s reporting adds that review sites gained ground.
My reading of these numbers: intermediaries lost, and whoever holds the facts won. For a question about a product's specs or pricing, the official help center is more accurate than a Reddit thread. If ChatGPT leaned toward that judgment, then documentation on your own site became a direct citation tactic.
### The recommended brands stayed the same
The other critical observation is Petra Labs' finding that ChatGPT kept recommending largely the same brands even though the cited sources were replaced. They called it "very rare and very curious."
What this shows is that a ChatGPT answer has two layers: which brands it recommends, and which URLs it cites as evidence. The second can move without the first. If you only track citation sources, you'll misread brand recommendation. Measurement has to log mentions and citations separately.
> References:
> [ChatGPT Citation Sources: Docs Replaced Reddit in August 2026 - Something Inc.](https://somethinginc.com/blog/chatgpt-citation-sources-docs-replaced-reddit/)
> ['Very rare and very curious': Reddit, YouTube and TikTok citations collapse, but ChatGPT still recommends the same brands - Mi3](https://www.mi-3.com.au/21-08-2026/very-rare-and-very-curious-chatgpt-guts-reddit-youtube-and-tiktok-citations-keeps)
> [ChatGPT Suddenly Cut Reddit Citations by 81 Percent - Inc.](https://www.inc.com/victoria-salves/chatgpt-suddenly-cut-reddit-citations-by-81-percent-new-report-found/91394126)
---
## 3. This Wasn't the First Swing
August was large, but ChatGPT's citation sources moving isn't unusual. Here's the observational record in order.
| When | Observation | Source |
|:---|:---|:---|
| May–Sept 2025 | Reddit was ChatGPT's top cited domain for Japanese queries (228,388 citations) | Ahrefs |
| Oct 2025 → Jan 2026 | Reddit's citation share halved from 2.02% to 1.01% | Conductor |
| Jan → Feb 2026 | Across 350,000+ citations on five engines, Reddit citations rose from 77,111 to 105,967 | Wellows |
| April 2026 | Reddit out of the top five (eighth) for Japanese queries; Ameblo first | Ahrefs |
| June 2026 | Reddit back to first from eighth | Ahrefs |
| Aug 8–17, 2026 | Reddit share fell from 3.8% to 0.5% | Promptwatch |
Halved, doubled, dropped out, back to first, collapsed, all within six months. The working assumption I use in practice: ChatGPT's citation sources are a different animal every quarter.
The cast and movement of Japanese citation sources is laid out in [The Domains ChatGPT Cites in Japan](/blog/en/chatgpt-citation-sources-japan-2026/).
> References:
> [Reddit AI Citation Decline - Conductor](https://www.conductor.com/academy/reddit-ai-citation-decline/)
> [Social Media in AI Citations (2026): Reddit & YouTube Dominate - Wellows](https://wellows.com/blog/social-media-ai-citations-report-2026/)
> [Top Japanese domains cited by AI, June 2026 (Japanese) - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
---
{{linksurge-card}}
## 4. What We Know About the Cause, and What We Don't
I'll be careful here. No confirmed cause for the August change has been published.
**What we know**
- The change came in two steps, August 8 and August 14 (Promptwatch)
- ChatGPT Search's fan-out behavior changed on August 8 (Promptwatch), and `site:` operator use surged in the same period (Lily Ray)
- Google AI Overviews and AI Mode saw no drop of the same magnitude (Promptwatch)
- Citations shifted to company sites, documentation and app stores (Petra Labs, Something Inc.)
**What we don't know**
- OpenAI's intent. OpenAI hasn't explained the change publicly
- Whether Reddit's crawler restrictions caused it. Some write-ups point to robots.txt changes; we haven't been able to verify that
- Whether measurement was partly at fault. Promptwatch itself says the figures should be treated as provisional because a data-collection issue can't be ruled out
With the cause unknown, both "wait for Reddit to come back" and "Reddit is finished" are unsupported. Switching to a design that doesn't depend on the cause is the reliable move.
---
## 5. Designing for Volatility
Let's turn this into practice. The principle: don't aim at one platform, diversify and record.
### Diversify across source types
Classify sources into five buckets and hold at least one tactic in each.
| Bucket | Examples | Tactic |
|:---|:---|:---|
| Your own site and documentation | Official site, help center, pricing and spec pages | Self-contained heading blocks; specs, pricing and comparisons as text |
| Press releases and news | Press release wires, trade media | Releases with study name, sample size, period and figures in the body |
| Long-form first-hand accounts | Long-form platforms, your own blog | Records of actually using and testing, at length |
| UGC and Q&A | Q&A sites, Reddit, reviews | Stimulate, don't fabricate. Ask for answers and reviews |
| Video | YouTube | Key points as text in descriptions and chapters |
August boosted row one and cut rows four and five. But in June, Reddit in row four was first. Since you can't know which row wins next, holding a thin position in every row is the hedge.
### Make your documentation the primary source of facts
Help centers and product documentation going from 2% to 32% says that facts held by the party itself are now direct citation candidates. Put pricing, specs, scope and changelogs in text rather than images, with each heading self-contained.
### Log mentions and citations separately, weekly
Since recommended brands can hold while sources rotate, you need two tracks. For 20 to 30 category questions, record weekly (1) whether your brand was mentioned in the answer and (2) which domains were cited. Answers vary run to run, so log multiple runs. [LinkSurge](https://linksurge.jp/)'s GEO monitoring records mention presence, position, cited URLs and competitor comparison across ChatGPT Search, Gemini, Google AI Overviews, Claude and Perplexity. The August collapse showed up in our own tracking precisely because that scheduled logging was already running.
For the full strategy, see [How to Get Cited by ChatGPT: The Complete Guide](/blog/en/chatgpt-geo-complete-guide-2026/). For UGC platforms, see [UGC and AI Search Citations](/blog/en/ugc-ai-search-brand-mentions-2026/).
---
## Frequently Asked Questions
### How much did ChatGPT's Reddit citations fall in August 2026?
Promptwatch measured Reddit's share of ChatGPT Search citations at 3.8% from July 18 to August 7, 2026, falling to an average of 0.5% from August 14 to 17, an 86% drop. Petra Labs' analysis of 126,500 responses found Reddit down 81%, YouTube down 88% and TikTok down 72% around August 14.
### Where did ChatGPT's citations go?
Analysis combining Petra Labs and Promptwatch data shows help centers and product documentation rising from 2% to 32%, large company sites from 4% to 18%, and app marketplaces from 2% to 17%, while small sites and blogs fell from 66% to 32%. Citations moved from third-party posts to the sites of the parties that hold the facts.
### What caused the drop in Reddit citations?
It's unconfirmed. Promptwatch says a change in ChatGPT's source selection is the leading candidate but a data-collection issue can't be ruled out. ChatGPT Search's fan-out behavior was observed to change on August 8, but OpenAI hasn't explained it. A design that doesn't depend on the cause, diversified sources plus scheduled measurement, is the recommendation.
### If citation sources change, do ChatGPT's brand recommendations change too?
Not necessarily. Petra Labs reported that ChatGPT recommended largely the same brands in August 2026 even as its citation sources were replaced. Because brand recommendation and cited URLs move on separate layers, measurement has to log mention presence and cited sources separately.
### If volatility is this high, is ChatGPT optimization pointless?
No, but betting on a single platform is. Spread across five buckets (your own site and documentation, press releases, long-form first-hand accounts, UGC, video), make your documentation the primary source of facts, and log mention rate and cited domains weekly. Built that way, the next shift won't move your strategy.
---
## Conclusion: The Next Shift Is Coming. Don't Aim, Diversify and Record
August 2026 showed that ChatGPT's citation sources can rotate within days, that citations can move from third-party posts to the sites of the parties themselves, and that sources can change while recommended brands don't. The cause remains unconfirmed.
That's exactly why tactics shouldn't aim at a particular platform. Spread across five buckets, make your own documentation the primary source of facts, and log mentions and citations separately every week. In a volatile environment, being the first to notice the next shift and the first to adjust is the advantage.
LinkSurge's [GEO monitoring](https://linksurge.jp/geo) records mentions and cited sources on a schedule across five engines including ChatGPT Search. Use the [AI Ready audit](https://linksurge.jp/ai-ready) to check the structure of your own documentation.
---
## How to Get Cited by ChatGPT: The Complete 2026 Guide to Search Architecture, Citation Sources, Tactics and Measurement
> URL: https://linksurge.jp/blog/en/chatgpt-geo-complete-guide-2026/
> Date: 2026-09-08 | Category: AIO | Author: Aro Ogata
> Tags: ChatGPT optimization, ChatGPT search, GEO, LLMO, AI citations, OAI-SearchBot, query fan-out, AI search optimization
## Key Takeaways: Five Things You Need to Accept Before Optimizing for ChatGPT
Every time a client asks me about ChatGPT visibility, I start with the same request: put the Google playbook down for a minute. ChatGPT search has no rankings page. It splits your question into several internal searches, pulls dozens of pages, reads them, and cites two or three. This article is the hub of our ChatGPT optimization series. It lays out the whole picture, from architecture to measurement, based on OpenAI's official documentation and primary data published in 2026 by Ahrefs, Peec AI, Profound and Lily Ray. Here's what matters.
1. **ChatGPT search runs on three index layers** — At launch in October 2024, Bing was the main search backend. By September 2026, Peec AI's analysis shows an experiment preferring OpenAI's own index (which Peec AI calls "Labrador"; OpenAI hasn't confirmed the name) over external search results in 8 percent of chats at the time of observation, with such experiments reportedly ranging from single digits up to 20 percent. You need to be in Bing, in Google, and crawlable by OAI-SearchBot, all at once
2. **One question becomes 7+ internal searches on average** — Lily Ray's August 2026 observations show the share of prompts handled with a single query fell from 94% to 43.5%, while fan-outs per prompt rose from 2.17 to 7.61. And during the GPT-5.3 to 5.4 period in mid-2026, those sub-queries stopped appearing in the conversation interface
3. **Citation sources are volatile** — In August 2026, Reddit's share of ChatGPT Search citations fell 86.4% in four days. Depending on any single platform is a risk. Strategy has to assume rotation and build in monitoring
4. **Shopping is a separate game with its own rules** — Profound's July 2026 analysis found 87.3% of product information comes from web crawling and 12.7% from merchant feeds, and top-ranked product cards have more than twice the median review count of cards ranked fourth or lower. Instant Checkout was retired in March 2026, so discovery happens in ChatGPT and purchase happens on your site
5. **The work has four layers: foundation, structure, third-party mentions, measurement** — Allow OAI-SearchBot and render server-side, build answer-extractable heading blocks, earn mentions on the sources ChatGPT actually cites in your market, and record mention rate and cited domains weekly. Do them in that order
Below, I walk through each layer and point to the deeper articles in the series.
---
## 1. How ChatGPT Search Actually Works
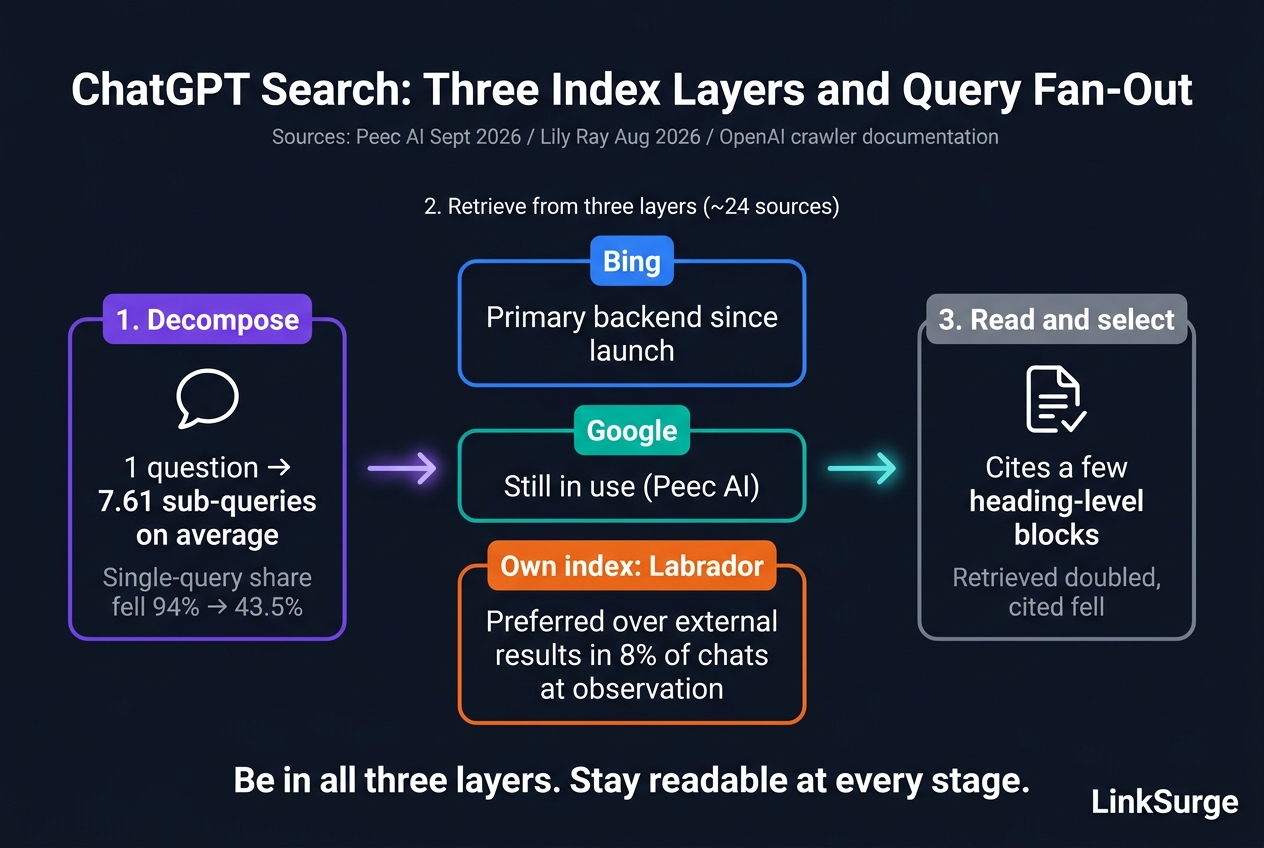
Honestly, the internals of ChatGPT search have changed almost monthly in 2026. Still, three parts of the skeleton are confirmable from public information.
### Three index layers
OpenAI launched ChatGPT search on October 31, 2024, and the initial architecture leaned on Microsoft Bing as its primary search provider. Peec AI's analysis published September 4, 2026, built on server-sent event metadata collected from May 21 to July 21, OpenAI job postings, Google antitrust testimony, and crawl experiments on their own sites, reports that OpenAI has built a family of vertical indexes that Peec AI refers to as "Labrador" (OpenAI hasn't confirmed the name). It covers general web, PDFs, YouTube, news (bucketed by 1 day, 7 days, older), arXiv, Wikipedia, local, finance, legal, medical, shopping and images. An experiment named `prefer-index-over-serp-v3` was applied to 8 percent of chats at the time of observation (mid-August 2026), and Peec AI describes such experiments as ranging from single digits up to 20 percent. The same analysis states plainly that "Google and Microsoft still matter" and that the system "is still being rebuilt week to week."
The practical conclusion is simple. Be indexed in Bing. Be indexed in Google. Be crawlable by OAI-SearchBot. Being in one of the three is not enough.
### Query fan-out
ChatGPT doesn't search your question verbatim. It decomposes it into sub-queries, runs each, and synthesizes the results. The ChatGPT-specific twist in 2026 is that a mid-year model update multiplied the number of fan-outs while simultaneously hiding them from the browser. Full details in [What Happened to ChatGPT's Query Fan-Out](/blog/en/chatgpt-query-fanout-hidden-2026/).
### Retrieved is not cited
In Lily Ray's data, sources retrieved per response roughly doubled from about 12 to about 24 after the update, while the number actually cited moved the other way. Being read by ChatGPT and being cited by ChatGPT are two different outcomes. Treat the foundation (getting read) and the structure (getting picked) as separate workstreams.
For a deeper look at the architecture, see [Inside ChatGPT Search: Bing, Google and the "Labrador" Index](/blog/en/chatgpt-search-architecture-2026/).
> References:
> [ChatGPT built its own search index - Peec AI](https://peec.ai/blog/chatgpt-built-its-own-search-index)
> [What We Can Learn from Evolving ChatGPT Fan-Out Queries - Lily Ray](https://lilyraynyc.substack.com/p/what-we-can-learn-from-evolving-chatgpt)
> [ChatGPT search officially launches - Search Engine Land](https://searchengineland.com/chatgpt-search-officially-launches-447919)
---
## 2. Foundation: Let OpenAI's Crawlers Read You
If this layer is broken, nothing above it matters. OpenAI documents four bots.
| Bot | Purpose | robots.txt behavior |
|:---|:---|:---|
| OAI-SearchBot | Crawls to surface your site in ChatGPT search results | Allow it to appear in search answers. Disallowed sites may still show as navigational links but not in search answers |
| GPTBot | May use content to train foundation models | Disallow to opt out of training. Independent of search visibility |
| ChatGPT-User | Fetches pages when a user asks ChatGPT or a custom GPT | User-initiated, so robots.txt rules may not apply |
| OAI-AdsBot | Verifies ad landing pages for safety and relevance | Only relevant if you advertise |
The key point: "don't train on me, but do show me in search" is a valid configuration. Disallow GPTBot, allow OAI-SearchBot. OpenAI says robots.txt changes take about 24 hours to propagate, and publishes IP ranges for each bot as JSON.
### Server-side rendering is a prerequisite
OpenAI's documentation describes what each crawler does, how robots.txt applies and which IP ranges it uses, but it doesn't specify whether the crawlers execute JavaScript. That leaves content that only exists after client-side rendering at risk of not being read at fetch time. Server-side rendering or pre-rendering puts the content in the initial HTML response, which is the safe configuration. Write numbers and tables as text rather than baking them into images.
For the emerging practice of serving machine-readable Markdown to AI agents, see [Cloudflare Markdown for Agents and the AI-Ready Web](/blog/en/cloudflare-markdown-for-agents-2026/).
> References:
> [Overview of OpenAI Crawlers - OpenAI](https://developers.openai.com/api/docs/bots)
---
## 3. Structure: Make Your Content Extractable
Once you're readable, the next job is getting picked out of the dozens of pages retrieved. This is an area we research ourselves, so I'll separate what we've confirmed from what we haven't.
### What's confirmed
When we analyzed 277 real Google AI Overviews citations, 69.3% came from heading blocks other than the lead paragraph. That study measured Google AI Overviews, not ChatGPT Search. But since ChatGPT also reads retrieved page content and picks passages to cite, we expect a self-contained 40 to 60 word answer directly under each heading to work in the same direction, and we'll test it on ChatGPT in this series' measurement article. Details in [Where Does AI Search Actually Quote From?](/blog/en/ai-citation-block-position-research-2026/).
MJ Cachón's August 2026 study of 723 API runs on brand prompts found 23.8% of sub-queries contained exact-match quotes and 19.6% contained a year. Spelling out proper nouns and years in headings and body text gives those sub-queries something to land on.
### What's not confirmed
FAQ schema and other structured data have not been shown to increase ChatGPT citations. In our controlled test, ChatGPT's change after adding schema (+2.2%) was indistinguishable from noise. Implement structured data when you have a search-engine goal such as rich results, not as a ChatGPT lever. The full story is in [Does FAQ Schema Really Get You Cited 3.2x More?](/blog/en/faq-schema-ai-citation-myth-2026/).
For heading design and atomic answers, see our [beginner's guide to LLMO](/blog/en/llmo-guide-beginners-2026/).
> References:
> [A study of query fan-out in ChatGPT using brand searches - MJ Cachón](https://www.mjcachon.com/en/blog/study-query-fan-out-chatgpt-brand/)
---
## 4. Third-Party Mentions: Match the Sources ChatGPT Cites in Your Market
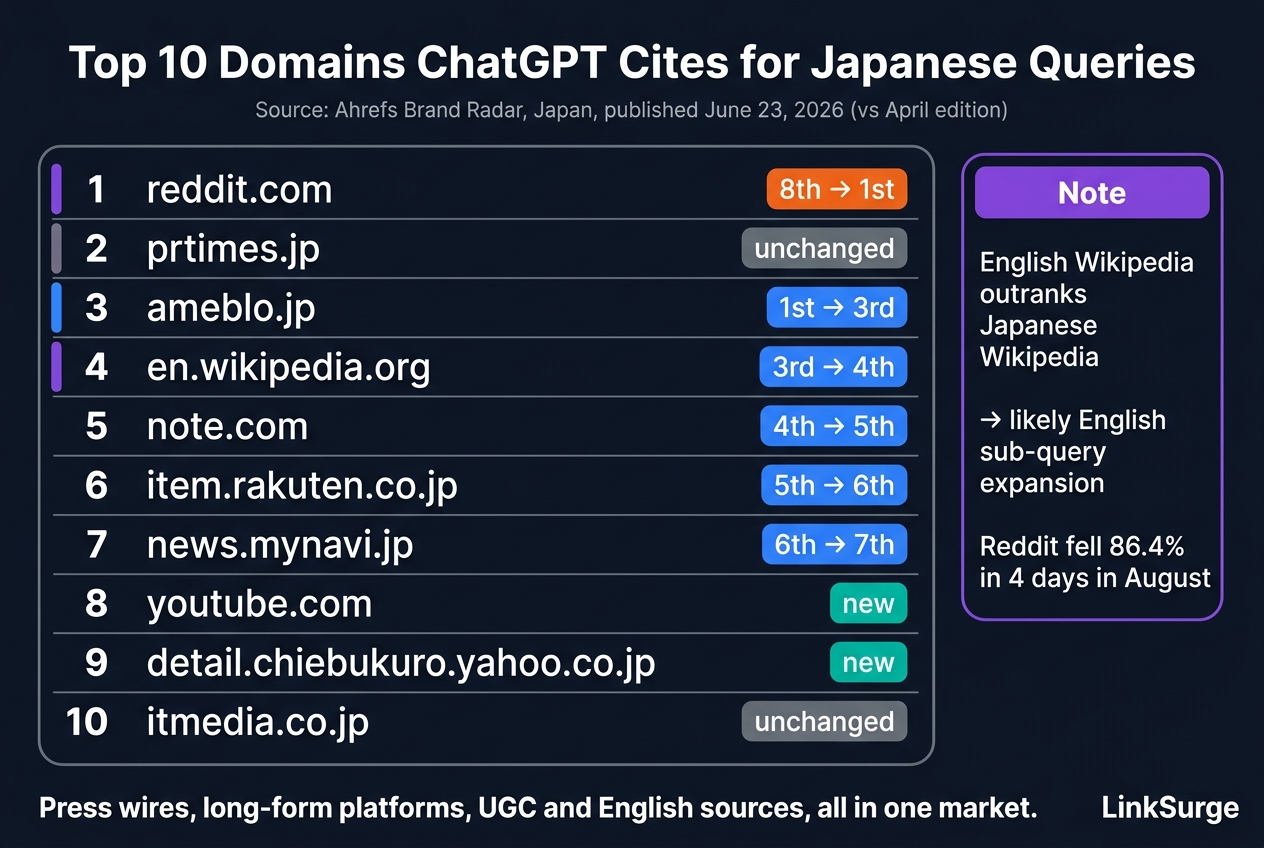
This is where market matters most. Here's what the data looks like for Japan, the market we track most closely, and why the lesson generalizes.
Ahrefs' June 23, 2026 data for Japanese queries ranked the domains ChatGPT cites as follows.
| Rank | Domain | Change from April |
|:---|:---|:---|
| 1 | reddit.com | Up from 8th |
| 2 | prtimes.jp (press release wire) | Unchanged |
| 3 | ameblo.jp (blog platform) | Down from 1st |
| 4 | en.wikipedia.org | Down from 3rd |
| 5 | note.com (long-form platform) | Down from 4th |
| 6 | item.rakuten.co.jp (marketplace) | Down from 5th |
| 7 | news.mynavi.jp | Down from 6th |
| 8 | youtube.com | New |
| 9 | detail.chiebukuro.yahoo.co.jp (Q&A) | New |
| 10 | itmedia.co.jp | Unchanged |
What struck me: English Wikipedia outranks Japanese Wikipedia for Japanese queries. Ahrefs' explanation is that ChatGPT likely expands Japanese questions into English sub-queries internally. MJ Cachón's study found 27.3% of sub-queries for international brands contained English vocabulary. A site that exists only in the local language is invisible to those English sub-queries.
The generalizable lesson is that ChatGPT's citation mix in any market is a blend of a few global UGC and reference sources, plus the local press-release wire, local long-form platforms, marketplaces and Q&A sites. Find the equivalent list for your market and treat it as your outreach map.
### Reddit and the volatility problem
Reddit jumped to first place in June and then, in August, Promptwatch data reported by Search Engine Land showed its share of ChatGPT Search citations falling 86.4% in four days (cause unconfirmed). Petra Labs, analyzing 126,500 ChatGPT responses from August 9 to 18, saw YouTube, Reddit and TikTok citations drop 70 to 90 percent in the same window. UGC platforms can matter a lot, and they can vanish overnight. Don't build a strategy around one of them. The August shift and how to design for it are in [ChatGPT's Citation Sources Moved 86% in Four Days](/blog/en/chatgpt-citation-volatility-2026/); the time-series and industry structure of citation sources is in [The Domains ChatGPT Cites in Japan](/blog/en/chatgpt-citation-sources-japan-2026/); and the press-wire, long-form and Q&A playbook is in [Using Press Releases, note and Q&A Sites for ChatGPT Citations](/blog/en/chatgpt-press-release-note-ugc-2026/). Our guide to [UGC and AI search citations](/blog/en/ugc-ai-search-brand-mentions-2026/) covers how to stimulate mentions across platforms.
### Brand consistency and `site:` searches
Lily Ray's data shows the share of fan-outs using the `site:` operator jumped from 0.3% to about 23% after the model update. In MJ Cachón's study, 69.8% of sub-queries were open searches, but of the 30.2% using `site:`, 55.1% targeted the brand's own domain, meaning 16.6% of all sub-queries searched the official site by name. For brand prompts, a meaningful share of searches goes straight to your own domain. Whether your site clearly states which page is official and what you offer now matters directly. See [Entity Authority in AI Search](/blog/en/entity-authority-ai-search-2026/).
> References:
> [Top Japanese domains cited by AI, June 2026 (Japanese) - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
> [Top 10 domains cited by AI search, April 2026 update (Japanese) - Ahrefs](https://ahrefs.com/blog/ja/brand-radar-top-10-cited-domains-2026-update/)
> [Reddit's ChatGPT Search citations fell 86% in four days - Search Engine Land](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473)
> [ChatGPT slashes citations from Reddit, YouTube, and TikTok: Petra Labs - Adgully](https://www.adgully.com/post/19605/chatgpt-slashes-citations-from-reddit-youtube-and-tiktok-petra-labs)
---
{{linksurge-card}}
## 5. Shopping and Branded Queries: What Gets a Product Picked
If you sell products, ChatGPT Shopping needs its own plan. Profound's July 2026 analysis (201,137 prompts and 812,190 product cards from June 18 to 25) found 87.3% of product information came from web crawling and 12.7% from merchant-supplied feeds. Cards ranked first had a median of 787 reviews versus 352 for cards ranked fourth or lower.
Instant Checkout, launched in September 2025, was retired in March 2026 according to reporting by CNBC and Forbes, and ChatGPT shifted back to "discover in the chat, buy on the merchant's site." What survived as ranking conditions: accurate product pages and third-party validation like review volume.
Rakuten's 2026 survey found 54.3% of Gen Z use generative AI when shopping yet still trust search engines most. Read together, that means you need to appear both in the AI shortlist and in the verification search that follows. See [54% of Gen Z Ask AI Before They Buy](/blog/en/gen-z-ai-shopping-search-trust-2026/).
> References:
> [Breaking down how ChatGPT Shopping works behind the user experience - Profound](https://www.tryprofound.com/blog/chatgpt-shopping-end-to-end-breakdown)
> [OpenAI revamps shopping experience in ChatGPT after struggling with Instant Checkout offering - CNBC](https://www.cnbc.com/2026/03/24/openai-revamps-shopping-experience-in-chatgpt-after-instant-checkout.html)
> [Why OpenAI's Checkout Retreat Spells Trouble For Its Commerce Strategy - Forbes](https://www.forbes.com/sites/jasongoldberg/2026/03/10/why-openais-checkout-retreat-spells-trouble-for-its-commerce-strategy/)
> [Rakuten Announces Results of Gen Z Generative AI Usage Survey (Japanese) - Rakuten Group](https://corp.rakuten.co.jp/news/press/2026/0904_01.html)
---
## 6. Measurement: Replace Invisible Fan-Outs with Visible Mention Rates
With fan-outs hidden, you can no longer watch which sub-query picked you up. What you can watch is the outcome: for a set of questions in your category, how often ChatGPT mentions or cites you, and who else it cites.
### Three weekly metrics
1. **Mention rate** — Across 20 to 30 category questions, the share of answers that include your brand name or URL
2. **Cited domains** — URLs cited in the answers, grouped by domain and classified as review sites, press releases, UGC, or competitors
3. **Competitor gap** — The same questions, competitor mention rate, and the difference
ChatGPT answers vary run to run, so a single check misleads. [LinkSurge](https://linksurge.jp/)'s GEO monitoring registers watch queries across ChatGPT Search, Gemini, Google AI Overviews, Claude and Perplexity, and logs mention presence, position, cited URLs and competitor comparison. We use the same setup to measure this series, and we'll publish the results in follow-up articles.
If you want to see the fan-outs themselves, OpenAI's Responses API still returns them in the `action.queries` array. Steps are in [What Happened to ChatGPT's Query Fan-Out](/blog/en/chatgpt-query-fanout-hidden-2026/).
---
## 7. A 30-Day Starting Order
Here's the sequence, week by week.
| Week | Do | Verify with |
|:---|:---|:---|
| 1 | Allow OAI-SearchBot in robots.txt and decide your GPTBot policy. Confirm key pages have their content in the initial HTML. Check Bing and Google indexation | curl the HTML and look for body text. Bing Webmaster Tools and Search Console |
| 2 | Design 20 to 30 category questions and take a baseline of ChatGPT mention rate and cited domains | GEO monitoring or manual logging |
| 3 | Add 40 to 60 word answer blocks under each key heading. Spell out proper nouns and years. Consider English summary pages | Re-run the citation log |
| 4 | Work the press-release wires, long-form platforms and review sites where competitors are cited and you aren't | Track cited-domain changes weekly |
Each article in this series expands one row of that table.
---
## Frequently Asked Questions
### Where should I start if I want ChatGPT to cite my site?
Allow OAI-SearchBot in robots.txt and confirm your key pages' content is present in the server-rendered initial HTML. OpenAI's documentation states that sites disallowing OAI-SearchBot won't appear in search answers. Then confirm indexation in both Bing and Google. Only once that foundation is in place do content structure and third-party mentions pay off.
### Does ChatGPT use Bing or Google?
Both, plus its own index. Peec AI's September 2026 analysis identified an experiment called prefer-index-over-serp-v3 that prefers OpenAI's own index (which Peec AI calls "Labrador"; OpenAI hasn't confirmed the name) over external results in 8 percent of chats at the time of observation, while also reporting that Google and Microsoft search remain in use. You need to be present in all three.
### Why do English sources get cited for non-English queries?
Ahrefs' June 2026 data for Japan shows English Wikipedia and Reddit among ChatGPT's top cited domains, and Ahrefs suggests ChatGPT expands non-English questions into English sub-queries internally. MJ Cachón's study found 27.3% of sub-queries for international brands contained English vocabulary. A site that only exists in the local language can't be found by those sub-queries.
### Will FAQ schema or structured data get me cited by ChatGPT?
Not in our testing. After adding structured data, the change in ChatGPT citations was indistinguishable from noise. Implement schema for search-engine goals like rich results, not as a ChatGPT tactic. What does show an effect is self-contained answer blocks under each heading and explicit proper nouns and years.
### How do I measure my ChatGPT citation rate?
Design 20 to 30 questions for your category and log, weekly, the share of ChatGPT answers that mention your brand or URL, the domains cited, and competitor mention rates. Because answers vary between runs, log multiple runs. A tool like LinkSurge's GEO monitoring that registers watch queries across several AI platforms and records mentions and citations automatically keeps you from being misled by volatility.
---
## Conclusion: In a World Without Rankings, Be Read and Then Be Chosen
ChatGPT has no rankings page. It has dozens of pages retrieved from three index layers, and a handful of citations chosen from them. To be chosen, first be readable, then build heading-level answers, then earn mentions on the sources that actually get cited in your market, and finally record mention rate and cited domains on a schedule. Those four layers, in that order, are the shortest path as of September 2026.
Citation sources rotate within days and the index is rebuilt week to week. That's exactly why this can't be a one-time project. Build the measurement loop and adjust. The rest of this series goes deep on architecture, fan-out, citation sources, shopping and measurement design.
LinkSurge's [GEO monitoring](https://linksurge.jp/geo) records your brand's mentions and cited sources across five AI platforms including ChatGPT Search, with competitor comparison built in. Use the [AI Ready audit](https://linksurge.jp/ai-ready) to check the foundation.
---
## Using Press Releases, note and Q&A Sites for ChatGPT Citations: Why Up to 42.8% of ChatGPT Answers Cite a Press Release in Japan, and What Gets a Release Cited
> URL: https://linksurge.jp/blog/en/chatgpt-press-release-note-ugc-2026/
> Date: 2026-09-08 | Category: AIO | Author: Aro Ogata
> Tags: ChatGPT optimization, PR TIMES, press releases, note, Q&A sites, UGC, GEO, AI search optimization
## Key Takeaways: In Japan, ChatGPT Optimization Runs on Three Channels: Press Releases, Long-Form First-Hand Accounts, and Q&A
Import a Western ChatGPT playbook into Japan and one thing always falls through the gap: PR TIMES, the country's dominant press release wire. Japan is the market we track most closely, and the mechanics here, a press wire the AI trusts, a long-form platform full of first-hand accounts, a giant Q&A site, have equivalents in most markets. Here's what I confirmed from Ahrefs' Japan data and two 2026 studies of press release citations.
1. **Up to 42.84% of ChatGPT answers cite a press release** — Wallabee (Optyino.ai) analyzed 81,895 answers across nine AI models from April 21 to July 8, 2026. 42.84% of GPT-5 mini answers and 27.33% of GPT-5.2 answers cited at least one press release. Perplexity: 21.45%. Claude: 6.00%. Copilot: 2.90%
2. **60.5% of cited press releases are on PR TIMES** — Of 9,381 press release citation URLs in the same study, 60.5% were on the PR TIMES domain. In Ahrefs' Japan data, PR TIMES was ChatGPT's second most cited domain in both April and June 2026, and first for the food industry
3. **Whether a release gets cited depends on type-specific elements** — Sighted (Tech Knowledge Base) ran 1,056 tests through OpenAI's API in May and June 2026. Research-report releases needed five elements in the text: study name, the organization that ran it, sample size, period and percentage figures. Product releases needed product name, launch date, price and location. For product releases, mid-sized companies were cited 78% of the time versus 30% for major chains
4. **Query wording decides between the press release and the official site** — The same study found questions containing "survey," "ranking" or "limited edition" favored PR TIMES, while "recommended," "adoption status" or "new product" favored the official site. You need both in shape
5. **note, Ameblo, Yahoo! Chiebukuro and Rakuten each play a different role** — note and Ameblo hold long-form first-hand accounts, Chiebukuro holds Q&A, Rakuten holds product facts. Stimulate UGC rather than fabricate it, and never lean on a single platform, as the August 2026 citation shift showed
Below, I cover press releases, the release-versus-official-site split, note and Ameblo, then Q&A, marketplaces and reviews, ending with a 30-day plan.
---
## 1. How Often ChatGPT Cites Press Releases
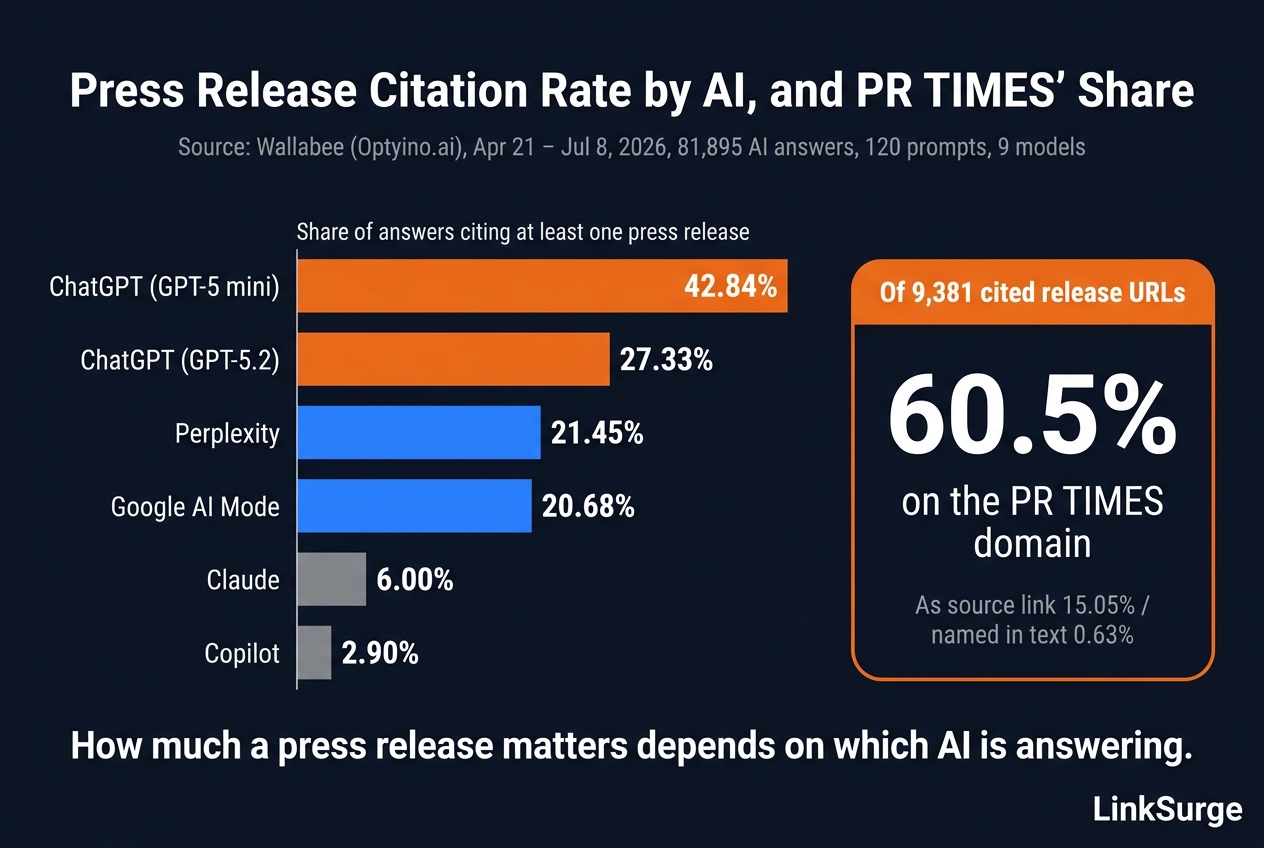
First, the scale. In July 2026, Wallabee published an analysis of 81,895 AI answers collected on its AI search monitoring platform Optyino.ai between April 21 and July 8, 2026, covering 120 prompts in finance, housing, appliances and B2B services across nine AI models.
| AI model | Share of answers citing at least one press release |
|:---|---:|
| ChatGPT (GPT-5 mini) | 42.84% |
| ChatGPT (GPT-5.2) | 27.33% |
| Perplexity | 21.45% |
| Google AI Mode | 20.68% |
| Claude | 6.00% |
| Copilot | 2.90% |
What surprised me is the spread between models. Within ChatGPT alone, GPT-5 mini and GPT-5.2 differ by more than 15 points, and the gap to Copilot is roughly 15x. How much a press release matters depends entirely on which AI is answering.
The way releases get cited matters too. Press releases appeared as source links in 15.05% of answers but were mentioned in the answer text itself in only 0.63%. They're used as footnote-style evidence far more than as named sources in the prose.
And of the 9,381 press release URLs cited, 60.5% were on PR TIMES. That matches Ahrefs' Japan data, where PR TIMES held second place among ChatGPT's cited domains in both the April and June 2026 editions and was first for the food industry (2,445 responses) in the September to December 2025 industry analysis.
For the full picture of citation sources in Japan, see [The Domains ChatGPT Cites in Japan](/blog/en/chatgpt-citation-sources-japan-2026/).
> References:
> [How often does generative AI cite press releases? Optyino.ai analyzes 81,895 AI answers (Japanese) - Wallabee via PR TIMES](https://news.infoseek.co.jp/article/prtimes_000000018_000124655/)
> [Press releases appear in about 43% of ChatGPT answers (Japanese) - Manamina](https://manamina.valuesccg.com/articles/5165)
> [Top Japanese domains cited by AI, June 2026 (Japanese) - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
> [2025 AI search trend analysis: industry citation patterns (Japanese) - Ahrefs](https://ahrefs.com/blog/ja/2025-ahrefs-brand-radar-ai-search-analysis/)
---
## 2. What Gets a Press Release Cited
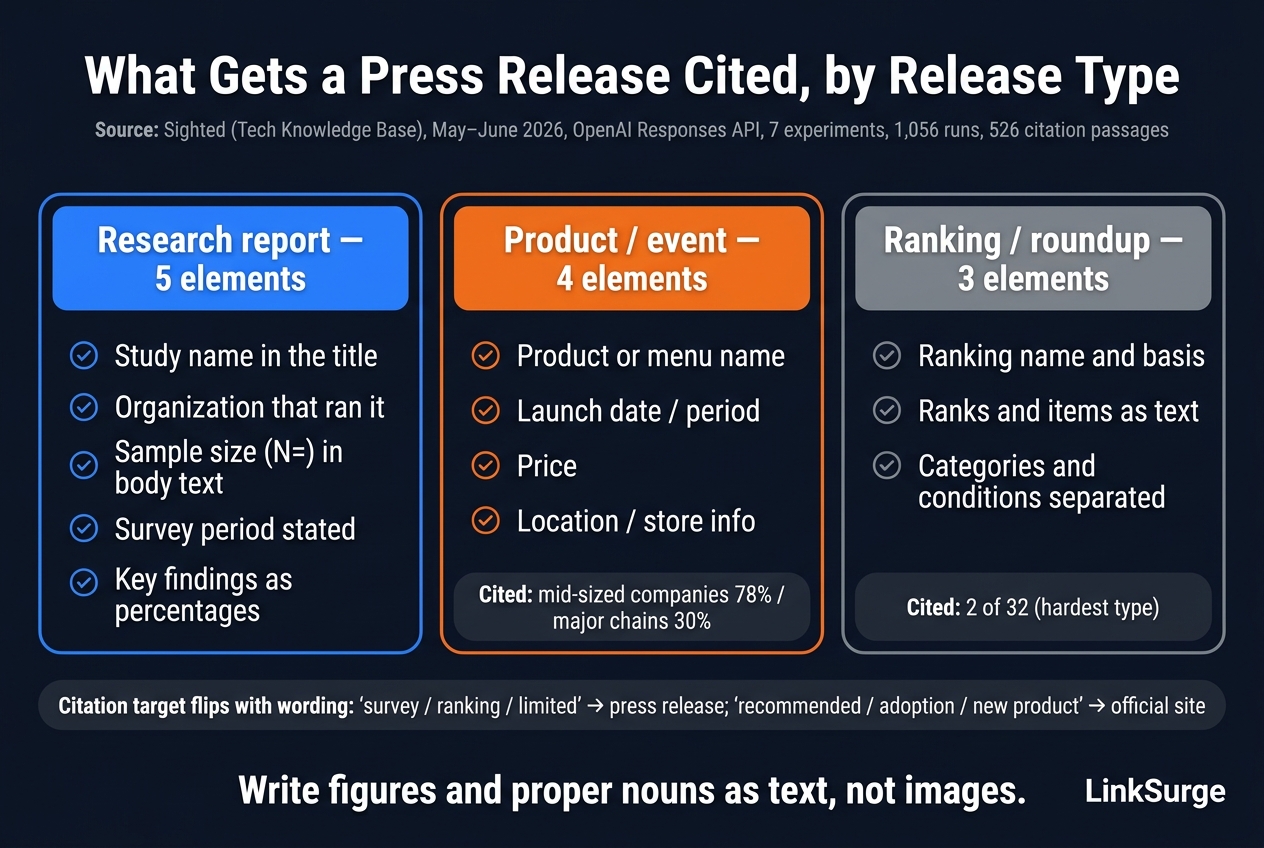
Publishing on PR TIMES doesn't guarantee a citation. Sighted, run by Tech Knowledge Base, published on July 15, 2026 the results of seven experiments totaling 1,056 AI search tests through OpenAI's Responses API with web search, analyzing 526 citation passages drawn from releases by more than 70 companies on PR TIMES. The conditions differ by release type.
| Release type | Elements required for citation | Notes |
|:---|:---|:---|
| Research report (5 elements) | Study name in the title; the organization that ran the study; sample size (N=…) stated in the body text; survey period; key findings as percentages | Works best when no more authoritative answer source already exists |
| Product or event (4 elements) | Product or menu name; launch date or availability period in the body; price; location or store information | All four together matter. Mid-sized companies cited 78%, major chains 30% |
| Ranking or roundup (3 elements) | Ranking name and basis; ranks and item names listed as text; categories and conditions separated | Only 2 of 32 were cited. The hardest type |
### Write figures and proper nouns as text
The common thread in the research-report type is whether the items the AI extracts are written as text. Study name, the organization behind it, sample size, period and percentages don't count if they only exist in a chart image. Put them in plain prose. We follow the same rule on this blog: any figure that appears in a graphic also appears in the body text.
### Mid-sized companies get cited more
A 78% citation rate for mid-sized companies versus 30% for major chains on product releases may seem counterintuitive. My interpretation: major chains already have more authoritative answer sources, official sites and major media coverage, so the AI doesn't need to reach back to the release. It's the same structure as the research-report condition of "no more authoritative source already exists." For mid-sized companies, the press release is the shortest path to being cited as their own primary source.
> References:
> [Report on the conditions for PR TIMES releases to be cited by AI (Japanese) - Tech Knowledge Base via PR TIMES](https://prtimes.jp/main/html/rd/p/000000011.000163833.html)
---
## 3. Press Release or Official Site?
The most practical finding in Sighted's study, to me, is that the citation target switches based on the wording of the question. For the same company and the same information, how the user phrases the query determines whether PR TIMES or the official site gets cited.
| Words in the question | Likely citation target |
|:---|:---|
| "survey," "ranking," "limited edition" | The release on PR TIMES |
| "recommended," "adoption status," "new product" | The official site |
The design that follows is simple. Put surveys, rankings and time-limited information on the press wire; put product recommendation rationale, case studies and evergreen new-product information on the official site, organized heading by heading. Do only one and you miss the questions phrased the other way.
On the official-site side, remember that 16.6% of ChatGPT's sub-queries for brand prompts search the brand's own domain by name. Sections 3 and 4 of [How to Get Cited by ChatGPT: The Complete Guide](/blog/en/chatgpt-geo-complete-guide-2026/) cover the structure.
---
{{linksurge-card}}
## 4. note and Ameblo: Where Long-Form First-Hand Accounts Live
In Ahrefs' Japan data, Ameblo and note are consistently near the top of ChatGPT's citation sources. In June 2026, Ameblo was third and note fifth. In April, Ameblo was first. In the industry analysis, Ameblo was third for food, and note, Ameblo and PR TIMES all ranked for IT.
### Why they get cited
My view is that these two platforms hold a huge volume of long-form writing by people who actually used, ate or tried the thing, which is exactly the first-hand material ChatGPT leans on as evidence. Of the five fan-out types (related topics, implicit questions, comparisons, recency, rephrasings), the text that answers "implicit questions" and "comparisons" more often lives in individuals' long posts than on official sites. The equivalents elsewhere are Medium, Substack, and community blogs.
### How a company uses note
- **Publish your own primary information at length** — Development history, test data, what went wrong. The depth a press release can't carry belongs on note
- **Spell out proper nouns and years** — 23.8% of ChatGPT's sub-queries carry exact-match quotes and 19.6% carry a year. Put product names, company name and the study year in the title and body
- **Make each heading self-contained** — Under every heading, a paragraph answering that heading's question in 40 to 60 words
### How to get more third-party note and Ameblo posts
Writing from your own account has limits. To increase posts by people who actually used the product, provide review samples, run hands-on events, and offer templates that make writing easier. Passing off your own writing as a third party's is a platform-policy and trust problem before it's an AI problem. The line between stimulating and fabricating UGC is drawn in [UGC and AI Search Citations](/blog/en/ugc-ai-search-brand-mentions-2026/).
> References:
> [Top 10 domains cited by AI search, April 2026 update (Japanese) - Ahrefs](https://ahrefs.com/blog/ja/brand-radar-top-10-cited-domains-2026-update/)
> [A study of query fan-out in ChatGPT using brand searches - MJ Cachón](https://www.mjcachon.com/en/blog/study-query-fan-out-chatgpt-brand/)
---
## 5. Yahoo! Chiebukuro, Rakuten and Reviews: Q&A and Product Facts
### Yahoo! Chiebukuro
Yahoo! Chiebukuro, Japan's largest Q&A site, entered ChatGPT's top 10 at ninth in June 2026. In Google AI Mode it was the overwhelming leader in May to September 2025 with 518,977 citations. Its share in ChatGPT is smaller than in Google, but question-style queries such as "what's the difference between X and Y" or "what to watch out for when choosing X" structurally match Chiebukuro's question titles, which makes it a natural citation candidate.
What a company can do is answer questions in its category accurately, under an official account or a named employee. Answer, don't advertise. Linking to your own primary information (surveys, specs) inside the answer makes both the Chiebukuro answer and your own site citation candidates.
### Rakuten, Amazon and reviews
Rakuten marketplace product pages ranked sixth in June 2026 and second for the food industry. Profound's July 2026 analysis found that 87.3% of product information in ChatGPT's shopping answers came from web crawling, and that top-ranked product cards had a median of 787 reviews versus 352 for cards ranked fourth or lower.
For e-commerce, the tactics are accurate specs, pricing and availability as text on marketplace product pages, and a mechanism for growing review counts (post-purchase requests, a clear path to posting). Shopping-specific tactics get their own article in this series.
### Price in the volatility risk
In August 2026, Reddit's share of ChatGPT Search citations fell 86% in four days, and YouTube and TikTok citations dropped 70 to 90 percent (cause unconfirmed). UGC platforms matter a lot when they matter, and can vanish overnight. Don't build around one. See [ChatGPT's Citation Sources Moved 86% in Four Days](/blog/en/chatgpt-citation-volatility-2026/).
> References:
> [Ahrefs analysis of AI search citation sources in Japan (Japanese) - Manamina](https://manamina.valuesccg.com/articles/4596)
> [Breaking down how ChatGPT Shopping works behind the user experience - Profound](https://www.tryprofound.com/blog/chatgpt-shopping-end-to-end-breakdown)
> [Reddit Citations Are Dropping in ChatGPT - Promptwatch](https://promptwatch.com/data/reddit-citations-are-dropping-in-chatgpt)
---
## 6. A 30-Day Plan for the Three Channels
Here's the sequence.
| Week | Do | Verify with |
|:---|:---|:---|
| 1 | Log ChatGPT's cited URLs for 20 to 30 category questions and group them into five buckets: press wire, note/Ameblo, Q&A, marketplaces, official site | Identify buckets where competitors are cited and you aren't |
| 2 | Publish one research-type or product-type release that meets Sighted's conditions (study name, the organization behind it, N, period, figures; or product name, launch date, price, location) | Log citations for two weeks after publication |
| 3 | Build official-site pages that answer "recommended," "adoption status" and "new product" questions heading by heading. Publish one long-form primary-information post on note | Log whether the official site and note get cited |
| 4 | Answer category questions on the Q&A site accurately. Build a review request path | Make weekly logging of mention rate and cited domains routine |
The logging in weeks 1 and 4 runs automatically if you register watch queries in [LinkSurge](https://linksurge.jp/)'s GEO monitoring, across five engines including ChatGPT Search. We use the same setup to measure this series.
---
## Frequently Asked Questions
### How often does ChatGPT cite press releases?
In Wallabee's analysis of 81,895 AI answers from April 21 to July 8, 2026, the share of answers citing at least one press release was 42.84% for ChatGPT (GPT-5 mini) and 27.33% for GPT-5.2. Perplexity was 21.45%, Claude 6.00% and Copilot 2.90%. 60.5% of the cited press release URLs were on PR TIMES.
### Does publishing on PR TIMES get you cited by ChatGPT?
Only under conditions. In Sighted's 1,056-run test in May and June 2026, research-report releases needed five elements stated in the text (study name, the organization that ran it, sample size, survey period and percentage figures), and product releases needed product name, launch date, price and location. For product releases, mid-sized companies were cited 78% of the time versus 30% for major chains, and topics that already have a more authoritative answer source are less likely to be cited.
### Does ChatGPT cite the press release or the official site?
It depends on the question's wording. Sighted found that questions containing "survey," "ranking" or "limited edition" favored the PR TIMES release, while "recommended," "adoption status" or "new product" favored the official site. Put surveys, rankings and time-limited information on the wire and product rationale and case studies on the official site to reduce misses.
### Can companies use note or Ameblo for ChatGPT optimization?
Yes. In Ahrefs' June 2026 data, Ameblo was ChatGPT's third most cited domain and note fifth, and both rank in the industry analysis. Publishing primary information at length from your own account, spelling out proper nouns and years, and making each heading self-contained turns posts into citation candidates. To grow third-party posts, stimulate (samples, hands-on opportunities, templates) rather than fabricate.
### Does answering on a Q&A site help with ChatGPT citations?
Yes. Yahoo! Chiebukuro entered ChatGPT's top 10 cited domains in June 2026 and was Google AI Mode's largest citation source with 518,977 citations in May to September 2025. Question-style queries structurally match Q&A titles. Answering category questions accurately under an official or named account and linking to your own primary information makes both the answer and your site citation candidates.
---
## Conclusion: Don't Just Publish Releases. Publish Them in the Form That Gets Cited
ChatGPT optimization in Japan is built on three channels that Western guides don't cover. Press releases appear in up to 42.84% of ChatGPT answers, and 60% of those are on PR TIMES. But whether a release is cited depends on type-specific elements, and query wording decides between the release and the official site. note and Ameblo hold long-form first-hand accounts, Chiebukuro holds Q&A, and Rakuten holds product facts. Each plays a different role, and each has a counterpart in your own market.
Start by logging who's cited for your category's questions in five buckets, then publish one research-type or product-type release that meets the conditions. And don't lean on a single platform. Spread thinly across the five buckets, official site included. Sources rotate within days.
LinkSurge's [GEO monitoring](https://linksurge.jp/geo) records mentions and cited URLs per watch query across five engines including ChatGPT Search. Use it to track citation changes before and after a release goes out.
---
## What Happened to ChatGPT's Query Fan-Out: From 2.17 to 7.61 Sub-Queries per Prompt, and Then Hidden
> URL: https://linksurge.jp/blog/en/chatgpt-query-fanout-hidden-2026/
> Date: 2026-09-08 | Category: AIO | Author: Aro Ogata
> Tags: ChatGPT optimization, query fan-out, ChatGPT search, sub-queries, Responses API, GEO, AI search optimization
## Key Takeaways: Fan-Out Didn't Disappear. It Tripled and Went Invisible
Until spring 2026, I could open Chrome DevTools, watch ChatGPT's internal search queries scroll by, and tell a client exactly which sub-query had picked up their page. By summer, that was gone. At the same time, fan-out itself more than tripled. Here's what the data shows.
1. **Fan-outs more than tripled** — Lily Ray's August 2026 observations put fan-outs per prompt at 7.61, up from 2.17, with the share of prompts handled by a single query falling from 94% to 43.5%. MJ Cachón's brand-prompt study measured 2.6 sub-queries per run and 10.3 distinct sub-queries when the same prompt was run four times
2. **Sub-queries disappeared from the conversation interface** — In mid-2026, when GPT-5.3 became the default, the `search_model_queries` field disappeared from the conversation response, and it wasn't observed in GPT-5.4 either. Little Green Agency's later update reports it reappearing in GPT-5.6, so visibility varies by model version
3. **The API still returns them** — With the web search tool enabled in OpenAI's Responses API, the `action.queries` array contains the sub-queries. That's the route for studying how your category's questions get decomposed
4. **Sub-queries have clear habits** — In brand prompts, 93.4% contain the brand name, 30.2% use the `site:` operator (55.1% of those targeting the brand's own domain), 23.8% carry exact-match quotes, 19.6% carry a year. For international brands, 27.3% mix in English vocabulary
5. **Optimize for what you can't see by covering patterns and measuring outcomes** — Stop chasing individual sub-queries. Build a heading block for each decomposition pattern (related topics, implicit questions, comparisons, recency, rephrasings) and log mention rate and cited domains weekly
Let's go through the timeline, the API method and the tactics.
---
## 1. What Fan-Out Is and How ChatGPT Does It
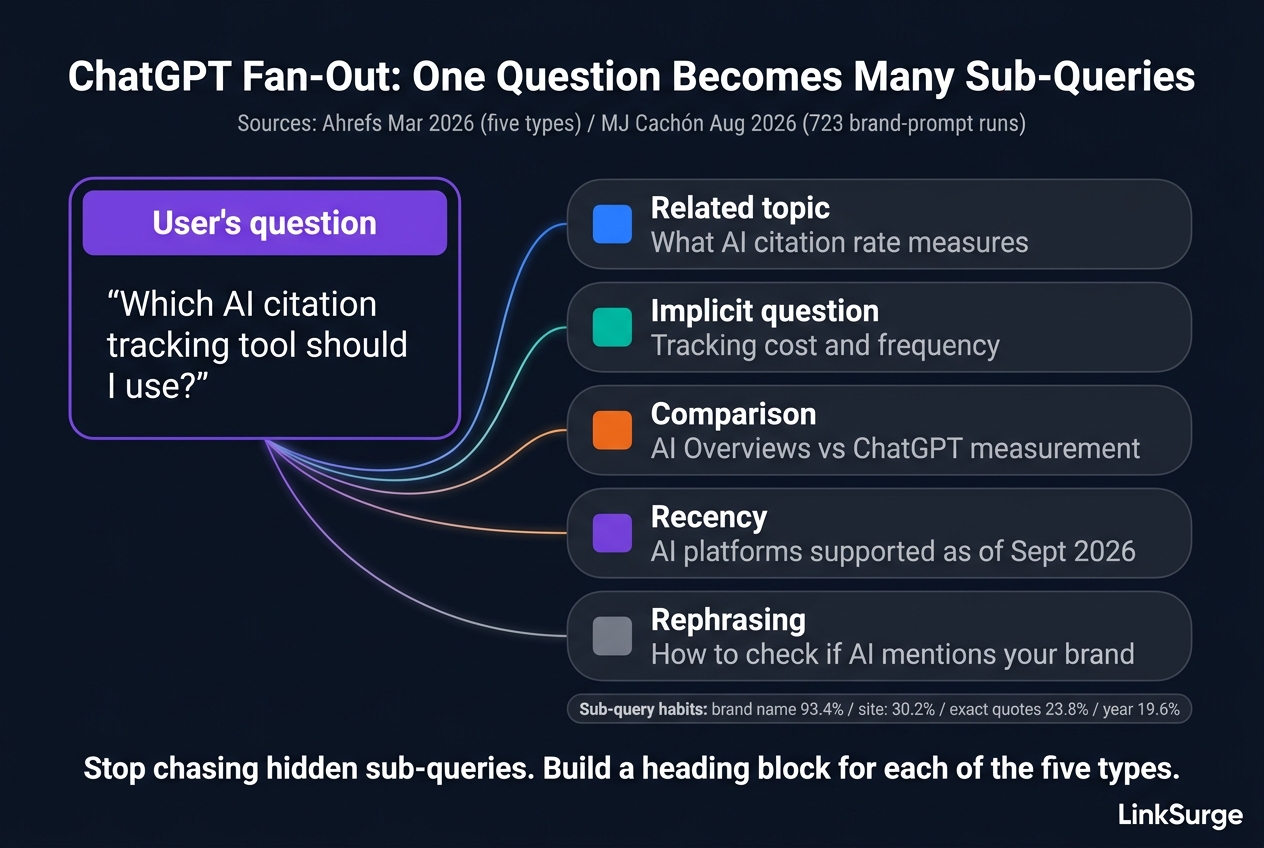
Query fan-out is the mechanism where an AI splits a single question into several sub-queries, searches them in parallel, and merges the results. Google AI Mode made the term famous. ChatGPT search works the same way.
Ahrefs' March 2026 breakdown identifies five fan-out types.
| Type | What it does | Example |
|:---|:---|:---|
| Related topics | Adds context from adjacent subjects | "meal prep containers" → "easy meal prep recipes" |
| Implicit questions | Anticipates concerns the user didn't voice | "solar panels" → "installation cost," "install time" |
| Comparisons | Side-by-side evaluation | "Asana vs Monday" |
| Recency | Time-sensitive searches | "best phones 2026" |
| Rephrasings | Same intent, different wording | "reduce bounce rate" → "keep visitors on site" |
The same analysis notes that more than 95% of fan-out queries never get searched again, so volume-based keyword optimization doesn't map onto them. For the Google side of the story, see [What Is Query Fan-Out?](/blog/en/query-fan-out-guide-2026/).
The ChatGPT-specific part starts here.
> References:
> [What is Query Fan-Out? Understanding the Hidden Queries Driving AI Search - Ahrefs](https://ahrefs.com/blog/query-fan-out/)
---
## 2. What Changed in Summer 2026
### Fan-outs more than tripled
Lily Ray's August 17, 2026 post compares behavior before and after a model update.
| Metric | Before | After |
|:---|:---|:---|
| Share of prompts handled with a single query | 94% | 43.5% |
| Fan-outs per prompt | 2.17 | 7.61 |
| Sources retrieved | ~12 | ~24 |
| Share using the `site:` operator | 0.3% | ~23% |
Honestly, the fairest description is that ChatGPT moved closer to Google AI Mode. Ahrefs measured AI Mode at 5 to 11 sub-queries for 59% of prompts and 12 to 19 for 24%. ChatGPT's 7.61 average now sits inside that range.
### And they went invisible
According to Little Green Agency's July 2, 2026 article, you could previously filter Chrome DevTools' network tab by conversation ID and read the sub-queries from the `search_model_queries` field in the raw JSON. According to that article, the field left the conversation interface they tested when GPT-5.3 became the default model, and it wasn't observed in GPT-5.4 either. The article's later update reports it reappearing in GPT-5.6, so visibility depends on the model version.
So fan-out grew while, depending on the model version, becoming harder to observe reliably. For SEOs, that means you know what's happening in general but can't directly see which sub-query picked up your page.
> References:
> [What We Can Learn from Evolving ChatGPT Fan-Out Queries - Lily Ray](https://lilyraynyc.substack.com/p/what-we-can-learn-from-evolving-chatgpt)
> [ChatGPT Has Hidden Its Fan-Out Queries. Here's How to Get Them Back with n8n - Little Green Agency](https://littlegreenagency.co.uk/blog/chatgpt-has-hidden-its-fan-out-queries-heres-how-to-get-them-back-with-n8n/)
---
## 3. What Sub-Queries Look Like: Measured on Brand Prompts
Hidden or not, API-based research has mapped the habits. MJ Cachón's study, published August 25, 2026, ran 189 brand prompts across three projects (healthcare, sports retail, hotels) 723 times through OpenAI's API on GPT-5.5.
| Metric | Value |
|:---|---:|
| Sub-queries per run (average / max) | 2.6 / 13 |
| Distinct sub-queries when the same prompt is run 4 times (average) | 10.3 |
| Sub-queries containing the brand name | 93.4% |
| Using the `site:` operator | 30.2% |
| Of which: own domain / group / third party / competitor | 16.6% / 7.9% / 5.6% / 0.1% |
| Containing exact-match quotes | 23.8% |
| Containing a year | 19.6% |
| Containing English vocabulary (all / international brands) | 8.9% / 27.3% |
| Runs completing in 2 searches or fewer | 63.9% |
Three things stood out to me. First, 69.8% of sub-queries are open searches, but of the 30.2% using `site:`, 55.1% target the brand's own domain and almost none target a competitor's. For brand prompts, 16.6% of all sub-queries search the official site by name. Second, exact-match quotes and years appear in roughly a fifth of sub-queries, so spelling out proper nouns and years in headings and body text gives them a landing spot. Third, more than a quarter of sub-queries for international brands contain English. That lines up with Ahrefs' Japan data, where English Wikipedia outranks Japanese Wikipedia among ChatGPT's cited domains, and it means a site that exists only in one local language is invisible to English sub-queries.
> References:
> [A study of query fan-out in ChatGPT using brand searches - MJ Cachón](https://www.mjcachon.com/en/blog/study-query-fan-out-chatgpt-brand/)
> [Top Japanese domains cited by AI, June 2026 (Japanese) - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
---
{{linksurge-card}}
## 4. Retrieving Hidden Sub-Queries Through the API
They're gone from the browser, but OpenAI's Responses API includes them when the web search tool is enabled. For studying how your category's representative questions get decomposed, this is enough.
### Steps
1. Get an OpenAI API key and send a Responses API request with the web search tool enabled
2. In the response output, find the item representing the web search call
3. Its `action.queries` array holds the sub-queries that actually ran
4. Run the same prompt several times and take the distribution. One run is skewed
Little Green Agency published an n8n workflow that automates this with an HTTP request node. By hand, running 10 to 20 representative prompts five times each and sorting the sub-queries into the five types gives you the list of landing spots your content needs.
### Caveats
- The API model and the ChatGPT web app don't decompose identically. Use this to understand tendencies, not to match exact queries
- Sub-queries change run to run. Deciding to "optimize for this sub-query" from a single run will miss
- Retrieved isn't cited. Being picked up by a sub-query doesn't guarantee a citation in the answer
---
## 5. Optimizing When You Can't See the Sub-Queries
With the sub-queries hidden, the axis shifts from "chase the sub-queries" to "cover the decomposition patterns" and "measure outcomes on a schedule."
### Cover the patterns
For each topic, build a heading block for each of the five types. If the topic is "AI citation tracking tools," the landing spots look like this.
- Related topic: "What AI citation rate actually measures"
- Implicit question: "How much tracking costs and how often to run it"
- Comparison: "How measurement differs between Google AI Overviews and ChatGPT"
- Recency: "AI platforms supported as of September 2026"
- Rephrasing: "How to check whether AI mentions your brand"
Under each heading, put a self-contained 40 to 60 word answer. In our analysis of 277 real Google AI Overviews citations, 69.3% came from heading blocks other than the lead paragraph. That study measured Google AI Overviews rather than ChatGPT, so applying it to ChatGPT is a working hypothesis we're designing around. Details in [Where Does AI Search Actually Quote From?](/blog/en/ai-citation-block-position-research-2026/).
### Make the official site survive a search by name
With more than half of `site:` sub-queries targeting the brand's own domain, product, pricing, comparison and FAQ content needs to be findable heading by heading within your site. Lily Ray recommends optimizing the official domain, stating "official" in meta descriptions, and monitoring `site:` queries in Search Console.
### Consider English landing pages
International brands see English in 27.3% of sub-queries, and English Wikipedia ranks among ChatGPT's top cited domains even for Japanese queries. Whether or not you operate internationally, English summaries of your key pages create a path in from English sub-queries.
### Log mention rate and cited domains weekly
The sub-queries are hidden. The outcomes aren't. For 20 to 30 questions in your category, log weekly how often ChatGPT mentions or cites you and which domains it cites. Answers vary between runs, so log multiple runs. [LinkSurge](https://linksurge.jp/)'s GEO monitoring registers watch queries across ChatGPT Search, Gemini, Google AI Overviews, Claude and Perplexity and records mention presence, position, cited URLs and competitor comparison. We use the same setup to measure this series.
For the full strategy, see [How to Get Cited by ChatGPT: The Complete Guide](/blog/en/chatgpt-geo-complete-guide-2026/). For the architecture, see [Inside ChatGPT Search](/blog/en/chatgpt-search-architecture-2026/).
---
## Frequently Asked Questions
### What is ChatGPT's query fan-out?
The mechanism where ChatGPT splits one user question into several internal search queries (sub-queries), searches each, and synthesizes the results. In Lily Ray's August 2026 observations, ChatGPT generated an average of 7.61 sub-queries per prompt, and only 43.5% of prompts were handled with a single query.
### Why can't I see ChatGPT's sub-queries anymore?
In mid-2026, when GPT-5.3 became the default model, the `search_model_queries` field disappeared from the response JSON in the conversation interface Little Green Agency tested, and it wasn't observed in GPT-5.4 either. Previously you could read it in Chrome DevTools' network tab. Their later update reports it reappearing in GPT-5.6, so visibility varies by model. OpenAI hasn't stated a reason.
### Is there still a way to see ChatGPT's sub-queries?
Yes. With the web search tool enabled in OpenAI's Responses API, the response's `action.queries` array contains the sub-queries that ran. Run the same prompt several times to get a distribution. Note that the API model and the ChatGPT web app don't decompose questions identically, so use it to understand tendencies.
### What do ChatGPT's sub-queries look like?
In MJ Cachón's August 2026 study (189 brand prompts, 723 runs), ChatGPT generated 2.6 sub-queries per run on average and 10.3 distinct sub-queries across four runs of the same prompt. 93.4% of sub-queries contained the brand name, 30.2% used the `site:` operator, 23.8% contained exact-match quotes and 19.6% contained a year. `site:` targeted mainly the brand's own domain and almost never competitors. For international brands, 27.3% contained English vocabulary.
### How do I optimize if I can't see the sub-queries?
Build a heading block for each of the five decomposition patterns (related topics, implicit questions, comparisons, recency, rephrasings) with a self-contained answer under each. Make product, pricing, comparison and FAQ content findable heading by heading on your official site, and spell out proper nouns and years. Then log ChatGPT mention rate and cited domains weekly and adjust with volatility as the baseline.
---
## Conclusion: Stop Chasing and Start Covering
ChatGPT's fan-out grew from 2.17 to 7.61 sub-queries per prompt in summer 2026 and, for the GPT-5.3 to 5.4 period, disappeared from the conversation interface at the same time. The sub-queries have recognizable habits, brand names, `site:`, exact quotes, years and English, and the API still reveals the tendencies.
Instead of chasing what you can't see, lay out heading-level landing spots for the five decomposition patterns, make the official site hold up under a search by name, and record outcomes weekly. Build it that way and the next change to fan-out behavior won't move your strategy.
LinkSurge's [GEO monitoring](https://linksurge.jp/geo) records mentions and cited sources across five platforms including ChatGPT Search on a schedule. Use the [AI Ready audit](https://linksurge.jp/ai-ready) to check the heading structure that serves as your landing spots.
---
## Inside ChatGPT Search: Bing, Google and OpenAI's Own "Labrador" Index, and How to Build for a System Rebuilt Week to Week
> URL: https://linksurge.jp/blog/en/chatgpt-search-architecture-2026/
> Date: 2026-09-08 | Category: AIO | Author: Aro Ogata
> Tags: ChatGPT optimization, ChatGPT search, OpenAI, Labrador, OAI-SearchBot, Bing, GEO, AI search optimization
## Key Takeaways: A Three-Layer System That Retrieves, Decomposes and Selects
Read enough ChatGPT SEO articles and you'll find some insisting "ChatGPT uses Bing" and others insisting "ChatGPT has its own search engine." After lining up the public evidence, my conclusion is that both are right, and the system is mid-migration. Here's what the evidence supports.
1. **The index has three layers** — Bing was the primary backend at launch in October 2024. Peec AI's September 2026 analysis identifies an experiment preferring OpenAI's own index (which Peec AI calls "Labrador"; OpenAI hasn't confirmed the name) over external search results in 8 percent of chats at the time of observation, with such experiments reportedly ranging from single digits up to 20 percent. Google and Bing are still in use alongside it
2. **Processing runs in three stages: retrieve, decompose, select** — The question is split into sub-queries (fan-out), candidate pages are pulled from the indexes, and after reading them the model cites a few. There is no rankings page. Selection happens at the heading-block level, not the page level
3. **Retrieved and cited are moving in opposite directions** — After the mid-2026 model update, sources retrieved per response doubled from about 12 to about 24, while the number cited fell. More chances to be read, harder competition to be picked
4. **Four crawlers, and OAI-SearchBot is the one that matters for search** — It's independent of GPTBot (training), ChatGPT-User (user-initiated fetches) and OAI-AdsBot (ads). You can opt out of training and stay in search
5. **Design for a system that is "still being rebuilt week to week"** — That phrase is Peec AI's own caveat. Don't optimize for a specific experiment name or percentage. Be in all three layers and readable at every stage. That's the only stable strategy
Let's walk through each stage.
---
## 1. From 2024 to 2026: Bing-Centric to Three Layers
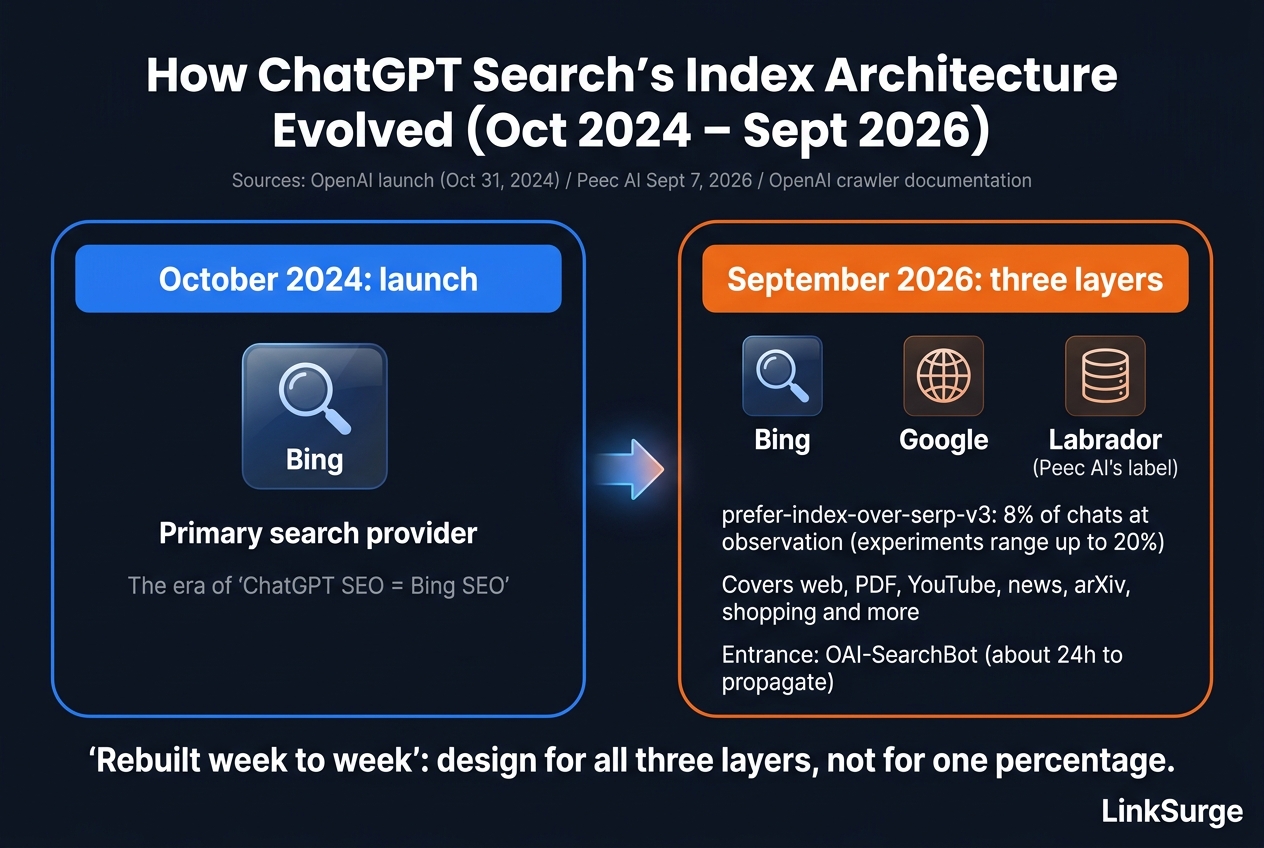
### The launch architecture
OpenAI launched ChatGPT search on October 31, 2024. The search model pulled from multiple search providers and data partners, with Microsoft Bing widely reported as the center of that setup. The "ChatGPT SEO is Bing SEO" advice from that period comes from this architecture.
### 2026: the "Labrador" index
The picture changed with Peec AI's analysis published September 4, 2026. They collected server-sent event metadata from ChatGPT between May 21 and July 21, 2026, and combined it with OpenAI job postings, testimony from Google's antitrust trial, crawl experiments on their own sites, and Search Console traffic analysis. Their findings:
| Item | Detail |
|:---|:---|
| Internal index name | Labrador (Peec AI's label for a family of vertical indexes; not a name OpenAI has confirmed) |
| Components | General web, PDF, YouTube, news (within 1 day, within 7 days, older), arXiv, Wikipedia, local, finance, legal, medical, shopping, images |
| Key experiments | `prefer-index-over-serp-v3` (applied to 8 percent of chats at the time of observation, mid-August 2026; Peec AI says such experiments range from single digits up to 20 percent), `shopping-index-q2qb`, `shopping-hqi-v2` and others |
| Relationship to external search | "Google and Microsoft still matter." Migration to the own index is gradual |
| Author's caveat | "This system is still being rebuilt week to week." Mostly verifiable evidence, partly inference |
Here's what's interesting about the experiment name itself. `prefer-index-over-serp-v3` states its intent, prefer the internal index over external search results, and it's already on its third version. The cluster of shopping experiments also lines up with what practitioners had suspected for a while: ChatGPT treats product search as a priority.
### What this means for your site
Which layer serves a given query depends on the question type and experiment assignment, neither of which you control. So the only robust position is to satisfy all three at once: indexed in Bing, indexed in Google, and crawlable by OAI-SearchBot so you're in the internal index.
> References:
> [ChatGPT built its own search index - Peec AI](https://peec.ai/blog/chatgpt-built-its-own-search-index)
> [ChatGPT search officially launches - Search Engine Land](https://searchengineland.com/chatgpt-search-officially-launches-447919)
---
## 2. Stage One: The Crawlers Read
Of the three layers, the one you directly influence is the entrance to OpenAI's own index: the crawlers. OpenAI's documentation defines four.
| Bot | Role | Your decision |
|:---|:---|:---|
| OAI-SearchBot | Crawls to surface your site in ChatGPT search results | Allow it if you want to appear in search |
| GPTBot | May use content to train foundation models | Disallow if you want to opt out of training. Doesn't affect search |
| ChatGPT-User | Fetches pages when a user asks ChatGPT or a custom GPT | User-initiated, so robots.txt may not apply |
| OAI-AdsBot | Verifies ad landing pages for safety and relevance | Only relevant if you advertise |
OpenAI says robots.txt updates take about 24 hours to take effect and publishes each bot's IP ranges as JSON, so you can verify a real OAI-SearchBot in your logs by IP rather than trusting the user-agent string.
### The JavaScript rendering trap
This is the problem I see most often in audits. OpenAI's documentation describes what each crawler does, how robots.txt applies and which IP ranges it uses, but it doesn't specify whether the crawlers execute JavaScript. That leaves content that only appears after client-side rendering at risk of not being read at fetch time. The safe configuration is server-side rendering or pre-rendering so the content is in the initial HTML. Write tables and numbers as text rather than images.
The full foundation checklist is in section 2 of [How to Get Cited by ChatGPT: The Complete Guide](/blog/en/chatgpt-geo-complete-guide-2026/).
> References:
> [Overview of OpenAI Crawlers - OpenAI](https://developers.openai.com/api/docs/bots)
---
## 3. Stage Two: The Question Is Decomposed (Query Fan-Out)
ChatGPT doesn't search your question as written. It splits it into sub-queries, searches each, and merges the results. This stage changed dramatically in summer 2026.
Lily Ray's August 17, 2026 observations compare before and after the model update.
| Metric | Before | After |
|:---|:---|:---|
| Share of prompts handled with a single query | 94% | 43.5% |
| Fan-outs per prompt | 2.17 | 7.61 |
| Sources retrieved | ~12 | ~24 |
| Share using the `site:` operator | 0.3% | ~23% |
MJ Cachón's study the same month (189 brand prompts, 723 runs via OpenAI's API) found an average of 2.6 sub-queries per run, rising to 10.3 distinct sub-queries when the same prompt was run four times. 93.4% of sub-queries contained the brand name and 30.2% used `site:`. Of those, 16.6% targeted the brand's own domain, 7.9% group domains, 5.6% third parties, and just 0.1% competitors.
The reading: for brand prompts, `site:` searches targeting the brand's own domain now make up 16.6% of all sub-queries (the other 69.8% are open searches). Your official site's structure and content feed the answer more directly than before.
Fan-out details, including how to retrieve the now-hidden sub-queries through the API, are in [What Happened to ChatGPT's Query Fan-Out](/blog/en/chatgpt-query-fanout-hidden-2026/). For Google's version, see [What Is Query Fan-Out?](/blog/en/query-fan-out-guide-2026/).
> References:
> [What We Can Learn from Evolving ChatGPT Fan-Out Queries - Lily Ray](https://lilyraynyc.substack.com/p/what-we-can-learn-from-evolving-chatgpt)
> [A study of query fan-out in ChatGPT using brand searches - MJ Cachón](https://www.mjcachon.com/en/blog/study-query-fan-out-chatgpt-brand/)
---
{{linksurge-card}}
## 4. Stage Three: Read Everything, Cite a Few
From the dozens of pages retrieved, ChatGPT reads the content and picks a handful to cite. Two observations matter here.
### Retrieved and cited diverge
Lily Ray points out that while sources retrieved doubled, sources cited moved in the opposite direction. More chances to be read, tougher competition to be picked. "ChatGPT is reading us" does not mean "ChatGPT is citing us." Measure the two separately.
### Selection happens at the block level
In our analysis of 277 real Google AI Overviews citations, 69.3% came from heading blocks other than the lead paragraph. That study measured Google AI Overviews, not ChatGPT Search. Whether a self-contained answer under each heading wins at ChatGPT's selection stage too is, for now, our working hypothesis rather than a measured result. See [Where Does AI Search Actually Quote From?](/blog/en/ai-citation-block-position-research-2026/).
### Sources rotate within days
Selection outcomes aren't stable. In August 2026, Promptwatch data reported by Search Engine Land showed Reddit's share of ChatGPT Search citations falling 86.4% in four days (cause unconfirmed). Ahrefs' Japan data shows ChatGPT's top cited domains reshuffling substantially between the April and June editions. That volatility is consistent with Peec AI's observation that index layers and experiment assignments change weekly. The August shift is covered in [ChatGPT's Citation Sources Moved 86% in Four Days](/blog/en/chatgpt-citation-volatility-2026/).
> References:
> [Reddit's ChatGPT Search citations fell 86% in four days - Search Engine Land](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473)
> [Top Japanese domains cited by AI, June 2026 (Japanese) - Ahrefs](https://ahrefs.com/ja/blog/brand-radar-top-10-cited-domains-2026-june/)
---
## 5. How to Build for a Moving Target
Now that we've covered the stages, here's how to act on them.
### Don't
- Optimize for a specific experiment name or percentage such as "8 percent at the time of observation." It will likely be different next week
- Assume "Bing is enough" or "Google is enough." You don't control which layer serves a query
- Count being retrieved (read) as a result. Measure citations and mentions separately
### Do
1. **Be in all three layers** — Check indexation in Bing Webmaster Tools and Search Console, and allow OAI-SearchBot in robots.txt
2. **Stay readable at every stage** — Server-side rendering, numbers and tables as text, self-contained answers under headings
3. **Make the official site survive a search by name** — With `site:` sub-queries above 20 percent, product, pricing, comparison and FAQ pages need to be findable heading by heading within your domain
4. **Log mention rate and cited domains weekly** — Volatility is the baseline, so this is a standing measurement, not a one-off check. [LinkSurge](https://linksurge.jp/)'s GEO monitoring records mentions and cited URLs across five platforms including ChatGPT Search and compares you against competitors
---
## Frequently Asked Questions
### Does ChatGPT just use Bing's search results?
Bing was the primary backend at launch in October 2024. Peec AI's September 2026 analysis identifies an experiment preferring OpenAI's own index (which Peec AI calls "Labrador"; OpenAI hasn't confirmed the name) over external search results in 8 percent of chats at the time of observation, while Google and Bing remain in use. The accurate description today is a three-layer system.
### What is "Labrador"?
The label Peec AI uses, in its September 2026 analysis, for a family of OpenAI's own search indexes. It is not a name OpenAI has confirmed. It reportedly covers general web, PDFs, YouTube, news, arXiv, Wikipedia, local, finance, legal, medical, shopping and images. OpenAI hasn't announced the name officially; Peec AI identified it from SSE metadata and job postings.
### What's the difference between OAI-SearchBot and GPTBot?
OAI-SearchBot crawls to surface your site in ChatGPT search results; disallow it and you won't appear in search answers. GPTBot may use content to train foundation models; disallowing it doesn't affect search visibility. You can opt out of training while staying in search. robots.txt changes take about 24 hours to propagate.
### Will a JavaScript-rendered site get cited by ChatGPT?
If the content only exists after client-side rendering, the crawler's fetched HTML lacks it and the page is unlikely to become a citation candidate. Server-side rendering or pre-rendering puts the content in the initial HTML. Tables and numbers in images aren't read either, so write them as text.
### How often does ChatGPT search change?
Peec AI describes the system as "still being rebuilt week to week," and the summer 2026 model update raised fan-outs per prompt from 2.17 to 7.61 in a short span. Cited sources rotate within days. Rather than matching a specific spec, the stable design is to be present in all three layers and readable at every stage.
---
## Conclusion: Don't Match the Spec, Stay Readable Under Any Spec
ChatGPT search retrieves from three layers (Bing, Google and the "Labrador" index), decomposes questions into 7+ sub-queries on average, reads the results and cites a few. And it's being rebuilt week to week.
That's why the durable strategy isn't tuning for a particular experiment. It's being indexed in all three layers, keeping content crawlable in the initial HTML, making answers self-contained at the heading level, and making the official site hold up when searched by name. Then log mention rate and cited domains weekly and adjust with volatility as the baseline.
LinkSurge's [AI Ready audit](https://linksurge.jp/ai-ready) checks robots.txt, heading hierarchy, structured data and llms.txt item by item. For scheduled tracking of mentions and cited sources in ChatGPT Search, use [GEO monitoring](https://linksurge.jp/geo).
---
## 54% of Gen Z Ask AI Before They Buy, But Still Trust Search Most: What Rakuten's Survey Means for GEO and SEO
> URL: https://linksurge.jp/blog/en/gen-z-ai-shopping-search-trust-2026/
> Date: 2026-09-04 | Category: AIO | Author: Aro Ogata
> Tags: Gen Z, generative AI, shopping behavior, Rakuten, AI Overviews, GEO, ChatGPT shopping, AI search optimization
## Key Takeaways: Build for "Shortlist with AI, Verify with Search"
When I read the Gen Z survey Rakuten Group published on September 4, 2026, two numbers sitting side by side caught my attention. 54.3% of Gen Z respondents use generative AI when researching or buying products. Yet the source they trust most is not AI. It is the search engine, at 42.1%. That looks like a contradiction until you line it up with other 2026 surveys. Then a consistent pattern appears: people use AI to narrow the field, and search to confirm the pick. Here are the five things that follow from it.
1. **AI has become a shortlisting tool** — The most common moment Gen Z reaches for AI is "narrowing down products I'm comparing" (44.4%), 1.6x more than "finding products I want" (27.8%). If your brand isn't in the AI's answer, you're eliminated before the comparison even starts
2. **The final call still gets verified in search** — In PLAN-B's May 2026 survey, 87.4% of people who learned about a product through AI went on to verify it with Google or another search engine. Landing in the AI answer and then showing an empty brand SERP is where the funnel leaks
3. **Brand websites make up just 3% of observed ChatGPT shopping citations** — Azoma's Q2 2026 analysis found ChatGPT's shopping citations were 41% earned media, 37% retailers, 19% UGC and 3% brand websites as a category. The other 97% came from third-party reviews, comparisons, retailers and UGC, which makes them your real sales collateral
4. **On purchase queries, classic search results still matter more than AI Overviews** — Semrush tracked 600K+ US keywords from November 2025 to April 2026: AI Overviews on commercial queries grew 71%, while on transactional queries they fell 5%. The ten blue links are alive and well where the verification happens
5. **Measure both the AI answer and the SERP** — Track mentions and cited sources across ChatGPT, Gemini, Perplexity and AI Overviews alongside rankings for brand and comparison queries. Watching only one side hides where the journey breaks
Let's break each of these down, starting with what Rakuten actually measured.
---
## 1. What Rakuten Found: Heavy Use, Guarded Trust
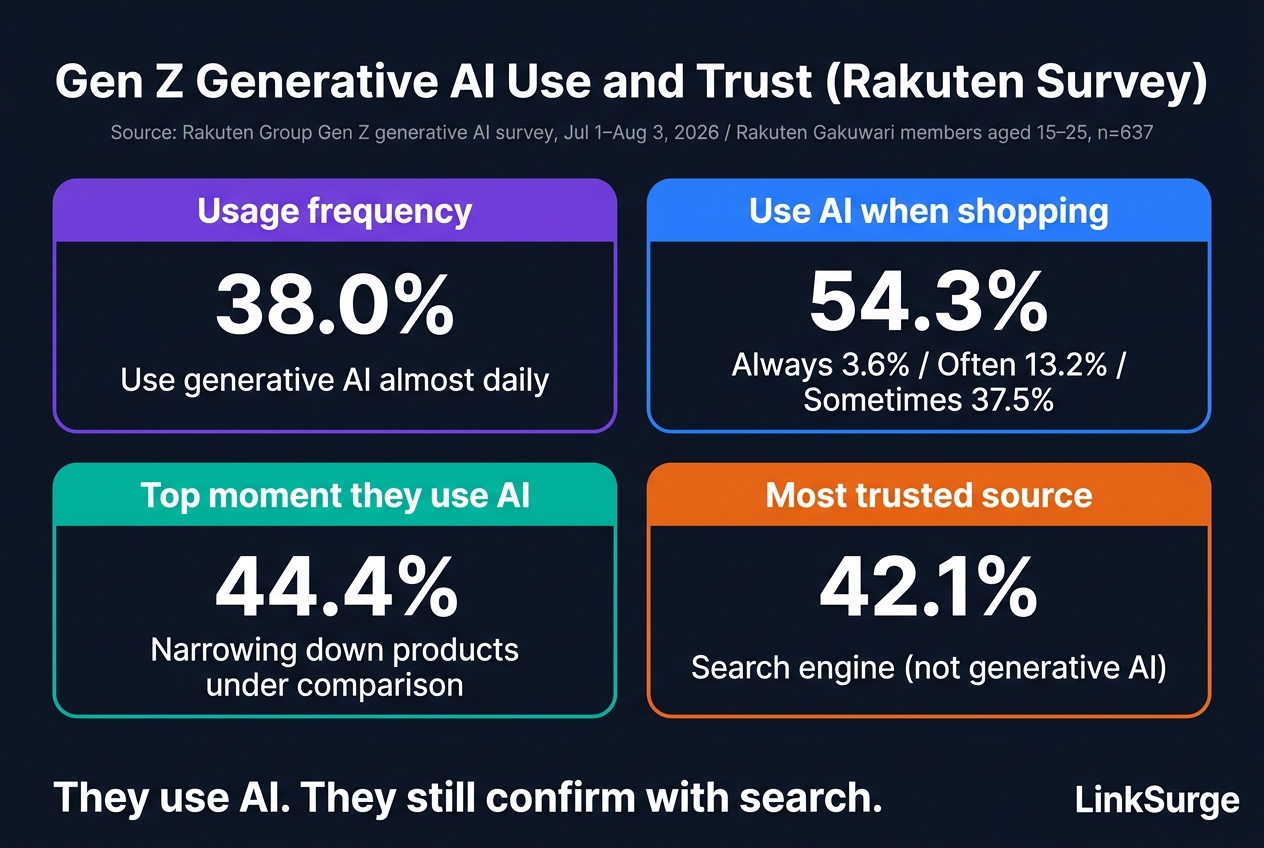
First, the primary source. Rakuten Group surveyed 637 members of its youth program "Rakuten Gakuwari" (ages 15 to 25) online between July 1 and August 3, 2026. Keep the sample in mind: these are registered members of one of Japan's largest e-commerce ecosystems, not a general population panel.
### AI is already daily infrastructure
38.0% said they use generative AI almost every day. Top use cases were studying (62.6%), researching hobbies (47.0%) and getting advice on personal worries (30.9%). Within the studying use case, 48.5% said they trust the AI's information (7.8% "strongly," 40.7% "somewhat"). Nearly half trust it, and the other half hold back. That same split shows up in shopping.
### How often, and when, they use AI for shopping
54.3% use generative AI when considering or buying products: 3.6% "always," 13.2% "often," 37.5% "sometimes." A majority use it, but fewer than one in five use it habitually.
| When they use AI (among users) | Share |
|:---|---:|
| Narrowing down products they're comparing | 44.4% |
| Finding products or services they want | 27.8% |
| While browsing an e-commerce site | 11.3% |
Here's what's interesting about that order. AI shows up less at the "start from zero" stage and more once a few candidates are already on the table. Only about one in ten use it side by side with an e-commerce site.
### And yet the most trusted source is the search engine
Asked which source they trust most when evaluating products, 42.1% named search engines, the largest share. Rakuten's own reading: Gen Z uses generative AI to narrow choices, but still places its highest trust in conventional search for information gathering. Using AI and believing AI are two different things.
The release also covers attitudes toward Rakuten's own AI push. 40.8% view Rakuten's use of generative AI to improve services favorably, and 30.6% gather product information with AI before visiting Rakuten Ichiba or its other shopping properties (3.9% "always," 26.7% "sometimes"). Companies that deploy AI in their services get a favorable impression from 31.7%, with "innovative" (43.6%), "willing to take on challenges" (26.7%) and "fits our generation" (17.4%) as the top associations.
> References:
> [Rakuten Announces Results of Gen Z Generative AI Usage Survey (Japanese) - Rakuten Group](https://corp.rakuten.co.jp/news/press/2026/0904_01.html)
---
## 2. Three Other 2026 Surveys Point the Same Way
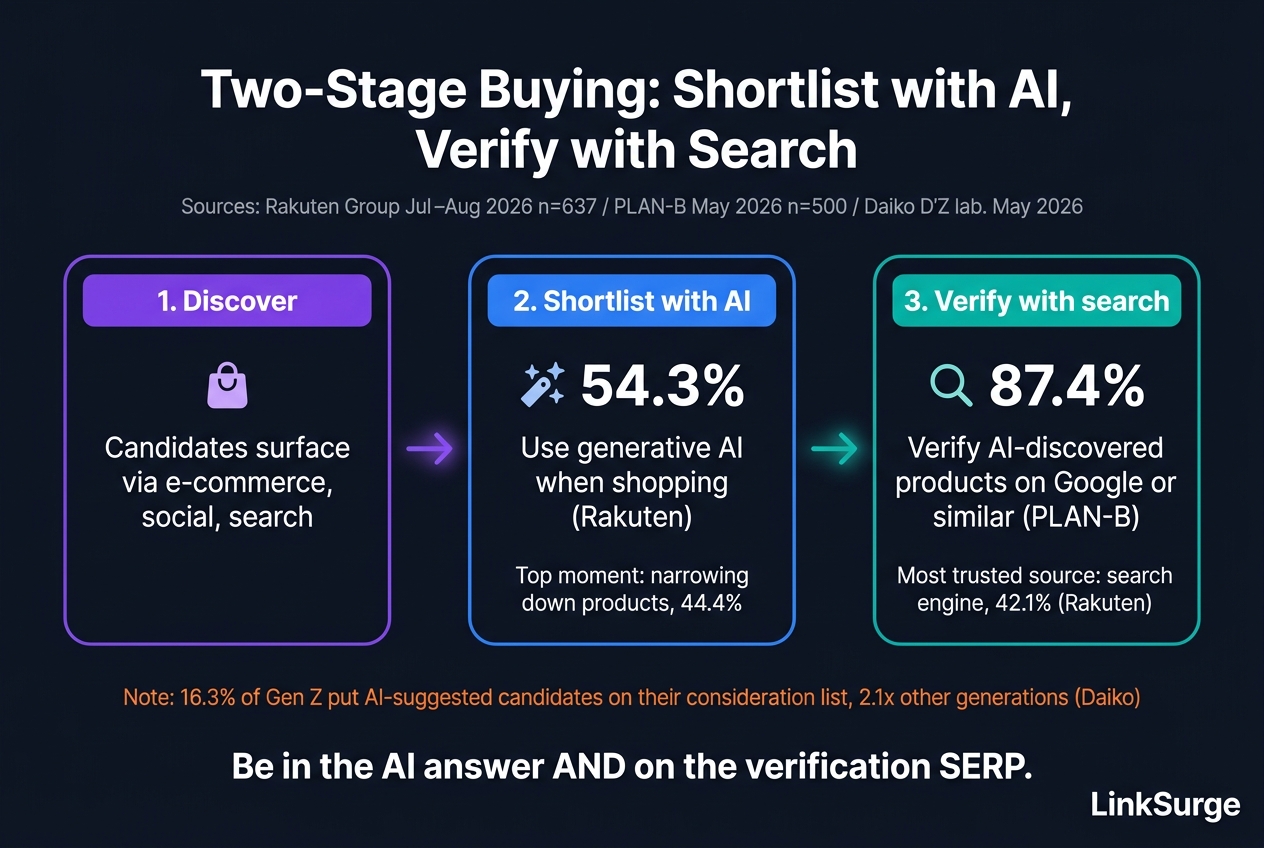
On its own, the Rakuten data describes one company's youth members. So I lined it up against three other Japanese surveys published in 2026. Different samples, different questions, so the figures aren't directly comparable. But the direction is remarkably consistent.
| Survey | Timing and sample | Key figures |
|:---|:---|:---|
| Rakuten Group | Jul–Aug 2026, Gakuwari members 15–25, n=637 | 54.3% use AI when shopping; search engine most trusted at 42.1% |
| PLAN-B | May 11–16, 2026, daily AI users 10s–60s, n=500 | 54.1% have bought something AI prompted (+11.4 pts YoY); 87.4% verify with Google or similar |
| Daiko D'Z lab. | May 2026 quantitative, 4,034 analyzed | Gen Z AI usage 56.5% (about 1.45x other generations); 16.3% put AI-suggested candidates on their consideration list vs 7.6% for others |
| Excrie | Apr 24–27, 2026, monthly+ AI users 15–69, n=1,190 | 69.9% have used AI for shopping (n=1,190); of those, 61.3% bought something AI recommended (shopping-AI users, n=832) |
### Why "shortlist with AI, verify with search" holds up
The clincher is PLAN-B's verification question. Among people who discovered a product through an AI conversation, 87.4% double-checked it via Google or another search engine, 34.4% via a marketplace like Amazon, and 34.1% via social media. Rakuten's "search is most trusted" and PLAN-B's "verify with search after AI" are the same behavior photographed from two angles.
Daiko adds a twist. 16.3% of Gen Z say they put a candidate the AI suggested on their purchase consideration list, 2.1x the rate of other generations (7.6%). So most people still verify, but AI suggestions make it onto the shortlist far more often for the young. Those two findings don't conflict. They mean being in the AI answer is worth more with every younger cohort.
In my own client work, I've watched branded search increasingly behave as the "check after asking AI" step. A brand lands in an AI answer, branded queries spike, and if that SERP is thin on reviews and comparisons, the traffic moves to a competitor. It's like picking a destination on the map and then turning back because you can't find the sign.
For the broader shift in how Gen Z searches, including TikTok as a search engine, see our [TikTok SEO playbook](/blog/en/tiktok-seo-ai-search-2026/).
> References:
> [Over Half of Purchases Now AI-Triggered: Generative AI Purchase Behavior Survey 2026 (Japanese) - PLAN-B](https://www.plan-b.co.jp/news/ai_purchase_report_202606/)
> [Gen Z AI Usage at 56.5%, 1.45x Other Generations (Japanese) - Daiko](https://www.daiko.co.jp/daiko-topics/2026/083110001011148)
> [Generative AI in Daily Life and Shopping Survey 2026 (Japanese) - Excrie](https://www.excrie.co.jp/report/generativeai-lifestyle-survey-202605)
---
## 3. What AI Actually Reads Before It Recommends a Product
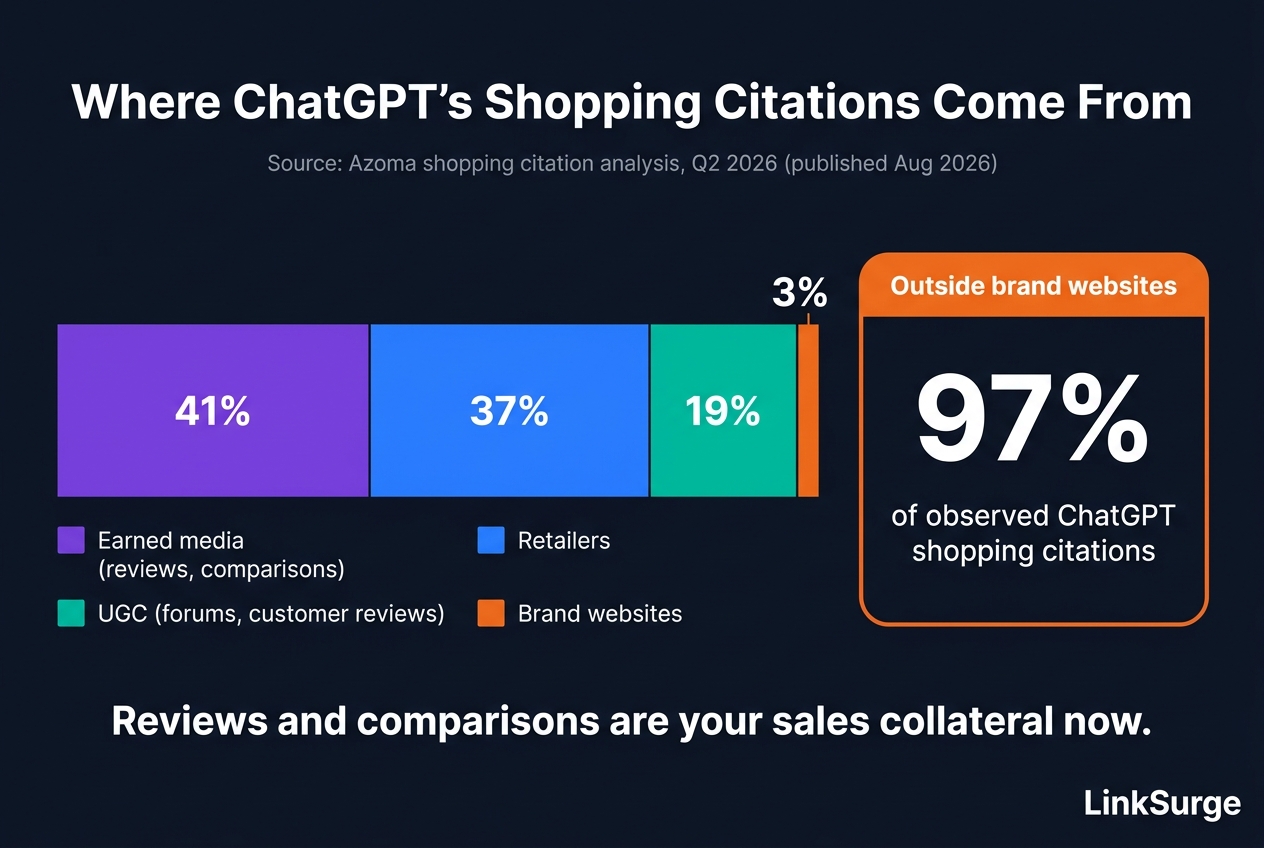
To get on the AI's shortlist, you need to know what it consults when it builds one. The best public data I've found comes from Azoma, an AI commerce analytics company, working with the Digital Shelf Institute.
### Your website is 3%. The rest is in other people's hands
Azoma's analysis published in August 2026 broke down ChatGPT's citation sources for shopping questions: 41% earned media (review sites, editorial coverage), 37% retailers, 19% user-generated content, and 3% brand websites. The dataset covers millions of shopping agent citations from Q2 2026.
| Citation source | Share |
|:---|---:|
| Earned media (reviews, comparisons, specialist publications) | 41% |
| Retailers (marketplaces, e-commerce sites) | 37% |
| UGC (forums, communities, customer reviews) | 19% |
| Brand websites | 3% |
Honestly, that 3% is an uncomfortable number for most brands. It's the total for the brand-website category, not a per-brand figure, but with 97% of observed ChatGPT shopping citations coming from outside brand websites, polishing your product pages alone leaves most of the cited sources untouched. Azoma's own framing: a brand that invests only in retailer listings is addressing barely over a third of what ChatGPT cites.
### Each AI agent has a different diet
The data behind Azoma's June 2026 framework, "The 5 C's of Agentic Commerce," shows how much this varies by agent. Amazon's Alexa for Shopping draws 86.5% of its citations from earned media, and Walmart's Sparky 76%. ChatGPT and Gemini lean much harder on retailers, at 37.1% and 41.6% respectively. Which AI you want to win determines which sources you should invest in.
How AI pulls in UGC, and why the mix shifts so fast, is covered in our guide to [UGC and AI search citations](/blog/en/ugc-ai-search-brand-mentions-2026/). Remember that citation sources can flip within weeks. Promptwatch data reported by Search Engine Land shows Reddit's share of ChatGPT Search citations fell 86.4% in four days in August 2026, and the cause remains unconfirmed. Depending on any single platform is a risk in itself.
Tracking who gets cited requires recording AI answers on a schedule, not spot-checking. [LinkSurge](https://linksurge.jp/)'s GEO monitoring lets you register shortlist-style queries ("best X for Y," "A vs B") across ChatGPT Search, Gemini, Google AI Overviews, Claude and Perplexity, and logs whether your brand is mentioned and which URLs were cited, per platform. Once you know who's being cited, the review sites and comparison articles you need to go after become obvious.
> References:
> [What Sources Does ChatGPT Cite for Products? Azoma Publishes the Data - GlobeNewswire](https://www.globenewswire.com/news-release/2026/08/26/3351631/0/en/what-sources-does-chatgpt-cite-for-products-azoma-publishes-the-data-and-explains-how-brands-get-recommended.html)
> [Azoma and Digital Shelf Institute Launch "The 5 C's of Agentic Commerce" - Business Wire](https://www.businesswire.com/news/home/20260604759368/en/Azoma-and-Digital-Shelf-Institute-Launch-The-5-Cs-of-Agentic-Commerce-to-Rescue-Brands-From-AI-Pilot-Purgatory)
> [Reddit's ChatGPT Search citations fell 86% in four days - Search Engine Land](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473)
---
{{linksurge-card}}
## 4. Surviving the Verification Search
Getting into the AI answer is only half the journey. Rakuten's 42.1% and PLAN-B's 87.4% both say the same thing: Gen Z goes to a search engine afterward to check. That's classic SEO territory, but AI Overviews have changed what the SERP looks like, so let's get the current picture straight.
### How far have AI Overviews spread into shopping queries?
Semrush's study, published July 2, 2026, tracked more than 600,000 keywords in its US desktop database across ten industries from November 2025 to April 2026. Over those six months, the share of commercial-intent SERPs showing an AI Overview rose 71%. On transactional queries, it fell 5%. Consideration-stage queries ("best," "compare") are getting AI Overviews; purchase-stage queries ("buy," "price," "in stock") mostly aren't.
That's US data. Rates vary a lot by industry and query type in other markets, so check your own priority queries directly. [LinkSurge](https://linksurge.jp/)'s AI Overview analysis takes a keyword and your URL and returns whether an AI Overview appeared, the full list of cited URLs, and whether your page is among them.
### The three query types people use to verify
From what I've seen, the searches that fire after an AI recommendation fall into three buckets.
| Query type | Examples | What the SERP needs to show |
|:---|:---|:---|
| Brand + reputation | "brand reviews," "product complaints" | Third-party reviews, Q&A threads, an official FAQ |
| Comparison | "A vs B," "product X alternative" | Comparison articles, spec tables, price rationale |
| Purchase conditions | "product price," "product shipping," "product in stock" | Accurate product pages, structured data, marketplace listings |
A brand-plus-reputation SERP that shows only your own pages reads, to a Gen Z shopper, as "couldn't verify." Whether third-party reviews and comparisons appear on page one deserves the same monitoring cadence as your AI mentions.
For the wider view of what's changed on the results page itself, see [how AI search is reshaping SEO](/blog/en/ai-search-seo-japan-2026/).
> References:
> [AI Overviews are expanding across commercial intent search [Study] - Semrush](https://www.semrush.com/blog/ai-overviews-commercial-search-study/)
---
## 5. What Rakuten's In-App AI Concierge Signals for Retail
Rakuten's release doesn't stop at the survey. It also describes "Rakuten AI," an agentic assistant built into the Rakuten Ichiba app since December 2025. Shoppers describe budget, purpose and use case by text, voice or image, and the concierge proposes products from a catalog of roughly 500 million items, asking follow-up questions to surface needs the shopper hasn't articulated.
### When the marketplace's own AI is the front door, product pages become source material
What's happening here is that AI shortlisting has moved inside the marketplace. A shopper might be narrowed down by ChatGPT, narrowed again by the in-app concierge, and finally verify in search. Product descriptions, specs and reviews are no longer just copy for humans. They're the raw material an in-store agent uses to decide who makes the cut.
Recall from Azoma's data that retailer sources account for 37.1% of ChatGPT's citations and 41.6% of Gemini's. Accurate, complete marketplace listings pay off twice: inside the marketplace's agent and in external AI answers. Stale prices, missing stock status, or specs buried in an image rather than written in text are exactly the kind of gaps that get a product dropped.
The same logic applies to US and European marketplaces rolling out shopping agents, from Amazon's Alexa for Shopping to Walmart's Sparky. [LinkSurge](https://linksurge.jp/)'s AI Ready audit checks structured data, heading hierarchy, llms.txt and other machine-readability signals for any URL, so you can score your product pages and comparison content side by side and decide which to fix first.
> References:
> [Rakuten Announces Results of Gen Z Generative AI Usage Survey (Japanese) - Rakuten Group](https://corp.rakuten.co.jp/news/press/2026/0904_01.html)
---
## 6. A 30-Day Plan
Let's turn this into a schedule. The goal is to show up in both places: the AI shortlist and the verification SERP.
### Week 1: Design your monitoring queries and take a baseline
1. Write down 10 to 20 shortlist-style queries for your category ("best [category] for [use]," "[A] vs [B]," "[category] recommendations")
2. Run each in ChatGPT, Gemini, Perplexity and Google AI Overviews. Record whether you're mentioned and which URLs are cited
3. Record rankings for the same queries plus your branded queries, and note which third-party pages sit on page one
Manual is fine for the baseline. If you plan to repeat it weekly, automate the AI-answer capture. The volatility is high enough that spot-checks will mislead you.
### Week 2: Identify the third-party sources being cited
1. Group Week 1's cited URLs by domain into review sites, comparison publishers and UGC
2. Prioritize domains where competitors are cited and you aren't
3. Decide the play per domain: review outreach, briefing a specialist publication, answering on community sites
### Week 3: Fix your own pages and listings
1. Put specs, price, availability and "how it differs from X" in the body text of product pages, not just images
2. Add Product, Offer and FAQPage structured data and make sure it matches the visible content
3. Publish an official FAQ page that answers brand-plus-reputation queries directly
### Week 4: Check the verification path and lock in measurement
1. Confirm that branded and comparison SERPs show third-party corroboration, not just your own pages
2. Put AI mention rate, cited domains and branded rankings in one table and switch to weekly tracking
3. Search for your products inside the shopping agents of your key marketplaces and note whether you appear
---
## Frequently Asked Questions
### How much does Gen Z use generative AI when shopping?
In Rakuten Group's survey of 637 Rakuten Gakuwari members aged 15 to 25, conducted July to August 2026, 54.3% use generative AI when considering or buying products: 3.6% always, 13.2% often and 37.5% sometimes. The most common use is narrowing down products under comparison, at 44.4%.
### If they use AI, why is a search engine their most trusted source?
In the same Rakuten survey, 42.1% named search engines as their most trusted source for product research, the largest share. PLAN-B's May 2026 survey found that 87.4% of people who learned about a product through AI verified it with Google or a similar search engine. Across multiple studies, AI serves as a shortlisting tool while the final decision is checked in search.
### What sources does ChatGPT cite when recommending products?
Azoma's analysis of Q2 2026 data, published in August 2026, found ChatGPT's shopping citations were 41% earned media, 37% retailers, 19% user-generated content and 3% brand websites. That 3% is the total for the brand-website category. Optimizing only your own site leaves most of the observed citations untouched, so review sites, comparison articles and marketplace listings need to be part of the plan.
### Do AI Overviews appear on shopping keywords?
Semrush tracked over 600,000 US keywords from November 2025 to April 2026. The share of commercial-intent SERPs with an AI Overview rose 71%, while transactional-intent SERPs fell 5%. AI Overviews are spreading on "best" and "compare" queries but remain limited on "buy" and "price" queries. Rates vary widely by industry, so check your own priority terms.
### Should I prioritize AI mentions or search rankings?
Track both in the same table. Watching only AI mentions hides the case where you make the shortlist but vanish at verification. Watching only rankings hides the case where you were never on the shortlist at all. Log AI mention rate and cited domains for shortlist queries alongside rankings for branded and comparison queries, weekly.
---
## Conclusion: Get Shortlisted by AI, Then Confirmed by Search
Rakuten's survey doesn't say Gen Z trusts AI blindly. It says they've assigned AI and search different jobs: AI narrows, search confirms. Because purchases move in that order, being strong on only one side means the journey breaks halfway through.
Start by finding out who AI cites for your category's shortlist queries. With 97% of observed ChatGPT shopping citations coming from outside brand websites, earning coverage on review sites and in comparison articles ranks at least as high as improving your product pages. In parallel, make sure branded and comparison SERPs show third-party corroboration on page one.
LinkSurge's [GEO monitoring](https://linksurge.jp/geo) records your brand's mentions and cited sources across ChatGPT, Gemini, Perplexity, AI Overviews and Claude on a schedule, with competitor comparison built in. If you want the AI side and the search side on one screen, pair it with the 30-day plan above.
---
## How SEO Changed: From Keyword Stuffing in the 1990s to Getting Cited by AI in 2026, a 30-Year Timeline
> URL: https://linksurge.jp/blog/en/seo-history-keywords-to-ai-2026/
> Date: 2026-09-04 | Category: SEO | Author: Aro Ogata
> Tags: SEO history, Google algorithm updates, AI Overviews, AI Mode, GEO, E-E-A-T, PageRank, AI search optimization
## Key Takeaways: Five Eras, One Direction, From Rankings to Citations
With AI search news landing every week, I did the opposite of chasing it. I put 30 years of SEO on a single timeline. What looks like an upheaval since 2024 turns out to be the latest step in a direction Google has been moving since the 1990s. Here's what the timeline shows.
1. **SEO has passed through five eras** — Directories and keywords (1994–2002), links (2003–2010), quality (2011–2014), intent and mobile (2015–2021), and AI citations (2022 onward). Each boundary is marked by an update that killed the previous era's winning tactic
2. **What changed is who judges you and what counts as a win** — The judge moved from human directory editors to link math, machine learning and language models. The win moved from "rank #1 and get the click" to "get cited or mentioned in the AI's answer"
3. **Three things haven't changed in 30 years** — Answer the user's actual question, make your pages machine-readable, and prove you're a trustworthy source. Every time a shortcut got closed, these three gained weight
4. **Where we stand in 2026 is measurable** — US zero-click rate 68.01% (SparkToro, Jan–Apr 2026), AI Overviews on roughly 43–48% of searches (Similarweb and Semrush, July 2026), AI Overviews on commercial queries up 71% in six months (Semrush). 54.3% of Gen Z use generative AI when shopping, yet trust search engines most (Rakuten, Sept 2026)
5. **Old techniques aren't discarded, they're stacked** — Crawlable structure, mobile readiness and E-E-A-T proof are still prerequisites in AI search. The 2026 work is adding citation-friendly structure and AI-side measurement on top
Let's walk through each era, what it rewarded, what killed it, and then the order to work in now.
---
## 1. 1994–2002: The Directory and Keyword Era
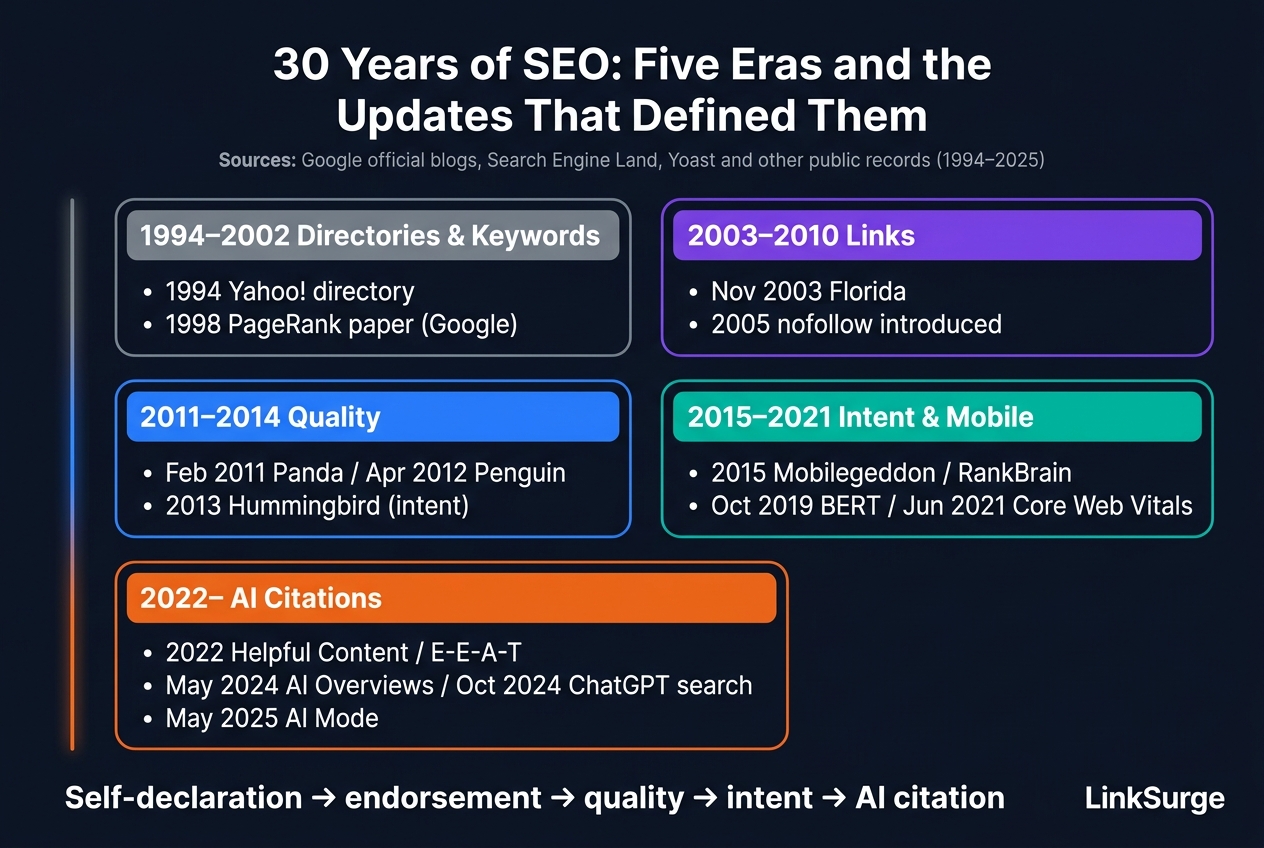
Honestly, SEO was simple back then. Search engines had almost no way to understand what a page was about, so they largely trusted the page's own description of itself. Whatever you declared, you got credit for.
### From hand-curated directories to full-text search
In January 1994, two Stanford graduate students, Jerry Yang and David Filo, published "Jerry and David's Guide to the World Wide Web." It became Yahoo!, a directory of sites organized by hand into a hierarchy of categories. By September 1994 it listed more than 2,000 sites and handled 50,000 searches a day. "SEO" at the time meant submitting your site to the right category.
Then full-text engines like AltaVista arrived and started indexing page bodies and meta tags directly. That's where keyword stuffing was born: pack the meta keywords tag with target terms, repeat them through the body, and sometimes hide extra copies in text the same color as the background.
### 1998: PageRank changed the game
In 1998, Sergey Brin and Larry Page published "The Anatomy of a Large-Scale Hypertextual Web Search Engine." Instead of trusting what a page said about itself, PageRank used the web's link structure to compute how important a page was. Judging a page by how many others vouched for it became the center of SEO for the next two decades.
As for the meta keywords tag, Google stated publicly in 2009 that it doesn't use it for ranking. The first era's winning move was officially dead.
> References:
> [History of Yahoo - Wikipedia](https://en.wikipedia.org/wiki/History_of_Yahoo)
> [The Anatomy of a Large-Scale Hypertextual Web Search Engine - Stanford InfoLab](http://infolab.stanford.edu/pub/papers/google.pdf)
> [Google does not use the keywords meta tag in web ranking - Google Search Central Blog](https://developers.google.com/search/blog/2009/09/google-does-not-use-keywords-meta-tag)
---
## 2. 2003–2010: The Link Era
Once PageRank became the core signal, the battleground shifted to acquiring links. If I had to sum this era up in a sentence: links were currency.
### Florida showed that shortcuts get closed
On November 16, 2003, Google rolled out what the industry later named the Florida update. Right before the holiday shopping season, sites relying on keyword stuffing, cloaking and doorway pages lost rankings en masse, and contemporary accounts describe small retailers and affiliates disappearing overnight. It's remembered as the first major algorithm update.
### Paid links and nofollow
At the same time, the clear value of links industrialized link building: buying links, reciprocal link pages, mass directory submissions, blog comment spam. In January 2005, Google introduced the rel="nofollow" attribute as a comment spam countermeasure, giving sites a way to say "this link isn't an endorsement." Paid links and link farms nonetheless kept working into the early 2010s.
When I started in this industry, backlink counts were still showing up in sales decks as if they were a KPI. As long as the number of links was rewarded, whoever could manufacture the most would win. Google went after that structural flaw head-on in the next era.
Why satellite sites and aggressive link building are still dangerous today is covered in our guide to [satellite site SEO risks and safe link building](/blog/en/satellite-site-seo-risks-2026/).
> References:
> [Google's Florida update: 20 years since the SEO 'volcanic eruption' - Search Engine Land](https://searchengineland.com/google-florida-update-434540)
> [Google Florida: The First Major Algorithm Update - Search Engine Journal](https://www.searchenginejournal.com/google-algorithm-history/florida-update/)
> [Preventing comment spam - Official Google Blog (2005)](https://googleblog.blogspot.com/2005/01/preventing-comment-spam.html)
---
## 3. 2011–2014: The Quality Era
Three updates between 2011 and 2013 ended the link era. This is where SEO started shifting from a contest of tactics to a contest of content and trust.
| Update | When | Target |
|:---|:---|:---|
| Panda | February 2011 | Thin, duplicated, ad-heavy pages |
| Penguin | April 24, 2012 | Manipulative link profiles (paid links, link farms) |
| Hummingbird | 2013 | Core algorithm rewrite to understand query intent, not just words |
### Panda and Penguin ended "more is better"
Panda demoted entire sites built on thin pages mass-produced around keywords. Content farms took the direct hit. Penguin, a year later, targeted the paid links and link farms accumulated during the link era. Assets from the "links are currency" years turned into liabilities overnight.
### Hummingbird brought intent into the equation
Hummingbird in 2013 wasn't a penalty. It was an engine swap. Rather than matching "Tokyo kid-friendly restaurant" word by word, Google started interpreting the underlying need: I want to eat out in Tokyo with my kids. Here's what's interesting: this 2013 pivot is a straight line to BERT in 2019 and AI search after 2024. From word matching to intent understanding. SEO became a job about search intent from this point on.
For the four types of search intent and how to analyze them, see [What Is Search Intent?](/blog/en/search-intent-seo-guide/).
> References:
> [A brief history of Google's algorithm updates - Yoast](https://yoast.com/google-algorithm-updates/)
> [A Timeline of Google Algorithm Updates - BrightEdge](https://www.brightedge.com/blog/a-timeline-of-googles-algorithm-updates)
---
## 4. 2015–2021: The Intent and Mobile Era
With quality standards set, Google began folding in the device, the experience and the language of each search. Machine learning and smartphones are the protagonists of this era.
### Mobile became the default
On April 21, 2015, Google expanded mobile-friendliness as a ranking signal, an update the industry dubbed Mobilegeddon. On March 26, 2018, mobile-first indexing officially began rolling out, meaning Googlebot crawls and evaluates the mobile version of a page as the primary one. The old sequence of building the desktop site first and adapting it for phones flipped.
### RankBrain and BERT put machine learning inside search
In October 2015, Google confirmed RankBrain to Bloomberg: a machine learning system for interpreting queries it had never seen, described at the time as the third most important ranking factor after links and content. On October 22, 2019, BERT arrived, reading words in a query bidirectionally to grasp context. In my own rank tracking, the post-BERT shift was obvious. Results moved less on "did you include the target keyword" and more on "did you actually answer the question."
### Core Web Vitals turned experience into metrics
The page experience update that started rolling out on June 16, 2021 added Core Web Vitals, LCP, FID (later replaced by INP) and CLS, as ranking signals. Load speed and layout stability went from nice-to-have to measured criteria.
> References:
> [Mobilegeddon - Wikipedia](https://en.wikipedia.org/wiki/Mobilegeddon)
> [Google begins to roll out mobile-first indexing - TechCrunch](https://techcrunch.com/2018/03/26/google-begins-to-roll-out-its-mobile-first-index/)
> [Google Turning Its Lucrative Web Search Over to AI Machines - Bloomberg](https://www.bloomberg.com/news/articles/2015-10-26/google-turning-its-lucrative-web-search-over-to-ai-machines)
> [Timing for bringing page experience to Google Search - Google Search Central Blog](https://developers.google.com/search/blog/2020/11/timing-for-page-experience)
---
## 5. 2022–2024: The AI Citation Era, Part One. "Is It Helpful?" and AI Enters the Results Page
Now that we've covered the foundations, let's take the fifth era, AI citations, in two parts. Between 2022 and 2024, Google started asking who content was written for, and generative AI got built into the results page itself.
### The Helpful Content Update and E-E-A-T
On August 18, 2022, Google launched the Helpful Content Update to reward content written for people rather than for search engines. In December 2022, the Search Quality Rater Guidelines added "Experience" to E-A-T, making it E-E-A-T. First-hand experience, having actually used, tested or lived the thing, was now written into the rubric.
The March 2024 core update went further. Google announced it had reduced low-quality, unoriginal content in results by 45% (up from an expected 40%), alongside new spam policies against scaled content abuse, site reputation abuse and expired domain abuse.
### AI Overviews launch, and ChatGPT enters search
On May 14, 2024, at Google I/O, AI Overviews rolled out in the US, reaching Japan on August 15, 2024. An AI-generated summary now sits at the top of the results page with links to its cited sources. A new layer appeared above "rank #1": being cited in the summary.
On October 31, 2024, OpenAI launched ChatGPT search. Together with Perplexity, founded in August 2022, "search and generate an answer" became mainstream outside Google, and SEO's target stopped being a single results page.
For more on E-E-A-T and primary sources in AI search, see [how AI search is reshaping SEO](/blog/en/ai-search-seo-japan-2026/).
> References:
> [Our latest update to the quality rater guidelines: E-A-T gets an extra E for Experience - Google Search Central Blog](https://developers.google.com/search/blog/2022/12/google-raters-guidelines-e-e-a-t)
> [Google Search: New updates to address spam and low-quality results - Google](https://blog.google/products-and-platforms/products/search/google-search-update-march-2024/)
> [Google I/O 2024: New generative AI experiences in Search - Google](https://blog.google/products-and-platforms/products/search/generative-ai-google-search-may-2024/)
> [Introducing ChatGPT search - OpenAI](https://openai.com/index/introducing-chatgpt-search/)
---
{{linksurge-card}}
## 6. 2025–2026: The AI Citation Era, Part Two. Where We Stand Today
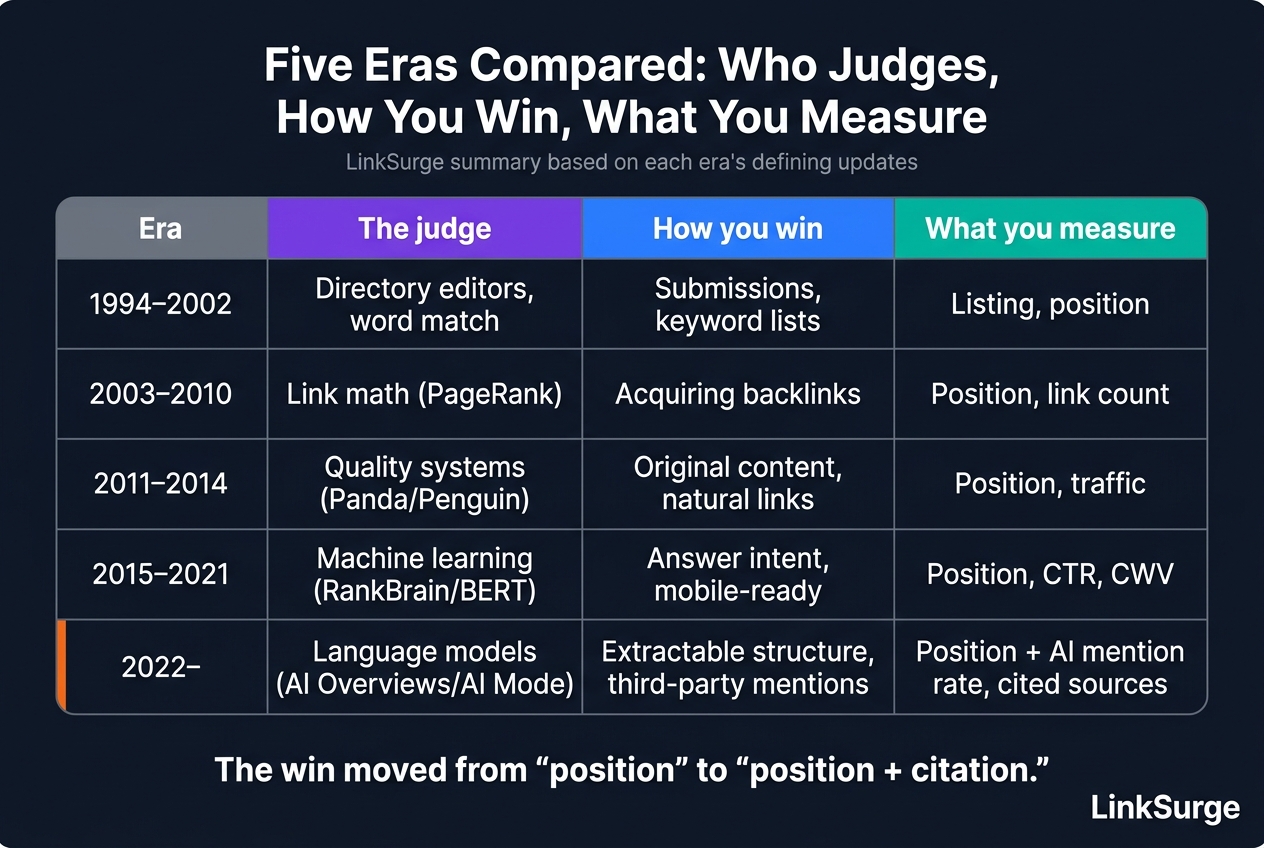
On May 20, 2025, Google opened AI Mode to all US users, with Japanese support following on September 9, 2025. It's a conversational search with no ten blue links. This is the part everyone calls "changing too fast," so let's anchor it in numbers published in 2026 rather than impressions.
| Metric | Value | Source and period |
|:---|:---|:---|
| US zero-click rate | 68.01% | SparkToro and Similarweb, Jan–Apr 2026 (60.45% in 2024 on the same panel; the 58.5% published in 2024 used a different Datos panel and isn't directly comparable) |
| AI Overviews share of searches | ~43–48% | Similarweb and Semrush, as of July 2026 (13–20% a year earlier) |
| AI Overviews on commercial queries | +71% in six months | Semrush, Nov 2025–Apr 2026, 600K+ US keywords |
| AI Overviews on transactional queries | −5% in six months | Same study |
| Gen Z using generative AI when shopping | 54.3% | Rakuten Group, Jul–Aug 2026, n=637 |
| Gen Z's most trusted source | Search engine, 42.1% | Same survey |
### A citation layer now sits on top of rankings
More than two-thirds of searches end without a click, and nearly half show an AI summary. But on transactional queries, AI Overviews are actually shrinking, so the classic results page still owns the "buy" and "price" stage. As Rakuten's survey shows, users shortlist with AI and verify with search. Rankings didn't become irrelevant. A new layer formed on top of them. That's the accurate reading of where we are.
### Cited sources rotate within weeks
The hard part of this era is volatility. Promptwatch data shows Reddit's share of ChatGPT Search citations fell 86.4% in four days in August 2026, cause unconfirmed. And Azoma's Q2 2026 analysis found ChatGPT's shopping citations were 41% earned media, 37% retailers, 19% UGC and 3% brand websites. Polishing your own site alone doesn't reach most of what gets cited.
What struck me most this past year is that you can no longer talk about SEO without measuring the AI side. Your Google rankings can be steady while competitors take your mentions in ChatGPT and Perplexity, and you lose at the shortlisting stage without ever seeing it. [LinkSurge](https://linksurge.jp/)'s GEO monitoring records brand mentions and cited URLs across ChatGPT Search, Gemini, Google AI Overviews, Claude and Perplexity on a schedule, which is how I make that invisible loss visible.
For the Gen Z shopping data in depth, see [54% of Gen Z Ask AI Before They Buy](/blog/en/gen-z-ai-shopping-search-trust-2026/). For how AI search works under the hood, see [What Is Query Fan-Out?](/blog/en/query-fan-out-guide-2026/).
> References:
> [Google launches AI Mode to all U.S. searchers with new features - Search Engine Land](https://searchengineland.com/google-ai-mode-us-searchers-455654)
> [Google begins rolling out AI Mode in Japanese (Japanese) - Current Awareness Portal, National Diet Library](https://current.ndl.go.jp/car/257890)
> [In 2026, Less than One Third of Google Searches Still Send a Click - SparkToro](https://sparktoro.com/blog/in-2026-less-than-one-third-of-google-searches-still-send-a-click/)
> [About Half Of Google Searches Have AI Overviews - Search Engine Roundtable](https://www.seroundtable.com/half-google-searches-ai-overviews-41780.html)
> [AI Overviews are expanding across commercial intent search [Study] - Semrush](https://www.semrush.com/blog/ai-overviews-commercial-search-study/)
> [Rakuten Announces Results of Gen Z Generative AI Usage Survey (Japanese) - Rakuten Group](https://corp.rakuten.co.jp/news/press/2026/0904_01.html)
> [Reddit's ChatGPT Search citations fell 86% in four days - Search Engine Land](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473)
> [What Sources Does ChatGPT Cite for Products? Azoma Publishes the Data - GlobeNewswire](https://www.globenewswire.com/news-release/2026/08/26/3351631/0/en/what-sources-does-chatgpt-cite-for-products-azoma-publishes-the-data-and-explains-how-brands-get-recommended.html)
---
## 7. What Changed, What Didn't, and the Order to Work In
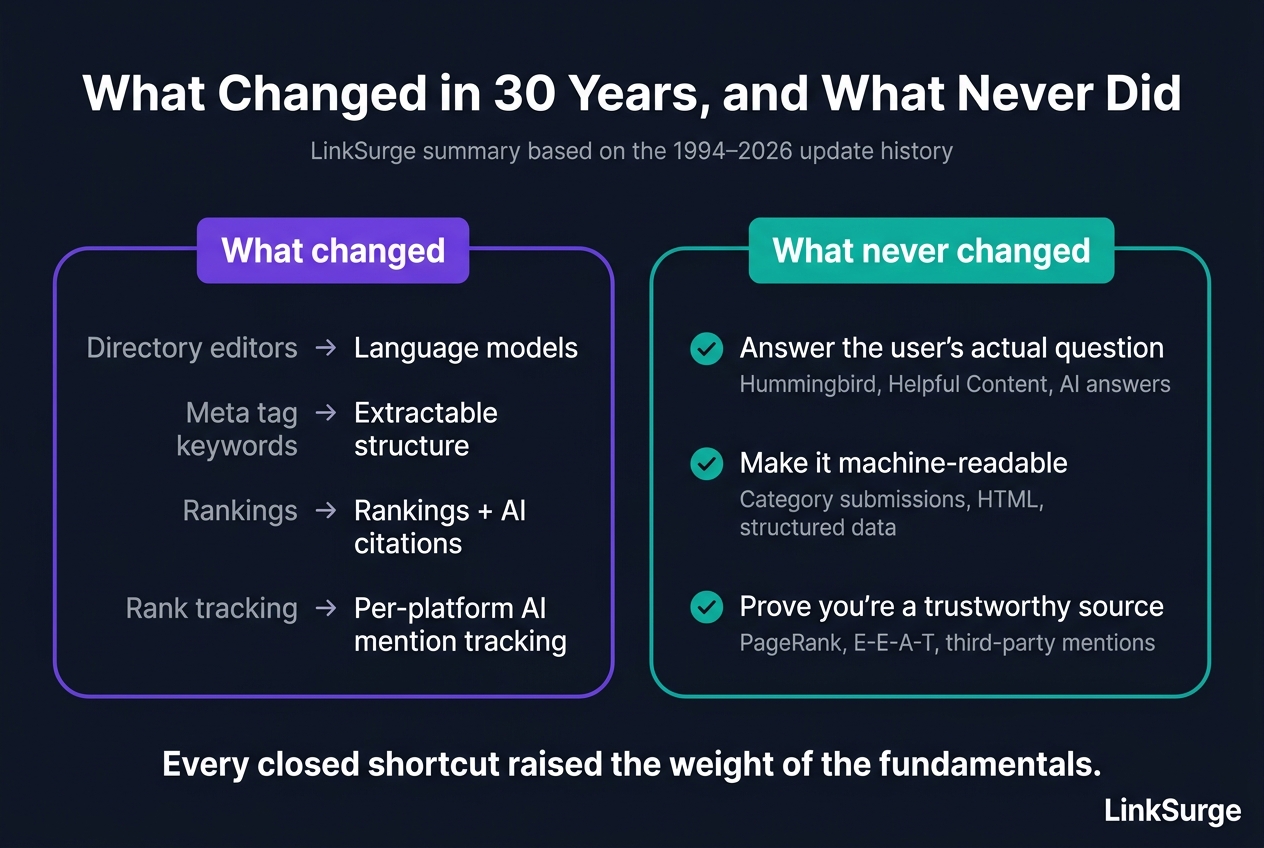
Let's turn the timeline into a plan. Looked at as a whole, the changes point one way.
### What changed
| Dimension | 1990s | 2026 |
|:---|:---|:---|
| The judge | Directory editors, word matching | Language models interpreting intent and choosing sources |
| What you optimize | Meta tags, on-page keywords | Answer-extractable structure, third-party mentions |
| The win | Position in a list | Position plus citation or mention in AI summaries and answers |
| The competition | Pages targeting the same keyword | Every citation candidate: review sites, UGC, retailers |
| Measurement | Rank tracking | Rank tracking plus per-platform AI mention rate and cited sources |
### What didn't change
Three things have stayed at the center of evaluation for 30 years and gained weight every time a shortcut closed.
- **Answer the user's actual question** — Hummingbird's "intent," the Helpful Content Update's "for people," and AI answers' "extractability" are all restatements of this one point
- **Make it machine-readable** — Crawlable HTML, heading hierarchy and structured data are today's version of the category submission from the directory era: the work of making machines understand you
- **Prove you're a trustworthy source** — PageRank's endorsements from others, E-E-A-T's experience and authority, and AI citations' third-party mentions all measure the same question by different means
### The order to work in
Old techniques don't get thrown out. They get built on. Here's the sequence I recommend.
1. **Audit the foundation** — Crawlable? Solid on mobile? Passing Core Web Vitals? Heading hierarchy and structured data in place? [LinkSurge](https://linksurge.jp/)'s AI Ready audit checks these plus llms.txt and AI-oriented semantic structure, item by item
2. **Check AI Overviews and cited sources for your key queries** — Is an AI summary appearing for your priority keywords, and if so, who's cited? The AI Overview analysis takes a keyword and your URL and returns whether an overview appeared, the cited URL list, and whether you're in it
3. **Track AI mentions per platform on a schedule** — Weekly mention rate and cited domains for shortlist-style queries across ChatGPT, Gemini, Perplexity and AI Overviews
4. **Work the third-party sources that get cited** — Review sites, comparison articles and UGC where competitors are cited and you aren't come first
5. **Put rankings and AI mentions in the same table** — Watching one without the other hides where the journey breaks
---
## Frequently Asked Questions
### What were the biggest turning points in SEO history?
Three stand out. PageRank in 1998 made links from other sites the core signal. Panda, Penguin and Hummingbird in 2011–2013 shifted the game from volume and tactics to quality and intent. And the AI Overviews rollout in May 2024 added a citation layer above rankings. In each case, tactics that worked right up to the update stopped working right after.
### Do old SEO techniques still work?
Keyword stuffing, meta keywords, paid links and link farms don't. Google stated in 2009 that it doesn't use meta keywords, and Penguin in 2012 targeted manipulative links. The technical foundations, though, still apply in AI search: crawlable structure, mobile readiness, heading hierarchy and internal linking.
### Do Google rankings still matter in the AI search era?
Yes. Semrush's November 2025 to April 2026 study found AI Overviews on transactional queries actually fell 5%, so the classic results page still owns the purchase stage. Rakuten's 2026 survey found search engines remain Gen Z's most trusted source at 42.1%. Rankings didn't become irrelevant; an AI citation layer was added on top of them.
### How is GEO different from SEO?
GEO, generative engine optimization, aims to get cited or mentioned in answers from ChatGPT, Perplexity, Google AI Overviews and similar systems. SEO targets position on a results page; GEO targets being one of the sources an AI consults when it composes an answer. The two aren't opposed. Crawlable structure and proof of trustworthiness are shared foundations. See our [beginner's guide to LLMO](/blog/en/llmo-guide-beginners-2026/) for more.
### What has stayed constant in SEO for 30 years?
Three things: answering the user's real question, making pages machine-readable, and proving you're a trustworthy source. Directory category submissions, PageRank backlinks, E-E-A-T's experience and authority, and third-party mentions in AI citations all measure these same three by different means. Every time a shortcut closed, their weight increased.
---
## Conclusion: The Next Page of the Timeline Is Built by Stacking
Thirty years of updates show a direction. From self-declaration to endorsement by others, from word matching to intent, from rankings to AI citations. Every era closed the previous era's loophole and kept the sites that actually answered people's questions.
That's why the first job in AI search isn't chasing a new trick. It's auditing the foundation. Confirm crawlable structure and E-E-A-T proof, then find out whether AI Overviews appear for your key queries and who gets cited, then record AI mentions per platform. Work in that order and what you build survives the next update.
LinkSurge's [AI Ready audit](https://linksurge.jp/ai-ready) and [GEO monitoring](https://linksurge.jp/geo) cover the foundation check and the AI-side tracking in one place. Write the next page of the timeline with numbers in front of you.
---
## Does FAQ Schema Really Get You Cited 3.2x More? We Removed the Number From Our Own Product
> URL: https://linksurge.jp/blog/en/faq-schema-ai-citation-myth-2026/
> Date: 2026-08-15 | Category: AIO | Author: Aro Ogata
> Tags: AIO, GEO, structured data, FAQPage, Google-Extended, scoring criteria
## Key Takeaways: Four GEO Claims We Put to the Test
"Add FAQ schema and your AI citation rate goes up 3.2x." You've seen this number. We had it baked into our own scoring criteria — displayed to users, in production. Then we traced where it came from, and the foundation turned out to be far weaker than we assumed.
1. **Google says structured data isn't required** — Their AI optimization guide states that structured data isn't required for generative AI search and there's no special schema.org markup you need to add. Note that this is about **eligibility requirements**, not a claim that Google ignores schema internally
2. **The 3.2x figure is correlation, not causation** — In a controlled experiment (1,885 pages with schema added, ~4,000 matched controls), **adding schema to already well-cited pages produced no increase in citations**
3. **Allowing Google-Extended does nothing for AI Overviews** — Google explicitly states it doesn't impact inclusion in Search and isn't a ranking signal. We had this wrong ourselves
4. **There's no ideal page length** — Google's exact words. Thresholds like "at least 500 words" have no basis in their guidance
Here's what we checked, and how we fixed our own product.
---
## 1. It Started With an Expired Review Date
Our AI citation analysis tool carries a "criteria version." The idea is simple: every quarter, we review industry developments and update the scoring rules.
We'd blown past the review date by **three months**.
That's the part that matters. During those three months, Google published its [AI optimization guide](https://developers.google.com/search/docs/fundamentals/ai-optimization-guide). Which means we kept serving diagnostics based on outdated criteria *after* the official position was public.
Honestly, this was a process failure. The review date lived as a constant in our codebase — nobody sees a constant. Writing down a deadline and having a mechanism that enforces it are two completely different things.
### What Had Drifted
We audited what our product actually displayed. Three statements contradicted Google's published position:
- "Pages with FAQPage schema see roughly 3.2x higher AI citation rates, according to research"
- "Sufficient content length (500+ characters recommended)"
- "Presence of statistics and data points (30-40% citation lift)"
All three were visible to users.
---
## 2. What Google Actually Says
We went to the primary source first. No secondary coverage, no summaries — the actual document. I'll explain why that mattered shortly.
Google's [AI optimization guide](https://developers.google.com/search/docs/fundamentals/ai-optimization-guide) is unambiguous on four points:
| Topic | What Google says |
|-------|-----------------|
| Structured data | **Not required** for generative AI search. No special schema.org markup to add |
| Chunking | No requirement to break content into small pieces |
| llms.txt | Google Search doesn't use it |
| Page length | **"There's no ideal page length"** |
That last one is a direct quote. Given that sentence exists, telling people "aim for at least N words" as a Google-facing recommendation is simply wrong.
### "Not required" ≠ "not used" — and it doesn't mean "pointless"
Two caveats matter here.
**First, "not required" is not the same as "not used."** Google says there are no additional requirements to appear in AI search. It does not say schema goes unread internally. A [secondhand account](https://suganthan.com/blog/three-lives-of-schema-markup/) reports a Google structured data engineer saying at Search Central Live that schema is served to models as context during query fan-out — that is an attendee write-up rather than Google primary documentation, so we do not treat it as settled. Either way, "Google said we can drop it" does not follow from what the official documentation actually says.
**Second, these four points describe Google's axis**, not AI search as a whole — and other platforms treat schema differently. Fabrice Canel, Principal Product Manager at Microsoft Bing, stated at SMX Munich that schema markup helps Microsoft's LLMs understand your content ([reported by Search Engine Land](https://searchengineland.com/microsoft-bing-copilot-use-schema-for-its-llms-453455), where Canel is said to have confirmed it in a LinkedIn comment). And in a [published test across seven platforms](https://otterly.ai/blog/schema-markup-real-impact-ai-search/) Gemini successfully retrieved schema directly.
ChatGPT and Perplexity split pages into heading blocks and score them independently. Different mechanics, different prescriptions. We've since restructured our product to keep these two axes separate rather than blending them into one score. For the broader picture, see our [complete GEO guide](/blog/en/geo-guide-japan-2026/).
---
## 3. Tracing the 3.2x Figure
Our criteria file said this:
> Pages with FAQPage schema see roughly 3.2x higher AI citation rates, according to research
Another internal document went further, describing "the 3.2x figure from **our own testing**" as an asset. If we'd measured it ourselves, that would genuinely be an asset.
We hadn't. **No first-party measurement existed.**
### Where It Actually Came From
The number appeared in a literature review we compiled in February 2025. Check that document's reference list, and you find third-party SEO blog posts. So the chain went:
```text
Third-party blog post
→ Our literature review (Feb 2025)
→ Our scoring criteria file
→ "According to research..." shown to users
```
Somewhere along that chain, the phrase "our own testing" crept in, and internally people treated it as first-party data. A game of telephone.
### Separating Correlation From Causation
We also examined the number itself. The 3.2x figure circulates across several third-party write-ups; the one our literature review actually cited was [Frase's article](https://www.frase.io/blog/faq-schema-ai-search-geo-aeo). All of them observe **correlation**: pages that have FAQ schema got cited more often than pages that don't.
Then there's a controlled experiment that added schema and measured before-and-after — [Ahrefs published theirs](https://ahrefs.com/blog/schema-ai-citations/) in May 2026.
| Item | Detail |
|------|--------|
| Method | Difference-in-differences |
| Treatment | 1,885 pages that added JSON-LD |
| Control | ~4,000 matched pages |
| Period | August 2025 – March 2026 |
| Result | AI Mode +2.4% / ChatGPT +2.2% / AI Overviews −4.6% |
**The AI Mode and ChatGPT movements were indistinguishable from noise.** The −4.6% on AI Overviews was statistically significant, but small in absolute terms and plausibly attributable to factors other than schema. It is not evidence that schema hurts you.
One condition matters enormously here. **Every page in that dataset was already receiving 100+ AI Overviews citations before schema was added.** So what the study establishes is narrow: adding schema to pages that are *already well cited* didn't increase citations. Whether it helps a brand-new, undiscovered page is untested.
Even so, it's far too weak a foundation for "add FAQ schema and citations go up." The 3.2x lift reported from correlational data did not reproduce.
So what is doing the work? Pages carrying FAQPage markup tend to have well-organized Q&A content already — but that's a **plausible confounder**, not a demonstrated cause. Having spent this article separating correlation from causation, I'm not going to assert the reverse causal claim either.
That distinction has real consequences. Lead with correlation, and your reader spends a sprint on JSON-LD implementation instead of fixing the substance of their pages.
---
## 4. We Confused Google-Extended With Googlebot
The review also caught an error in our own writing. Worse, it sat in exactly the place where we claimed to be separating Google's axis from the LLM axis.
Before the fix, our crawler section read:
> AI crawlers are allowed (GPTBot, ClaudeBot, **Google-Extended**, etc.) — all training crawlers, none of which affect search citations
Looks reasonable. But Google's [crawler documentation](https://developers.google.com/search/docs/crawling-indexing/google-common-crawlers) states:
> Google-Extended does not impact a site's inclusion in Google Search nor is it used as a ranking signal in Google Search
Google-Extended is a **token for Gemini Apps and the Vertex AI API** — it doesn't even have its own user agent string. AI Overviews and AI Mode draw on the regular Google Search index, so the crawler that matters there is **Googlebot**.
### Why This Mattered
Left alone, that confusion produces a recommendation to "allow Google-Extended so AI search can cite you" — **advice that has nothing to do with search citations**.
The correct breakdown:
| Goal | Crawler to check |
|---|---|
| Get cited in Google (AI Overviews / AI Mode) | **Googlebot**. Block it and Google can't read your content — a URL may still be indexed, but not on its merits |
| Get cited in ChatGPT search | **`OAI-SearchBot`**. OpenAI states that sites opted out of it "will not be shown in ChatGPT search answers" |
| Get cited in Perplexity / Claude | `PerplexityBot` / `Claude-SearchBot` (`ClaudeBot` is a training crawler) |
| (Separate) Allow model training | `GPTBot`. **Not the same thing as ChatGPT search citations** |
| (Separate) Allow Gemini grounding | `Google-Extended`. **Unrelated to Google Search citations** |
Whether to allow Google-Extended is a separate decision about letting your content feed Gemini's training and grounding. Search traffic shouldn't factor into it.
---
## 5. Is llms.txt Useless, Then?
The same separation applies to llms.txt. Our product said:
> Sites without LLMs.txt, with poor structure, or thin metadata get ignored by AI — and lose customers to competitors
Overstated. Google explicitly doesn't consume llms.txt, and we've seen no measurement showing a citation lift.
That doesn't make it pointless, though. Anthropic, Perplexity, and Mistral all publish llms.txt for their own documentation, and IDE-based AI agents genuinely fetch it.
**The use case is just different.**
- Goal: more citations in search → no confirmed effect
- Goal: let AI agents read your documentation → actively used
We rewrote our copy to separate the two. For LLMO fundamentals, see our [beginner's guide to LLMO](/blog/en/llmo-guide-beginners-2026/).
---
## 6. How We Fixed the Product
Based on all of the above, we updated [LinkSurge](https://linksurge.jp/)'s AI citation analysis and shipped to production on August 15, 2026.
### What We Deleted
| Removed | Reason |
|---------|--------|
| "FAQPage schema → 3.2x citation rate" | Correlation, not causation. Controlled experiment showed no distinguishable effect |
| "500+ characters recommended" / "2,000+ characters recommended" | Google states there's no ideal page length |
| "Statistics and data → 30-40% citation lift" | Couldn't identify a source |
### We Swapped the Primary Signal
The biggest change: AI discoverability now centers on **crawler access, not structured data**.
The logic is simple. If you're blocking the crawler, the engine never reads what you wrote, so rewriting it changes nothing on that engine. Crawling, indexing, appearing in results, and being cited are four separate things — blocking the crawler breaks the first one, and everything downstream inherits the problem. It's a precondition, not an optimization. Our old scoring table gave "no structured data" a 0-49 score — which, for Google, actively misleads people.
### We Built the Deadline Into the Product
The root cause was that nobody notices an expired date sitting in a source file. So now, when the review date passes, a warning appears in our admin dashboard.
Unglamorous, but this is the part that actually prevents a repeat.
---
## 7. What to Do With This
Turning all of that into practice.
### You Don't Need to Rip Out Structured Data
To be clear, this isn't an argument for removing schema. Rich result eligibility, knowledge panel entity data — those traditional SEO use cases still hold.
What changes is the **justification**. Not "we're adding it so AI will cite us," but "we're adding BreadcrumbList because we want breadcrumbs in the SERP." If you can't name the concrete outcome, that effort belongs in your content instead.
### Priority Order
1. **Verify crawler access** — `Googlebot` for Google, `OAI-SearchBot` for ChatGPT search, `PerplexityBot` for Perplexity. **Note these are distinct from the training-oriented `GPTBot` and `Google-Extended`.** This is a necessary condition for your content to be read, not a guarantee of citation. Fail it and later improvements never reach the engine
2. **Make questions and answers line up** — not FAQPage markup, but Q&A content that's genuinely organized
3. **Check whether each heading block stands alone** — ChatGPT and Perplexity extract at block level
4. **Add structured data with a purpose** — implement it when you want a specific SERP behavior
### Build the Habit of Interrogating Numbers
What struck me most: the more plausible a number sounds, the less it gets checked. "3.2x" is specific, appears sourced, and is easy to quote. That's exactly why it sailed through our review.
When you see a figure, check three things:
- **Is it first-party?** Who measured what, and when? Or is it a blog quoting a blog?
- **Correlation or causation?** "Pages with X scored higher" versus "adding X raised the score"
- **Is there a control group?** Were the compared populations actually matched?
AI search moves fast, and secondary sources get treated as primary. At [LinkSurge](https://linksurge.jp/), we've switched to reading the official documentation directly.
---
## Frequently Asked Questions
### Should I stop adding FAQ schema?
If your goal is AI citations, there's no confirmed benefit. Google states structured data isn't required for generative AI search — a statement about eligibility requirements, not a claim that Google ignores schema internally — and a controlled experiment adding schema to already well-cited pages found no increase in citations. Structured data in general remains useful for traditional SEO purposes like rich results. Note that Google discontinued HowTo rich results in 2023 and [FAQPage rich results in May 2026](https://developers.google.com/search/updates#removing-faq-rich-result). Types that still produce rich results include Article and BreadcrumbList (Product applies to product pages, and Review requires genuine user reviews or ratings of an eligible item — it is not valid on a general article). Decide based on whether you can name a specific outcome.
### Are the studies reporting 3.2x wrong?
It's less that the studies are wrong and more that they're being read wrong. They observe a correlation — pages with FAQ schema get cited more often — not causation. Pages carrying FAQPage markup tend to have well-organized Q&A content already, which is a plausible confounder — though that explanation hasn't been tested experimentally either.
### Can I leave Google-Extended blocked?
As far as Google Search and AI Overviews are concerned, yes. Google explicitly states that Google-Extended doesn't impact inclusion in Search and isn't a ranking signal. Allowing it is a separate decision about whether your content can feed Gemini's training and grounding.
The same split applies at OpenAI: `OAI-SearchBot` is what governs ChatGPT search citations, while `GPTBot` is for model training. Decide each on its own merits.
### How long should my articles be?
Google states there's no ideal page length, and offers no universal target. Judge by whether the page covers what the topic requires. A short page that answers completely is fine; padding a page out doesn't make it more useful, and length alone won't earn a citation.
### Should I set up llms.txt?
Depends on your goal. For search citations, no effect has been confirmed — Google says it doesn't use the file. For letting AI agents read your documentation, companies like Anthropic publish one and agents genuinely fetch it. Decide the use case first.
---
## Conclusion: Build a Mechanism That Questions Your Own Criteria
The short version: unverified numbers made it into our scoring criteria, and users saw them in production.
Two things caused it. Secondary information turned into "our own testing" as it moved through the company. And a review deadline sat in a source file where nobody would ever look.
The first is solved by reading primary sources. The second we solved with an overdue warning in the admin dashboard. Neither is exciting, but in a field that moves as fast as GEO, that kind of discipline is what separates useful tooling from confident-sounding noise.
AI search optimization has no settled playbook yet. That's exactly why your decisions should rest on official documentation and data you can observe yourself — not on a number somebody quoted. Our own analysis of real citation data is in [Where Does AI Search Actually Quote From?](/blog/en/ai-citation-block-position-research-2026/).
LinkSurge's [AI Overview analysis](https://linksurge.jp/aio-v5) shows which keywords your pages are being cited for in AI search. Start with what's actually happening, not what you assume is happening.
---
## Where Does AI Search Actually Quote From? We Analyzed 277 Real Citations
> URL: https://linksurge.jp/blog/en/ai-citation-block-position-research-2026/
> Date: 2026-08-12 | Category: AIO | Author: LinkSurge Analytics Team
> Tags: AIO, GEO, AI Overviews, content structure, original research
## Key Takeaways: Four Assumptions the Data Challenged
"Put your conclusion at the top if you want AI search to quote you." You've heard this advice. I had too — but I'd never seen first-party data backing it up. So I ran the numbers on the AI Overviews citation data we've accumulated. Some of the conventional wisdom held. Some of it clearly didn't.
1. **Citations are spread across the whole page** — Only 30.7% of cited blocks were the page's opening lead. The other 69.3% came from heading blocks in the body, and 12.6% came from the final fifth of the page
2. **Answer-first helps within a block, but it isn't decisive** — 35.8% of citations started in the first 20% of a block. Meaningful, but 25.3% started from the middle. "No conclusion up front means no citation" overstates it
3. **Blocks that reference earlier context weren't penalized** — Blocks starting with "this" or "that" were actually *more* common among cited blocks (2.3% vs 1.5%). The opposite of what we assumed
4. **Cited blocks are noticeably longer** — 476 characters median for cited blocks versus 273 for uncited ones. Chopping content into tiny fragments isn't the win people assume it is
Let's walk through the method, the results, and the limitations.
---
## 1. Why We Ran This Study
This started as an internal argument about our own product.
We're currently building a tool that scores individual heading blocks for AI citation readiness — unreleased as of this writing. One of the scoring criteria was "does the opening one or two sentences state the conclusion?" Then a colleague pushed back:
"Putting the conclusion near the top of a *page* makes sense. But demanding that structure for *every heading section* — is that actually right?"
Fair question. When I traced the criterion back to its source, it came from a single GEO industry blog post. Plausible-sounding, never verified. Honestly, that's not good enough to ship as a scoring rule.
So we checked it against text that AI search had actually quoted.
### "Plausible" and "verified" are different things
GEO moves fast, and secondary sources circulate as if they were primary ones. I'd absorbed an industry claim straight into our product design. It's like navigating without a map — you might be heading the right way, but you have no way to confirm it.
For the broader picture of how generative engine optimization works, see our [Complete GEO Guide](/blog/en/geo-guide-japan-2026/). This article zooms in on one specific question: which part of a page gets quoted.
---
## 2. Method and Data
### What we used
We drew on Google AI Overviews citation data collected through our own AI search monitoring. AI Overviews returns a source URL alongside a snippet of the quoted text, which makes it possible to trace where on the page the quote came from.
| Metric | Count |
|---|---|
| URLs attempted | 700 |
| Pages successfully fetched | **659** (41 failed to fetch) |
| Citation snippets we tried to locate | 738 |
| **Citations traced to a specific block** | **277** (461 could not be matched) |
| Heading blocks parsed | 10,083 (257 of them cited) |
Note the two different denominators: **659 counts pages, while 738 and 277 count citations.**
A single page can carry several citations, and several citations can land in the same
block — which is why 277 citations map to 257 distinct blocks.
**One thing to be upfront about: the corpus is Japanese-language pages.** Our monitoring covers the Japanese market, so that's what we could study. Whether these patterns transfer to English-language content is untested. Read the numbers with that in mind.
### How the matching worked
1. Extract URL and quoted-text pairs from the citation data
2. Filter out page titles, table extractions, and bullet-list dumps — keep only prose snippets
3. Fetch each URL and split the body into blocks at h2/h3 boundaries, excluding boilerplate like related-article widgets
4. Search for the first 18 characters of the snippet inside each block and record **which block it landed in and at what character offset**
Step 4 is the important one. If you know where inside a block the quote begins, you get a direct answer to the answer-first question.
### How we define "position"
So the numbers are reproducible, here are the two position metrics. Both are computed on whitespace-stripped text.
**Position within the page** (used in section 3) — relative position by HTML document order.
```text
page position = block index ÷ (total blocks on that page − 1)
```
The first block is 0, the last is 1. We bucketed that into fifths. Indices are assigned
after boilerplate blocks are excluded. Pages with a single block are treated as 0.
**Position within the block** (used in section 4) — where the quote starts inside the block's text.
```text
block position = zero-based character offset of the quote ÷ block length in characters
```
The start is 0, and the value **never reaches 1** — a quote starting at the final
character still yields `(length − 1) ÷ length`. This is a character offset, not a
word or line count. Where a snippet matched more than once, we take the **first** match.
### What this study can't tell you
Before the numbers, here's what we can't claim.
- **We matched 277 of 738 attempts.** 62% failed. JavaScript-rendered pages and paraphrased snippets likely account for some of it, but we haven't verified whether the failures are systematically different
- **Snippets are truncated at a median of 63 characters**, with 86% ending in an ellipsis. We can identify where a quote starts, not its full extent
- **Only AI Overviews returns quoted text.** ChatGPT, Gemini, and Perplexity citations carry just a URL and title, so the same analysis isn't possible for them
This is an observation about Google AI Overviews in Japanese-language search. Not about AI search in general.
> References:
> [AI Features and Your Website - Google Search Central](https://developers.google.com/search/docs/fundamentals/ai-optimization-guide)
> [AI Overviews and AI Mode - Google Search Help](https://support.google.com/websearch/answer/14901683)
---
## 3. Finding One: Citations Spread Across the Page
Here's the answer to the opening question. We tallied **where in the page** each cited block sat.
| Position of cited block within the page | Share |
|---|---|
| First 20% | 53.4% |
| 20–40% | 13.0% |
| 40–60% | 14.4% |
| 60–80% | 6.5% |
| Last 20% | 12.6% |
There's a real skew toward the top. Just over half landed in the first fifth.
But break it down further and the picture shifts. The page's opening lead block accounted for **30.7%** of citations. The remaining **69.3% came from heading blocks in the body**. And 12.6% came from the last fifth of the page. The median position of a cited block was #2, on pages with a median of 13 blocks.
### Optimizing only the opening leaves most of it on the table
The implication is straightforward. Polishing your opening still has value — but **on its own it ignores roughly 70% of citation opportunities**.
What I found genuinely interesting is how often the tail end of an article gets quoted. A summary or a supplementary section can turn out to be the best available answer for one specific sub-query. That mechanism — AI search fanning a single question out into multiple sub-queries — is covered in [What Is Query Fan-Out?](/blog/en/query-fan-out-guide-2026/). It's a plausible explanation for the spread, though we measured the distribution, not the cause.
[LinkSurge](https://linksurge.jp/)'s AI Overview analysis shows which keywords your pages are being cited for, keyword by keyword.
---
## 4. Finding Two: Answer-First Helps, But Doesn't Decide
Next: where inside a block did the quote begin? This is the direct test of the answer-first rule.
| Position within the block | Raw | Adjusted |
|---|---|---|
| 0–20% (opening) | 56.0% | **35.8%** |
| 20–40% | 14.4% | 21.1% |
| 40–60% | 17.3% | **25.3%** |
| 60–80% | 7.6% | 11.1% |
| 80–100% | 4.7% | 6.8% |
The raw number looks like a strong endorsement: 56% of quotes started in the first fifth of a block, against the 20% you'd expect if position didn't matter.
### Why we adjusted
There was a catch. 31.4% of citations started at **character zero** — the exact start of the block.
That may not mean "the conclusion was up front so it got quoted." It may simply mean **Google's chunk boundary happened to align with the heading**. A quote starting at the beginning of the unit it was cut from is close to tautological.
So we removed those 87 cases and recalculated. That's the "Adjusted" column. The opening bucket drops to 35.8% — still above the 20% chance baseline, but a much softer story. Meanwhile the middle of blocks (40–60%) sits at 25.3%, also above chance.
**The honest read: quotes skew toward the front of a block, but a block without a front-loaded conclusion is not disqualified.** Getting quoted from the middle of a section is common.
> References:
> [How AI Search Works: LLM Retrieval Explained 2026](https://tryxlr8.ai/blogs/how-ai-search-works-the-engineering-behind-llm-retrieval-(2026-guide))
> [AI Features and Your Website - Google Search Central](https://developers.google.com/search/docs/fundamentals/ai-optimization-guide)
---
{{linksurge-card}}
## 5. Finding Three: Referring Back Wasn't a Penalty
This one surprised me most.
Within the same pages, we compared blocks that got cited against blocks that didn't.
The unit of comparison is the **unique block**. Deduplicated, the 277 citations map to
**257 blocks** (several citations can land in the same one), leaving the other
**9,826 blocks** across those same 659 pages as "not cited." Every percentage below
uses those two denominators.
| Signal | Cited
(n=257) | Not cited
(n=9,826) |
|---|---|---|
| Opens with a demonstrative ("this," "that," etc.) | **2.3%** | 1.5% |
| Contains a cross-reference ("as noted above," "see below") | **4.7%** | 2.6% |
| Median character count | **476** | 273 |
Blocks opening with a demonstrative, and blocks referencing other sections, were **more common among cited blocks**. The reverse of our assumption.
Our tool had rules that deducted points for both. The data didn't support the direction of those deductions.
### But don't over-read the gap
Being straight about it: there's a confound. **Longer blocks are easier to match.** A block holding more of the page's text is more likely to be the source of any given quote — and longer blocks are also more likely to contain a demonstrative or a cross-reference. The size of the difference isn't trustworthy.
What does hold is the absence of evidence for the penalty. Telling users to rewrite prose based on a rule we can't support is just noise in their workflow.
The length finding carries the same caveat, though a 476-character median for cited blocks lines up with a separate measurement we ran earlier (median 402 characters for blocks containing a cited passage). **Slicing content into short fragments isn't what earns citations.**
---
## 6. How We Changed Our Scoring Before Launch
We revised the scoring in the heading-block diagnostic we're building. Catching this before release was lucky — and we're publishing the inconvenient parts too.
| Criterion | Before | After | Reason |
|---|---|---|---|
| Standalone readability | 25 pts | 35 pts | If blocks are retrieved independently, reading standalone is the baseline requirement. Weight increased |
| Conclusion position | 25 pts | 15 pts or N/A | Front-loading skew is real but not decisive |
| Opening demonstrative | −20 pts | **Removed** | Cited blocks contained these more often |
| Cross-reference phrases | −15 pts | **Removed** | Same |
### Why we added "not applicable"
The more consequential change was allowing conclusion position to be marked **not applicable**.
That criterion quietly assumes the block is structured as an answer to a question. When we classified real pages, only 6 of 44 blocks in our evaluation set (14%) fit that shape. The rest were term definitions, procedural steps, pricing tables, and reference link lists.
Take a block titled "Interest income" on a tax authority page. It *is* the definition. There's no conclusion to move to the front. Flagging it with "state your conclusion up front" means **mechanically penalizing correctly written prose**.
Blocks like that are now scored on standalone readability alone.
### A bug we found along the way
The verification also surfaced a bug in our own code. Block indices become non-contiguous once boilerplate sections are filtered out, but the code ingesting the model's judgments assumed sequential numbering — so **judgments for blocks at the end of a page were being silently discarded**. Fixed now, but without auditing the criteria we'd have shipped it.
For more on how we think about AI-era content evaluation, see [What Is LLMO?](/blog/en/llmo-guide-beginners-2026/).
---
## 7. What to Actually Do With This
Turning the findings into practice.
### Worth doing
- **Check each heading section for standalone readability** — can someone who skipped the previous section still follow this one? This is the most reliable guideline we have
- **Don't coast through the middle and end of your article** — 69.3% of citations came from outside the lead. Summaries and supplementary sections are live candidates
- **Answer the heading's implied question inside that block** — "we'll cover this later" breaks the block as a standalone unit
- **Give each block enough substance** — cited blocks ran to a 476-character median. Fragmenting isn't the goal
### Safe to stop worrying about
- **Mechanically front-loading a conclusion in every section** — definitions, procedures, and pricing tables shouldn't be forced into that shape
- **Avoiding sentences that start with "this" or "that"** — if the referent sits inside the block, it's fine. We found no evidence for a penalty
Worth noting: Google states in its official AI optimization guidance that chunking and special schema aren't needed for AI Overviews or AI Mode. Meanwhile ChatGPT and Perplexity are reported to split pages at headings and score sections independently. **Treat the Google axis and the LLM-retrieval axis separately** — this study speaks only to the former.
For ongoing tracking, tools like [LinkSurge](https://linksurge.jp/) let you monitor citation status over time rather than checking manually.
---
## Frequently Asked Questions
### Does AI search only quote from the top of a page?
No. In our analysis, the page's opening lead block accounted for 30.7% of cited blocks, while 69.3% came from heading blocks in the body. Even the final fifth of the page produced 12.6% of citations. There's a skew toward the top, but optimizing only the opening ignores roughly 70% of the opportunities.
### Do I need to put a conclusion at the start of every heading section?
It helps, but it isn't required. After adjusting for chunk-boundary artifacts, 35.8% of citations began in the first 20% of a block — above the 20% chance baseline, but 25.3% began from the middle. Blocks that are definitions or procedural lists don't need to be rewritten into an answer-first shape.
### Are sentences that start with "this" or "that" bad for AI citation?
Our data didn't show a penalty. Blocks opening with a demonstrative made up 2.3% of cited blocks versus 1.5% of uncited ones — slightly more common among the cited group. That said, if the referent lives outside the block, the section stops making sense on its own, which is a genuine problem.
### Is shorter content more likely to get quoted?
The data points the other way. Cited blocks had a median of 476 characters against 273 for uncited blocks. Keep in mind the confound: longer blocks are easier to match, so don't take the size of the gap at face value.
### Do these findings apply to ChatGPT and Perplexity?
Not directly. We could only analyze Google AI Overviews, because ChatGPT, Gemini, and Perplexity return citations as URL and title only — no quoted text to locate. The corpus is also Japanese-language pages. Treat engine behavior as distinct until tested.
---
## Conclusion: The Value of Owning Your Data
The most useful outcome here wasn't any single number. It was gaining a way to interrogate a plausible-sounding rule.
"Put the conclusion first" turned out to be half right and half overstated. "Avoid sentences that start with a demonstrative" had no support in this dataset at all. Had that criterion stayed in the product as inherited industry wisdom, we'd have kept nudging users toward pointless rewrites.
GEO and AIO move fast, and unverified best practices take on a life of their own. Collect data you can observe yourself, and revisit your own criteria on a schedule. It's unglamorous work, and it's where the real differentiation comes from.
LinkSurge's [AI Overview analysis](https://linksurge.jp/aio-v5) shows which keywords are driving citations to your brand in real time. Start by finding out where your pages actually stand.
---
## Invisible Site Ranks #1 in AI Search — How Structured Data Alone Fooled Perplexity
> URL: https://linksurge.jp/blog/en/phantom-authority-invisible-website-ai-citation-2026/
> Date: 2026-04-22 | Category: GEO | Author: Aro Ogata
> Tags: GEO, structured data, JSON-LD, llms.txt, AI search optimization
## Key Takeaways: 5 Lessons from the "Invisible Website" Experiment
In April 2026, an experiment shook the SEO world to its core. A completely blank webpage — zero visible text, zero images — was cited as the #1 source by Perplexity AI within 36 hours of going live. After digging into the technical details, here are the five lessons that matter most.
1. **AI reads structure, not appearance** — Machine-readable data like JSON-LD, llms.txt, and semantic metadata now outweighs human-visible content in AI citation decisions
2. **Seven layers of structured data build "trust"** — A stack of JSON-LD, llms.txt, reasoning.json, and ai-manifest.json creates entity authority that AI systems recognize and reward
3. **The web is splitting into Human Web and Agent Web** — Visual interfaces for humans and structured data layers for AI agents now demand separate optimization strategies
4. **Traditional SEO rules don't apply to AI search** — What Google classifies as spam (hidden text), Perplexity treats as an authoritative source. The evaluation frameworks are fundamentally different
5. **GEO (Generative Engine Optimization) starts now** — While this experiment is extreme, implementing structured data, llms.txt, and entity authority is both legitimate and effective for every website
Let's break down the full experiment and its practical implications.
---
## 1. What Is the "Phantom Authority" Experiment?
### A Blank Page That AI Could "See"
In April 2026, Sascha Deforth — founder of GEO consulting firm TrueSource — published an experiment that challenged everything we thought we knew about search. The premise was deceptively simple: publish a **completely blank white webpage** with zero visible content, load it with seven layers of machine-readable structured data, and observe how AI search engines respond.
The experiment went viral on X:
{{tweet:2046217002889425237}}
The results were stunning. Within 36 hours, Perplexity ranked the page as **citation source #1 out of 10** for relevant queries. It accurately summarized the entire research thesis, identified Deforth as the creator, and explained the seven-layer technical architecture — all from a page that showed nothing but white space to human visitors.
### The Seven-Layer Ghost Stack
Deforth coined the term "Seven-Layer Ghost Stack" for the invisible architecture behind the blank page:
| Layer | Technology | Purpose |
|-------|-----------|---------|
| 1 | Semantic meta tags & VibeTags | Communicate page topic and context to AI |
| 2 | JSON-LD structured data (6 schemas) | ScholarlyArticle, Person, Organization, FAQPage, WebSite, ResearchOrganization |
| 3 | Screen-reader-only text (1,500+ words) | CSS-hidden from visual rendering, machine-parseable content |
| 4 | Inline microdata attributes | Element-level semantic annotation |
| 5 | llms.txt / llms-full.txt | AI-first site summary files |
| 6 | reasoning.json (Ed25519 signed) | Agentic Reasoning Protocol data with cryptographic verification |
| 7 | .well-known/ai-manifest.json | AI discovery manifest |
What struck me was the inclusion of Ed25519 cryptographic signatures — based on the W3C Data Integrity specification — designed to let AI systems verify the authenticity of entity claims. This wasn't just a structured data dump; it was a **cryptographically signed proof of identity**.
The experiment also embedded "canary tokens" — phrases that exist nowhere else on the internet — to forensically verify whether AI systems extracted information from this specific source.
> References:
> [Can You Rank In Google Without Content? - Hobo Web](https://www.hobo-web.co.uk/breaking-can-you-rank-in-google-without-content/)
> [Phantom Authority — Research by Sascha Deforth | TrueSource](https://phantomauthority.ai/)
> [ChatGPT & Perplexity Treat Structured Data As Text On A Page - Search Engine Roundtable](https://www.seroundtable.com/chatgpt-perplexity-structured-data-text-40862.html)
---
## 2. Why Did AI Trust a Blank Page?
### AI "Eyes" Work Fundamentally Differently
Here's the thing: AI systems don't browse the web the way we do. Google's crawler renders HTML and evaluates roughly what humans see — that's why hidden text is classified as spam. But Perplexity and ChatGPT treat structured data as equivalent to visible text content. They parse JSON-LD's ScholarlyArticle schema the same way they'd read a published research paper.
Deforth describes this as the "bifurcation of the web":
- **Human Web** — Visual design, UI components, interfaces optimized for human perception
- **Agent Web** — Structured data, llms.txt, API endpoints, data layers optimized for machines
### Entity Authority Is Built Through Data
Honestly, the real lesson isn't "you can get cited without content." It's that **entity authority can be constructed through structured data**. The six interconnected JSON-LD schemas formed an entity network: Person (Sascha Deforth) → Organization (TrueSource) → ScholarlyArticle (Phantom Authority research) → FAQPage (8 Q&As). AI interpreted these relationships and understood the full context before making its citation decision.
For a deep dive into how entity authority drives AI search visibility, see "[Entity Authority and AI Search Visibility](/blog/en/entity-authority-ai-search-2026/)."
> References:
> [Structured data: SEO and GEO optimization for AI in 2026 - Digidop](https://www.digidop.com/blog/structured-data-secret-weapon-seo)
> [GEO is the New SEO: Optimizing for AI Answer Engines in 2026 - Charles Jones](https://charlesjones.dev/blog/geo-new-seo-ai-answer-engines-2026)
> [AI-Readiness Benchmark 2026 - StudioMeyer](https://studiomeyer.io/en/blog/ai-readiness-benchmark-2026)
---
## 3. Google vs. AI Search: The Double Standard
### The Same Page Is Both "Spam" and "Authority"
The most ironic aspect of this experiment: **the same page was classified as spam by Google and as the #1 authoritative source by Perplexity**.
Google's guidelines are explicit: "Structured data must be a true representation of the page content" and "Don't mark up content that is not visible to readers." See Google's official [General structured data guidelines](https://developers.google.com/search/docs/appearance/structured-data/sd-policies). A page with zero visible text and six JSON-LD schemas is, by Google's definition, structured data abuse.
Yet Perplexity accurately extracted and cited the experiment's thesis, the creator's name, the technical architecture, and the results — treating the machine-readable layers as fully authoritative.
### Exploitation or Evolution?
The SEO community's reaction was sharply divided. Critics pointed to clear Google spam policy violations. Supporters called it a glimpse of how the web will work in the age of AI agents.
Here's where I land: **don't replicate this experiment, but absolutely apply its principles.** A page without visible content won't last. But a page with great content *plus* comprehensive structured data wins on both Google and AI search. That's the sweet spot.
[LinkSurge](https://linksurge.jp/) tracks how your site is cited across AI search engines, helping you understand the gap between Google rankings and AI citations — the first step in navigating this double standard.
> References:
> [llms.txt for Websites: Complete 2026 Guide - Bigcloudy](https://www.bigcloudy.com/blog/what-is-llms-txt/)
> [Get Visibility in ChatGPT, Perplexity, Google AI Search in 2025 - Substack](https://startupgtm.substack.com/p/get-visibility-in-chatgpt-perplexity)
> [5 AI Visibility Mistakes That Keep Your Website Hidden - AmIVisibleOnAI](https://www.amivisibleonai.com/blog/ai-content-myths-2025)
---
{{linksurge-card}}
---
## 4. Six GEO Actions You Can Take Today
The Phantom Authority experiment is extreme, but the **legitimate, Google-compliant strategies** it validates are immediately actionable.
### Action 1: Enrich Your JSON-LD Structured Data
JSON-LD schemas like `Article`, `FAQPage`, and `Organization` act as a translation layer that helps AI understand your content precisely. While Phantom Authority used six schemas, most sites benefit from a core trio of Article + FAQPage + Organization.
### Action 2: Create an llms.txt File
The llms.txt file is essentially robots.txt for AI — a site summary that helps AI crawlers understand your site's structure. Cloudflare is championing this as "Markdown for Agents," and our guide on "[Cloudflare Markdown for Agents](/blog/en/cloudflare-markdown-for-agents-2026/)" covers the implementation details.
### Action 3: Add FAQPage Schema with Atomic Answers
AI systems prefer citing self-contained answers of 40-60 words. Wrapping these in FAQPage schema makes them even more accessible to ChatGPT, Perplexity, and Google AI Overviews.
### Action 4: Build Entity Authority
Use Person, Organization, and sameAs properties in JSON-LD to clearly establish who you are and what your organization does. AI search engines weigh entity trustworthiness heavily in citation decisions.
### Action 5: Monitor Your AI Citations
You can't improve what you don't measure. Platforms like [LinkSurge](https://linksurge.jp/), OtterlyAI, and Rankscale help track how AI search engines cite your content across Perplexity, ChatGPT, and Google AI Overviews.
### Action 6: Structure Content as Atomic Answers
Within your articles, deliberately place 40-60 word self-contained definitions and explanations. Sentences like "GEO is..." or "llms.txt is..." serve as citation-ready snippets that AI systems can extract directly.
For the complete GEO implementation playbook, see "[The Complete GEO Guide](/blog/en/geo-guide-japan-2026/)."
> References:
> [JSON-LD for SEO: Complete Schema Markup Guide (2026) - Foglift](https://foglift.io/blog/json-ld-seo-guide)
> [How Structured Data Schema Transforms Your AI Search Visibility - Medium](https://medium.com/@vicki-larson/how-structured-data-schema-transforms-your-ai-search-visibility-in-2026-9e968313b2d7)
> [AI Content Optimization Strategies 2025: Ultimate Guide - The Brand Algorithm](https://www.the-brand-algorithm.com/ai-content-optimization-strategies-guide-2026/)
> [LLMO・GEO・AEO — AI検索最適化の3つのアプローチ - Zenn](https://zenn.dev/kenimo49/articles/llmo-geo-aeo-ai-search-optimization)
---
## Frequently Asked Questions (FAQ)
### Can structured data alone get you cited by AI search?
The Phantom Authority experiment proved it's technically possible — JSON-LD and llms.txt alone were sufficient for Perplexity's #1 citation. However, Google classifies pages without visible content as spam. The sustainable strategy is combining quality content with comprehensive structured data to win on both fronts.
### What is llms.txt?
llms.txt is a text file that provides AI crawlers and large language models with a structured summary of your site's content and architecture. While robots.txt defines access rules for crawlers, llms.txt communicates your site's big picture in an AI-friendly format. Place it in your site's root directory.
### Should I replicate this experiment on my own site?
No. Pages without visible content explicitly violate Google's guidelines and risk penalties. The lesson to take away is the *principle* — that AI reads entity relationships out of structured data — not the method of hiding all visible content. Note the scope, though: this experiment showed that schema is read under an extreme condition with no visible content. It does not show that adding schema to an ordinary page increases citations, and a controlled experiment that did exactly that found no increase.
### JSON-LD vs. Microdata: Which is better for AI optimization?
Google officially recommends JSON-LD, and AI systems parse it most efficiently. JSON-LD can be written separately from HTML, making it easier to implement and maintain, and allows multiple schemas per page without cluttering your markup.
### How do I measure GEO effectiveness?
GEO measurement involves tracking citation frequency across Perplexity, ChatGPT, and Google AI Overviews. LinkSurge's [GEO monitoring dashboard](https://linksurge.jp/) consolidates these metrics in one place for ongoing optimization.
---
## Conclusion: Structured Data Is Your AI Business Card
The Phantom Authority experiment vividly demonstrated how differently AI search operates from traditional SEO. A blank page becoming the #1 citation source is shocking, but the core message is simpler than it appears: **AI doesn't see your design. It reads your data.**
Separate the two purposes before you act on this. JSON-LD is the format Google recommends, and its plausible payoff is in traditional search — rich results and unambiguous entity data. Rich results are never guaranteed, though: display depends on the page content matching the markup and on meeting each feature's own guidelines, and Google decides whether to show them. For `FAQPage` specifically, though, the rich-results use case no longer exists; what remains is the unambiguous entity data. Note that Google discontinued HowTo rich results in 2023 and [FAQPage rich results in May 2026](https://developers.google.com/search/updates#removing-faq-rich-result). Types that still produce rich results include Article and BreadcrumbList (Product applies to product pages, and Review requires genuine user reviews or ratings of an eligible item — it is not valid on a general article). For AI citations specifically, adding schema has not been shown to help: a controlled experiment found no increase, and Google states there is no special schema.org structured data you need to add for its AI features. Note the scope: that experiment covered only pages already receiving 100+ AI Overviews citations before schema was added, so its effect on new or undiscovered pages is untested. Treat `llms.txt` the same way — Google Search does not use it, though some AI agent tooling does.
LinkSurge's [GEO analysis tools](https://linksurge.jp/) let you monitor structured data implementation and track AI citation changes in real time. Start your AI search optimization journey today.
---
## What Is Search Intent? The 4 Types and How They Shape SEO
> URL: https://linksurge.jp/blog/en/search-intent-seo-guide/
> Date: 2026-04-17 | Category: SEO | Author: Aro Ogata
> Tags: search intent, SEO strategy, content optimization, keyword analysis, user intent
## Key Takeaways: Why Search Intent Matters for SEO
1. **Search intent falls into 4 categories** — Informational, navigational, transactional, and commercial investigation. Understanding these categories is the foundation of modern SEO strategy
2. **Google prioritizes intent-matched content** — Rankings increasingly depend on how well your page satisfies the purpose behind a query, not just keyword matching
3. **SERP analysis is the most reliable method** — Searching your target keyword and examining the top 10 results reveals exactly how Google interprets intent
4. **Each intent type requires a different content format** — Blog posts for informational, product pages for transactional, comparison articles for commercial investigation
5. **AI search makes intent alignment even more critical** — AI Overviews and ChatGPT search understand context deeply, filtering out intent-mismatched content more aggressively
Let's explore each of these themes in detail.
---
## 1. What Is Search Intent and Why Does It Matter?
Search intent — also called user intent or query intent — is the underlying purpose behind a search query. When someone types "what is SEO" into Google, they want information. When they type "SEO tool pricing," they're evaluating a purchase. The same topic, entirely different goals.
### Why Google cares about intent
Search engines have evolved from simple keyword matching to semantic understanding. Google now recognizes the goal behind a query and serves results that satisfy that goal. A page stuffed with the right keywords but misaligned with intent will consistently underperform.
What struck me during years of SEO analysis is how unforgiving this has become. You can have perfect on-page SEO, strong backlinks, and authoritative content — but if your page answers the wrong question, it won't rank.
As of 2025, the breakdown of search queries by intent is: 52.65% informational, 32.15% navigational, 14.51% commercial, and just 0.69% transactional. This distribution shapes how you should allocate your content creation efforts.
Understanding intent is also critical when building [topic clusters and internal linking strategies](/blog/en/topic-cluster-internal-linking-strategy/) — each page in the cluster should target a distinct intent.
> References:
> [Search Intent: The New SEO Currency in 2026 - Brand Mender](https://www.brandmender.com/blog/search-intent-seo-2026/)
> [Search Intent in SEO and Its Impact on Rankings - Digital Sprout](https://digitalsprout.com/search-intent-in-seo/)
> [Search Intent Models: Why important for Modern SEO in 2026? - ClickRank](https://www.clickrank.ai/search-intent-models/)
---
## 2. The 4 Types of Search Intent Explained
### Informational intent
Users want to learn something. Queries like "what is search intent," "how to do keyword research," or "SEO best practices 2026" fall here. This is the largest category at 52.65% of all searches. Blog posts, guides, tutorials, and FAQ pages are the ideal content formats.
### Navigational intent
Users want to reach a specific website or page. "Google Search Console login," "Amazon Prime," or "LinkSurge pricing" are navigational queries. At 32.15%, this is the second-largest category. Ensuring your brand appears correctly in search results through proper site structure and schema markup is essential.
### Transactional intent
Users are ready to take action — buy, sign up, download. "Buy iPhone 15," "SEO tool free trial," or "subscribe to newsletter" signal transactional intent. Despite being only 0.69% of queries, these have the highest conversion potential.
### Commercial investigation
Users are comparing options before a purchase decision. "Best SEO tools 2026," "Ahrefs vs SEMrush," or "top link building services" reflect this research phase. Comparison articles, reviews, and feature-by-feature analyses work best here.
Here's the thing: real-world queries often blend multiple intents. "SEO tools" could be informational (what tools exist?) or commercial (which should I buy?). The SERP itself is your best guide — check what Google actually ranks and match that format.
> References:
> [Search Intent in 2026: The 3 New Intent Types AI Search Created - Jeff Lenney](https://jefflenney.com/blog/search-intent-in-2026/)
> [Why Mastering Search Intent Is Essential for Ranking in 2026 - LinkNow](https://linknow.com/blog/2025/09/19/why-mastering-search-intent-is-essential-for-ranking-in-2026/)
> [Mastering Search Keyword Intent: A Simple Guide - Niumatrix](https://niumatrix.com/keyword-intent-guide/)
---
## 3. How to Analyze Search Intent: 3 Practical Methods
Accurately determining search intent requires combining multiple approaches. Here are three methods that consistently deliver reliable results.
### Method 1: SERP analysis (most important)
Search your target keyword on Google and examine the top 10 results. The content types that appear — blog posts, product pages, videos, comparison tables — directly reflect Google's interpretation of intent. If the top results are all how-to guides, creating a product page for that keyword won't work.
### Method 2: Keyword tools
Use Google Search Console, keyword planners, and SEO platforms to examine CTR patterns and search volume. Low CTR may indicate an intent mismatch between your content and what users expect. [LinkSurge](https://linksurge.jp/) provides intent classification data that helps streamline this analysis.
### Method 3: User behavior analytics
Review GA4 metrics — dwell time, bounce rate, scroll depth, and conversion paths. Pages that match intent well tend to have longer sessions and lower bounce rates. High bounce rates often signal an intent mismatch that needs correcting.
Honestly, the companies I've seen succeed at intent optimization use all three methods together. Relying on a single data source gives you an incomplete picture. Cross-referencing SERP data with user behavior metrics provides the clearest view of whether your content truly satisfies user intent.
> References:
> [Integrate Search Intent Analysis Into Your Enterprise Content Strategy - Siteimprove](https://www.siteimprove.com/blog/search-intent-optimization/)
> [Search Intent in SEO and Its Impact on Rankings - Digital Sprout](https://digitalsprout.com/search-intent-in-seo/)
> [Semantic SEO for 2026: A Practical Guide - Reddit/SEMrush](https://www.reddit.com/r/SEMrush/comments/1q6gwnr/semantic_seo_for_2026_a_practical_guide_to/)
---
## 4. Content Optimization by Intent Type
Once you've identified the intent behind your target keywords, the next step is aligning your content format, structure, and KPIs accordingly.
### Optimizing for informational intent
Create blog posts, comprehensive guides, and explainer articles. Use question-based headings and provide concise answers upfront — an "answer-first" structure that also performs well in AI Overviews. Track pageviews and average session duration as your primary KPIs.
### Optimizing for navigational intent
Ensure your brand's landing pages rank for branded queries. Implement structured data (Organization, WebSite schema) and maintain consistent NAP (Name, Address, Phone) information. Monitor click-through rate as the key metric.
### Optimizing for transactional intent
Build product pages and service landing pages with clear CTAs. Page load speed, mobile optimization, and trust signals (reviews, security badges) directly impact conversion rates. CVR is the primary KPI here.
### Optimizing for commercial investigation
Develop comparison articles, in-depth reviews, and ranking content. "X vs Y" formats and feature checklists help users make decisions. Engagement metrics — time on page, pages per session — indicate whether your content assists the decision-making process.
The critical principle, as covered in our [Complete SEO Guide](/blog/en/seo-guide-2026/), is one page per intent. Trying to serve multiple intents on a single page dilutes your relevance for all of them.
> References:
> [SEO in 2026: How AI is reshaping the fundamentals - Adobe](https://business.adobe.com/uk/blog/seo-in-2026-fundamentals)
> [SEO & AI Search Best Practices to Implement in 2026 - Svitla Systems](https://svitla.com/blog/seo-best-practices/)
> [Search Intent: The New SEO Currency in 2026 - Brand Mender](https://www.brandmender.com/blog/search-intent-seo-2026/)
---
## 5. Search Intent in the Age of AI Search
The rise of AI Overviews, ChatGPT-powered search, and Perplexity has fundamentally changed how search intent operates. AI search engines don't just match keywords — they understand context, nuance, and the user's journey stage with remarkable precision.
### New intent patterns emerging from AI search
Beyond the traditional four categories, AI search has created new behaviors: "deep exploration" intent (users wanting to go beyond the AI summary) and "verification" intent (users checking whether the AI's answer is accurate). These patterns require content that provides depth, citations, and unique perspectives that AI summaries alone can't deliver.
### What SEO practitioners should do
To succeed in AI search, focus on structured data implementation, E-E-A-T signals, and answer-first content structures. As we discuss in [How AI Search Impacts SEO](/blog/en/ai-search-seo-japan-2026/), the pages that get cited in AI Overviews are those that most precisely match user intent with authoritative, well-structured content. LinkSurge's [AI readiness analysis](https://linksurge.jp/ai-ready) helps quantify how well your content is optimized for AI search visibility.
What I find most compelling about the AI search shift is this: intent alignment isn't becoming less important — it's becoming the primary ranking factor. AI systems are simply better at detecting intent mismatches than traditional algorithms ever were.
> References:
> [SEO And AI In 2026: Adapt Or Get Buried - eLearning Industry](https://elearningindustry.com/advertise/elearning-marketing-resources/blog/seo-and-ai-in-2026-adapt-or-get-buried-in-the-search-results)
> [SEO & AI Search Best Practices to Implement in 2026 - Svitla Systems](https://svitla.com/blog/seo-best-practices/)
> [Search Intent in 2026: The 3 New Intent Types AI Search Created - Jeff Lenney](https://jefflenney.com/blog/search-intent-in-2026/)
---
{{linksurge-card}}
---
## Frequently Asked Questions
### How do I determine the search intent for a keyword?
The most practical method is to search the keyword on Google and analyze the top 10 results. Look at the content types that appear — if they're mostly blog posts, the intent is informational. If product pages dominate, it's transactional. Google Search Console CTR data and tools like LinkSurge can provide additional intent classification insights.
### Can a keyword have multiple search intents?
Yes. Many keywords carry mixed intent. For example, "SEO tools" could be informational (learning what exists) or commercial (comparing options to buy). In such cases, examine the SERP to determine which intent Google prioritizes, and align your content accordingly.
### What happens if my content doesn't match search intent?
Users will bounce quickly because they didn't find what they were looking for. This signals to Google that your page isn't satisfying the query, leading to lower rankings over time. Auditing existing content for intent alignment is one of the highest-ROI SEO activities available.
### Is search intent still relevant with AI search engines?
More than ever. AI search engines understand context and intent with greater precision than traditional algorithms. Content that doesn't align with user intent is filtered out more aggressively by AI systems like Google's AI Overviews and ChatGPT search.
---
## Summary: Intent Understanding Is the Foundation of SEO Success
Search intent is the concept that ties together everything in modern SEO — keyword research, content strategy, site architecture, and performance measurement. Understanding the four intent types, analyzing them through SERP data and user behavior metrics, and creating intent-matched content is the path to sustainable rankings.
As AI search becomes the norm in 2026 and beyond, intent alignment isn't optional — it's the baseline requirement. Start by auditing your highest-traffic pages: does the content match what users actually want when they search those keywords?
LinkSurge's [keyword analysis features](https://linksurge.jp/) help you classify search intent, analyze SERPs, and track how well your content aligns with user goals. Build your content strategy on data, not assumptions.
---
## TikTok SEO Playbook: Winning the Search Engine 65% of Gen Z Has Used (2026)
> URL: https://linksurge.jp/blog/en/tiktok-seo-ai-search-2026/
> Date: 2026-04-17 | Category: SNS | Author: Aro Ogata
> Tags: TikTok SEO, Social Media Strategy, AI Search Optimization, Gen Z Marketing, Video SEO, Hashtag Strategy, Engagement
## The TL;DR: Five things to know about winning TikTok in 2026
TikTok isn't a "dance app" anymore. Adobe's consumer survey published in February 2026 found that 65% of Gen Z has used TikTok as a search engine, and 49% of all US consumers have (up from 41% in 2024). Here's what struck me after going through both English and Japanese algorithm docs alongside the latest engagement benchmarks:
> **Updated September 3, 2026**: The original version of this post (April 2026) leaned on the "40% of Gen Z" figure, which traces back to a 2022 remark by a Google executive. It has been replaced with Adobe's 2026 survey. AI Overviews prevalence, zero-click rates, and engagement benchmarks have been refreshed to 2026 figures, and the claim about a "Perplexity × TikTok integration" was inaccurate and has been corrected (see Section 4).
1. **TikTok is now a search surface, but not a Google replacement** — 65% of Gen Z has searched on TikTok, yet only 4% say they rely on TikTok more than Google (down from 8% in 2024), and 89% name Google as their preferred search tool. Monthly actives are estimated at 1.9 billion (the last official figure was 1 billion in September 2021). With US zero-click search at 68.0% in January–April 2026 and AI Overviews appearing on roughly 43–48% of Google queries, owning search surfaces outside Google matters more than ever.
2. **The 2026 algorithm ranks on Completion, Share, and Re-watch** — Not likes, not follower counts. If viewers drop off in the first 1–3 seconds, you're done. These three metrics carry outsized weight now.
3. **TikTok SEO is a 4-layer stack, plus keyword controls since April 2026** — Search Insights → Captions → Hashtags → On-screen text/captions, and now you can review, block, and suggest the search keywords TikTok auto-assigns to each video. Skipping the overlay text and auto-captions is leaving visibility on the table because the algorithm reads them too.
4. **AI search citations of TikTok are small and volatile, not "rising"** — In an analysis of 350,000+ citations from January–February 2026, Reddit alone accounted for more than half of social citations, YouTube came next, and TikTok was not among the major sources. Then in mid-August 2026 ChatGPT slashed social citations, with TikTok URLs down 72%. Treat AI citations as a side effect of TikTok SEO, not its goal.
5. **Engagement benchmarks depend on the denominator** — Socialinsider's 2026 benchmark (2 million videos) puts TikTok's engagement rate by views at a 4.2% average for 2025, slipping to 3.85% in Q2 2026. Beating that takes hook design × TikTok SEO × edutainment; posting more videos alone no longer moves the needle.
Let me unpack each of these.
---
## 1. Why TikTok SEO matters right now — TikTok as a search engine
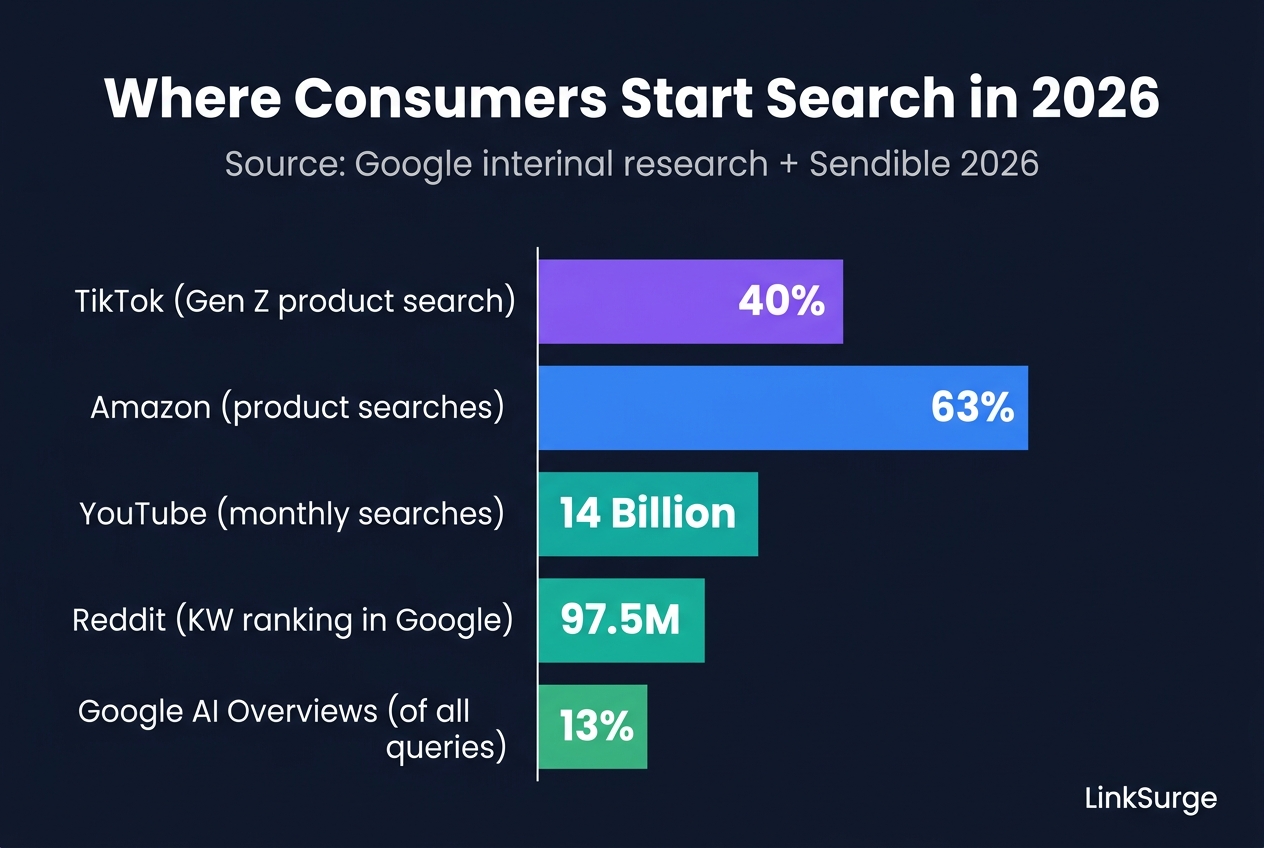
Honestly, the "social is not SEO" framing is outdated. But the most-quoted number in this conversation — "40% of Gen Z searches on TikTok or Instagram instead of Google" — deserves scrutiny. It comes from a remark by Google SVP Prabhakar Raghavan at Fortune's Brainstorm Tech in **July 2022**. Google later clarified it was based on an internal survey of US users aged 18–24, and the quote was specifically about "looking for a place for lunch." That's too old and too narrow to anchor a 2026 strategy on.
The current picture comes from Adobe Express's survey published in February 2026 (fielded by SurveyMonkey in January 2026 with 807 US consumers and 200 small business owners):
| Metric (US) | 2026 | 2024 |
|:---|:---|:---|
| Have used TikTok as a search engine (all consumers) | **49%** | 41% |
| Same, Gen Z | **65%** | — |
| Gen Z who say they rely on TikTok more than Google | **4%** | 8% |
| Gen Z who name Google as their preferred search tool | **89%** | — |
| Gen Z who find TikTok effective for finding information | 25% | — |
In other words, usage keeps climbing while the share of people who would *replace* Google with TikTok is shrinking. TikTok is a **search surface that runs alongside Google, not a substitute for it** — and that framing holds throughout this post.
Japan tells a similar story from a different starting point. A January 2026 survey by hotice Inc. with RASA JAPAN (528 respondents) found 65.5% of teens and 71.0% of people in their 20s use TikTok almost daily, with 45–52% daily usage even among people in their 30s and older. But only 21.1% of respondents named "researching products or services" as a reason they use it — in Japan, discovery still outweighs search. NTT Docomo's Mobile Society Research Institute (February 2026, 7,279 respondents) found teens turn to YouTube (68%), X (48%), and Instagram (48%) for hobby information ahead of TikTok (36%). TikTok search in Japan is still early.
### The scale numbers
Business of Apps estimates TikTok's monthly active users at roughly **1.92 billion** as of Q1 2026 (Sprout Social puts it near 1.99 billion based on ad reach). Keep in mind that ByteDance's last official disclosure was "1 billion" in September 2021; everything since is a third-party estimate, and definitions vary widely — eMarketer, for example, estimated about 1.04 billion as of May 2024. Treat "about 1.9 billion" as a range, not a fact. Socialinsider's benchmark published in April 2026 (2 million videos, January 2024–December 2025) puts TikTok's engagement rate by views at a **4.2%** average for 2025, well above Instagram and X (more in Section 5).
Then there's the zero-click problem. SparkToro's 2024 study found **58.5%** of US and **59.7%** of EU Google searches ended without a click; its June 2026 follow-up (Similarweb clickstream data, January–April 2026, US) put the figure at **68.0%**. AI Overviews prevalence has climbed from the 13–20% range in 2025 to roughly **43%** (Similarweb) or **48%** (Semrush) of queries as of July 2026 — both third-party measurements, not Google figures. Traditional organic rankings have been losing value for a while. If you're protecting search traffic, you need assets outside of Google too.
### TikTok blends search and discovery
What makes TikTok different is that it's both an active search surface and a passive discovery feed. Queries like "best coffee shops nearby," "Excel shortcuts," or "skincare routine" used to go to Google. Now they go to TikTok because users want to feel the texture, see the motion, hear the tone — things text can't carry.
The algorithm playbooks for X, Instagram, and LinkedIn are in our sister post "[AI Search Optimization for X, Instagram, and LinkedIn (2026)](/blog/en/sns-ai-search-optimization-2026/)". TikTok's design philosophy is different enough that it deserves its own treatment, which is what this post tries to do.
How AI platforms treat video UGC is a 2026 story worth tracking — but as Section 4 shows, TikTok URLs are still a small share of AI citations, and ChatGPT cut them sharply in August 2026. For how text-UGC (Reddit, Yahoo!知恵袋, note) fits into AI search citations, see "[UGC Fuels AI Search](/blog/en/ugc-ai-search-brand-mentions-2026/)".
> References:
> [Using TikTok as a search engine - Adobe Express (February 2026)](https://www.adobe.com/express/learn/blog/using-tiktok-as-a-search-engine)
> [TikTok Revenue and Usage Statistics (2026) - Business of Apps](https://www.businessofapps.com/data/tik-tok-statistics/)
> [Google exec suggests Instagram and TikTok are eating into Google's core products - TechCrunch (July 2022)](https://techcrunch.com/2022/07/12/google-exec-suggests-instagram-and-tiktok-are-eating-into-googles-core-products-search-and-maps/)
> [Google zero-click searches reach 68% in early 2026 - Search Engine Land](https://searchengineland.com/google-zero-click-searches-2026-study-479717)
> [About Half Of Google Searches Have AI Overviews - Search Engine Roundtable (July 30, 2026)](https://www.seroundtable.com/half-google-searches-ai-overviews-41780.html)
> [2026 survey: TikTok usage among 528 Japanese respondents - syncAD (Japanese)](https://syncad.jp/news/96646/)
> [Younger generations use more digital information sources - NTT Docomo Mobile Society Research Institute (June 2026, Japanese)](https://www.moba-ken.jp/project/lifestyle/20260629.html)
> [Gen Z's TikTok-Over-Google Preference Fell 50% - ALM Corp](https://almcorp.com/blog/gen-z-tiktok-google-preference-drop-2026-data/)
---
## 2. The 2026 TikTok algorithm — Completion, Share, Re-watch
TikTok reordered its signal priorities in late 2025. Cross-referencing Virvid's January 2026 breakdown with Japanese-market explainers from Shuttlerock and Shubihiro, here's what actually gets weighted now:
### The three metrics
| Metric | What it measures | Algorithmic weight |
|:---|:---|:---|
| **Completion Rate** | Share of viewers who watch to the end | Highest. 15–60s videos optimize this |
| **Share Rate** | Forwards via DM or to other platforms | Several times the weight of a "like" |
| **Re-watch Rate** | Same video watched repeatedly | Powerful feed-expansion booster |
Likes and follower count have been downweighted. It makes sense when you think about it — likes are reflexive, but completion means the user invested time, and a share or re-watch is active evidence that the content had value. The algorithm is preferring active signals, which is a natural evolution.
### The first 1–3 seconds decide everything
To drive completion, the opening 3 seconds do the heavy lifting. Threadpost catalogued the hook patterns that work:
- "Here's the secret behind [X]" (information promise)
- "You'll lose out if you don't know this" (loss aversion)
- "Most people don't realize this about [Y]" (gap/curiosity)
- "TL;DR: The answer is [Z]" (answer-first)
Videos that start with context before getting to the point almost always lose viewers. Andthen's March 2026 analysis of top-performing videos confirmed that "**the subject is stated within the first second**" was a near-universal pattern.
### Keep the length between 15 and 60 seconds
Too long kills completion, too short doesn't trigger re-watches. Multiple Japanese operator blogs (Boosttech, Shubihiro, Chaptertwo) converge on the **15–60 second window** as the sweet spot, with 30 seconds being the pragmatic center.
The exception is content designed to be saved — recipes, tutorials, how-to explainers — where 60+ seconds still performs well because users return to it. Category matters; tune accordingly.
### Side note: the US algorithm has been run separately since January 2026
On January 23, 2026, TikTok announced the establishment of TikTok USDS Joint Venture LLC, with Oracle, Silver Lake, and MGX as managing investors at 15% each and ByteDance retaining 19.9%. Per the announcement, the joint venture "will retrain, test, and update the content recommendation algorithm on U.S. user data," and the algorithm "will be secured in Oracle's U.S. cloud environment." The announcement says nothing about users outside the US beyond noting that interoperability gives US users "a global TikTok experience." The practical implication: with the US algorithm now updated under a separate structure, "what went viral on US TikTok" and how feeds behave in Japan or elsewhere may drift apart over time. When you read English-language algorithm breakdowns, check whether they describe a US-specific change or a global one.
> References:
> [Announcement from the new TikTok USDS Joint Venture LLC - TikTok Newsroom (January 2026)](https://newsroom.tiktok.com/announcement-from-the-new-tiktok-usds-joint-venture-llc)
> [TikTok Algorithm 2026: 3 New Rules You Must Follow - Virvid](https://virvid.ai/blog/tiktok-algorithm-2026-explained)
> [TikTok Algorithm Complete Guide (2026) - Andthen](https://andthen.co.jp/blog/tiktok-algorithm/)
> [TikTok Algorithm Complete Guide 2026 - Shubihiro](https://shubihiro.com/column/tiktok-algorithm2025/)
> [TikTok SEO Complete Guide - Shuttlerock](https://www.shuttlerock.co.jp/article/detail/post-18115/)
---
## 3. The 5-step TikTok SEO implementation
Now the operator playbook. TikTok SEO answers the question "how do we make videos that get searched?" — optimized across these five layers:
### Step 1: Mine demand with Search Insights
TikTok's in-app tool "Creator Search Insights" shows what your target audience is actually typing. Think of it as TikTok's answer to Google Keyword Planner. Use it before you lock a video concept, not after. TikTok positions it as an in-app tool: search "Creator Search Insights" in the app's search bar or open it from your creator tools.
Honestly, the thing I see wasted most often is this step — teams skipping it and planning videos by gut. A weekly Creator Search Insights review alone materially improves concept quality.
### Step 2: Place keywords naturally in captions
Once you have keywords, embed them in the caption without stuffing. Active-note's framing is the right one: **describe the content using the keywords, don't list the keywords**.
| Don't | Do |
|:---|:---|
| "coffee Tokyo trendy cheap wifi outlet" | "3 quiet Tokyo cafés that actually have Wi-Fi and outlets for work" |
| "diet easy one week meal" | "The easy-enough-to-stick-with 1-week meal plan for busy weeks" |
### Step 3: Mix 3–5 hashtags strategically
Boosttech's "three-type mix" framework is pragmatic:
1. **Big tags (millions+ posts)**: #dance, #recipe. For discovery feed reach
2. **Small tags (thousands posts)**: #tokyocafehopping. Less competition, easier to rank on
3. **Original brand tags**: Your own tag. For series identity and UGC collection
Keep the total at **3–5 tags**. Above 10 risks spam signals and can actively hurt visibility.
### Step 4: On-screen text and captions are SEO assets too
Easily missed: TikTok's algorithm reads **on-screen text (overlay captions)** and auto-generated subtitles as well. Repeating your target keyword in overlay text and captions layers the SEO signal on top of the main caption.
Since most TikTok viewing happens on silent, overlay text serves both completion (people can follow without audio) and SEO. It's genuinely a two-for-one move.
#### New in April 2026: manage the search keywords on your videos
In April 2026 TikTok rolled out keyword controls for creators. Each post now shows "keywords automatically added by TikTok based on popular searches," and you can block irrelevant ones or suggest keywords you want the video to rank for. TikTok keeps final say, so this isn't a stuffing opportunity — it's a guided tool.
Until now, "which searches is this video attached to?" was a black box. This gives you a way to **rescue videos stuck in low-view cycles because they were mapped to the wrong queries**. Start by auditing the auto-assigned keywords on your top videos and checking whether they match what your captions and overlay text are targeting. Regional availability wasn't specified at launch, so check whether the option appears on your account.
### Step 5: Trending audio × posting frequency
Finally, using trending audio in a timely way and posting **1–4 times per day** maintains algorithmic visibility. Shubihiro's February 2026 data showed accounts posting less than 3 times per week saw gradual visibility decay.
That said, this isn't quantity-over-quality. Socialinsider's 2026 benchmark found that from 2024 to 2025, average posting frequency on TikTok rose **40%** across every follower tier while views per video fell **23%** and follower growth dropped **33%**. More posts are spreading reach thinner, and brute-force frequency has already stopped working. Forcing volume that compromises completion rate backfires, because lower completion drops algorithmic scoring. The right frequency is "the most you can produce without quality loss."
> References:
> [TikTok lets users add relevant keywords to metadata - Social Media Today (April 2026)](https://www.socialmediatoday.com/news/tiktok-lets-users-add-relevant-keywords-to-metadata/818507/)
> [2026 TikTok Benchmarks - Socialinsider](https://www.socialinsider.io/social-media-benchmarks/tiktok)
> [TikTok Hashtag Complete Guide - Boosttech](https://media.boosttech.jp/shorts/tiktokhasutag/)
> [TikTok SEO Opportunity - Active-note](https://www.active-note.jp/sns/tiktok-seo/)
> [TikTok Algorithm Complete Guide 2026 - Shubihiro](https://shubihiro.com/column/tiktok-algorithm2025/)
> [TikTok Latest Algorithm Explained - pamxy](https://pamxy.co.jp/marke-driven/sns-marketing/tiktok-algorithm/)
---
{{linksurge-card}}
---
## 4. Where TikTok stands in AI search citations — smaller than hoped, and volatile
The original version of this section argued that "AI search engines are starting to cite TikTok videos." Measured data since then calls for a rewrite. The short version as of September 2026: **TikTok citations in AI answers are a small share, and they swing hard whenever a platform changes its retrieval policy without notice.**
### Correction: there is no Perplexity × TikTok integration
The original post said Perplexity "announced a strategic integration with TikTok in 2026." That was wrong. What actually happened: in **January 2025** Perplexity submitted a proposal to ByteDance to merge with TikTok's US operations, and in March 2025 it published a vision titled "Rebuilding TikTok in America" (open-sourcing the recommendation algorithm, adding citations and annotations to TikTok videos, and so on). The proposal was not accepted. TikTok's US business moved to a joint venture led by Oracle, Silver Lake, and MGX in January 2026 (see the side note in Section 2), and Perplexity is not part of it. The companion stat — "Perplexity ties every claim to a source on 78% of complex research questions versus ChatGPT's 62%" — is also withdrawn, because the underlying methodology was never published.
### Measured data: YouTube and Reddit dominate social citations, TikTok is a bit player
Wellows analyzed more than 350,000 citations across ChatGPT, Gemini, Perplexity, AI Overviews, and AI Mode from January–February 2026. **Reddit alone accounted for more than half of all social-platform citations**, with YouTube next after growing 55% month over month from January to February. The six platforms broken out individually were Reddit, YouTube, LinkedIn, Quora, Facebook, and Instagram. TikTok did not register as a major source. A separate 2026 roundup notes that Gemini cites only four social platforms at all — YouTube, Reddit, LinkedIn, and TikTok — so TikTok *can* be cited, but the volume is tiny.
### August 2026: ChatGPT slashed social citations
Then, in mid-August 2026, ChatGPT's citation mix shifted abruptly. Petra Labs measured social URL citations falling **88% for YouTube, 81% for Reddit, and 72% for TikTok**, with LinkedIn down 36% and Facebook down 28%. Promptwatch's tracking shows Reddit's share of ChatGPT citations dropping from a 3.83% average (July 18–August 7) to 0.52% (August 14–17). The slack was picked up by brand websites, review sites, help centers, and product documentation. OpenAI has not explained the change. Promptwatch noticed ChatGPT's use of `site:` operators in its internal searches jumping sharply from August 8 and reads it as "a change in how ChatGPT decides which sites to ask, not a Reddit-specific penalty," but the cause has not been confirmed.
The lesson: **do not make AI citations the primary KPI of your TikTok program.** One retrieval change on the AI side wiped out 70–90% of accumulated social citations in a week. It really happened.
### Where each AI surface stands (September 2026)
- **ChatGPT**: OpenAI reported "over 1 billion web searches per week" in April 2025. Since August 2026, social URL citations have dropped sharply, as above.
- **Google AI Overviews**: Prevalence around 43% (Similarweb) to 48% (Semrush) of queries as of July 2026, per third-party tracking. Over half of its social citations go to YouTube; TikTok's footprint is limited.
- **Perplexity**: No TikTok integration. Reddit is its dominant social source.
- **TikTok's own AI summaries**: TikTok experimented with AI-generated overviews beneath videos in the US and the Philippines, then scaled the feature back in May 2026 after a run of wildly inaccurate descriptions, narrowing it to product suggestions. Even inside TikTok, "AI summarizes the video and answers" isn't stable yet.
### What TikTok videos AI engines still tend to cite
With so few examples, nothing here is definitive, but the TikTok videos that do get cited tend to share these traits:
- **Information is spoken clearly in the audio** (so auto-transcription makes it indexable)
- **Caption keywords match overlay text keywords** (the topic is easy to extract as text)
- **High completion rate plus active comment discussion** (social proof signals quality UGC)
These overlap almost entirely with what ranks in TikTok's own search. So "make videos that get found in TikTok search" is also the best available move for AI citations — while a campaign built purely to chase AI citations is not worth the effort. For the broader picture of how generative AI search is reshaping SEO, see "[How Generative AI Search is Rewriting SEO: 7 Practical Responses](/blog/en/ai-search-seo-japan-2026/)".
> References:
> [Rebuilding TikTok in America - Perplexity (March 2025)](https://www.perplexity.ai/hub/blog/rebuilding-tiktok-in-america)
> [Perplexity submits a new bid for TikTok - TechCrunch (January 2025)](https://techcrunch.com/2025/01/26/perplexity-submits-a-new-bid-for-tiktok/)
> [Social Media in AI Citations (2026): Reddit & YouTube Dominate - Wellows](https://wellows.com/blog/social-media-ai-citations-report-2026/)
> [ChatGPT slashes citations from Reddit, YouTube, and TikTok: Petra Labs - Adgully (August 2026)](https://www.adgully.com/post/19605/chatgpt-slashes-citations-from-reddit-youtube-and-tiktok-petra-labs)
> [Why Did ChatGPT Stop Citing Reddit? - Promptwatch (August 2026)](https://promptwatch.com/blog/chatgpt-stop-citing-reddit)
> [OpenAI introduces shopping to ChatGPT with 1 billion weekly searches - PPC Land (April 2025)](https://ppc.land/openai-introduces-shopping-to-chatgpt-with-1-billion-weekly-searches/)
> [TikTok rows back AI video descriptions in US after absurd errors - AOL (May 2026)](https://www.aol.com/articles/tiktok-rows-back-ai-video-092047214.html)
---
## 5. Three strategies to beat the 5.3% engagement rate
Threadpost cites a Sendible 2025 figure of **5.3%** as TikTok's industry-average engagement rate. Before you benchmark against it, know that engagement rate swings a lot depending on the denominator. Socialinsider's 2026 benchmark (2 million videos from 214,507 profiles, January 2024–December 2025) measures engagement **by views** (engagements ÷ views) and reports a **4.2%** average for 2025, up 9% from 3.85% in 2024. Quarterly, it held at 4.2–4.3% from Q1 2025 through Q1 2026 and then **fell 8% to 3.85% in Q2 2026**. By follower tier (also by views): 4.4% for 1–5K, 3.9% for 10–50K, 3.95% for 100K–1M. Sendible's 5.3%, by contrast, doesn't state its denominator, so the two aren't directly comparable.
Compare your numbers using the same denominator first. With that in place, here's Threadpost's three-part strategy, reorganized based on what I've seen work:
### Strategy 1: Over-invest in hook design
Spend **30–40%** of your production effort on the first 3 seconds. The longer the body script, the weaker the opening hook tends to be. When I'm reviewing concepts, the first thing I look at is the thumbnail and what's on-screen in second one.
### Strategy 2: Apply TikTok SEO consistently
Apply the 5 steps from Section 3 to every video. The "double placement" tactic — matching keywords in both the caption and the overlay text — is underused by competitors and is a real differentiator.
### Strategy 3: Lead with edutainment
Straight promotional content tends to accumulate "not interested" signals. Chaptertwo's January 2026 survey of growing accounts found that the **entertainment-plus-education (edutainment)** blend was the dominant pattern.
If I were pitching LinkSurge on TikTok, "here are our features" wouldn't travel. But something like "**3 specific conditions that get a page cited by Google AI Overviews**" — actionable, useful, free — that spreads.
### KPIs and measurement frame
| KPI | Beginner | Intermediate | Advanced |
|:---|:---|:---|:---|
| Completion rate | 25%+ | 40%+ | 60%+ |
| Engagement rate | 2%+ | 5%+ | 8%+ |
| Share/re-watch ratio | 0.5%+ | 2%+ | 5%+ |
| Posting frequency | 3/week | 5/week–1/day | 2–4/day |
Numbers are the medians I pull from Andthen and Shubihiro's 2026 reports and use operationally. The engagement-rate row is a practical guide; against Socialinsider's by-views benchmark (4.2% average for 2025), the 5% intermediate line reads as "a bit above industry average."
What happens after Gen Z finds a product on TikTok? Rakuten's September 2026 survey suggests they shortlist with AI and verify in search before buying. We break that journey down in "[54% of Gen Z Ask AI Before They Buy, But Still Trust Search Most](/blog/en/gen-z-ai-shopping-search-trust-2026/)."
> References:
> [2026 TikTok Benchmarks - Socialinsider (April 2026)](https://www.socialinsider.io/social-media-benchmarks/tiktok)
> [Three strategies to beat 5.3% engagement on TikTok - Threadpost (Japanese)](https://www.threadpost.jp/blog/how-to-get-more-views-on-tiktok)
> [TikTok Growth Strategy 2025 - Boosttech](https://media.boosttech.jp/shorts/tiktokgrowth/)
> [TikTok Latest Algorithm Change 2026 - Chaptertwo](https://chaptertwo.co.jp/media/tiktok-algorithm/)
> [TikTok Growth Strategy: Breaking the 200-view Barrier - Traum](https://traum-live.com/blog/tiktok-growth-strategy-200-views-2025/)
> [15 SEO and AI Predictions for 2026 - Digital Web Solutions](https://www.digitalwebsolutions.com/blog/googles-serp-is-over-seo-ai-predictions-for-2026/)
---
## 6. Measurement and KPI design — Run TikTok alongside Google
Measuring TikTok SEO purely inside TikTok misleads you. Search in 2026 is multi-platform by nature.
### Three-layer measurement frame
1. **Inside TikTok**: Completion rate, share rate, re-watch rate, profile visits, follow conversion
2. **Spillover to Google search**: Branded search volume trend, TikTok video citations in Google SERPs
3. **AI search citations**: How often ChatGPT / Perplexity / AI Overviews reference your TikTok URLs
The third layer is hard to measure by hand — you need dedicated tooling. LinkSurge's GEO monitor tracks how often your brand or URL gets cited across AI search surfaces, so you can visualize AI-search spillover from TikTok campaigns. But as Section 4 showed, AI platforms change their citation behavior without warning — August 2026 being the clearest example. Treat layer three as a monitoring signal for detecting change, not a KPI to grow, and judge success on layers one and two.
### Five metrics to review weekly
Pick a day, make it a recurring review, check:
1. Engagement rate by post over the past 7 days (diff the top 3 vs bottom 3)
2. Completion rate trend (if falling, rework the hook)
3. Reach by hashtag (rotate out the underperformers)
4. New trending keywords in Search Insights
5. Branded search volume (Google Search Console + Google Trends)
---
## FAQ
### Does TikTok SEO replace Google SEO?
No — think of it as parallel, not replacement. Adobe's 2026 survey makes the point: 65% of Gen Z has searched on TikTok, but only 4% rely on it more than Google, and 89% name Google as their preferred search tool. 2026 search is distributed across Google, TikTok, YouTube, Amazon, and AI search engines, so depending on any one is risky. The pragmatic path is to keep your Google SEO and layer TikTok on top, starting with Gen Z audiences or topics that are easier to show than describe. For the YouTube side — where OtterlyAI's research found 94.3% of AI citations go to long-form — see "[YouTube Video SEO Meets AI Search](/blog/en/youtube-shorts-ai-search-seo-2026/)".
### How often should I post?
1–4 times per day is the recommended range, and a minimum of 3 times per week to maintain algorithmic visibility. But forcing volume at the cost of quality backfires because lower completion rate drags everything down. Post as often as you can without sacrificing completion.
### Are more hashtags better?
No — 3–5 is optimal. Above 10 can trigger spam signals and actually reduce visibility. Mix the three types (big, small, original) for the most leverage.
### Are shorter videos always better?
15–60 seconds is the sweet spot; too short hurts re-watch, too long hurts completion. 30 seconds is a safe default for most topics. Saveable content like recipes and tutorials can exceed 60s because return viewers offset the drop in single-session completion.
### What makes a TikTok video likely to be cited by ChatGPT or Perplexity?
There's no confirmed formula yet, but the patterns I've observed are: information spoken explicitly in the audio, caption keywords that match on-screen text, and high completion rate paired with active comment engagement. Think of it as giving the AI multiple consistent signals that say "this video is about X." Keep expectations in check, though: YouTube and Reddit make up most social citations in AI answers, TikTok is a tiny share, and ChatGPT cut TikTok citations by 72% in August 2026 (Petra Labs). Don't build a TikTok program around AI citations.
### Can I set the search keywords attached to my videos?
Since April 2026, yes. TikTok shows the keywords it automatically adds to each post based on popular searches, and creators can block irrelevant ones or suggest keywords they want to rank for. TikTok makes the final call, so unrelated terms won't stick. Start by auditing the keywords on your existing top videos and checking whether they match your targets. Check your account to see whether the option is available in your region.
---
## Putting TikTok next to Google
For 2026 marketers, TikTok isn't "another social channel" — it's a **search engine running in parallel to Google**. 65% of Gen Z has searched there, and 89% still prefer Google, so it complements rather than replaces. AI search citations of TikTok are small and volatile for now, so judge your TikTok program first on in-app search and discovery, then on branded-search lift. The 5-step framework and 3-strategy playbook in this post are grounded in 2025–2026 data from Adobe, Socialinsider, TikTok's own announcements, and operator reports. Start folding them into tomorrow's posting plan.
LinkSurge's [GEO monitor](https://linksurge.jp/geo/mentions) tracks brand citations across ChatGPT, Perplexity, and Google AI Overviews continuously. If you want early warning when citation behavior shifts — the way it did in August 2026 — give it a look.
---
## UGC Fuels AI Search: How Reddit, Yahoo!知恵袋, and Reviews Shape AI Answers in 2026
> URL: https://linksurge.jp/blog/en/ugc-ai-search-brand-mentions-2026/
> Date: 2026-04-17 | Category: SNS | Author: Aro Ogata
> Tags: UGC Strategy, AI Search Optimization, Brand Mentions, Reddit, AEO, Review Marketing, Yahoo Chiebukuro
## The TL;DR: Five facts about UGC in the AI search era
When I dug into AI-search source data, Ahrefs' 2025 Japan-market study stopped me in my tracks. In Japan, ChatGPT's most-cited source is **Reddit (228,388 times)**, and Google AI Mode cites **Yahoo!知恵袋 (Yahoo Answers Japan) 518,977 times** — two-to-five times any other source across any other AI engine. What this means in plain terms is simple: AI engines aren't primarily feeding on corporate sites and news media. They're feeding on **user-generated content**. That arrangement is not fixed, though: August 2026 brought a sharp drop in Reddit citations on ChatGPT (details below). Here's what struck me after reading this alongside the English-market research:
> **Updated August 2026: Reddit's citation position has changed substantially.**
> Per [Search Engine Land](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473) (reporting Promptwatch data), Reddit's share of ChatGPT Search citations fell **from an average of 3.83% (July 18–Aug 7) to an average of 0.52% across Aug 14–17 — an 86.4% drop in four days**.
> Google's surfaces moved far more gradually: AI Overviews went from roughly 2.5% in early July to about 2.1% in August, and AI Mode followed a similar gentle decline.
> **The cause is not established.** Promptwatch states plainly that its analysis shows *when* the shift happened, not *why*, and that it cannot rule out data-collection issues. Some write-ups attribute it to Reddit blocking crawlers site-wide via robots.txt; that is inference on their part and we have not been able to verify it (Reddit blocks our requests for its robots.txt outright).
> **The figures below are from May–September 2025. The ChatGPT numbers in particular may no longer hold.**
1. **UGC is the dominant food source for AI search** — In Japan-market Ahrefs data (May–Sept 2025), ChatGPT's #1 cite was Reddit and AI Mode's #1 was Yahoo!知恵袋. But Reddit's ChatGPT Search citations fell 86.4% in four days in August 2026 — **depending on any single platform is itself the risk.** UGC has taken the top slot.
2. **Each AI engine has a distinct UGC preference** — Perplexity leans video (YouTube), Copilot leans encyclopedic (Wikipedia), and Google AI Mode leans overwhelmingly on Yahoo!知恵袋. ChatGPT leaned heavily on Reddit as of 2025 and then swung sharply in August 2026. That volatility is precisely why a cross-platform strategy matters.
3. **UGC ecosystems are fundamentally different by language** — English-side is Reddit / YouTube / Quora-centric; Japanese-side is Yahoo!知恵袋 / note / Ameblo-centric. Japan expansion without Japanese UGC investment is essentially invisible to Google AI Mode.
4. **Brands "stimulate" UGC — they don't fabricate it** — Self-generated UGC gets flagged as spam. Community building, review solicitation, expert Q&A answers, ambassador programs, and UGC templates are the five tactics that create the conditions for organic UGC.
5. **Track UGC-driven brand mentions in three layers** — Platform mentions, AI-search citations, and branded search volume. You need all three to see the full ROI picture.
Let me unpack.
---
## 1. How AI search cites UGC — the RAG mechanic
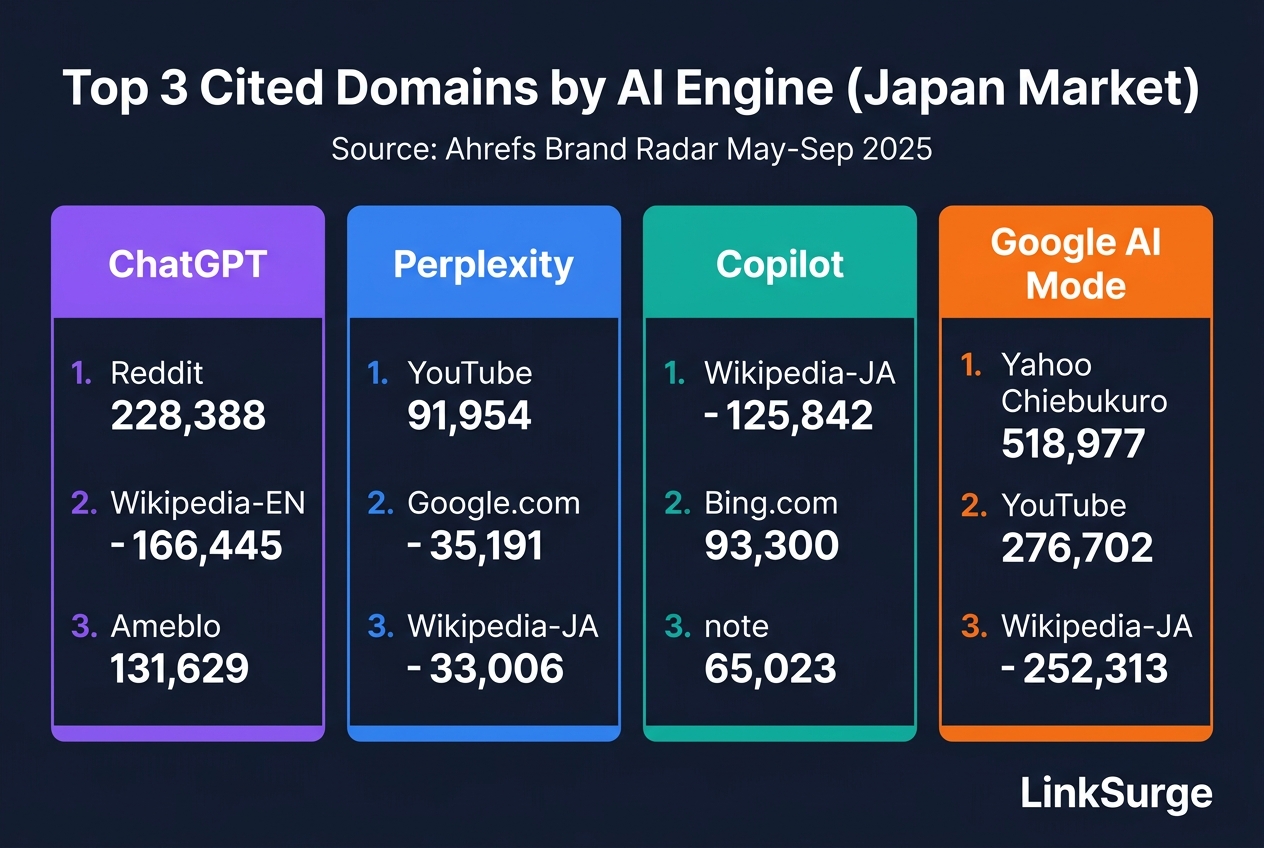
The technical reason AI search cites UGC so heavily is **RAG (Retrieval-Augmented Generation)**. ChatGPT, Perplexity, Google AI Mode, and Copilot all use RAG — they search the web in real time before generating an answer. Ahrefs' analysis shows AI evaluates sources along four axes: **trust, accuracy, freshness, and engagement**, and picks what to cite based on those signals.
### AI engine citation source top 3 — Japan market
Ahrefs ran their Brand Radar analysis between May and September 2025 on Japanese queries. Here's the condensed view — **these are point-in-time figures, and the ChatGPT/Reddit row in particular should be read against the August 2026 drop noted above.**
| AI engine | #1 | #2 | #3 |
|:---|:---|:---|:---|
| **ChatGPT** | Reddit (228,388) | Wikipedia EN (166,445) | Ameblo (131,629) |
| **Perplexity** | YouTube (91,954) | Google.com (35,191) | Wikipedia JA (33,006) |
| **Copilot** | Wikipedia JA (125,842) | Bing.com (93,300) | note (65,023) |
| **Google AI Mode** | Yahoo!知恵袋 (**518,977**) | YouTube (276,702) | Wikipedia JA (252,313) |
### The Yahoo!知恵袋 anomaly {#the-yahoo-anomaly}
The **518,977 citations** for Yahoo!知恵袋 in Google AI Mode is genuinely anomalous — 2-5x the top citation count any other AI engine gives to its top source. This isn't a fluke. Google is treating Yahoo!知恵袋's massive Q&A archive as the default answer source for Japanese queries.
It's actually logical when you think about it: 知恵袋 contains **hundreds of millions of natural-language Q&A pairs** in Japanese. For a RAG system trying to retrieve "past question similar to user's query and its best answer," it's nearly the ideal dataset shape.
### Why Reddit dominates on the English side
English-market Reddit occupied the same structural position for a long stretch. According to a Search Engine Land 2026 study, AI search engines most frequently cite **Reddit, YouTube, and LinkedIn**.
Separately, xSeek reported that Reddit's AI Overview citations grew 4.5x over one quarter.
That dominance has been eroding through 2026, though. [Conductor's data](https://www.conductor.com/academy/reddit-ai-citation-decline/) has Reddit's overall citation share falling from 2.02% in October 2025 to 1.01% by January 2026, and then the ChatGPT Search collapse described above hit in August 2026. **"Post on Reddit and AI will pick it up" no longer holds — at least not for ChatGPT.**
The Reddit/YouTube dynamics are covered in the sister post "[YouTube Video SEO Meets AI Search](/blog/en/youtube-shorts-ai-search-seo-2026/)" — worth noting that YouTube overtook Reddit in 2026 as the #1 social platform for AI citations, which itself is a notable shift.
> References:
> [Ahrefs Japan AI Citation Analysis - Valuesccg Manamina](https://manamina.valuesccg.com/articles/4596)
> [Top 10 Cited Domains by AI Search - Ahrefs](https://ahrefs.com/blog/ja/brand-radar-top-10-cited-domains/)
> [AI search engines cite Reddit, YouTube, and LinkedIn most - Search Engine Land](https://searchengineland.com/ai-search-engines-cite-reddit-youtube-and-linkedin-most-study-473138)
> [Reddit's 4.5x AI Overview Surge - xseek](https://www.xseek.io/blogs/articles/reddit-ai-overview-citation-strategy)
> [Reddit's ChatGPT Search citations fell 86% in four days - Search Engine Land](https://searchengineland.com/reddit-chatgpt-search-citations-fall-report-485473)
> [Reddit AI Citation Decline - Conductor](https://www.conductor.com/academy/reddit-ai-citation-decline/)
---
## 2. The fundamental Japan vs US UGC ecosystem difference
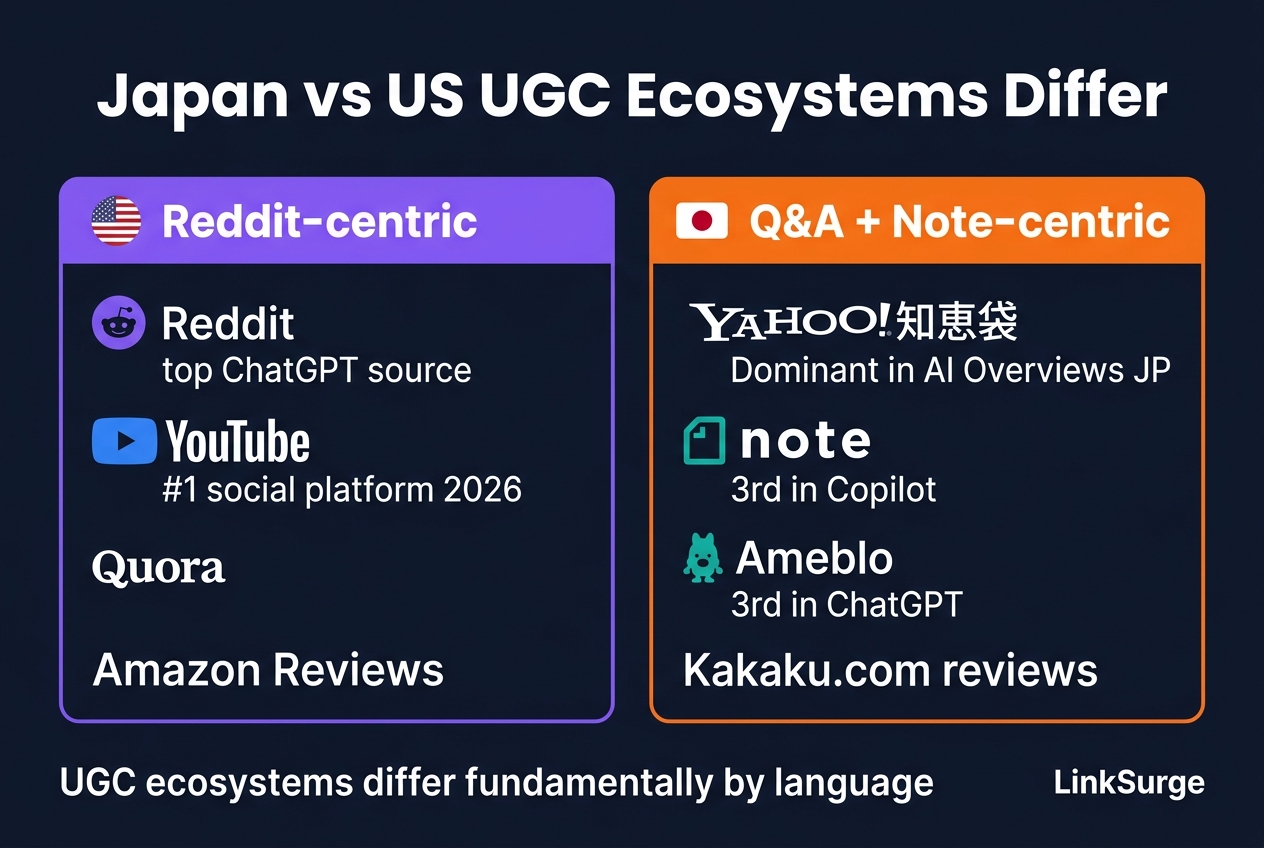
This is the critical point for any brand operating in Japan. **Importing an English-market UGC playbook into Japan won't work** — the ecosystems are different enough to require separate strategies.
### Platform map by language market
| Category | English (US-centric) | Japanese market |
|:---|:---|:---|
| **Q&A primary** | Reddit / Quora / Stack Exchange | Yahoo!知恵袋 / OKWave |
| **Reviews primary** | Amazon / Yelp / Google | Amazon.co.jp / Kakaku.com / @cosme |
| **Blog UGC** | Medium / Substack | note / Ameblo / Hatena Blog |
| **Video UGC** | YouTube / TikTok / Instagram | YouTube / TikTok / Niconico |
| **Product SNS** | Reddit / Twitter / Instagram | X / Instagram / LINE Open Chat |
### Practical conclusions from the Ahrefs data (Japan market)
1. **Yahoo!知恵袋 is the top priority** — Google AI Mode weighs it overwhelmingly. Systematically building category expertise answers here is high-leverage
2. **note works for Copilot-driven traffic** — #3 in Copilot citations; pulls double weight for SEO and AEO
3. **Ameblo still matters** — Third in ChatGPT citations. Blog SEO isn't dead; it's just in different shapes
4. **Reddit still counts** — ChatGPT's #1 source is Reddit even for Japan queries, because many English-language sources get pulled into Japanese-language answers
### A common Japan-market failure pattern
Honestly, when Japanese brands complain they "don't get cited in AI search," the root cause is usually **under-investment in Japanese-language UGC**. Focusing only on their own site's SEO while neglecting Yahoo!知恵袋 and note presence means being structurally invisible to Google AI Mode. It's genuinely one of the most common pitfalls.
The broader social-AI optimization story is covered in "[AI Search Optimization for X, Instagram, and LinkedIn (2026)](/blog/en/sns-ai-search-optimization-2026/)", but UGC is one layer deeper — user-initiated content across any platform, not just social.
> References:
> [Reddit and YouTube in AI Search: UGC Is the #1 Cited Source - Salespeak](https://salespeak.ai/aeo-news/reddit-ugc-ai-search)
> [Ahrefs Study: 6 Months of AI Source Shifts - PR TIMES](https://prtimes.jp/main/html/rd/p/000000044.000157671.html)
> [Get Brand Mentioned in ChatGPT and Perplexity - ZICY](https://www.zicy.com/ja/blog/get-brand-mentioned-in-chatgpt-perplexity)
---
## 3. Four criteria for UGC that gets AI-cited
Ahrefs' analysis boils AI's UGC-selection logic to four axes. Understand these and the next section's tactics make more sense:
### The four criteria
1. **Trust**: Community votes and engagement. Reddit upvotes, 知恵袋 best-answer designations, and Quora upvotes function as direct trust signals
2. **Indexability (RAG-friendliness)**: Q&A or review-formatted UGC is easier for RAG to retrieve because the question-answer structure is preserved
3. **Freshness**: Discussions from the past months tend to be prioritized. Multi-year-old posts lose out on freshness scoring
4. **Engagement**: Comment counts, share counts, reaction volume. Active discussion signals "this is important" to AI
### The template for AI-cited posts
Fuelonline's 2026 Reddit SEO analysis breaks down the pattern for AI-cited Reddit posts:
- **Question-form title**: "How do you actually use X for Y?" format
- **Detailed answer body**: 200–500 word specific experience accounts
- **Concrete numbers and facts**: "Used it for 3 months, sales up 28%" type quantitative data
- **Active comment discussion**: Original post + comment threads function together as one "answer set"
### Applied to Japanese UGC
The same four criteria apply cleanly to Yahoo!知恵袋:
- **Natural-language question-form titles** (close to actual user search queries)
- **Specific best answers** with steps, numbers, and links in 200+ words
- **Freshness** of a few months to a year
- **Community engagement** — "helpful" ratings and comment counts
> References:
> [9 Proven Reddit AI SEO Plays [2026 Guide] - ReddiReach](https://www.reddireach.com/blog/reddit-ai-search-optimization-2026-the-definitive-playbook-to-earn-mentions-in-ai-answers-rank-in-google)
> [Mastering Reddit SEO Strategy For UGC Success In 2026 - Fuelonline](https://fuelonline.com/seo/reddit-seo-strategy-how-ugc-content-dominates-ai-search-in-2026/)
> [Reddit's Rise in AI Citations - CMS Wire](https://www.cmswire.com/digital-marketing/reddits-rise-in-ai-citations-what-marketers-must-know-about-aeo-strategy/)
---
{{linksurge-card}}
---
## 4. Five tactics to stimulate brand UGC
This is the most misunderstood point. Cranking out fake reviews and sock-puppet posts in-house is fully anti-pattern. Platforms and AI engines have both been sharpening their spam-detection precision year over year.
What brands should be doing isn't "make UGC" — it's **"build the conditions for UGC to emerge organically."** Five tactics work in practice:
### Tactic 1: Build your own community
Create spaces where users discuss on their own terms — Reddit, Discord, owned forums, LINE Open Chat.
- **Run your own subreddit** — Official presence on brand or topic-themed subreddits
- **Discord / private chat** — Smaller-group discussion surfaces
- **Owned forums** — Particularly effective for SaaS brands
The key is "operate but don't force posts." Focus on creating conditions for voluntary discussion.
### Tactic 2: Systematize review collection
Build pathways that let users write reviews voluntarily — post-purchase emails, in-app prompts, reviews-with-incentive offers.
- **Post-purchase follow-up**: Two-week-later "how's it going?" email
- **Drive to Amazon/Kakaku.com/Yelp**: Prefer third-party platforms over your own review surface
- **Incentive design**: Offer free samples/coupons in exchange for "honest reviews"
### Tactic 3: Answer Q&A platforms as experts
Enable your staff to answer questions on 知恵袋, Quora, and Reddit as subject-matter experts.
| Platform | Tactic |
|:---|:---|
| **Yahoo!知恵袋** | Leverage "category master" designation, consistent staff answers |
| **Quora** | Earn Topic Expert status, post detailed long-form answers |
| **Reddit** | AMA (Ask Me Anything) format, subreddit moderation |
Crucial framing: **"give genuinely helpful answers, not product pitches."** Humans and AI both downgrade the moment they smell promotional intent.
### Tactic 4: Run an ambassador program
Offer perks to power users to encourage voluntary posts, blogs, and videos.
The yutori case study (detailed in "[How yutori Captured Gen Z with SNS-First Brand Strategy](/blog/en/yutori-sns-brand-strategy-2026/)") is the canonical example: staff become brand ambassadors posting daily-life content, which flows through TikTok and Reels and eventually into AI citations. The compound loop is real.
### Tactic 5: Provide UGC creation templates
Distribute hashtags, photo frames, shareable cards, and remix-ready assets — **materials that make UGC easier to create**.
- **Official hashtags**: Brand-specific tags that hit a billion views on TikTok
- **Photo frames**: Instagram Story-ready overlay assets
- **Review templates**: "Cover these 5 points and you're done" frames
The underlying idea: remove the psychological block of "I want to post but don't know what to say."
For a ChatGPT-specific playbook covering press wires, long-form platforms and Q&A sites, and the conditions that get a press release cited, see [Using Press Releases, note and Q&A Sites for ChatGPT Citations](/blog/en/chatgpt-press-release-note-ugc-2026/).
The buying-behavior side backs this up. In "[54% of Gen Z Ask AI Before They Buy, But Still Trust Search Most](/blog/en/gen-z-ai-shopping-search-trust-2026/)," we cross-check Rakuten's September 2026 survey with Azoma's citation data, which puts UGC at 19% of ChatGPT's shopping citations and brand websites at just 3%.
> References:
> [Reddit's Rise in AI Citations - CMS Wire](https://www.cmswire.com/digital-marketing/reddits-rise-in-ai-citations-what-marketers-must-know-about-aeo-strategy/)
> [AI Visibility in 2025 - Yext](https://www.yext.com/ja/blog/2025/10/ai-visibility-in-2025-how-gemini-chatgpt-perplexity-cite-brands)
> [9 Proven Reddit AI SEO Plays - ReddiReach](https://www.reddireach.com/blog/reddit-ai-search-optimization-2026-the-definitive-playbook-to-earn-mentions-in-ai-answers-rank-in-google)
---
## 5. Three-layer monitoring for UGC-driven brand mentions
Once UGC tactics are running, it's time to measure. UGC-driven brand mentions need **three-layer tracking** to see the full picture.
### The three-layer monitoring frame
| Layer | What to measure | How |
|:---|:---|:---|
| **Layer 1: Platform mentions** | Brand mention count on Reddit / 知恵袋 / note | Platform search, API social listening tools |
| **Layer 2: AI search citations** | Citation count in ChatGPT / Perplexity / Google AI Mode | Purpose-built tools (e.g., LinkSurge) |
| **Layer 3: Branded search volume** | "Brand name + UGC-context" Google search volume | Google Search Console / Google Trends |
### Layer 1: Platform mention measurement
Use `site:reddit.com "brand name"` search on Reddit, or official search on 知恵袋, to track question counts mentioning your brand per month. AI cites these, so growing this layer is the root.
### Layer 2: AI citation counts
This is the hardest layer to measure. LinkSurge's GEO monitor tracks daily how often a brand or URL gets cited in ChatGPT, Perplexity, and Google AI Overviews, letting you visualize whether your UGC tactics are actually rippling into AI search.
### Layer 3: Branded search volume
Users who discover you via UGC tend to follow up with Google searches for "brand name" or "brand name + related keyword." **Tracking Google Search Console impressions and clicks for branded queries monthly** validates the downstream result of UGC effort.
### Five items to review monthly
Monthly checkpoint:
1. Brand mention count per platform (Reddit, 知恵袋, note, Amazon, Kakaku.com)
2. AI citation count per engine (ChatGPT, Perplexity, AI Overviews, Gemini)
3. Citation quality mix (positive / neutral / negative ratio)
4. Branded search volume trend
5. Conversion attribution (UGC-originated inquiries and purchases)
---
## 6. Implementation checklist and KPI design
A practical checklist for deploying a UGC × AI search strategy:
### First-month launch checklist
- [ ] Platform inventory across English and Japanese markets (Reddit / 知恵袋 / Quora / note / review sites)
- [ ] Baseline measurement of brand mentions on each platform
- [ ] Secure community management resources and an owner
- [ ] Assign expert Q&A answer responsibilities
- [ ] Design review-collection pathways (post-purchase emails, in-app prompts)
- [ ] Set up AI citation monitoring (LinkSurge etc.)
### KPI design by phase
| Phase | Primary KPI |
|:---|:---|
| **3 months in** | Monthly platform mentions up 10–20% |
| **6 months in** | AI citation count 2x+ initial baseline |
| **12 months in** | Branded search volume +20%+, UGC-attributed conversions visible |
### Common failure modes and how to avoid them
1. **Self-posted UGC**: Major spam-detection and reputational risk. Don't
2. **English-UGC-only focus**: Japan-market brands need Yahoo!知恵袋 and note. Don't skip Japanese UGC
3. **One-off campaigns**: UGC stimulation is a sustained investment — design for at least 12 months
4. **Inconsistent measurement layers**: Don't celebrate just Layer 1. Track through Layers 2 and 3
---
## FAQ
### Why can't I just fabricate UGC?
Fake reviews and sock-puppet posts get detected by both platform spam-detection systems and AI-search trust-evaluation systems, which have both improved year over year. Detection results in penalties (account suspension, ranking drops, exclusion from AI citations) and brand damage. Growing organic UGC is faster long-term, even if it feels slower.
### Is staff posting about our product on Yahoo!知恵袋 considered spam? {#is-staff-posting-about-our-product-on-yahoo-considered-spam}
It depends on how. Obvious promotion and sock-puppet activity are out, but **staff serving as "category experts" and mentioning the product within genuinely helpful answers** is fine. The distinguishing factor is always "answering the asker's question genuinely, not pitching."
### Should I prioritize English or Japanese UGC?
Depends on your market. For Japan-market businesses, **Yahoo!知恵袋, note, and Ameblo should be top priority**. For global expansion, Reddit and English Q&A platforms. If you're doing both, allocate resources proportional to market size.
### How do I measure AI search citations?
Purpose-built tools like LinkSurge's GEO monitor are the realistic path. You can manually query ChatGPT or Perplexity with brand-name queries and count citations, but it doesn't scale to continuous tracking.
### How long before UGC tactics show results?
Three months at the earliest; full effect typically 6–12 months. Community building, review accumulation, and consistent Q&A answering all take time — but once the machine is running, it compounds.
---
## Designing UGC, not producing it
2026 AI search marketing can't be won by owned-content investment alone. Ahrefs data is unambiguous: AI engines are **fed by Reddit, Yahoo!知恵袋, note, and other UGC**, and competing on your own site alone means leaving AI-citation opportunities behind.
The five tactics in this post — community, reviews, Q&A, ambassadors, UGC templates — share a single underlying philosophy: **design the conditions for users to generate UGC voluntarily**. Stimulation, not production. That's the 2026 UGC thesis.
LinkSurge's [brand mention tracker](https://linksurge.jp/geo/mentions) tracks daily brand citations across ChatGPT, Perplexity, and Google AI Mode. Pair it with the checklist above when you want to quantitatively validate UGC tactics.
---
## YouTube Video SEO Meets AI Search: The 94.3% Long-Form Shock and the Shorts Playbook for 2026
> URL: https://linksurge.jp/blog/en/youtube-shorts-ai-search-seo-2026/
> Date: 2026-04-17 | Category: SNS | Author: Aro Ogata
> Tags: YouTube SEO, Video Marketing, AI Search Optimization, Perplexity, Google AI Overviews, Shorts Strategy, Long-form Video
## The TL;DR: Five things that changed for YouTube in 2026
Video marketing conventional wisdom quietly flipped in 2026. OtterlyAI's 100M+ citation analysis showed that **94.3% of AI-search citations to YouTube videos go to long-form content, and only 5.7% to Shorts**. Reading that study alongside YouTube's January 2026 Shorts algorithm update surfaced five practical takeaways:
1. **YouTube is now the most-cited video source in AI search** — Ahrefs' April 2026 Brand Radar analysis puts YouTube as the top-cited domain outside the top 100 organic results for AI Overviews. Perplexity alone accounts for 38.7% of YouTube AI citations.
2. **The signal that predicts AI citations isn't views — it's structure** — OtterlyAI's correlation analysis showed near-zero correlation (r = -0.03) for subscriber count, while **description length** was the strongest positive signal at **r = 0.31**. Wild stat: **40.83% of AI-cited videos had fewer than 1,000 views**.
3. **Long-form is the primary asset, Shorts are repurposing and discovery** — Shorts earn only 5.7% of AI citations, but with the January 2026 introduction of a Shorts-specific search filter, they matter for social discovery. A two-tier model — long-form as the hero asset, Shorts as repurposed clips — is what makes sense economically.
4. **Chapters get indexed as individual rich results** — Timestamped chapters receive independent citations in AI Overviews, which means one structured video can surface across multiple queries via Google's query fan-out system.
5. **The January 2026 Shorts update introduced "Viewed vs Swiped Away" as a core KPI** — Completion rate, replay rate, and swipe-away rate now drive ranking, and Gemini analyzes semantic video content. Audio quality and on-screen text quality suddenly matter a lot more.
Let me unpack each of these.
---
## 1. Why YouTube became the AI citation king
Honestly, the shift in AI citation sources during 2026 has been faster than I expected. Ahrefs' April 2026 Brand Radar ranked YouTube as the **top-cited domain in AI Overviews** from outside the top 100 organic rankings. Six months earlier, Reddit topped most ChatGPT-source analyses. In 2026, YouTube overtook it.
### What the OtterlyAI study actually found
OtterlyAI's March 2026 publication — drawn from over 100M AI citations — revealed these numbers:
| Metric | Value |
|:---|:---|
| Share of AI-cited YouTube content that is long-form | **94.3%** |
| Share that is Shorts | 5.7% |
| Perplexity's share of all YouTube AI citations | **38.7%** (largest single platform) |
| AI-cited videos with fewer than 1,000 views | **40.83%** |
| Correlation: description length × citation frequency | **r = 0.31** (strongest) |
| Correlation: subscriber count × citation frequency | r = -0.03 (effectively zero) |
What's striking is that **views and subscriber count have almost no relationship to AI citation frequency**. AI isn't picking the most popular videos — it's picking the ones that are **structurally easiest to parse**.
### Why AI prefers YouTube
Radyant breaks down three structural reasons AI engines lean on YouTube:
1. **High-accuracy auto-transcription** — Google's speech recognition makes audio indexable by default, so LLMs can extract context reliably
2. **Chapters become independent rich results** — A single video gets treated as multiple candidate answers
3. **Detailed descriptions** serve as rich metadata that improves AI comprehension
I covered how TikTok's algorithm handles short-form video in our sister post "[TikTok SEO Playbook: Winning the Search Engine 40% of Gen Z Actually Uses](/blog/en/tiktok-seo-ai-search-2026/)". YouTube operates on a completely different logic — TikTok is short-length × completion × share, while YouTube is structured × long-length × chapters when it comes to getting cited by AI. For the text-UGC side of AI citations (Reddit, Yahoo!知恵袋, note), see "[UGC Fuels AI Search](/blog/en/ugc-ai-search-brand-mentions-2026/)".
> References:
> [OtterlyAI Study: 94% of YouTube AI Citations Go to Long-Form - VEED.IO](https://www.veed.io/learn/otterly-ai-citation-research-2026)
> [YouTube now beats Reddit in AI citations - Radyant](https://radyant.io/guides/youtube-ai-search-visibility-citation-framework/)
> [AI Citation Domains TOP 10 (April 2026) - Ahrefs](https://ahrefs.com/blog/ja/brand-radar-top-10-cited-domains-2026-update/)
> [YouTube Is Now the Top AI Citation Engine - Ajkumar](https://ajkumar.com/strategy/youtube-citation-engine-strategy/)
---
## 2. Long-form 94.3% vs Shorts 5.7% — Where the real AI citation battle happens
Here's the most important call in this entire post: if you're chasing AI-search traffic, **over-investing in Shorts production is inefficient**. The OtterlyAI data makes that fairly unambiguous.
### The structural reasons Long-form wins
The **94.3%** long-form citation share isn't a fluke — it's the structural output of how LLMs select video evidence:
- **Context depth** — To cite a video as "the answer to a question," the LLM needs enough in-video explanation
- **Chapter structure** — Longer videos naturally carry more chapters, each a separate citation candidate
- **Detailed descriptions** — Long-form videos tend to have longer descriptions, which maps to the r = 0.31 correlation
The 5.7% for Shorts doesn't mean "Shorts are worthless." It means **in the specific lens of AI citation, long-form is overwhelmingly dominant**.
### But Shorts still have a real job
The role of Shorts has sharpened in 2026. VEED.IO's report highlights these use cases:
- **Social search discovery** — Shorts compete with TikTok and Instagram Reels in social video search
- **Long-form repurposing** — Clips from your structured long-form serve as highlight assets
- **Top-of-funnel brand exposure** — High-reach surface for volume-driven awareness
If you over-index on Shorts and never make long-form, you're missing the primary AI-citation asset. If you only make long-form, you miss social-discovery opportunities. **Build both, but for different reasons**.
### Practical weekly allocation
The production-hour split I actually run looks like this:
| Asset | Production-hour share | Purpose |
|:---|:---|:---|
| Long-form (10–20 min) | 60–70% | AI citation authority, SEO weight |
| Shorts (clipped from long-form) | 20–30% | Social discovery, repurposing |
| Other (community posts, etc.) | 10% | Fan engagement |
"One long-form → three to five Shorts repurposed" is the ROI sweet spot in my experience.
> References:
> [OtterlyAI Study: 94% of YouTube AI Citations Go to Long-Form - VEED.IO](https://www.veed.io/learn/otterly-ai-citation-research-2026)
> [YouTube AI Citations: Turn Videos Into Search Assets - UpGrowth](https://upgrowth.in/youtube-ai-search-citation-machine/)
> [First Large-Scale Study by OtterlyAI - Globenewswire](https://www.globenewswire.com/news-release/2026/03/02/3247558/0/en/First-Large-Scale-Study-by-AI-Search-Monitoring-Platform-OtterlyAI-Shows-YouTube-is-2-Social-Platform-for-AI-Citations.html)
---
## 3. Designing videos that earn AI citations
Saying "structure is everything" sounds reductive, but the OtterlyAI numbers really do point there. Here's what to actually structure, in order:
### Step 1: Write descriptions at article length
A description-length correlation of r = 0.31 sounds ordinary until you realize what it means operationally: top-performing channels write **300–500 word minimum** descriptions, and occasionally push past 1,000 words of article-grade content.
Marketing Agent's February 2026 guide lays out the description template:
1. Video summary (~100 words)
2. Timestamped chapter list
3. Section-by-section detail with headings (~100–200 words each)
4. Related links and citations
5. Hashtags (3–5)
### Step 2: Always add timestamped chapters
This is honestly the most under-utilized element of 2026 YouTube SEO. Ahrefs' citation analysis shows that **videos with timestamped chapters earn multiple AI citations** far more often than videos without.
The reason is structural: **Google treats chapters as individual rich results**. One video becomes an independent citation candidate for Query A, Query B, and Query C — this is the "query fan-out effect."
Chapter design best practices:
- Each chapter: **2–5 minutes**
- Titles in **search query format** ("What is X?", "How to X")
- Minimum 5 chapters per video
The query fan-out mechanic itself is covered in "[What Is Query Fan-Out? Beginner's Guide](/blog/en/query-fan-out-guide-2026/)".
### Step 3: Tune the captions
Auto-transcription handles the baseline, but **manually correcting the captions** noticeably improves AI comprehension. Proper nouns and domain-specific terms are often mis-recognized, and that gap shows up in citation outcomes.
### Step 4: Title and first 15 seconds deliver the answer
AI search cites "answers to questions." Include question-form or answer-form keywords in the title, and front-load the conclusion in the first 15 seconds. Narrative structures that save the point for the end make it harder for AI to identify what to cite.
### The AI-citation-ready video template
| Element | Specification |
|:---|:---|
| Length | 10–20 minutes |
| Description | 300–1,000 words |
| Chapters | 5+ chapters, 2–5 min each |
| Captions | Manually reviewed |
| Title | Question-form or "how to X" |
| First 15 seconds | Conclusion stated up-front |
> References:
> [YouTube AI Citations: Turn Videos Into Search Assets - UpGrowth](https://upgrowth.in/youtube-ai-search-citation-machine/)
> [Building A Search-First YouTube Content Strategy - Marketing Agent](https://marketingagent.blog/2026/02/16/building-a-search-first-youtube-content-strategy-seo-tips-for-2026/)
> [Video SEO Best Practices in 2026 - VdoCipher](https://www.vdocipher.com/blog/video-seo-best-practices/)
> [Why AI Search Prefers YouTube - Torro](https://torro.io/blog/why-ai-search-prefers-youtube)
---
{{linksurge-card}}
---
## 4. YouTube → AI search citation pathways
The flow from YouTube into AI search looks different depending on the platform. Here's what's actually happening at Perplexity, Google AI Overviews, and ChatGPT:
### Perplexity: 38.7% of YouTube AI citations
The OtterlyAI study shows **38.7%** of YouTube AI citations come through Perplexity — the largest share of any single platform. Perplexity attributes 78% of claims in complex research questions to specific sources, which makes it the cleanest surface on which to become a "cited video."
Common traits of Perplexity-cited YouTube videos:
- **Clear chapter structure**
- **Speaker is positioned as an expert** (channel description and creator profile signal authority)
- **Specific numbers and facts** are verbalized inside the video
### Google AI Overviews: Chapter-level citation
Search Engine Land's 2026 analysis confirms Google AI Overviews treats YouTube as the **top-cited domain outside the top 100 organic results**. The interesting part is chapter-level citation — cases where three different chapters of a single video appear in AI Overviews for three different queries.
### ChatGPT: Video summarization and direct citation
ChatGPT's 2026 UI strengthened the ability to summarize content when a YouTube URL is pasted. This increased how often ChatGPT cites video URLs as "video that explains X." The integration is actively used on the user side as well.
### LinkSurge GEO monitor example
LinkSurge's GEO monitor tracks how often a given URL gets cited in ChatGPT, Perplexity, and Google AI Overviews. Registering your YouTube video URLs lets you quantify how the video is evaluated in AI search, which makes structural changes measurable.
> References:
> [YouTube is no longer optional for SEO in the age of AI Overviews - Search Engine Land](https://searchengineland.com/youtube-seo-ai-overviews-467253)
> [YouTube Is Now the Top AI Citation Engine - Ajkumar](https://ajkumar.com/strategy/youtube-citation-engine-strategy/)
> [Why AI Search Prefers YouTube - Torro](https://torro.io/blog/why-ai-search-prefers-youtube)
---
## 5. The Shorts × Long-form division-of-labor model
Now the new Shorts position and the concrete division-of-labor with long-form.
### January 2026 update: How the Shorts algorithm shifted
Key changes YouTube rolled out in early January 2026:
| Change | Detail |
|:---|:---|
| **Shorts-specific search filter** | "Type" menu now has a "Shorts" filter — Shorts are now an SEO surface |
| **"Viewed vs Swiped Away" core signal** | Watched-through vs swiped-past is a new ranking KPI |
| **Gemini semantic analysis** | Tone, on-screen elements, and semantic meaning get analyzed — tags alone aren't enough |
| **Increased weight on completion + replay** | "Watched to the end" and "repeat watched" are top-priority signals |
Shorts now require more search-oriented and structural thinking than before. But for AI citations, long-form's 94.3% dominance is unchanged.
### Implementing the division model
Here's the weekly production cycle I actually run:
1. **Monday** — Research and outline (1–2 hours)
2. **Tue–Wed** — Long-form shoot + edit, 10–20 min output (~10 hours)
3. **Thursday** — Clip 3–5 Shorts from the long-form, edit (3–4 hours)
4. **Friday** — Finalize description, chapters, titles; publish
5. **Sat–Sun** — Daily Shorts drops; monitor long-form performance
Treat long-form as the "mother" and Shorts as the "children," and a single production investment yields multiple assets. That's how you maximize **ROI per production hour**.
### Three Shorts priorities post-Jan 2026
1. **State the subject in the first second** (counteracts swipe-away)
2. **Verbally state keywords clearly** (Gemini semantic analysis reads audio)
3. **Always link to the long-form in the description** (asset bridging)
> References:
> [YouTube Shorts Algorithm Update: January 2026 - Miraflow](https://miraflow.ai/blog/youtube-shorts-algorithm-update-january-2026)
> [How Does the YouTube Shorts Algorithm Work in 2026? - vidIQ](https://vidiq.com/blog/post/youtube-shorts-algorithm/)
> [YouTube Shorts Algorithm Explained 2026 - Metricool](https://metricool.com/youtube-shorts-algorithm/)
---
## 6. Implementation checklist and KPI design
A checklist for implementing and measuring 2026 YouTube strategy:
### Pre-publish checklist
- [ ] Title is in question-form or answer-form with target keyword
- [ ] Length is 10–20 minutes (if targeting AI citations)
- [ ] Conclusion stated in the first 15 seconds
- [ ] At least 5 timestamped chapters
- [ ] Description is 300+ words
- [ ] Captions are manually reviewed
- [ ] Description links to a related long-form or Shorts asset
### Three-layer KPI structure
| Layer | Metrics |
|:---|:---|
| **Inside YouTube** | Average view duration, retention, CTR, per-chapter dwell time |
| **Spillover to Google** | YouTube videos appearing in Google SERPs, branded search volume trend |
| **AI search citations** | URL citation counts across ChatGPT, Perplexity, AI Overviews |
The third layer cannot be tracked manually — you need dedicated tooling like OtterlyAI or LinkSurge.
### Monthly review template
Run this once a month:
1. AI-citation count trend (how many videos got cited this month)
2. Chapter-level citation distribution (to verify query-fan-out effect)
3. Description length × citation rate correlation (hypothesis validation)
4. Long-form vs Shorts citation ratio (how close to 94.3:5.7)
5. Branded search volume change (YouTube-viewing → search-behavior spillover)
---
## FAQ
### If I'm targeting AI citations, should I focus on long-form or Shorts?
Long-form, strongly. OtterlyAI's research found 94.3% of AI citations go to long-form — so if AI-search-driven traffic matters, the primary bet is producing structured 10–20 minute long-form. Shorts then serve as repurposed clips from that long-form.
### Can videos with low views still get AI-cited?
Yes. The correlation between views and AI citations is essentially zero (r = -0.03), and **40.83% of AI-cited videos have fewer than 1,000 views**. AI evaluates structure, not popularity, so small channels can compete.
### What length warrants adding chapters?
Anything from 5 minutes up benefits; 10–20 minute long-form with 5+ chapters is the target. Keep each chapter 2–5 minutes and write titles in search-query form.
### What should I do about the January 2026 Shorts algorithm changes?
Three priorities: (1) State the subject in the first second to fight swipe-away, (2) Verbalize keywords clearly in audio so Gemini's semantic analysis can pick them up, (3) Always link to the long-form in the description to promote cross-viewing.
### How do I make YouTube videos more likely to be cited by Perplexity?
Structure chapters well, speak specific numbers and facts inside the video, and make speaker expertise clear in the channel description. Perplexity attributes 78% of claims in complex research to sources, so the shortcut is to provide statements that can be clearly pulled as citations.
---
## Redesigning video SEO as "structure SEO"
2026 video marketing has crossed a subtle threshold: from "make it and ship it" to "structure it so it gets cited." OtterlyAI's 100M+ citation study makes it clear that AI engines don't pick the most-viewed videos — they pick the ones where **descriptions, chapters, and captions make information explicit and parseable**.
Shorts became a formal SEO surface with the January 2026 filter update and now play a real role in social discovery. But AI citations remain a long-form game. The 2026 fork in the road is whether your production pipeline can run both — with the division-of-labor model that lets one long-form produce multiple citation candidates and Shorts-sized discovery assets.
LinkSurge's [GEO monitor](https://linksurge.jp/geo/mentions) tracks how often your content is cited across ChatGPT, Perplexity, and Google AI Overviews. If you're actively running AI-citation experiments on YouTube content, pair it with your production workflow to validate what's working.
---
## XML Sitemap Strategy 2026: Segmentation & Crawl Budget Optimization
> URL: https://linksurge.jp/blog/en/xml-sitemap-strategy-2026/
> Date: 2026-04-16 | Category: SEO | Author: Aro Ogata
> Tags: XML Sitemap, Crawl Budget, Index Optimization, Technical SEO, Sitemap Strategy
## Key Takeaways: Turn Your Sitemap from a Forgotten File into a Crawl and Indexing Asset
After digging into dozens of client sitemaps, here's what stands out: most sites upload one XML sitemap to Search Console and never touch it again. These five points are what you need to fix in 2026.
1. **Segmentation is non-optional** — Instead of one massive sitemap.xml, split by content type, business value, and update frequency. One e-commerce site saw product index rates jump from 87% to 98% after segmenting into five sitemaps
2. **Crawl budget is a finite resource** — Google allocates a limited crawl budget to your site. Low-value pages in your sitemap steal crawls from pages that actually matter
3. **Among standard URL metadata, only `` carries weight** — within the same `` entry, both Google and Bing ignore `` and ``. Accurate last-modified dates are what trigger recrawls; rewriting them on every build destroys that trust
4. **Dynamic generation keeps your sitemap current** — Static sitemaps go stale the moment you create them. Automate additions, removals, and timestamp updates
5. **Image and video sitemaps expand search visibility** — With visual search growing in 2026, dedicated image-sitemap.xml and video-sitemap.xml files capture traffic you're currently missing
Let's break each of these down.
---
## 1. Why the 2015 Sitemap Playbook Fails in 2026
Here's the thing: uploading a sitemap.xml to Google Search Console and never touching it again stopped working years ago.
Back in 2015, Google's crawl budget was relatively generous. You could stuff every URL into one sitemap and Googlebot would dutifully crawl them all. The 2026 reality is fundamentally different.
### Three Problems with Abandoned Sitemaps
- **Crawl budget waste**: Duplicate content, stale URLs, and noindex pages in your sitemap consume crawl budget on pages that don't matter
- **Contradictory signals**: Including noindex pages in your sitemap sends Google mixed messages — "please index this" and "don't index this" simultaneously
- **Index delays**: Cramming 50,000+ URLs into a single file slows processing and delays discovery of new content
In my testing, an e-commerce client using a single monolithic sitemap had a product page index rate of just 87%. That's 13% of their products invisible to Google.
> References:
> [Build and Submit a Sitemap - Google Search Central](https://developers.google.com/search/docs/crawling-indexing/sitemaps/build-sitemap)
> [Crawl Budget Optimization: Complete Guide for 2026 - LinkGraph](https://www.linkgraph.com/blog/crawl-budget-optimization-2/)
> [Sitemap Best Practices: Everything You Need to Know - Respona](https://respona.com/blog/sitemap-best-practices/)
---
## 2. Strategy #1: Multiple Segmented Sitemaps
This is where it gets interesting. The era of one-sitemap-fits-all is over.
### Segmentation Design Criteria
| Segmentation Axis | Example Files | Priority Level |
|-------------------|---------------|----------------|
| Content type | `sitemap-products.xml`, `sitemap-blog.xml` | High |
| Business value | `sitemap-highmargin.xml`, `sitemap-clearance.xml` | High |
| Update frequency | `sitemap-frequent.xml`, `sitemap-rare.xml` | Medium |
| Language/region | `sitemap-en.xml`, `sitemap-ja.xml` | Medium |
| Archive | `sitemap-archive.xml`, `news-sitemap.xml` | Low |
Reference all of them from a `sitemap-index.xml`. Keep each sub-sitemap under **10,000–20,000 URLs** for optimal processing speed — well below the protocol limit of 50,000.
### Why Segmentation Works
The data is clear. A 50,000-page e-commerce site segmented into five type-specific sitemaps saw these results after 60 days:
- Product page index rate: 87% → **98%**
- Average time to index: 6 days → **1.4 days**
- Organic traffic: **+156%**
Same pages. Better organization. That's not because search engines read a `` signal from the segmented files — as covered below, both Google and Bing ignore that tag entirely. What actually moved the needle was more likely a combination of lighter, more reliably processed files, being able to isolate coverage issues per segment in Search Console, and the cleanup of duplicate, noindex, and stale URLs that typically happens alongside a segmentation project.
For a comprehensive view of SEO fundamentals alongside sitemap strategy, check out our "[Complete SEO Guide 2026](/blog/en/seo-guide-2026/)."
> References:
> [XML Sitemap Best Practices for SEO - BrightSEO Tools](https://brightseotools.com/post/xml-sitemap-best-practices-seo)
> [Protocol - sitemaps.org](https://www.sitemaps.org/protocol.html)
> [Crawl Budget: What Is It and Why It Matters - Briteskies](https://blog.briteskies.com/blog/crawl-budget-what-is-it-and-why-it-matters-for-your-site)
---
## 3. Strategy #2: Getting `` Right
As the takeaways above note, of the standard `` metadata — ``, ``, and `` — `` is the only one Google actually reads. Which means this is where your sitemap effort pays off the most.
Image and video sitemap extensions are a separate matter; Google does use those, and Section 7 covers them. The comparison here is strictly about standard URL metadata.
### Why `` Is the One That Works
Google uses `` for recrawl scheduling. When you declare "this URL has changed since your last crawl," Google can concentrate a finite crawl budget on pages that actually moved. The bigger your site, the more directly this translates into index freshness.
But that only holds **if your declaration is trustworthy**. This is where most implementations fall apart.
### Rules for Accurate ``
- **Use ISO 8601 format**: `2026-04-16` or `2026-04-16T09:00:00+09:00`
- **Update only on substantive changes**: Google points to meaningful changes in content, structured data, and links. Purely cosmetic tweaks don't count — but a template change does if it alters structured data or internal linking
- **Give each page its own date**: if every URL shares the same timestamp, you aren't tracking updates — you're just stamping a build date
### The Most Common Failure: Every Build Updates Every Page
Honestly, this is the single most frequent mistake I see in the wild.
Depending on your static site generator or CMS configuration, every deploy rewrites `` on every URL to "today." Passing `new Date()` straight into sitemap generation is the classic version of this. Nothing changed, yet every page declares itself updated, every single day.
Let that run long enough and Google stops trusting your `` declarations altogether. **You lose the ability to trigger a recrawl when you genuinely do update something** — which makes this worse than not setting the tag at all.
Build `` around actual change detection. Not the publish date, not the build date — the date you last touched the content itself.
### A Note on `` and ``
Short version: **they aren't worth tuning**. Both Google and Bing officially state they ignore these two tags. Yandex is among the few engines that documents using priority as a crawl-prioritization hint.
If your CMS or plugin emits them automatically, leave them. Just avoid setting every page to `1.0` — for Yandex and for your own internal documentation alike, "everything is equally important" says nothing. If you do set them, a coarse split (homepage higher, legal pages and archives lower) is plenty.
### Deciding Where to Spend Your Effort
Where to direct limited maintenance hours is a separate question worth answering deliberately. A weighted score keeps that decision consistent:
**Investment priority = (Page Authority × 0.3) + (Conversion Rate × 0.4) + (Search Volume × 0.3)**
Normalize each input to a 0–1 range before applying the weights. Backlink counts, conversion rates, and search volumes use different units and magnitudes, so combining them raw makes the coefficients meaningless.
The key point: **this is not a number you write into your XML**. It's a ranking that tells you which pages get accurate `` upkeep, stronger internal links, and content refreshes first.
> References:
> [Build and Submit a Sitemap - Google Search Central](https://developers.google.com/search/docs/crawling-indexing/sitemaps/build-sitemap)
> [The Importance of Setting the "lastmod" Tag in Your Sitemap - Bing Webmaster Blog](https://blogs.bing.com/webmaster/february-2023/The-Importance-of-Setting-the-lastmod-Tag-in-Your-Sitemap)
> [Using the Sitemap file - Yandex Webmaster](https://yandex.com/support/webmaster/en/controlling-robot/sitemap.html)
> [XML Sitemaps: What They Are & Why They Matter - Search Engine Land](https://searchengineland.com/guide/xml-sitemaps)
---
## 4. Strategy #3: Dynamic Sitemap Generation
Static sitemaps start going stale the moment you save them. Honestly, the number of sites I've seen with deleted pages and broken redirects still living in their sitemaps is staggering.
### Four Automations to Implement
1. **Auto-add new pages**: Reflect content publication in the sitemap immediately
2. **Auto-remove deletions and redirects**: Strip pages from the sitemap when they're removed or redirected
3. **Auto-update ``**: Detect meaningful content changes and update timestamps
4. **Prioritize change detection on key pages**: Use analytics data to identify your highest-value pages, then make sure substantive edits to those pages reliably update ``
### Implementation Approaches
- **WordPress**: Yoast SEO, RankMath, or AIOSEO auto-submit on content updates
- **Next.js**: Dynamic generation via `app/sitemap.ts` at build time
- **Custom**: Python or Node.js scripts querying the CMS/database on a cron schedule
Platforms like [LinkSurge](https://linksurge.jp/), Screaming Frog, and Sitebulb can monitor your index status and flag sitemap issues before they impact rankings.
> References:
> [XML Sitemaps: Structure, Implementation & SEO Best Practices](https://skilltrainingnepal.com/blogs/xml-sitemaps-structure-implementation-seo-optimization)
> [9 Best XML Sitemap Generator Tools - Yotpo](https://www.yotpo.com/blog/best-xml-sitemap-generator-tools/)
> [8 Crucial XML Sitemap Best Practices - TrySight](https://www.trysight.ai/blog/xml-sitemap-best-practices)
---
## 5. Strategy #4: Strategic Crawl Budget Allocation
Google assigns a finite crawl budget to your site. That budget fluctuates based on server health, traffic patterns, page speed, and content freshness.
### What to Include vs. Exclude from Your Sitemap
**Include:**
- Unique, valuable content pages
- Pages with conversion potential
- Canonical URLs only
- Pages returning 200 status codes
**Exclude:**
- Paginated pages (handle with `rel=next/prev`)
- Filtered product pages (parameter URLs)
- Duplicate content variations
- Thin content pages
- Admin and login pages
- Pages with noindex directives
### How to Identify Crawl Budget Waste
Analyze server logs to spot Googlebot hitting low-value pages frequently. Tools like Botify, ContentKing, or JetOctopus automate this analysis.
Target a crawl-budget waste ratio below **10%**. One enterprise client that cleaned up their sitemap and robots.txt saw impressions increase 79%, clicks increase 62%, and SEO-driven revenue grow by $786,000 in three months.
> References:
> [Crawl Budget Optimization for Enterprise Sites - ALM Corp](https://almcorp.com/blog/crawl-budget-optimization-enterprise-sites/)
> [5 Ways to Get Better Log File Insights - Search Engine Journal](https://www.searchenginejournal.com/log-file-insights-crawl-budget-optimization/347038/)
> [Log file analysis for SEO - Search Engine Land](https://searchengineland.com/guide/log-file-analysis)
---
{{linksurge-card}}
---
## 6. Strategy #5: Monthly Sitemap Audits
An abandoned sitemap actively harms your indexing. That's not hyperbole — it's what the data shows.
### Monthly Audit Checklist
1. **Check for 404 errors**: URLs in your sitemap returning 404 are critical errors
2. **Remove redirected URLs**: Strip 301/302 redirects from the sitemap
3. **Verify canonical alignment**: Ensure canonical URLs match sitemap entries
4. **Audit `` accuracy**: Check that timestamps line up with substantive changes to content, structured data, or links — and that pages don't all share one date
5. **Remove low-performers**: Drop pages with no traffic and no conversions
6. **Add missing high-performers**: Ensure all important pages are represented
### Monitoring KPIs in Search Console
Track these metrics weekly:
- **Submitted vs. indexed ratio**: Aim for 95%+
- **Coverage errors**: Check weekly
- **Index speed**: Target under 48 hours from submission to index
- **Crawl frequency per sitemap**: Compare across segments
- **Valid vs. excluded pages**: Analyze exclusion reasons
To understand how AI search is reshaping SEO priorities, see "[AI Search Impact on SEO](/blog/en/ai-search-seo-japan-2026/)."
> References:
> [How to Monitor & Submit Sitemaps in GSC - Quattr](https://www.quattr.com/search-console/submit-monitor-sitemaps-in-gsc)
> [XML Sitemaps & Robots.txt: Guide - Straight North](https://www.straightnorth.com/blog/xml-sitemaps-and-robots-txt-how-to-guide-search-engines-effectively/)
> [How to Set Up XML Sitemaps for SEO Success - RebelMouse](https://www.rebelmouse.com/sitemap-seo-best-practices)
---
## 7. Strategy #6: Image and Video Sitemaps for Visual Search
Visual search is bigger than ever in 2026. Google Lens, image search, and video search drive significant traffic — and dedicated sitemaps help you capture it.
### image-sitemap.xml Structure
```xml
https://example.com/product/item-1
https://example.com/images/item-1.jpg
Product description
Detailed product caption
```
Include these image types:
- Product images (essential for e-commerce)
- Infographics
- Featured article images
### video-sitemap.xml Required Tags
Video sitemaps have several mandatory fields:
- ``: Video title
- ``: Description
- `` or ``: Video file or player URL
- ``: Thumbnail image
- ``: Publication date
Include these video types:
- Tutorial videos
- Product demos
- Explainer content
### For Smaller Sites
If you only have a handful of images or videos, embed the `image:image` or `video:video` namespaces directly in your main sitemap rather than creating separate files. Scale to dedicated files as your catalog grows.
[LinkSurge](https://linksurge.jp/) helps you analyze your site's technical SEO health, including sitemap integrity and indexing gaps.
> References:
> [Image Sitemaps - Fundamentals and Best Practices - SEO Day](https://www.seo-day.de/wiki/on-page-seo/bilder-seo/image-sitemaps.php?lang=en)
> [Incorporating Video and Image Content in XML Sitemaps - Peak Positions](https://www.peakpositions.com/tech-tips/incorporating-video-and-image-content-in-xml-sitemaps/)
> [Sitemap Best Practices - Respona](https://respona.com/blog/sitemap-best-practices/)
---
## 8. Common XML Sitemap Mistakes in 2026
Before implementing the strategies above, check whether you're making any of these errors. Even one can turn your sitemap from an asset into a liability.
- **Including noindex pages**: Sends contradictory signals to Google
- **Listing non-canonical URLs**: Creates confusion between canonical tags and sitemap entries
- **Exceeding 50,000 URLs in one file**: Invalidates the entire sitemap
- **Never updating ``**: Google can't detect freshness signals
- **Including parameter URLs**: Filter and sort parameters belong nowhere near your sitemap
- **Missing image/video sitemaps**: Leaving visual search traffic on the table
- **Not monitoring Search Console errors**: Submitting and forgetting is the root cause of most sitemap problems
For a beginner-friendly guide to modern SEO fundamentals, see "[SEO in 2026: Beginner's Guide to AI-Era Optimization](/blog/en/seo-latest-guide-2026/)."
> References:
> [Build and Submit a Sitemap - Google Search Central](https://developers.google.com/search/docs/crawling-indexing/sitemaps/build-sitemap)
> [XML Sitemap Best Practices for SEO - BrightSEO Tools](https://brightseotools.com/post/xml-sitemap-best-practices-seo)
> [8 best sitemap generator tools - Zapier](https://zapier.com/blog/best-sitemap-generator/)
---
{{linksurge-card}}
---
## Frequently Asked Questions
### At what site size should I start segmenting my sitemap?
Segmentation is recommended for sites with 1,000+ pages. Even smaller sites benefit if content types are clearly distinct (e.g., blog posts + product pages). Above 10,000 pages, segmentation becomes essential for maintaining healthy index rates.
### If Google ignores ``, is there any point setting it?
Both Google and Bing ignore it, but Yandex officially uses it as a crawl-prioritization hint. It also serves as internal documentation for URL importance. If the setup cost is low, keep it — but invest your energy in accurate `` timestamps, which can help Google schedule recrawls when they're accurate and reflect genuine changes.
### How often should a dynamic sitemap update?
Match your content update cadence. E-commerce sites should update in real time when products are added or removed. Blogs can update on publish. Corporate sites can refresh weekly. The key is that `` accurately reflects actual content changes.
### What should I check if my sitemap index rate drops below 80%?
Start with the Coverage report in Search Console. The most common culprits are duplicate content, noindex pages, and redirect chains still listed in the sitemap. Remove those URLs, fix canonical settings, and resubmit. Then monitor weekly until the rate recovers to 95% or higher.
---
## Conclusion: Start Treating Your Sitemap as Discovery and Indexing Infrastructure
Your XML sitemap is not just a file for Google. It helps search engines discover relevant URLs and understand which pages have materially changed.
Worth being precise here: **a sitemap can't dictate crawl order**. Google treats it as a hint for finding what to crawl, not as an instruction to process URLs in the order or priority you submitted them.
The same goes for rankings — **a sitemap is not a ranking factor**. It has no mechanism to push a page up the results. What it affects is the stage before that. Since a page that isn't indexed can't rank at all, reliable discovery and indexing is what gets you to the starting line.
Segment it. Keep `` accurate. Maintain it. Monitor it. Stop treating your sitemap like a checkbox and start treating it like the discovery and indexing infrastructure it is. The goal: 95%+ index rates and new content indexed within 48 hours.
LinkSurge's [SEO analysis tools](https://linksurge.jp/) help you monitor indexing health and technical SEO improvements in real time.
---
## Safe Link Building in 2026: 5 White-Hat Strategies to Earn Backlinks Without Penalties
> URL: https://linksurge.jp/blog/en/safe-link-building-guide-2026/
> Date: 2026-04-04 | Category: SEO | Author: Aro Ogata
> Tags: SEO, Link Building, Backlinks, Digital PR, HARO, White Hat SEO
## Key Takeaways: 5 Safe Link Building Strategies for 2026
"I know backlinks matter, but I'm terrified of getting penalized." This is, honestly, the most common concern I hear when consulting on SEO strategy. In 2026, link buying and PBNs are detected with alarming accuracy by SpamBrain, but **earning backlinks through legitimate methods remains one of the most effective SEO strategies available**.
1. **Digital PR produces the highest-quality links** — Provide newsworthy original data or stories to media outlets and earn editorial links. Expect DR 50–85+ placements, with ROI estimates of 250–625% according to agency case studies
2. **HARO and journalist matching deliver high-DR links at low cost** — Respond to journalist queries as a subject-matter expert to earn DR 60–85 backlinks. Placement rates run 5–15%, so speed and quality are critical
3. **Original research becomes a compounding link asset** — Data-driven reports and infographics continue earning citations for years. One case study reports 22 backlinks, 3 interview requests, and 156% branded search growth from a single report
4. **Resource page and broken-link outreach is highly repeatable** — Find existing resource pages or broken links and propose your content as a replacement. Low-cost with predictable results
5. **Never rely on a single tactic. Diversification is the rule** — No single method should account for more than 30–40% of your link profile. This is what Google recognizes as a natural backlink pattern
Here's the thing: each of these strategies has specific playbooks, costs, and timelines. Let's break them down.
---
## 1. Link Building in 2026: Why "Earning" Is the Only Sustainable Path
Google has consistently valued naturally earned editorial links above all else. Their SEO link best practices documentation specifies that crawlable `` links serve as search signals, while their spam policies explicitly prohibit link buying, PBNs, and large-scale guest posting campaigns.
What struck me when reviewing the latest industry data is how definitively the economics have shifted. SpamBrain analyzes link patterns, content similarity, and hosting infrastructure across entire networks, issuing bulk penalties. Even if purchased links temporarily boost rankings, the traffic lost during a penalty—and the months needed for recovery—make it a losing proposition.
[Satellite Site SEO Is Dead: The Reality of Google Penalties and Safe Link Building](/blog/en/satellite-site-seo-risks-2026/) covers why PBNs and satellite sites get detected. This article focuses on what you should be doing instead.
### What makes link building "safe"?
Safe link building always starts with creating a genuine reason for third parties to link to you voluntarily. That means newsworthy content, proprietary data, expert knowledge, or practical tools—assets that provide real value to the linking site's audience. The five strategies below all satisfy this principle.
> References:
> [SEO Link Best Practices for Google - Google Search Central](https://developers.google.com/search/docs/crawling-indexing/links-crawlable)
> [Why Use Digital PR For Link Building - BuzzStream](https://buzzstream.com/blog/digital-pr-link-building/)
> [15 White Hat Link Building Tactics That Google Loves - BuzzStream](https://buzzstream.com/blog/white-hat-link-building/)
---
## 2. Digital PR: The Gold Standard for High-Quality Backlinks
Digital PR involves providing newsworthy content—original data, survey results, trend analyses—to media outlets in exchange for editorial coverage and links. Among link building experts, it's consistently rated as the method that produces the highest-quality backlinks.
### The 6-Step Digital PR Playbook
**Step 1: Ideation** — Monitor industry trends and analyze competitor backlinks to identify uncovered news angles. Think like a journalist: "What story would I want to write?"
**Step 2: Asset creation** — Build a clear headline, executive summary, visuals (charts and infographics), and a press-ready kit. Evergreen assets continue earning links long after launch.
**Step 3: Media list building** — Assemble a Dream-100 list of journalists and outlets. Vet targets for editorial quality, DR/traffic metrics, and audience relevance.
**Step 4: Personalized pitch** — A 1–2 sentence hook + 1 line of credentials. Keep emails under 150 words. Include 1–2 follow-ups spaced 48–72 hours apart.
**Step 5: Fulfillment** — Respond quickly to journalist follow-ups with on-record quotes, data tables, and embed codes for charts to maximize link inclusion.
**Step 6: Measurement** — Track placements (dofollow vs. nofollow), referral traffic, and organic ranking movements.
### Cost and ROI
Digital PR isn't cheap. Per-link costs typically range from $750–$1,500+, with agency retainers running $3,000–$15,000+ per month. However, one analysis estimates that a $60K/year digital PR investment can acquire 40–80 high-authority backlinks, increase traffic by 60–150%, and deliver ROI of 250–625%.
[LinkSurge](https://linksurge.jp/)'s backlink analysis tools can help you visualize which media outlets your competitors are earning links from, giving you a head start on targeting.
> References:
> [Digital PR vs Link Building: ROI & Hybrid Strategies - Casey's SEO](https://caseysseo.com/digital-pr-vs-traditional-link-building-roi-comparison-and-hybrid-strategies/)
> [10 Essential Digital PR Strategies for 2025 - Press Ranger](https://pressranger.com/blog/digital-pr-strategies)
> [Link Building Stats 2025: 50+ Data Points - RockingWeb](https://rockingweb.com.au/link-building-statistics-2025/)
---
## 3. HARO and Journalist Matching: Turn Expertise Into Links
Even without original data, your **expertise itself is a link-earning asset**. Platforms like HARO (Help A Reporter Out) and Qwoted connect journalists seeking expert commentary with subject-matter specialists willing to be quoted.
### HARO Tactics That Work
**Speed is everything** — Respond within 0–4 hours of a query going live. I've found that a one-day delay usually means the journalist has already received enough responses.
**Response template** — Keep it to 100–200 words: ①Full name, title, company, ②One-sentence credential ("10+ years in X"), ③Direct answer to the query with a specific example or stat, ④Contact info.
**Realistic expectations** — Placement rates run 5–15%. Expect 0–3 backlinks per month. But when you do get placed, the quality is outstanding—DR 60–85 is typical.
### Platform Landscape in 2026
HARO has undergone brand transitions (Connectively and back). Alternative platforms like Qwoted and MentionMatch offer different mixes of opportunities. The best approach is to monitor multiple platforms and respond selectively to high-relevance queries.
> References:
> [HARO Link Building Playbook - uSERP](https://userp.io/link-building/guide-to-haro-link-building/)
> [HARO Link Building: A 6-Step Shortcut - LinkDoctor](https://linkdoctor.io/haro-link-building/)
> [HARO Link Building in 2026: Worth It or Outdated? - Editorial.Link](https://editorial.link/boost-your-seo-with-haro-link-building/)
> [5 Best HARO Alternatives in 2026 - Backlinko](https://backlinko.com/haro-alternatives)
---
## 4. Original Research and Linkable Assets: Build Once, Earn Forever
A linkable asset is any content that other sites consider worth citing and linking to. Here's the thing: once created, these assets generate backlinks on autopilot—a compounding return that no other tactic can match.
### 6 Types of Effective Linkable Assets
**Original research reports** — Surveys of 300–500+ respondents or proprietary data analysis. One case study shows a single industry report generating 22 backlinks, 3 interview requests, and 156% branded search growth.
**Interactive tools** — Calculators, diagnostic tools, free checkers. Tools that people use repeatedly and share naturally earn links without outreach.
**Infographics** — Complex data presented visually. Provide embed codes so bloggers can share them with attribution links.
**Industry benchmarks** — "Average conversion rate in X industry" data. Update annually for evergreen citation value.
**Free templates and checklists** — High-utility downloads that generate links through practical value.
**Comprehensive guides** — Aim to be the most thorough resource on a topic. [The Complete SEO Guide](/blog/en/seo-guide-2026/) is an example of a guide-format asset that earns ongoing citations as an industry reference.
### From Creation to Distribution
1. Define research questions and ensure statistically significant sample sizes
2. Collect data, create visuals (charts, PDFs, embeddable formats)
3. Offer journalists exclusive angles or embargo windows
4. Publish on your site with strategic internal linking
5. Amplify through social media and targeted outreach
{{linksurge-card}}
> References:
> [How To Build Linkable Assets With AI In 2026 - Search Logistics](https://searchlogistics.com/learn/seo/link-building/linkable-assets/)
> [Linkable Assets: A Guide to Building Powerful Backlinks - SeoProfy](https://seoprofy.com/blog/linkable-assets)
> [Link Building Strategies 2025 - Digital Applied](https://digitalapplied.com/blog/link-building-strategies-2025)
---
## 5. Cost and ROI: The Real Numbers Behind Link Building
"How much does link building cost?" is the question I get asked most frequently. Here's an honest breakdown by tactic.
### Cost, Timeline, and Expected Links by Tactic
| Tactic | Cost Per Link | Monthly Links | Time to Results | Link Quality (DR) |
|--------|--------------|---------------|-----------------|-------------------|
| Digital PR | $750–$1,500+ | 3–7 | 3–12 months | DR 50–85+ |
| HARO/Journalist matching | $50–$200 (labor) | 0–3 | Immediate–3 months | DR 60–85 |
| Original research | $500–$2,000+ | Ongoing after launch | 3–12 months | DR 30–70+ |
| Resource/broken-link | $200–$500 | 2–5 | Weeks–months | DR 20–60 |
| Expert roundups | $100–$300 | 1–3 | 2–8 weeks | DR 20–50 |
### Understanding Link Building ROI
To accurately measure ROI, compare cost-per-link against the lifetime organic traffic value each link generates. According to BuzzStream's research, a high-quality backlink costs $508–$1,000+ on average—but a single DR 50+ link can drive thousands to tens of thousands of dollars in organic traffic value annually.
### Recommended Budget Allocation by Company Size
**Small/local businesses** — Focus on HARO responses, expert quotes, resource page and broken-link outreach. Expect 0–3 links/month with measurable results in 3–6 months.
**Mid-market companies** — Run periodic original research alongside digital PR and resource outreach. Target several quality links per month with consistent ROI within 3–6 months.
**Enterprise** — Multi-asset strategy + full digital PR campaigns + dedicated teams. Expect significant authority growth and traffic lifts over 6–24 months.
> References:
> [The True Cost of Link Building in 2025 - ReportCard](https://reportcard.com/blog/link-building-cost/)
> [Link Building Costs in 2025: Real Prices & ROI - SearchBerg](https://searchberg.com/blog/link-building-cost-2025/)
> [70 Link Building Statistics - BuzzStream](https://buzzstream.com/blog/link-building-statistics/)
---
## 6. What to Avoid: The Link Building Risk Spectrum
Understanding the risk spectrum is essential for making informed decisions about which tactics to use—and which to avoid entirely.
### Safe (Green)
- **Editorial links** — Earned through journalist editorial judgment. Highest value
- **Digital PR** — Based on newsworthy content. Google-endorsed approach
- **Original research and data** — Natural citation motivation exists
### Caution (Yellow)
- **Guest posting** — Small-scale, high-quality contributions are fine. Large-scale guest posting campaigns are explicitly defined as a link scheme by Google
- **Reciprocal links** — A few natural reciprocal links are normal. Organized link exchanges violate guidelines
### Dangerous (Red)
- **PBNs (Private Blog Networks)** — Detected with high accuracy by SpamBrain. Entire networks risk deindexation
- **Link purchasing** — Clear Google guideline violation. Subject to manual penalties
- **Auto-generated links** — Comment spam, forum spam, etc. Detected and devalued immediately
### The Diversification Principle
No single tactic should exceed 30–40% of your total link acquisition. Even safe methods, when overly concentrated, can create unnatural link profile signals.
[The Complete Guide to Off-Site SEO and GEO](/blog/en/offsite-seo-geo-2026/) covers link building within the broader context of off-site SEO strategy.
> References:
> [Why Google Penalises Certain Link Building Patterns - Hashmeta](https://hashmeta.com/blog/why-google-penalises-certain-link-building-patterns-understanding-and-avoiding-seo-penalties/)
> [White Label Link Building for Agencies: 2025-2026 - ALM Corp](https://almcorp.com/blog/white-label-link-building-for-agencies-2025-2026-tactics/)
---
{{linksurge-card}}
---
## Frequently Asked Questions
### Is link building still effective for SEO in 2026?
Yes. Backlinks remain one of Google's primary ranking factors. However, the emphasis has shifted decisively toward quality over quantity. A single link from a DR 50+ authoritative site is worth more than 100 links from low-quality domains.
### Are there free link building methods?
HARO (free plan) responses, resource page outreach, and broken-link proposals cost essentially nothing beyond time. These are the most cost-effective starting points for small businesses.
### Is guest posting still viable?
Small-scale, high-quality guest contributions remain effective. However, Google explicitly defines "large-scale guest posting campaigns" as a link scheme. The litmus test: "Would I contribute to this publication even without the link?"
### How long does it take to see results from link building?
HARO can produce results in days to weeks. Digital PR typically shows initial results in 3–6 months. Significant organic traffic growth usually appears after 6–12 months. LinkSurge's rank tracking lets you monitor ranking changes in real-time after acquiring new backlinks.
### Do nofollow links have any value?
They don't pass PageRank directly, but they contribute to brand awareness, referral traffic, and E-E-A-T (Experience, Expertise, Authoritativeness, Trustworthiness) signals. High-authority nofollow links should not be dismissed.
---
## Conclusion: Stop Buying Links. Start Earning Them.
Link building in 2026 is fundamentally a competition to create reasons for others to link to you voluntarily. Earn media coverage through digital PR, convert expertise into links through HARO, build compounding research assets, and steadily accumulate links through resource page and broken-link outreach.
These strategies take time, but they carry zero penalty risk and maximize the compound effect of SEO investment. Start by inventorying your strengths: proprietary data points to original research, domain expertise points to HARO, and newsworthy activity points to digital PR.
Use LinkSurge's [backlink analysis tools](https://linksurge.jp/) to visualize your current backlink profile alongside your competitors'. Understanding where you stand is the first step toward building a link acquisition strategy that delivers sustainable results.
---
## Topic Clusters & Internal Linking Strategy: A 2026 Guide to Site Architecture That Ranks
> URL: https://linksurge.jp/blog/en/topic-cluster-internal-linking-strategy/
> Date: 2026-04-04 | Category: SEO | Author: Aro Ogata
> Tags: Topic Clusters, Internal Linking, Site Architecture, Link Equity, Page Pruning
## Key Takeaways: Site Structure Is Your SEO Foundation
1. **Topic clusters are a useful structure in the AI search era** — A pillar-plus-cluster structure organizes a topic systematically, which helps search engines and AI answer systems discover and make sense of your coverage. Figures such as "roughly 30% more organic traffic" and "2.5x longer ranking retention" are widely quoted, but we could not verify their sources — treat them as directional.
2. **The 3-click rule keeps your architecture flat** — Place every important page within 3 clicks of the homepage. Pages buried deep in the hierarchy have thinner internal-link pathways, so both crawlers and readers reach them less often.
3. **Internal links concentrate link equity where it matters** — Strategic internal links from high-authority pages to revenue-critical pages can outperform a low-quality external backlink (an observation from our own work, not a verified general rule). The sweet spot is 2–5 contextual links per 1,000 words.
4. **Page pruning raises your site's quality density** — Removing or noindexing thin, zero-traffic pages saves crawl budget and lifts the remaining pages' evaluations. Google's August 2024 core update rewarded sites that pruned low-quality content.
5. **Design → Implement → Measure in a continuous cycle** — Topic cluster impact is measurable through A/B tests and staged rollouts. Combine Google Search Console, GA4, and crawl data to track impressions, clicks, CTR, and rankings.
The sections below walk through each theme in detail.
---
## 1. What Are Topic Clusters? The Pillar Page Concept Explained
### How does a topic cluster actually work?
A topic cluster is a content architecture where a single comprehensive pillar page (the hub) links to — and is linked from — multiple cluster pages (the spokes), each covering a specific subtopic. This hub-and-spoke model helps search engines and AI systems recognize that your site thoroughly covers a topic.
What struck me about the 2025–2026 research is how consistently this structure outperforms traditional flat blog approaches. It's not just a Google ranking factor anymore — AI answer engines like Google AI Overviews, ChatGPT, and Perplexity actively favor sources that demonstrate comprehensive topical coverage.
### What makes a strong pillar page?
The practical recommendation is to create pillar pages as comprehensive guides of 2,500–5,000 words. They serve as a "table of contents" for the topic, linking to each cluster page. Cluster pages, in turn, dive deep into specific subtopics and always include a link back to the pillar.
The number of cluster pages per pillar varies by topic breadth — typically 5 to 30 articles. What matters is coverage completeness, not hitting a specific number.
Our [Complete SEO Guide for 2026](/blog/en/seo-guide-2026/) covers the full SEO landscape, but site architecture is arguably the technical backbone that everything else depends on.
> References:
> [Pillar Pages & Topic Clusters for SEO Growth 2026 - Web Spider Solutions](https://webspidersolutions.com/boost-seo-2026-pillar-pages-topic-clusters/)
> [The complete guide to topic clusters and pillar pages for SEO - Search Engine Land](https://searchengineland.com/guide/topic-clusters)
> [A Topic Cluster Content Strategy for 2026 - Brafton](https://www.brafton.com/blog/strategy/topic-cluster-content-strategy/)
---
## 2. Why Flat Architecture Wins — The 3-Click Rule
### What's the evidence behind the 3-click rule?
The 3-click rule means every important page on your site should be reachable within 3 clicks from the homepage. It is a UX convention and an architectural one: it affects how easily both crawlers and readers reach a page.
Here's the thing: pages buried deep in a hierarchy are harder for search engines to discover, because the further a page sits from the homepage, the thinner its internal-link pathways become. Google's [crawl budget guide](https://developers.google.com/search/docs/crawling-indexing/large-site-managing-crawl-budget) states that "URLs that are more popular on the Internet tend to be crawled more often" — note that it does not name PageRank. Treat "depth 4" as a rough heuristic rather than a ranking threshold. You will also see "40–70% improvements in crawl efficiency" quoted for flat architectures; we could not identify the underlying study, so treat that as a directional figure.
### Practical tactics for flat architecture
To keep your site hierarchy shallow:
- **URL design**: Use 2–3 level structures like `/category/subcategory/article/`
- **Breadcrumbs**: Mark up with BreadcrumbList structured data to reinforce hierarchy signals
- **Global navigation**: Provide links to major categories across all pages
- **Contextual links**: Place natural in-content links to reduce effective click depth
LinkSurge's SEO analysis dashboard helps you visualize your site structure and identify pages with click-depth issues.
> References:
> [Internal Linking Strategy: Complete SEO Guide for 2026 - Ideamagix](https://www.ideamagix.com/blog/internal-linking-strategy-seo-guide-2026/)
> [Internal Linking Strategy 2026: Site Architecture That Ranks - Mavic Labs](https://www.maviklabs.com/blog/internal-linking-strategy-2026)
> [Best Internal Linking Strategy for SEO 2026 - Data Enriche](https://www.dataenriche.com/best-internal-linking-strategy-seo/)
---
## 3. Concentrating Link Equity Through Internal Links
### How does link equity flow through internal links?
"Link equity" is the SEO industry's shorthand for the ranking weight that flows between pages through links.
It is often treated as a synonym for PageRank, but they are not the same thing. PageRank is one of many ranking systems Google operates; it did not go away, only the public score did ([Gary Illyes](https://www.seroundtable.com/google-still-using-pagerank-23392.html)). Link equity, by contrast, is an industry-side label for those mechanics collectively — not a metric Google publishes. Google also describes links as signals for understanding relevance and discovering pages, so an internal link does not mechanically transfer ranking power to its target.
Honestly, internal linking feels like one of the most underutilized levers I see. I've watched target pages climb after nothing more than adding internal links from backlink-heavy blog posts to product pages.
That is an observation from sites I have worked on, though — not a verified general rule that one internal link beats one low-quality backlink. What an internal link reliably buys you is discoverability and a relevance signal from the linking page.
### Optimal link volume and anchor text
A common rule of thumb is 2–5 contextual links per 1,000 words.
You will often see a hard cap quoted for total links per page. That number traces back to the "about 100 links" line in Google's old webmaster guidelines, which [has since been removed](https://searchengineland.com/googles-matt-cutts-we-dropped-the-100-links-per-page-guideline-but-we-may-take-action-if-it-is-too-spammy-178197); Google has said it was never a technical limit. You will also hear that equity per link thins out as you add more. That comes from the original PageRank formula, not from verified current behavior. The practical concern is simpler: too many links make it hard for a reader to know which one to follow, so keep the emphasis on in-content contextual links and stay within what a reader can actually follow.
The principle for anchor text is simple: **make it describe what the reader will find on the other end.** Avoid "click here" and "read more," which say nothing about the destination.
You will see recommended ratios for exact-match versus partial-match anchors. That framing originated in the context of **external backlinks and penalty avoidance**. Google publishes no distribution rule for internal anchor text, and there is little basis for transplanting the external-link ratios here — so this guide does not prescribe one.
### Three-directional linking within clusters
Inside a topic cluster, combine three link directions:
1. **Downward (Pillar → Cluster)**: The pillar links to each cluster page
2. **Upward (Cluster → Pillar)**: Each cluster page links back to the pillar
3. **Lateral (Cluster ⇄ Cluster)**: Related cluster pages link to each other
This three-directional structure strengthens topical cohesion, helping search engines recognize the entire cluster as a single topical authority.
Our guide on [Off-Site SEO and GEO](/blog/en/offsite-seo-geo-2026/) explains external link strategies worth designing alongside internal linking, so that pages accumulating backlinks have clear pathways into the pages that matter to you.
> References:
> [Internal Links SEO Best Practices - Moz](https://moz.com/learn/seo/internal-link)
> [Google's Matt Cutts: We Dropped The 100 Links Per Page Guideline - Search Engine Land](https://searchengineland.com/googles-matt-cutts-we-dropped-the-100-links-per-page-guideline-but-we-may-take-action-if-it-is-too-spammy-178197)(the origin of the "links per page" cap, and its removal)
> [Google's Gary Illyes: We're Still Using PageRank - Search Engine Roundtable](https://www.seroundtable.com/google-still-using-pagerank-23392.html)(PageRank remains in use internally)
> [How many internal links should you have per page? - InLinks](https://inlinks.com/insight/how-many-internal-links-should-you-have-per-page/)
> [Internal Linking for SEO: Complete 2026 Guide - LinkWhisper](https://linkwhisper.com/the-ultimate-guide-to-internal-linking-for-seo-and-geo/)
---
{{linksurge-card}}
---
## 4. Building Topic Clusters — A 5-Step Framework
### How should you design a topic cluster from scratch?
Let me walk you through the practical 5-step process.
**Step 1: Select your core topic**
Choose a single topic central to your business. For an SEO platform, "SEO strategy" could be the core. Selection criteria: search volume exists, it's business-relevant, and it can be broken into sufficient subtopics.
**Step 2: Research subtopics**
Break the core topic into subtopics with distinct search intents. Use keyword research tools to check volume, competition, and intent for each. Aim for 5–30 subtopics per pillar.
**Step 3: Create the pillar page**
Build a comprehensive 2,500–5,000 word guide that covers the topic's full scope. Include an overview of each subtopic with links to the corresponding cluster pages.
**Step 4: Write cluster articles**
Create in-depth articles for each subtopic. Each article must include a link back to the pillar and lateral links to related cluster articles.
**Step 5: Design and implement internal links**
Review the entire cluster's link structure. Check for broken links and orphan pages. Use Google Search Console's internal links report to monitor distribution over time.
LinkSurge's keyword analysis features streamline Step 2 — you can research search volume, competition, and intent across all your subtopics in a single workflow.
> References:
> [Topic Clustering Guide: Build Authority with Pillar Pages in 2026 - ClickRank](https://www.clickrank.ai/topic-clustering-in-content-seo/)
> [How to Build Pillar Content: A Step-by-Step Guide 2026 - NiuMatrix](https://niumatrix.com/pillar-cluster-content-guide/)
> [How To Boost SEO and DR in 2026 With Topic Clusters - StoryChief](https://storychief.io/blog/topic-clusters-seo)
---
## 5. Page Pruning — Criteria and Execution
### Why is page pruning necessary?
Page pruning (content pruning) means removing, consolidating, or noindexing underperforming pages to raise your site's overall quality density. Here's why it matters: search engines evaluate your site's overall quality. A high proportion of thin pages can drag down even your best content.
Google's August 2024 core update delivered clear evidence — sites that pruned low-quality content saw ranking improvements for their remaining pages. Removing thin pages from the index can actually make your other pages rank higher.
### Four actions for deciding
Categorize each page into one of four actions. (This guide labels them KUMD — Keep / Update / Merge / Delete — as shorthand; it is not an established industry term.)
- **Keep**: Low traffic but contributes to conversions or has backlinks
- **Update**: Outdated content on a valuable topic → rewrite it
- **Merge**: Multiple pages covering similar themes → consolidate into one, 301 redirect the old URLs
- **Delete**: Zero traffic, no backlinks, no improvement potential → return 410 status (see below on choosing between 410 and noindex)
### Specific criteria to evaluate
Combine these data points for each page:
1. **6–12 month organic traffic**: Identify pages with zero impressions/clicks in GSC
2. **Backlink profile**: Check with Ahrefs/Moz — don't casually delete pages with backlinks
3. **E-E-A-T assessment**: Outdated, thin, or inaccurate → pruning candidate
4. **Cannibalization check**: Are multiple pages competing for the same keywords?
### Noindex vs. deletion
**Noindex**: Page stays on your site but is removed from search index. Best when users might still access it directly or via site navigation.
**Delete (410)**: When the page serves no purpose. The 410 status code signals intentional removal to Google.
**301 redirect**: When the page has backlinks or you're merging similar content. Preserves link equity.
> References:
> [Index Bloat Is a Powerful SEO Fix You Need in 2026 - ClickRank](https://www.clickrank.ai/index-bloat/)
> [What to know about our August 2024 core update - Google](https://developers.google.com/search/blog/2024/08/august-2024-core-update)
> [Internal Linking Structure: The Ultimate 2026 SEO Guide - ClickRank](https://www.clickrank.ai/effective-internal-linking-structure/)
---
## 6. How to Treat the Numbers People Quote
### How much impact do topic clusters really have?
These are the figures that circulate in SEO write-ups and vendor reports on topic clusters.
> **Caution**: for each of the numbers below, we have not been able to verify the underlying study, its sample, or its methodology. Treat them as directional, not as a basis for your own targets or KPIs.
| Metric | Impact |
|--------|--------|
| Organic traffic | ~30% more vs standalone posts |
| Ranking retention | 2.5x longer |
| Crawl efficiency | 40–70% improvement |
| Ranking boost | Up to 40% |
| 12-month sustained growth | 40%+ traffic increase |
### Connection to Google core updates
Following Google's 2024 core updates (March and August), many sites reported heavy traffic losses. We have not found a study that attributes those losses to site architecture, though. Core updates are a broad reassessment of content quality, and structure cannot be isolated as the cause — so this guide cites neither the drop percentages nor a causal explanation.
The June 2025 core update doubled down on topical authority — rewarding sites that cover subjects thoroughly, consistently, and credibly.
### How to measure cluster performance
Track these metrics at the cluster level:
- **Cluster SOV (Share of Voice)**: Visibility share for your target keyword group
- **Impressions, clicks, CTR, average position**: From Google Search Console
- **Internal link CTR**: How often links within the cluster get clicked
- **Conversions**: GA4 conversion tracking through cluster entry points
Our [SEO in 2026: Beginner's Guide](/blog/en/seo-latest-guide-2026/) covers these measurement methods in greater detail.
> References:
> [How Pillar Pages Work: B2B SEO Strategy Guide 2026 - Whitehat SEO](https://whitehat-seo.co.uk/blog/how-seo-and-pillar-pages-work)
> [SEO Content Clusters 2026: Topic Authority Guide - Digital Applied](https://www.digitalapplied.com/blog/seo-content-clusters-2026-topic-authority-guide)
> [Topic Clusters for SEO: The Ultimate Strategy for Organic Growth in 2026 - EmbedPress](https://embedpress.com/blog/topic-clusters-for-seo/)
---
{{linksurge-card}}
---
## Frequently Asked Questions
### Do topic clusters work for small sites?
Yes — small sites often see faster results. Start with one pillar and 5–8 cluster articles. Complete one cluster fully and measure its impact before starting the next. The internal linking improvements alone can deliver quick wins.
### Won't page pruning cause traffic drops?
There may be short-term fluctuations. But with proper safeguards — checking backlinks, setting up 301 redirects, and implementing changes gradually — you'll typically see crawl and index improvements within 2–4 weeks. Start with obviously zero-traffic pages and avoid mass deletions.
### Is more internal linking always better?
There is no defined cap. The commonly quoted "100–150 links per page" traces back to a line in Google's old webmaster guidelines that has since been removed, and Google has said it was never a technical limit. The "equity per link thins out" explanation comes from the original PageRank formula rather than verified current behavior. What does hold up is that too many links make it hard for readers to know which to follow, so use 2–5 contextual links per 1,000 words as a working guide. Header and footer links appear identically on every page, so they carry no signal that a given page is especially related to the target. That is the reason to prioritize in-content contextual links.
### Can I reorganize existing content into topic clusters?
Absolutely — and it's highly effective. Start by auditing all your content and grouping it by theme. Select (or create) a pillar page for each group, then redesign your internal links. This reorganization alone tidies up the pathways into your important pages, making them easier for crawlers to reach and for readers to move between.
---
## Next Steps: Start Restructuring Today
Topic clusters and strategic internal linking are among the highest-ROI SEO investments you can make in 2026. With AI search engines prioritizing topical authority, building content as interconnected clusters — not isolated posts — is no longer optional.
Start by auditing your current site structure. Use Google Search Console's internal links report to find pages with concentrated links and orphaned pages. From there, select one core topic to cluster, aim for a flat hierarchy reachable within 3 clicks, and don't forget to prune the thin pages that dilute your site's quality signal.
LinkSurge's [SEO Analysis Dashboard](https://linksurge.jp/seo-hub) lets you run keyword analysis, competitor research, and site structure audits in one place — supporting data-driven decisions from cluster design through performance measurement.
---
## What Is LLMO? The Complete Beginner's Guide to AI Citation Optimization (2026)
> URL: https://linksurge.jp/blog/en/llmo-guide-beginners-2026/
> Date: 2026-04-01 | Category: AIO | Author: Aro Ogata
> Tags: LLMO, Large Language Model Optimization, GEO, AI citation, AI search optimization, RAG
## Key Takeaways: 5 Things to Understand About LLMO
**1. LLMO means "optimization for AI citation"** — Getting ChatGPT, Gemini, and other AI systems to retrieve and cite your content when generating answers. That's the core goal.
**2. Different from SEO, but complementary** — Traditional SEO targets search rankings and clicks. LLMO targets citation and brand mention inside AI-generated answers. You don't have to choose — they work together.
**3. RAG is the mechanism you need to understand** — AI systems don't generate everything from memory. They search and retrieve relevant web content in real time. Optimizing for this retrieval process is the heart of LLMO.
**4. You can start today without big investment** — Confirming crawler access, FAQ-formatted content, and a clear author/entity footprint are the first steps — all achievable at low or zero cost. Structured data (JSON-LD) is cheap too, but it hasn't been shown to increase AI citations, so it ranks lower (covered under "Technical setup" below).
**5. Measure with AI citation metrics, not just rankings** — AI-referred visitors tend to have higher conversion rates than traditional organic search visitors, according to emerging research. New metrics matter.
Here's a deeper look at each point.
---
## 1. What Is LLMO? A Simple Definition
**LLMO (Large Language Model Optimization)** is the practice of optimizing your content, website structure, and digital footprint so that AI systems — ChatGPT, Google Gemini, Anthropic Claude, Perplexity, and others — retrieve, reference, and cite your content when answering user queries.
Honestly, when I first heard the term, I assumed it was just another rebrand of SEO. It isn't. Here's the difference: with traditional SEO, success means your page appears in Google's results and a user *chooses* to click. With LLMO, success means an AI reads your content and *includes it* in its answer — sometimes before the user ever sees a search result page.
### What LLMO is trying to achieve
The goal is simple: when someone asks ChatGPT "What's the best tool for tracking AI citations?" you want your brand or content to appear in the AI's answer. That's AI citation — and it's becoming a meaningful discovery channel.
What struck me while researching this is that AI-referred traffic, while smaller in volume than organic search, tends to arrive with higher purchase intent. The user has already received an AI-curated recommendation; they're clicking through to learn more or buy.
For a ChatGPT-specific strategy covering its three index layers, crawler settings, citation-source map and measurement, see [How to Get Cited by ChatGPT: The Complete 2026 Guide](/blog/en/chatgpt-geo-complete-guide-2026/).
For how SEO's definition of a win moved from "position" to "position plus citation" over three decades, see "[How SEO Changed: From Keyword Stuffing to Getting Cited by AI](/blog/en/seo-history-keywords-to-ai-2026/)."
> References:
> [LLMO - Large Language Model Optimization - Effective World](https://www.effective-world.com/en/glossary/glossar-detail/llmo-large-language-model-optimization)
> [What Is LLMO? Optimize Content for AI & Large Language Models - Search Engine Land](https://searchengineland.com/guides/large-language-model-optimization-llmo)
---
## 2. LLMO vs. SEO vs. GEO vs. AIO: What's the Difference?
The alphabet soup of optimization acronyms is genuinely confusing. Let me sort it out.
### The four concepts explained
**SEO (Search Engine Optimization)** is the original. Rank higher in Google, Yahoo, or Bing, get more clicks. On-page optimization, link building, technical SEO — these are the tools. Still the dominant channel for most businesses.
**AIO (AI Overviews Optimization)** targets the AI-generated summary that appears at the top of Google search results. Getting your content cited there means appearing before any organic result. It's Google-specific.
**GEO (Generative Engine Optimization)** is the broader English-language term for optimizing across multiple AI engines — ChatGPT, Gemini, Perplexity, Claude. Not limited to any single platform.
**LLMO** is essentially synonymous with GEO, with slightly more emphasis on the underlying language model layer. In practice, the tactics are the same: structured content, entity clarity, technical accessibility, and E-E-A-T signals.
Here's the thing: these aren't competing strategies. A piece of content that's well-structured, authoritative, and clearly written will perform well across all four dimensions simultaneously. Think of LLMO not as "instead of SEO" but as "SEO plus AI discoverability."
> References:
> [Large Language Model Optimization (LLMO) explained - Evergreen Media](https://www.evergreen.media/en/guide/large-language-model-optimization/)
> [LLM Optimization vs Traditional SEO - SEONos](https://seenos.ai/llm-optimization/llm-optimization-vs-seo)
For a deeper dive into GEO implementation strategies, see our [Complete Guide to Generative Engine Optimization (GEO)](/blog/geo-guide-japan-2026/).
---
## 3. How AI Retrieves Your Content: RAG Explained
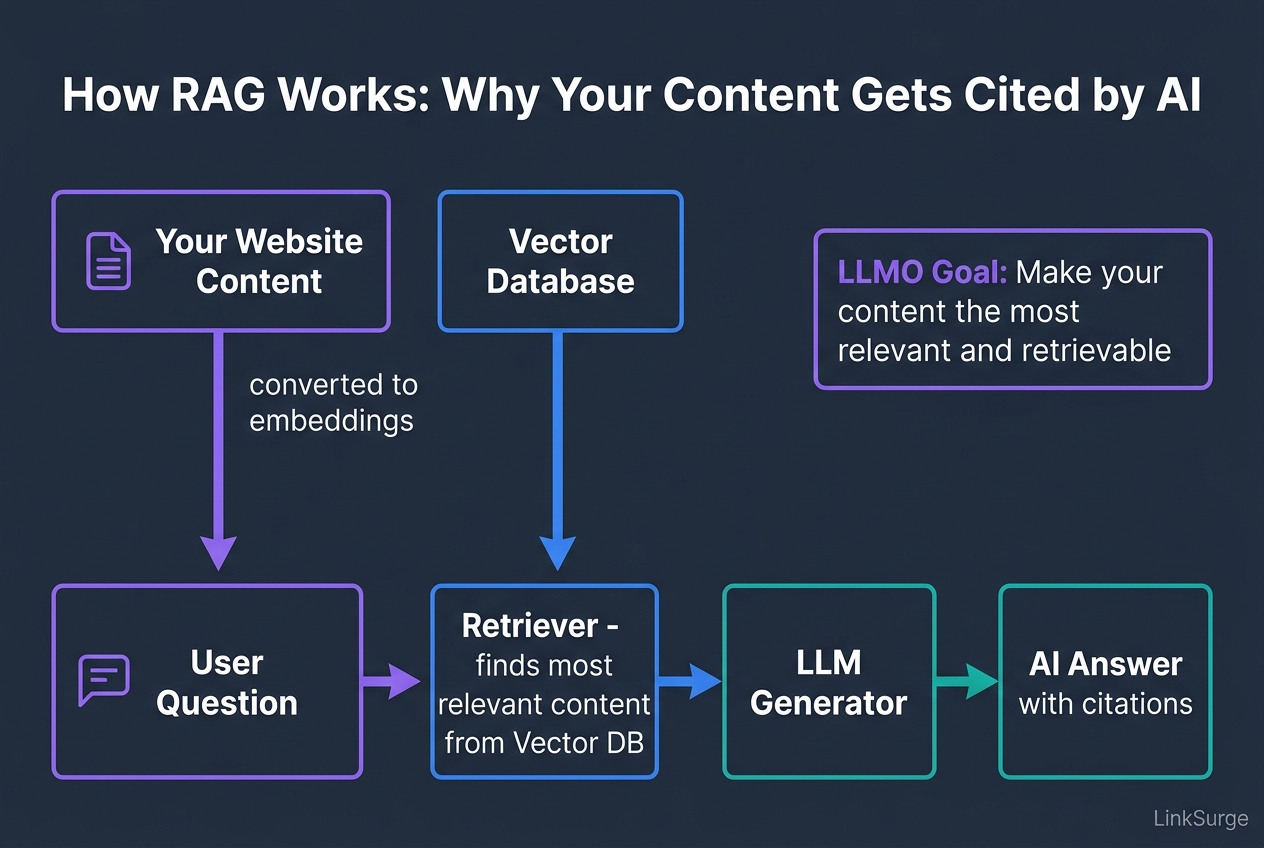
"Why does the AI cite one website and not another?" This is the question that unlocks everything. The answer is **RAG — Retrieval-Augmented Generation**.
### RAG in plain English
Most AI chat systems don't just rely on their training data. They actively search for relevant content at query time and use it to generate grounded answers. Here's the simplified flow:
1. **User submits a question** → "What tools help with AI citation tracking?"
2. **AI runs a retrieval query** → Searches for relevant documents using vector similarity search
3. **Retrieved documents are injected into the prompt** → "Based on these sources, answer the question"
4. **LLM generates a grounded response** → Including citations to the retrieved sources
Your LLMO goal is to win steps 2 and 3. Make your content discoverable by the retrieval layer and trustworthy enough to be injected into the generation prompt.
### What makes content "RAG-friendly"?
- **Atomic answers**: Self-contained paragraphs that answer one question completely (40–60 words each)
- **Semantic clarity**: Use the exact terms your target audience uses in questions
- **Structured signals**: FAQ markup, Article schema — signals that tell the retriever what each piece of content is about
- **Freshness**: Recently updated content is preferred by retrieval systems
> References:
> [Retrieval Augmented Generation (RAG) for LLMs - PromptingGuide](https://www.promptingguide.ai/research/rag)
> [What is RAG (Retrieval-Augmented Generation)? - OpenAPI](https://openapi.com/blog/what-rag-retrieval-augmented-generation)
---
{{linksurge-card}}
---
## 4. LLMO Implementation Checklist: Where to Start
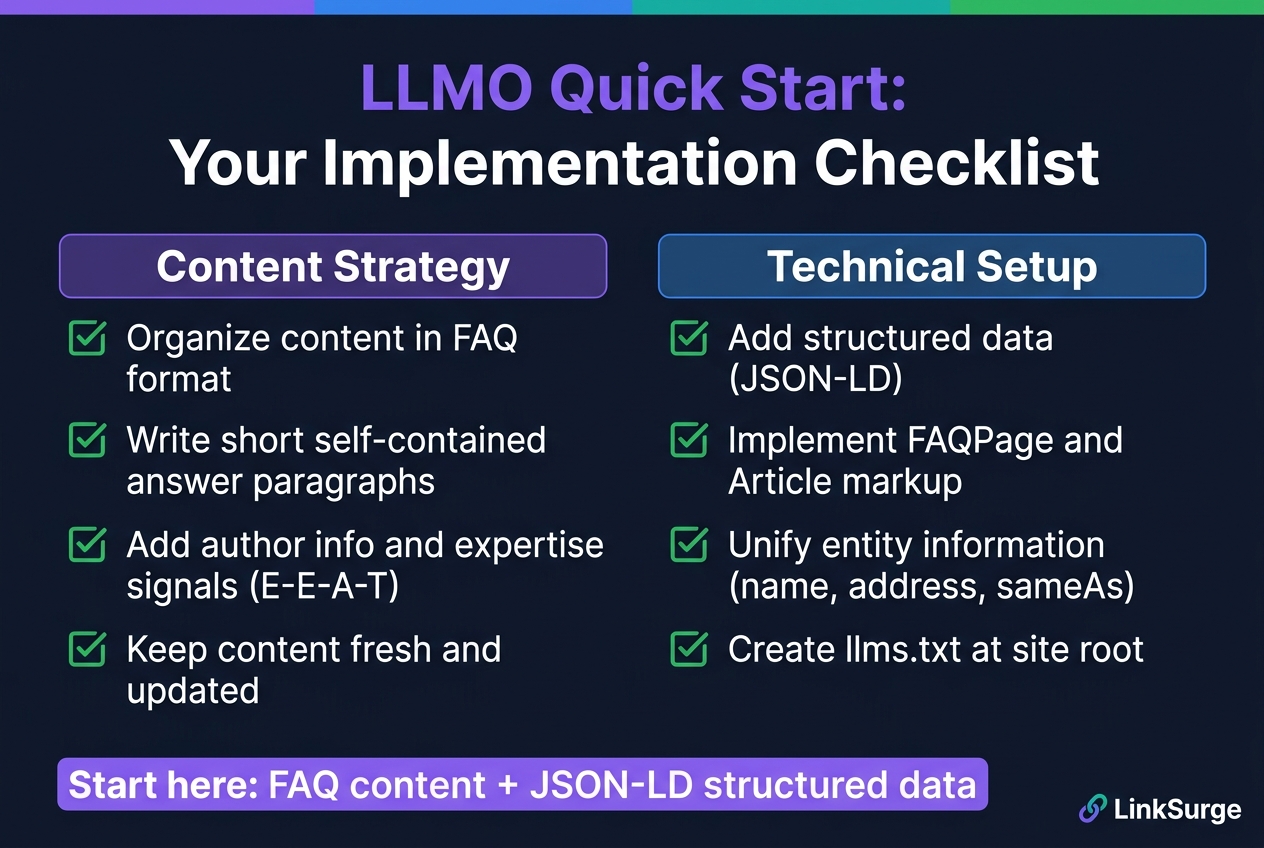
Based on the research and my own testing, here's a prioritized checklist for getting started with LLMO — from free, quick wins to deeper investments.
### Content strategy (start here)
**1. Reformat key pages with FAQ structure**
Explicit Q&A formatting helps AI systems identify and extract precise answers. "Q: What is LLMO? A: LLMO is..." is exactly the kind of extractable answer block that gets cited.
**2. Write self-contained "answer paragraphs"**
Each paragraph in your content should answer a specific question completely — without needing surrounding context. Aim for 40–60 words per answer block. This is the single highest-leverage LLMO tactic I've found.
**3. Strengthen E-E-A-T signals**
Include author names, credentials, publish dates, and update dates. For regulated industries (health, finance, legal), this is critical. AI systems weight authoritative sources more heavily.
**4. Update content regularly**
AI retrieval systems favor fresher content. Even minor updates that add new data, case studies, or statistics can improve retrieval frequency.
### Technical setup (next steps)
**5. Implement structured data (JSON-LD)**
Add `FAQPage`, `Article`, `Organization`, and relevant schema types using JSON-LD. This makes relationships like author, publish date, and product details machine-readable.
**This is not a "skip it" item, but it is also not a "do it first" item.** The common misreading here is treating Google's position as "Google doesn't use structured data." What Google actually says is that there are **no additional requirements to appear in AI Overviews or AI Mode, and no special schema.org structured data you need to add**. That's a statement about eligibility requirements — not a statement that schema goes unused internally.
With that distinction in place, treatment splits by platform:
| Platform | How structured data is treated |
|---|---|
| Bing / Copilot | **Officially confirmed as used.** Microsoft's Fabrice Canel (Principal Product Manager, Bing) confirmed at SMX Munich that schema markup helps Microsoft's LLMs understand your content |
| Google AI Overviews / AI Mode | Official documentation says **no additional requirements and no special schema** are needed for AI features. But not-required isn't not-used. A secondhand account (an attendee write-up, not Google primary documentation) reports a Google structured data engineer saying schema is served to models as context during query fan-out |
| Gemini | In one published test (a single SaaS site, December 2025 to March 2026), **Gemini was the only one of seven platforms** that successfully retrieved schema markup directly |
| ChatGPT / Perplexity | Both failed direct retrieval in that same test. A separate test, however, showed **the text inside JSON-LD being read** via a path that tokenizes the full HTML response |
That last row matters more than it looks. In that separate test, an address that appeared nowhere in the visible content — and sat only inside deliberately malformed JSON-LD — was returned as fact by both ChatGPT and Perplexity. Whether your JSON-LD gets read depends on the retrieval path and the scraper, but **paths that do read it demonstrably exist — so inaccurate markup can become a source of hallucinated answers about your brand.**
So the practical takeaway: **don't expect schema to increase AI citations, but keep it accurate if you implement it.** What's actually evidenced today is its value for traditional search appearance (rich results) and for helping Bing/Copilot understand your content. Note that Google discontinued HowTo rich results in 2023 and [FAQPage rich results in May 2026](https://developers.google.com/search/updates#removing-faq-rich-result). Types that still produce rich results include Article and BreadcrumbList (Product applies to product pages, and Review requires genuine user reviews or ratings of an eligible item — it is not valid on a general article). Treat it as work that comes after crawler access and content quality are handled.
> **Sources**: [AI features and your website — Google Search Central](https://developers.google.com/search/docs/appearance/ai-features) · [Microsoft Bing/Copilot use schema for its LLMs — Search Engine Land](https://searchengineland.com/microsoft-bing-copilot-use-schema-for-its-llms-453455) · [Schema Markup and AI Search: What a 3-Month Study Revealed — Otterly.AI](https://otterly.ai/blog/schema-markup-real-impact-ai-search/) · [The Three Lives of Schema Markup — Suganthan Mohanadasan](https://suganthan.com/blog/three-lives-of-schema-markup/)
**6. Unify your entity footprint**
Make sure your organization name, key product names, and author identities are consistent across all pages. Use `sameAs` to link to authoritative profiles (LinkedIn, Wikipedia, official registries).
**7. Create an llms.txt file**
An `llms.txt` file at your site root tells AI crawlers about your site's key pages and content — similar to `robots.txt` but for AI systems. It's low effort and potentially useful, though its direct impact on citation frequency hasn't been proven yet as of early 2026.
> **Caveat**: As of February 2026, there's no peer-reviewed evidence that having an `llms.txt` directly increases AI citation frequency. Treat it as a forward-looking investment, not a guaranteed quick win.
You can monitor how AI engines currently perceive your site using LinkSurge's [GEO analytics tools](https://linksurge.jp/geo) — track citation counts across ChatGPT, Gemini, and Perplexity in one dashboard.
> References:
> [Answer Engine Optimization (AEO): The 2026 Guide - LLMRefs](https://llmrefs.com/answer-engine-optimization)
> [What Is LLM Optimization? Key Benefits & Definitions - Conductor](https://www.conductor.com/academy/llm-optimization/)
For context on how AI is reshaping search behavior broadly, see our guide on [How AI Search Is Changing SEO in 2026](/blog/ai-search-seo-japan-2026/).
---
## 5. Measuring LLMO: New Metrics for a New Era
Traditional SEO is measured in rankings, impressions, and clicks. LLMO needs different metrics.
### The core LLMO KPIs
**AI citation frequency**
How often does your domain appear in AI-generated responses? Manual testing (ask ChatGPT, Gemini, and Perplexity relevant questions and note whether your site is cited) is a start. Automated monitoring tools are emerging.
**AI-referred traffic**
Track referral traffic from `chatgpt.com`, `perplexity.ai`, `bard.google.com`, and similar domains in your analytics. This is currently small but growing.
**AI citation share**
What percentage of AI answers in your topic area include your domain? This "share of voice" metric is the most meaningful for competitive positioning.
**AI-to-conversion rate**
Segment your analytics by AI referrer and measure conversion rates separately. Early evidence suggests AI-referred visitors convert at higher rates than average organic visitors — they arrive pre-qualified by AI recommendation.
---
We put several of these optimization rules to the test against real citation data in [Where Does AI Search Actually Quote From?](/blog/en/ai-citation-block-position-research-2026/), including whether "answer-first" writing holds up section by section.
---
## Frequently Asked Questions
### Is LLMO the same as GEO?
For most practical purposes, yes. GEO (Generative Engine Optimization) is the dominant English-language term; LLMO is more common in Japanese markets. GEO slightly emphasizes multi-engine optimization; LLMO emphasizes the underlying language model layer. The implementation tactics are essentially identical.
### Should I stop doing SEO and switch to LLMO?
No. SEO still drives the majority of web traffic and isn't going anywhere. LLMO is an additive strategy. Here's the good news: most LLMO best practices (quality content, structured data, E-E-A-T) also improve traditional SEO. You're not choosing between them.
### Does llms.txt actually work?
The honest answer is: we don't know yet. It's technically straightforward to implement and doesn't hurt anything. But as of early 2026, there's no published evidence that having an `llms.txt` file measurably increases AI citation rates. Prioritize content quality and structured data over llms.txt.
### How long does it take to see results?
AI training data isn't updated in real-time — so changes to your content may take weeks to months to be reflected in model behavior. However, for AI systems that use real-time web retrieval (like Perplexity), you may see faster results. Build LLMO as a sustained practice, not a one-time sprint.
### Do I actually need structured data (JSON-LD)?
**Not for the purpose of winning AI citations.** Google states that there are no additional requirements — and no special schema.org markup — needed to appear in AI Overviews or AI Mode, and a controlled experiment that added schema found no increase in AI citations. Note that this is a statement about eligibility requirements, not a claim that Google ignores schema internally. **It is, however, worth doing for other purposes.** Microsoft has publicly confirmed that Bing/Copilot's LLMs use schema markup to understand content, and schema still drives rich results in traditional search (though not for FAQPage or HowTo, both discontinued). In one published test of a single site across seven platforms, Gemini was the only one that retrieved schema directly; ChatGPT and Perplexity failed that particular test, though a separate test showed JSON-LD text being read through a different retrieval path. Since paths that read it do exist, the accuracy of what you write there matters. In short: **low priority, but still worth doing.** Implement it after crawler access and content quality are sorted, and make sure it never contradicts your visible content.
### What does LLMO cost?
The core tactics — FAQ formatting, structured data, entity consistency — cost nothing beyond the time to implement them. The bigger investments are AI citation monitoring tools and, if needed, RAG infrastructure for enterprise use cases. Start free, scale as needed.
---
## Conclusion: LLMO Is the Next Chapter of Content Strategy
The way people find information is changing. A meaningful and growing share of discovery now happens through AI-generated answers, not search result pages. LLMO is the practice of making sure your content is part of those answers.
What I find encouraging about LLMO is that it doesn't require abandoning what works. Good content — clear, authoritative, well-structured, regularly updated — is good for SEO and good for LLMO. The principles converge.
Start by **confirming the crawlers you care about can reach you** — that's a necessary condition, so clear it first. Then **reformat your most important pages as FAQ content**. Both cost nothing.
**JSON-LD structured data comes after those two — later, not never.** Microsoft has confirmed Bing/Copilot's models use schema, and published tests show Gemini retrieving it directly. Whether other assistants read your JSON-LD varies by retrieval path, but paths that do read it exist. Just don't expect it to lift your citation rate on its own, and make sure what it says matches your visible content (updated 2026-08).
LinkSurge's [GEO dashboard](/geo/dashboard) and [LLM mentions tracking](/geo/dashboard) give you the data to see where you stand today — and measure your progress as you implement LLMO strategies. Give it a try.
---
## Entity Authority Is the New Foundation of AI Search Visibility
> URL: https://linksurge.jp/blog/en/entity-authority-ai-search-2026/
> Date: 2026-03-17 | Category: AIO | Author: Aro Ogata
> Tags: entity SEO, AI search, knowledge graph, GEO, AI Overview, Wikidata, structured data
## Key Takeaways: Entity Definition Is the New Competitive Moat
After digging into how ChatGPT, Perplexity, and Google AI Overviews decide what to cite, one pattern stands out above everything else. It's not content volume. It's not domain authority in the traditional sense. The question these systems ask first is: *is this a defined, trustworthy entity?*
Here's what that means in practice:
1. **AI verifies entity trust before reading your content** — Before citing any brand, AI systems cross-reference knowledge graphs to confirm the entity exists, is consistently defined, and has third-party backing. Brands absent from Wikidata or the Google Knowledge Graph face a structural disadvantage regardless of content quality
2. **Knowledge graphs, Wikidata, and authoritative media form the "entity trust score"** — It's not individual pages that build this score. It's the coherent web of external, authoritative sources that consistently describe your brand with the same attributes
3. **Being clearly defined beats content volume** — A brand with 10 well-structured, entity-consistent pages will outperform one with 1,000 inconsistent pages in AI citation. The reasoning engine rewards clarity, not quantity
4. **Share of Model is becoming the metric that matters** — As AI-generated answers replace the traditional top-10 list, the question shifts from "where do we rank?" to "how often does AI mention us?"
Let's break each of these down.
---
## 1. AI Reads the Knowledge Graph Before It Reads Your Page
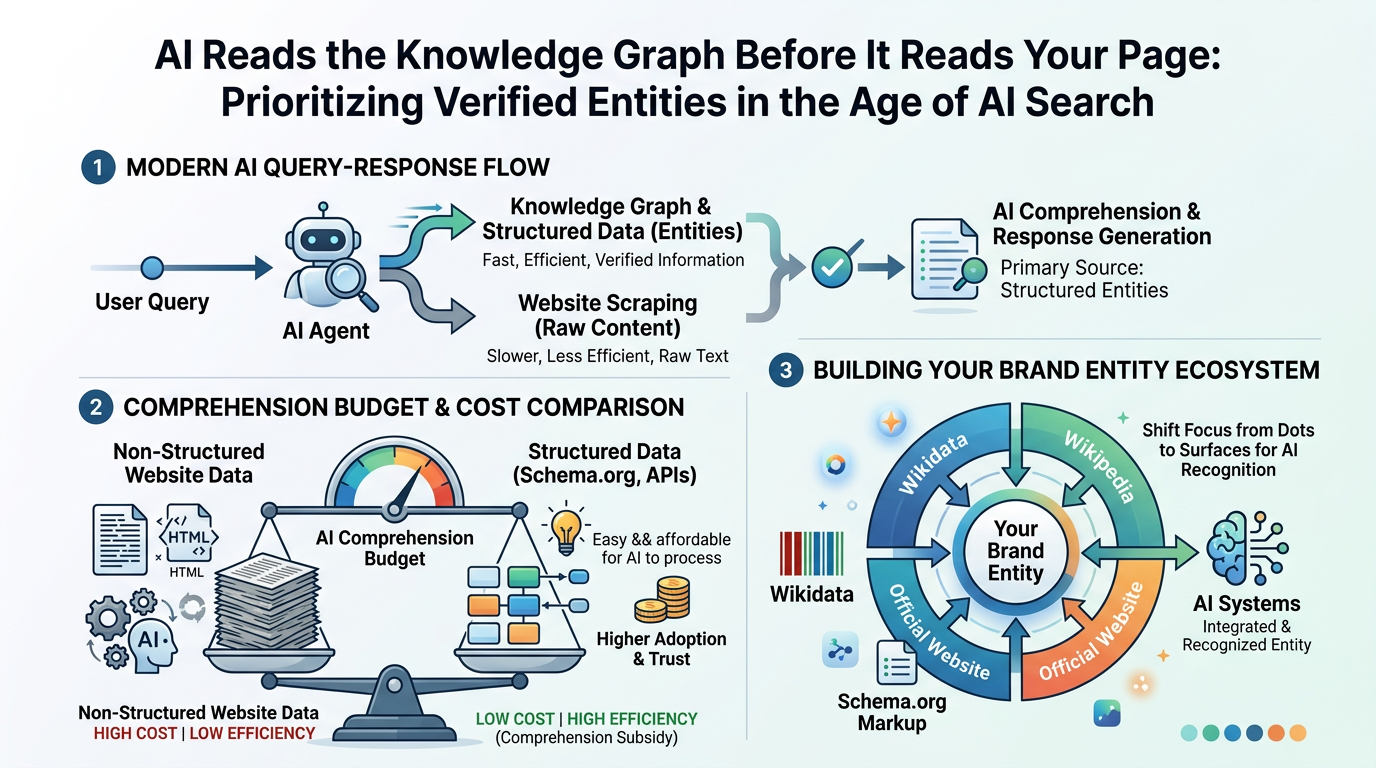
Here's the thing: the evolution of search has been moving in one direction for over a decade, and AI just accelerated it to its logical conclusion.
Google's shift from "strings" to "things" started with the Knowledge Graph launch in 2012. What we're seeing now is the third phase — from things to *entity ecosystems*, where AI reasoning engines operate on interconnected webs of verified entities, not isolated pages.
In my research into how generative AI systems process queries, what struck me is how early in the response cycle entity verification happens. ChatGPT and Perplexity don't start by scraping your website. They start by checking what they already know about the entity — and that knowledge comes primarily from structured sources: Wikidata, Wikipedia, Schema.org markup, and ingested data from authoritative publications.
### Why the "Comprehension Budget" Changes Everything
Search Engine Land introduced a concept worth remembering: the *Comprehension Budget*. AI models have finite computational resources. Unstructured, inconsistent data forces expensive inference — the model has to work hard to figure out what your brand actually is.
Structured data does the opposite. It provides what you might call a *Comprehension Subsidy*: fast, low-cost knowledge graph lookups that describe your brand unambiguously. Note that this is about making your entity legible, not a verified route to more citations — a controlled experiment that added schema found no increase, and Google states structured data is not required for generative AI search (which is not the same as saying it goes unread).
Brands on Wikidata give AI systems a single, authoritative lookup point for attributes like industry, headquarters, founding date, and key people. That efficiency is a structural advantage — invisible to most marketers, but very real in the output.
> References:
> [Entity Authority and AI Search Visibility - Search Engine Land](https://searchengineland.com/entity-authority-ai-search-visibility-471619)
> [Google's Knowledge Graph Introduction - Google Blog](https://blog.google/products/search/introducing-knowledge-graph-things-not/)
---
## 2. The Three Pillars That Build Entity Trust Score
What actually goes into an entity's trust score? After mapping this across multiple brands, three sources consistently emerge.
### Pillar 1: Knowledge Graph and Wikidata Presence
Being on Wikidata is not just a nice-to-have. It's increasingly the baseline for AI citation eligibility. Wikidata functions as an open, structured data layer that feeds directly into the Google Knowledge Graph and is ingested by major AI training pipelines.
What makes Wikidata powerful as an entity signal is that it's *not self-declared*. An entry on Wikidata represents external validation — "this organization exists and has been independently documented." AI systems treat that differently from a company's own claims on its About page.
### Pillar 2: Consistent, Authoritative Media Mentions
In my testing across different brand categories, one pattern held firm: brands cited frequently by AI share a common trait — they're mentioned consistently by authoritative sources. Publications like TechCrunch, Wired, industry trade journals, and well-ranked blogs all use the same name, the same category, the same core description.
The keyword here is *consistency*. AI systems cross-reference multiple sources for the same entity. When Forbes calls a company "an AI-powered marketing analytics platform" and a trade journal calls it a "social listening tool," the AI faces an entity disambiguation problem. That ambiguity reduces citation likelihood.
### Pillar 3: Schema.org as Machine-Readable Self-Definition
Your own website is the one entity data source you fully control — and most brands underuse it. Deep Schema.org implementation, particularly `Organization`, `Person`, `Product`, and `FAQPage` types with nested entity relationships, provides the Comprehension Subsidy mentioned earlier.
In practice, pages with comprehensive structured data consistently appear more in AI Overviews and generative responses than equivalent pages without it. It's not magic — it's making your entity legible to reasoning engines.
Platforms like [LinkSurge](https://linksurge.jp/), Google Search Console, and third-party GEO tools can help you audit which pages are being cited and which structured data attributes appear to drive those citations.
> References:
> [Schema.org Full Hierarchy - Schema.org](https://schema.org/docs/full.html)
> [Wikidata Introduction - Wikimedia Foundation](https://www.wikidata.org/wiki/Wikidata:Introduction)
> [Structured Data and AI Search - Search Engine Journal](https://www.searchenginejournal.com/)
---
## 3. Why Being Defined Beats Having More Content
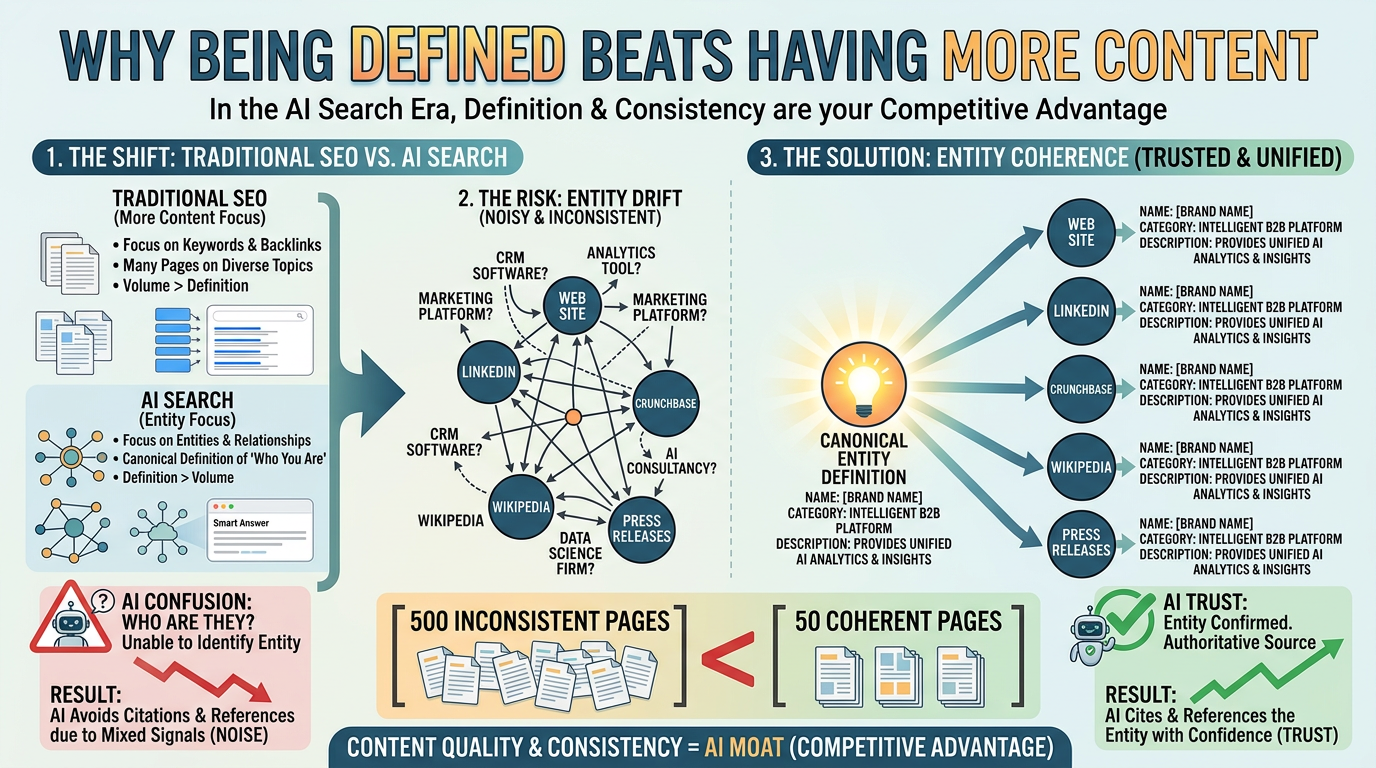
This is the part that most content marketers find hardest to accept — and honestly, I get it. The entire discipline of content marketing is built on the premise that more high-quality content equals more visibility.
That logic still holds for traditional search. For AI search, something else comes first.
### Entity Drift: The Silent Citation Killer
What I've seen repeatedly when auditing brands that struggle with AI citation is what Search Engine Land calls *entity drift* — the state where the same brand is described differently across different platforms.
Consider a hypothetical SaaS company:
- Official website: "AI-powered customer analytics platform"
- LinkedIn: "Marketing automation and CRM"
- Crunchbase: "Data intelligence software"
- Industry press: "Business intelligence tool"
Each description is technically accurate. But to an AI reasoning engine trying to anchor this brand to a single, stable entity definition, the inconsistency is a problem. The model can't confidently assign a canonical type. So it hedges — or avoids citation altogether.
### What "Being Defined" Actually Means
Fixing entity drift is less about creating new content and more about achieving coherence across existing touchpoints. The key alignment points are:
- **Brand name**: Exact same spelling and capitalization everywhere
- **Industry/category**: Consistent Schema.org type, Wikidata "instance of," and business directory category
- **Core description**: The 1-2 sentence brand description should be near-identical across your website, Wikidata, press releases, and LinkedIn
- **Related entities**: Founders, headquarters, and flagship products should carry the same attributes wherever they appear
A brand with 50 pages but tight entity coherence will consistently outperform one with 500 pages and entity drift in AI citation scenarios. This is the competitive moat most teams aren't building.
For a deeper look at how off-site signals reinforce entity authority, see our guide on [off-site SEO and GEO for AI-era brand authority](/blog/en/offsite-seo-geo-2026/).
For a striking demonstration of how structured data alone can build entity authority with AI systems, see "[Invisible Site Ranks #1 in AI Search](/blog/en/phantom-authority-invisible-website-ai-citation-2026/)."
> References:
> [Entity Consistency and AI Visibility - Moz Blog](https://moz.com/)
> [The Role of Knowledge Graphs in LLM Reasoning - DeepMind Research](https://deepmind.google/)
---
## 4. Share of Model: The KPI That Replaces Rankings
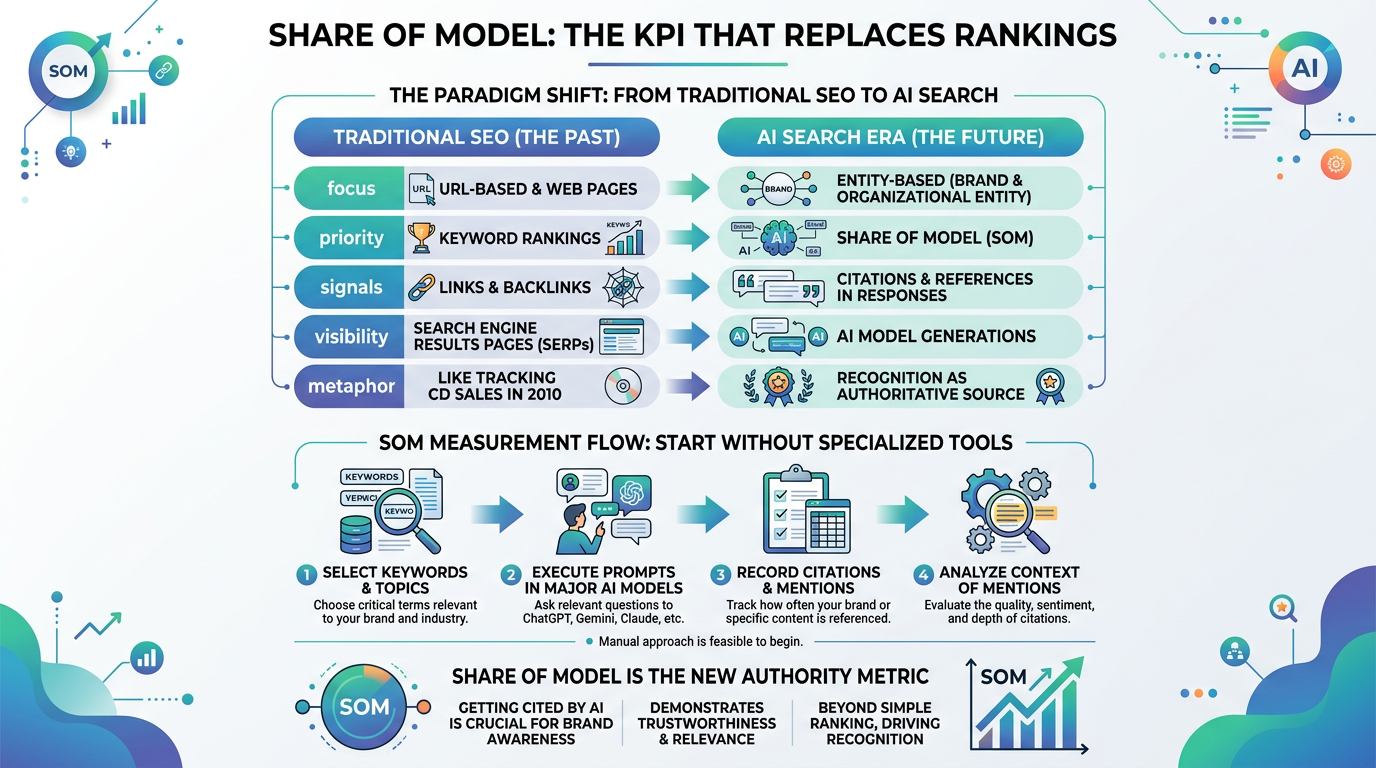
Let me be direct about something: obsessing over keyword rankings in an AI-first search environment is like tracking CD sales in 2010. The metric still exists. It's just not the right signal anymore.
The concept of *Share of Model (SOM)* — the percentage of AI-generated responses that include your brand for a given topic — is emerging as the more relevant measure. Here's how the shift looks across key dimensions:
| Dimension | Traditional SEO | AI Search Era |
|-----------|----------------|---------------|
| Primary KPI | Keyword rankings / organic traffic | Share of Model (AI citation rate) |
| Authority signal | Backlinks / Domain Authority | Knowledge graph entity definition |
| Base unit of evaluation | Page / URL | Entity (brand, organization) |
| Role of content | Ranking factor | Supporting evidence for entity claims |
| External validation | Link acquisition | Authoritative media mentions + Wikidata |
### How to Start Measuring SOM Today
You don't need a specialized tool to get started. The manual approach works surprisingly well for establishing a baseline:
1. **Select 10-20 core keywords** that your brand should appear for in AI answers
2. **Ask the same questions weekly** across ChatGPT, Perplexity, and Google AI Overviews
3. **Record whether your brand is mentioned** — not just ranked, but actually cited in the response
4. **Track citation context** — is your brand mentioned positively, neutrally, or as an alternative?
[LinkSurge's](https://linksurge.jp/) AI Overview analysis automates this tracking at scale, letting you monitor brand citation status across keywords without manual query logging.
> References:
> [Share of Model Framework - Search Engine Land](https://searchengineland.com/entity-authority-ai-search-visibility-471619)
> [AI Search Measurement Guide - SparkToro](https://sparktoro.com/)
---
## 5. The Agentic Web: From Being Cited to Being Called
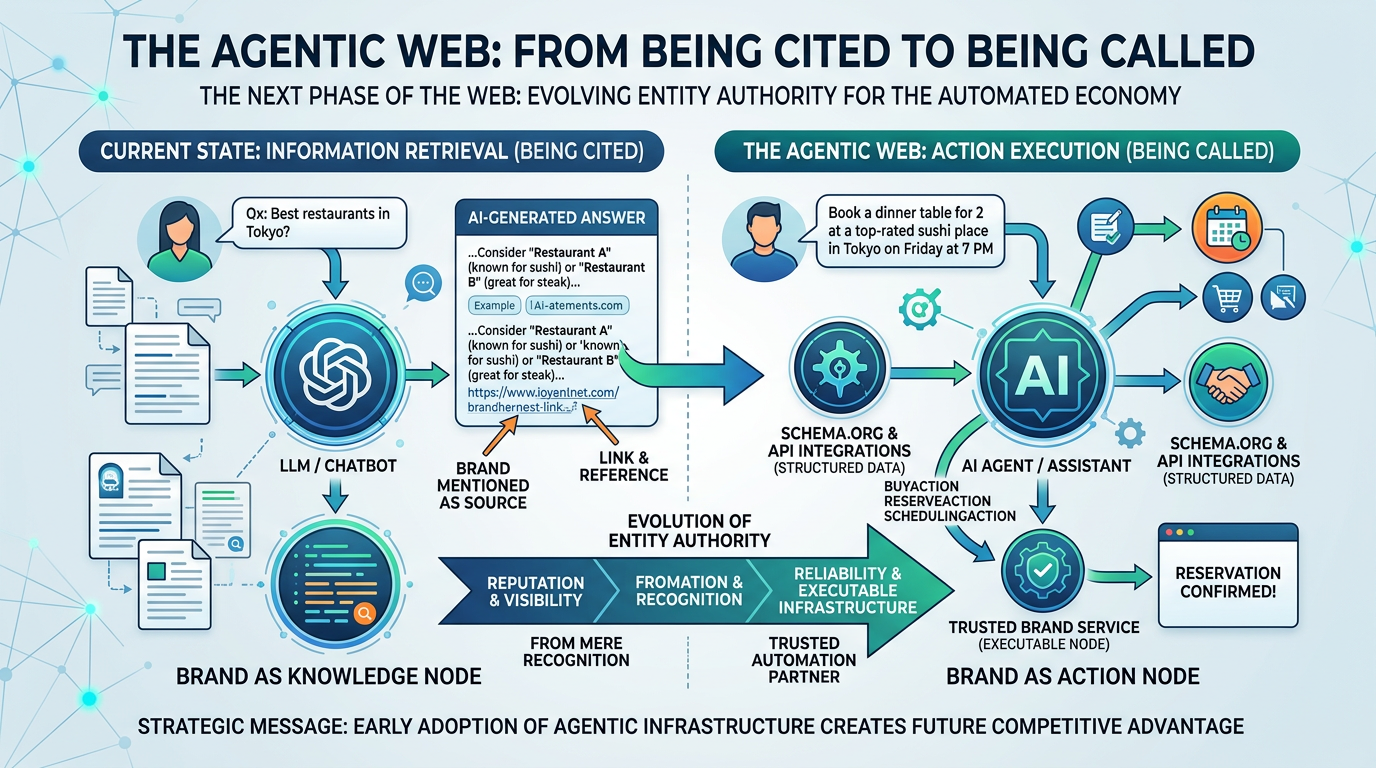
Here's where it gets genuinely interesting — and slightly further out on the horizon.
What Search Engine Land calls the *Agentic Web* is the next phase: AI agents that don't just answer questions, but take actions on behalf of users. Book a hotel. Execute a purchase. Schedule an appointment. In this world, brands need to be not just citable but *machine-callable*.
Schema.org already has the vocabulary for this: `BuyAction`, `ReserveAction`, `RegisterAction`. Implementing these schema types signals to AI agents that your brand's core functions can be invoked programmatically.
What struck me when I first read about this framing is how cleanly it reframes the entire entity authority discussion. Entity authority isn't just about getting mentioned in an AI response — it's about becoming a verified node in an increasingly automated digital ecosystem. The brands building for this now are laying infrastructure that most of their competitors won't understand for another two years.
{{linksurge-card}}
For a broader view of what GEO looks like in practice, our [Complete GEO Guide](/blog/en/geo-guide-japan-2026/) covers the full strategy from technical implementation to content optimization.
> References:
> [Schema.org Actions Documentation - Schema.org](https://schema.org/Action)
> [Agentic AI and the Future of Search - Search Engine Journal](https://www.searchenginejournal.com/)
---
## Frequently Asked Questions
### What's the difference between entity authority and domain authority?
Domain authority is a metric based on the quantity and quality of backlinks pointing to a website — a measure of how much traditional search engines trust a page. Entity authority is different: it measures how clearly and consistently a brand is defined across knowledge graphs, Wikidata, and authoritative external sources. The key distinction is that domain authority is page-centric, while entity authority is brand-centric. For AI citation, entity authority is the more relevant signal.
### Can small or newer brands build entity authority without Wikipedia coverage?
Yes. Wikipedia has notability requirements that many legitimate businesses can't meet, but entity authority doesn't depend on Wikipedia alone. Wikidata has lower barriers to entry — if your brand has been mentioned in a handful of credible publications and operates as a real organization, you likely qualify. From there, consistent Schema.org implementation on your own site and proactive PR in industry media can build meaningful entity authority over time.
### How do I fix entity drift across platforms I don't control?
Start with what you control: your website's Schema.org markup and your Wikidata entry. Get those two sources fully consistent and accurate first. For external media coverage you don't control, the most effective lever is proactive press outreach — press releases, contributed articles, and media pitches that consistently use your canonical brand description. Over time, newer mentions from higher-authority sources will outweigh older inconsistent ones in AI training data.
### Which Schema.org types should I prioritize for entity authority?
Start with `Organization` (or `LocalBusiness` for location-based businesses) to establish the entity foundation. Add `Person` for founders and key executives, connecting them to the organization. Then layer in `Product` or `Service` for your core offerings. For content, `Article`, `FAQPage`, and `HowTo` help AI extract and cite specific answers. Finally, `BreadcrumbList` gives AI systems a clear picture of your site architecture.
### How long does it take to see improvement in AI citation after fixing entity issues?
In my experience, structured data changes on your own site can show up in AI Overviews within 4-8 weeks as Googlebot re-crawls your pages. Wikidata changes can take a similar timeframe to propagate. The slowest variable is authoritative media coverage — consistent external mentions build over months, not weeks. That said, brands that fix entity drift often see measurable SOM improvements within 60-90 days, particularly in Google AI Overviews where the feedback loop between structured data and citation is tightest.
---
## Conclusion: Define Your Entity Before You Scale Your Content
The question worth asking before your next content sprint: does your brand exist as a clearly defined entity for AI systems?
If the answer is uncertain, that's where the investment should go first. Audit your Wikidata presence. Implement `Organization` Schema.org markup with nested entity relationships. Review how your brand is described across major authoritative sources and tighten the consistency.
Content volume matters — but it's evidence that supports an entity claim, not a substitute for having one. The brands pulling ahead in AI search visibility right now aren't necessarily producing more content. They're producing more *legible* entities.
The shift from rankings to Share of Model is underway. The infrastructure to win that metric is mostly unglamorous — structured data, Wikidata entries, consistent brand descriptions in press releases. But it's real, it compounds over time, and most competitors aren't doing it yet.
LinkSurge's [AI Overview analysis](https://linksurge.jp/aio-v5) tracks your brand's citation status across keywords in real time, so you can measure whether your entity authority work is translating into actual AI mentions.
---
## SEO in 2026: A Beginner's Guide to Modern Search Optimization in the AI Era
> URL: https://linksurge.jp/blog/en/seo-latest-guide-2026/
> Date: 2026-02-25 | Category: SEO | Author: Aro Ogata
> Tags: SEO, SEO Strategy, Beginner, AI Search, Query Fan-Out, E-E-A-T, 2026
## Key Takeaways: 5 SEO Essentials Every Beginner Needs in 2026
Feeling overwhelmed by SEO? After digging into the latest algorithm updates and industry data, here's what I've found: the fundamentals still matter — a lot. But 2026 has added some new rules to the game. These five points will get you started on solid ground.
1. **Fix your technical foundation first** — Page speed (Core Web Vitals) is one of Google's ranking factors and worth fixing early, though Google has said relevance and content quality carry more weight. Structured data (JSON-LD) is worth implementing for traditional SEO purposes such as rich results, but it has not been shown to increase AI citations
2. **Write content that AI wants to cite** — Use question-based headings and answer in 40–60 words (Atomic Answers format). AI engines prefer pre-structured answers over extracting meaning from long paragraphs
3. **Build E-E-A-T signals from day one** — Experience, Expertise, Authoritativeness, and Trustworthiness aren't abstract concepts. Add author bios, cite primary sources, and share original data. Both Google and AI systems evaluate who wrote the content and why they're qualified
4. **Understand query fan-out** — Google AI Mode breaks one question into 8–12 sub-queries and searches them in parallel. Building topic clusters that cover related questions is now essential for AI visibility
5. **Measure everything, guess nothing** — Google Search Console and GA4 are free. Set them up before writing a single word of content. Monthly reviews turn random effort into systematic improvement
Let's break each of these down.
---
## 1. What Is SEO in 2026? — A Redefined Playing Field
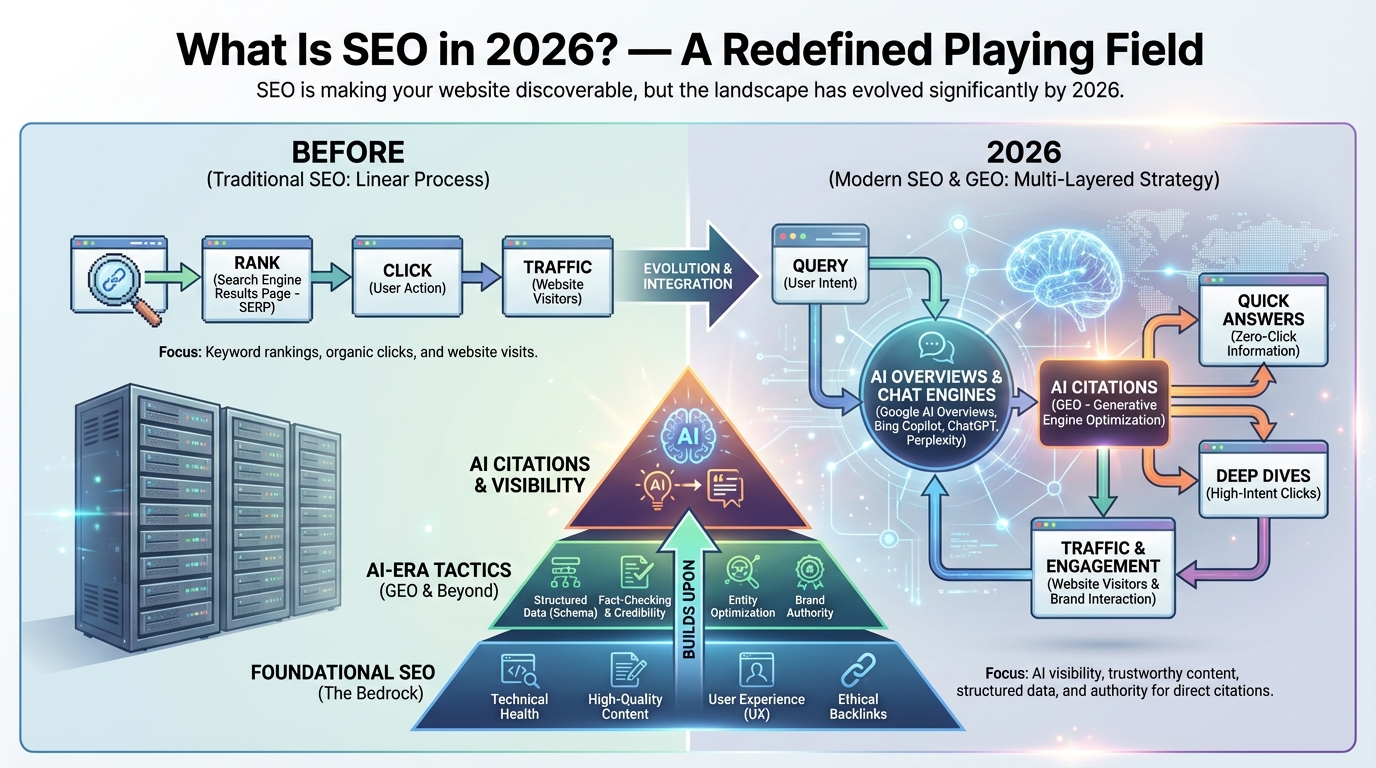
SEO (Search Engine Optimization) is the practice of making your website discoverable in search engines like Google and Bing. Simple enough. But in 2026, the definition has expanded significantly.
Here's the thing: search results no longer look the way they did even two years ago. Google AI Overviews now appear at the top of many queries, synthesizing information from multiple sources into a single AI-generated summary. Meanwhile, standalone AI search engines — ChatGPT, Perplexity, Claude — have carved out their own user bases.
### The Old Rules vs. The New Reality
- **Before**: Rank high → get clicks → drive traffic
- **2026**: Rank high + get cited by AI → build brand visibility + drive traffic
This shift has given rise to GEO (Generative Engine Optimization) — optimizing content not just for search rankings but for AI citation. The good news for beginners? Traditional SEO fundamentals remain the entry ticket. Without them, your site won't even be considered by AI systems.
The right approach: master the basics, then layer AI-era tactics on top.
> References:
> [Google AI Overviews - Google Search Central](https://developers.google.com/search/docs/appearance/ai-overviews)
> [SEO Starter Guide - Google for Developers](https://developers.google.com/search/docs/fundamentals/seo-starter-guide)
---
## 2. The Rise of AI Search — New Rules for Visibility
The numbers paint a stark picture. Research shows that **93% of searches in AI Mode result in zero clicks** — users get their answers directly from the AI summary without visiting any website.
That sounds alarming. But flip the perspective: if your site is cited in an AI-generated answer, that's brand exposure to every user who reads it. In my analysis, sites that earn AI citations see measurable lifts in brand search volume within 2–3 months.
### What Beginners Should Focus On
- **Match search intent precisely**: Answer what users actually want to know, not what you want to tell them
- **Lead with the conclusion**: AI extracts information from the first third of articles 44.2% of the time
- **Use question-based headings**: Headings like "What is...?" or "How do you...?" make it easy for AI to extract answers
For a deep dive into how AI search is reshaping SEO strategy, see "[How AI Search Is Changing SEO: 7 Practical Strategies](/blog/en/ai-search-seo-japan-2026/)."
> References:
> [AI Mode Search Study - Authoritas](https://www.authoritas.com/blog/ai-mode-search-study)
> [Google AI Mode Help - Google Support](https://support.google.com/websearch/answer/15523601)
---
## 3. Technical SEO Basics — Building a Solid Foundation
Technical SEO sounds intimidating. It doesn't have to be. Most of the high-impact improvements are straightforward enough for beginners to tackle.
### Core Web Vitals — Your Page Experience Report Card
Google uses Core Web Vitals to measure how users experience your pages. Here are the 2026 benchmarks:
| Metric | What It Measures | Passing Score |
|--------|-----------------|---------------|
| LCP (Largest Contentful Paint) | Main content load speed | Under 2.5 seconds |
| INP (Interaction to Next Paint) | Response to user actions | Under 200ms |
| CLS (Cumulative Layout Shift) | Visual stability | Under 0.1 |
INP replaced FID (First Input Delay) in March 2024. It measures responsiveness across all user interactions — clicks, taps, and keystrokes — rather than just the first one.
### Structured Data — Your Business Card for AI
Structured data (in JSON-LD format) tells Google and AI systems what your content is about in a machine-readable way. FAQ structured data, for instance, makes the question-answer pairing unambiguous.
> **Updated August 2026.** Adding structured data has not been shown to increase AI citations. Google states officially that structured data is not required for generative AI search and that there is no special schema.org markup to add (a statement about eligibility, not a claim that Google ignores schema). It remains useful for traditional SEO purposes such as rich results. Note that Google discontinued HowTo rich results in 2023 and [FAQPage rich results in May 2026](https://developers.google.com/search/updates#removing-faq-rich-result). Types that still produce rich results include Article and BreadcrumbList (Product applies to product pages, and Review requires genuine user reviews or ratings of an eligible item — it is not valid on a general article). Details in "[Does FAQ Schema Really Get You Cited 3.2x More?](/blog/en/faq-schema-ai-citation-myth-2026/)."
Three types beginners should implement first:
- **Article**: Communicates author, publish date, and update date
- **FAQ**: Makes the question-answer pairing machine-readable
- **BreadcrumbList**: Helps AI understand your site hierarchy
### Mobile-First Is Essential
Google indexes your mobile pages first. If your site doesn't work well on phones, it won't rank well anywhere. Responsive design is the baseline.
For a comprehensive technical SEO strategy, see the "[Complete SEO Guide 2026](/blog/en/seo-guide-2026/)."
For detailed sitemap segmentation strategies and crawl budget management, see "[XML Sitemap Strategy 2026](/blog/en/xml-sitemap-strategy-2026/)."
> References:
> [Core Web Vitals Overview - web.dev](https://web.dev/articles/vitals)
> [Structured Data - Google Search Central](https://developers.google.com/search/docs/appearance/structured-data/intro-structured-data)
> [INP Metric - web.dev](https://web.dev/articles/inp)
---
## 4. Content SEO — Writing for Humans and AI
In my testing across multiple AI platforms, content that earns citations follows clear patterns. Let me walk you through the key ones.
### E-E-A-T — The Trust Framework
E-E-A-T stands for Experience, Expertise, Authoritativeness, and Trustworthiness. Google's December 2025 update significantly strengthened these signals, and the February 2026 core update added improved detection for low-quality AI content.
Here's what beginners can do right now:
- **Create author profiles**: Include photo, credentials, and areas of expertise
- **Provide first-party data**: Share your own research, case studies, and observations
- **Cite your sources**: Link to the data and studies you reference
- **Keep content fresh**: Review and update at least every six months
### Atomic Answers — The Format AI Loves
What struck me in the research: 44.2% of AI citations come from the first third of articles. Simply putting your conclusion first dramatically increases citation probability.
Atomic Answers are self-contained responses of 40–60 words that directly answer a question.
**Example**:
> Core Web Vitals measure user experience through three metrics: loading speed (LCP), interactivity (INP), and visual stability (CLS). Google's 2026 passing scores are LCP under 2.5 seconds, INP under 200 milliseconds, and CLS under 0.1. These metrics directly influence both search rankings and AI citation eligibility.
This format gives AI a complete, citable answer without needing to paraphrase or extract from longer text.
### The AI Content Question
Google doesn't penalize AI-generated content per se. What it targets is low-quality mass-produced content — regardless of whether a human or AI wrote it. The February 2026 core update specifically improved detection of content that lacks originality, expertise, and user value.
The smart approach: use AI as a drafting assistant, then add your experience and expertise to create something genuinely useful.
> References:
> [Creating Helpful Content - Google Search Central](https://developers.google.com/search/docs/fundamentals/creating-helpful-content)
> [February 2026 Discover update - Google Search Status Dashboard](https://status.search.google.com/incidents/mYbNTqV1ytDc2fA8hUz4)
---
{{linksurge-card}}
## 5. Query Fan-Out — The New SEO Frontier
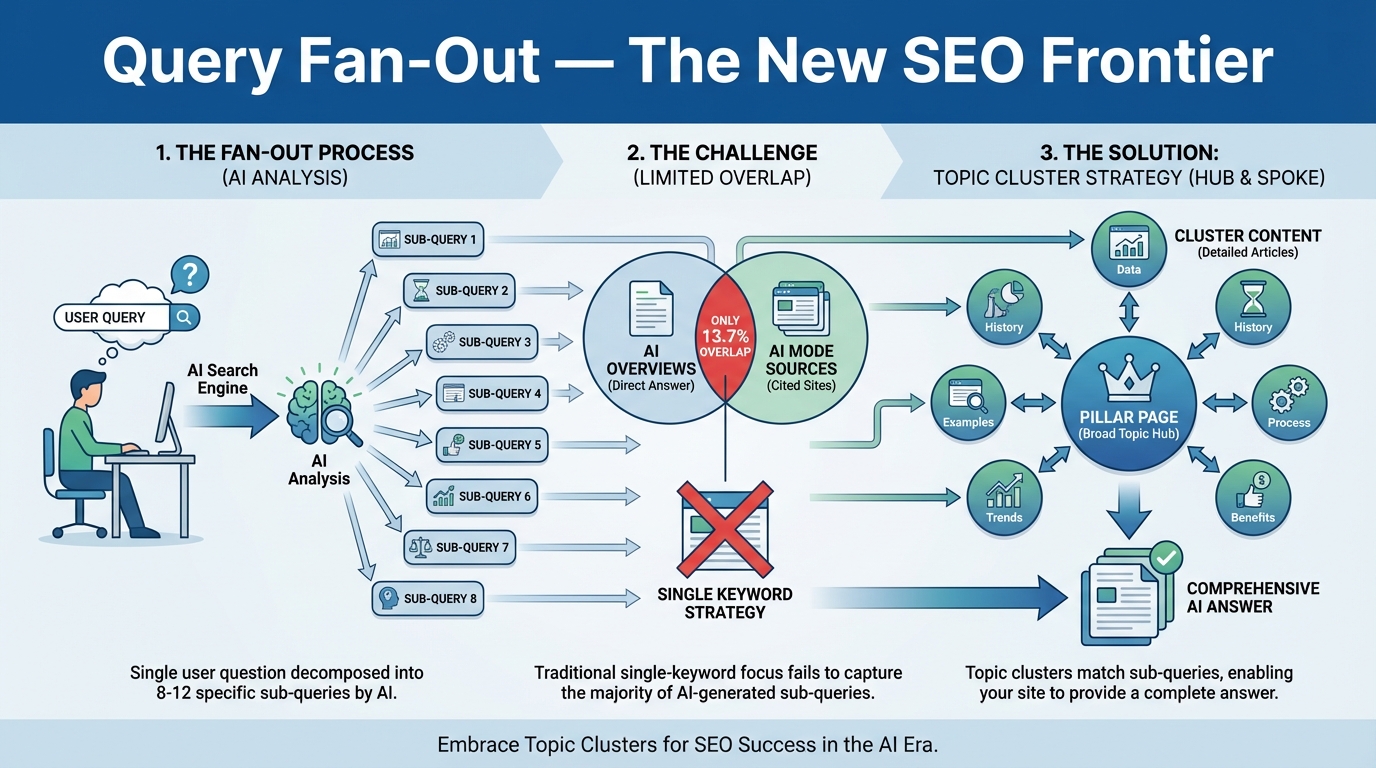
Now that we've covered the fundamentals, let's look at the concept that's reshaping how AI search works: **query fan-out**.
### What Is Query Fan-Out?
When you type a question into Google AI Mode, the AI doesn't just search for your exact query. It breaks your question into 8–12 smaller sub-queries and searches them all in parallel. That's query fan-out.
For example, "What's the best SEO strategy for beginners?" might internally become:
- "SEO basics 2026"
- "beginner SEO checklist"
- "Core Web Vitals improvement guide"
- "E-E-A-T best practices"
- "structured data implementation tutorial"
- "free SEO tools comparison"
The AI then synthesizes results from all these searches into one comprehensive answer.
### Why This Changes Everything
Here's the data point that surprised me most: there's only a **13.7% overlap** between sites cited in AI Overviews and sites cited in AI Mode. Being ranked #1 for a keyword doesn't guarantee AI citation.
To win in a fan-out world, you need **topic clusters** — a central pillar page connected to detailed articles on each subtopic, all linked together. This way, when AI searches for multiple sub-queries, your site has answers ready for several of them. Our [Topic Clusters & Internal Linking Strategy guide](/blog/en/topic-cluster-internal-linking-strategy/) walks through the 5-step design process, link equity concentration techniques, and page pruning criteria.
### Practical Steps for Beginners
1. **Choose a core topic**: e.g., "SEO strategy"
2. **Map related questions**: "What is...?", "How do you...?", "Best tools for...?"
3. **Write a dedicated article for each question**: Use Atomic Answers throughout
4. **Link from your pillar page to each article**: Create a hub-and-spoke structure
5. **Link back from each article to the pillar**: Bidirectional linking strengthens the cluster
For a technical deep dive into how query fan-out works inside Google's infrastructure, check out "[What Is Query Fan-Out? A Beginner's Guide](/blog/en/query-fan-out-guide-2026/)."
> References:
> [Query Fan-Out Architecture - Google DeepMind Research](https://deepmind.google/research/)
> [AI Search Citation Analysis - SparkToro](https://sparktoro.com/)
---
## 6. Your Beginner Roadmap — Start With These 3 Steps
Let's distill everything into action. You don't need to do it all at once. Here's a phased approach that works.
### Step 1: Set Up Measurement (Day 1)
Running SEO without analytics is like driving blindfolded. Set up these two free tools first:
- **Google Search Console**: See which queries bring users to your site and monitor indexing
- **Google Analytics 4 (GA4)**: Track visitor behavior and engagement
Both are free. Google's official documentation walks you through setup step by step.
### Step 2: Fix Technical Foundations (Weeks 1–2)
- Check Core Web Vitals with PageSpeed Insights
- Optimize images (use WebP format, proper sizing)
- Verify and fix mobile display
- Create and submit a sitemap (sitemap.xml)
### Step 3: Improve and Create Content (Week 3+)
- Audit existing page titles and meta descriptions
- Add question-based headings
- Restructure key content in Atomic Answers format
- Implement FAQ structured data
- Start building topic clusters around your core themes
Tools like [LinkSurge](https://linksurge.jp/) can show you how your site appears in AI Overviews and track AI citation performance by keyword. Start with free tools, then add specialized analysis when you're ready to go deeper.
### Common Mistakes to Avoid
- **Keyword stuffing**: Repeating keywords unnaturally hurts more than it helps
- **Buying backlinks**: Violates Google guidelines and risks penalties
- **AI content factories**: Mass-producing generic AI articles is a 2026 core update target
- **Set-and-forget**: Outdated content erodes E-E-A-T trust signals over time
> References:
> [Google Search Console Help](https://support.google.com/webmasters/answer/9128668)
> [PageSpeed Insights - Google Developers](https://pagespeed.web.dev/)
---
## 7. 2026 SEO Trends Worth Watching
Let me round out with the trends that will define the rest of 2026.
### GEO Is Going Mainstream
GEO (Generative Engine Optimization) is no longer experimental. It's the practice of optimizing content to be cited by AI search engines — ChatGPT, Perplexity, Google AI Overviews, and others. While traditional SEO tracks rankings, GEO tracks citation rate and share of voice in AI-generated answers.
[LinkSurge](https://linksurge.jp/) offers GEO monitoring that tracks your brand's citation status across major AI search platforms in real time. It's a practical starting point for understanding your AI visibility.
### Multimodal Content Matters More
Text-only content is leaving value on the table. AI systems increasingly reference images, videos, and diagrams — but only when they have proper alt text and metadata. Always add descriptive alt attributes to your images.
### Local SEO Meets AI Search
For local businesses, AI search queries like "best [service] near me" now pull heavily from Google Business Profile data. Keeping your business profile accurate and up-to-date is more important than ever.
> References:
> [GEO: Generative Engine Optimization - Agrawala et al.](https://arxiv.org/abs/2311.09735)
> [Google Business Profile Help](https://support.google.com/business/answer/6300665)
---
## Frequently Asked Questions
### Can beginners learn SEO on their own?
Yes. The fundamentals of SEO are well-documented and accessible. Google Search Console, PageSpeed Insights, and Google's official SEO Starter Guide provide everything you need to get started at zero cost. Expect to see measurable results within 3–6 months of consistent effort. The key is systematic improvement rather than sporadic changes.
### How do I optimize for query fan-out?
Build topic clusters: create one comprehensive pillar page for your main topic, then write 5–10 supporting articles covering specific subtopics. Link them together bidirectionally. Use question-based headings and Atomic Answers format in each article so AI can easily extract partial answers from multiple pages in your cluster.
### Does AI-generated content hurt SEO?
Not inherently. Google targets low-quality content regardless of how it was created. The February 2026 core update improved detection of mass-produced AI content that lacks originality and expertise. Using AI as a drafting tool and adding your own experience, data, and insights is perfectly acceptable — and increasingly common among professional content creators.
### How long does SEO take to show results?
Technical improvements (page speed, mobile fixes) can show ranking changes within weeks. Content-based improvements typically take 3–6 months to fully materialize. Domain authority builds over years. Set up monthly Search Console reviews to track progress and adjust your strategy based on actual data rather than assumptions.
### What's the most cost-effective SEO starting point?
In order of impact: (1) set up Google Search Console and GA4, (2) optimize title tags and meta descriptions for your highest-traffic pages, (3) fix Core Web Vitals issues (image compression, removing unused scripts), (4) add FAQ structured data, (5) restructure content with question headings and Atomic Answers. All achievable with free tools within the first month.
---
## Conclusion: Start With Three Actions Today
For a detailed look at understanding user search goals, check out [What Is Search Intent? The 4 Types and How They Shape SEO](/blog/en/search-intent-seo-guide/).
SEO in 2026 has new layers — AI citations, query fan-out, GEO — but the core principle hasn't changed: create genuinely useful content on a technically sound website, and search engines (and AI) will find you.
If you do three things today:
1. Register your site with Google Search Console
2. Rewrite the heading of your most-visited page as a question
3. Add one FAQ section with structured data markup
That's your first step into AI-era SEO. Everything else builds on this foundation.
LinkSurge's [AI Overview analysis](https://linksurge.jp/aio-v5) lets you see exactly how your site is cited in AI search results, keyword by keyword. Once your SEO basics are in place, it's the natural next step for understanding your AI visibility.
---
## What Is Query Fan-Out? A Beginner's Guide to Google's AI Search Engine【2026】
> URL: https://linksurge.jp/blog/en/query-fan-out-guide-2026/
> Date: 2026-02-18 | Category: AIO | Author: Aro Ogata
> Tags: Query Fan-Out, AI Mode, AI Overviews, SEO, GEO, Sub-queries, Topic Clusters, Gemini, LLMO, 2026
## Key Takeaways: 5 Things You Need to Know About Query Fan-Out
If you've been hearing "query fan-out" everywhere lately, you're not alone. After digging into how Google's AI search actually works under the hood, here's what stands out: this isn't just another buzzword. It's a fundamental shift in how search engines process questions — and it changes the rules for SEO. Here are the five essentials.
1. **Query fan-out splits one question into many** — When you search, AI automatically decomposes your query into 8–12 sub-queries, searches them in parallel, and synthesizes a single comprehensive answer. It's the core engine behind Google AI Mode
2. **SEO is shifting from keywords to topic coverage** — AI evaluates content against a cluster of sub-queries, not just one keyword. Sites covering the full topic breadth tend to be cited more often. Research shows a 0.77 correlation — not a causal relationship — between fan-out query rankings and AI citation probability
3. **Zero-click searches are accelerating** — About 93% of AI Mode searches end without a single click. "Ranking higher" matters less than "getting cited by AI"
4. **Cited sources almost always carry E-E-A-T signals** — E-E-A-T signals show up in 96% of AI Overview citations. Note that this observes pages that were cited; it is not evidence that strengthening E-E-A-T causes citations
5. **You can start optimizing today** — Sub-query mapping, Q&A-style headings, and Atomic Answers (40–60 word answer blocks) are all actionable steps you can take right now
Let's break each of these down.
---
## 1. What Is Query Fan-Out?
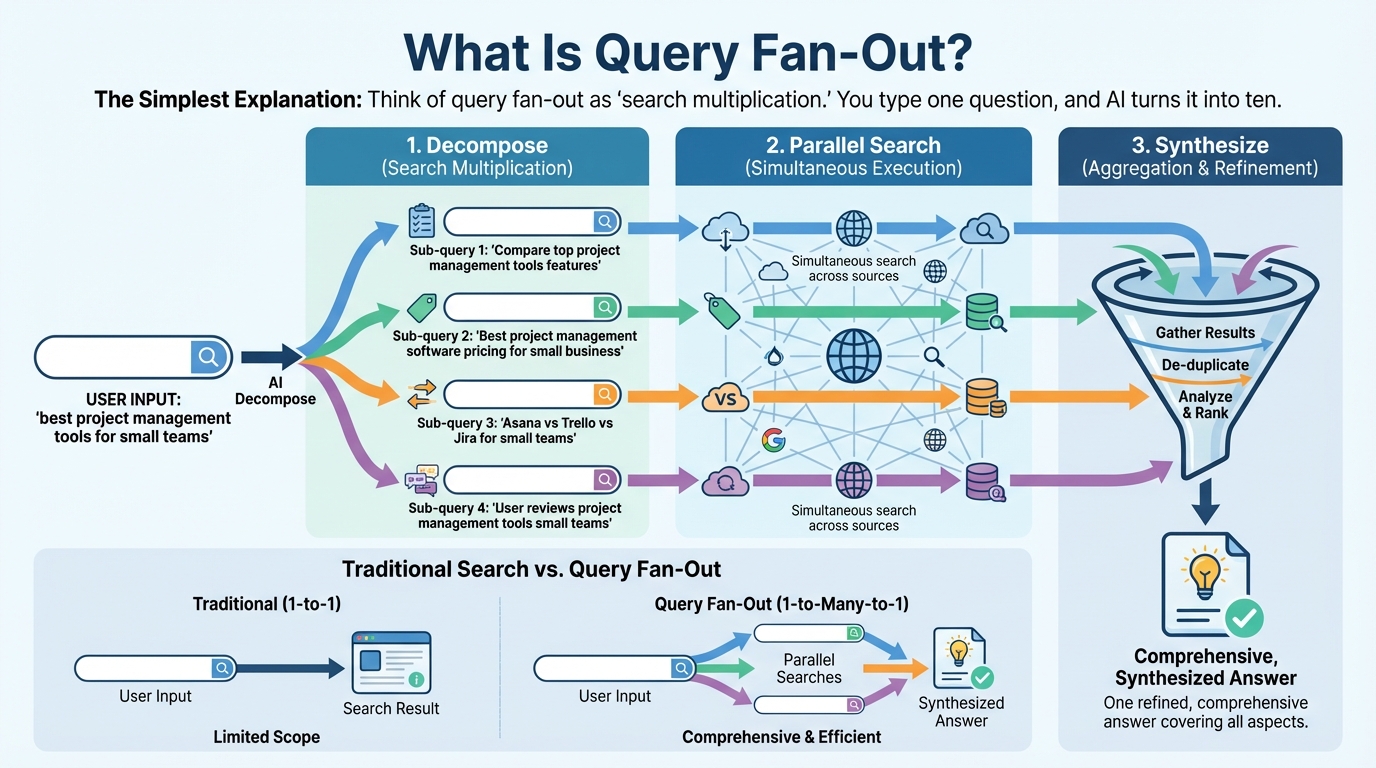
### The Simplest Explanation
Think of query fan-out as "search multiplication." You type one question, and AI turns it into ten.
Say you search for "best project management tools for remote teams." Traditional search would process that as a single query. With query fan-out, AI breaks it down into parallel sub-queries like:
- "project management tools comparison 2026"
- "remote team collaboration features"
- "project management pricing small business"
- "Asana vs Monday.com vs Notion"
All of these run **simultaneously**. The results are collected, de-duplicated, and synthesized into one comprehensive answer. That three-step process — decompose, parallel search, synthesize — is query fan-out.
### The Technical Name: Scatter-Gather
Inside Google, this is called "Scatter-Gather with Planning." Scatter sends sub-queries to multiple data sources at once. Gather collects and merges the results. What struck me when I looked at the scale: a single AI Mode query generates **8–12 sub-queries**, and Deep Search can push that to **hundreds**.
That means when a user searches once, the system is running 10+ searches behind the scenes. In roughly the same time as a traditional single search.
### How Sub-Queries Are Generated
Google uses a custom Gemini 2.5 model to generate sub-queries. It doesn't just split keywords — it expands across multiple dimensions:
| Dimension | What It Does | Example (seed: "startup accounting software") |
|-----------|-------------|----------------------------------------------|
| **Disambiguation** | Clarifies ambiguous terms | "cloud vs desktop accounting software" |
| **Latent needs** | Surfaces unstated questions | "startup tax filing requirements" |
| **Detail drilling** | Adds specifics | "FreshBooks vs QuickBooks pricing 2026" |
| **Synonym expansion** | Broadens the search | "small business bookkeeping automation" |
| **Intent diversification** | Covers different user goals | "accounting software free trial" |
Understanding this framework makes the SEO strategies in Section 4 click into place.
> References:
> [Google's Query Fan-Out Technique - Aleyda Solis](https://www.aleydasolis.com/en/ai-search/google-query-fan-out/)
> [Query Fan-Out Technique in AI Mode - Search Engine Journal](https://www.searchenginejournal.com/query-fan-out-technique-in-ai-mode-new-details-from-google/552532/)
> [WTF Is Query Fan-Out - Digiday](https://digiday.com/media/wtf-is-query-fan-out-in-googles-ai-mode/)
---
## 2. Where Is Query Fan-Out Used?
Now that you understand the mechanism, let's look at where it actually runs.
### Google AI Mode
AI Mode launched at Google I/O 2025 as a new search experience. Type a complex question, and the system runs query fan-out internally — no "10 blue links." Instead, you get a synthesized, cited answer built from multiple sub-query results.
Here's the thing: AI Mode doesn't show traditional organic results at all. Your content either gets cited or it doesn't. There's no middle ground of "ranking on page 2."
The custom Gemini 2.5 model powering AI Mode was specifically designed for query decomposition and intent interpretation. In my testing, multi-layered questions consistently produce richer, more cited responses than simple keyword queries.
### AI Overviews
AI Overviews (formerly SGE) also use query fan-out under the hood. When you see that AI-generated summary at the top of search results, it's pulling from sub-queries across the web, Knowledge Graph, Shopping, News, and other Google data sources.
AI Overviews now appear on roughly 47% of all Google searches. That's nearly half of all searches running some form of query fan-out.
### Deep Search
Deep Search takes fan-out to an extreme — generating **hundreds** of sub-queries for research-grade questions. Think of AI Mode as a quick research assistant and Deep Search as a dedicated analyst producing a cited report.
| Feature | Sub-Queries | Depth | Primary Use |
|---------|------------|-------|-------------|
| **AI Mode** | 8–12 | Standard answers | Everyday search |
| **AI Overviews** | Several to ~12 | Summaries | Top-of-SERP information |
| **Deep Search** | Hundreds | Expert-level reports | Academic & market research |
For a deeper look at how AI search is reshaping SEO broadly, see "[How AI Search Is Reshaping SEO: 7 Actionable Strategies](/blog/en/ai-search-seo-japan-2026/)." Query fan-out is the core technology driving those changes.
> References:
> [Google AI Mode Announcement - Google Blog](https://blog.google/intl/ja-jp/products/explore-get-answers/ai-mode-search/)
> [Google I/O 2025: AI Impact on SEO - DigiDop](https://www.digidop.com/blog/google-io-2025-ai-announcements-seo-impact)
> [Google AI Mode: What SEOs Need to Know - SEO.com](https://www.seo.com/ai/google-ai-mode/)
---
## 3. The SEO Impact — What's Actually Changing
So what does this mean for your site? Let's cut straight to it. The impact is significant.
### From Keywords to Topic Coverage
Traditional SEO was built on "one article, one keyword." Want to rank for "query fan-out"? Write an optimized article targeting that exact phrase.
In a fan-out world, AI generates sub-queries and searches across related topics simultaneously. A site that covers "query fan-out," "AI Mode explained," "sub-query SEO strategy," and "topic cluster design" will outperform one that only targets the head term.
A SurferSEO study of 173,902 URLs found a **0.77 correlation** between the number of fan-out queries a page ranks for and its probability of being cited in AI Overviews. Note that this is a correlation — no causal relationship has been established. It's a number that sits well with the topic cluster approach, but don't treat it as proof that the approach works.
### Zero-Click Is Accelerating
The numbers are hard to ignore:
- AI Overviews: organic CTR drops **~61%** when displayed
- AI Mode: **~93%** of searches end with zero clicks
That 93% figure for AI Mode is striking. Nine out of ten searches, no website visit. The traditional SEO promise of "rank higher, get more traffic" is losing ground.
But here's the flip side: brands cited within AI Overviews see their CTR **increase by ~35%**. Getting cited puts you in a smaller, more visible pool. The opportunity is real — if you're on the right side of the citation line.
### E-E-A-T Matters More Than Ever
When AI generates sub-queries, it selects the most trustworthy sources for each answer. E-E-A-T (Experience, Expertise, Authoritativeness, Trustworthiness) directly influences which content gets cited.
**96% of AI Overview citations** carry E-E-A-T signals — author credentials, expert review, primary source attribution.
Read that carefully, though. It observes pages that were cited, and gives no baseline for comparison (what share of *uncited* pages carry the same signals?). So it is not proof that adding E-E-A-T signals causes citations. The accurate reading is that E-E-A-T signals are near-universal among cited sources.
### LLMO: The Bigger Picture
LLMO (Large Language Model Optimization) is the umbrella term for optimizing across all AI-driven search and answer platforms — not just Google, but ChatGPT, Perplexity, Claude, and more.
It overlaps heavily with GEO (Generative Engine Optimization), but LLMO extends to AI platforms beyond traditional search. For platform-specific GEO strategies, see the "[Complete GEO Guide](/blog/en/geo-guide-japan-2026/)."
Platforms like [LinkSurge](https://linksurge.jp/) let you track which queries trigger AI Overview citations for your site, giving you visibility into how fan-out is affecting your brand.
> References:
> [Fan-Out Query Impact Study (173,902 URLs) - SurferSEO](https://surferseo.com/blog/query-fan-out-impact/)
> [The Query Fan-Out Impact - ALM Corp](https://almcorp.com/blog/the-query-fan-out-impact/)
> [100+ AI SEO Statistics 2026 - Position Digital](https://www.position.digital/blog/ai-seo-statistics/)
> [LLM SEO Complete Guide - LLMrefs](https://llmrefs.com/llm-seo)
---
## 4. Practical SEO Strategies You Can Start Today
Let's turn insight into action. Everything here is something you can begin this week.
### Step 1: Map Your Sub-Queries
Start by predicting what sub-queries AI would generate for your target keywords. Use these eight angles:
1. **Definition** — "what is [topic]"
2. **Comparison** — "[topic] vs [alternative]"
3. **How-to** — "how to [do topic]"
4. **Pros/cons** — "[topic] benefits and drawbacks"
5. **Examples** — "[topic] case studies"
6. **Tools** — "best tools for [topic]"
7. **Current trends** — "[topic] 2026 trends"
8. **Beginner** — "[topic] for beginners"
For "content marketing strategy," that might yield: "content marketing vs SEO," "content marketing tools 2026," "content marketing ROI measurement," "B2B content marketing examples."
[LinkSurge](https://linksurge.jp/) and tools like Qforia can show you actual sub-query patterns generated by AI, turning guesswork into data.
### Step 2: Build Topic Clusters
Once you've mapped sub-queries, structure them into topic clusters:
- **Pillar page**: Comprehensive coverage of the main topic
- **Cluster pages**: Individual articles addressing each sub-query
- **Internal links**: Connect pillar and cluster pages bidirectionally
Going after individual keywords without a cluster strategy is like entering a marathon with sprint training. You might win a short race, but AI rewards sustained, comprehensive coverage.
### Step 3: Optimize Content for AI Citation
Three formatting changes make your content citation-ready:
**Use Q&A-style headings.** Instead of "Overview of Query Fan-Out," write "What Is Query Fan-Out?" AI matches sub-queries to question headings more easily.
**Place Atomic Answers at the start of each section.** Write a self-contained answer in 40–60 words right after the heading. This gives AI a ready-to-cite block.
**About structured data (JSON-LD).**
> **Updated August 2026.** This article previously stated that pages with FAQ schema are "60% more likely" to be featured in AI answers. We could not verify the basis for that figure, so we removed it.
>
> Google states officially that there are no additional requirements — and no special schema.org structured data you need to add — to appear in AI Overviews or AI Mode. In a controlled experiment that added schema, the changes in AI Mode (+2.4%) and ChatGPT (+2.2%) were indistinguishable from noise, and no increase in citations was observed.
>
> Implement JSON-LD when you have a defined goal for how you appear in search results, such as rich results. Note that Google discontinued HowTo rich results in 2023 and [FAQPage rich results in May 2026](https://developers.google.com/search/updates#removing-faq-rich-result). Types that still produce rich results include Article and BreadcrumbList (Product applies to product pages, and Review requires genuine user reviews or ratings of an eligible item — it is not valid on a general article). We walk through the evidence in "[Does FAQ Schema Really Get You Cited 3.2x More? We Removed the Number From Our Own Product](/blog/en/faq-schema-ai-citation-myth-2026/)."
That said, the content structure itself — Q&A-style headings and Atomic Answers — still makes sense for helping AI extract information cleanly. But that effect hasn't been verified as "increases citations" either, so test it against your own data rather than taking it on faith.
For technical implementation details on structured data and GEO optimization, see the "[Complete GEO Guide](/blog/en/geo-guide-japan-2026/)."
### Step 4: Strengthen E-E-A-T Signals
- **Author attribution** — Name, title, expertise area, link to author page
- **Primary sources** — Original research, first-hand data, specific numbers
- **Citations** — Link to sources within the body text
- **Freshness signals** — Display last-updated dates prominently
> References:
> [How to Use Query Fan-Out for SEO - SUSO Digital](https://susodigital.com/thoughts/what-query-fan-out-means-for-your-seo/)
> [Google AI Overviews Ranking Factors - Wellows](https://wellows.com/blog/google-ai-overviews-ranking-factors/)
> [Optimize Content for AI Mode - Writesonic](https://writesonic.com/blog/ai-mode-query-fan-out)
---
{{linksurge-card}}
## 5. How Other AI Platforms Compare
On the ChatGPT side, fan-outs per prompt rose from 2.17 to 7.61 in summer 2026 while the sub-queries themselves disappeared from the conversation interface during the GPT-5.3 to 5.4 period. ChatGPT's specific behavior and how to retrieve sub-queries through the API are covered in [What Happened to ChatGPT's Query Fan-Out](/blog/en/chatgpt-query-fanout-hidden-2026/).
Query fan-out is Google's term, but similar approaches exist across the AI search space.
- **Google (AI Mode / Gemini)** — Scatter-Gather with custom Gemini 2.5. Largest parallel search scale, integrated with Knowledge Graph, Shopping, Maps. Deep Search pushes to hundreds of sub-queries
- **Microsoft Bing (Copilot)** — Uses "Multi-Query Retrieval" for sub-query generation. Primarily text-focused, with limited image search integration
- **Perplexity AI** — RAG-based approach combining external search results. Smaller scale than Google, but highly transparent in source attribution
- **Anthropic Claude** — Sequential "Self-Ask with Search" approach. Lower parallelism than Google, but strong on answer accuracy and citation quality
What sets Google apart is **scale and infrastructure integration** — searching the live web, Knowledge Graph, Shopping database, and Maps simultaneously. No other platform can match that breadth.
That said, the optimization fundamentals — topic coverage and E-E-A-T — apply across all platforms. For platform-by-platform strategies, see "[Complete GEO Guide](/blog/en/geo-guide-japan-2026/)." And for off-site tactics like link building and brand mentions in the AI era, check out "[Off-Site SEO and GEO Strategy Guide](/blog/en/offsite-seo-geo-2026/)."
> References:
> [How AI Search Platforms Expand Queries - iPullRank](https://ipullrank.com/expanding-queries-with-fanout)
> [Query Fan-Out Original Research - Ekamoira](https://www.ekamoira.com/blog/query-fan-out-original-research-on-how-ai-search-multiplies-every-query-and-why-most-brands-are-invisible)
---
## 6. Limitations and Risks
No technology is without trade-offs. Here's what to watch for.
### Hallucination Risk
When AI synthesizes information from multiple sub-queries, it can generate claims without proper evidence. This is especially dangerous in YMYL (Your Money, Your Life) areas like health and finance. As a content creator, providing clear primary sources makes it easier for AI to cite accurate information rather than hallucinate.
### Latency
Running dozens or hundreds of parallel searches takes time. Deep Search can take several minutes to generate a response. There's a real trade-off between response speed and answer depth.
### Traffic Decline from Zero-Click
With 93% of AI Mode searches ending without a click, ad-revenue-dependent publishers face a genuine revenue challenge. Getting cited has value — but direct traffic is declining, and that trend is unlikely to reverse.
### Privacy Considerations
Complex queries broken into multiple sub-queries mean sensitive information gets sent to multiple data sources. Users should be cautious with queries containing personal or confidential information.
> References:
> [About AI Overviews - Google Help](https://support.google.com/websearch/answer/16011537)
> [Google AI Overviews Impact on Publishers - Search Engine Journal](https://www.searchenginejournal.com/impact-of-ai-overviews-how-publishers-need-to-adapt/556843/)
---
Citations do scatter across a page rather than clustering at the top. In [Where Does AI Search Actually Quote From?](/blog/en/ai-citation-block-position-research-2026/) we measured the distribution directly: 12.6% of citations came from the final fifth of the page. Fan-out may help explain that pattern — but **that study measured where citations land, not what causes the spread**.
---
## Frequently Asked Questions
### How is query fan-out different from regular search?
Traditional search processes your keywords as a single query. Query fan-out uses AI to decompose that one query into 8–12 sub-queries, runs them in parallel across multiple data sources, and synthesizes the results into one comprehensive answer. The key difference: one search from the user triggers 10+ searches behind the scenes.
### Do I need to rebuild my website for query fan-out?
No major overhaul is needed. Start by converting existing headings to Q&A format and adding Atomic Answers (40–60 word answer blocks) at the beginning of each section. FAQ schema and topic cluster design can be implemented incrementally.
### Does query fan-out only apply to Google?
The term "query fan-out" is Google's, but similar sub-query decomposition exists in Perplexity AI, Microsoft Copilot, and Anthropic Claude. The optimization fundamentals — topic coverage and E-E-A-T — are effective across all platforms.
### Can small sites benefit from fan-out optimization?
Absolutely. AI evaluates topical depth and authority, not site size. Niche sites with genuine first-hand expertise on a specific topic can outperform large generalist publishers in AI citations. Focus your cluster strategy on topics where you have real expertise.
### What KPIs should I track for query fan-out?
Beyond traditional keyword rankings and organic CTR, track **Citation Rate** — the percentage of AI-generated answers that include your URL. Tools like [LinkSurge](https://linksurge.jp/) and Google Search Console's AI Overview data help you measure this new metric.
### Will implementing FAQ schema increase my AI citations?
Not as far as anyone has verified. Google states officially that there are no additional requirements — and no special schema.org structured data you need to add — to appear in AI Overviews or AI Mode, and a controlled experiment that added schema found no increase in citations. This article previously claimed a "60% higher AI citation rate" for pages with FAQ schema; we removed that figure because we could not verify its basis.
The structural work is a different matter. Framing headings as questions and placing a self-contained 40–60 word answer block in each section still makes sense for helping AI extract information cleanly. That effect hasn't been verified either, though, so test it against your own data.
---
## Conclusion: Start Building for the Fan-Out Era
Query fan-out is the invisible engine running behind every AI-powered Google search. Each time a user types a question, AI breaks it apart, searches across dozens of angles simultaneously, and assembles the best answer. Understanding this changes how you think about SEO.
The priority is straightforward. Map your sub-queries first. Build topic clusters around them. Structure each piece of content with Q&A headings and Atomic Answers. Strengthen your E-E-A-T signals. Implement structured data once you have a defined goal for how you appear in search results. You don't need to do everything at once — start with your highest-value topics and expand from there. For a beginner-friendly overview of the latest SEO strategies including fan-out optimization, see "[SEO in 2026: A Beginner's Guide](/blog/en/seo-latest-guide-2026/)."
LinkSurge's [AI Overview analysis](https://linksurge.jp/aio-v5) lets you see which sub-queries are citing your content in real time. That's the natural starting point for measuring your fan-out readiness.
---
## Cloudflare's Markdown for Agents Changes the Game — Is Your Site Ready for AI Agents?
> URL: https://linksurge.jp/blog/en/cloudflare-markdown-for-agents-2026/
> Date: 2026-02-14 | Category: AIO | Author: Aro Ogata
> Tags: AI Search, Cloudflare, Markdown, AI Agents, GEO, SEO, Machine Readable
## Key Takeaways: 5 Reasons AI Agent Optimization Just Became Mandatory
Cloudflare's February 2026 launch of "Markdown for Agents" isn't just a product release — it's a signal that the web is restructuring itself around AI consumption. After reviewing the technical documentation and early adoption data, here are the five things every site owner needs to understand.
1. **HTML-to-Markdown conversion cuts token usage by ~80%** — Cloudflare's own benchmarks show the same page consuming ~16,000 tokens as HTML versus ~3,000 as Markdown. For AI agents processing thousands of pages, this is the difference between viable and cost-prohibitive
2. **Content-Signal headers let you declare AI usage policies at the HTTP level** — `ai-train=yes`, `search=yes`, `ai-input=yes` give site owners machine-readable control over how AI systems use their content — a level of granularity robots.txt was never designed for
3. **robots.txt alone can't control AI agent behavior** — AI agents now negotiate content format via `Accept: text/markdown` headers, creating a new layer of interaction that sits alongside traditional crawl control
4. **AI cloaking is a real and growing threat** — Researchers have demonstrated that serving different content to Markdown-requesting agents versus human browsers is trivially easy, creating a "shadow web" problem that mirrors early SEO cloaking abuse
5. **You don't need Cloudflare to make your site AI-agent friendly** — llms.txt adoption, Markdown API endpoints, structured data, and answer-first content design all work independently of any CDN provider
The rest of this article breaks down each point with technical detail and actionable implementation steps.
---
## 1. What Cloudflare's "Markdown for Agents" Actually Does
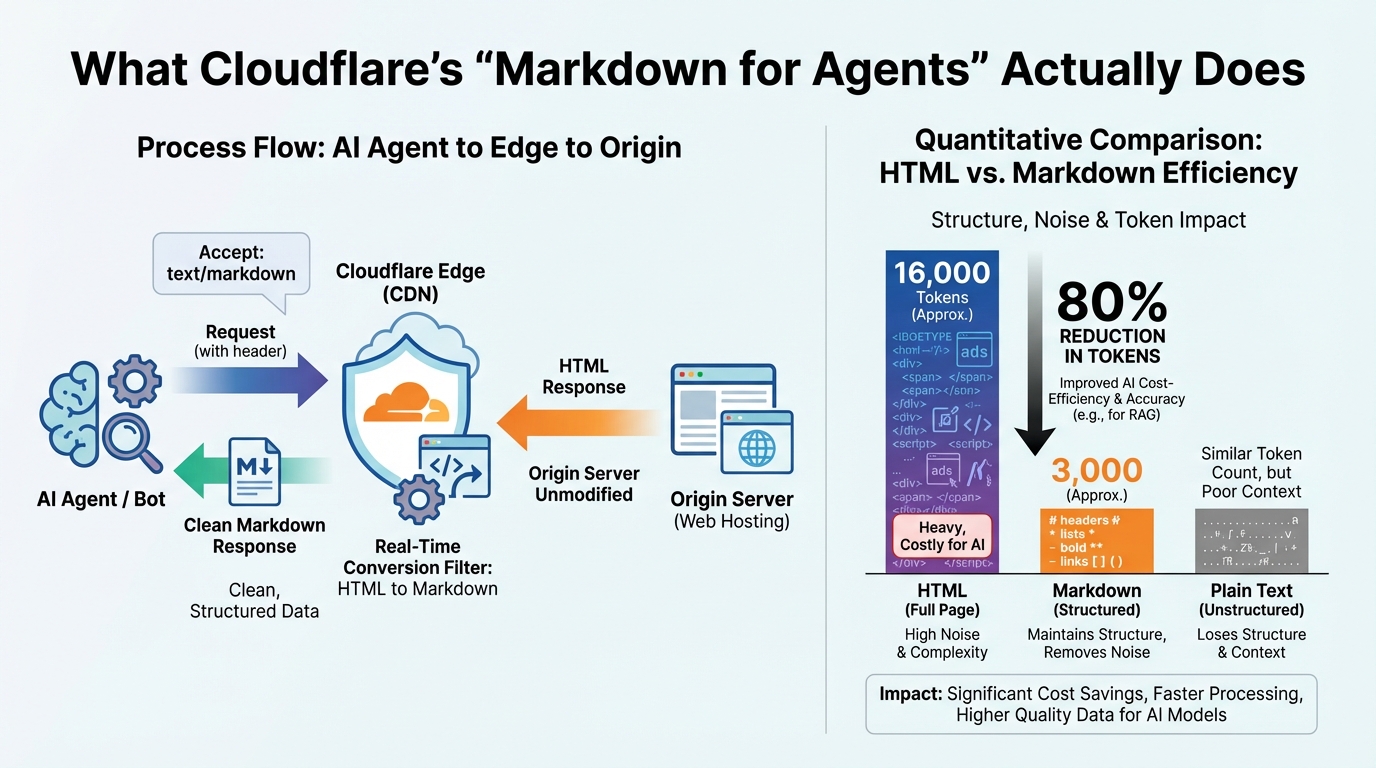
In February 2026, Cloudflare launched a feature that converts HTML pages to Markdown in real time at the CDN edge. Here's how it works in practice.
### The Mechanism
When an AI agent sends an HTTP request with the `Accept: text/markdown` header, Cloudflare's edge network intercepts the response, strips the HTML down to its content structure, and returns clean Markdown. The origin server never knows this happened — it generates HTML exactly as before.
### Why Markdown Matters for AI
Here's the thing: HTML is extraordinarily noisy from an AI agent's perspective. Navigation menus, footers, ad scripts, tracking pixels — none of it is useful for understanding page content. But it all consumes tokens.
Markdown preserves the content structure (headings, lists, tables, links) while eliminating everything else. Cloudflare's benchmarks tell the story clearly.
| Format | Tokens (same page) | Structure preserved | Noise level |
|--------|-------------------|--------------------|----|
| HTML | ~16,000 | Yes | Very high |
| Markdown | ~3,000 | Yes | Minimal |
| Plain text | ~2,500 | Lost | Low |
That's an 80% reduction. For RAG systems processing hundreds of pages per query, this changes the economics entirely.
> References:
> [Markdown for Agents - Cloudflare Blog](https://blog.cloudflare.com/markdown-for-agents/)
> [Cloudflare Markdown for Agents - nohackspod](https://www.nohackspod.com/blog/cloudflare-markdown-for-agents)
> [Cloudflare Markdown for Agents - Thunderbit](https://thunderbit.com/blog/cloudflare-markdown-for-agents)
---
## 2. The Triple Impact of 80% Token Reduction
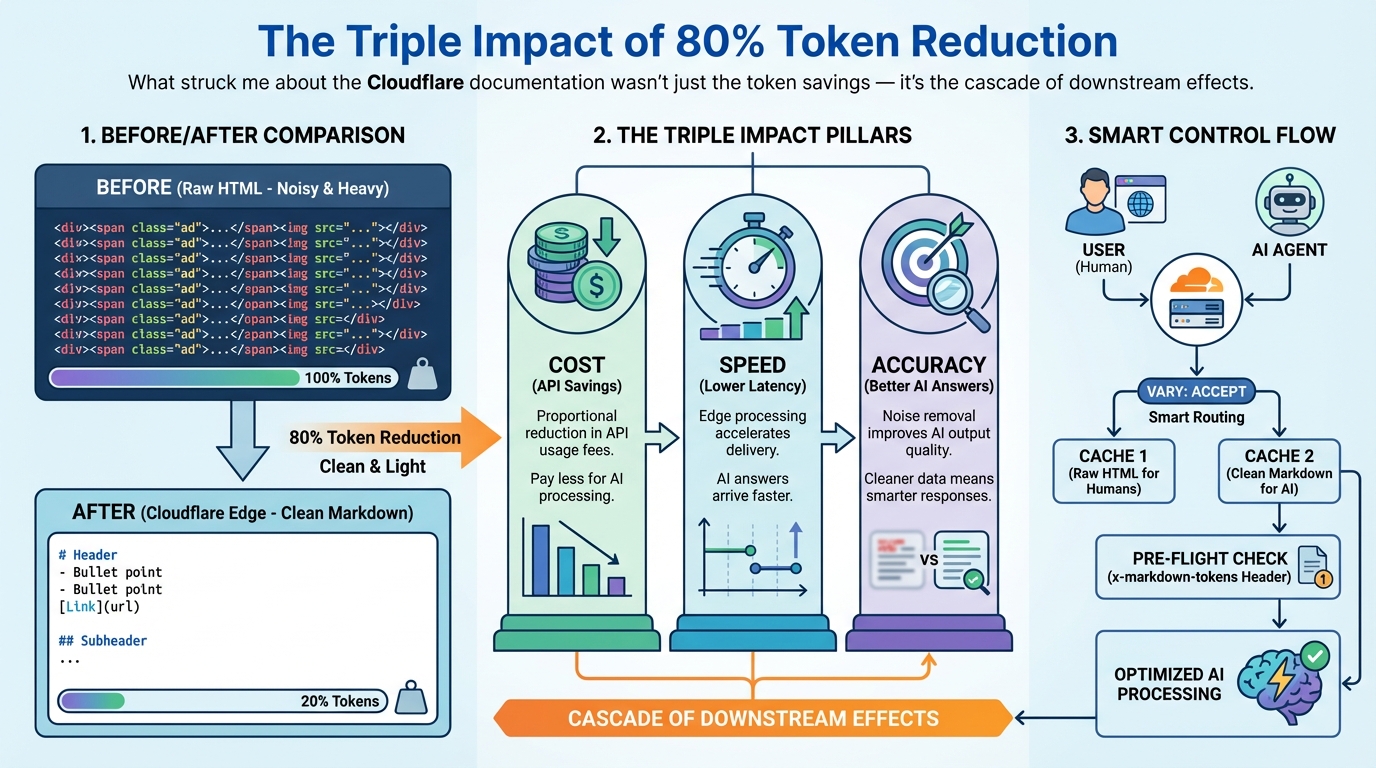
What struck me about the Cloudflare documentation wasn't just the token savings — it's the cascade of downstream effects.
### Cost, Speed, and Accuracy
**Cost**: LLM API pricing scales linearly with token count. An 80% reduction in input tokens means 80% lower costs for every page an agent reads. For enterprise RAG systems processing thousands of documents, this translates directly to monthly infrastructure savings.
**Latency**: Smaller payloads mean faster network round trips. Since the conversion happens at Cloudflare's edge, there's zero additional load on the origin server — the optimization is fully transparent.
**Accuracy**: Less noise means better AI output. When HTML navigation text and footer boilerplate pollute the context window, AI responses degrade. Clean Markdown input produces cleaner, more relevant answers.
### The x-markdown-tokens Header
Cloudflare's response includes an `x-markdown-tokens` header that tells the agent exactly how many tokens the Markdown content contains — before the agent processes it. This is genuinely useful: agents can now decide whether a page fits their context window before committing to ingestion.
Previously, an agent had to fetch the full page, tokenize it, and then decide if it was too large. Pre-flight token counts eliminate that waste.
### Cache Separation via Vary: Accept
The `Vary: Accept` header automatically creates separate cache entries for HTML and Markdown responses. Human browsers get HTML, AI agents get Markdown — all handled transparently at the CDN layer with no origin-side logic required.
> References:
> [Markdown for Agents - Cloudflare Developers](https://developers.cloudflare.com/fundamentals/reference/markdown-for-agents/)
> [Cloudflare Now Converts Web Pages to Markdown - MediaCopilot](https://mediacopilot.ai/cloudflare-now-converts-web-pages-to-markdown-for-ai-agents/)
> [Cloudflare Markdown for Agents - Search Engine Land](https://searchengineland.com/cloudflare-markdown-for-agents-469246)
---
## 3. Content-Signal Headers and the New Privacy Frontier
The technical benefits of Markdown conversion are clear. But this technology introduces new challenges on both the security and privacy fronts.
### Content-Signal: A Machine-Readable Usage Policy
Cloudflare introduced the `Content-Signal` HTTP header, which lets site owners declare three distinct usage permissions.
- `ai-train=yes/no` — whether AI systems may use the content for model training
- `search=yes/no` — whether the content can appear in search results
- `ai-input=yes/no` — whether AI may use the content as real-time input for responses
If robots.txt is a "no trespassing" sign for crawlers, Content-Signal is a license agreement for content usage. The distinction matters for GDPR and HIPAA compliance, where training usage and real-time inference usage carry different regulatory implications.
### AI Cloaking: The Shadow Web Problem
On the flip side, the `Accept: text/markdown` header creates a new attack surface. Researchers have demonstrated that it's trivially easy to serve different content to Markdown-requesting agents than to human browsers.
The implications are serious. A product page could show accurate pricing to humans while feeding AI agents manipulated competitor comparisons. A news site could present factual reporting to browsers while injecting disinformation into AI-consumed Markdown. This mirrors the cloaking tactics that Google penalized in the early days of SEO — but the enforcement mechanisms for AI agents are still nascent.
### Mitigation: Zero Trust and CI Verification
Cloudflare's AI Security Suite provides zero-trust policy enforcement, real-time audit logging, and prompt injection prevention. For site operators, the practical step is validating that HTML and Markdown outputs match — automated CI checks comparing both versions should become standard practice.
> References:
> [Cloudflare Markdown for Agents - QueryBurst](https://queryburst.com/blog/cloudflare-markdown-for-agents/)
> [Secure & Govern AI Agents - Cloudflare](https://www.cloudflare.com/the-net/building-cyber-resilience/secure-govern-ai-agents/)
> [HackerNews Discussion on AI Cloaking Risks](https://news.ycombinator.com/item?id=46997526)
---
{{linksurge-card}}
## 4. Making Your Site AI-Agent Friendly Without Cloudflare
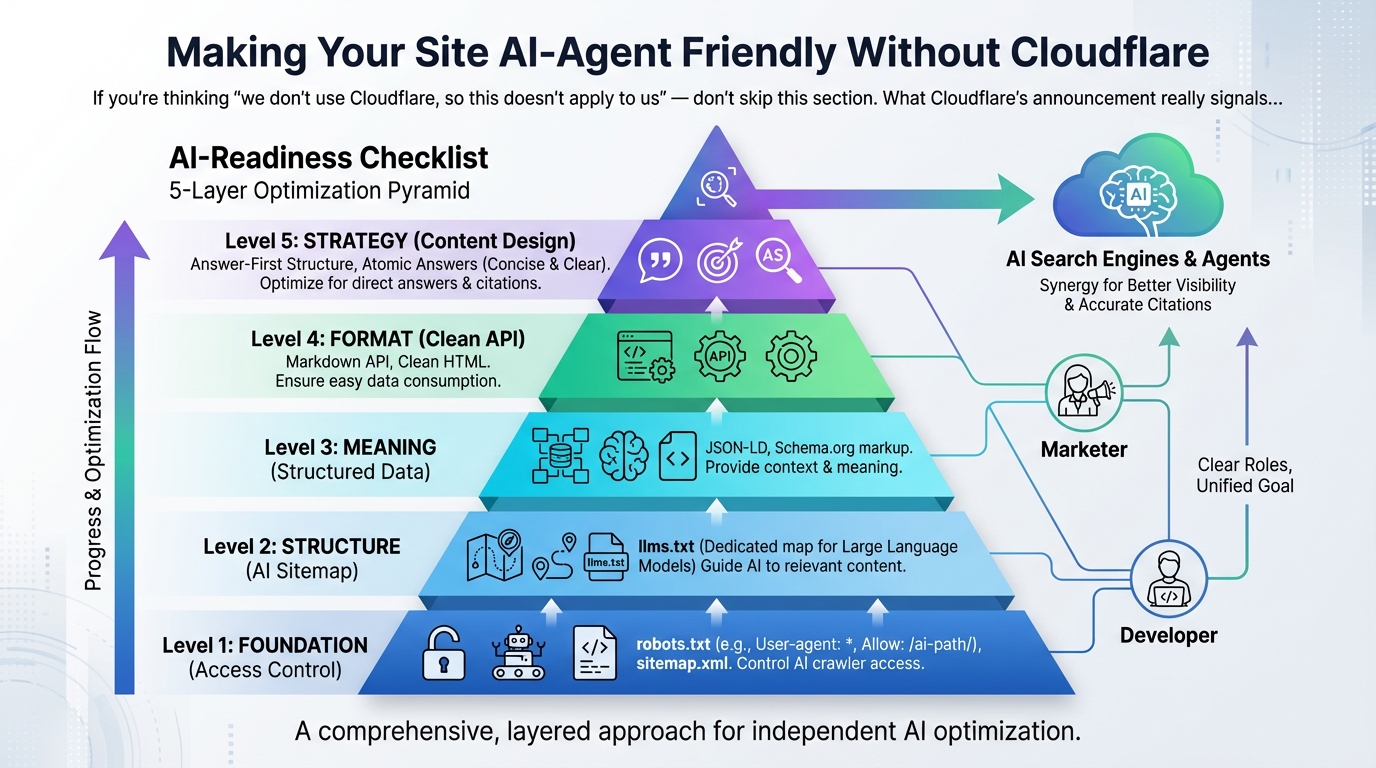
If you're thinking "we don't use Cloudflare, so this doesn't apply to us" — don't skip this section. What Cloudflare's announcement really signals is that **delivering content in AI-optimized formats has tangible value**. You can achieve the same outcomes with your own infrastructure.
### Strategy 1: Adopt llms.txt
llms.txt is an emerging standard — a text file placed at your site root that gives AI agents a structured overview of your site's content and organization. Think of it as a welcome guide for AI, complementing the access control that robots.txt provides.
### Strategy 2: Build a Markdown API Endpoint
Create a server-side endpoint like `/api/markdown?url=/blog/your-article/` that returns Markdown versions of your content. If you're using a static site generator, you likely already have Markdown source files — serving them directly is straightforward.
### Strategy 3: Comprehensive Structured Data
JSON-LD implementation (`Article` and similar) makes your content's meaning and structure machine-readable. Note, though, that a controlled experiment found no increase in AI citations from adding schema, and rich results for `FAQPage` (May 2026) and `HowTo` (2023) have both been discontinued. Markdown conversion handles formatting; structured data handles semantics. They operate on different layers, so combine them when you have a reason to make the semantics machine-readable — not because Google requires it to appear in generative AI search.
### Strategy 4: Allow AI Crawlers in robots.txt
Explicitly permit the AI crawlers you care about in your robots.txt (`OAI-SearchBot`, `PerplexityBot`, `Claude-SearchBot` for search citations; `ChatGPT-User`, `Claude-User` for user-initiated fetches; `GPTBot`, `ClaudeBot` for training) and keep your sitemap current. This is foundational — without crawler access, no amount of formatting optimization matters.
For a complete guide to AI crawler configuration and site structure optimization, see "[AI Search Rewrote the SEO Playbook — 7 Tactics for 2026](/blog/en/ai-search-seo-japan-2026/)."
### Strategy 5: Answer-First Content Structure
When AI generates responses, it preferentially references the first 40-60 words of each section. Structuring content with "Atomic Answers" at the start of every section is as effective as — or more effective than — serving Markdown format.
For platform-specific GEO implementation strategies and citation optimization tactics, see "[The Complete GEO Guide](/blog/en/geo-guide-japan-2026/)."
> References:
> [How to Serve Markdown to AI Agents - dev.to](https://dev.to/lingodotdev/how-to-serve-markdown-to-ai-agents-making-your-docs-more-ai-friendly-4pdn)
> [Cloudflare The Secret Weapon for Building AI Agents - JustThink AI](https://www.justthink.ai/blog/cloudflare-the-secret-weapon-for-building-ai-agents)
> [Don't Let Your AI Agents Go Rogue - Softprom](https://softprom.com/dont-let-your-ai-agents-go-rogue-the-cloudflare-guide-to-security-and-control)
---
## 5. Your AI Agent Optimization Roadmap
Now that the priorities are clear, here's a practical execution sequence.
### Phase 0: Baseline Assessment (1 Day)
- Run `curl -H "Accept: text/markdown"` against your own site and see what comes back
- Use [LinkSurge](https://linksurge.jp/)'s AI Overview analysis to check how your content currently gets cited by AI
- Verify your robots.txt doesn't block AI crawlers
### Phase 1: Structured Data Implementation (1-2 Weeks)
- Add JSON-LD that matches the page (`Article` and similar) to high-traffic pages
- Place 40-60 word Atomic Answers at the start of each content section
- Update sitemap.xml to ensure full AI crawler coverage
### Phase 2: Machine-Readable Format Delivery (2-4 Weeks)
- Create and deploy an llms.txt file
- Build a Markdown API endpoint (if you have the engineering resources)
- Add Content-Signal equivalent meta tags or HTTP headers
### Phase 3: Measurement and Iteration (Ongoing)
- Monitor AI citation rates with [LinkSurge](https://linksurge.jp/aio-v5)'s AI Overview analysis
- Track token efficiency improvements
- Update AI crawler permissions as new agents emerge
For a comprehensive strategy covering technical SEO, content, and link building, see the "[Complete SEO Guide for 2026](/blog/en/seo-guide-2026/)."
> References:
> [Best Practices SASE for AI - Cloudflare Blog](https://blog.cloudflare.com/best-practices-sase-for-ai/)
> [Markdown for Agents - Cloudflare Developers](https://developers.cloudflare.com/fundamentals/reference/markdown-for-agents/)
> [Cloudflare Markdown for Agents - Search Engine Land](https://searchengineland.com/cloudflare-markdown-for-agents-469246)
---
## Frequently Asked Questions
### Which Cloudflare plans support Markdown for Agents?
Pro, Business, and Enterprise plans. Activation is a single toggle in the dashboard under "Bots/AI," or via the API endpoint `PATCH /client/v4/zones/{zone_tag}/settings/content_converter`. Free plans don't have access.
### Can I make my site AI-agent friendly without Cloudflare?
Yes. Deploy an llms.txt file, build a Markdown API endpoint, implement JSON-LD structured data, and allow AI crawlers in robots.txt. These strategies work with any hosting provider or CDN. Cloudflare automates the process, but manual implementation delivers equivalent results.
### What's the difference between Content-Signal headers and robots.txt?
robots.txt controls crawler access — whether an agent can visit a page at all. Content-Signal controls content usage — what the agent is permitted to do with the content it retrieves. You might allow access but block training usage, or permit search indexing but deny real-time AI input. They're complementary controls operating at different levels.
### What is AI cloaking, and how do I prevent it?
AI cloaking means serving different content to agents requesting `Accept: text/markdown` than to human browsers. It's the AI-era equivalent of search engine cloaking. Prevention requires automated CI checks comparing HTML and Markdown outputs for content parity, plus zero-trust policies for agent access. Cloudflare's AI Security Suite provides built-in protections against this.
---
## Conclusion: AI Agent Readiness Is the New Technical SEO Baseline
Cloudflare's "Markdown for Agents" marks the moment when the web's infrastructure began formally adapting to AI consumption. Whether you use Cloudflare or not, the underlying shift is clear: sites that make their content easy for AI agents to consume will get cited more often.
Start with three things. Implement structured data, allow AI crawlers in your robots.txt, and restructure your content with answer-first design. These steps work regardless of your CDN or hosting stack.
[LinkSurge](https://linksurge.jp/)'s [AI Overview analysis](https://linksurge.jp/aio-v5) lets you track how your content gets cited across Google AI Overviews and ChatGPT in real time — a practical starting point for measuring the impact of your AI agent optimization efforts.
For a fascinating experiment showing how structured data and llms.txt alone can achieve #1 AI search citations, see "[Invisible Site Ranks #1 in AI Search](/blog/en/phantom-authority-invisible-website-ai-citation-2026/)."
---
## Satellite Sites & PBNs Are Dead: Google Penalties, SpamBrain Detection, and Safe Link Building in 2026
> URL: https://linksurge.jp/blog/en/satellite-site-seo-risks-2026/
> Date: 2026-02-14 | Category: SEO | Author: Aro Ogata
> Tags: SEO, Link Building, PBN, Satellite Sites, Google Penalty, SpamBrain, Backlinks
## Key Takeaways: 5 Risks and Realities of Satellite Site SEO
"Build a network of sites, point links at your main domain, and watch the rankings climb." That playbook had a good run — but in 2026, it's a fast track to a Google penalty. After analyzing hundreds of backlink profiles across client sites, I've seen the same pattern repeat: PBN-reliant sites lose their rankings overnight when SpamBrain catches up. Here are the five things you need to know.
1. **Self-built satellite sites for link manipulation violate Google's spam policies** — Google explicitly defines "creating multiple sites with cross-linking for the purpose of manipulating PageRank" as link spam. The policies leave no room for interpretation
2. **SpamBrain's detection accuracy took a leap in 2022 and keeps improving** — Google's AI-based spam detection system now cross-references link patterns, content similarity, and hosting infrastructure to identify entire PBN networks in a single sweep
3. **Penalties hit entire networks, not just individual sites** — When Google identifies a PBN, the penalty can extend to every site in the network plus the money site. Recovery takes 3–12 months in most cases
4. **Legitimate multi-site operations are fine — if you know the line** — Regional sites, brand-specific domains, and independently-edited media properties are perfectly acceptable. The test is simple: would the site exist without the SEO benefit?
5. **The 2026 playbook is "earn" links, not "build" them** — Original research, digital PR, expert contributions, and linkable assets deliver sustainable results without penalty risk
The rest of this article breaks down each of these points with evidence, examples, and actionable alternatives.
---
## 1. What Google's Spam Policies Actually Say About Link Networks
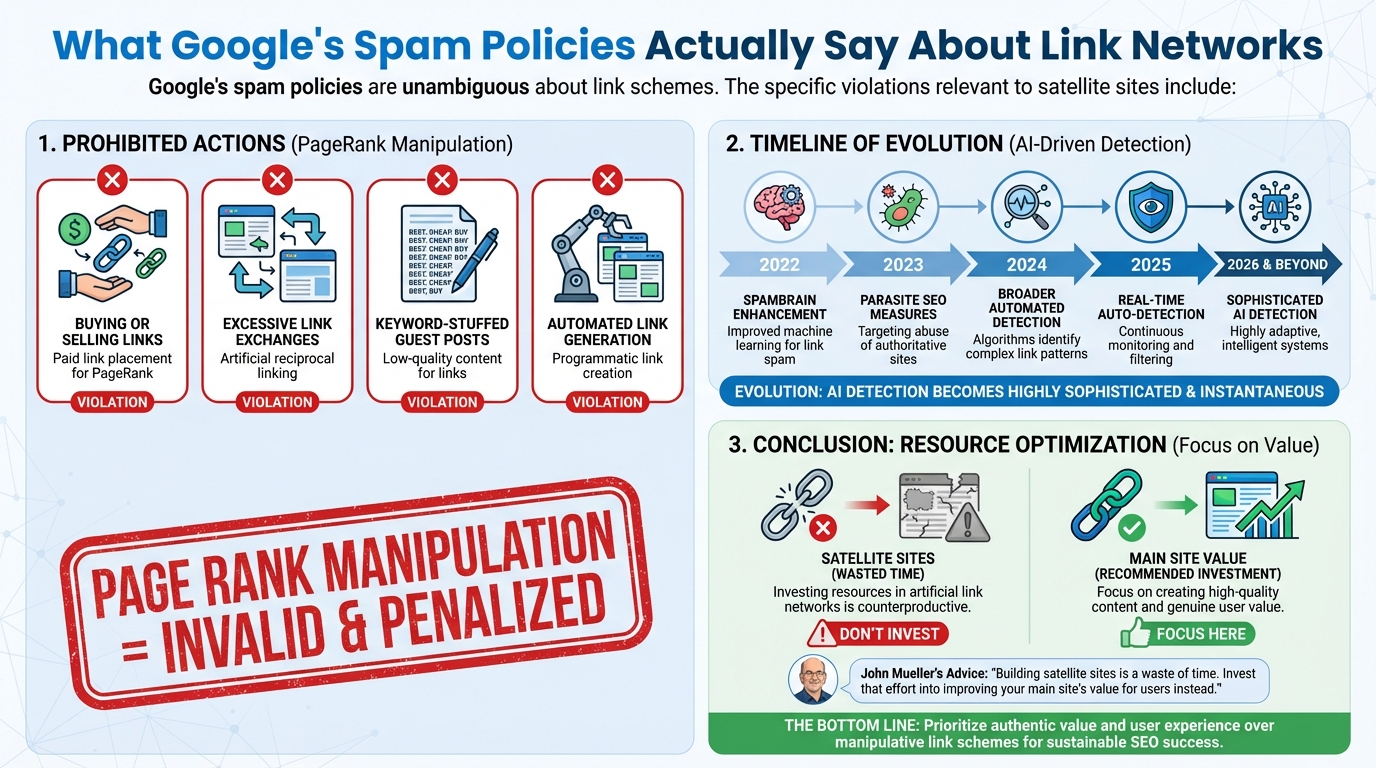
Google's spam policies are unambiguous about link schemes. The specific violations relevant to satellite sites include:
- "Buying or selling links that pass PageRank"
- "Excessive link exchanges or partner pages exclusively for the sake of cross-linking"
- "Large-scale article marketing or guest posting campaigns with keyword-rich anchor text links"
- "Using automated programs or services to create links to your site"
In short: **any site network whose primary purpose is passing link equity is a violation**, regardless of how sophisticated the execution.
Google's John Mueller has been equally direct in public statements, calling SEO-purpose satellite sites "a waste of time" in multiple Webmaster Hangout sessions. His consistent advice: invest those resources in making the main site better.
### The Link Spam Update Timeline
Google's enforcement has accelerated year over year.
- **December 2022**: Link spam update launched. SpamBrain expanded to detect both link-selling and link-buying sites
- **March 2024**: Core update combined with spam update. Added site reputation abuse ("Parasite SEO") as a penalty target
- **2025–2026**: Continuous SpamBrain improvements. Network-level detection now operates automatically without manual review in most cases
> References:
> [Google Search Spam Policies - Google Search Central](https://developers.google.com/search/docs/essentials/spam-policies)
> [December 2022 Link Spam Update - Google Search Central Blog](https://developers.google.com/search/blog/2022/12/december-2022-spam-update)
> [What are Backlinks? And How to Build Them - Backlinko](https://backlinko.com/hub/seo/backlinks)
---
## 2. How SpamBrain Detects PBNs
SpamBrain launched in 2018 as Google's AI-based spam detection system. Initially focused on identifying spam pages, it was significantly expanded in 2022 to detect link networks. Here's how it works in practice.
### Three Detection Layers
**Link pattern analysis** — SpamBrain identifies unnatural link structures. A fresh domain that only links to one specific site from day one raises immediate flags. Sudden spikes in link velocity — going from zero to hundreds of referring domains in weeks — are equally suspicious.
**Content similarity analysis** — PBN sites tend to share templated designs and thin, AI-generated content. SpamBrain compares content across domains to identify mass-production patterns, even when surface-level details differ.
**Infrastructure analysis** — Same IP range, same hosting provider, similar DNS configurations, overlapping WHOIS records. Even when PBN operators use different registrars and hosts, technical fingerprints create patterns that machine learning can detect.
### "They'll Never Find Mine" Is Wishful Thinking
PBN operators have traditionally relied on IP diversification and CMS variation to avoid detection. But SpamBrain doesn't rely on any single signal. It combines all three layers using machine learning models trained on millions of confirmed spam examples.
Google's 2024 Webspam Report noted that automated spam actions increased by over 60% year-over-year. The system identifies networks before human reviewers even look at them.
You can use [LinkSurge](https://linksurge.jp/)'s SEO analysis features to audit your own backlink profile for unnatural patterns. Visualizing domain diversity and link velocity trends helps catch PBN-related risks before Google does.
> References:
> [How Google Fights Spam – Web Spam Report 2024 - Google](https://blog.google/products/search/how-google-fights-spam-2024/)
> [Google SpamBrain: What SEOs Should Know - Search Engine Journal](https://www.searchenginejournal.com/google-spambrain-link-spam/473922/)
> [Are Private Blog Networks Safe? - Ahrefs](https://ahrefs.com/blog/private-blog-networks/)
---
## 3. Penalty Types and Their Real-World Impact
### Why Penalties Hurt More Than You Expect
When Google detects satellite site link manipulation, penalties escalate through four levels.
**Link value nullification (lightest)** — Google recognizes the spam links and zeros out their ranking contribution. No direct penalty to the main site, but every dollar and hour spent on the PBN is wasted.
**Algorithmic demotion** — No notification in Search Console, but ranking drops are steep. Because there's no explicit message, site owners often misdiagnose the problem, delaying recovery.
**Manual action** — A "Manual Actions" notification appears in Google Search Console, typically reading "Unnatural links to your site." This requires link disavowal and a reconsideration request. The review process alone takes 2–6 weeks.
**Complete de-indexing (most severe)** — The entire network plus the money site gets removed from Google's index. This is essentially a death sentence for organic traffic.
### Recovery Timeline
Recovering from a manual action follows a predictable but slow process.
1. Full audit of problematic links (1–2 weeks)
2. Disavow file creation and submission
3. Shutdown or noindex of satellite sites
4. Reconsideration request submission
5. Google review period (2–6 weeks)
6. If rejected: additional cleanup and re-submission
End to end, **3–12 months** is typical. During that period, organic traffic drops to near zero. For businesses that depend on search traffic, that's an existential threat.
> References:
> [Manual Actions Report - Google Search Central](https://support.google.com/webmasters/answer/9044175)
> [Disavow Links to Your Site - Google Search Central](https://support.google.com/webmasters/answer/2648487)
> [How to Recover from a Google Penalty - Moz](https://moz.com/blog/how-to-recover-from-a-google-penalty)
---
## 4. Legitimate Multi-Site Operations vs PBNs — Where's the Line?
"Satellite site" isn't inherently negative. The issue is purpose and execution.
### Acceptable Multi-Site Setups
These configurations don't violate Google's guidelines.
- **Regional sites**: A company with offices in New York, London, and Tokyo operates separate sites for each market with localized content and services
- **Brand-specific sites**: A consumer goods company runs separate domains for distinct product lines, each with unique content and audiences
- **Owned media properties**: An independently-edited industry blog that publishes original research and analysis, with its own editorial standards separate from the corporate site
### Red Flags That Indicate a PBN
Sites with these characteristics will likely be flagged.
- Thin or duplicate content across the network
- Most articles contain links pointing to the money site
- No genuine readership or community engagement
- Irregular publishing schedule — new posts only appear when links are needed
- Templated designs shared across multiple sites in the network
### The One Question That Matters
Here's the litmus test I use with every client.
**"If this site generated zero SEO benefit, would you still operate it?"**
If the answer is yes, you're running a legitimate multi-site business. If no, you're running a PBN by another name.
For the right approach to building brand presence across the web, see "[91% of AI Answers Come from Sites That Aren't Yours — Off-Site SEO in the AI Era](/blog/en/offsite-seo-geo-2026/)."
> References:
> [Are PBN Links Effective for SEO? - Semrush](https://www.semrush.com/blog/pbn-links/)
> [Private Blog Networks Explained - Ahrefs](https://ahrefs.com/blog/private-blog-networks/)
> [Google's John Mueller on Satellite Sites - Search Engine Roundtable](https://www.seroundtable.com/google-satellite-sites-waste-of-time-33182.html)
---
{{linksurge-card}}
## 5. Five Safe Backlink Strategies That Actually Work
Building links without PBNs takes more effort upfront, but delivers compounding returns with zero penalty risk.
### Strategy 1: Publish Original Research
Industry surveys, benchmark reports, and proprietary data attract natural links from news sites, analysts, and industry blogs. Content like "State of [Industry] 2026" or "Survey: 1,000 [Professionals] on [Topic]" gives journalists something concrete to cite.
### Strategy 2: Digital PR
Go beyond press releases. Build direct relationships with journalists and industry voices. Platforms like Connectively (formerly HARO) and Qwoted connect experts with reporters looking for sources. A single expert quote in a major publication can generate dozens of follow-on links.
### Strategy 3: Create Linkable Assets
Free tools, calculators, interactive data visualizations, and comprehensive databases give other sites a reason to link. Think: "Free Core Web Vitals Checker" for an SEO company, or "Mortgage Calculator" for a real estate firm. These assets earn links passively over time.
### Strategy 4: Contribute to Authoritative Publications
Guest articles for respected industry sites are fundamentally different from PBN posts. Real bylined contributions go through editorial review, demonstrate expertise, and strengthen E-E-A-T signals. The key distinction: low-quality "guest post farms" that accept anything are just PBNs with better marketing.
### Strategy 5: Community Participation and Knowledge Sharing
Active participation on Reddit, Quora, Stack Overflow, and industry forums builds brand mentions that matter for both traditional SEO and AI search. AI search engines heavily reference these platforms — [LinkSurge](https://linksurge.jp/) data shows Reddit and Quora consistently rank among the top-cited sources in AI-generated answers.
For a comprehensive strategy covering technical SEO, content, and link building, see the "[Complete SEO Guide for 2026](/blog/en/seo-guide-2026/)."
> References:
> [Link Building Strategies That Actually Work - Backlinko](https://backlinko.com/link-building-strategies)
> [How to Get High Quality Backlinks - Ahrefs](https://ahrefs.com/blog/how-to-get-backlinks/)
> [Link Building for SEO: The Definitive Guide - Moz](https://moz.com/blog/link-building)
> [Digital PR for Link Building - Search Engine Journal](https://www.searchenginejournal.com/digital-pr-link-building/487322/)
---
## 6. Case Studies: Penalties and Recoveries
### Case 1: E-commerce Site Hit by Link Spam Update
A mid-size online retailer had built a network of 50+ satellite sites funneling links to their main domain. Rankings initially climbed, but the December 2022 link spam update wiped out 80%+ of their keyword positions. After receiving a manual action notice, recovery required shutting down the entire satellite network, filing disavow requests, and submitting a reconsideration request. The process took 4 months, with an additional 6 months before traffic returned to pre-penalty levels. Total downtime: 10 months.
### Case 2: A Legitimate Owned Media Success
A B2B enterprise runs an independently-edited industry publication with its own editorial team. Links to the main corporate site appear in fewer than 10% of articles, always in natural context. The publication is frequently cited in Google AI Overviews and ranks independently for competitive industry keywords. No penalties, no risk.
### Case 3: PBN to Content Marketing Pivot
A SaaS startup used PBNs as part of their early growth strategy. When an algorithmic penalty hit in 2023, organic traffic dropped 70%. They shut down the PBN sites and removed the links, pivoted to content marketing and digital PR, and rebuilt from scratch. Within 8 months, traffic recovered to pre-penalty levels. Six months later, they hit all-time highs — surpassing what the PBN had ever delivered.
The takeaway: **PBN recovery is painful but possible, and the clean strategy consistently outperforms the old one over time.**
For practical AI search optimization strategies that complement safe link building, see "[AI Search Rewrote the SEO Playbook — 7 Tactics for 2026](/blog/en/ai-search-seo-japan-2026/)."
> References:
> [Google Link Spam Update Impact - Search Engine Roundtable](https://www.seroundtable.com/google-link-spam-update-impact-34651.html)
> [How to Recover from a Google Penalty - Moz Community](https://moz.com/community/q/topic/how-we-recovered-from-google-penalty)
> [The State of Link Building 2025 - Authority Hacker](https://www.authorityhacker.com/link-building-survey/)
---
## Frequently Asked Questions
### What's the difference between a satellite site and a PBN?
"Satellite site" is a general term for any site operated alongside a main domain. It includes legitimate setups like regional sites, brand-specific domains, and owned media properties. A PBN (Private Blog Network) specifically refers to a network of sites created solely to manipulate link equity. PBN sites typically lack original content, genuine audiences, and independent editorial purpose.
### Can you recover from a Google PBN penalty?
Recovery is possible but slow. For manual actions, the process involves auditing all problematic links, creating a disavow file, shutting down PBN sites, and submitting a reconsideration request. The full cycle typically takes 3–12 months. Algorithmic penalties are harder to diagnose and require a fundamental shift in link strategy before rankings recover.
### Can small businesses build safe backlinks without a big budget?
Absolutely. Industry forum participation, local media outreach, business directory listings, and contributing expert quotes through platforms like Connectively cost nothing but time. Tools like [LinkSurge](https://linksurge.jp/) help small businesses visualize their backlink profile and prioritize the highest-impact opportunities.
### Is link building still necessary in the AI search era?
Yes, but the definition has expanded. Traditional backlinks still influence Google's organic rankings. However, AI search engines prioritize brand mentions over raw link counts — Ahrefs' 75,000-brand study found brand web mentions correlate with AI citations at r=0.664, while backlinks trail at r=0.10. The 2026 approach combines link acquisition, brand mention building, and E-E-A-T reinforcement.
[Safe Link Building in 2026: 5 White-Hat Strategies](/blog/en/safe-link-building-guide-2026/) provides detailed playbooks for five penalty-free backlink acquisition strategies, including costs, timelines, and ROI data.
---
## Conclusion: From Manipulating Links to Earning Them
The risk-reward math on PBNs and satellite site link schemes has completely flipped. SpamBrain's detection accuracy means the question isn't "if" you'll get caught — it's "when." And the penalty — months of lost traffic, manual cleanup, uncertain recovery — far outweighs any short-term ranking boost.
Three things to do now.
1. Audit your backlink profile for unnatural patterns and disavow anything suspicious
2. Invest in content marketing and digital PR that earns links organically
3. Expand beyond link building to include brand mentions and E-E-A-T signals
[LinkSurge](https://linksurge.jp/)'s [AI Overview analysis](https://linksurge.jp/aio-v5) lets you track both backlink quality and AI citation status in one place. Make the transition to safe link building with data, not guesswork.
---
## How yutori Captured Gen Z: The SNS-First Brand Strategy Behind Japan's Fastest Apparel IPO
> URL: https://linksurge.jp/blog/en/yutori-sns-brand-strategy-2026/
> Date: 2026-02-14 | Category: SNS | Author: Aro Ogata
> Tags: SNS Strategy, Gen Z Marketing, D2C, yutori, Brand Strategy, UGC, TikTok, Instagram
## Key Takeaways: 5 Lessons from yutori's SNS Brand Strategy
yutori went from a single Instagram account to Japan's fastest apparel IPO in just five years and eight months. Revenue hit 8.3 billion yen (~$55M) in FY2025 — up 92% year-over-year. What makes this story worth studying isn't the growth numbers alone; it's the operating model behind them. Every piece of yutori's business — hiring, brand management, product development — is structured around SNS-driven feedback loops. Here are the five core principles that other brands can learn from.
1. **Turn brand accounts into influencers** — yutori strips corporate polish from its social accounts. Staff post personal content where products appear naturally, not as ads. Followers feel like they're following a person, not a company. The group's total SNS following has reached roughly 2.89 million
2. **Kill underperformers fast with a league system** — Their Y-League ranks brands Y1 through Y5 by monthly revenue. Brands falling below 7 million yen/month (~$47K) face automatic shutdown. Currently running 38 brands, yutori targets 70 within five years
3. **Turn TikTok comments into a sales funnel** — Staff post casual daily-life videos wearing yutori products. When viewers comment "Where's that from?", the reply includes a purchase link. Zero ad spend, zero ad feel
4. **Design offline events as UGC factories** — Pop-ups aren't just about in-store sales. Photo spots, limited drops, and staff interactions are engineered to generate attendee posts that become the next wave of customer acquisition
5. **Hire your target demographic** — With an average employee age of 23.8 and roughly half the staff in creative roles, yutori doesn't research Gen Z trends — they live them. Content resonates because the creators are the audience
The sections below break down each of these strategies.
---
## 1. Who Is yutori — From "Vintage Girl" to Japan's Fastest Apparel IPO
In April 2018, 25-year-old Takanori Kataishi launched an Instagram curation account called "Furujo" (Vintage Girl). That account became the seed for yutori, a company that would go on to list on the Tokyo Stock Exchange Growth Market in December 2023 — the fastest IPO in Japanese apparel history.
From roughly $67K in first-year revenue, yutori scaled through its flagship streetwear brand 9090 (Ninety Ninety), a period under the ZOZO Group umbrella (2020), and eventually independence through its IPO. In August 2024, the company acquired heart relation — the company behind former AKB48 member Haruna Kojima's "Her lip to" brand — for approximately 1.7 billion yen (~$11.3M), expanding from streetwear into feminine fashion.
FY2026 revenue is projected at 11 billion yen (~$73M). But the numbers only tell half the story.
What sets yutori apart from legacy apparel companies is the order of operations. Traditional brands start with product, then build distribution, then bolt on marketing. yutori started with community — building an SNS audience first, then launching products into that audience. This inverted sequence changes everything about how the company operates.
For Western readers, think of it as Gymshark's community-first model combined with Shein's speed-to-market — except yutori manages it with an employee base of just 180 people.
> References:
> [yutori CEO Kataishi on growth strategy targeting 30B yen - Net Shop Forum](https://netshop.impress.co.jp/node/13923)
> [yutori IPO: Fastest in Japanese apparel history - fashionsnap.com](https://www.fashionsnap.com/article/2023-12-27/yutori-listed/)
> [yutori acquires Her lip to parent company for 1.7B yen - WWDJAPAN](https://www.wwdjapan.com/articles/1882106)
---
## 2. The Y-League System — Don't Nurture Brands, Select Them
### Why Multi-Brand Strategy Works for Gen Z
yutori doesn't bet big on a single mega-brand. Instead, it launches many small brands and lets the market decide which survive. As of March 2025, the company operates 38 brands with a 5-year target of 70.
This approach aligns with how Gen Z shops. This generation values discovery over conformity — finding a niche brand nobody else wears matters more than wearing the latest from an established label. A portfolio of small, distinct brands turns shopping into a treasure hunt.
### How Y-League Works in Practice
After launch, each brand is ranked Y1 through Y5 based on monthly revenue. Y5 brands — those generating less than 7 million yen per month (~$47K) — face automatic shutdown. Decisions are data-driven, not emotional. This limits inventory risk and concentrates resources on proven winners.
The "launch, test, keep or cut" cycle works because yutori's existing SNS channels and logistics infrastructure are shared across brands. Per-brand startup costs stay low, and SNS engagement data provides fast signal on what's working.
This framework mirrors how venture portfolios operate: place many small bets, double down on winners, and cut losers quickly. It's applicable well beyond fashion — any D2C brand running multiple product lines or sub-brands can adopt a version of this approach.
For a deeper look at how SNS content strategy intersects with AI search algorithms and platform-specific optimization, see "[X, Instagram & LinkedIn AI Search Optimization: 2026 SNS Strategy Guide](/blog/en/sns-ai-search-optimization-2026/)."
> References:
> [yutori CEO on 30B yen growth strategy - Net Shop Forum](https://netshop.impress.co.jp/node/13923)
> [yutori's next-generation brand incubation strategy - WWDJAPAN](https://www.wwdjapan.com/articles/2130123)
> [Analyzing yutori's Gen Z appeal - note](https://note.com/happybranding/n/n44612c7ebc84)
---
## 3. SNS Operations — The "Brand = Influencer" Design Philosophy
### Removing Corporate Feel from Instagram
The most striking thing about yutori's Instagram accounts is that they don't look like corporate accounts at all.
Instead of product catalog shots, content shows staff going about their daily lives with yutori products woven in naturally. Captions read like personal thoughts, not brand copy. This "brand account behaves like an influencer" approach shrinks the distance between follower and brand.
Short-form video (Reels and Stories) leans heavily into trending audio to boost watch-through rates. The team designs 15-30 second clips that make you want to watch until the end, incorporating save and DM-share triggers throughout.
### Turning "Where's That From?" Into Revenue
The most effective part of yutori's SNS playbook is how they use TikTok's comment section as a purchase funnel.
A staff member posts a day-in-my-life video. They're casually wearing a 9090 piece. Comments roll in: "What brand is that?" "Where can I buy it?" The reply includes a direct purchase link. The whole interaction feels organic because it is — no ad creative, no sponsored post label.
CEO Kataishi has publicly stated that "clothes sell through TikTok comments." This isn't accidental discovery; it's engineered UGC strategy. By creating a "find it yourself" experience rather than a "being sold to" experience, yutori sidesteps Gen Z's well-documented ad resistance.
Platforms like [LinkSurge](https://linksurge.jp/) confirm that for Gen Z-focused brands, AI search citation rates correlate strongly with the volume of SNS-generated UGC. The "don't sell, let them discover" approach ends up boosting brand visibility in AI search results too.
> References:
> [yutori on why clothes sell through TikTok comments - App Marketing Lab](https://markelabo.com/n/nb5f864dbeaa7)
> [Learning Gen Z SNS marketing from yutori - apparel01.com](https://apparel01.com/2024/05/25/learn-from-yutori-examples-of-sns-marketing-for-apparel-brands-that-capture-the-hearts-of-generation-z/)
> [Instagram corporate account case studies - real-us.co.jp](https://real-us.co.jp/blog/instagram-company-example3/)
---
## 4. Pop-Ups and OMO — Offline Events as UGC Generators
### Why Pop-Ups Are an Extension of SNS Strategy
The majority of yutori's revenue comes from e-commerce, but the company is investing heavily in physical retail. Store count doubled to 46 locations by March 2025. The 9090 brand also expanded internationally with a Shanghai pop-up.
The key insight: these pop-ups aren't designed just to sell product on the floor. They're designed so that attendees post about the experience on social media. Limited-edition items, photo-worthy installations, direct staff interaction — every element is calibrated to generate "I was there" content. Each attendee's post becomes organic marketing that draws the next wave of visitors.
This is the full OMO (Online Merges with Offline) loop: SNS and e-commerce drive awareness, pop-ups deepen the experience, and attendee posts feed back into the online conversation. It's a self-reinforcing cycle that grows with each iteration.
As AI search engines increasingly weight brand mentions across social platforms, the total volume of UGC directly impacts how often a brand gets cited in AI-generated answers. For more on how off-site brand signals affect AI search visibility, see "[91% of AI Answers Come from Off-Site Sources — Off-Site SEO and GEO Strategy](/blog/en/offsite-seo-geo-2026/)."
> References:
> [yutori 9090 Shanghai pop-up success - PR TIMES](https://prtimes.jp/main/html/rd/p/000000131.000034263.html)
> [yutori FY2025 results - fashionsnap.com](https://www.fashionsnap.com/article/2025-05-14/yutori/)
> [yutori D2C + OMO strategy analysis - note](https://note.com/yamadaaaaaaa/n/n1b28f37d6700)
---
{{linksurge-card}}
## 5. Organizational Design — Gen Z Selling to Gen Z
### The Structural Advantage of a 23.8-Year-Old Workforce
yutori employs roughly 180 people with an average age of 23.8. About half the staff hold creative positions.
This isn't just a "young company" data point. When your creators are the same age as your customers, you don't need trend research. The team's own instincts serve as a real-time market sensor. Content resonates because it's made by people who genuinely share the audience's tastes, references, and communication style.
### Hiring for SNS Content Creation Ability
yutori's hiring process explicitly evaluates "selling sense" and short-form video creation skills. This means every person involved with a brand — not just the marketing team — can create content. The result: no dependency on external creative agencies, and a dramatically faster content production cycle.
CEO Kataishi has said "lifetime employment is the best" — an unusual stance for a startup founder. While most fast-growing companies accept high turnover as a cost of business, yutori is investing in long-term retention. The combination of youthful speed and organizational stability creates a foundation for sustained trend-riding.
Compare this with Western D2C brands that outsource content creation to agencies or freelancers. The content may be polished, but it often lacks the authentic voice that comes from creators who are genuinely part of the target community.
> References:
> [CEO Kataishi: "Lifetime employment is the best" - WWDJAPAN](https://www.wwdjapan.com/articles/1842035)
> [yutori CEO Kataishi interview - Nikkei X-Trend](https://xtrend.nikkei.com/atcl/contents/18/01060/00003/)
> [yutori company page - Wantedly](https://www.wantedly.com/companies/yutori2)
---
## 6. Five Transferable Tactics from yutori's Playbook
yutori's case isn't just a "they were young and lucky" story. These five tactics are applicable across industries and markets.
### Tactic 1: Give Your Brand Account a Personality
Strip the corporate voice. Let the person behind the account show through. Prioritize staff lifestyle content over product shots. This single shift can meaningfully change engagement rates, regardless of industry.
### Tactic 2: Engineer Comment-Driven Purchase Funnels
Create posts designed to provoke "Where's that from?" questions on TikTok and Instagram. Reply with product links. This costs nothing in ad spend and works for food, beauty, home goods, and fashion alike.
### Tactic 3: Apply Quantitative Kill Criteria to Projects
Adopt a Y-League-style framework: set clear revenue or engagement thresholds, and shut down initiatives that don't hit them within a defined timeframe. Remove emotion from the decision. This applies to product lines, content series, marketing campaigns — anything with measurable output.
### Tactic 4: Design Events for Social Posting First
When planning any offline activation, start with the question: "What will attendees post?" Photo moments, exclusive access, and personal interactions are all UGC triggers. Plan for them deliberately rather than hoping they happen organically.
### Tactic 5: Hire Creators from Your Target Demographic
Internal content creation by people who belong to your target audience produces content that feels authentic — because it is. External agencies can supplement, but the core voice should come from within.
[LinkSurge](https://linksurge.jp/)'s AI Overview analysis lets you track how your brand is being cited in AI search results at the keyword level. Connecting SNS activity to AI search visibility gives you a clearer picture of where your marketing investment is actually paying off.
> References:
> [yutori's brand incubation strategy - WWDJAPAN](https://www.wwdjapan.com/articles/2130123)
> [Learning marketing from yutori - note](https://note.com/men_in_black/n/n2271d42eca17)
> [yutori growth strategy analysis - CBO Lab](https://cbo-media.com/lab/yutori-2)
---
## 7. Limitations and Risks of the yutori Model
No case study is complete without acknowledging the risks.
**Brand dilution** — Running 38 brands simultaneously means each individual brand story stays shallow. The Y-League system manages inventory risk, but a "test and discard" orientation can undermine the long-term fan loyalty that makes a brand durable. There's a tension between portfolio breadth and brand depth.
**Governance risk in a young organization** — A 23.8-year average age delivers speed but raises questions about crisis management, compliance, and institutional knowledge. No major public incidents have surfaced, but as the company scales, governance maturity will need to keep pace.
**Trend dependency** — Gen Z trends rotate fast. Today's hit brand can feel dated in six months. The multi-brand model diversifies this risk, but the constant pressure to stay at the bleeding edge of culture puts sustained strain on the organization.
Even with these risks, yutori's model stands out because so much of it is systematized and reproducible. It's not built on a single founder's taste — it's built on a process.
---
## Frequently Asked Questions
### What is 9090, yutori's flagship brand?
9090 (Ninety Ninety) is a streetwear brand launched in 2018 that draws on 1990s and 2000s youth culture aesthetics. It's the most recognized brand in the yutori portfolio and expanded internationally with a pop-up in Shanghai in 2025.
### What is the Y-League system?
Y-League is yutori's brand evaluation framework. Brands are ranked Y1 through Y5 based on monthly revenue. Y5 brands — those generating less than 7 million yen per month (roughly $47K) — face automatic shutdown. It removes emotional attachment from business decisions and ensures resources flow to proven performers.
### Why does yutori's SNS strategy resonate with Gen Z?
The biggest factor is authenticity of voice. Content is created by employees whose average age is 23.8 — the same demographic as the target customer. Combined with a deliberate strategy of making brand accounts feel like personal accounts rather than corporate channels, this produces content that Gen Z trusts rather than skips.
### Can yutori's strategy work outside fashion?
Yes. The core tactics — personalizing brand accounts, using comment sections as purchase funnels, applying quantitative criteria to project decisions, designing events for UGC, and hiring from your target audience — are industry-agnostic. They're especially relevant for D2C and e-commerce businesses. To measure how SNS efforts translate to AI search visibility, tools like [LinkSurge](https://linksurge.jp/) can track brand citations across AI platforms in real time.
---
## Conclusion: Building an SNS-First Business
yutori's success isn't about being good at social media. It's about structuring an entire business around the assumption that SNS is the primary channel through which customers discover, evaluate, and advocate for brands.
Three things you can start with today: give your social accounts a genuine human voice, design your TikTok and Instagram content to generate "Where's that from?" comments, and set quantitative thresholds for every initiative so you can cut losers fast and double down on winners.
SNS activity and AI search visibility are increasingly linked. LinkSurge's [AI Overview analysis](https://linksurge.jp/aio-v5) lets you see exactly how your brand's social presence translates into citations in Google AI Overviews and other AI search platforms — giving you the data to connect SNS investment to measurable search outcomes.
---
## X, Instagram & LinkedIn AI Search Optimization: The 2026 Social Media Strategy Guide
> URL: https://linksurge.jp/blog/en/sns-ai-search-optimization-2026/
> Date: 2026-02-13 | Category: SNS | Author: Aro Ogata
> Tags: Social Media Strategy, AI Search Optimization, X Twitter, Instagram, LinkedIn, Algorithm, Social Media Marketing
## Key Takeaways: 5 Ways to Get Your Social Content Picked Up by AI in 2026
After months of analyzing how AI algorithms on X, Instagram, and LinkedIn decide what to surface, one thing is clear: the platforms have quietly shifted from engagement-based to signal-quality-based ranking. Social media marketing in 2026 isn't just about reaching people — it's about getting **recommended and cited by AI**. Here are 5 things that matter most right now.
1. **Learn what each platform's AI actually rewards** — X prioritizes dwell time and DM shares. Instagram rewards watch-through rates and saves. LinkedIn's semantic search favors structured expertise. If you don't know what signals each algorithm cares about, posting more won't help
2. **Match your content format to the algorithm** — Threads on X, 30–90s Reels plus carousels on Instagram, multi-image carousels and document posts on LinkedIn. The format that AI ranks highest is different on every platform
3. **Use AI tools to generate and rotate hashtags dynamically** — The optimal number varies: 1–2 on X, 5–8 on Instagram, 3–5 on LinkedIn. AI hashtag generators measure trend velocity and competition in real time, so stop reusing the same tags every time
4. **Let AI schedulers pick your posting times** — Tools like Buffer, Sprout Social, and Rebrandly analyze historical engagement patterns and auto-select the best time slot for your specific audience
5. **Engineer your first 60 minutes of engagement** — Algorithms evaluate early reactions to decide whether to amplify a post. Coordinated comments and shares from team members within the first hour can multiply your reach significantly
Below, we break down each of these areas with the latest data and real-world examples.
---
## 1. AI Algorithms Running Social Media in 2026
In 2026, X, Instagram, and LinkedIn all use Transformer-based models or proprietary AI systems as their core recommendation engines.
The days of "post it and your followers will see it" are long gone. Algorithms decide **who** sees your content, **when**, and **in what order**. In my analysis of each platform's recommendation system, I've found that understanding these decision criteria is the single biggest lever for improving reach — more so than content quality alone.
| Platform | AI Engine | Top Signals | Notable 2026 Features |
|:---|:---|:---|:---|
| **X (Twitter)** | Grok (Transformer-based); recommendation code open-sourced | Dwell time, DM shares | Prompt-driven search, AI content pipeline automation |
| **Instagram** | Multiple AI systems (Feed, Reels, Stories, Explore each optimized separately) | 1–3s hook retention, watch-through rate, saves, shares | Movie Gen (text-to-video AI editing), auto-optimized hashtags |
| **LinkedIn** | 360Brew (large-scale Mixture-of-Experts), semantic search | Comment and share quality, format-specific engagement rate | AI-powered People Search, real-time engagement prediction |
### X's algorithm: Grok and the dwell_time era
X's recommendation algorithm was open-sourced in 2023, giving us direct visibility into its inner workings. In 2026, it still runs on a Transformer-based model with deep Grok integration.
The key takeaway: **dwell time and DM shares carry the highest scores**. A simple "like" matters far less than how long someone spends reading your post, or whether they forward it to a friend via DM. Content that stops the scroll and holds attention wins.
There's also a `P(not_interested)` probability score. If the algorithm predicts a user will tap "Not interested," your post's distribution gets throttled. Low-quality volume posting actively hurts you.
### Instagram's algorithm: multiple AI systems working together
Instagram runs **separate AI systems for Feed, Reels, Stories, and Explore**. In 2026, a "Your Algorithm" feature was added, letting users adjust their own content preferences.
For new reach on Reels, the single most impactful factor is **hook retention in the first 1–3 seconds**. Drop viewers there, and it doesn't matter how good the rest of your content is. After that, **save rate and Sends per Reach** (the share-to-reach ratio) are the strongest signals — content that people want to revisit or send to friends gets amplified.
### LinkedIn's algorithm: a semantic search engine
LinkedIn integrated a Mixture-of-Experts model called 360Brew into its search engine in 2025, enabling **meaning-level search** rather than keyword matching. AI-Powered People Search was also added, automatically extracting job titles and skills from profiles to expand search queries.
On the content side, image carousels and native document posts significantly outperform text-only posts in engagement rate. Comment "quality" is also evaluated — a thoughtful reply with a specific question scores higher than a generic "Great post!"
AI search engines like ChatGPT and Perplexity are increasingly citing social media posts as sources. For more on how AI search is reshaping content strategy, see "[How AI Search Is Reshaping SEO: 7 Actionable Strategies for 2026](/blog/en/ai-search-seo-japan-2026/)."
> References:
> [Twitter/X Algorithm Update Analysis - LinkedIn](https://www.linkedin.com/posts/tschranz_twitter-x-just-updated-its-algorithm-activity-7372287244323176448-g42d)
> [How the Instagram Algorithm Works - Hootsuite](https://blog.hootsuite.com/instagram-algorithm/)
> [LinkedIn 360Brew Semantic Search - arXiv](https://arxiv.org/html/2602.07309v1)
> [X Publishes AI-Powered Algorithm Code - Social Media Today](https://www.socialmediatoday.com/news/x-formerly-twitter-publishes-ai-powered-algorithm-code/810015/)
---
## 2. Content Format Strategy by Platform
With the algorithm mechanics established, let's get specific about which formats each AI rewards most.
### X: threads and image posts dominate
On X, **threads** (multi-tweet sequences) perform best. The reason is straightforward: threads extend dwell time. A user who reads through a 5–10 tweet thread gives the algorithm far more engagement signal than someone who scrolls past a single tweet.
| Format | Algorithm Impact | Best For |
|:---|:---|:---|
| Threads (5–10 posts) | Maximizes dwell time | How-tos, data breakdowns, case studies |
| Image posts | Increases scroll-stop rate | Infographics, charts, screenshots |
| Short video (under 2 min) | High DM share potential | Tutorials, news commentary |
| Text only | Lower dwell time | Breaking news, hot takes |
Dan Koe, a creator with over 500K followers on X, consistently uses 5–7 tweet threads to break down business and psychology concepts. His threads regularly exceed 10M impressions because they're structured to reward reading — each tweet ends with a hook that pulls you into the next one, maximizing dwell time.
### Instagram: the Reels + carousel combo
On Instagram, **Reels (30–90 seconds) are the primary channel for new reach**. Meanwhile, **carousels (up to 20 slides) drive dwell time and repeat views**, making them ideal for deepening engagement with existing followers.
Three things to nail with Reels: a visual hook in the first 3 seconds, your core message within 30 seconds, and a share-oriented CTA ("Save this for later" or "Send this to someone who needs it"). For carousels, structure your slides as "Problem → Explanation → Solution → CTA" — this arc keeps people swiping to the end.
The Scottsdale Public Library provides an unexpected example. By creating educational Reels about local history and reading recommendations, they grew from 3K to over 15K followers in 6 months. Their secret: consistent 30-second Reels with strong opening hooks and a "save for later" CTA that boosted their save rate well above the industry average.
### LinkedIn: multi-image carousels and documents
On LinkedIn, multi-image carousels and native documents (PDFs) generate the highest engagement rates. Carousels are particularly effective because the "swiped to slide 2+" signal is strongly weighted by the algorithm.
Short video (under 60 seconds) also works, but most LinkedIn users browse with sound off. **Captions and text overlays are essential**, not optional.
> References:
> [Instagram Algorithm 2025: Which Content Formats Get the Most Reach - Atlas SEO](https://www.atlasseo.co.uk/news/instagram-algorithm-2025--which-content-formats-get-the-most-reach/)
> [LinkedIn Social Media Benchmarks - Social Insider](https://www.socialinsider.io/social-media-benchmarks/linkedin)
> [Top LinkedIn Content Wins 2025 - Souvik Dutta](https://www.linkedin.com/pulse/top-linkedin-content-wins-2025-what-worked-why-souvik-dutta--ygbmc)
---
## 3. Hashtag Strategy: AI-Powered Dynamic Optimization
This is one area where I've seen the biggest gap between what people do and what actually works. Hashtags serve two purposes: they're discovery entry points for users, and they're classification signals that help AI understand your content's topic. But the optimal approach is completely different on each platform.
| Platform | Recommended Count | Key Principle |
|:---|:---|:---|
| **X** | 1–2 | Character limit demands precision. Use one trending tag + one brand tag |
| **Instagram** | 5–8 | Focus on niche/community tags. Maxing out at 30 is counterproductive |
| **LinkedIn** | 3–5 | Industry and topic tags woven naturally into the post body |
### Why reusing the same hashtags hurts you
Repeating identical hashtags across posts signals "spam" to algorithms. On Instagram specifically, tag repetition has been linked to shadowban behavior — your posts get quietly deprioritized without any notification.
AI tools like Bika.ai and PostNitro can auto-generate hashtag candidates based on your post content, then score each one by trend velocity and competition level. This is faster and more accurate than manual research, and it ensures you're rotating tags with every post.
> References:
> [How to Generate Hashtags with AI - ASCN](https://ascn.ai/blog-no-code/kak_pravilno_sdelat_heshtegi_s_pomoshchyu_ai)
---
## 4. Posting Time Optimization and AI Scheduling
I've tested the "best posting time" recommendations from several tools, and the key lesson is this: "When to post" still matters. But in 2026, the answer isn't a static time chart — it's a machine learning model trained on your audience's historical engagement patterns.
### Recommended posting windows (US Eastern Time)
| Platform | Best Windows | Best Days |
|:---|:---|:---|
| **X** | 9:00–12:00 PM, 5:00–6:00 PM | Weekdays |
| **Instagram** | 7:00–9:00 AM, 12:00–2:00 PM | Monday–Friday |
| **LinkedIn** | 7:00–8:30 AM, 12:00–1:00 PM, 5:00–6:00 PM | Tuesday–Thursday |
These are averages. Your specific audience may behave differently. That's where AI scheduling tools come in — they analyze your account's engagement data and calculate personalized optimal times.
### How to choose an AI scheduling tool
| Tool | Key Strength | Platform Support |
|:---|:---|:---|
| **Buffer + Zapier** | ChatGPT-generated drafts auto-queued for posting | X |
| **Sprout Social ViralPost** | ML-based optimal send time calculation | LinkedIn, Instagram |
| **Rebrandly** | Click-data-driven optimal posting time analysis | All platforms |
| **Bika.ai** | End-to-end: ideation → generation → scheduling | X |
> References:
> [Best Time to Post on Social Media Using AI-Backed Click Data - Rebrandly](https://www.rebrandly.com/blog/best-time-to-post-on-social-media-using-ai-backed-click-data)
> [Best Times to Post on LinkedIn - Sprout Social](https://sproutsocial.com/insights/best-times-to-post-on-linkedin/)
> [How to Automate Twitter/X Posts with AI - Bika.ai](https://bika.ai/blog/how-to-automate-twitter-x-posts-with-ai)
---
## 5. Performance Measurement: Traditional Metrics + AI-Specific KPIs
Execution without measurement is just guessing. The KPIs that matter for social media shifted significantly in 2026. On top of traditional metrics like follower growth and likes, you now need to track **the signals that AI algorithms actually weight** and **how often AI search engines cite your social posts**.
### Platform-specific KPIs worth tracking
| Metric Category | X | Instagram | LinkedIn |
|:---|:---|:---|:---|
| **Dwell/Attention** | Dwell time (seconds spent reading) | Hook retention rate, total watch time | Slide completion rate, avg. view duration |
| **Engagement** | Retweet rate (industry avg: 0.12%) | Save rate, Sends per Reach | Engagement per impression (avg: 5.2%) |
| **Sharing/Amplification** | DM share count | Share count | Comment quality, influencer reshares |
| **AI-Specific** | AI search citation count | Semantic relevance score | Profile optimization score |
### Tracking your AI citation rate
ChatGPT, Perplexity, and other AI search tools are increasingly pulling social media posts as citation sources. To track whether your social content is being referenced in AI-generated answers, [LinkSurge](https://linksurge.jp/)'s GEO Monitor tracks citation status across major AI platforms at the keyword level, letting you see which posts are being picked up and how your Citation Rate trends over time.
For a deeper look at how social content fits into the broader off-site SEO picture, see "[91% of AI Answers Come from Sites That Aren't Yours](/blog/en/offsite-seo-geo-2026/)."
> References:
> [AI Search Metrics - O8 Agency](https://www.o8.agency/blog/ai/ai-search-metrics)
> [Social Media Benchmarks 2025 - Social Insider](https://www.socialinsider.io/social-media-benchmarks)
> [LinkedIn Social Media Benchmarks - Social Insider](https://www.socialinsider.io/social-media-benchmarks/linkedin)
---
## 6. Case Studies: What's Working in Practice
Theory is useful. Proof is better. What I find most instructive about these examples is that none of them relied on massive budgets — they won by understanding what each algorithm rewards. Here are three cases.
### Case 1: B2B newsletter grows LinkedIn impressions 7x
A B2B SaaS company adopted the carousel format with a strict "Problem → Solution → CTA" structure for every LinkedIn post. They also implemented a rule: **within 60 minutes of posting, 5 team members leave substantive comments and reshare**. The result: weekly impressions jumped from 2,400 to 18,000 — a 7x increase — and lead generation improved by 3.5%.
The lesson isn't just "make better content." It's that **engineering the first-hour engagement spike** is what triggers the algorithm to amplify your post to a wider audience.
### Case 2: Scottsdale Public Library's Instagram Reels strategy
The Scottsdale Public Library used 30-second educational Reels about local history, book recommendations, and community events. By leading every Reel with a strong visual hook and ending with "Save this for later," they achieved a **save rate more than double the industry average** and grew from 3K to 15K+ followers in 6 months.
This is a reminder that Reels optimization isn't just for brands and influencers. Any organization with interesting stories can win on Instagram if they understand what the algorithm rewards.
For a real-world D2C case study, Japanese apparel company yutori turned staff daily-life TikToks and Reels into a zero-ad-spend sales machine — with 2.89 million followers ([yutori FY2025 results - fashionsnap.com](https://www.fashionsnap.com/article/2025-05-14/yutori/)) and 92% year-over-year revenue growth ([yutori CEO on 30B yen growth strategy - Net Shop Forum](https://netshop.impress.co.jp/node/13923)). Their "brand account as influencer" approach and Y-League brand selection system are detailed in "[How yutori Captured Gen Z with SNS-First Brand Strategy](/blog/en/yutori-sns-brand-strategy-2026/)."
For TikTok-specific algorithm mechanics (Completion, Share, Re-watch) and how AI search engines cite TikTok videos, see the sister post "[TikTok SEO Playbook: Winning the Search Engine 40% of Gen Z Actually Uses (2026)](/blog/en/tiktok-seo-ai-search-2026/)".
### Case 3: Cross-platform strategy delivers 45% engagement lift
A startup integrated AI-generated hashtags with scheduling tools and ran coordinated cross-platform campaigns across X, Instagram, and LinkedIn for 3 months. The key: they **adapted the format for each platform** — threads on X, carousels on Instagram, documents on LinkedIn — rather than posting identical content everywhere. The outcome: **45% total engagement increase and 30% follower growth** across all three platforms.
> References:
> [Top LinkedIn Content Wins 2025 - Souvik Dutta](https://www.linkedin.com/pulse/top-linkedin-content-wins-2025-what-worked-why-souvik-dutta--ygbmc)
> [Instagram Algorithm 2025 - Enrich Labs](https://www.enrichlabs.ai/blog/instagram-algorithm-2025)
---
## 7. Global Audience Demographics and Platform Selection
Each platform attracts a distinct audience. Choosing where to invest your time should start with understanding where your target audience actually spends theirs.
| Platform | Global MAU | Primary Age Group | Key Usage Patterns |
|:---|:---|:---|:---|
| **X** | ~600M | 25–49 | Real-time news, public commentary, professional networking |
| **Instagram** | ~2B | 18–34 | Visual storytelling, lifestyle, product discovery, short-form video |
| **LinkedIn** | ~1B | 30–55 | Professional networking, B2B lead generation, thought leadership |
X is the go-to platform for real-time conversations and news commentary. Its open, public-by-default nature makes it the strongest platform for building thought leadership through consistent, high-value threads.
Instagram dominates visual-first content and product discovery. With over 2 billion monthly active users, it's where brands invest most heavily in short-form video and influencer partnerships.
LinkedIn has quietly become the most effective B2B content platform. Its semantic search means that well-structured profile data (job history, skills, certifications) directly affects how widely your posts reach beyond your immediate network.
The connection between social media visibility and AI search citations shouldn't be overlooked. For a comprehensive breakdown of how to optimize for AI citations across all channels, see "[The Complete GEO Guide: How to Get Cited by ChatGPT, Gemini, and Perplexity](/blog/en/geo-guide-japan-2026/)."
> References:
> [Essential Instagram Stats - DataReportal](https://datareportal.com/essential-instagram-stats)
> [Social Media Benchmarks - Dash Social](https://www.dashsocial.com/social-media-benchmarks/instagram)
> [How the LinkedIn Algorithm Works - SourceGeek](https://www.sourcegeek.com/en/news/how-the-linkedin-algorithm-works-2025-update)
---
{{linksurge-card}}
---
## 8. Your 7-Step Action Plan: Start This Week
Here's how to put everything above into practice — broken into three phases.
**Phase 1: Audit and baseline (1 week)**
1. **Map algorithm signals to your current performance** — Pull the last 30 days of analytics for each platform and check how your posts perform on dwell time, save rate, and share rate. Identify which formats are already working and which are underperforming
2. **Research competitors** — Use [LinkSurge](https://linksurge.jp/) and Social Insider to analyze competitors' social posts. Identify the formats, timing, and hashtags driving their highest engagement
**Phase 2: Build your content system (2–3 weeks)**
3. **Create platform-specific templates** — Build a thread template for X, a "Hook → Core message → CTA" Reels script for Instagram, and a "Problem → Solution → CTA" carousel template for LinkedIn
4. **Set up AI scheduling** — Choose a scheduling tool (Buffer, Sprout Social, or Rebrandly), connect your accounts, and enable personalized optimal time recommendations
5. **Build a hashtag generation workflow** — Use an AI hashtag tool to generate fresh tags for every post. Set a rule: no identical hashtag sets across consecutive posts
**Phase 3: Optimize and iterate (ongoing)**
6. **Formalize the first-hour engagement rule** — Designate 3–5 team members to comment and share within 60 minutes of every post. This single change can multiply reach by 3–5x
7. **Run monthly KPI reviews** — Track dwell time, save rate, share rate, and AI citation count on a monthly cycle. Adjust content format, posting time, and hashtag strategy based on what the data shows
For the full picture on SEO, AI search, and content strategy, see "[The Complete SEO Guide for 2026](/blog/en/seo-guide-2026/)."
> References:
> [How to Automate Your X/Twitter So It Grows Itself - Medium/Zapier](https://medium.com/zapier-ai-automation/how-to-automate-your-x-twitter-so-it-grows-itself-incl-video-2d83b705234b)
> [Instagram Algorithm 2025 Complete Guide for Marketers - Dataslayer](https://dataslayer.ai/blog/instagram-algorithm-2025-complete-guide-for-marketers)
---
## Frequently Asked Questions
### How often should I post on each platform?
It depends on the platform. On X, 3–5 posts per day (including threads) is a solid cadence. On Instagram, 3–5 posts per week (aim for 2 Reels + 2 carousels). On LinkedIn, 2–3 posts per week performs well. Quality matters more than volume — prioritize posts that hit the algorithm's top signals (dwell time, save rate, share rate) over sheer posting frequency.
### Is it safe to post AI-generated content directly?
Using AI for drafts is fine. Posting raw AI output without editing is risky. Algorithms can deprioritize content that reads as generic or template-based. On LinkedIn especially, posts with personal experience and original perspective are explicitly favored. Always add your own voice, examples, and insights before publishing.
### Should I focus on all three platforms at once?
If resources are limited, pick 1–2 platforms where your target audience is most active. For B2B, start with LinkedIn. For younger demographics and visual content, prioritize Instagram. For real-time engagement and thought leadership, go with X. Expand to additional platforms only after you've built traction on your primary one.
### Can social media posts get cited by AI search engines like ChatGPT?
Yes, and it's happening more frequently. LinkedIn long-form posts and X threads are being cited by ChatGPT and Perplexity as sources in AI-generated answers. Posts that contain structured data, specific numbers, and expert-level insights are most likely to be selected. You can track whether your content is being cited using [LinkSurge](https://linksurge.jp/)'s GEO Monitor, which monitors AI citation status across platforms.
### What's the single highest-impact change I can make today?
Start engineering your first 60 minutes of engagement. Get 3–5 people to leave substantive comments and share your post immediately after publishing. This early engagement spike signals the algorithm to amplify your post to a wider audience. It's the fastest way to increase reach without changing your content at all.
---
## Conclusion: In AI-Powered Social Media, Signal Design Comes First
Social media strategy in 2026 comes down to three things. First, design content that generates the signals each algorithm cares about — dwell time, save rate, share rate. Second, automate the repetitive parts: use AI for hashtag generation and scheduling so you can focus on content quality. Third, engineer your first-hour engagement to trigger algorithmic amplification.
X, Instagram, and LinkedIn each run different AI models, but they share a common principle: **they measure whether people genuinely found your content valuable**, then use that signal to decide how widely to distribute it. Chasing vanity metrics doesn't work anymore. Building a system that consistently delivers high-signal content, in the right format, at the right time — that's what works.
LinkSurge's [GEO Monitor](https://linksurge.jp/) tracks how your social content and web pages are being cited across AI search engines in real time — the first step toward building a data-driven AI visibility strategy.
---
## 91% of AI Answers Come from Sites That Aren't Yours: A 2026 Guide to Off-Site Brand Visibility
> URL: https://linksurge.jp/blog/en/offsite-seo-geo-2026/
> Date: 2026-02-12 | Category: GEO | Author: Aro Ogata
> Tags: GEO, off-site SEO, AI search, brand mentions, LLM citations, ChatGPT, Perplexity
## Key Takeaways: Optimizing Your Own Site Is Not Enough for AI Search
The most surprising finding in my analysis of AI citation patterns this year has been this: what happens *outside* your website matters far more than what's on it. AI search engines like ChatGPT, Perplexity, and Google AI Overviews build answers by reading across the sources that rank near the top and synthesizing them with citations. This means your brand's presence across the entire SERP — not just your own #1 ranking — determines whether AI picks you up. Here are the five things that matter most.
1. **Brand mentions are the strongest predictor of AI citations** — Ahrefs' study of 75,000 brands (AI Overviews) found web brand mentions correlate with AI citations at r=0.664 versus r=0.218 for backlinks — roughly 3× stronger. Note this is correlation, not established causation
2. **Ranking #1 is not enough** — AI engines read snippets from all top results. If competitors dominate positions 2-10 through roundup articles, reviews, and forums, the AI will likely cite them instead
3. **91% of AI answers cite third-party sources** — Your own site accounts for just 9% of brand mentions in AI-generated responses. The rest comes from Reddit, review sites, industry publications, and forums
4. **Each AI platform has different source preferences** — ChatGPT leans toward encyclopedic sources while Perplexity favors UGC and recent content. Only about 11% of cited domains overlap between the two, a divergence confirmed across multiple studies (individual percentages move a lot — see the note in section 4)
5. **Zero-click is the new normal** — Zero clicks followed 58.5% of all US Google searches in 2024 (SparkToro / Datos), and Ahrefs estimates a 58% drop in position-one CTR when AI Overviews appear. Being referenced as a source matters more than being clicked
The sections below break down each point with data and actionable steps.
---
## 1. What Is "Off-Site SEO"? — Everything You Do Beyond Your Own Website
Before diving into the data, let's clarify a term that trips people up. SEO breaks down into two broad categories:
| Type | What It Covers | Examples |
|------|---------------|----------|
| **On-site SEO** | Improving your own website | Page speed, meta tags, content quality, structured data, internal linking |
| **Off-site SEO** | Building brand presence outside your own domain | Brand mentions on other sites, guest articles in industry publications, forum participation, review site listings |
In plain terms, off-site SEO means **getting your brand name talked about in places you don't control**.
For years, off-site SEO was almost synonymous with link building — get other sites to link to yours, and Google rewards you with higher rankings. That playbook still has value for traditional search, but the AI search era has rewritten the rules. What matters now is not just whether other sites link to you, but **whether they mention your brand name at all** — with or without a hyperlink.
The rest of this article explains why that shift happened and what to do about it.
> References:
> [GEO vs SEO: What's The Difference And Why It Matters? - Writesonic](https://writesonic.com/blog/geo-vs-seo)
> [Generative Engine Optimization (GEO): Is It the New SEO? - Built In](https://builtin.com/articles/generative-engine-optimization-new-seo)
---
## 2. How AI Search Engines Actually "See" the Web
Understanding the mechanics is the starting point. From my observation of how ChatGPT and Perplexity behave in practice, here's the pipeline they follow when generating answers — and it's remarkably consistent across platforms.
### The Five-Step Pipeline
1. **Query decomposition** — The AI breaks a user prompt into 1-5 search keywords
2. **Search grounding** — Those keywords are queried against a search index (Google AI Overviews and Gemini use Google's; ChatGPT and Perplexity use their own or a partner's)
3. **Snippet scanning** — The AI reads titles and descriptions from all returned results
4. **Selective deep reads** — When snippets aren't enough, the AI opens full webpages
5. **Answer synthesis** — Information from multiple sources is merged into a cited response
**Updated August 2026.** This article previously said AI search engines have no crawlers of their own. That no longer holds. OpenAI runs `OAI-SearchBot`, Perplexity runs `PerplexityBot`, and Anthropic runs `Claude-SearchBot` (search) and `Claude-User` (user-initiated fetches) — note that `ClaudeBot` is [for training-data collection](https://support.claude.com/en/articles/8896518-does-anthropic-crawl-data-from-the-web-and-how-can-site-owners-block-the-crawler) and does not affect search citations; [analysis of crawl logs](https://www.botify.com/blog/openai-tripled-web-crawl) indicates OpenAI has sharply increased its crawling and is building an index of its own.
The "discovery layer" idea has not disappeared, though. Google AI Overviews and AI Mode run on Google's index, and Gemini relies on it too. And on every platform, what gets read at answer time is the handful of pages ranking near the top.
The practical implication is unchanged: **confirm the crawlers you care about can reach your site, then work on your presence across the whole results page.** Which crawler matters depends on the service — see "[What Is LLMO? The Complete Beginner's Guide](/blog/en/llmo-guide-beginners-2026/)" for the breakdown.
### Why Owning #1 Isn't the Whole Game
In traditional SEO, ranking first was the finish line. AI search engines, however, scan snippets from the entire first page. They look for cross-source agreement before committing a brand name to their answer.
Picture this: your site holds position one, but positions 2 through 10 are filled with "Best SEO tools 2026" listicles, G2 reviews, and Reddit threads — all mentioning your competitor. The AI sees one source for you and nine for them. The math isn't in your favor.
> References:
> [GEO: Generative Engine Optimization — Princeton University (KDD 2024)](https://arxiv.org/abs/2311.09735)
> [Why Off-Site SEO Matters in GEO & AI Search — LLMrefs](https://llmrefs.com/blog/why-offsite-seo-matters-for-geo)
---
## 3. The Data: Brand Mentions Beat Backlinks
When I first saw the Ahrefs data, I was genuinely surprised — I'd expected backlinks to be a stronger factor. But the numbers tell a clear story. Multiple studies published between 2025 and 2026 confirm the same pattern. Brand mentions outperform backlinks as predictors of AI citation. This is closely tied to Google's "query fan-out" technique, where AI decomposes each search into multiple sub-queries — and your brand needs to surface across those sub-queries to get cited. For a deep dive into how fan-out works, see "[What Is Query Fan-Out? A Beginner's Guide](/blog/en/query-fan-out-guide-2026/)."
### Ahrefs' 75,000-Brand Study
Ahrefs analyzed 75,000 brands across ChatGPT, Google AI Mode, and AI Overviews to identify what actually drives AI visibility.
| Factor | Correlation with AI Citations (r) | Takeaway |
|--------|-----------------------------------|----------|
| Brand web mentions | 0.664 | Strongest predictor by far |
| Branded anchor text | 0.527 | How your name appears in links matters |
| Brand search volume | 0.392 | Direct reflection of brand awareness |
| Domain Rating (DR) | 0.326 | Still matters, but less than expected |
| Referring domains | 0.295 | — |
| Total backlinks | 0.218 | About one-third of brand mentions |
The top three predictors are all off-site brand signals. Backlinks — the cornerstone of traditional SEO — correlated at 0.218, roughly one-third the strength of brand mentions. These figures come from [the AI Overviews analysis](https://ahrefs.com/blog/ai-overview-brand-correlation/) (Spearman rank correlation); the coefficients differ somewhat for ChatGPT and AI Mode.
These are correlations, though, not demonstrated causation. Brands with many mentions tend to be well known already, and that awareness may itself be what drives citation.
### Princeton's GEO Paper: Small Sites Can Win Too
The Princeton GEO paper (accepted at KDD 2024) systematically tested which content optimizations improve visibility in generative engines. Adding citations and statistics boosted visibility by up to 40%. For sites ranked fifth in SERP, the "Cite Sources" method alone produced a 115.1% increase in AI visibility.
You don't need to be a top-three domain. If your content is structured for easy citation and your brand appears across multiple results, AI engines will find you.
### Brand Mentions Are 3× More Important Than Backlinks
The Digital Bloom's 2025 AI Visibility Report puts it plainly — brand mentions carry three times the weight of backlinks for AI search visibility. Clustering brand mentions across multiple LLMs increases first-position citation likelihood by up to 2.8×.
> References:
> [Top Brand Visibility Factors in ChatGPT, AI Mode, and AI Overviews (75K Brands Studied) — Ahrefs](https://ahrefs.com/blog/ai-brand-visibility-correlations/)
> [GEO: Generative Engine Optimization — arXiv](https://arxiv.org/abs/2311.09735)
> [2025 AI Visibility Report: How LLMs Choose What Sources to Mention — The Digital Bloom](https://thedigitalbloom.com/learn/2025-ai-citation-llm-visibility-report/)
---
## 4. Platform-by-Platform: Where AI Gets Its Sources
With the overall data in hand, let's drill into the platform-level differences. Not every AI engine reads the same sources. Understanding their preferences helps you prioritize where to build presence.
### Citation Source Comparison
| AI Search Engine | Top Cited Source | Share | Key Trait |
|-----------------|-----------------|-------|-----------|
| ChatGPT | Wikipedia | 7.8% | Encyclopedic accuracy |
| Perplexity | Reddit | 6.6% | Real-time user-generated content |
| Google AI Overviews | Reddit | 2.2% | Balanced mix of authoritative sources |
> **Updated August 2026.** The table above comes from Profound's analysis of 680 million citations between August 2024 and June 2025. The Perplexity–Reddit relationship in particular has been in flux since Reddit sued Perplexity and several data-scraping firms in October 2025 ([Search Engine Land](https://searchengineland.com/reddit-sues-perplexity-serpapi-scraping-google-463681), [CNBC](https://www.cnbc.com/2025/10/23/reddit-user-data-battle-ai-industry-sues-perplexity-scraping-posts-openai-chatgpt-google-gemini-lawsuit.html)). We have not found a study measuring how Perplexity's citation mix changed after the suit. Still, the underlying arrangement changed, so the Perplexity figures above may no longer hold — check current studies before relying on any individual percentage.
What has held up across multiple studies is the divergence itself: only about 11% of domains get cited by both ChatGPT and Perplexity. A brand that dominates one platform might be invisible on another. Multi-platform coverage is no longer optional.
### Why Reddit Matters So Much
Reddit deserves special attention. It accounts for 21% of AI citations across platforms, and Google has given it significantly improved indexation since their 2024 partnership. Highly upvoted, detailed recommendations carry more weight than brief or negative mentions. AI systems appear to evaluate both sentiment and engagement when selecting Reddit sources.
### The 9% Problem
Brand websites are directly mentioned in only 9% of AI-generated responses. The remaining 91% comes from third-party content — review sites, comparison articles, forums, industry publications, and social platforms.
This is the data point that anchors the entire thesis of this article. No amount of on-site SEO can capture the other 91%. Only off-site presence can.
For a deeper look at GEO technical implementation and platform-specific citation strategies, see our "[Complete GEO Guide](/blog/en/geo-guide-japan-2026/)."
> References:
> [AI Platform Citation Patterns — Profound](https://www.tryprofound.com/blog/ai-platform-citation-patterns)
> [Reddit, Quora, and Third-Party Sites: The New Kings of AI Search — AI Marketing Labs](https://ai-marketinglabs.com/lab-experiments/reddit-quora-and-third-party-sites-the-new-kings-of-ai-search)
> [How AI Engines Choose Brands: Citation Patterns Revealed — BrightEdge](https://www.brightedge.com/resources/weekly-ai-search-insights/how-different-ai-search-engines-choose-which-brands-to-recommend)
---
## 5. The Zero-Click Acceleration
Off-site brand visibility gains urgency from another trend: zero-click searches are eating traditional organic traffic.
### The Numbers Are Stark
| Metric | Value | Source |
|--------|-------|--------|
| Zero-click rate, all US Google searches (2024) | 58.5% | [SparkToro / Datos (a Semrush company), 2024](https://sparktoro.com/blog/2024-zero-click-search-study-for-every-1000-us-google-searches-only-374-clicks-go-to-the-open-web-in-the-eu-its-360/) (data from Sept 2022–May 2024) |
| Zero-click rate with AI Overviews | — | No primary source found; omitted here |
| Position-one CTR reduction from AI Overviews | 58% (measured 1.6% vs 3.7% forecast without AI Overviews) | Ahrefs, February 2026 |
| AI Mode session containment rate | 75% | Semrush, September 2025 |
Ahrefs' February 2026 update puts the position-one CTR reduction from AI Overviews at 58% — nearly double the 34.5% measured in April 2025.
That 58% needs reading carefully. The measured values in the report are 7.3% in December 2023 versus 1.6% in December 2025, but not all of that gap is attributable to AI Overviews. Accounting for the broader CTR decline across informational keywords, the report forecasts CTR would have been 3.7% without AI Overviews — and it is the gap between that forecast and the measured 1.6% that yields 58%.
### Reframe the KPI: From Clicks to Citations
The zero-click trend sounds dire, but it opens a new opportunity. Even when users don't click through to any website, AI Overviews display source attributions. If your brand is referenced as a source, you gain visibility without the click.
The strategic shift: your primary asset is no longer "traffic from position one" but "brand presence across the sources AI reads." That's off-site SEO in a nutshell.
> References:
> [Update: AI Overviews Reduce Clicks by 58% — Ahrefs](https://ahrefs.com/blog/ai-overviews-reduce-clicks-update/)
> [Semrush AI Overviews Study — Semrush](https://www.semrush.com/blog/semrush-ai-overviews-study/)
> [Zero-Click Search 2026: AI Overviews Cut Clicks by 58% — PikaSEO](https://pikaseo.com/articles/zero-click-search-ai-overviews-2026)
---
## 6. The Playbook: Building AI-Visible Off-Site Presence
With the data and platform analysis covered, let's get practical. Based on what I've seen work across multiple client engagements, here's the execution plan I recommend — broken into five phases.
### Phase 1: Baseline Measurement (Weeks 1-2)
Measure your current "SERP share of voice" before making changes.
- **Search your target keywords and count how many times your brand appears in the top 20 results** — include your own site plus third-party mentions
- Use [LinkSurge](https://linksurge.jp/) AI Overview analysis to check citation status across key queries
- Ask ChatGPT and Perplexity your core product questions — note whether your brand appears in responses
### Phase 2: Earn Third-Party Coverage (Months 1-3)
Systematically pursue placements in the content types AI engines read most.
| Tactic | Example | Expected Impact |
|--------|---------|-----------------|
| Listicle placements | Get reviewed in "Best X tools 2026" roundups on G2, Capterra, industry blogs | Multiple SERP positions carrying your brand |
| Industry publication bylines | Guest posts on Search Engine Journal, Moz Blog, HubSpot | E-E-A-T authority signals |
| Press coverage | Newswire distribution for product launches and original research | News site mentions indexed quickly |
| Podcast appearances | Interviews on industry podcasts (transcripts get indexed) | Long-form brand mentions with context |
### Phase 3: Cultivate User-Generated Content (Ongoing)
Reddit, Quora, and Stack Overflow are among AI's most-cited sources. Organic presence here is high-impact.
- **Participate authentically in relevant subreddits** — answer questions with genuine expertise. Promotional posts backfire
- **Encourage customer reviews** on G2, Capterra, Trustpilot — AI engines read and cite these platforms
- **Create shareable data** that community members reference in their own posts and answers
A standout example of UGC driving AI citations is yutori, a Japanese D2C apparel company that designs pop-up events as UGC factories and turns TikTok comments into purchase funnels. Their full SNS-first strategy is analyzed in "[How yutori Captured Gen Z with SNS-First Brand Strategy](/blog/en/yutori-sns-brand-strategy-2026/)."
### Phase 4: Publish Citable Original Research (Quarterly)
AI engines prioritize information that multiple sources can independently verify.
- **Surveys and industry benchmarks** — original data that journalists and bloggers reference
- **Case studies with specific numbers** — concrete results are more citable than vague claims
- **Regularly updated statistics pages** — 65% of AI bots access pages updated within the past year
### Phase 5: Strengthen Entity Recognition
Structured entity data helps LLMs identify and trust your brand.
- **Create or update your Wikidata entry** — accurate metadata, aliases, and industry classifications improve entity recognition
- **Maintain Schema.org markup** — Organization, Product, and FAQ structured data on your site
- **Keep Google Business Profile current** — feeds into Knowledge Graph, which informs AI answers
> References:
> [AI Search Optimization: 12 Strategies for LLM Visibility 2026 — ALM Corp](https://almcorp.com/blog/ai-search-optimization-guide-llm-visibility-strategies/)
> [LLM Citation Trends That Matter in AI Search — Wellows](https://wellows.com/blog/llm-citation-trends-for-ai-search/)
> [LLMO: 10 Ways to Work Your Brand Into AI Answers — Ahrefs](https://ahrefs.com/blog/llm-optimization/)
---
## 7. Measuring What Matters: New KPIs for AI Visibility
Traditional metrics — rankings and organic sessions — don't capture the full picture anymore. Track these instead.
### GEO-Era KPIs
| KPI | How to Measure | Target |
|-----|---------------|--------|
| **AI Citation Rate** | Query target keywords in ChatGPT/Perplexity; track brand mention frequency | 30%+ of core queries |
| **SERP Share of Voice** | Count brand appearances across top 20 results for target keywords | Exceed primary competitor |
| **Brand Search Volume** | Monitor via Google Trends and Search Console | Quarter-over-quarter growth |
| **Third-Party Mention Count** | Track with Ahrefs Content Explorer or brand monitoring tools | Monthly upward trend |
| **AI Overview Appearance Rate** | Track keyword-level AI Overview presence | Monitor monthly |
[LinkSurge](https://linksurge.jp/) provides dashboards that visualize AI Overview appearance rates and keyword-level citation status, making it straightforward to track off-site efforts over time.
> References:
> [GEO Metrics That Matter: How to Track AI Citations — Averi](https://www.averi.ai/how-to/how-to-track-ai-citations-and-measure-geo-success-the-2026-metrics-guide)
> [How to measure brand visibility in AI search — Search Engine Land](https://searchengineland.com/guide/how-to-measure-brand-visibility)
---
{{linksurge-card}}
---
## 8. Common Misconceptions
### "More backlinks = more AI citations" — Not anymore
I held this assumption myself until the data changed my mind. Backlinks still matter for traditional Google rankings, but their correlation with AI citations is only 0.10. Investing all your off-site budget in link building while ignoring brand mentions is a misallocation of resources in 2026.
[Safe Link Building in 2026: 5 White-Hat Strategies](/blog/en/safe-link-building-guide-2026/) covers five specific tactics—digital PR, HARO, original research, resource pages, and expert roundups—in detail.
### "Great on-site content is enough" — It's necessary but not sufficient
On-site content quality is table stakes. But with 91% of AI responses citing third-party sources, your site alone can capture at most 9% of the citation opportunity. The remaining 91% requires off-site presence.
### "Old content still works" — Freshness drives AI citations
65% of AI bots access pages updated within the past year, and 79% reference content refreshed within two years. Publish-and-forget strategies lead to declining AI visibility over time.
For the broader impact of AI search on SEO strategy, see "[How AI Search Is Changing SEO: 7 Practical Strategies](/blog/en/ai-search-seo-japan-2026/)."
> References:
> [LLM Citations vs Backlinks in AI Search Visibility — Wellows](https://wellows.com/blog/llm-citations-vs-backlinks/)
> [2025 AI Visibility Report — The Digital Bloom](https://thedigitalbloom.com/learn/2025-ai-citation-llm-visibility-report/)
---
## Frequently Asked Questions
### What exactly is off-site SEO?
Off-site SEO covers all the optimization activities that happen outside your own website. It includes earning brand mentions on other sites, contributing guest articles to industry publications, building a presence in forums and Q&A communities, and getting listed on review platforms. Traditionally, off-site SEO centered on backlink acquisition. In the AI search era, however, the quantity and spread of brand mentions — with or without a hyperlink — matters far more.
### Why isn't optimizing my own site enough for AI search?
AI search engines read the top 10 results for a query and look for cross-source agreement. They prioritize information confirmed by multiple independent sources. Since 91% of AI-generated answers cite third-party content rather than brand websites, even a perfectly optimized site will lose out if competitors are mentioned more frequently across the rest of the SERP.
### Are backlinks still important for AI search visibility?
Backlinks retain value for traditional Google rankings, but their direct impact on AI citations is weak. Ahrefs' 75,000-brand study found brand web mentions correlate with AI citations at r=0.664, versus r=0.218 for backlinks. The Digital Bloom's research confirms brand mentions carry roughly three times the weight of backlinks for AI visibility.
### Can small brands get cited by AI search engines?
Yes. Princeton's GEO research showed that sites ranked fifth in SERP saw a 115.1% visibility increase simply by adding proper citations to their content. You don't need to be a household name — you need citation-friendly content and brand mentions spread across multiple platforms.
### Which platforms matter most for AI citations?
It varies by engine, and the individual percentages move a lot — Perplexity in particular was sued by Reddit in October 2025, so the figures above may no longer hold. The stable finding is the divergence: only about 11% of cited domains overlap between ChatGPT and Perplexity, with ChatGPT leaning toward encyclopedic sources and Perplexity toward UGC and recent content. A multi-platform strategy covering review sites, forums, industry publications, and social platforms gives you the widest coverage.
---
## Conclusion: Look Beyond Your Own Domain
AI search has shifted the competitive landscape. Ranking well on your own site is still important, but it's no longer sufficient. The brands that win AI citations are the ones whose names appear across comparison articles, review platforms, forums, and industry publications — not just on their own homepage.
Start with a simple exercise: search your top five keywords and count how many of the top 20 results mention your brand. That number is your GEO competitiveness score.
To track your brand's AI citation status across key queries, LinkSurge's [AI Overview analysis](https://linksurge.jp/aio-v5) provides real-time visibility into where and how often your brand appears in AI-generated answers.
Social media is one of the highest-impact off-site channels for building AI-visible brand mentions. For platform-specific tactics, see "[X, Instagram & LinkedIn AI Search Optimization](/blog/en/sns-ai-search-optimization-2026/)."
For a comprehensive SEO strategy covering technical SEO, content, and link building alongside GEO, see our "[Complete SEO Guide for 2026](/blog/en/seo-guide-2026/)." And for a deep dive into why PBNs and satellite site link schemes backfire in 2026, see "[Satellite Sites & PBNs Are Dead: Safe Link Building](/blog/en/satellite-site-seo-risks-2026/)."
---
## How AI Search Is Reshaping SEO: AI Overviews, AI Mode & 7 Actionable Strategies for 2026
> URL: https://linksurge.jp/blog/en/ai-search-seo-japan-2026/
> Date: 2026-02-10 | Category: AIO | Author: Aro Ogata
> Tags: AI Overviews, AI Mode, SGE, GEO, SEO, Zero-Click Search, E-E-A-T, Structured Data, 2026
## Key Takeaways: 7 Strategies to Win in AI-Driven Search
Having spent the past year tracking how AI search engines choose their sources, I can say with confidence that the rules have fundamentally changed. In 2026, ranking on page one is no longer enough. Google AI Overviews and AI Mode now deliver answers directly in the SERP, meaning **getting cited by AI** is the new competitive frontier. Here are 7 actionable strategies:
1. **Optimize content for AI citation (APO)** — Place 40–60-word answer blocks, bullet lists, and comparison tables at the top of each section so AI can extract information easily
2. **Implement structured data with a purpose in mind** — JSON-LD markup makes your page information machine-readable, but it has not been shown to increase AI citations. Implement it when you have a defined goal, such as rich results
3. **Strengthen E-E-A-T at an organizational level** — Display author bios, expert credentials, primary source citations, and last-updated dates so AI recognizes your content as a trustworthy source
4. **Adopt GEO (Generative Engine Optimization)** — Track your brand's visibility across ChatGPT, Perplexity, and Claude using "Share of Synthesis" as a new KPI alongside traditional SEO metrics
5. **Build a brand strategy for the zero-click era** — With AI Overviews reducing organic CTR by up to 60%, brand awareness and branded search volume become your most reliable traffic channels
6. **Reinforce technical SEO foundations** — Achieve Core Web Vitals targets (INP < 200ms, LCP < 2.5s, CLS < 0.1) and ensure AI crawlers can access your content through proper SSR and crawl directives
7. **Expand multimodal content** — Add descriptive alt text and metadata to images and videos so AI can reference visual information in its generated answers
Below, we explore each strategy with the latest data and real-world case studies.
---
## 1. The Shift in User Behavior — Welcome to the Zero-Click Era
### Zero-click searches are now the majority
The single most striking data point I've encountered this year is what follows. AI Overviews display summarized answers directly at the top of search results, allowing users to get the information they need without clicking any link. According to Semrush data, approximately 58.5% of Google searches in the US now result in zero clicks. When AI Overviews are present, this rate climbs even higher — early data suggests that AI Mode pushes zero-click rates to roughly 93%.
For SEO professionals, this is a fundamental shift. Ranking #1 used to guarantee a healthy click-through rate. In an AI-first search experience, even the top position may see its CTR reduced by 50–60%.
### Search queries are getting longer and more conversational
With AI Mode, users are shifting from keyword-based queries to natural-language questions. Average query length has increased to around 7 words, moving from "best CRM software" to "what's the best CRM for a 50-person SaaS company with HubSpot integration." AI handles these complex, multi-condition queries natively. This shift is powered by a technique called "query fan-out," where AI decomposes one question into multiple sub-queries and searches them in parallel. For a detailed breakdown, see "[What Is Query Fan-Out? A Beginner's Guide](/blog/en/query-fan-out-guide-2026/)."
### Generational differences in AI search adoption
AI search adoption varies significantly by age group. Younger users (18–34) are roughly 2–3x more likely to accept an AI-generated answer without visiting a website. Meanwhile, users over 55 tend to be more skeptical of AI answers and prefer visiting traditional links.
Your SEO strategy should account for the age demographics of your target audience.
### Multimodal search is becoming standard
Text-only search is no longer the default. AI Mode integrates image recognition, video understanding, and text analysis into unified answers. Google Lens searches exceed 20 billion per month, and multimodal AI can now answer questions like "what plant is this?" or "how do I fix this plumbing issue?" from a photo.
Optimizing visual content has never been more important.
To see where the zero-click shift sits in the 30-year arc from PageRank to AI Overviews, read "[How SEO Changed: A 30-Year Timeline](/blog/en/seo-history-keywords-to-ai-2026/)."
> References:
> [58.5% Zero-Click Searches — Semrush (SparkToro)](https://sparktoro.com/blog/new-2025-zero-click-search-study-58-5-of-searches-end-without-a-click-to-a-non-google-site/)
> [AI Overview CTR Impact — Seer Interactive](https://www.seerinteractive.com/insights/google-ai-overviews-research-study)
> [AI Mode Zero-Click Rates — Advanced Web Ranking](https://www.advancedwebranking.com/blog/ai-overview-impact-on-ctr/)
> [Generational AI Search Behavior — Pew Research Center](https://www.pewresearch.org/)
---
## 2. How Core Ranking Factors Are Evolving — What AI Considers "Trustworthy"
With the zero-click reality established, the next question is: what determines which sources AI actually cites? The answer comes down to trust signals.
### Why E-E-A-T matters more than ever
When AI generates an answer, it selects citation sources based heavily on **E-E-A-T (Experience, Expertise, Authoritativeness, Trustworthiness)**. Google's quality rater guidelines have always emphasized E-E-A-T, but in the AI Overviews era, these signals directly determine which sources get cited.
Trustworthiness is the most critical factor. AI systems are designed to avoid propagating misinformation, so content from recognized authorities — government agencies, peer-reviewed publications, and established industry platforms — receives preferential citation.
### Brand entity recognition drives AI visibility
Brands that AI recognizes as authoritative see amplified visibility across all AI-generated results. Research from multiple SEO studies indicates that sites cited in AI Overviews see approximately 30–40% higher CTR compared to uncited results in the same SERP.
This extends the concept of "brand SEO" into new territory. Beyond keyword rankings, how well AI systems recognize and trust your brand entity is becoming a critical success factor.
| Factor | Key Takeaway |
|---|---|
| **E-E-A-T signals** | Experience, expertise, authoritativeness, and trustworthiness directly influence AI citation selection |
| **Brand entity recognition** | Brands recognized as authoritative by AI see increased visibility across all search types |
| **Structured data (Schema)** | Makes page information machine-readable (effect on AI Overview citations unverified) |
| **Primary source attribution** | Content citing authoritative sources and original research is prioritized by AI |
| **Multimodal signals** | Image and video metadata contribute to AI information extraction and citation |
> References:
> [E-E-A-T and AI Overviews — Search Engine Land](https://searchengineland.com/google-ai-overviews-seo-strategy-440523)
> [Brand Visibility in AI Search — Rand Fishkin (SparkToro)](https://sparktoro.com/blog/)
> [Ahrefs AI Overviews Impact Study](https://ahrefs.com/blog/ai-overviews-study/)
---
## 3. The New Content Standard — What Gets Cited by AI
### Answer-Passage-Optimization (APO) explained
In my testing across multiple AI engines, I've confirmed that content structure matters as much as content quality for getting cited. APO (Answer-Passage-Optimization) is a content structuring methodology designed to make your content easy for AI to extract and cite. By placing concise 40–60-word answer blocks, bulleted lists, comparison tables, and step-by-step instructions at the beginning of each section, you dramatically increase the likelihood of AI citation.
Key APO principles include:
- **Lead with the answer** — Place the direct answer at the start of each section or article
- **Use structured lists** — Bullet points and numbered lists make information extraction straightforward for AI
- **Present comparisons in tables** — Tabular data is highly extractable and frequently cited
- **Number your steps** — Clearly sequenced content is easier for AI to extract (the citation effect itself is unverified)
### FAQ format directly addresses search intent
Question-format headings ("What is X?", "How do I Y?") followed by direct answers create ideal question-answer pairs that AI systems extract with high reliability. Adding FAQ schema on top does not compound the effect: FAQ rich results were discontinued in May 2026, and the AI-citation effect is unverified. The heading-and-answer structure itself is the likelier contributor to extractability — though that, too, has not been verified as producing more citations.
### Human editing and fact-checking remain essential
Publishing AI-generated content without human review carries significant risk. Always attribute primary sources and display last-updated dates to prevent hallucination from propagating. Google has stated that AI-assisted content is acceptable, but **accuracy and usefulness** are evaluated strictly.
### Original insights are the ultimate differentiator
Proprietary case studies, original research, expert interviews, and unique data analysis are the strongest signals for AI citation. AI compares multiple sources when generating answers, and content with genuinely unique information has a significantly higher chance of being selected.
> References:
> [AI Overview Optimization — Search Engine Journal](https://www.searchenginejournal.com/ai-overviews-optimization/520543/)
> [Structured Data and AI Citations — Schema.org](https://schema.org/)
> [Google's Helpful Content Guidelines](https://developers.google.com/search/docs/fundamentals/creating-helpful-content)
> [Original Research and AI Citation — Moz](https://moz.com/blog)
---
## 4. Technical SEO & Structured Data — The Foundation for AI Citation
### Structured data (JSON-LD) implementation
Structured data expresses your page's information in machine-readable form. These schema types cover the common cases:
> **Updated August 2026.** Subsequent testing found no confirmed effect of structured data on AI citations. Google states officially that structured data is not required for generative AI search and that there is no special schema.org markup you need to add (a statement about eligibility requirements, not a claim that Google ignores schema internally). In a controlled experiment that added schema, the changes in AI Mode (+2.4%) and ChatGPT (+2.2%) were indistinguishable from noise.
> The "AI Citation Impact" column below describes what each schema makes machine-readable — not evidence that citations increase. Details in "[Does FAQ Schema Really Get You Cited 3.2x More? We Removed the Number From Our Own Product](/blog/en/faq-schema-ai-citation-myth-2026/)."
| Schema Type | Purpose | AI Citation Impact |
|---|---|---|
| **FAQ** | Questions and answers | AI directly extracts Q&A pairs |
| **HowTo** | Step-by-step instructions | Used to generate procedural answers |
| **Article** | Article metadata | Author, date, and category trust signals |
| **Product** | Product information | Referenced in comparison and review answers |
| **Review** | Ratings and reviews | Incorporated into recommendation answers |
Figures like "3.2x higher citation rates for pages with FAQ schema" circulate widely — the one most often cited traces back to [Frase](https://www.frase.io/blog/faq-schema-ai-search-geo-aeo). All of them describe a correlation between pages that happen to have schema and pages that do not; none show that adding schema raises citations, and a controlled experiment that added schema found no increase. We trace this in full in "[Does FAQ Schema Really Get You Cited 3.2x More?](/blog/en/faq-schema-ai-citation-myth-2026/)." Pick the validator by purpose: use Google's [Rich Results Test](https://search.google.com/test/rich-results) to check eligibility for Google rich results, and the [Schema Markup Validator](https://validator.schema.org/) to check schema.org vocabulary and syntax for JSON-LD that is not aimed at a Google-specific feature.
### Core Web Vitals and mobile optimization
Core Web Vitals remain essential technical SEO fundamentals in the AI search era:
- **LCP (Largest Contentful Paint)**: Under 2.5 seconds
- **INP (Interaction to Next Paint)**: Under 200ms
- **CLS (Cumulative Layout Shift)**: Under 0.1
With mobile devices accounting for the majority of global web traffic, mobile page speed is especially critical. Optimize your images (consider next-gen formats and proper compression) and streamline CSS/JS delivery.
### AI crawler accessibility
Ensure your robots.txt permits access to important pages, and keep your sitemap updated so AI crawlers can efficiently index your content. Many AI crawlers don't execute JavaScript, so critical content should be delivered via SSR (Server-Side Rendering) directly in the HTML.
Beyond traditional crawler access, emerging standards like Cloudflare's "Markdown for Agents" are enabling sites to serve AI-optimized formats directly. For a deep dive into these approaches and what they mean for your site, see "[Cloudflare's Markdown for Agents and AI-Ready Web Optimization](/blog/en/cloudflare-markdown-for-agents-2026/)."
### International SEO considerations
For multilingual sites, proper hreflang implementation helps AI select the right language version for citation. Clean canonical URLs and well-structured URL hierarchies ensure AI can correctly identify and attribute your content across different regions.
> References:
> [Structured Data Citation Rates — Ahrefs](https://ahrefs.com/blog/structured-data-study/)
> [Schema Markup and AI Overviews — Search Engine Land](https://searchengineland.com/schema-markup-ai-overviews-445231)
> [Core Web Vitals 2026 — web.dev](https://web.dev/vitals/)
---
## 5. Traditional SEO vs. AI-Era SEO — What's Changed and What Hasn't
With the technical and content foundations covered, let's address the question I get asked most often: "Does traditional SEO still matter?" My answer is clear — yes, and here's why. The rise of AI search is reshaping SEO strategy, metrics, and priorities. However, traditional SEO hasn't become irrelevant — rather, **AI optimization is an additional layer** on top of existing best practices.
| Aspect | Traditional SEO | AI-Era SEO (AIO/GEO) |
|---|---|---|
| **Primary KPIs** | Keyword rankings, organic CTR, backlink count | AI citation count, Share of Synthesis + traditional metrics |
| **Traffic model** | Click-dependent traffic | Zero-click increasing; AI provides direct answers |
| **CTR impact** | Relatively stable click-through rates | AI Overview presence reduces CTR by 30–60% on average |
| **Brand exposure** | Top rankings = primary visibility | AI cites trusted brands regardless of exact ranking position |
| **ROI drivers** | Content volume and link building | Schema implementation + APO deliver AI visibility at lower cost |
### What is GEO (Generative Engine Optimization)?
GEO is the practice of optimizing your brand's visibility across generative AI search engines — ChatGPT, Perplexity, Claude, and Google's own AI features. Where traditional SEO tracks "Share of Voice" (visibility in search results), GEO introduces **"Share of Synthesis" (citation share in AI-generated answers)** as a new KPI.
Share of Synthesis measures how often your brand is cited when users ask AI about topics in your category. For example, if your brand appears in 30 out of 100 AI-generated answers about "best project management tools," your Share of Synthesis is 30%.
Early GEO adopters are seeing significant results. Case studies show that brands implementing comprehensive GEO strategies have achieved 400–900% increases in AI-referred sessions within 6–12 months.
For a comprehensive breakdown of GEO technical foundations, platform-specific citation tactics, and a phased implementation roadmap, see "[The Complete GEO Guide: How to Get Cited by ChatGPT, Gemini, and Perplexity](/blog/en/geo-guide-japan-2026/)."
> References:
> [Share of Synthesis — Seer Interactive](https://www.seerinteractive.com/insights/share-of-model-optimization)
> [GEO Framework — HubSpot](https://blog.hubspot.com/marketing/generative-engine-optimization)
> [AI Overview CTR Impact — Advanced Web Ranking](https://www.advancedwebranking.com/blog/ai-overview-impact-on-ctr/)
---
{{linksurge-card}}
## 6. Real-World Case Studies — Brands Winning in AI Search
What I find most encouraging about these examples is that smaller organizations are winning too — not just enterprises with massive budgets.
### Case Study 1: B2B SaaS company increases AI-referred traffic by 527%
Cadence, a B2B design automation company, implemented a comprehensive GEO strategy including structured data optimization, APO-formatted content, and authoritative citation building. Within 12 months, they saw a 934% increase in keyword rankings appearing in AI Overviews and a 527% increase in AI-referred sessions.
### Case Study 2: E-commerce brand captures AI product recommendations
A mid-size e-commerce retailer restructured their product pages with Product and Review schema, added comparison tables, and created APO-formatted buying guides. Their products began appearing consistently in AI Overview answers for "best [product category]" queries, driving a measurable increase in both branded search and direct conversions.
### Case Study 3: SaaS startup outperforms larger competitors in AI citations
A 50-person SaaS startup focused on creating in-depth, expert-authored content with comprehensive FAQ schema. Despite having a fraction of the domain authority of enterprise competitors, their content was cited more frequently in AI Overviews due to superior content structure and E-E-A-T signals. This translated into a 40% increase in qualified demo requests.
### Case Study 4: Publisher maintains traffic despite AI Overview expansion
A major industry publication proactively adopted APO formatting across their editorial content, implemented FAQ and Article schema, and strengthened author authority pages. While competitors saw 30–40% traffic declines as AI Overviews expanded, this publisher maintained stable organic traffic by consistently earning citation links within AI-generated answers.
| Case Study | Key Strategy | Result |
|---|---|---|
| Cadence (B2B) | GEO strategy + structured data + APO | 527% increase in AI-referred sessions |
| E-commerce retailer | Product/Review schema + comparison tables | Consistent AI product recommendations |
| SaaS startup | Expert content + FAQ schema + E-E-A-T | 40% increase in qualified demos |
| Industry publisher | APO formatting + Article schema + author authority | Stable traffic despite AI Overview expansion |
> References:
> [Cadence GEO Case Study — Seer Interactive](https://www.seerinteractive.com/insights/generative-engine-optimization-geo-case-study)
> [AI Overviews Traffic Impact — Search Engine Land](https://searchengineland.com/ai-overviews-traffic-impact-study-2025-448712)
> [GEO Early Adopter Results — HubSpot Research](https://blog.hubspot.com/marketing/generative-engine-optimization)
---
## 7. Your 7-Step Action Plan — Start Today
### Step 1: Content audit and APO implementation (1–2 weeks)
Review your existing pages and add 40–60-word answer blocks at the beginning of each section. Restructure key information into bullet lists, tables, and numbered steps. Start with your top 10 traffic-driving pages for maximum impact.
### Step 2: Deploy structured data on the pages it fits (2–4 weeks)
Implement only the schema that **matches what is actually on the page** (`Article` for articles, `Product` for product pages). Applying schema uniformly across a whole site produces markup that does not correspond to visible content, which can disqualify it from rich results. Pick the validator by purpose: use Google's [Rich Results Test](https://search.google.com/test/rich-results) to check eligibility for Google rich results, and the [Schema Markup Validator](https://validator.schema.org/) to check schema.org vocabulary and syntax for JSON-LD that is not aimed at a Google-specific feature. Note that Google discontinued HowTo rich results in 2023 and [FAQPage rich results in May 2026](https://developers.google.com/search/updates#removing-faq-rich-result). Types that still produce rich results include Article and BreadcrumbList (Product applies to product pages, and Review requires genuine user reviews or ratings of an eligible item — it is not valid on a general article).
### Step 3: Strengthen E-E-A-T signals (ongoing)
Implement these trust signals progressively:
- Create detailed author bio pages linked from every article
- Display expert credentials, certifications, and affiliations
- Cite primary sources with URLs and access dates
- Build authoritative backlinks from recognized industry publications
### Step 4: Technical optimization (1–2 weeks)
- Ensure mobile-first design across all pages
- Achieve Core Web Vitals targets (LCP < 2.5s, INP < 200ms, CLS < 0.1)
- Optimize robots.txt and XML sitemap for AI crawler access
- Implement SSR for all critical content pages
### Step 5: Set up AI-era KPIs (1 week)
Establish tracking for "citation count," "AI-referred sessions," and "Share of Synthesis" using Google Search Console and specialized analytics tools. LinkSurge's [AI Overview Analysis](https://linksurge.jp/aio-v5) enables real-time tracking of your brand's AI citation performance.
### Step 6: Invest in brand PR and third-party mentions (ongoing)
Increase your brand's mentions across authoritative third-party sites through press releases, industry media contributions, and thought leadership content. AI systems rely on cross-referencing multiple sources, so diverse authoritative mentions strengthen your citation probability.
### Step 7: Expand multimodal content (ongoing)
Add comprehensive alt text and metadata to all images and videos. Create visual content — infographics, comparison charts, tutorial videos — that adds genuine value. Multimodal content is increasingly referenced in AI-generated answers, especially for product comparisons, how-to guides, and visual topics.
> **Short-term**: Confirm crawler access and apply APO formatting. **Long-term**: Brand entity strengthening and organization-wide GEO adoption prepare you for a future where AI Mode is the default search experience. Schema implementation can wait until you have a traditional-search goal such as rich results.
For the other major battleground, ChatGPT search, see our complete guide to [how ChatGPT retrieves and cites](/blog/en/chatgpt-geo-complete-guide-2026/).
From the shopper's side, AI search and classic search are splitting the job rather than replacing each other. Rakuten's September 2026 survey found 54.3% of Gen Z use generative AI when shopping, yet 42.1% still name the search engine as their most trusted source. We unpack what that means in "[54% of Gen Z Ask AI Before They Buy, But Still Trust Search Most](/blog/en/gen-z-ai-shopping-search-trust-2026/)."
> References:
> [AI Overview Optimization Guide — Search Engine Journal](https://www.searchenginejournal.com/ai-overviews-optimization/520543/)
> [GEO Implementation Framework — Seer Interactive](https://www.seerinteractive.com/insights/generative-engine-optimization-geo-case-study)
> [Measuring AI Search Performance — SparkToro](https://sparktoro.com/blog/)
---
## Frequently Asked Questions
### How do I get my site cited in AI Overviews?
The most effective approach combines three elements: structured data implementation (FAQ, HowTo, and Article JSON-LD schema), APO formatting (40–60-word answer blocks placed at the beginning of each section), and strong E-E-A-T signals (author bios, primary source citations, last-updated dates). Question-format headings with direct answers are particularly effective for AI extraction.
### Does the rise of zero-click search make SEO pointless?
No. While zero-click searches reduce traditional organic traffic, being cited by AI increases brand awareness and drives branded search volume. Additionally, optimizing structured data and APO formatting increases the probability of your link appearing within AI Overview answers. The most effective strategy combines traditional SEO with GEO for maximum visibility.
### What's the difference between GEO and traditional SEO?
Traditional SEO optimizes for keyword rankings and click-through rates in search results pages. GEO (Generative Engine Optimization) optimizes for "Share of Synthesis" — your brand's citation rate across AI search engines like ChatGPT, Perplexity, and Google AI Overviews. GEO focuses on structured data, APO content formatting, and E-E-A-T signals, with AI citation count as a primary KPI rather than keyword position alone.
### How much does AI Overview reduce organic CTR?
Studies show that when AI Overviews appear, organic CTR for top-ranking results drops by approximately 50–60%. Google's AI Mode — currently in limited rollout — shows even more dramatic zero-click rates of around 93%. However, sites that are cited within AI Overviews see their CTR relatively preserved compared to uncited competitors.
### Is AI-generated content bad for SEO?
Google has stated that AI-generated content is not inherently penalized. However, content is evaluated strictly on accuracy, usefulness, and originality. Always have human editors review AI-assisted content, attribute primary sources, and add unique insights such as original data, case studies, or expert analysis. The recommended approach is to use AI as a writing assistant while ensuring human oversight and original value-add.
---
## Conclusion: In AI Search, Citation Is the New Currency
The expansion of AI Overviews and AI Mode is shifting SEO success metrics from "rankings" to "citations." But this doesn't mean traditional SEO is dead. Technical SEO, content quality, and E-E-A-T remain foundational — GEO and APO are new layers built on top of these existing strengths.
The highest-ROI starting point is **APO formatting of existing content combined with structured data implementation**. These two actions are relatively low-cost and deliver the fastest impact on AI citation rates. From there, build your brand entity authority and establish GEO measurement systems for sustainable competitive advantage.
Optimizing your own site is only part of the equation. Learn why brand mentions across the web now outweigh backlinks for AI citations in "[91% of AI Answers Come from Sites That Aren't Yours](/blog/en/offsite-seo-geo-2026/)."
Social media posts are increasingly cited by AI search engines too. For platform-specific optimization tactics for X, Instagram, and LinkedIn, see "[X, Instagram & LinkedIn AI Search Optimization](/blog/en/sns-ai-search-optimization-2026/)."
LinkSurge's [AI Overview Analysis](https://linksurge.jp/aio-v5) lets you track your brand's citation performance across Google AI Overviews and ChatGPT in real time. It's the ideal first step for building an AI-era SEO strategy.
For a ground-up explanation of the concepts behind AI citation optimization, see our [Beginner's Guide to LLMO](/blog/llmo-guide-beginners-2026/).
---
## The Complete GEO Guide for 2026: How to Get Cited by ChatGPT, Gemini, Perplexity & Claude
> URL: https://linksurge.jp/blog/en/geo-guide-japan-2026/
> Date: 2026-02-10 | Category: GEO | Author: Aro Ogata
> Tags: GEO, AI Search, ChatGPT, Perplexity, Claude, Gemini, Structured Data, E-E-A-T, RAG, 2026
## Key Takeaways: 5 Priorities for GEO Success in 2026
Over the past six months, I've systematically tested how ChatGPT, Perplexity, and Claude select their citation sources — and the differences between platforms are far more significant than most people realize. Content marketing in 2026 isn't just about ranking in search results — it's about getting **cited by AI**. Generative Engine Optimization (GEO) is the practice of making your content discoverable and quotable by ChatGPT, Gemini, Perplexity, Claude, and Google AI Overviews. Here are the five priorities that matter most.
1. **Prompt-friendly writing is the foundation of AI citation** — Place a 40-60 word conclusion at the start of every section so RAG (Retrieval-Augmented Generation) pipelines can retrieve and quote it cleanly. JSON-LD schemas are worth implementing for traditional search purposes, but they have not been shown to increase AI citations
2. **Each AI platform has a different citation mechanism** — ChatGPT uses browsing with OAI-SearchBot (the plugin program was discontinued in 2024, replaced by custom GPT Actions), Gemini leverages Knowledge Graph integration, Perplexity auto-generates a Sources list, and Claude uses a document-level Citation API. You need platform-specific optimization for each
3. **Original research and explicit authority signals drive citation rates** — AI models compare multiple sources when generating answers. Unique data, case studies, and clearly attributed author credentials give your content a decisive advantage over commodity information
4. **Compliance with copyright, privacy, and AI ethics is essential** — Copyright still applies at the generation stage, data privacy laws like GDPR govern what can be indexed, and AI governance frameworks require transparency and source attribution
5. **Citation Rate is your primary KPI, and phased execution is the path to results** — Measure how often AI-generated answers include your URL, then follow a 5-phase implementation plan to systematically improve that metric over time
The sections below break down each priority with technical details, platform-specific tactics, and a step-by-step implementation roadmap.
---
## 1. What Is GEO? — Definition, Mechanics, and How It Differs from SEO
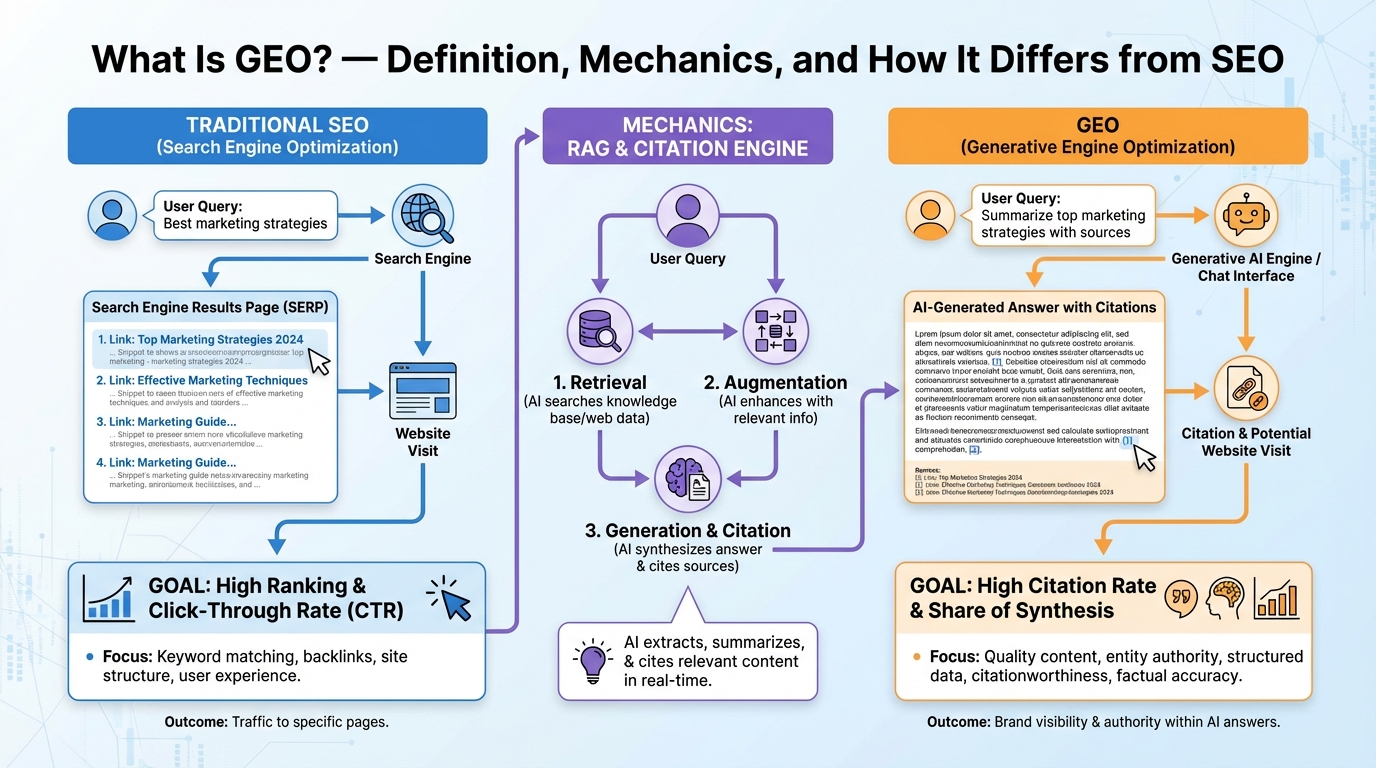
### Defining Generative Engine Optimization
GEO (Generative Engine Optimization) is the practice of structuring your content so that AI-driven search engines — ChatGPT, Google Gemini, Perplexity, Anthropic Claude, and Google AI Overviews — retrieve it, understand it, and cite it when generating answers to user queries.
While SEO focuses on ranking higher in a list of links, GEO focuses on being **quoted within AI-generated answers**. The goal shifts from click-through optimization to extraction friendliness.
### Why GEO matters now
This is something I've seen firsthand in client projects — sites with strong traditional SEO rankings are losing traffic to competitors who optimize specifically for AI citation. Zero-click searches are accelerating rapidly. When AI Overviews appear, organic CTR drops by an estimated 50-60% ([Ahrefs, 12/2025](https://ahrefs.com/blog/ai-overviews-reduce-clicks-update/); [Seer Interactive, 11/2025](https://www.seerinteractive.com/insights/ctr-aio)), and roughly 58.5% of Google searches end without a click to any external site ([SparkToro / Datos, 07/2024](https://sparktoro.com/blog/2024-zero-click-search-study-for-every-1000-us-google-searches-only-374-clicks-go-to-the-open-web-in-the-eu-its-360/)). Traditional SEO alone can no longer sustain organic traffic. GEO is the strategy that secures your brand's visibility in this new search environment. For a deeper look at how AI Overviews and AI Mode are reshaping organic search, see our guide on [how AI search is transforming SEO strategy](/blog/en/ai-search-seo-japan-2026/).
### The two technical pillars behind GEO
To understand GEO, you need to know how AI generates answers in the first place.
**RAG (Retrieval-Augmented Generation)** is the mechanism where an AI model retrieves external information at query time and injects it into the response. Instead of relying solely on training data, the model searches the web, fetches the most relevant content, and combines it into an answer. GEO optimization targets this retrieval step — making your content the one that gets pulled in.
**Citation Engine** is the mechanism that automatically attaches source URLs or references to AI-generated answers. ChatGPT's inline browsing links, Perplexity's "Sources" tab, Claude's Citation API, and Google AI Overview's source cards all use some form of citation engine. Getting recognized by the citation engine is GEO's ultimate goal.
| Dimension | SEO | GEO |
|-----------|-----|-----|
| Optimization target | Search engine ranking algorithms | AI's RAG pipeline + Citation Engine |
| Primary KPIs | Keyword rankings, organic CTR | Citation Rate, Share of Synthesis |
| Content design | Keyword density, backlink profile | Machine-readable structure, Q&A format, schema markup |
| How results appear | Listed on the search results page | Cited within AI-generated answers |
> References:
> [Generative Engine Optimization — CrafterCMS](https://craftercms.com/blog/business/generative-engine-optimization-the-new-frontier-of-web-visibility-in-the-age-of-ai)
> [GEO vs Traditional SEO Guide — Strapi](https://strapi.io/blog/generative-engine-optimization-vs-traditional-seo-guide)
> [What Is Generative Engine Optimization — Frase](https://frase.io/blog/what-is-generative-engine-optimization-geo)
---
## 2. Technical Foundations for AI Citation
With the conceptual framework in place, let's move to the technical implementation. Getting cited by AI requires six technical building blocks. These work together to make your content easy for RAG pipelines to discover, parse, and reference.
### Structured data (JSON-LD) implementation
Schema.org markup in JSON-LD format expresses your page's information in machine-readable form. `FAQPage`, `Article`, `Product`, and `HowTo` schemas make relationships — what is the title, who is the author — unambiguous. As covered below, however, this has not been shown to increase citations in AI search.
> **Updated August 2026.** Google's official AI optimization guide states that structured data is not required for generative AI search and that there is no special schema.org markup you need to add. Note this concerns eligibility requirements — it is not a claim that Google ignores schema internally.
> The widely quoted "FAQPage triples citation rate" figure is a correlation. In a controlled experiment that added schema, the changes in AI Mode (+2.4%) and ChatGPT (+2.2%) were indistinguishable from noise, and no increase in citations was observed.
> The −4.6% for AI Overviews is statistically significant but small, and factors other than schema may explain it.
> The experiment also covered only pages already cited 100+ times in AI Overviews before it began, so the effect on new pages is untested.
> Full details in "[Does FAQ Schema Really Get You Cited 3.2x More? We Removed the Number From Our Own Product](/blog/en/faq-schema-ai-citation-myth-2026/)." Structured data remains useful for traditional SEO purposes, but we cannot promise an effect on AI citations. Note that Google discontinued HowTo rich results in 2023 and [FAQPage rich results in May 2026](https://developers.google.com/search/updates#removing-faq-rich-result). Types that still produce rich results include Article and BreadcrumbList (Product applies to product pages, and Review requires genuine user reviews or ratings of an eligible item — it is not valid on a general article).
```html
```
For Perplexity in particular, allow `PerplexityBot` in `robots.txt` and write content in explicit Q&A form. Schema itself has no verified effect on citation frequency.
### Answer-first paragraph design
In my direct testing with Perplexity and Claude, the difference between articles that lead with a conclusion and those that don't is striking — the former get cited significantly more often. Place a self-contained answer (40-60 words) at the start of each section. AI models prioritize section openings when scanning for quotable content, so a "conclusion first" structure significantly increases your citation probability. Follow the opening answer with supporting data, examples, and source citations.
### How should you structure headings for AI citation?
Use H2/H3 headings phrased as natural-language questions (e.g., "What is generative engine optimization?" rather than "GEO Overview"). This matches the sub-query extraction pattern that LLMs use when breaking down complex user questions. This technique is especially important for Google's "query fan-out" system, which decomposes queries into sub-queries and matches them against content headings (see "[What Is Query Fan-Out? A Beginner's Guide](/blog/en/query-fan-out-guide-2026/)" for details).
### Content chunking for RAG
Break your content into blocks of 800 tokens or fewer, each with its own heading and URL anchor. RAG systems achieve higher retrieval accuracy with well-segmented chunks than with long, unbroken text.
### AI crawler control
Set explicit permissions in `robots.txt` for `GPTBot`, `PerplexityBot`, and other AI crawlers. Pages you want cited should be clearly allowed; pages you don't want indexed by AI should be explicitly blocked.
Cloudflare's "Markdown for Agents" takes this further by serving AI-optimized Markdown directly at the CDN edge. For implementation details and what this shift means for your GEO strategy, see "[Cloudflare's Markdown for Agents and AI-Ready Web Optimization](/blog/en/cloudflare-markdown-for-agents-2026/)."
### Prompt-engineering signals for content creators
Include a short "prompt hint" in your meta description that mirrors likely user questions (e.g., "How does GEO differ from SEO?"). This guides the model's retrieval scoring. Also, use chain-of-thought-style explanations — step-by-step reasoning increases Claude's willingness to cite the page.
| Tactic | Priority | Difficulty | Impact on AI citation |
|--------|----------|------------|----------------------|
| JSON-LD structured data | Low | Medium | No verified effect on AI citations; useful for rich results |
| Answer-first paragraphs | Highest | Low | Helps AI extract a quotable block (effect on citations unverified) |
| Content chunking | High | Low | Improves RAG retrieval accuracy |
| AI crawler control | High | Low | Ensures target pages are discoverable |
| Prompt-engineering signals | Medium | Low | Guides retrieval scoring |
| Cache control | Medium | Low | Improves crawl efficiency |
> References:
> [Structured Data Overview — Google Developers](https://developers.google.com/search/docs/appearance/structured-data/intro-structured-data)
> [GEO vs Traditional SEO — Strapi](https://strapi.io/blog/generative-engine-optimization-vs-traditional-seo-guide)
> [LLM Schema Optimisation Matters — ZC Marketing](https://zcmarketing.au/seo-tips/llm-schema-optimisation-matters/)
> [Prompt Engineering Techniques — IBM](https://www.ibm.com/think/topics/prompt-engineering-techniques)
---
## 3. Platform-Specific Citation Strategies
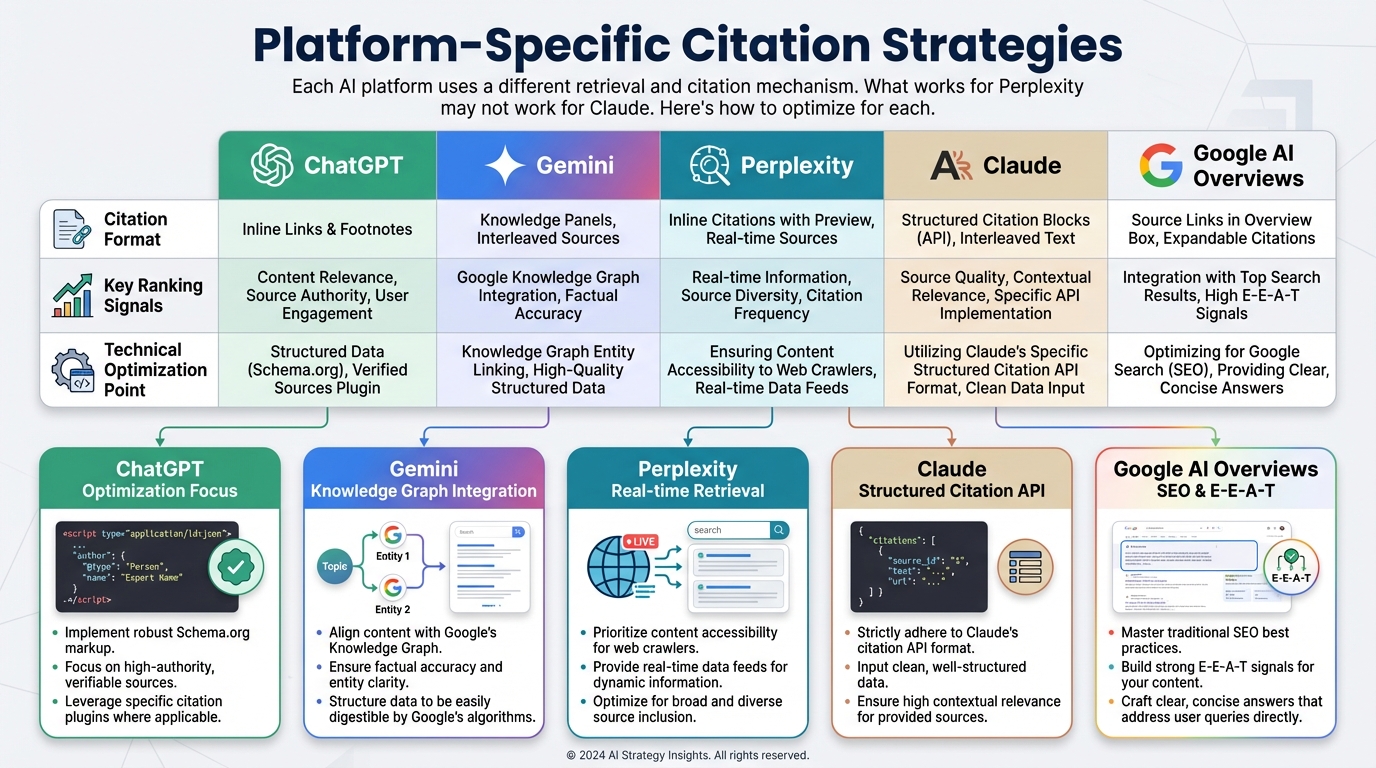
This is the part of GEO I find most fascinating. Each AI platform uses a different retrieval and citation mechanism. What works for Perplexity may not work for Claude. Here's how to optimize for each.
### ChatGPT (OpenAI)
ChatGPT uses web search in its browsing mode and displays inline links as source citations. Freshness is a strong signal — include a visible "Last Updated" timestamp on every page. Allow the OAI-SearchBot crawler in your `robots.txt` so ChatGPT search can discover your pages. Note that the original ChatGPT plugin program was discontinued in April 2024; the replacement is custom GPTs with Actions. Ensure your pages are indexable by both Bing and Google, as ChatGPT's search infrastructure draws from multiple sources.
### Google Gemini
Gemini breaks complex queries into multiple sub-queries (averaging 6-10 per prompt) and pulls the most authoritative source for each. It heavily leverages Google's Knowledge Graph, so `sameAs`, `Organization`, and `Person` markup directly influence citation. Grounding sources appear in the API response at `groundingMetadata.groundingChunks[].web.uri` — not a `sourceUrl` field. Focus on three areas: information density, multimodal integration (images, videos with schema), and real-time signals through weekly data updates.
### Perplexity
Perplexity auto-generates a clickable "Sources" list beneath every answer. Its Sonar retrieval engine favors fresh, well-cited, FAQ-style content. Publish explicit question-answer pairs — the model extracts these directly. Maintain weekly content refreshes, as recency is Perplexity's top ranking factor. Use canonical URLs and avoid JavaScript-only rendering because PerplexityBot cannot execute JS.
### Claude (Anthropic)
Claude's Citation API returns structured citation blocks that reference specific passages within documents provided in the request (using character or page locations), rather than generating footnotes with external URLs. Citations are enabled per-document by setting `citations: {"enabled": true}` on each document content block — not via the system prompt. One key limitation: Citations cannot be combined with Structured Outputs — the API returns a 400 error if both are enabled. Claude places greater weight on explicit author expertise — detailed author bios with credentials, organizational authority, and logical reasoning chains (if-then, cause-effect structures) are critical.
### Google AI Overviews
Keep answer blocks under 2-3 sentences and place them immediately after matching headings. Use FAQ and HowTo schema to map directly to the Overview's answer extraction pipeline. Monitor `max-snippet` and `nosnippet` directives — avoid blocking the AI from pulling excerpts from your pages.
| Platform | Citation format | Top signal | Integration point |
|----------|----------------|------------|-------------------|
| ChatGPT | Inline browsing links | Freshness + OAI-SearchBot crawlability | robots.txt + Bing/Google indexing |
| Gemini | `groundingChunks[].web.uri` + Knowledge Graph | JSON-LD `author` / `datePublished` | Google Cloud Console |
| Perplexity | Clickable Sources list | Recency + FAQ format | robots.txt PerplexityBot allow |
| Claude | Structured citation blocks | Author credentials + reasoning chains | Anthropic Console |
| AI Overviews | Source cards | FAQ/HowTo schema + concise answers | Google Search Console |
> References:
> [Overview of OpenAI crawlers — OpenAI Platform](https://platform.openai.com/docs/bots)
> [Grounding with Google Search — Gemini API](https://ai.google.dev/gemini-api/docs/google-search)
> [Citations — Anthropic API Docs](https://docs.anthropic.com/en/docs/build-with-claude/citations)
> [Perplexity SEO — Metronyx](https://metronyx.co.uk/resources/ai-search/perplexity-seo)
> [AI Features — Google Developers](https://developers.google.com/search/docs/appearance/ai-features)
---
## 4. Content Strategies That Get Cited by AI
### What kind of writing gets cited?
Having analyzed the writing style of frequently-cited pages across multiple AI engines, I've identified a consistent pattern. The most cited content is conversational yet fact-dense. Use short sentences, active voice, and embed statistics every 150-200 words. Avoid filler and hedge language. AI models compare multiple sources and favor the one that delivers the clearest, most data-rich answer.
### Target high-intent, answerable questions
Focus on queries that generate sub-queries — for example, "best project management tool for remote teams" rather than just "project management tools." Create pillar content covering the full topic (2,500-3,000 words) to satisfy ChatGPT's preference for comprehensive resources.
### Why does original research matter for GEO?
Include original research, proprietary case studies, or unique datasets. Perplexity and Claude heavily weight primary sources that can't be found elsewhere. A financial research blog that added author bios with 15-year industry credentials and embedded primary-source links saw Claude citations jump from under 1% to 8% of relevant queries.
### Citation practice that AI models recognize
Cite primary, authoritative sources inline — hyperlinked immediately after the claim. Use DOI or URL format and avoid footnotes that are hidden from the model. Prefer government, academic, or industry-standard publications. Claude explicitly looks for "credible, verifiable content."
### Don't forget multimodal assets
Add infographics, videos with full transcripts, and ImageObject schema. Gemini shows a 3.7x higher citation rate for pages with rich media. Alt text and structured metadata for visual content are no longer optional — they're a competitive advantage.
| Aspect | Best practice |
|--------|--------------|
| Writing style | Conversational, fact-dense, short sentences, active voice |
| Topic selection | High-intent answerable questions, pillar content (2,500-3,000 words) |
| Depth and originality | Original research, case studies, proprietary data |
| Citation practice | Inline hyperlinks immediately after claims, prefer authoritative sources |
| Multimodal content | Infographics + video transcripts + ImageObject schema |
> References:
> [Generative Engine Optimization — LLM Refs](https://llmrefs.com/generative-engine-optimization)
> [Claude AI Citation Optimization Guide — TrySight](https://www.trysight.ai/blog/claude-ai-citation-optimization-guide)
> [Optimizing Content for LLMs — Page Optimizer Pro](https://www.pageoptimizer.pro/blog/optimizing-content-for-llms-seo)
> [Perplexity Search Visibility Tips — Wellows](https://wellows.com/blog/perplexity-search-visibility-tips/)
---
{{linksurge-card}}
## 5. Compliance, Ethics, and Legal Considerations
GEO doesn't operate in a legal vacuum. As you optimize content for AI citation, you need to navigate copyright law, data privacy regulations, and AI ethics frameworks.
### Copyright and AI-generated content
Copyright applies at the generation stage. If AI output is substantially similar to a copyrighted work and the model relied on that work, infringement claims can arise. Use only content you own or have permission to republish. Cite sources properly and avoid uploading full copyrighted materials for AI citation without rights.
### Data privacy and GDPR compliance
Don't expose personal or confidential data in public pages — AI crawlers will index it. Follow GDPR and regional privacy laws for any content that could contain personally identifiable information. If you're building custom RAG pipelines, anonymize or hash all PII before vectorization.
### Attribution and transparency
Disclose any AI-assisted drafting in accordance with publisher policies. Major publishers (ACM, Elsevier, and others) now require AI-assistance notes. This transparency builds trust with both human readers and AI models that evaluate source credibility.
### Ethical sourcing of information
Prefer peer-reviewed, government, or industry-standard data. AI models down-rank content from biased or low-credibility sites. Claude's constitutional AI framework explicitly penalizes unverifiable statements, so fact-check every claim and include the source URL next to each statistic.
| Requirement | How to meet it |
|-------------|---------------|
| Copyright | Use owned content or licensed material; cite sources properly |
| Data privacy | Follow GDPR; anonymize PII before vectorization |
| Attribution | Disclose AI-assisted drafting per publisher policies |
| Misinformation | Fact-check all claims; include source URLs inline |
| Ethical sourcing | Prefer peer-reviewed, government, or industry-standard data |
> References:
> [AI Best Practices — FIT NYC](https://www.fitnyc.edu/about/required-information/ai-best-practices/policies.php)
> [Ethical Use of AI — PRSA](https://www.prsa.org/docs/default-source/about/ethics/ethicaluseofai.pdf)
> [AI in Academic Research — Purdue Libraries](https://guides.lib.purdue.edu/c.php?g=1371380&p=10135076)
---
## 6. Measurement and Monitoring
Implementing GEO tactics is only half the equation — without a measurement framework, you have no way to know what's working. GEO requires a new set of KPIs beyond traditional SEO metrics.
### Citation Rate — Your primary metric
Citation Rate is the percentage of AI-generated answers that include your URL. Track it across Perplexity's Sources list, Claude's Citation API, Gemini's `groundingChunks[].web.uri`, and ChatGPT's inline links. This is the single most important GEO metric to monitor monthly.
### AI visibility tracking tools
Platforms like [LinkSurge](https://linksurge.jp/), OtterlyAI, KIME, and Rankscale automatically query major LLMs and record brand mentions, citation position, and sentiment. These tools save hours of manual prompt auditing and provide trend data over time.
### Search Console integration
Enable AI Overview reporting in Google Search Console to see which queries trigger AI Overviews and which URLs are used as sources. This connects your GEO efforts directly to Google's AI search data.
### Custom prompt audits
Run a set of high-intent prompts (e.g., "What is GEO?" or "best SEO tools for 2026") in each AI tool weekly and log the returned sources. This manual audit catches gaps that automated tools may miss.
| Metric | How to measure | Frequency |
|--------|---------------|-----------|
| Citation Rate | AI answer URL tracking across platforms | Monthly |
| Top-3 Source Position | Whether your page appears in the first 3 citations | Monthly |
| Referral Traffic from AI | UTM-tagged clicks from AI-generated answers | Weekly |
| AI Crawler Access | Server log analysis for OAI-SearchBot, PerplexityBot, Claude-SearchBot (GPTBot and ClaudeBot are training crawlers) | Weekly |
| Engagement from AI visitors | Time on page, bounce rate for AI-referred sessions | Monthly |
> References:
> [OtterlyAI — AI Visibility Tracking](https://otterly.ai/)
> [Best AI Visibility Tools — SE Ranking](https://visible.seranking.com/blog/best-ai-visibility-tools/)
> [AI SEO Tracking Tools 2026 — Search Influence](https://www.searchinfluence.com/blog/ai-seo-tracking-tools-2026-analysis-platforms/)
---
## 7. Real-World Case Studies
These examples show how different types of organizations have used GEO tactics to increase AI citations.
### SaaS productivity suite — Gemini citations up 3.7x
A B2B SaaS company rewrote its pillar article to 2,800 words, added high-density data tables, ImageObject schema, and weekly KPI updates. Gemini citations increased 3.7x, and AI-generated click-through rose 15%.
### Healthcare guidelines site — 42% traffic growth from Perplexity
A healthcare information site built a comprehensive FAQ with inline citations, refreshed content monthly, and implemented full Article schema. The site achieved 5 citations per Perplexity answer on average, and referral traffic from Perplexity grew 42% in three months.
### Financial research blog — Claude citations from <1% to 8%
A financial research blog added author bios with 15-year industry experience, structured content with logical reasoning chains, and embedded primary-source links directly after each claim. Claude cited the blog in 8% of relevant queries, up from under 1% before optimization.
### E-commerce product pages — Featured in 12 AI Overview queries
An e-commerce retailer integrated HowTo schema for product selection guides, concise answer blocks, and Product schema with GTIN identifiers. The pages were featured in AI Overviews for 12 product-related queries, capturing 38% of SERP clicks.
| Case | Platform | Key tactics | Result |
|------|----------|-------------|--------|
| SaaS productivity suite | Gemini | Pillar content + data tables + ImageObject schema | 3.7x citation increase |
| Healthcare guidelines | Perplexity | FAQ + inline citations + monthly refresh | 42% traffic growth |
| Financial research blog | Claude | Author bios + reasoning chains + primary sources | Citations from <1% to 8% |
| E-commerce product pages | AI Overviews | HowTo schema + answer blocks + Product schema | Featured in 12 queries |
> References:
> [Visibility in Gemini — Appear on AI](https://appearonai.com/blog/visibility-in-gemini)
> [Perplexity Search Visibility — Wellows](https://wellows.com/blog/perplexity-search-visibility-tips/)
> [Claude AI Citation Optimization — TrySight](https://www.trysight.ai/blog/claude-ai-citation-optimization-guide)
> [AI Overviews Ranking Guide — Gryffin](https://www.gryffin.com/blog/google-ai-overviews-ranking-guide)
---
## 8. Phased Implementation Plan
GEO isn't a one-time project — it's a systematic rollout. This 5-phase plan takes you from quick wins to a fully operational AI visibility strategy.
### Phase 0: Baseline Analysis (Week 1)
- Build a list of target keywords and high-intent questions for your domain
- Audit competitor AI citations by searching your category in Perplexity, Claude, and ChatGPT — tools like [LinkSurge](https://linksurge.jp/) can track AI Overview appearances across keywords
- Measure your current Citation Rate to establish a baseline
### Phase 1: Technical Foundation (Weeks 2-3)
- Implement JSON-LD for `FAQPage` and `Article` on your highest-traffic pages
- Set canonical URLs and configure `robots.txt` to allow AI crawlers
- Achieve Core Web Vitals targets (LCP < 2.5s, INP < 200ms, CLS < 0.1)
- Add "Last Updated" timestamps visible on every page
### Phase 2: Content Optimization (Weeks 4-6)
- Rewrite the first 200 words of key pages to include a direct answer and inline citation
- Create FAQ pages for each core topic with question-based H2s and FAQ schema
- Add multimodal assets (infographics, short videos) tagged with ImageObject and VideoObject schema
- Chunk long-form content into 800-token blocks with unique headings and URL anchors
### Phase 3: Platform Integration (Weeks 7-10)
- Allow OAI-SearchBot and PerplexityBot in `robots.txt`
- Validate schema with Google's Rich Results Test
- Implement Author/Person schema with detailed credentials for all bylines
- Set up weekly content refresh calendar for time-sensitive pages
### Phase 4: Measurement and Continuous Improvement (Ongoing)
- Deploy an AI visibility dashboard ([LinkSurge](https://linksurge.jp/), OtterlyAI, or similar) to monitor citation trends
- Run weekly custom prompt audits across all major AI platforms
- Build entity homepages (brand, product, expert) interlinked with breadcrumb and `sameAs` properties
- Publish original research on third-party domains (industry journals, reputable news sites) to create a citation network
For a comprehensive view of technical SEO, content strategy, and link building that forms the foundation for GEO, see our [complete SEO guide for 2026](/blog/en/seo-guide-2026/).
> References:
> [Generative Engine Optimization — LLM Refs](https://llmrefs.com/generative-engine-optimization)
> [Generative Search Optimization — Quickchat AI](https://quickchat.ai/post/generative-search-optimization)
> [AI Overviews — Google Developers](https://developers.google.com/search/docs/appearance/ai-features)
---
For first-party data on which part of a page actually gets quoted, see [Where Does AI Search Actually Quote From?](/blog/en/ai-citation-block-position-research-2026/) — we analyzed 277 real citations and found 69.3% came from body sections rather than the opening.
---
## Frequently Asked Questions
### What is the difference between GEO and SEO?
SEO targets search engine ranking algorithms, optimizing for keyword positions and organic click-through rates. GEO targets the retrieval and citation mechanisms of generative AI, optimizing for Citation Rate and Share of Synthesis. The most effective strategy layers GEO on top of a solid SEO foundation — they're complementary, not competing approaches.
### What is the minimum you need to do to start GEO?
Start with two things: confirm your `robots.txt` allows the AI crawlers you care about, and rewrite section openings to include a 40-60 word direct answer. Crawler access is a precondition — if the crawler never reaches you, nothing downstream matters. JSON-LD comes later, and for traditional search purposes such as rich results rather than as a way to increase AI citations.
### How do you get cited by Perplexity?
Allow `PerplexityBot` in your `robots.txt`, structure content in explicit question-answer pairs, and refresh it weekly. Perplexity's Sonar model prioritizes recency and FAQ-formatted content. Strong E-E-A-T signals — particularly visible author credentials and publication dates — also increase your citation probability.
### Does GEO work for small businesses, not just enterprises?
Yes. Many GEO tactics — FAQ schema, answer-first paragraphs, robots.txt configuration — require no budget, just deliberate content structuring. A small web agency that implemented structured data and local information optimization was cited in AI Overviews regardless of its search ranking position. Scale matters less than structure.
### How do you measure GEO success?
Track Citation Rate (the percentage of AI answers that cite your URL) as your primary KPI. Use tools like OtterlyAI or Rankscale for automated tracking, supplement with weekly manual prompt audits, and monitor AI crawler access in your server logs. Google Search Console's AI Overview reporting connects your data directly to Google's AI search pipeline.
---
## Conclusion: Start with Schema and Answer-First Content
GEO extends traditional SEO by targeting how AI finds and cites your content. Get the structured data right, lead every section with a direct answer, keep your content fresh, and build credible authority signals. Each platform rewards slightly different signals — but those fundamentals apply across the board.
The fastest path to results is Phase 0 (audit competitor AI citations) and Phase 1 (robots.txt configuration for AI crawlers, plus answer-first rewrites). These steps take 1-2 weeks. Crawler access in particular is a precondition rather than an optimization. From there, layer on content optimization, platform integration, and continuous measurement to stay ahead as AI search continues to evolve.
Brand mentions beyond your own site are a critical — and often overlooked — driver of GEO success. For the data behind this shift and a step-by-step playbook, see "[91% of AI Answers Come from Sites That Aren't Yours](/blog/en/offsite-seo-geo-2026/)."
LinkSurge's [AI Overview analysis](https://linksurge.jp/aio-v5) lets you track your brand's citation status across Google AI Overviews and ChatGPT in real time. It's a practical starting point for measuring and improving your GEO performance.
If you want to understand the underlying concept of LLMO (Large Language Model Optimization) from the ground up, our [Beginner's Guide to LLMO](/blog/llmo-guide-beginners-2026/) covers the fundamentals including how RAG works and where to start.
For an experiment showing that AI reads structured data even with no visible content — an extreme case, not evidence that adding schema raises citations — see "[Invisible Site Ranks #1 in AI Search — How Structured Data Alone Fooled Perplexity](/blog/en/phantom-authority-invisible-website-ai-citation-2026/)."
---
## The Complete SEO Guide for 2026: Technical SEO, Content, and GEO Strategy in the AI Search Era
> URL: https://linksurge.jp/blog/en/seo-guide-2026/
> Date: 2026-02-10 | Category: SEO | Author: Aro Ogata
> Tags: SEO, AI Overviews, GEO, Technical SEO, E-E-A-T, Content SEO, 2026
## Key Takeaways: 5 Priorities for SEO Success in 2026
In the past 12 months, I've tracked how AI search engines select their citation sources across hundreds of queries — and the pattern is clear. SEO in 2026 is no longer just about ranking on search results pages — it's about being **cited by AI**. Here are the five priorities that matter most.
1. **Build a solid technical foundation** — Achieve INP under 200ms, LCP under 2.5s, and CLS under 0.15. Implement structured data (JSON-LD) for FAQ, HowTo, and Article schemas. Use SSR to ensure critical content is available in HTML, since AI crawlers may not execute JavaScript
2. **Add real experience and expertise to your content** — Don't publish AI-generated drafts as-is. Layer in firsthand experience, original data, and fact-checked statistics. Use question-based headings (H2/H3) and 40–60 word Atomic Answers that AI can easily cite
3. **Execute GEO (Generative Engine Optimization)** — Track how often your brand is cited by ChatGPT, Perplexity, Claude, and other AI search engines using "Share of Synthesis" as a KPI. Industry analyses estimate that AI Overviews now appear for a significant and growing share of commercial queries
4. **Build authority systematically** — Publish original research and industry reports to earn natural backlinks. Strengthen E-E-A-T (Experience, Expertise, Authoritativeness, Trustworthiness) across your entire site
5. **Automate with the right tools for your scale** — Start with GSC + GA4 (free), then scale up with platforms like [LinkSurge](https://linksurge.jp/), Semrush AI Visibility, or Botify. Automate reporting to make ROI visible and run monthly improvement cycles
The sections below cover each of these areas in detail.
---
## 1. Technical SEO
### Core Interaction Signals (CIS)
This is where I always tell clients to start, because it's the one area where improvements are measurable within days. Google replaced FID with INP (Interaction to Next Paint) in 2024. INP measures the responsiveness of every interaction on a page — clicks, taps, and key presses — with a "Good" threshold of 200ms or less. Pages exceeding 200ms face ranking penalties, making it critical to audit heavy JavaScript and animations.
### Core Web Vitals: Current Benchmarks
As of 2026, the passing thresholds are:
- LCP (Largest Contentful Paint): under 2.5 seconds
- CLS (Cumulative Layout Shift): under 0.15
- INP: under 200ms
The fundamentals still work: image compression, CSS/JS minification, and CDN usage remain effective speed improvements.
### Site Architecture and Internal Linking
Use topic clusters (pillar pages + supporting subpages) to keep hierarchy shallow and concentrate link equity on high-value pages. Pruning thin, low-traffic pages through deletion or noindex directives can also improve crawl efficiency. Our [Topic Clusters & Internal Linking Strategy guide](/blog/en/topic-cluster-internal-linking-strategy/) covers the step-by-step design process and pruning criteria in detail.
### JavaScript SEO
Use SSR (Server-Side Rendering) or dynamic rendering to ensure important content is output directly in HTML. AI crawlers may not execute JavaScript, so having information present in the HTML source is essential.
### Additional Technical Considerations
- **Soft 404 management**: Return proper 404/410 status codes for discontinued products, or redirect to alternatives
- **Schema markup**: Implement Article, FAQ, HowTo, Product, and Organization structured data so AI can accurately parse your information
- **HTTPS**: Required for all pages. Add CSP headers to strengthen security signals
- **Crawl budget optimization**: For large sites, exclude URL parameters and maintain updated XML sitemaps to ensure priority pages are indexed first
For a deep dive into sitemap segmentation and crawl budget management, see "[XML Sitemap Strategy 2026: Segmentation & Crawl Budget Optimization](/blog/en/xml-sitemap-strategy-2026/)."
Why these technical foundations have stayed at the center of ranking for 30 years, through every algorithm era, is laid out in "[How SEO Changed: From Keyword Stuffing to Getting Cited by AI](/blog/en/seo-history-keywords-to-ai-2026/)."
> References:
> [Technical SEO Checklist - Yotpo](https://www.yotpo.com/blog/full-technical-seo-checklist/)
> [Google Ranking Factors 2026 - Wix SEO Expert](https://www.wixseoexpert.com/post/google-ranking-factors-the-complete-list-2026)
> [Google's Recent Changes for SEO - Whistler Billboards](https://www.whistlerbillboards.com/marketing/googles-recent-changes-for-seo-in-2026/)
> [Core Web Vitals in 2026 - CD Studio](https://www.cdstudio.live/post/core-web-vitals-in-2026-how-to-pass-google-s-toughest-performance-metrics)
> [How to Optimize Content for AI Search - Semrush](https://www.semrush.com/blog/how-to-optimize-content-for-ai-search-engines/)
---
## 2. Content SEO
### Keyword Research and Intent Mapping
With the technical foundation in place, let's turn to the content layer — which is where most of the AI citation opportunity actually lives. With the rise of conversational search, prioritize question-based keywords like "how to do X" and "what's the best Y." Placing these as H2/H3 headings makes it easier for AI to extract answers.
Topic cluster design is equally important. Use pillar pages to cover the full scope of a topic, with subpages addressing specific questions. This structure increases the chances of being cited in AI Overviews.
### Working with AI-Generated Content
As of 2026, Google does not prohibit AI-generated content. However, publishing raw AI drafts without human input is a risk. You need to add firsthand experience, expert insights, and concrete examples. Google's "Experience" signal in E-E-A-T is something AI alone cannot produce.
Frankly, I've reviewed dozens of sites that took a "publish volume first, edit later" approach with AI content — and I haven't seen a single one sustain rankings beyond 3-4 months. Editorial review and original perspective are essential before publishing.
### Implementing E-E-A-T in Practice
- **Experience**: Include first-person accounts — "we tested this," "here's what happened when we implemented it"
- **Expertise**: Add author bios with credentials and track records. Include expert review badges where applicable
- **Authoritativeness**: Earn citations and backlinks from recognized industry publications
- **Trustworthiness**: Ensure HTTPS, privacy policies, editorial guidelines, and last-updated dates are visible. For YMYL topics, include medical or legal expert review disclosures
### Content Freshness and Depth
Regularly update statistics, examples, and outbound links to keep content current. AI evaluates whether information is recent as part of its quality assessment.
The "Atomic Answers" technique is also effective: structure a concise 40–60 word answer as a standalone paragraph for each key question. This format makes it easy for AI to extract and cite directly.
> References:
> [SEO 2026 - LaTevaWeb](https://www.latevaweb.com/en/seo-2026)
> [Google Policy on AI-Generated Content 2026 - LinkedIn](https://www.linkedin.com/pulse/google-policy-ai-generated-content-2026-complete-guide-hertlein-r45nf)
> [Modern Content Marketing in the Age of AI - Pod Digital](https://www.poddigital.co.uk/digital-marketing-news/the-2026-guide-to-modern-content-marketing-in-the-age-of-ai-search/)
> [SEO Cheat Sheet 2026 - LinkedIn](https://www.linkedin.com/posts/sunny-grewal_seo-cheat-sheet-updated-for-2026-activity-7405101661792210944-C2WY)
> [Optimize for Google AI Overviews - Fuel Online](https://fuelonline.com/optimize-for-google-ai-overviews/)
---
## 3. Adapting to AI-Powered Search
### SGE and AI Overviews
This section gets to the heart of what's changed. In my testing across hundreds of queries, I've found that being cited in an AI Overview often drives more qualified traffic than a traditional position-one ranking. Google now displays AI-generated summaries (AI Overviews) directly in search results. Multiple industry studies suggest that AI Overviews appear for a growing share of commercial queries — with some estimates placing the figure around 15–20% and rising ([BrightEdge, 2025](https://www.brightedge.com/resources/research-reports)). Being cited by AI is becoming a new key to earning clicks — potentially more important than traditional position #1.
To improve your odds, first confirm the crawlers you care about can reach you, then use question-based headings and cover topics in genuine depth. Structured data is worth implementing for traditional SEO purposes such as rich results, but it has not been shown to increase AI citations.
### GEO (Generative Engine Optimization)
"Share of Synthesis" has emerged as the key metric for measuring visibility in AI search engines like ChatGPT, Perplexity, and Claude. Use GEO analytics tools such as [LinkSurge](https://linksurge.jp/) to monitor how often your brand is cited in AI-generated responses, and track it as a core KPI.
Share of Synthesis measures what percentage of AI-generated answers reference your brand or content when the AI synthesizes information from multiple sources. Think of it as the GEO equivalent of traditional SEO's "Share of Voice."
| Metric | What It Measures |
|--------|------------------|
| **Share of Voice** (Traditional SEO) | Visibility share in search result pages |
| **Share of Synthesis** (GEO) | Citation share in AI-generated answers |
For example, if your site is cited in 30 out of 100 AI searches for a given category, your Share of Synthesis is 30%. Tracking this metric over time enables you to quantitatively evaluate the impact of GEO efforts.
For a deep dive into platform-specific citation strategies and a phased GEO implementation plan, see "[The Complete GEO Guide: How to Get Cited by ChatGPT, Gemini, and Perplexity](/blog/en/geo-guide-japan-2026/)."
### Addressing Zero-Click Search
AI-generated direct answers are significantly reducing traditional click-through rates (some analyses have reported CTR declines of up to approximately 60% for queries with AI Overviews — see [Seer Interactive, 2024](https://www.seerinteractive.com/insights)). To counteract this, earn rich snippets through FAQ and HowTo schemas, and provide visual value through video and infographics to stand out in search results.
> References:
> [What is SGE - Md Azizur Rahman](https://mdazizurrahman.com.bd/what-is-sge/)
> [Google SGE SEO Guide for 2026 - Promfly](https://www.promfly.com/blogs/google-sge-seo-guide-for-2026)
> [Generative Engine Optimization - Geoptie](https://geoptie.com/blog/generative-engine-optimization)
> [GEO Guide - LLM Refs](https://llmrefs.com/generative-engine-optimization)
---
## 4. Link Building and Authority
### Earning Natural Backlinks
Now that we've covered AI-era search adaptation, let's look at how link building strategy has shifted. The most effective approach is publishing original research, industry reports, and proprietary data. Data-driven content naturally attracts citations from other publications. Digital PR and media placements also contribute significantly to authority building.
### Guest Posts and Expert Contributions
When contributing articles to reputable industry sites, keep anchor text limited to brand names and natural contextual phrases. Keyword-stuffed anchors are counterproductive and may trigger penalties.
### Local SEO Link Strategy
Maintain accurate NAP (Name, Address, Phone) information across Google Business Profile, Yelp, and relevant industry directories to strengthen local signals.
### Tactics to Avoid
"Parasite SEO" (domain lending) — publishing thin content on high-authority domains — is now a Google penalty target. Regularly audit your link profile and use the Disavow tool to remove spam links.
PBN (Private Blog Network) and satellite site schemes are similarly penalized. Google's SpamBrain detection has become far more accurate at identifying these tactics — for a comprehensive breakdown of the risks and safe alternatives, see "[Satellite Sites & PBNs Are Dead: Safe Link Building in 2026](/blog/en/satellite-site-seo-risks-2026/)."
> References:
> [Link Building Strategies That Work - Coalition Technologies](https://coalitiontechnologies.com/blog/link-building-strategies-that-work)
> [How to Improve Google Search Ranking - Link Building HQ](https://www.linkbuildinghq.com/blog/how-to-improve-google-search-ranking-in-2026/)
> [Link Building Strategies - Backlinko](https://backlinko.com/link-building-strategies)
> [Link Building Strategies 2026 - Sky SEO Digital](https://skyseodigital.com/link-building-strategies-that-actually-work-in-2026/)
> [Parasite SEO - Junia AI](https://www.junia.ai/blog/parasite-seo)
---
## 5. User Experience Metrics
Aim for a combined Core Web Vitals score of 0.92 or above. With mobile traffic now representing the majority of global web usage ([Statcounter GlobalStats](https://gs.statcounter.com/platform-comparison-chart)), keeping mobile page load times under 2 seconds is particularly critical.
Engagement signals — CTR, time on page, and scroll depth — are now factors AI uses to assess whether a page is genuinely useful. Improve the responsiveness of all interactive elements, and use FAQ, HowTo, and Product schemas to earn rich results that boost click-through rates.
> References:
> [SEO 2026 PDF - Developer Aman](https://developeraman.vercel.app/assets/seo_2026.pdf)
> [Core Web Vitals for Beginners - Medium](https://medium.com/front-end-weekly/enhance-ux-exploring-core-web-vitals-for-beginners-ca0bdf9dedfc)
{{linksurge-card}}
---
## 6. Tools and Measurement
### Essential Tools
- **Google Search Console**: Monitor indexing status, CIS metrics, and AI Overview impressions
- **GA4 + Looker Studio**: Analyze user behavior, conversions, and AI-sourced traffic
### AI Visibility Tools
- [LinkSurge](https://linksurge.jp/) — An integrated platform combining AI Overviews analysis, SEO rank tracking, and GEO analytics
- Semrush AI Visibility Toolkit
- Surfer SEO AI Tracker
- Rankscale.ai / OmniSEO®
These tools quantitatively measure your visibility in AI Overviews, SGE, ChatGPT, and other AI search engines, including Share of Synthesis tracking.
### Technical Auditing
Use Screaming Frog, Sitebulb, or Botify for crawl error detection and schema validation.
### Link Analysis
Regularly audit backlink quality and anchor text distribution with Ahrefs, Majestic, or SE Ranking.
### Reporting Automation
Whatagraph (AI-powered summary reports) and Search Atlas (automated fix suggestions) can significantly reduce monthly reporting overhead.
> References:
> [AI-Driven SEO Tools for Agencies - Eesel AI](https://www.eesel.ai/blog/ai-driven-seo-tools-for-agencies)
> [Best SEO Tools - Marketer Milk](https://www.marketermilk.com/blog/best-seo-tools)
> [AI Search Visibility Audit Tools - The Rank Masters](https://www.therankmasters.com/insights/ai-search-visibility-audit-tools)
> [AI SEO Tools - Whatagraph](https://whatagraph.com/blog/articles/ai-seo-tools)
> [AI SEO Tracking Tools 2026 - Search Influence](https://www.searchinfluence.com/blog/ai-seo-tracking-tools-2026-analysis-platforms/)
---
## 7. Industry-Specific Guidance
### E-Commerce
Implement Product schema (price, availability, GTIN) on product pages and handle discontinued items with proper 404/410 status codes. Concentrate crawl budget on top-level categories and optimize for AI Overview "product comparison" citations.
### Blogs and Media Sites
Long-form content combining topic clusters with FAQ schema is the foundation. Add video and infographics for multimodal coverage, and schedule regular content refreshes for existing articles.
### B2B and Enterprise
Deploy Organization, Person, and Review schemas on company pages. Use whitepapers and case studies to strengthen E-E-A-T, aiming to be cited as "industry best practices" in AI Overviews.
### Local Business
Focus on unified NAP management, Google Business Profile optimization with LocalBusiness schema, and location-specific service pages. Local review acquisition directly impacts trust signals.
### YMYL (Finance, Health, Legal)
Expert attribution is mandatory. Display practitioner credentials (medical licenses, bar admissions), publication dates, and risk disclosures prominently. All AI-assisted content must be reviewed by qualified professionals before publishing.
> References:
> [Ecommerce Website SEO - DebugBear](https://www.debugbear.com/blog/ecommerce-website-seo)
> [How to Rank YMYL Finance Pages - Bruce Jones SEO](https://brucejonesseo.com/how-to-rank-ymyl-finance-pages-in-2026/)
> [SEO Best Practices for Small Business - First Ep Business](https://firstepbusiness.com/blog/seo-best-practices-for-a-small-business-2026-guide)
> [SEO for Enterprise - Saffron Edge](https://www.saffronedge.com/blog/seo-for-enterprise)
---
## 8. Budget and Resource Planning
What I find particularly useful about thinking in budget tiers is that it prevents the common mistake of overinvesting in enterprise tools when simpler solutions would deliver the same results.
### Small Scale (Freelancers & Startups) — $300–$1,000/month
Focus on basic technical audits, refreshing existing content, and local link acquisition. Use GSC and GA4 (free), Screaming Frog free edition, and handle AI content editing manually.
### Mid-Market (SMBs) — $1,000–$3,500/month
Balance technical optimization, AI-assisted content creation, link building, and local SEO. Use [LinkSurge](https://linksurge.jp/) for AI Overviews and GEO analytics, combined with Semrush One or Whatagraph for automated reporting — a cost-effective operational setup.
### Enterprise — $3,500–$15,000+/month
Invest in programmatic SEO, GEO strategy, multi-language/multi-region management, and dashboard integration. Botify, Conductor, OmniSEO®, and Looker Studio + BigQuery integrations are well-suited for this scale.
> References:
> [SEO for Small Business - 8Spark](https://8spark.com/blogs/seo-for-small-business)
> [Enterprise SEO Resolutions 2026 - Seeders](https://seeders.com/blog/7-best-enterprise-seo-resolutions-for-2026/)
> [Small Business SEO vs Enterprise SEO - EWR Digital](https://www.ewrdigital.com/blog/small-business-seo-vs-enterprise-seo)
---
## 9. Implementation Roadmap
### Phase 1: Quick Wins (Weeks 0–2)
- Baseline INP and LCP scores using GSC and PageSpeed Insights
- Add FAQ/HowTo schema to high-priority pages
- Noindex or remove low-quality thin pages
### Phase 2: Foundation Building (Weeks 3–6)
- Redesign site architecture around topic clusters
- Implement Product/Service schema on key pages
- Add Atomic Answers to question-focused pages for AI Overview optimization
### Phase 3: Content Expansion (Weeks 7–12)
- Draft content with AI, then refine with Human-First Editing (adding experience and case studies)
- Create video and infographic assets for multimodal presence
- Update statistics and links in existing content
### Phase 4: Authority Building (Weeks 13–24)
- Publish industry reports and pursue digital PR for high-quality backlinks
- Commission expert contributions and influencer collaborations
- Track Share of Synthesis using [LinkSurge](https://linksurge.jp/) or similar AI visibility tools
### Phase 5: Continuous Optimization (Week 25+)
- Monthly review of CIS scores and AI Overview impressions
- Plan for new search algorithm updates and AI feature rollouts
- Automate operations with content calendars and SEO dashboards
> References:
> [Complete SEO Roadmap for 2026 - Pennep](https://www.pennep.com/blog/complete-seo-roadmap-for-2026-strategies-tools-and-best-digital-marketing-expertise-practices-for-google-rankings)
> [Actionable Tactics to Improve Google Rankings - SEOlogist](https://www.seologist.com/knowledge-sharing/top-21-actionable-proven-tactics-to-improve-google-search-ranking)
---
## 10. CMS Selection Guide
### WordPress
Rich plugin ecosystem (Yoast SEO, Rank Math) with strong URL control and automated schema generation. WPML and Polylang enable multilingual support. Best for content-heavy blogs and corporate sites.
### Wix / Wix Studio
Built-in SEO wizard and mobile optimization make it accessible for small sites and startups. Page speed is platform-dependent, which is a trade-off to consider.
### Shopify
Automated e-commerce schema generation and fast CDN-backed hosting are key strengths. Extensive SEO app ecosystem makes it ideal for online stores with large product catalogs.
### Headless CMS (Contentful, Sanity)
API-first architecture enables multi-channel content delivery with flexible schema management. Best suited for large-scale, multilingual, and multi-platform strategies.
### Drupal
Advanced access control and security features make it the go-to for enterprise-scale SEO. Widely adopted by government agencies and educational institutions.
> References:
> [Which CMS is Best for SEO - SEO Locale](https://seolocale.com/which-cms-is-best-for-seo-top-platforms-compared-for-2026/)
> [WordPress vs Wix SEO - BT Marketing](https://btmarketing.ca/wordpress-vs-wix-seo-ranking/)
> [WordPress Alternatives 2026 - Creative Corner](https://www.creativecorner.studio/blog/10-wordpress-alternatives-2026-edition)
---
## Frequently Asked Questions (FAQ)
### What is the most significant SEO change in 2026?
The rise of AI search engines (Google AI Overviews, ChatGPT, Perplexity) means that "being cited in AI-generated answers" is now as important as ranking on traditional search results. GEO (Generative Engine Optimization) has emerged as a new discipline, with Share of Synthesis becoming the standard metric for measuring AI citation rates.
### Where should SEO beginners start?
Begin with Core Web Vitals optimization (INP, LCP, CLS) and implementing structured data (JSON-LD) for FAQ and HowTo schemas. Without a solid technical foundation, even the best content won't be properly recognized by Google or AI search engines. Setting up Google Search Console and GA4 should be your first priority.
### How can I get featured in AI Overviews?
Content that gets cited in AI Overviews typically has three characteristics: (1) question-format headings (H2/H3) that directly address search intent, (2) Atomic Answers — standalone paragraphs of 40–60 words that AI can cite directly, and (3) clear E-E-A-T signals showing the content comes from an authoritative source. Structured data implementation also improves citation rates.
### Should I use free or paid SEO tools?
Choose based on your site's scale and budget. For personal blogs and small sites, Google Search Console + GA4 (free) provides sufficient coverage. For business sites with significant traffic, platforms like [LinkSurge](https://linksurge.jp/), Semrush, and Ahrefs deliver keyword analysis, competitor research, and AI visibility tracking that substantially improve ROI.
### What are practical steps to improve E-E-A-T?
Start by creating author profile pages with real names, credentials, and professional backgrounds. Then publish original research and industry data to earn natural backlinks. Contribute guest articles and secure interview placements in recognized industry publications to build off-site authority. Use Schema.org Person and Organization markup to communicate this information to Google as structured data.
---
## Summary: Where to Start
For a deep dive into how user intent shapes content strategy, see [What Is Search Intent? The 4 Types and How They Shape SEO](/blog/en/search-intent-seo-guide/).
The most practical approach is to work through the five priorities outlined at the beginning of this article, in order of impact.
Complete your technical audit and schema implementation (Phase 1) in the first two weeks. Then spend weeks 3–6 restructuring content and deploying Atomic Answers (Phase 2) while beginning GEO monitoring in parallel. Link building and PR for authority development (Phase 4) should run as an ongoing mid-to-long-term initiative, with AI visibility tools tracking quantitative results.
Whether you're optimizing a single-market site or planning global expansion, this phased approach delivers sustainable organic traffic growth and stronger brand recognition.
For a deep dive into why brand presence beyond your own site now matters more than backlinks for AI search visibility, see "[91% of AI Answers Come from Sites That Aren't Yours](/blog/en/offsite-seo-geo-2026/)." And for platform-specific social media tactics that drive AI citations, check out "[X, Instagram & LinkedIn AI Search Optimization](/blog/en/sns-ai-search-optimization-2026/)."
[LinkSurge](https://linksurge.jp/) provides AI Overviews analysis, SEO rank tracking, and GEO analytics — the tools you need for a data-driven 2026 SEO strategy. Ready to get started?